


Add extended Combined ARC comparison
Browse files
.gitattributes
CHANGED
|
@@ -33,3 +33,4 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
assets/combined_arc_model_comparison.png filter=lfs diff=lfs merge=lfs -text
|
README.md
CHANGED
|
@@ -60,9 +60,15 @@ Machine-readable reports are published under `reports/sft-v2-300k/`.
|
|
| 60 |
|
| 61 |
### Compact-model comparison
|
| 62 |
|
|
|
|
|
|
|
| 63 |
| Model | Parameters | PIQA acc | ARC-Easy acc | ARC-Challenge acc | **Combined ARC acc** | HellaSwag acc |
|
| 64 |
|---|---:|---:|---:|---:|---:|---:|
|
| 65 |
| **TR-HASH MoE 200M Full SFT** | **201.2M** | **68.01%** | **57.24%** | **27.13%** | **47.29%** | **33.21%** |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 66 |
| GPT-2 Small | 124M | 62.89% | 43.81% | 19.03% | ≈35.63% | 28.92% |
|
| 67 |
| OPT-125M | 125M | 63.00% | 43.60% | 19.10% | ≈35.51% | 29.20% |
|
| 68 |
| Pythia-160M | 160M | 62.73% | 43.52% | 18.77% | 35.34% | — |
|
|
@@ -73,9 +79,12 @@ the [AMD-LLM lm-evaluation-harness comparison](https://github.com/AMD-AGI/AMD-LL
|
|
| 73 |
their combined values are approximate because the published component scores
|
| 74 |
are rounded. Pythia-160M uses EleutherAI's
|
| 75 |
[official zero-shot result](https://github.com/EleutherAI/pythia/blob/main/evals/pythia-v1/pythia-160m/zero-shot/160m_step143000.json).
|
| 76 |
-
|
| 77 |
-
|
| 78 |
-
|
|
|
|
|
|
|
|
|
|
| 79 |
|
| 80 |
## Training recipe
|
| 81 |
|
|
|
|
| 60 |
|
| 61 |
### Compact-model comparison
|
| 62 |
|
| 63 |
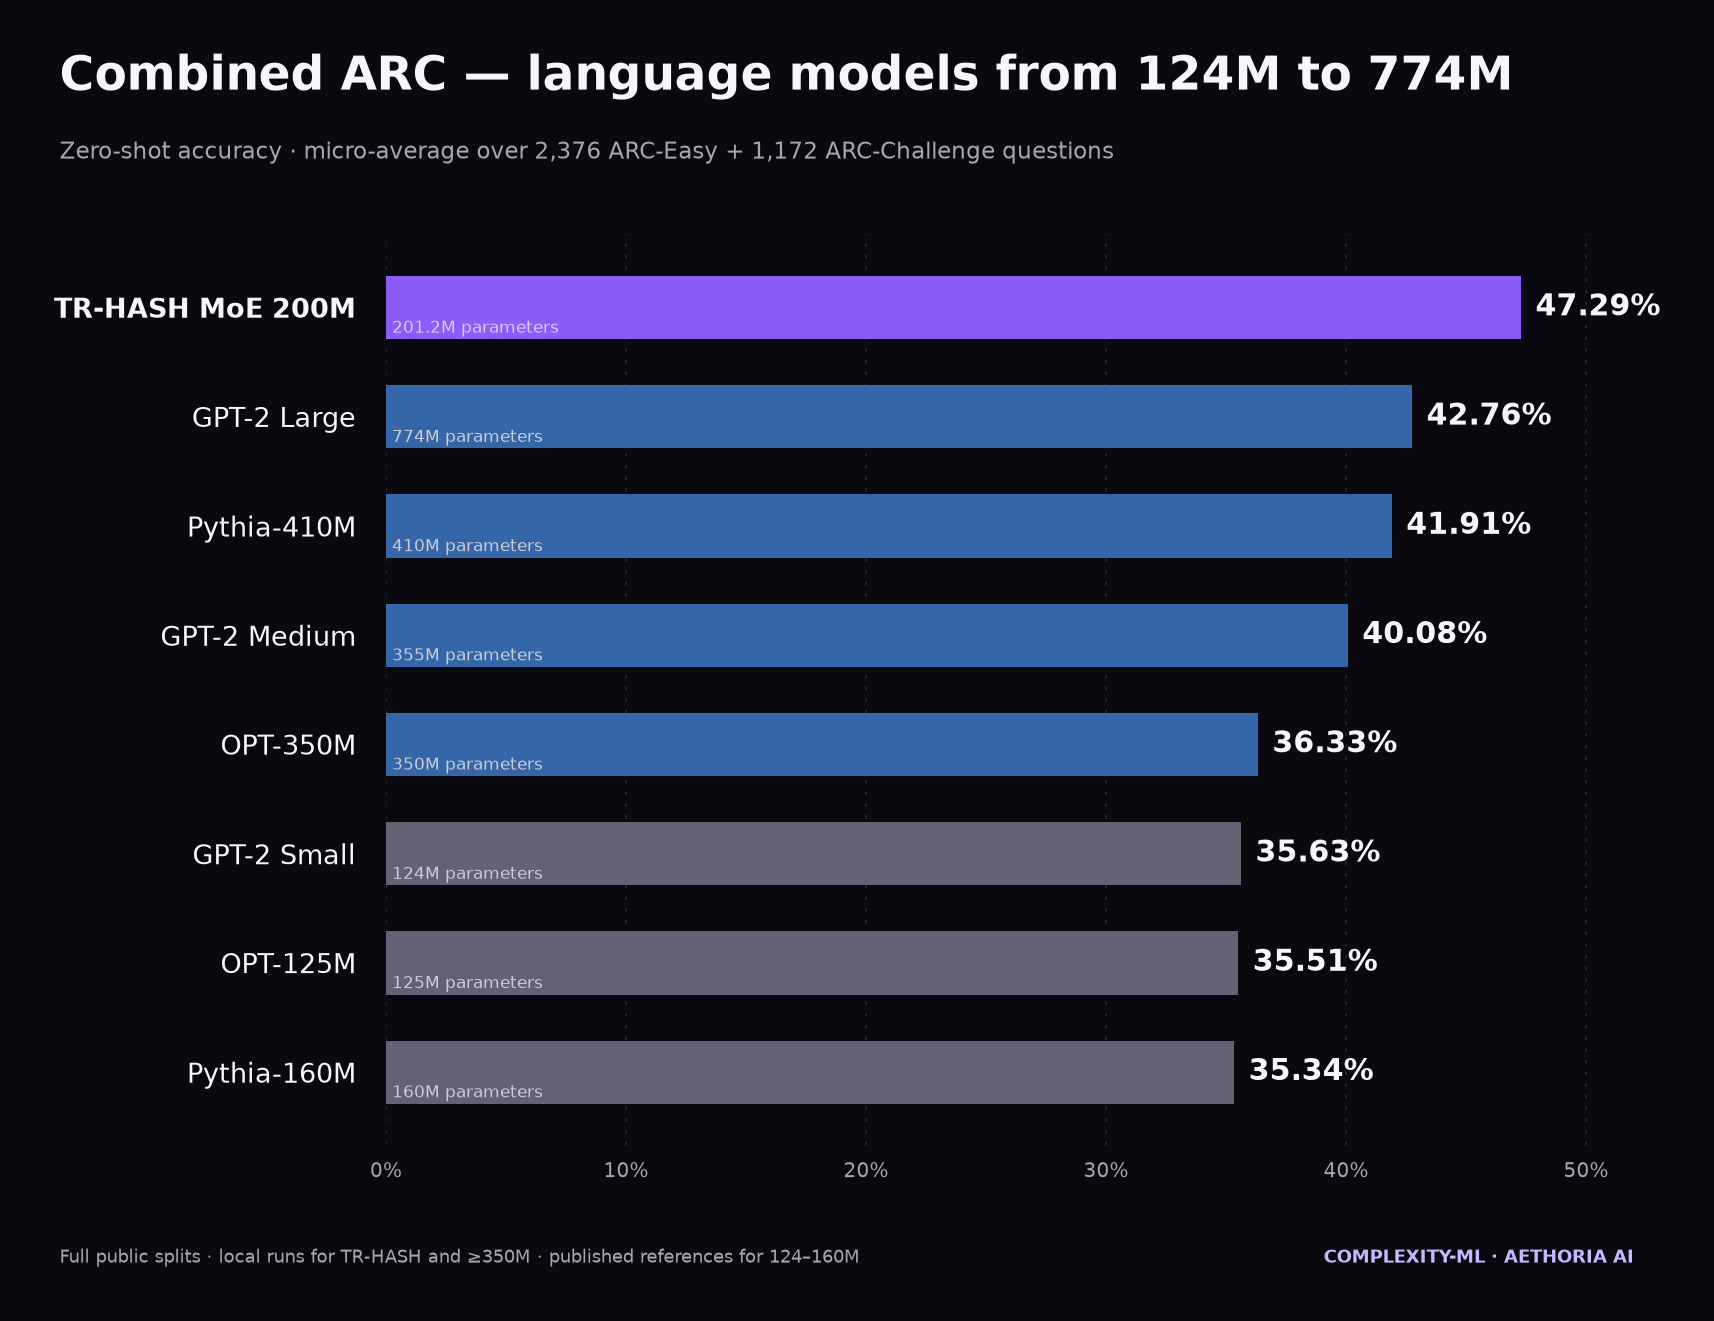
+

|
| 64 |
+
|
| 65 |
| Model | Parameters | PIQA acc | ARC-Easy acc | ARC-Challenge acc | **Combined ARC acc** | HellaSwag acc |
|
| 66 |
|---|---:|---:|---:|---:|---:|---:|
|
| 67 |
| **TR-HASH MoE 200M Full SFT** | **201.2M** | **68.01%** | **57.24%** | **27.13%** | **47.29%** | **33.21%** |
|
| 68 |
+
| GPT-2 Large | 774M | — | 53.11% | 21.76% | 42.76% | — |
|
| 69 |
+
| Pythia-410M | 410M | — | 52.02% | 21.42% | 41.91% | — |
|
| 70 |
+
| GPT-2 Medium | 355M | — | 49.16% | 21.67% | 40.08% | — |
|
| 71 |
+
| OPT-350M | 350M | — | 43.98% | 20.82% | 36.33% | — |
|
| 72 |
| GPT-2 Small | 124M | 62.89% | 43.81% | 19.03% | ≈35.63% | 28.92% |
|
| 73 |
| OPT-125M | 125M | 63.00% | 43.60% | 19.10% | ≈35.51% | 29.20% |
|
| 74 |
| Pythia-160M | 160M | 62.73% | 43.52% | 18.77% | 35.34% | — |
|
|
|
|
| 79 |
their combined values are approximate because the published component scores
|
| 80 |
are rounded. Pythia-160M uses EleutherAI's
|
| 81 |
[official zero-shot result](https://github.com/EleutherAI/pythia/blob/main/evals/pythia-v1/pythia-160m/zero-shot/160m_step143000.json).
|
| 82 |
+
GPT-2 Medium, GPT-2 Large and Pythia-410M were evaluated locally in MLX FP16
|
| 83 |
+
with the same causal-choice evaluator as TR-HASH. OPT-350M used the identical
|
| 84 |
+
prompt and scoring formula in PyTorch MPS FP16 because MLX does not implement
|
| 85 |
+
the OPT architecture. The 124M–160M references were reported through
|
| 86 |
+
lm-evaluation-harness, so that part of the comparison is informative rather
|
| 87 |
+
than a claim of bit-identical evaluation runtimes.
|
| 88 |
|
| 89 |
## Training recipe
|
| 90 |
|
assets/combined_arc_model_comparison.png
ADDED
|
Git LFS Details
|
reports/sft-v2-300k/arc_combined_model_comparison.json
ADDED
|
@@ -0,0 +1,75 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"aggregation": "micro-average over 2376 ARC-Easy and 1172 ARC-Challenge test examples",
|
| 3 |
+
"metric": "raw causal-choice accuracy",
|
| 4 |
+
"models": [
|
| 5 |
+
{
|
| 6 |
+
"model": "AETHORIA-AI/TR-HASH-MoE-200M-160B-SFT",
|
| 7 |
+
"parameters": 201194880,
|
| 8 |
+
"arc_easy_acc": 0.5723905723905723,
|
| 9 |
+
"arc_challenge_acc": 0.2713310580204778,
|
| 10 |
+
"arc_combined_acc": 0.4729425028184893,
|
| 11 |
+
"combined_correct": 1678,
|
| 12 |
+
"backend": "mlx-fp16"
|
| 13 |
+
},
|
| 14 |
+
{
|
| 15 |
+
"model": "openai-community/gpt2-large",
|
| 16 |
+
"parameters": 774030080,
|
| 17 |
+
"arc_easy_acc": 0.5311447811447811,
|
| 18 |
+
"arc_challenge_acc": 0.2175767918088737,
|
| 19 |
+
"arc_combined_acc": 0.427564825253664,
|
| 20 |
+
"combined_correct": 1517,
|
| 21 |
+
"backend": "mlx-fp16"
|
| 22 |
+
},
|
| 23 |
+
{
|
| 24 |
+
"model": "EleutherAI/pythia-410m",
|
| 25 |
+
"parameters": 405334016,
|
| 26 |
+
"arc_easy_acc": 0.5202020202020202,
|
| 27 |
+
"arc_challenge_acc": 0.21416382252559726,
|
| 28 |
+
"arc_combined_acc": 0.41910935738444194,
|
| 29 |
+
"combined_correct": 1487,
|
| 30 |
+
"backend": "mlx-fp16"
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"model": "openai-community/gpt2-medium",
|
| 34 |
+
"parameters": 354823168,
|
| 35 |
+
"arc_easy_acc": 0.49158249158249157,
|
| 36 |
+
"arc_challenge_acc": 0.2167235494880546,
|
| 37 |
+
"arc_combined_acc": 0.4007891770011274,
|
| 38 |
+
"combined_correct": 1422,
|
| 39 |
+
"backend": "mlx-fp16"
|
| 40 |
+
},
|
| 41 |
+
{
|
| 42 |
+
"model": "facebook/opt-350m",
|
| 43 |
+
"parameters": 331196416,
|
| 44 |
+
"arc_easy_acc": 0.4398148148148148,
|
| 45 |
+
"arc_challenge_acc": 0.20819112627986347,
|
| 46 |
+
"arc_combined_acc": 0.36330326944757607,
|
| 47 |
+
"combined_correct": 1289,
|
| 48 |
+
"backend": "pytorch-mps-fp16"
|
| 49 |
+
},
|
| 50 |
+
{
|
| 51 |
+
"model": "openai-community/gpt2",
|
| 52 |
+
"parameters": 124439808,
|
| 53 |
+
"arc_easy_acc": 0.4381,
|
| 54 |
+
"arc_challenge_acc": 0.1903,
|
| 55 |
+
"arc_combined_acc_approx": 0.356257,
|
| 56 |
+
"source": "AMD-AGI/AMD-LLM published rounded lm-evaluation-harness scores"
|
| 57 |
+
},
|
| 58 |
+
{
|
| 59 |
+
"model": "facebook/opt-125m",
|
| 60 |
+
"parameters": 125239296,
|
| 61 |
+
"arc_easy_acc": 0.436,
|
| 62 |
+
"arc_challenge_acc": 0.191,
|
| 63 |
+
"arc_combined_acc_approx": 0.35513,
|
| 64 |
+
"source": "AMD-AGI/AMD-LLM published rounded lm-evaluation-harness scores"
|
| 65 |
+
},
|
| 66 |
+
{
|
| 67 |
+
"model": "EleutherAI/pythia-160m",
|
| 68 |
+
"parameters": 162322944,
|
| 69 |
+
"arc_easy_acc": 0.4351851851851852,
|
| 70 |
+
"arc_challenge_acc": 0.18771331058020477,
|
| 71 |
+
"arc_combined_acc": 0.35343855693348365,
|
| 72 |
+
"source": "EleutherAI official zero-shot result"
|
| 73 |
+
}
|
| 74 |
+
]
|
| 75 |
+
}
|