


no em-dashes, plainer prose
Browse files- README.md +20 -31
- charts/categories-heatmap.png +2 -2
- charts/wrapped.png +0 -0
README.md
CHANGED
|
@@ -18,16 +18,13 @@ tags:
|
|
| 18 |
|
| 19 |
**[Try it →](https://hemmingway.io)** · **[Mac and Android apps →](https://hemmingway.io/download)** · **[Code →](https://github.com/lukeckprobierts/Hemmingway-1)**
|
| 20 |
|
| 21 |
-
|
| 22 |
-
going to send. Ask one for a text to your landlord and you get three options, a
|
| 23 |
preamble, and a paragraph explaining the options. Hemmingway-1 gives you the
|
| 24 |
text.
|
| 25 |
|
| 26 |
-
We built it for the writing people do every day
|
| 27 |
-
note to a colleague, the thing you
|
| 28 |
-
against the biggest models in the world at exactly that.
|
| 29 |
-
|
| 30 |
-
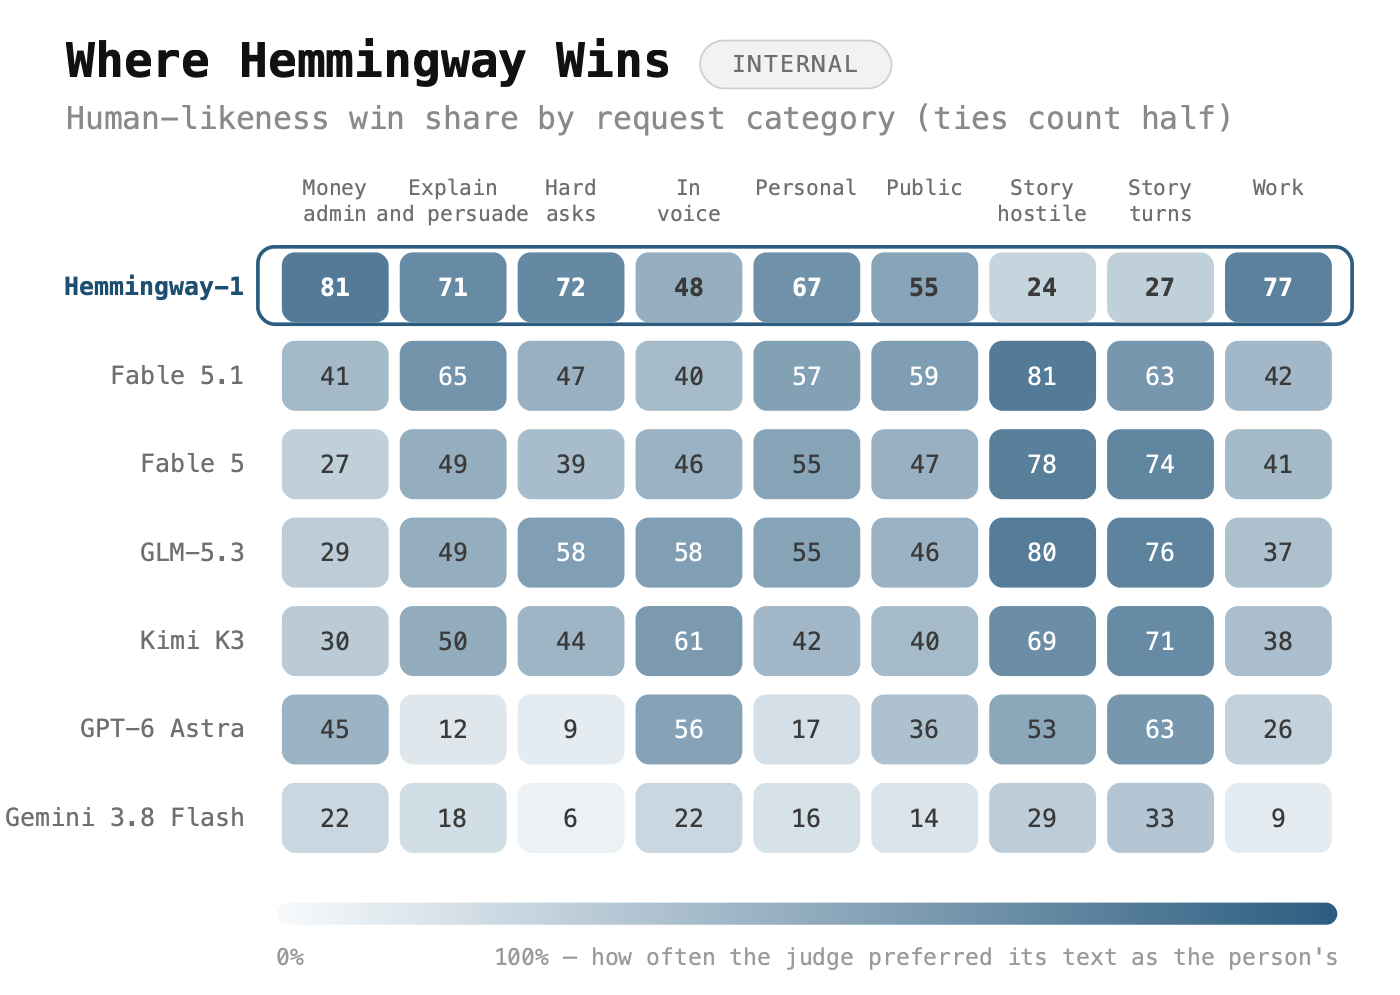
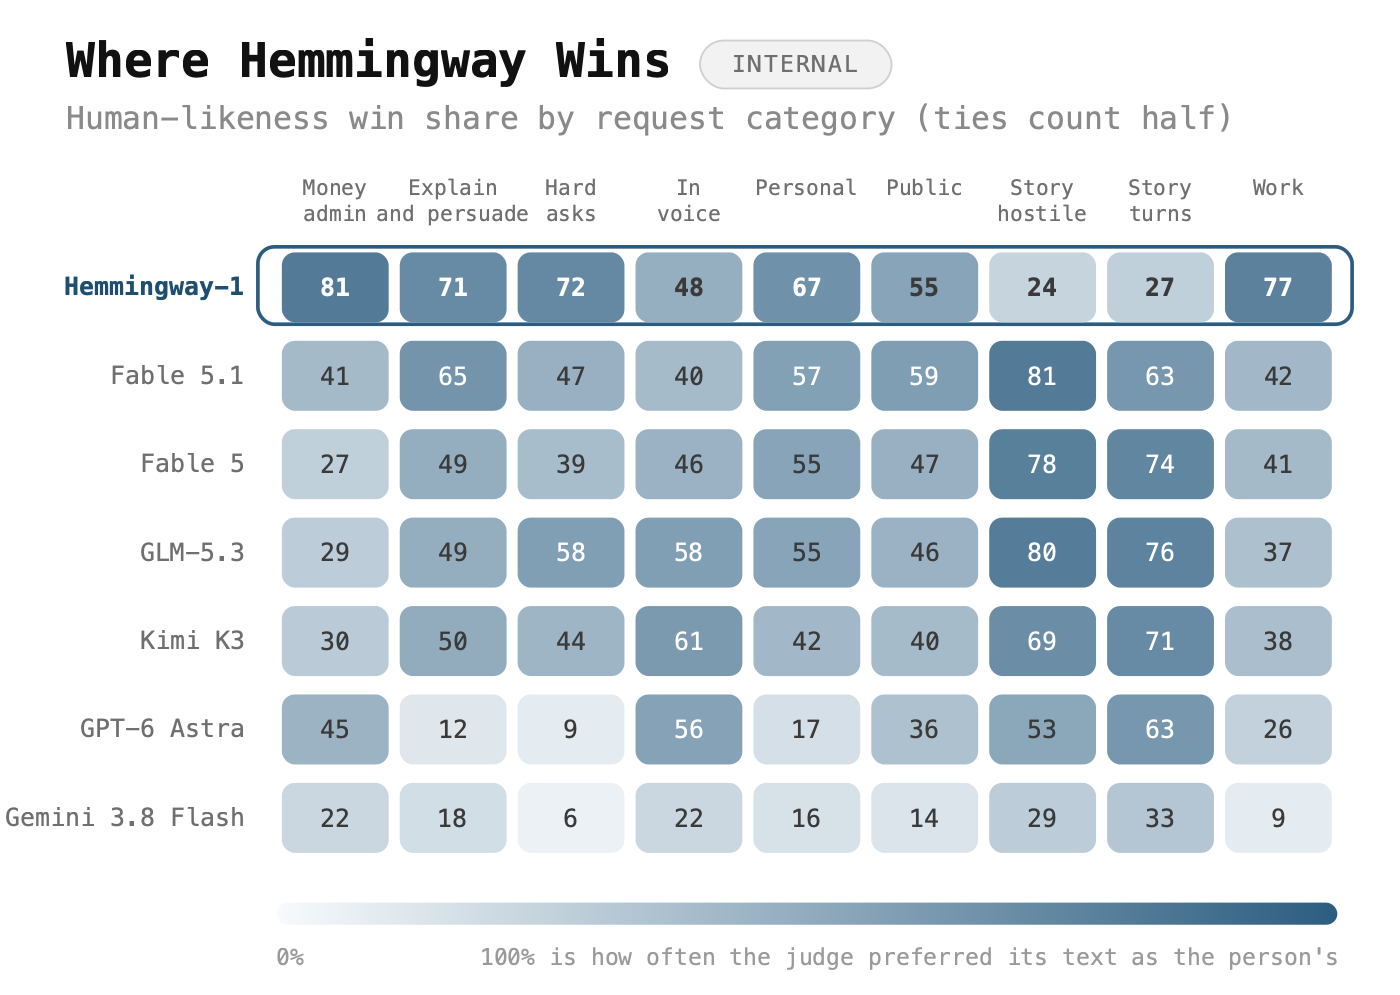
It came first.
|
| 31 |
|
| 32 |
## It writes the best everyday messages of any model we tested
|
| 33 |
|
|
@@ -36,31 +33,30 @@ to the same request, shuffled so the judge never knows which is which.
|
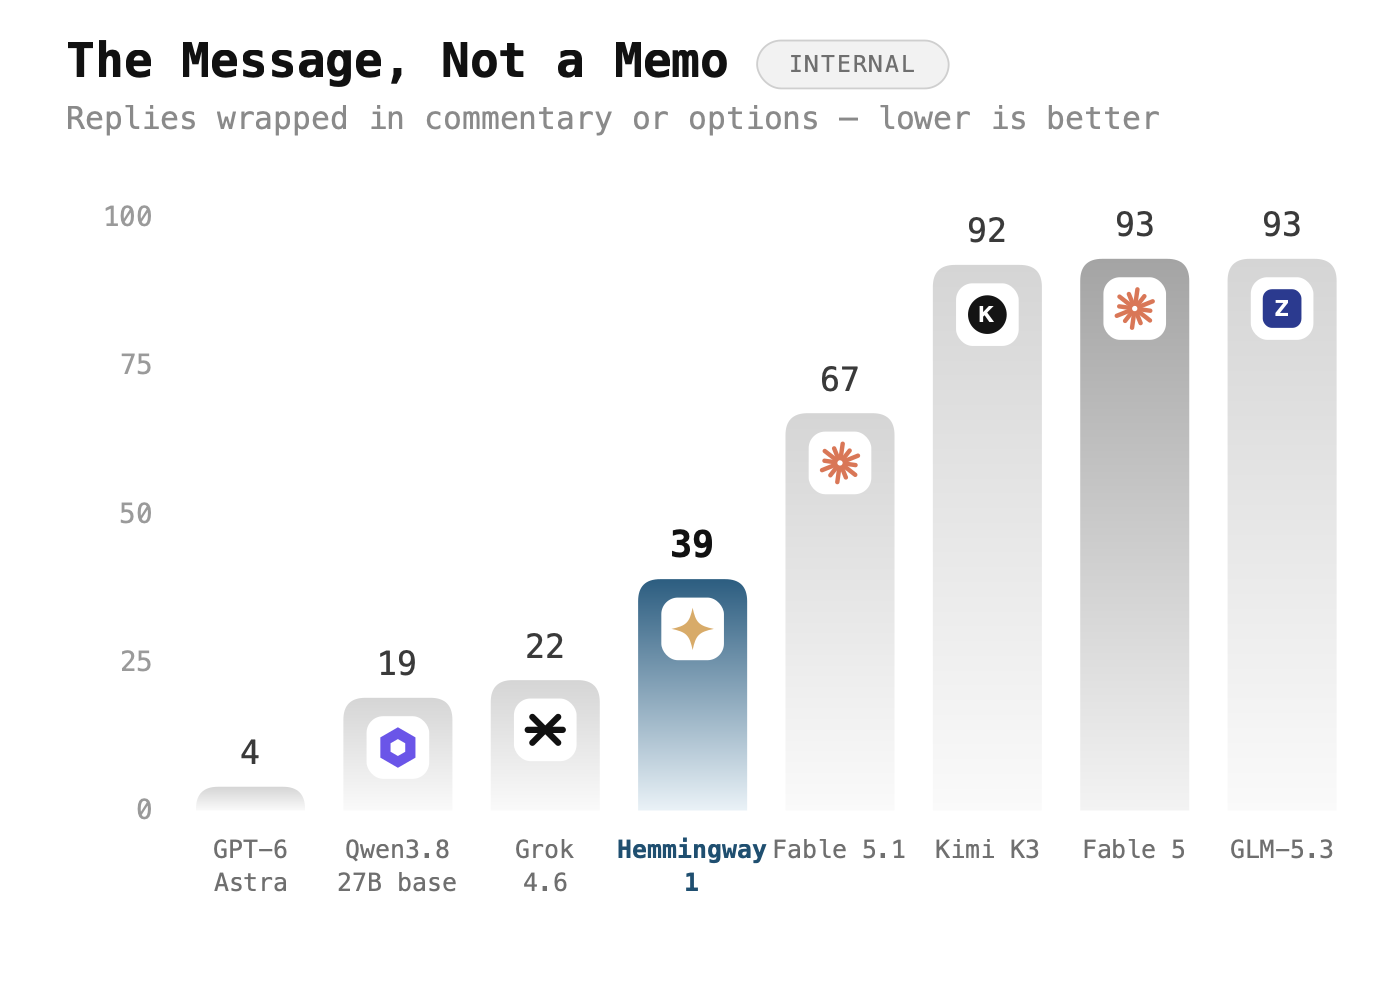
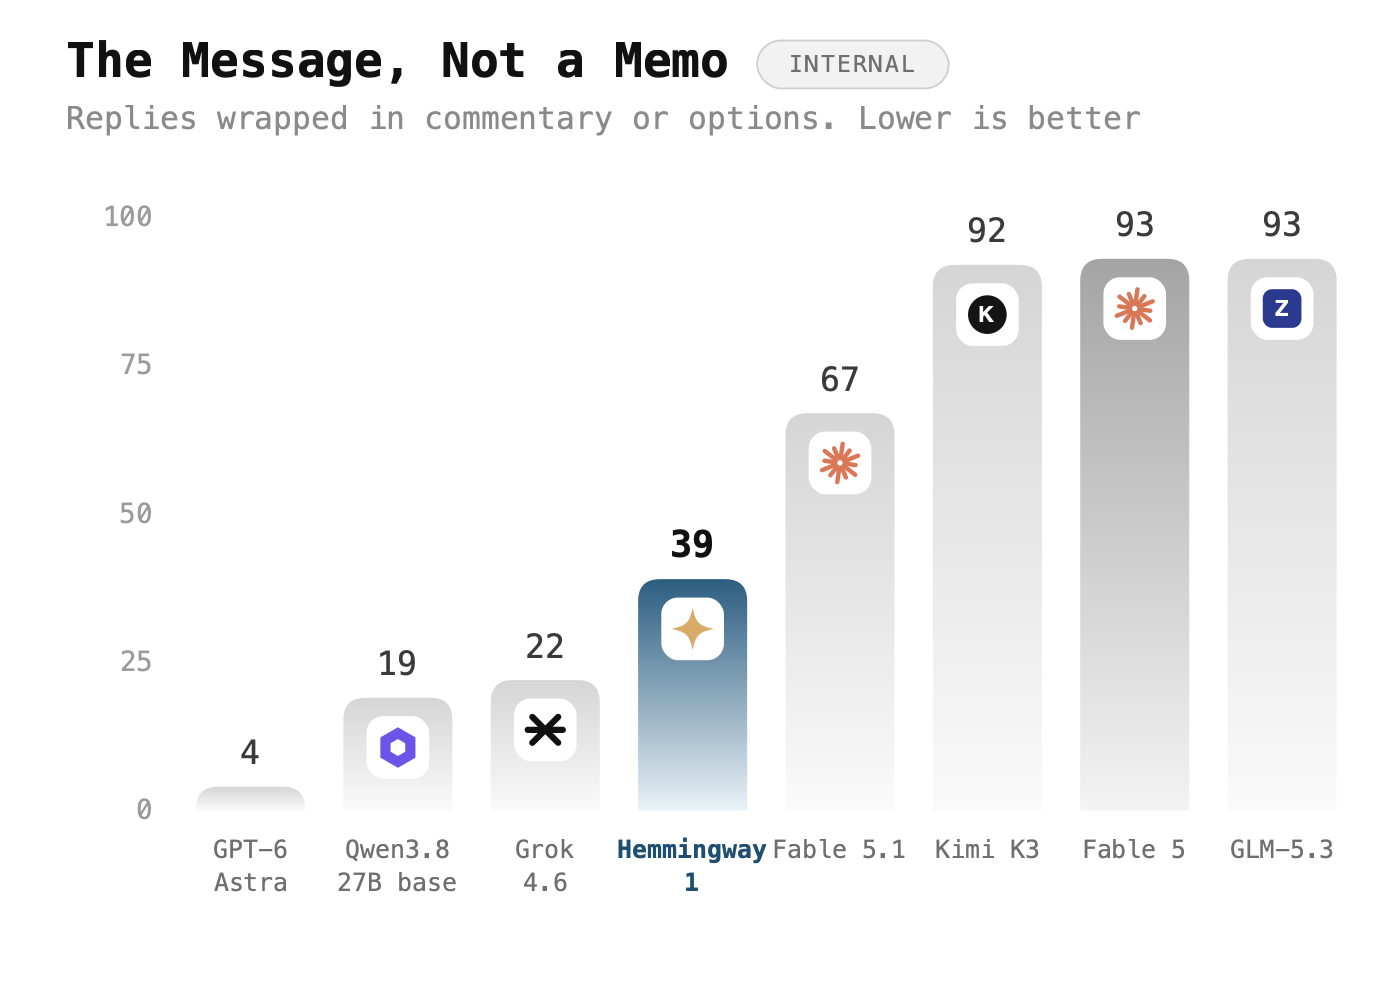
|
| 36 |
|
| 37 |

|
| 38 |
|
| 39 |
-
|
| 40 |
-
|
| 41 |
|
| 42 |
-
## And it
|
| 43 |
|
| 44 |
Same matchups, one question: which of these two did a person write?
|
| 45 |
|
| 46 |

|
| 47 |
|
| 48 |
-
Twenty-six points clear of the next model.
|
| 49 |
-
Hemmingway-1, and it's the number we're proudest of.
|
| 50 |
|
| 51 |
## Where it wins
|
| 52 |
|
| 53 |
-
Broken down by what you
|
| 54 |
-
|
| 55 |
|
| 56 |

|
| 57 |
|
| 58 |
-
|
| 59 |
-
|
| 60 |
Hemmingway-1 gets 72%.
|
| 61 |
|
| 62 |
-
|
| 63 |
-
|
| 64 |
|
| 65 |
## You get the message, not a memo
|
| 66 |
|
|
@@ -73,7 +69,7 @@ Fable 5, GLM-5.3 and Kimi K3 do it to more than nine replies in ten.
|
|
| 73 |
|
| 74 |
## It reads the room
|
| 75 |
|
| 76 |
-
EQ-Bench 4 is not ours. It
|
| 77 |
by its own harness.
|
| 78 |
|
| 79 |

|
|
@@ -88,12 +84,6 @@ best model on the board.
|
|
| 88 |
Level with Kimi K3, comfortably past Qwen3.8-Max and DeepSeek V4 Pro, and 504
|
| 89 |
points above the model we started from.
|
| 90 |
|
| 91 |
-
## How it got here
|
| 92 |
-
|
| 93 |
-
Every round, from our first 9B to this one.
|
| 94 |
-
|
| 95 |
-

|
| 96 |
-
|
| 97 |
## Run it
|
| 98 |
|
| 99 |
```bash
|
|
@@ -118,15 +108,14 @@ print(tok.decode(out[0][ids.shape[-1]:], skip_special_tokens=True))
|
|
| 118 |
| Parameters | 27B |
|
| 119 |
| Built on | Qwen3.8-27B |
|
| 120 |
| Context | 262,144 tokens |
|
| 121 |
-
| Licence | Apache-2.0
|
| 122 |
|
| 123 |
## The fine print
|
| 124 |
|
| 125 |
CommunicationBench, Human-Likeness and StoryBench are our own benchmarks. We
|
| 126 |
-
built them, we ran them, and we
|
| 127 |
-
blind and run in both orders so position
|
| 128 |
-
different model from the ones being judged. EQ-Bench 4
|
| 129 |
-
not ours.
|
| 130 |
|
| 131 |
-
It
|
| 132 |
decide anything medical, legal or financial.
|
|
|
|
| 18 |
|
| 19 |
**[Try it →](https://hemmingway.io)** · **[Mac and Android apps →](https://hemmingway.io/download)** · **[Code →](https://github.com/lukeckprobierts/Hemmingway-1)**
|
| 20 |
|
| 21 |
+
Ask most models for a text to your landlord and you get three options, a
|
|
|
|
| 22 |
preamble, and a paragraph explaining the options. Hemmingway-1 gives you the
|
| 23 |
text.
|
| 24 |
|
| 25 |
+
We built it for the writing people do every day. Messages, emails, the awkward
|
| 26 |
+
note to a colleague, the thing you have been putting off. Then we tested it
|
| 27 |
+
against the biggest models in the world at exactly that, and it came first.
|
|
|
|
|
|
|
| 28 |
|
| 29 |
## It writes the best everyday messages of any model we tested
|
| 30 |
|
|
|
|
| 33 |
|
| 34 |

|
| 35 |
|
| 36 |
+
It beats Fable 5.1, and it beats GPT-6 Astra by fifty points. Kimi K3, GLM-5.3,
|
| 37 |
+
Grok 4.6 and DeepSeek V4 Pro all come in behind it. At 27B.
|
| 38 |
|
| 39 |
+
## And it is the one that sounds like a person
|
| 40 |
|
| 41 |
Same matchups, one question: which of these two did a person write?
|
| 42 |
|
| 43 |

|
| 44 |
|
| 45 |
+
Twenty-six points clear of the next model.
|
|
|
|
| 46 |
|
| 47 |
## Where it wins
|
| 48 |
|
| 49 |
+
Broken down by what you asked for. Higher means the judge more often took its
|
| 50 |
+
version for the one a person wrote.
|
| 51 |
|
| 52 |

|
| 53 |
|
| 54 |
+
It wins money and admin, work, the hard asks you keep rewriting, and talking
|
| 55 |
+
someone round. Most of them by a wide margin. GPT-6 Astra gets 9% on hard asks.
|
| 56 |
Hemmingway-1 gets 72%.
|
| 57 |
|
| 58 |
+
It loses on hostile storytelling and long story turns. The story models are
|
| 59 |
+
better at those.
|
| 60 |
|
| 61 |
## You get the message, not a memo
|
| 62 |
|
|
|
|
| 69 |
|
| 70 |
## It reads the room
|
| 71 |
|
| 72 |
+
EQ-Bench 4 is not ours. It is the public emotional-intelligence benchmark, run
|
| 73 |
by its own harness.
|
| 74 |
|
| 75 |

|
|
|
|
| 84 |
Level with Kimi K3, comfortably past Qwen3.8-Max and DeepSeek V4 Pro, and 504
|
| 85 |
points above the model we started from.
|
| 86 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 87 |
## Run it
|
| 88 |
|
| 89 |
```bash
|
|
|
|
| 108 |
| Parameters | 27B |
|
| 109 |
| Built on | Qwen3.8-27B |
|
| 110 |
| Context | 262,144 tokens |
|
| 111 |
+
| Licence | Apache-2.0, yours to use, including commercially |
|
| 112 |
|
| 113 |
## The fine print
|
| 114 |
|
| 115 |
CommunicationBench, Human-Likeness and StoryBench are our own benchmarks. We
|
| 116 |
+
built them, we ran them, and we are telling you that up front. Every matchup was
|
| 117 |
+
blind and run in both orders so position could not sway it, and the judge was a
|
| 118 |
+
different model from the ones being judged. EQ-Bench 4 is not ours.
|
|
|
|
| 119 |
|
| 120 |
+
It is English-first. It can be wrong and still sound certain. Do not use it to
|
| 121 |
decide anything medical, legal or financial.
|
charts/categories-heatmap.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
charts/wrapped.png
CHANGED
|
|