


DSpark v2 head, full vocab: 2.62x vs no drafter, 4.67 tok/step
Browse files- README.md +170 -0
- acceptance-by-position.png +0 -0
- config.json +68 -0
- model.safetensors +3 -0
README.md
ADDED
|
@@ -0,0 +1,170 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
base_model:
|
| 4 |
+
- Qwen/Qwen3.6-27B
|
| 5 |
+
library_name: transformers
|
| 6 |
+
tags:
|
| 7 |
+
- speculative-decoding
|
| 8 |
+
- dspark
|
| 9 |
+
- draft-model
|
| 10 |
+
- vllm
|
| 11 |
+
- qwen3
|
| 12 |
+
datasets:
|
| 13 |
+
- nvidia/Open-SWE-Traces
|
| 14 |
+
- greghavens/gpt-5.6-sol-coding-and-debugging-traces
|
| 15 |
+
- greghavens/fable-5-coding-and-debugging-traces
|
| 16 |
+
- greghavens/glm-5.2-coding-and-debugging-traces
|
| 17 |
+
- Roman1111111/claude-sonnet-4.6-120000x
|
| 18 |
+
- qsardor/Claude-Sonnet-Opus
|
| 19 |
+
- ianncity/GLM-5.2-Conversation
|
| 20 |
+
---
|
| 21 |
+
|
| 22 |
+
# Qwen3.6-27B-DSpark
|
| 23 |
+
|
| 24 |
+
A DSpark draft head for **Qwen3.6-27B**, trained on a mixed agentic + general-chat
|
| 25 |
+
corpus. Drops into stock vLLM as a `--speculative-config`.
|
| 26 |
+
|
| 27 |
+
**2.62× faster decoding than no speculation**, **1.48× faster than the upstream
|
| 28 |
+
DSpark head**, and **1.27× faster than Qwen3.6's built-in MTP**, at **4.67 tokens
|
| 29 |
+
accepted per target pass**. Measured over 96 held-out prompts spanning agentic
|
| 30 |
+
tool-use, coding and general chat, with generation length and sampling fixed so
|
| 31 |
+
wall-clock is directly comparable.
|
| 32 |
+
|
| 33 |
+
> **Two builds of this head.** This is the **full-vocabulary** build (8.20 GiB) —
|
| 34 |
+
> prefer it for long-context agentic work. A **vocabulary-truncated** build of the
|
| 35 |
+
> same trained weights is at
|
| 36 |
+
> [`abstract-extraordinary/Qwen3.6-27B-DSpark-49k`](https://huggingface.co/abstract-extraordinary/Qwen3.6-27B-DSpark-49k)
|
| 37 |
+
> (6.20 GiB, faster on short prompts, no throughput advantage on long ones). See
|
| 38 |
+
> [Vocabulary variants](#vocabulary-variants).
|
| 39 |
+
|
| 40 |
+
## Usage
|
| 41 |
+
|
| 42 |
+
```bash
|
| 43 |
+
vllm serve unsloth/Qwen3.6-27B-NVFP4 \
|
| 44 |
+
--speculative-config '{"method":"dspark",
|
| 45 |
+
"model":"abstract-extraordinary/Qwen3.6-27B-DSpark",
|
| 46 |
+
"num_speculative_tokens":8}' \
|
| 47 |
+
--trust-remote-code
|
| 48 |
+
```
|
| 49 |
+
|
| 50 |
+
Use `num_speculative_tokens: 8`. The head drafts blocks of exactly 8 tokens
|
| 51 |
+
(`block_size=8`), so a smaller value leaves trained capacity unused and a larger one
|
| 52 |
+
asks it to predict positions it has never seen.
|
| 53 |
+
|
| 54 |
+
## Benchmarks
|
| 55 |
+
|
| 56 |
+
**96 held-out prompts across 8 workload buckets.** All five configurations ran in a
|
| 57 |
+
single session against the same prompts, identical but for `--speculative-config`,
|
| 58 |
+
each emitting exactly 300 greedy tokens (`temperature=0`, `min_tokens=max_tokens`,
|
| 59 |
+
`ignore_eos`) so wall-clock is directly comparable. Target `unsloth/Qwen3.6-27B-NVFP4`,
|
| 60 |
+
single GB10, concurrency 1. Every figure is a draft-weighted pool over the whole run,
|
| 61 |
+
not a mean over prompts.
|
| 62 |
+
|
| 63 |
+
| config | tok/s | tok/step | accept | vs no drafter |
|
| 64 |
+
|---|---|---|---|---|
|
| 65 |
+
| no drafter | 10.05 | — | — | 1.00× |
|
| 66 |
+
| [`satgeze/Qwen3.6-27B-DSpark`](https://huggingface.co/satgeze/Qwen3.6-27B-DSpark) (upstream, untrained) | 17.74 | 2.86 | 23.4% | 1.77× |
|
| 67 |
+
| Qwen3.6 built-in MTP (3 tokens) | 20.76 | 3.25 | 75.1% | 2.07× |
|
| 68 |
+
| **this model** | **26.28** | **4.67** | 46.2% | **2.62×** |
|
| 69 |
+
| [same head, 49k vocab](https://huggingface.co/abstract-extraordinary/Qwen3.6-27B-DSpark-49k) | 28.18 | 4.66 | 46.0% | 2.80× |
|
| 70 |
+
|
| 71 |
+
The upstream head was run at **both** `num_speculative_tokens: 8` and `15` (its own
|
| 72 |
+
`block_size`); 8 was faster (17.74 vs 17.07 tok/s) and is quoted here, so the
|
| 73 |
+
baseline is shown at its stronger setting.
|
| 74 |
+
|
| 75 |
+
MTP shows a much higher acceptance *percentage* while being slower. The two are not
|
| 76 |
+
in tension: MTP drafts 3 tokens per pass and this head drafts 8, so a higher hit
|
| 77 |
+
rate on fewer guesses still yields fewer accepted tokens per step (3.25 vs 4.67).
|
| 78 |
+
Tokens per step is the quantity that converts into wall-clock.
|
| 79 |
+
|
| 80 |
+
By workload:
|
| 81 |
+
|
| 82 |
+
| bucket | mean prompt tok | no drafter | this model | speedup |
|
| 83 |
+
|---|---|---|---|---|
|
| 84 |
+
| general chat (ianncity) | 125 | 11.10 | 34.51 | 3.11× |
|
| 85 |
+
| agentic (kimi-k3) | 1,000 | 10.92 | 33.11 | 3.03× |
|
| 86 |
+
| agentic (fable-5) | 1,446 | 10.84 | 32.62 | 3.01× |
|
| 87 |
+
| general chat (qsardor) | 68 | 11.11 | 32.13 | 2.89× |
|
| 88 |
+
| general/code/math (sonnet-4.6) | 93 | 11.11 | 30.95 | 2.79× |
|
| 89 |
+
| agentic (glm-5.2) | 5,770 | 9.78 | 23.48 | 2.40× |
|
| 90 |
+
| agentic (gpt-5.6-sol) | 9,752 | 8.92 | 20.59 | 2.31× |
|
| 91 |
+
| agentic SWE (nvidia) | 15,841 | 7.82 | 16.67 | 2.13× |
|
| 92 |
+
|
| 93 |
+
Absolute tok/s tracks prompt length rather than head quality — long prompts spend
|
| 94 |
+
most of their wall-clock in prefill, which speculation does not accelerate. The
|
| 95 |
+
speedup column is the like-for-like comparison. The kimi-k3 bucket was excluded from
|
| 96 |
+
training entirely and is a clean generalisation probe.
|
| 97 |
+
|
| 98 |
+
### Acceptance by draft position
|
| 99 |
+
|
| 100 |
+

|
| 101 |
+
|
| 102 |
+
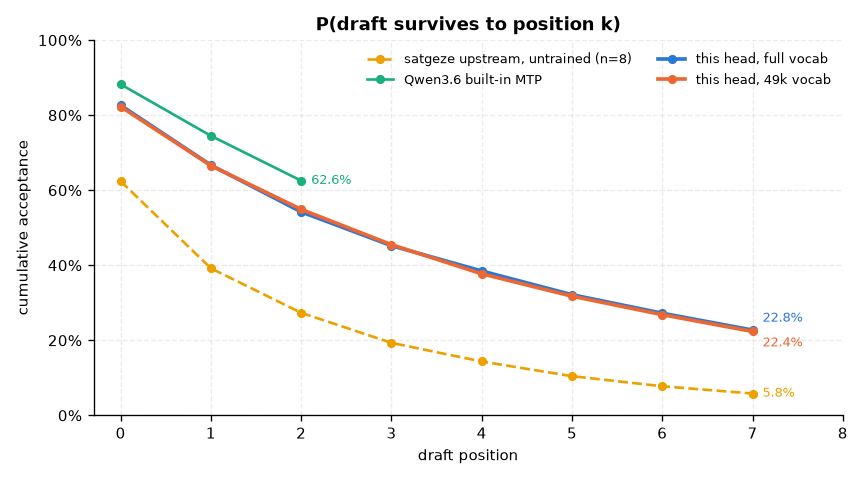
Acceptance decays *multiplicatively*: surviving to position 3 means winning four
|
| 103 |
+
consecutive rejection tests. That compounding is why a few points at position 0 turn
|
| 104 |
+
into a large difference in tokens per step, and it is what separates this head from
|
| 105 |
+
the untrained upstream one. Upstream starts at a respectable 62.4% at position 0 but
|
| 106 |
+
halves roughly every two positions to 5.8% by position 7; this head starts at 82.7%
|
| 107 |
+
and still retains 22.8%.
|
| 108 |
+
|
| 109 |
+
## Vocabulary variants
|
| 110 |
+
|
| 111 |
+
| | this model | [`-49k`](https://huggingface.co/abstract-extraordinary/Qwen3.6-27B-DSpark-49k) |
|
| 112 |
+
|---|---|---|
|
| 113 |
+
| draft vocabulary | 248,320 (full) | 49,167 |
|
| 114 |
+
| size on disk | 8.20 GiB | 6.20 GiB |
|
| 115 |
+
| tok/s (96 prompts) | 26.28 | 28.18 |
|
| 116 |
+
| tok/step | 4.67 | 4.66 |
|
| 117 |
+
| best for | long-context agentic | short-prompt / chat-shaped |
|
| 118 |
+
|
| 119 |
+
Both are the **same trained weights**. The `-49k` build row-gathers `lm_head` and
|
| 120 |
+
`markov_w2` to the tokens the target actually emits — a post-hoc transform, not a
|
| 121 |
+
retrain. It is faster per decode step because the draft head streams its whole
|
| 122 |
+
weight set every step and a smaller head streams less. That saving is large on short
|
| 123 |
+
prompts and **disappears on long ones**, where prefill dominates wall-clock, while a
|
| 124 |
+
small acceptance cost remains. **If your prompts run to thousands of tokens, use
|
| 125 |
+
this full-vocab build.**
|
| 126 |
+
|
| 127 |
+
## Training
|
| 128 |
+
|
| 129 |
+
Assistant turns **regenerated by the target model itself** (temperature 0.7, top-p
|
| 130 |
+
0.95), so the head learns the distribution it will actually have to predict — not the
|
| 131 |
+
distribution of whatever model produced the original traces.
|
| 132 |
+
|
| 133 |
+
14,707 conversations from seven sources: fresh `nvidia/Open-SWE-Traces` windows, three
|
| 134 |
+
agentic trace sets, and three general-chat sets. 44.93M supervised tokens at 46.6% loss
|
| 135 |
+
density (mean 3,055 per sample). 600 steps in 6.3 h on one node, lr 6e-4, 384 anchors,
|
| 136 |
+
`block_size=8`; final loss 0.73 from ~1.05. Held-out offline accepted length was
|
| 137 |
+
monotone across all 20 checkpoints and plateaued at steps 540–600, so the run
|
| 138 |
+
converged rather than being truncated.
|
| 139 |
+
|
| 140 |
+
Held-out prompts were excluded from training by content fingerprint before harvesting,
|
| 141 |
+
train/val shard offsets verified disjoint, and the publishers' own splits respected
|
| 142 |
+
where they exist. All evaluation above uses only held-out samples.
|
| 143 |
+
|
| 144 |
+
## Limitations
|
| 145 |
+
|
| 146 |
+
- **Correctness is unverified — not failed.** Speculative decoding is
|
| 147 |
+
distribution-preserving under rejection sampling, but we could not run a
|
| 148 |
+
token-identity check: greedy decoding is not reproducible on this stack run-to-run
|
| 149 |
+
(a target-only run matches *itself* on 3 of 12 prompts, because prefix caching and
|
| 150 |
+
batch composition change the numerical path). This head adds no measurable
|
| 151 |
+
divergence beyond that baseline, which is weaker evidence than a proof.
|
| 152 |
+
- **No live-traffic measurement.** Every number here is a held-out benchmark at
|
| 153 |
+
concurrency 1. Held-out and live figures have disagreed before for this line of
|
| 154 |
+
heads.
|
| 155 |
+
- **Single hardware.** Benchmarked only on one GB10 with `unsloth/Qwen3.6-27B-NVFP4`.
|
| 156 |
+
Speculative-decoding economics are bandwidth-dependent; expect different ratios
|
| 157 |
+
elsewhere.
|
| 158 |
+
- Acceptance is far from uniform across workloads (40.5–60.4% by bucket). Long agentic
|
| 159 |
+
prompts draft best per step but gain least in wall-clock, because prefill dominates
|
| 160 |
+
there.
|
| 161 |
+
- Run-to-run spread on this benchmark is about 1% on pooled tok/s (measured by
|
| 162 |
+
repeating the no-drafter and MTP configurations on two vLLM builds). Differences
|
| 163 |
+
smaller than that should not be read as real.
|
| 164 |
+
|
| 165 |
+
## Credits
|
| 166 |
+
|
| 167 |
+
Initialised from [`satgeze/Qwen3.6-27B-DSpark`](https://huggingface.co/satgeze/Qwen3.6-27B-DSpark).
|
| 168 |
+
DSpark architecture from *DSpark: Confidence-Scheduled Speculative Decoding with
|
| 169 |
+
Semi-Autoregressive Generation*. Training data from NVIDIA and the community dataset
|
| 170 |
+
authors listed above.
|
acceptance-by-position.png
ADDED
|
config.json
ADDED
|
@@ -0,0 +1,68 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3DSparkModel"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"attn_output_gate": true,
|
| 8 |
+
"block_size": 8,
|
| 9 |
+
"bos_token_id": 248044,
|
| 10 |
+
"confidence_head_with_markov": true,
|
| 11 |
+
"dtype": "bfloat16",
|
| 12 |
+
"enable_confidence_head": true,
|
| 13 |
+
"eos_token_id": 248044,
|
| 14 |
+
"full_attention_interval": 4,
|
| 15 |
+
"head_dim": 128,
|
| 16 |
+
"hidden_act": "silu",
|
| 17 |
+
"hidden_size": 5120,
|
| 18 |
+
"initializer_range": 0.02,
|
| 19 |
+
"intermediate_size": 17408,
|
| 20 |
+
"layer_types": [
|
| 21 |
+
"full_attention",
|
| 22 |
+
"full_attention",
|
| 23 |
+
"full_attention",
|
| 24 |
+
"full_attention",
|
| 25 |
+
"full_attention"
|
| 26 |
+
],
|
| 27 |
+
"linear_conv_kernel_dim": 4,
|
| 28 |
+
"linear_key_head_dim": 128,
|
| 29 |
+
"linear_num_key_heads": 16,
|
| 30 |
+
"linear_num_value_heads": 48,
|
| 31 |
+
"linear_value_head_dim": 128,
|
| 32 |
+
"mamba_ssm_dtype": "float32",
|
| 33 |
+
"markov_head_type": "vanilla",
|
| 34 |
+
"markov_rank": 256,
|
| 35 |
+
"mask_token_id": 248200,
|
| 36 |
+
"max_position_embeddings": 262144,
|
| 37 |
+
"max_window_layers": 28,
|
| 38 |
+
"model_type": "qwen3",
|
| 39 |
+
"mtp_num_hidden_layers": 1,
|
| 40 |
+
"mtp_use_dedicated_embeddings": false,
|
| 41 |
+
"num_anchors": 384,
|
| 42 |
+
"num_attention_heads": 32,
|
| 43 |
+
"num_hidden_layers": 5,
|
| 44 |
+
"num_key_value_heads": 8,
|
| 45 |
+
"num_target_layers": 64,
|
| 46 |
+
"output_gate_type": "swish",
|
| 47 |
+
"pad_token_id": null,
|
| 48 |
+
"partial_rotary_factor": 1.0,
|
| 49 |
+
"rms_norm_eps": 1e-06,
|
| 50 |
+
"rope_parameters": {
|
| 51 |
+
"partial_rotary_factor": 1.0,
|
| 52 |
+
"rope_theta": 10000000,
|
| 53 |
+
"rope_type": "default"
|
| 54 |
+
},
|
| 55 |
+
"sliding_window": null,
|
| 56 |
+
"target_layer_ids": [
|
| 57 |
+
1,
|
| 58 |
+
16,
|
| 59 |
+
31,
|
| 60 |
+
46,
|
| 61 |
+
61
|
| 62 |
+
],
|
| 63 |
+
"tie_word_embeddings": false,
|
| 64 |
+
"transformers_version": "5.14.1",
|
| 65 |
+
"use_cache": true,
|
| 66 |
+
"use_sliding_window": false,
|
| 67 |
+
"vocab_size": 248320
|
| 68 |
+
}
|
model.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2f0432e860cdd51dbbc4ab848af74e66383b08240d2f27bf4706f52e3405c215
|
| 3 |
+
size 8800317146
|