

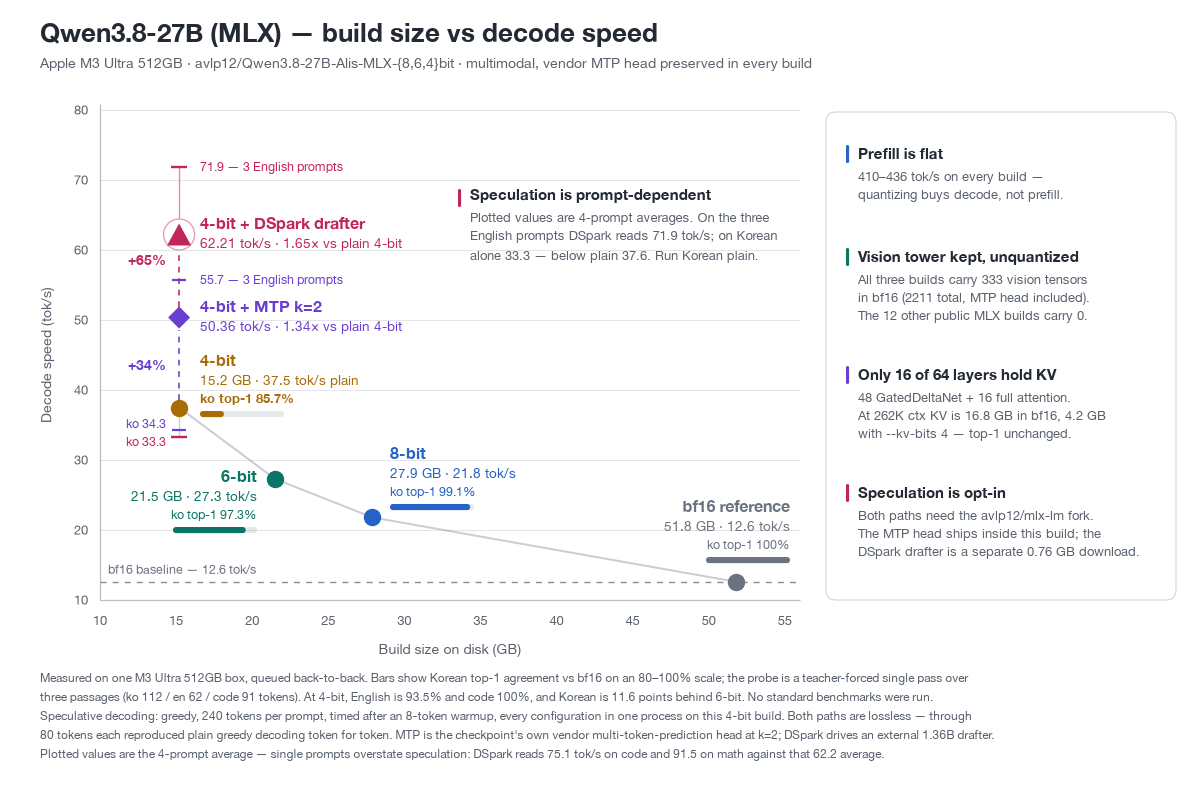
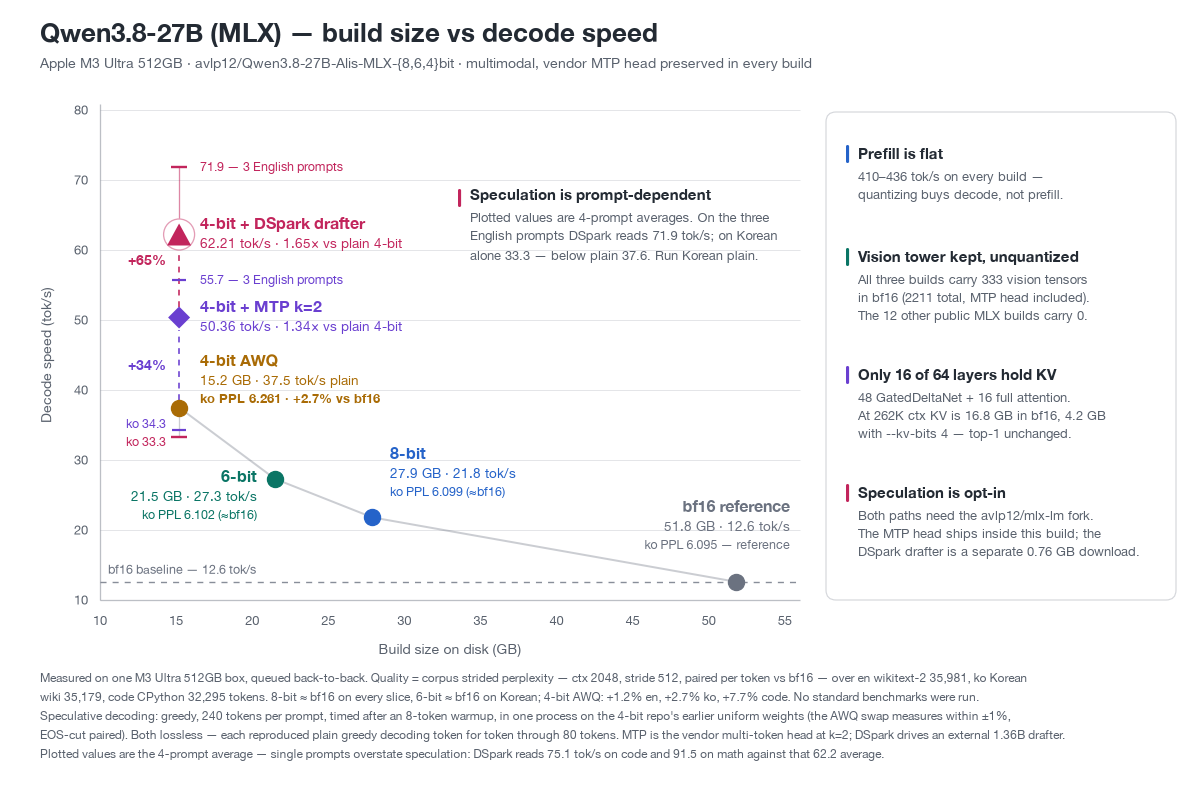
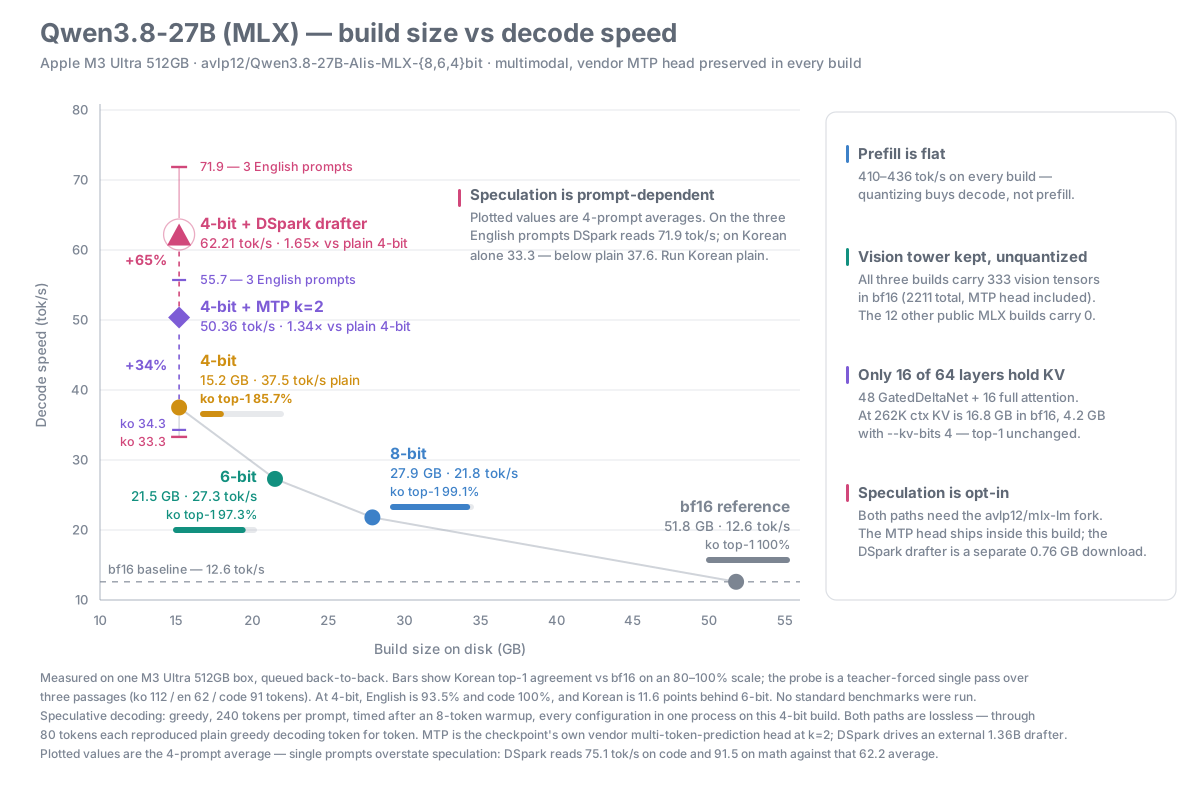
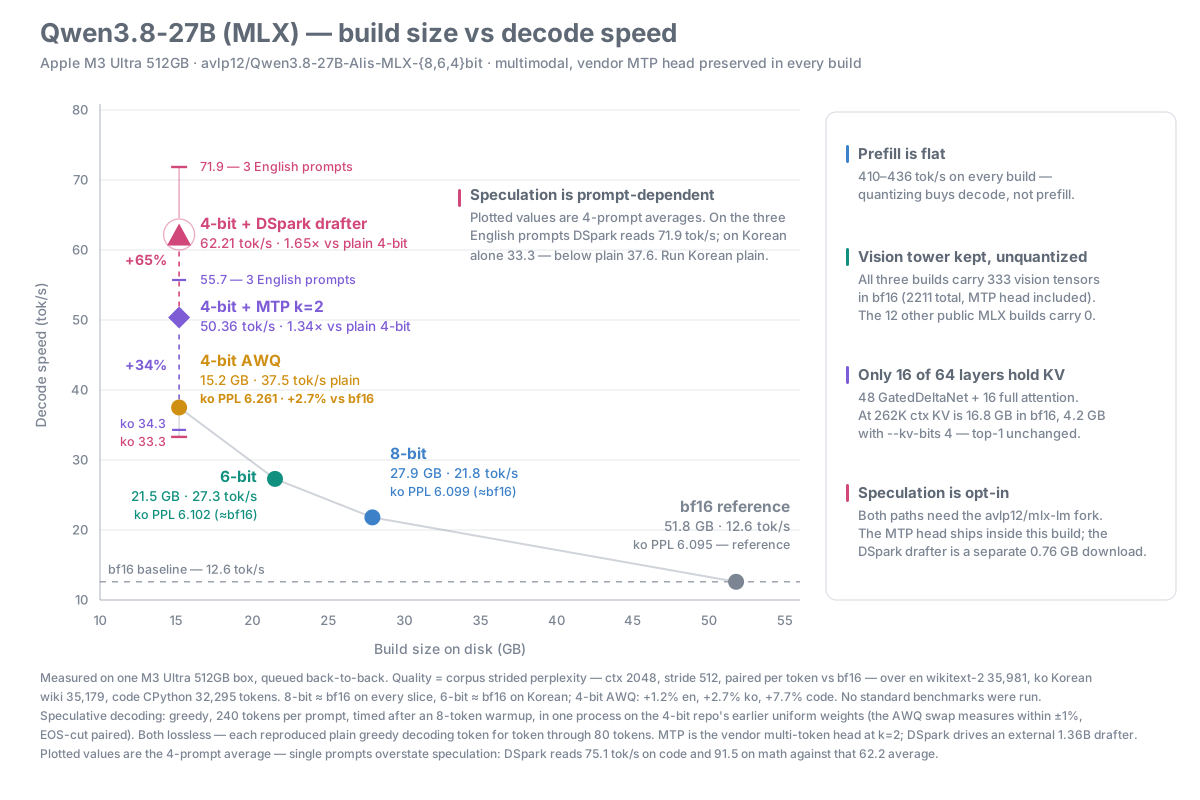
Quality: corpus strided PPL replaces low-power top-1 probe; spec-table harness footnotes; chart updated
Browse files- README.md +35 -31
- assets/builds.png +2 -2
- assets/builds.svg +11 -19
- assets/make_builds_png.py +16 -24
README.md
CHANGED
|
@@ -17,22 +17,22 @@ tags:
|
|
| 17 |
|
| 18 |
# Qwen3.8-27B-Alis-MLX-6bit
|
| 19 |
|
| 20 |
-
 for Apple silicon, with the **vision tower and the MTP head both preserved**. 21.5 GB on disk, 27.3 tok/s decode,
|
| 23 |
|
| 24 |
## At a glance
|
| 25 |
|
| 26 |
-
| Build | Size (GB) | Decode (tok/s) | Prefill (tok/s) | Peak RAM (GB) |
|
| 27 |
-
|---|---|---|---|---|---|
|
| 28 |
-
| bf16 reference | 51.8 | 12.6 | 410 | 51.1 |
|
| 29 |
-
| 8-bit | 27.9 | 21.8 | 429 | 28.2 |
|
| 30 |
-
| 6-bit (this repo) | 21.5 | 27.3 | 424 | 21.9 |
|
| 31 |
-
| 4-bit | 15.2 | 37.5 | 436 | 15.6 |
|
| 32 |
|
| 33 |
-
|
| 34 |
|
| 35 |
-
Against bf16 this build is 42% of the size at 2.17× the decode speed. Against the 8-bit build it is 23% smaller and 25% faster,
|
| 36 |
|
| 37 |
## The vision tower is intact
|
| 38 |
|
|
@@ -74,13 +74,13 @@ python -m mlx_vlm.generate \
|
|
| 74 |
--prompt "Describe every shape in this image, with its color and position."
|
| 75 |
```
|
| 76 |
|
| 77 |
-
Verified end to end before publishing: I fed a hand-drawn test image (red circle top left, blue square top right, green triangle at the bottom) to the 4-bit build of this set and it described every color, shape, and position correctly. The vision path is the same bf16 tower in all three builds.
|
| 78 |
|
| 79 |
## Which build should I use?
|
| 80 |
|
| 81 |
-
- **6-bit (this repo, 21.5 GB)** — the default I would reach for first.
|
| 82 |
-
- **8-bit (27.9 GB)** — the fidelity choice. Take it when the output is the product and the machine is 48 GB or larger:
|
| 83 |
-
- **4-bit (15.2 GB)** — the reach build, and the fastest at 37.5 tok/s. Take it when the model would otherwise not fit
|
| 84 |
|
| 85 |
All three carry the same vision tower and the same MTP head. The choice is purely language-model precision.
|
| 86 |
|
|
@@ -148,7 +148,7 @@ mlx_lm.generate --model avlp12/Qwen3.8-27B-Alis-MLX-6bit \
|
|
| 148 |
--max-tokens 512
|
| 149 |
```
|
| 150 |
|
| 151 |
-
**Every speculative figure below was measured on the 4-bit build of this set
|
| 152 |
|
| 153 |
| Configuration, 4-bit build | 4-prompt avg | 3 English prompts | chat | code | math | ko |
|
| 154 |
|---|---|---|---|---|---|---|
|
|
@@ -158,6 +158,8 @@ mlx_lm.generate --model avlp12/Qwen3.8-27B-Alis-MLX-6bit \
|
|
| 158 |
|
| 159 |
Lossless on that build: all four prompts reproduced plain greedy decoding **token for token through 80 tokens**.
|
| 160 |
|
|
|
|
|
|
|
| 161 |
**Why this build cannot inherit those multiples.** What lifted them is a small-M quantized-GEMM kernel that the fork now enables from inside `mlx_lm.utils.load()`. It fires only in the multi-token verification window (M = 6..8) and only on **4-bit, group-64** weights, so it never engages at 6 bits; plain decode at M = 1 is untouched on every build either way. The gap it fills is upstream: [ml-explore/mlx#4265](https://github.com/ml-explore/mlx/issues/4265). Set `MLXLM_NO_FAST_QMM=1` to opt out.
|
| 162 |
|
| 163 |
**This 6-bit build has never been measured under either speculative path** — the MTP head is present, the fork drives it, and the drafter below accepts it as a target, but I have no number for any of the three rows on this build. Start at k=2 and measure your own workload rather than interpolating from a table taken on a different precision.
|
|
@@ -212,7 +214,7 @@ Speculative decoding pays off in proportion to how predictable the continuation
|
|
| 212 |
|
| 213 |
The hybrid layout is why long context is cheap on this model. Only the **16 full-attention layers** hold a growing KV cache; the 48 GatedDeltaNet layers carry a fixed-size recurrent state instead. With 4 KV heads at head_dim 256, that comes to **64 KB per token** in bf16 across the whole model. That per-token figure is a property of the layout and is identical in all three builds.
|
| 214 |
|
| 215 |
-
Measured at 16K context on the 4-bit and 8-bit builds, as whole-process peaks — so they include activations and prefill buffers, not the cache alone. This 6-bit build was not measured; it sits between the two columns.
|
| 216 |
|
| 217 |
| KV precision | Peak RAM (GB), 4-bit build | Peak RAM (GB), 8-bit build | top-1 agreement |
|
| 218 |
|---|---|---|---|
|
|
@@ -249,31 +251,33 @@ This is a flat, data-free round-to-nearest recipe: no calibration set, no activa
|
|
| 249 |
|
| 250 |
## Quality
|
| 251 |
|
| 252 |
-
|
| 253 |
|
| 254 |
-
|
|
| 255 |
-
|---|---|---|---|
|
| 256 |
-
|
|
| 257 |
-
|
|
| 258 |
-
|
|
| 259 |
-
|
|
| 260 |
|
| 261 |
-
This build is where the size curve and the quality curve are still on speaking terms.
|
| 262 |
|
| 263 |
Three honest caveats:
|
| 264 |
|
| 265 |
-
- **
|
| 266 |
-
- **
|
| 267 |
-
- **
|
|
|
|
|
|
|
| 268 |
|
| 269 |
## Limitations and caveats
|
| 270 |
|
| 271 |
-
- **
|
| 272 |
-
- **No standard benchmarks were run.** There are no MMLU, GSM8K, or HumanEval numbers here, and none should be inferred from the
|
| 273 |
- **Vision quality is unquantified.** The tower is preserved bit-exact and verified to work on a shapes probe. That is a functional check, not a VQA evaluation. No image benchmark was run at any bit-width.
|
| 274 |
- **MTP and KV-cache figures come from the neighboring builds.** This build was not measured on either axis; the head and the layout are present and identical, the numbers are not.
|
| 275 |
-
- **Shape-dependent numerics.** The hybrid stack takes different kernel paths depending on the shape of the input it receives —
|
| 276 |
-
- **Long-form reasoning is unprobed.**
|
| 277 |
|
| 278 |
## License and attribution
|
| 279 |
|
|
|
|
| 17 |
|
| 18 |
# Qwen3.8-27B-Alis-MLX-6bit
|
| 19 |
|
| 20 |
+

|
| 21 |
|
| 22 |
+
A 6-bit MLX quantization of [Qwen/Qwen3.8-27B](https://huggingface.co/Qwen/Qwen3.8-27B) for Apple silicon, with the **vision tower and the MTP head both preserved**. 21.5 GB on disk, 27.3 tok/s decode, Korean corpus perplexity **statistically indistinguishable from the bf16 original** (6.1018 vs 6.0954, paired over 35K tokens), and only hairline — though measurable — excesses on English and code. This is the balanced build of the set: it fits a 32 GB Mac and keeps non-English output intact.
|
| 23 |
|
| 24 |
## At a glance
|
| 25 |
|
| 26 |
+
| Build | Size (GB) | Decode (tok/s) | Prefill (tok/s) | Peak RAM (GB) | PPL en / ko / code |
|
| 27 |
+
|---|---|---|---|---|---|
|
| 28 |
+
| bf16 reference | 51.8 | 12.6 | 410 | 51.1 | 5.7734 / 6.0954 / 1.6813 |
|
| 29 |
+
| 8-bit | 27.9 | 21.8 | 429 | 28.2 | 5.7760 / 6.0987 / 1.6815 |
|
| 30 |
+
| 6-bit (this repo) | 21.5 | 27.3 | 424 | 21.9 | 5.7924 / 6.1018 / 1.6854 |
|
| 31 |
+
| 4-bit (AWQ) | 15.2 | 37.5 | 436 | 15.6 | 5.8450 / 6.2609 / 1.8105 |
|
| 32 |
|
| 33 |
+
Speed and RAM were measured on one Apple M3 Ultra (512 GB unified memory), all builds queued back to back in a single batch so they share machine state; the 4-bit row of that batch was that repo's earlier uniform release, and its AWQ replacement is the same size with plain decode re-measured at 37.7 tok/s. Peak RAM is the load-plus-probe peak at short context; add KV cache for your own context length (see below). Perplexity is corpus-scale strided PPL — ctx 2048, stride 512 — described in the quality section.
|
| 34 |
|
| 35 |
+
Against bf16 this build is 42% of the size at 2.17× the decode speed. Against the 8-bit build it is 23% smaller and 25% faster, and the paired corpus test prices that step at +0.28% PPL on English and +0.23% on code — both significant, both hairline — with Korean not separable at all.
|
| 36 |
|
| 37 |
## The vision tower is intact
|
| 38 |
|
|
|
|
| 74 |
--prompt "Describe every shape in this image, with its color and position."
|
| 75 |
```
|
| 76 |
|
| 77 |
+
Verified end to end before publishing: I fed a hand-drawn test image (red circle top left, blue square top right, green triangle at the bottom) to the 4-bit build of this set — its earlier uniform release — and it described every color, shape, and position correctly. The vision path is the same bf16 tower in all three builds.
|
| 78 |
|
| 79 |
## Which build should I use?
|
| 80 |
|
| 81 |
+
- **6-bit (this repo, 21.5 GB)** — the default I would reach for first. Its Korean corpus PPL is statistically indistinguishable from bf16 — the axis where the 4-bit build pays its clearest user-visible cost — while staying 6.4 GB smaller and 25% faster than 8-bit. Peak was 21.9 GB at short context and it leaves usable headroom on a 32 GB Mac, which is the machine this build exists for.
|
| 82 |
+
- **8-bit (27.9 GB)** — the fidelity choice. Take it when the output is the product and the machine is 48 GB or larger: statistically indistinguishable from bf16 on every corpus slice. Also the right reference to compare a smaller build against.
|
| 83 |
+
- **4-bit (15.2 GB, now the AWQ recipe)** — the reach build, and the fastest at 37.5 tok/s. Take it when the model would otherwise not fit. Its corpus PPL runs +1.2% / +2.7% / +7.7% over bf16 on English / Korean / code — the one build whose cost is significant on every slice, and the Korean share of it is what the extra 6.3 GB here buys back.
|
| 84 |
|
| 85 |
All three carry the same vision tower and the same MTP head. The choice is purely language-model precision.
|
| 86 |
|
|
|
|
| 148 |
--max-tokens 512
|
| 149 |
```
|
| 150 |
|
| 151 |
+
**Every speculative figure below was measured on the 4-bit build of this set — its earlier uniform 4-bit weights — not on this one.** It is quoted here because it is what the fork's two speculative paths do on this checkpoint, and because the ordering between them is informative — but the multiples do not transfer to this build, for a reason spelled out under the table. Measured on one Apple M3 Ultra (512 GB), greedy, 240 tokens per prompt, timed after an 8-token warmup, every configuration in the same process, over four prompts: chat, code, math, and Korean.
|
| 152 |
|
| 153 |
| Configuration, 4-bit build | 4-prompt avg | 3 English prompts | chat | code | math | ko |
|
| 154 |
|---|---|---|---|---|---|---|
|
|
|
|
| 158 |
|
| 159 |
Lossless on that build: all four prompts reproduced plain greedy decoding **token for token through 80 tokens**.
|
| 160 |
|
| 161 |
+
**Three footnotes on this table, added after an audit of the measurement harness.** First, the harness did **not stop at end-of-sequence** — every run decoded a fixed 240 tokens, so on prompts whose answer ends early, part of the window measures post-termination behavior, and per-prompt figures are sensitive to what a build happens to do after its answer ends. Read the averages, not the per-prompt cells. Second, acceptance-rate comparisons **between builds** are only meaningful on a common token sequence, scored paired — each build free-running its own text measures the text as much as the build. Third, the 4-bit build measured here was that repo's earlier uniform release; the AWQ weights now hosted there measure **within ±1%** of it on both speculative paths under an EOS-cut paired protocol. A full re-measurement under the corrected harness is a separate track.
|
| 162 |
+
|
| 163 |
**Why this build cannot inherit those multiples.** What lifted them is a small-M quantized-GEMM kernel that the fork now enables from inside `mlx_lm.utils.load()`. It fires only in the multi-token verification window (M = 6..8) and only on **4-bit, group-64** weights, so it never engages at 6 bits; plain decode at M = 1 is untouched on every build either way. The gap it fills is upstream: [ml-explore/mlx#4265](https://github.com/ml-explore/mlx/issues/4265). Set `MLXLM_NO_FAST_QMM=1` to opt out.
|
| 164 |
|
| 165 |
**This 6-bit build has never been measured under either speculative path** — the MTP head is present, the fork drives it, and the drafter below accepts it as a target, but I have no number for any of the three rows on this build. Start at k=2 and measure your own workload rather than interpolating from a table taken on a different precision.
|
|
|
|
| 214 |
|
| 215 |
The hybrid layout is why long context is cheap on this model. Only the **16 full-attention layers** hold a growing KV cache; the 48 GatedDeltaNet layers carry a fixed-size recurrent state instead. With 4 KV heads at head_dim 256, that comes to **64 KB per token** in bf16 across the whole model. That per-token figure is a property of the layout and is identical in all three builds.
|
| 216 |
|
| 217 |
+
Measured at 16K context on the 4-bit and 8-bit builds (the 4-bit column on that repo's earlier uniform release), as whole-process peaks — so they include activations and prefill buffers, not the cache alone. This 6-bit build was not measured; it sits between the two columns.
|
| 218 |
|
| 219 |
| KV precision | Peak RAM (GB), 4-bit build | Peak RAM (GB), 8-bit build | top-1 agreement |
|
| 220 |
|---|---|---|---|
|
|
|
|
| 251 |
|
| 252 |
## Quality
|
| 253 |
|
| 254 |
+
Corpus-scale strided perplexity against fixed token streams: window 2048, stride 512, so every scored token sees up to 2048 tokens of left context. Three slices — **English** = wikitext-2 test (35,981 tokens), **Korean** = Korean Wikipedia (35,179 tokens), **code** = CPython standard library (32,295 tokens). Every build scores the same tokens in the same order, so build-to-build comparisons are paired per token, and significance is judged on the paired excess NLL with a blockwise standard error (512-token blocks) — roughly 16–20× the sensitivity of the probe this section used to carry.
|
| 255 |
|
| 256 |
+
| Build | en · wikitext-2 | ko · Korean wiki | code · CPython |
|
| 257 |
+
|---|---|---|---|
|
| 258 |
+
| bf16 reference | 5.7734 | 6.0954 | 1.6813 |
|
| 259 |
+
| 8-bit | 5.7760 | 6.0987 | 1.6815 |
|
| 260 |
+
| **6-bit (this repo)** | **5.7924** | **6.1018** | **1.6854** |
|
| 261 |
+
| 4-bit (AWQ) | 5.8450 | 6.2609 | 1.8105 |
|
| 262 |
|
| 263 |
+
This build is where the size curve and the quality curve are still on speaking terms. Against bf16, paired: **Korean is not separable at all** — the 95% CI on this build's Korean excess NLL includes zero — while English and code carry excesses the test can find but you will struggle to feel: +0.0033 and +0.0024 nats/token (+0.33% and +0.24% PPL). The 8-bit build is indistinguishable from bf16 on all three slices; the 4-bit AWQ build is significantly above on all three, at +1.2% / +2.7% / +7.7% — on Korean and code, a different quality class from this one.
|
| 264 |
|
| 265 |
Three honest caveats:
|
| 266 |
|
| 267 |
+
- **"Indistinguishable" means the test could not separate them at this sample size, not that they are identical.** A still larger corpus might resolve a Korean difference; 35K paired tokens did not.
|
| 268 |
+
- **Perplexity prices average next-token surprise, not task success.** It ranks the builds with real statistical power, but it is not a benchmark suite.
|
| 269 |
+
- **The hairline English and code excesses are significant but tiny.** Treat them as the honest price of this tier, not as a reason to step up to 8-bit — step up when you need the reference build, not because of 0.3%.
|
| 270 |
+
|
| 271 |
+
**Why this table changed.** Earlier revisions of this card ranked the builds with a top-1 agreement probe over three short passages (62–112 tokens). At that size the probe had no statistical power: its standard error ran several times the effects it claimed to rank, and on English it read the sign of a recipe difference **backwards**. It is removed rather than restated.
|
| 272 |
|
| 273 |
## Limitations and caveats
|
| 274 |
|
| 275 |
+
- **Perplexity is the only quality metric here.** It is corpus-scale (≈103K scored tokens, paired per token) and it replaced a probe that had no statistical power — but it is still average next-token surprise, not a task suite.
|
| 276 |
+
- **No standard benchmarks were run.** There are no MMLU, GSM8K, or HumanEval numbers here, and none should be inferred from the perplexity table.
|
| 277 |
- **Vision quality is unquantified.** The tower is preserved bit-exact and verified to work on a shapes probe. That is a functional check, not a VQA evaluation. No image benchmark was run at any bit-width.
|
| 278 |
- **MTP and KV-cache figures come from the neighboring builds.** This build was not measured on either axis; the head and the layout are present and identical, the numbers are not.
|
| 279 |
+
- **Shape-dependent numerics.** The hybrid stack takes different kernel paths depending on the shape of the input it receives — the batched scoring pass behind the perplexity table is not the same shape as incremental decode, and near-tie positions can resolve differently between those paths. Perplexity is far less sensitive to this than an argmax metric, but do not expect bit-identical numbers from a different harness.
|
| 280 |
+
- **Long-form generated reasoning is unprobed.** Perplexity scores 2048-token windows of existing text; it does not exercise long generated reasoning chains, where low-bit damage tends to concentrate. Spot-check your own thinking-mode prompts.
|
| 281 |
|
| 282 |
## License and attribution
|
| 283 |
|
assets/builds.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/builds.svg
CHANGED
|
|
assets/make_builds_png.py
CHANGED
|
@@ -136,35 +136,27 @@ txt(200, 331, "50.36 tok/s · 1.34× vs plain 4-bit", 13.5, CM)
|
|
| 136 |
|
| 137 |
# ============ 4-bit ============
|
| 138 |
ax.plot([179.1], [407.5], "o", markersize=16 * PT, color=C4, zorder=6)
|
| 139 |
-
txt(200, 366, "4-bit", 15.5, C4, "bold")
|
| 140 |
txt(200, 385, "15.2 GB · 37.5 tok/s plain", 13.5, C4)
|
| 141 |
-
txt(200, 403, "ko
|
| 142 |
-
bar(200, 411, 84, GREY, 0.16, z=4)
|
| 143 |
-
bar(200, 411, 23.9, C4)
|
| 144 |
|
| 145 |
# ============ 6-bit (label to the left) ============
|
| 146 |
ax.plot([275.0], [478.9], "o", markersize=16 * PT, color=C6, zorder=6)
|
| 147 |
txt(257, 482, "6-bit", 15.5, C6, "bold", ha="right")
|
| 148 |
txt(257, 501, "21.5 GB · 27.3 tok/s", 13.5, C6, ha="right")
|
| 149 |
-
txt(257, 519, "ko
|
| 150 |
-
bar(173, 527, 84, GREY, 0.16, z=4)
|
| 151 |
-
bar(173, 527, 72.7, C6)
|
| 152 |
|
| 153 |
# ============ 8-bit ============
|
| 154 |
ax.plot([372.4], [517.4], "o", markersize=16 * PT, color=C8, zorder=6)
|
| 155 |
txt(390, 459, "8-bit", 15.5, C8, "bold")
|
| 156 |
txt(390, 478, "27.9 GB · 21.8 tok/s", 13.5, C8)
|
| 157 |
-
txt(390, 496, "ko
|
| 158 |
-
bar(390, 504, 84, GREY, 0.16, z=4)
|
| 159 |
-
bar(390, 504, 80.2, C8)
|
| 160 |
|
| 161 |
# ============ bf16 ============
|
| 162 |
ax.plot([736.1], [581.8], "o", markersize=16 * PT, color=CB, zorder=6)
|
| 163 |
txt(790, 512, "bf16 reference", 15.5, CB, "bold", ha="right")
|
| 164 |
txt(790, 531, "51.8 GB · 12.6 tok/s", 13.5, CB, ha="right")
|
| 165 |
-
txt(790, 549, "ko
|
| 166 |
-
bar(706, 557, 84, GREY, 0.16, z=4)
|
| 167 |
-
bar(706, 557, 84, CB)
|
| 168 |
|
| 169 |
# ============ in-plot callout: the Korean caveat ============
|
| 170 |
ax.add_patch(FancyBboxPatch((459.5, 190.5), 0.1, 15,
|
|
@@ -206,18 +198,18 @@ txt(858, 556, "DSpark drafter is a separate 0.76 GB download.", 13, MUT)
|
|
| 206 |
|
| 207 |
# ============ footnotes ============
|
| 208 |
for fy, s in [
|
| 209 |
-
(682, "Measured on one M3 Ultra 512GB box, queued back-to-back.
|
| 210 |
-
"
|
| 211 |
-
"
|
| 212 |
-
(701, "
|
| 213 |
-
"
|
| 214 |
-
"No standard benchmarks were run."),
|
| 215 |
(720, "Speculative decoding: greedy, 240 tokens per prompt, timed after an "
|
| 216 |
-
"8-token warmup,
|
| 217 |
-
"
|
| 218 |
-
(739, "
|
| 219 |
-
"
|
| 220 |
-
"k=2; DSpark drives an external 1.36B drafter."),
|
| 221 |
(758, "Plotted values are the 4-prompt average — single prompts overstate "
|
| 222 |
"speculation: DSpark reads 75.1 tok/s on code and 91.5 on math "
|
| 223 |
"against that 62.2 average.")]:
|
|
|
|
| 136 |
|
| 137 |
# ============ 4-bit ============
|
| 138 |
ax.plot([179.1], [407.5], "o", markersize=16 * PT, color=C4, zorder=6)
|
| 139 |
+
txt(200, 366, "4-bit AWQ", 15.5, C4, "bold")
|
| 140 |
txt(200, 385, "15.2 GB · 37.5 tok/s plain", 13.5, C4)
|
| 141 |
+
txt(200, 403, "ko PPL 6.261 · +2.7% vs bf16", 12.5, C4, "bold")
|
|
|
|
|
|
|
| 142 |
|
| 143 |
# ============ 6-bit (label to the left) ============
|
| 144 |
ax.plot([275.0], [478.9], "o", markersize=16 * PT, color=C6, zorder=6)
|
| 145 |
txt(257, 482, "6-bit", 15.5, C6, "bold", ha="right")
|
| 146 |
txt(257, 501, "21.5 GB · 27.3 tok/s", 13.5, C6, ha="right")
|
| 147 |
+
txt(257, 519, "ko PPL 6.102 (≈bf16)", 12.5, C6, ha="right")
|
|
|
|
|
|
|
| 148 |
|
| 149 |
# ============ 8-bit ============
|
| 150 |
ax.plot([372.4], [517.4], "o", markersize=16 * PT, color=C8, zorder=6)
|
| 151 |
txt(390, 459, "8-bit", 15.5, C8, "bold")
|
| 152 |
txt(390, 478, "27.9 GB · 21.8 tok/s", 13.5, C8)
|
| 153 |
+
txt(390, 496, "ko PPL 6.099 (≈bf16)", 12.5, C8)
|
|
|
|
|
|
|
| 154 |
|
| 155 |
# ============ bf16 ============
|
| 156 |
ax.plot([736.1], [581.8], "o", markersize=16 * PT, color=CB, zorder=6)
|
| 157 |
txt(790, 512, "bf16 reference", 15.5, CB, "bold", ha="right")
|
| 158 |
txt(790, 531, "51.8 GB · 12.6 tok/s", 13.5, CB, ha="right")
|
| 159 |
+
txt(790, 549, "ko PPL 6.095 — reference", 12.5, CB, ha="right")
|
|
|
|
|
|
|
| 160 |
|
| 161 |
# ============ in-plot callout: the Korean caveat ============
|
| 162 |
ax.add_patch(FancyBboxPatch((459.5, 190.5), 0.1, 15,
|
|
|
|
| 198 |
|
| 199 |
# ============ footnotes ============
|
| 200 |
for fy, s in [
|
| 201 |
+
(682, "Measured on one M3 Ultra 512GB box, queued back-to-back. Quality = "
|
| 202 |
+
"corpus strided perplexity — ctx 2048, stride 512, paired per token "
|
| 203 |
+
"vs bf16 — over en wikitext-2 35,981, ko Korean"),
|
| 204 |
+
(701, "wiki 35,179, code CPython 32,295 tokens. 8-bit ≈ bf16 on every "
|
| 205 |
+
"slice, 6-bit ≈ bf16 on Korean; 4-bit AWQ: +1.2% en, +2.7% ko, "
|
| 206 |
+
"+7.7% code. No standard benchmarks were run."),
|
| 207 |
(720, "Speculative decoding: greedy, 240 tokens per prompt, timed after an "
|
| 208 |
+
"8-token warmup, in one process on the 4-bit repo's earlier uniform "
|
| 209 |
+
"weights (the AWQ swap measures within ±1%,"),
|
| 210 |
+
(739, "EOS-cut paired). Both lossless — each reproduced plain greedy "
|
| 211 |
+
"decoding token for token through 80 tokens. MTP is the vendor "
|
| 212 |
+
"multi-token head at k=2; DSpark drives an external 1.36B drafter."),
|
| 213 |
(758, "Plotted values are the 4-prompt average — single prompts overstate "
|
| 214 |
"speculation: DSpark reads 75.1 tok/s on code and 91.5 on math "
|
| 215 |
"against that 62.2 average.")]:
|