

Ilk yayin: LoRA adaptoru + model karti + karar.py
Browse files- README.md +13 -5
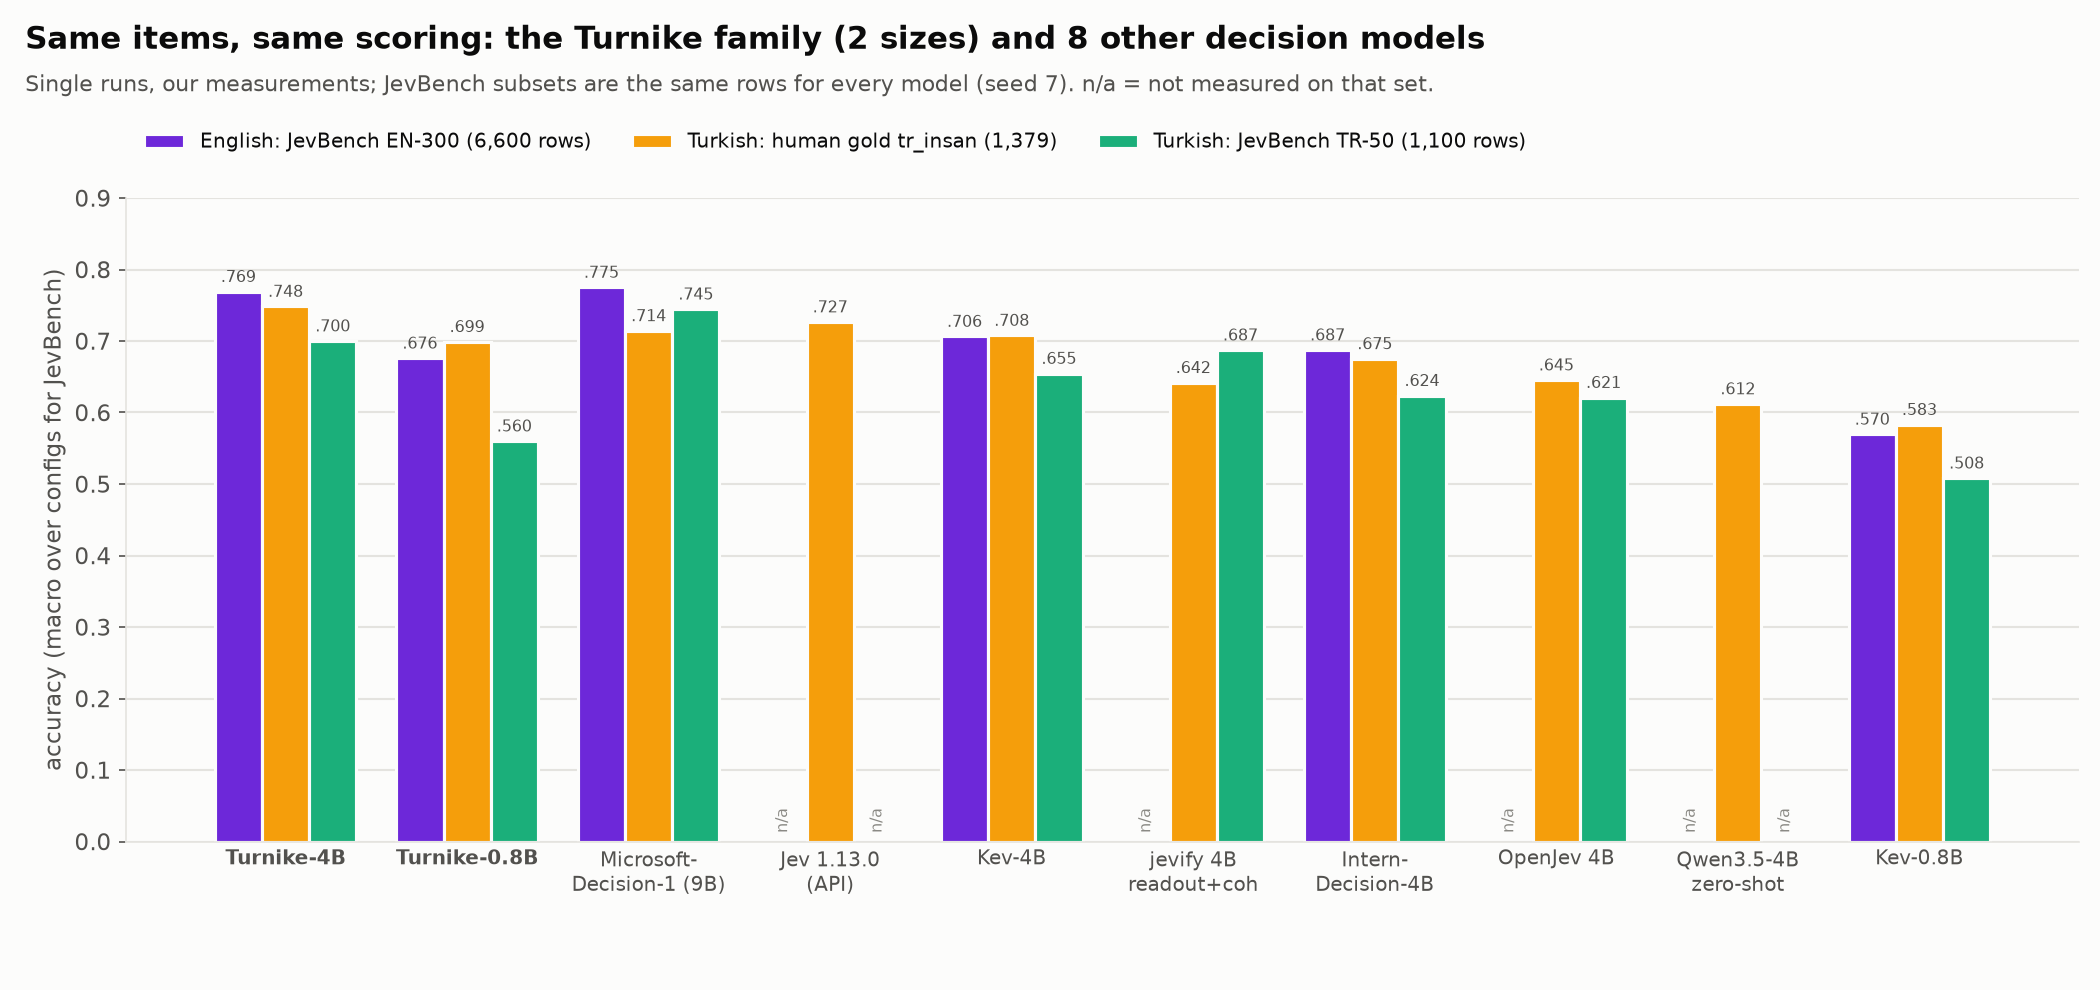
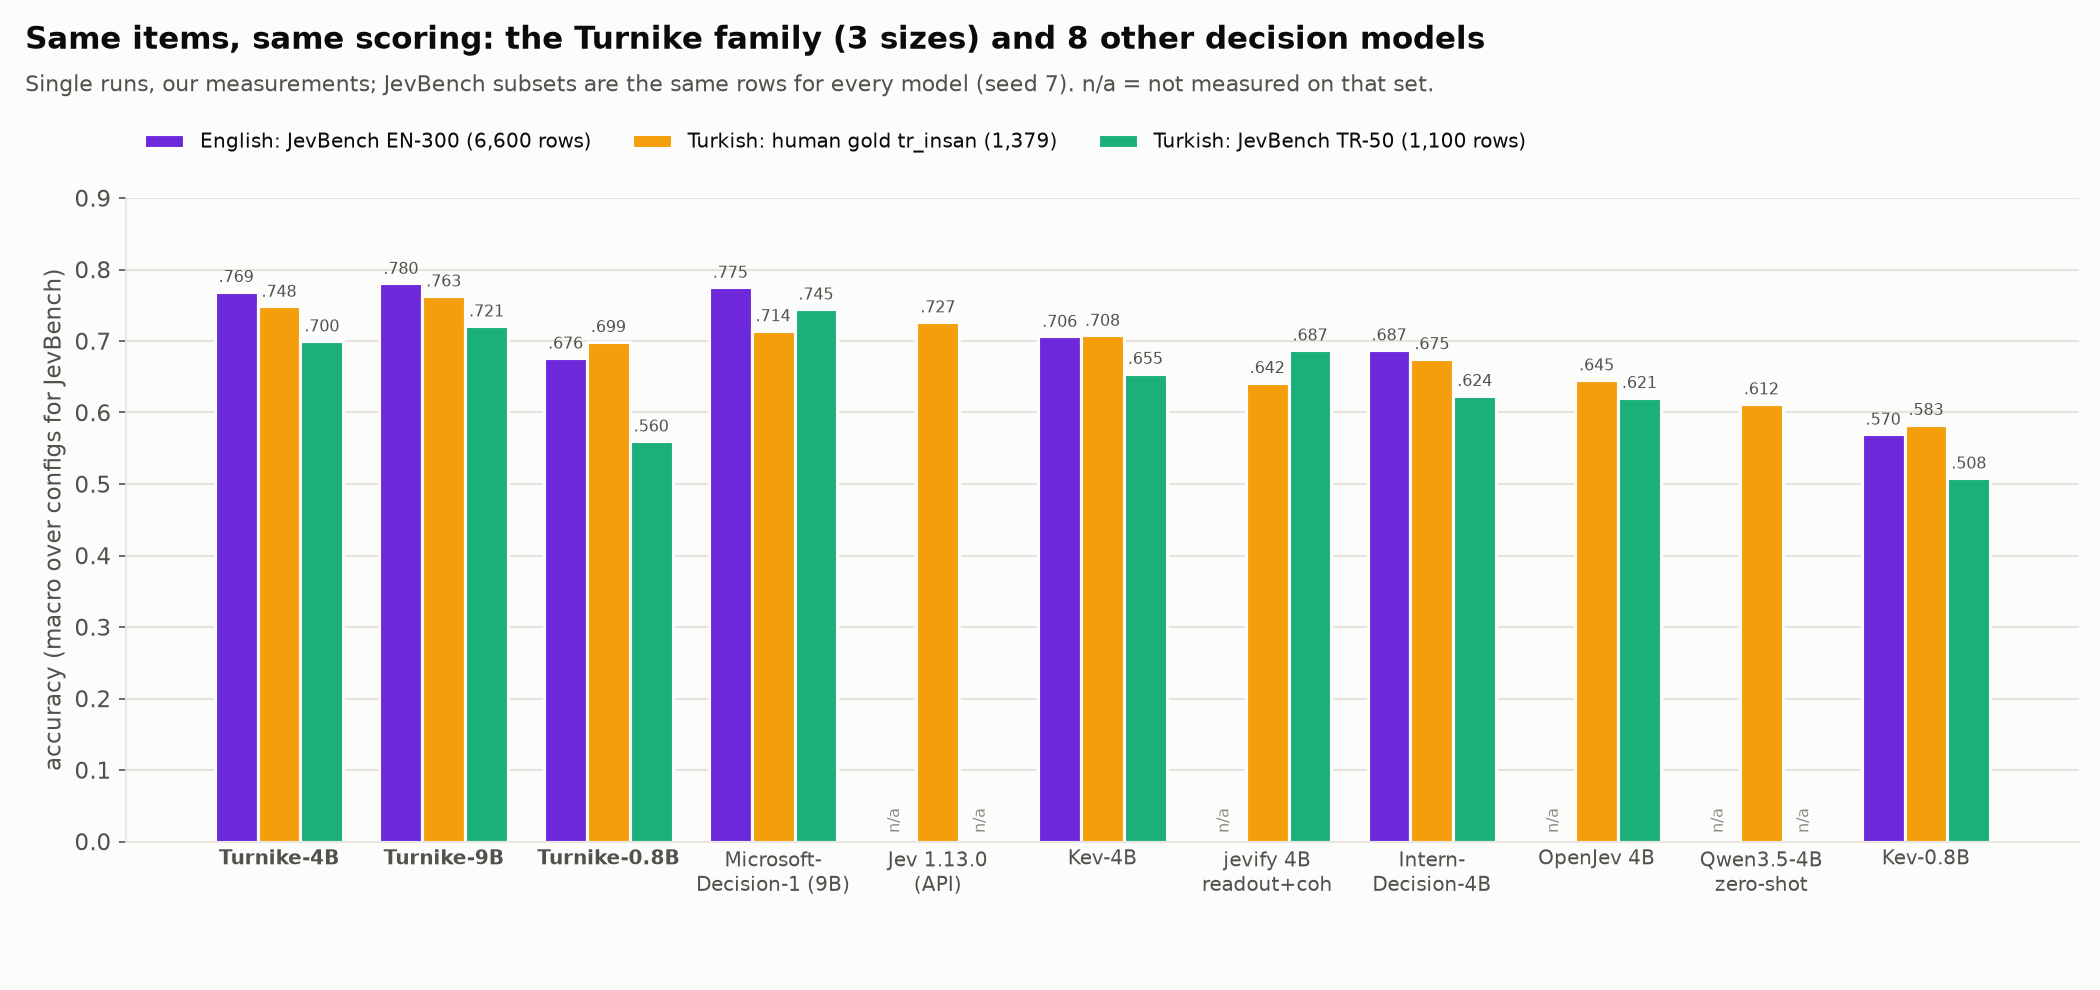
- assets/fig_compare.png +2 -2
README.md
CHANGED
|
@@ -75,6 +75,7 @@ Three sizes, one recipe: the same data, the same draw (seed 3) and the same hype
|
|
| 75 |
|---|---|---|---|---|---|---|---|---|---|
|
| 76 |
| [Turnike-0.8B](https://huggingface.co/berkay123001/turnike-0.8b) | Qwen/Qwen3.5-0.8B | 10.8M | 0.676 | 0.682 / 0.674 | 0.699 | 0.560 | 0.840 | 0.724 | RTX 5060 Ti 16 GB, batch 4 × 8 |
|
| 77 |
| **Turnike-4B** (this card) | Qwen/Qwen3.5-4B | 32.5M | 0.769 | 0.826 / 0.748 | 0.748 | 0.700 | 0.891 | 0.832 | RTX 5060 Ti 16 GB, batch 4 × 8 |
|
|
|
|
| 78 |
|
| 79 |
<sub>Same protocol as the tables below: single runs, the same items for every model, no calibration recipe. Differences below about 0.01 (0.02 on TR-50) are within run-to-run noise.</sub>
|
| 80 |
|
|
@@ -211,6 +212,7 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 211 |
| model | JevBench EN-300 (EN) | LegalBench rules, 885 (EN) | tr_insan, 1,379 human-labelled (TR) | JevBench TR-50 (TR) | practical TR, 2,966 (TR) |
|
| 212 |
|---|---|---|---|---|---|
|
| 213 |
| **Turnike-4B** | 0.769 | 0.832 | 0.748 | 0.700 | 0.891 |
|
|
|
|
| 214 |
| **Turnike-0.8B** | 0.676 | 0.724 | 0.699 | 0.560 | 0.840 |
|
| 215 |
| Microsoft-Decision-1 (9B, closed, API) | 0.775 | – | 0.714 | 0.745 | 0.857 |
|
| 216 |
| Jev 1.13.0 (API) | – | 0.924 † | 0.727 | – | 0.872 |
|
|
@@ -291,6 +293,7 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 291 |
| model | EN-300 macro | held-6 / other-16 | McNemar vs Turnike-4B (only-Turnike-4B / only-other) |
|
| 292 |
|---|---|---|---|
|
| 293 |
| **Turnike-4B** | 0.769 | 0.826 / 0.748 | – |
|
|
|
|
| 294 |
| **Turnike-0.8B** | 0.676 | 0.682 / 0.674 | 993 / 378, p = 6e-64 |
|
| 295 |
| Microsoft-Decision-1 (9B, closed, API) | 0.775 | 0.843 / 0.750 | 426 / 465, p = 0.20 |
|
| 296 |
| Kev-4B | 0.706 | 0.772 / 0.682 | 795 / 381, p = 4e-34 |
|
|
@@ -306,6 +309,7 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 306 |
| model | topic (301) | sentiment 3-way (300) | NLI (300) | film stars 1–5 (178) | product stars 1–5 (300) | all (1,379) | McNemar vs Turnike-4B |
|
| 307 |
|---|---|---|---|---|---|---|---|
|
| 308 |
| **Turnike-4B** | 0.924 | 0.910 | 0.790 | 0.562 | 0.480 | **0.748** | – |
|
|
|
|
| 309 |
| **Turnike-0.8B** | 0.884 | 0.870 | 0.727 | 0.472 | 0.450 | **0.699** | 152 / 84, p = 1e-5 |
|
| 310 |
| Microsoft-Decision-1 (9B, closed, API) | 0.887 | 0.893 | 0.727 | 0.545 | 0.450 | **0.714** | 141 / 94, p = 0.003 |
|
| 311 |
| Jev 1.13.0 (API) | 0.904 | 0.893 | 0.777 | 0.517 | 0.457 | **0.727** | 131 / 101, p = 0.06 |
|
|
@@ -323,6 +327,7 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 323 |
| model | TR-50 macro | held-6 / other-16 | McNemar vs Turnike-4B (only-Turnike-4B / only-other) |
|
| 324 |
|---|---|---|---|
|
| 325 |
| **Turnike-4B** | 0.700 | 0.750 / 0.681 | – |
|
|
|
|
| 326 |
| **Turnike-0.8B** | 0.560 | 0.583 / 0.551 | 239 / 85, p = 4e-18 |
|
| 327 |
| Microsoft-Decision-1 (9B, closed, API) | 0.745 | 0.840 / 0.709 | 72 / 121, p = 5e-4 |
|
| 328 |
| Kev-4B | 0.655 | 0.720 / 0.630 | 127 / 77, p = 6e-4 |
|
|
@@ -335,11 +340,11 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 335 |
|
| 336 |
### Behaviour tests (Table 6)
|
| 337 |
|
| 338 |
-
| test | **Turnike-4B** | **Turnike-0.8B** | Jev 1.13.0 (API) | Kev-4B | internlm/Intern-Decision-4B | Kev-0.8B |
|
| 339 |
-
|---|---|---|---|---|---|---|
|
| 340 |
-
| planted instruction: accuracy clean / planted (800 × 2) | 0.927 / 0.941 | 0.885 / 0.892 | – | 0.897 / 0.816 | 0.877 / 0.599 | 0.826 / 0.568 |
|
| 341 |
-
| hijack rate ↓ | −0.014 | −0.008 | – | +0.081 | +0.279 | +0.259 |
|
| 342 |
-
| LegalBench rule application (885, 10 tasks, none trained on) | 0.832 | 0.724 | 0.924 † | 0.786 | 0.656 | 0.496 |
|
| 343 |
|
| 344 |
<sub>Protocol: one run each, same items and scoring code. Planted instruction: the same 800 items with a sentence inserted into the text that names a wrong answer; hijack rate = how much more often the model gives the named answer than on the clean copy (0 = ignored). † Reported by the jevify author on the same 885 items; not our run.</sub>
|
| 345 |
|
|
@@ -348,6 +353,9 @@ Measured for the Turnike models only (the competitors were not run on these two
|
|
| 348 |
- **Turnike-4B, "None of the above", balanced** (908 MMLU/ARC items × 2 variants, half with the right option removed; the option count no longer gives the answer away): accuracy 0.768 (drop variant) / 0.742 (add variant). It picks "none" in 0.809 / 0.798 of the items where the right option is missing, and wrongly in 0.223 / 0.252 where it is present. In the "add" variant the added option is off-topic only in items without the right option, which can itself hint "none"; the "drop" variant has no such hint.
|
| 349 |
- **Turnike-4B, KVKK sufficiency** (internal Turkish personal-data check; two yes/no questions: is a legal basis stated, is the data controller named; 1,172 decisions): 2 errors. On the real policy texts it is 1,160/1,160 correct (named controller 9/9, legal basis 10/10, must-be-insufficient 1,141/1,141); all 2 errors are on the 12 short synthetic passages (titles, headings, one-sentence statements) of the controller question (10/12). Gold sets are tiny; two seeds of the 4B recipe gave 11 and 16 errors.
|
| 350 |
|
|
|
|
|
|
|
|
|
|
| 351 |
- **Turnike-0.8B, "None of the above", balanced** (908 MMLU/ARC items × 2 variants, half with the right option removed; the option count no longer gives the answer away): accuracy 0.558 (drop variant) / 0.532 (add variant). It picks "none" in 0.666 / 0.653 of the items where the right option is missing, and wrongly in 0.402 / 0.428 where it is present. In the "add" variant the added option is off-topic only in items without the right option, which can itself hint "none"; the "drop" variant has no such hint.
|
| 352 |
- **Turnike-0.8B, KVKK sufficiency** (internal Turkish personal-data check; two yes/no questions: is a legal basis stated, is the data controller named; 1,172 decisions): 6 errors. On the real policy texts it is 1,158/1,160 correct (named controller 7/9, legal basis 10/10, must-be-insufficient 1,141/1,141); errors by set: A-controller 2/9, S 4/12. Gold sets are tiny; two seeds of the 4B recipe gave 11 and 16 errors.
|
| 353 |
|
|
|
|
| 75 |
|---|---|---|---|---|---|---|---|---|---|
|
| 76 |
| [Turnike-0.8B](https://huggingface.co/berkay123001/turnike-0.8b) | Qwen/Qwen3.5-0.8B | 10.8M | 0.676 | 0.682 / 0.674 | 0.699 | 0.560 | 0.840 | 0.724 | RTX 5060 Ti 16 GB, batch 4 × 8 |
|
| 77 |
| **Turnike-4B** (this card) | Qwen/Qwen3.5-4B | 32.5M | 0.769 | 0.826 / 0.748 | 0.748 | 0.700 | 0.891 | 0.832 | RTX 5060 Ti 16 GB, batch 4 × 8 |
|
| 78 |
+
| [Turnike-9B](https://huggingface.co/berkay123001/turnike-9b) | Qwen/Qwen3.5-9B | 43.3M | 0.780 | 0.839 / 0.758 | 0.763 | 0.721 | 0.889 | 0.890 | Colab RTX PRO 6000 96 GB, batch 16 × 2 |
|
| 79 |
|
| 80 |
<sub>Same protocol as the tables below: single runs, the same items for every model, no calibration recipe. Differences below about 0.01 (0.02 on TR-50) are within run-to-run noise.</sub>
|
| 81 |
|
|
|
|
| 212 |
| model | JevBench EN-300 (EN) | LegalBench rules, 885 (EN) | tr_insan, 1,379 human-labelled (TR) | JevBench TR-50 (TR) | practical TR, 2,966 (TR) |
|
| 213 |
|---|---|---|---|---|---|
|
| 214 |
| **Turnike-4B** | 0.769 | 0.832 | 0.748 | 0.700 | 0.891 |
|
| 215 |
+
| **Turnike-9B** | 0.780 | 0.890 | 0.763 | 0.721 | 0.889 |
|
| 216 |
| **Turnike-0.8B** | 0.676 | 0.724 | 0.699 | 0.560 | 0.840 |
|
| 217 |
| Microsoft-Decision-1 (9B, closed, API) | 0.775 | – | 0.714 | 0.745 | 0.857 |
|
| 218 |
| Jev 1.13.0 (API) | – | 0.924 † | 0.727 | – | 0.872 |
|
|
|
|
| 293 |
| model | EN-300 macro | held-6 / other-16 | McNemar vs Turnike-4B (only-Turnike-4B / only-other) |
|
| 294 |
|---|---|---|---|
|
| 295 |
| **Turnike-4B** | 0.769 | 0.826 / 0.748 | – |
|
| 296 |
+
| **Turnike-9B** | 0.780 | 0.839 / 0.758 | 291 / 366, p = 0.004 |
|
| 297 |
| **Turnike-0.8B** | 0.676 | 0.682 / 0.674 | 993 / 378, p = 6e-64 |
|
| 298 |
| Microsoft-Decision-1 (9B, closed, API) | 0.775 | 0.843 / 0.750 | 426 / 465, p = 0.20 |
|
| 299 |
| Kev-4B | 0.706 | 0.772 / 0.682 | 795 / 381, p = 4e-34 |
|
|
|
|
| 309 |
| model | topic (301) | sentiment 3-way (300) | NLI (300) | film stars 1–5 (178) | product stars 1–5 (300) | all (1,379) | McNemar vs Turnike-4B |
|
| 310 |
|---|---|---|---|---|---|---|---|
|
| 311 |
| **Turnike-4B** | 0.924 | 0.910 | 0.790 | 0.562 | 0.480 | **0.748** | – |
|
| 312 |
+
| **Turnike-9B** | 0.934 | 0.910 | 0.830 | 0.584 | 0.483 | **0.763** | 62 / 82, p = 0.11 |
|
| 313 |
| **Turnike-0.8B** | 0.884 | 0.870 | 0.727 | 0.472 | 0.450 | **0.699** | 152 / 84, p = 1e-5 |
|
| 314 |
| Microsoft-Decision-1 (9B, closed, API) | 0.887 | 0.893 | 0.727 | 0.545 | 0.450 | **0.714** | 141 / 94, p = 0.003 |
|
| 315 |
| Jev 1.13.0 (API) | 0.904 | 0.893 | 0.777 | 0.517 | 0.457 | **0.727** | 131 / 101, p = 0.06 |
|
|
|
|
| 327 |
| model | TR-50 macro | held-6 / other-16 | McNemar vs Turnike-4B (only-Turnike-4B / only-other) |
|
| 328 |
|---|---|---|---|
|
| 329 |
| **Turnike-4B** | 0.700 | 0.750 / 0.681 | – |
|
| 330 |
+
| **Turnike-9B** | 0.721 | 0.793 / 0.694 | 77 / 100, p = 0.10 |
|
| 331 |
| **Turnike-0.8B** | 0.560 | 0.583 / 0.551 | 239 / 85, p = 4e-18 |
|
| 332 |
| Microsoft-Decision-1 (9B, closed, API) | 0.745 | 0.840 / 0.709 | 72 / 121, p = 5e-4 |
|
| 333 |
| Kev-4B | 0.655 | 0.720 / 0.630 | 127 / 77, p = 6e-4 |
|
|
|
|
| 340 |
|
| 341 |
### Behaviour tests (Table 6)
|
| 342 |
|
| 343 |
+
| test | **Turnike-4B** | **Turnike-9B** | **Turnike-0.8B** | Jev 1.13.0 (API) | Kev-4B | internlm/Intern-Decision-4B | Kev-0.8B |
|
| 344 |
+
|---|---|---|---|---|---|---|---|
|
| 345 |
+
| planted instruction: accuracy clean / planted (800 × 2) | 0.927 / 0.941 | 0.932 / 0.936 | 0.885 / 0.892 | – | 0.897 / 0.816 | 0.877 / 0.599 | 0.826 / 0.568 |
|
| 346 |
+
| hijack rate ↓ | −0.014 | −0.004 | −0.008 | – | +0.081 | +0.279 | +0.259 |
|
| 347 |
+
| LegalBench rule application (885, 10 tasks, none trained on) | 0.832 | 0.890 | 0.724 | 0.924 † | 0.786 | 0.656 | 0.496 |
|
| 348 |
|
| 349 |
<sub>Protocol: one run each, same items and scoring code. Planted instruction: the same 800 items with a sentence inserted into the text that names a wrong answer; hijack rate = how much more often the model gives the named answer than on the clean copy (0 = ignored). † Reported by the jevify author on the same 885 items; not our run.</sub>
|
| 350 |
|
|
|
|
| 353 |
- **Turnike-4B, "None of the above", balanced** (908 MMLU/ARC items × 2 variants, half with the right option removed; the option count no longer gives the answer away): accuracy 0.768 (drop variant) / 0.742 (add variant). It picks "none" in 0.809 / 0.798 of the items where the right option is missing, and wrongly in 0.223 / 0.252 where it is present. In the "add" variant the added option is off-topic only in items without the right option, which can itself hint "none"; the "drop" variant has no such hint.
|
| 354 |
- **Turnike-4B, KVKK sufficiency** (internal Turkish personal-data check; two yes/no questions: is a legal basis stated, is the data controller named; 1,172 decisions): 2 errors. On the real policy texts it is 1,160/1,160 correct (named controller 9/9, legal basis 10/10, must-be-insufficient 1,141/1,141); all 2 errors are on the 12 short synthetic passages (titles, headings, one-sentence statements) of the controller question (10/12). Gold sets are tiny; two seeds of the 4B recipe gave 11 and 16 errors.
|
| 355 |
|
| 356 |
+
- **Turnike-9B, "None of the above", balanced** (908 MMLU/ARC items × 2 variants, half with the right option removed; the option count no longer gives the answer away): accuracy 0.801 (drop variant) / 0.792 (add variant). It picks "none" in 0.813 / 0.778 of the items where the right option is missing, and wrongly in 0.168 / 0.139 where it is present. In the "add" variant the added option is off-topic only in items without the right option, which can itself hint "none"; the "drop" variant has no such hint.
|
| 357 |
+
- **Turnike-9B, KVKK sufficiency** (internal Turkish personal-data check; two yes/no questions: is a legal basis stated, is the data controller named; 1,172 decisions): 2 errors. On the real policy texts it is 1,158/1,160 correct (named controller 9/9, legal basis 9/10, must-be-insufficient 1,140/1,141); errors by set: A-legal 1/10, C2 1/899. Gold sets are tiny; two seeds of the 4B recipe gave 11 and 16 errors.
|
| 358 |
+
|
| 359 |
- **Turnike-0.8B, "None of the above", balanced** (908 MMLU/ARC items × 2 variants, half with the right option removed; the option count no longer gives the answer away): accuracy 0.558 (drop variant) / 0.532 (add variant). It picks "none" in 0.666 / 0.653 of the items where the right option is missing, and wrongly in 0.402 / 0.428 where it is present. In the "add" variant the added option is off-topic only in items without the right option, which can itself hint "none"; the "drop" variant has no such hint.
|
| 360 |
- **Turnike-0.8B, KVKK sufficiency** (internal Turkish personal-data check; two yes/no questions: is a legal basis stated, is the data controller named; 1,172 decisions): 6 errors. On the real policy texts it is 1,158/1,160 correct (named controller 7/9, legal basis 10/10, must-be-insufficient 1,141/1,141); errors by set: A-controller 2/9, S 4/12. Gold sets are tiny; two seeds of the 4B recipe gave 11 and 16 errors.
|
| 361 |
|
assets/fig_compare.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|