

Jev-style decision model: GGUF BF16 / Q8_0 / Q4_K_M, client script, model card
Browse files- .gitattributes +4 -0
- Jev-Style-Qwen3.5-2B-Decision-BF16.gguf +3 -0
- Jev-Style-Qwen3.5-2B-Decision-Q4_K_M.gguf +3 -0
- Jev-Style-Qwen3.5-2B-Decision-Q8_0.gguf +3 -0
- README.md +123 -0
- calibration.png +3 -0
- jev_style_client.py +91 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,7 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
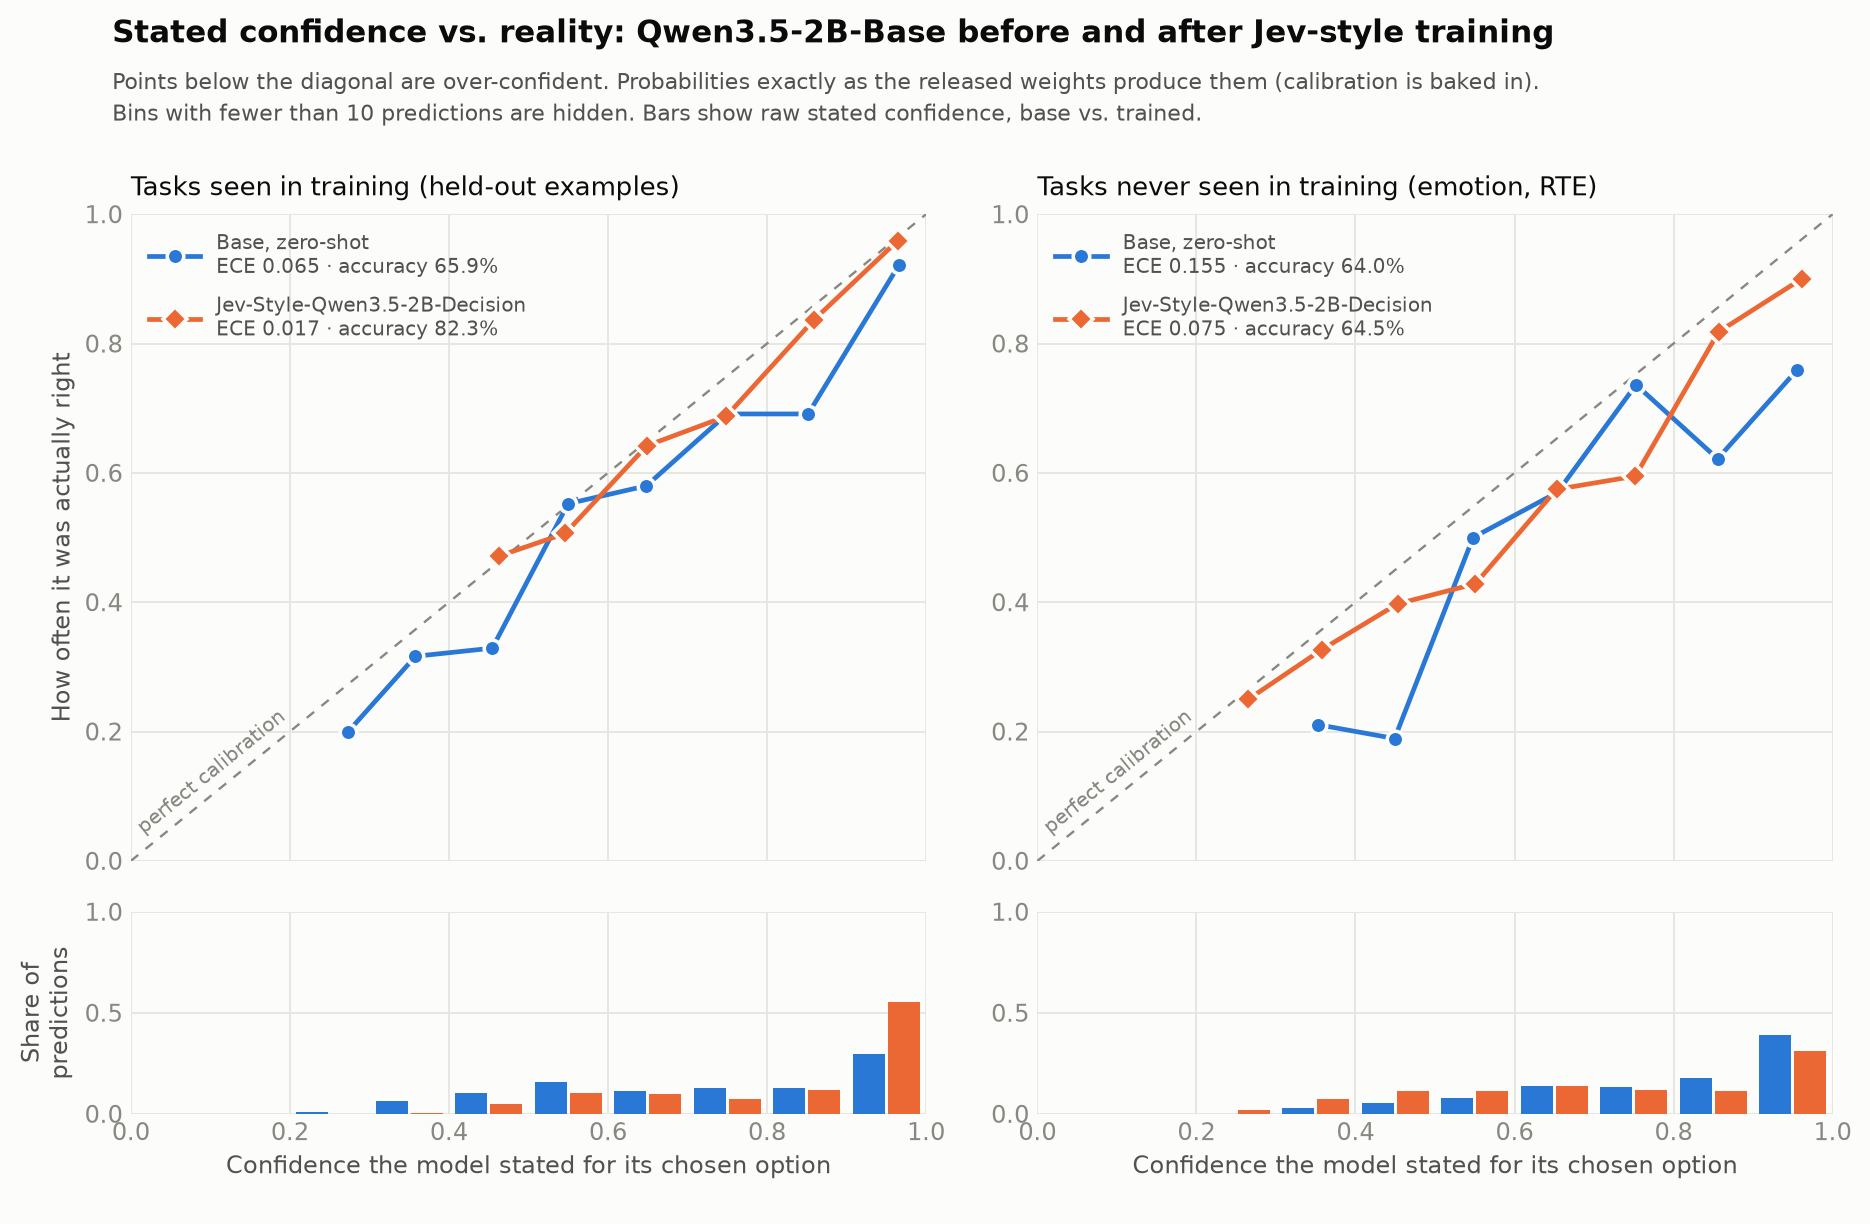
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
Jev-Style-Qwen3.5-2B-Decision-BF16.gguf filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
Jev-Style-Qwen3.5-2B-Decision-Q4_K_M.gguf filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
Jev-Style-Qwen3.5-2B-Decision-Q8_0.gguf filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
calibration.png filter=lfs diff=lfs merge=lfs -text
|
Jev-Style-Qwen3.5-2B-Decision-BF16.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ccc6f44df660114180bf12a38ecef09cec9afe138f7776f2fb047aea5c2ce470
|
| 3 |
+
size 3897379936
|
Jev-Style-Qwen3.5-2B-Decision-Q4_K_M.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f3c14cd9d6d314d22f22ec527914e1cb7b5a9043823d4e815c0d232a9cd16cf6
|
| 3 |
+
size 1312156768
|
Jev-Style-Qwen3.5-2B-Decision-Q8_0.gguf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:470aa63b87fedf852e292580424fc4511778dffdbd459858f68abf4892dba040
|
| 3 |
+
size 2076666976
|
README.md
ADDED
|
@@ -0,0 +1,123 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
base_model: Qwen/Qwen3.5-2B-Base
|
| 4 |
+
pipeline_tag: text-generation
|
| 5 |
+
language:
|
| 6 |
+
- en
|
| 7 |
+
tags:
|
| 8 |
+
- gguf
|
| 9 |
+
- jev-style
|
| 10 |
+
- system-one
|
| 11 |
+
- decision-model
|
| 12 |
+
- calibration
|
| 13 |
+
- classification
|
| 14 |
+
- qwen3.5
|
| 15 |
+
datasets:
|
| 16 |
+
- nyu-mll/glue
|
| 17 |
+
- fancyzhx/ag_news
|
| 18 |
+
- google/boolq
|
| 19 |
+
- SetFit/sst5
|
| 20 |
+
---
|
| 21 |
+
|
| 22 |
+
# Jev-Style-Qwen3.5-2B-Decision (GGUF)
|
| 23 |
+
|
| 24 |
+
A **Jev-style decision model**: it does not write text. Give it a state, a question and a list of options, and it returns the decision **with calibrated probabilities** from a single token position. Runs in **LM Studio** and **llama.cpp**.
|
| 25 |
+
|
| 26 |
+
| File | Size | Same decision as bf16 | Accuracy (500 held-out) |
|
| 27 |
+
|---|---|---|---|
|
| 28 |
+
| `Jev-Style-Qwen3.5-2B-Decision-Q4_K_M.gguf` | 1.3 GB | 94.4% | 82.4% |
|
| 29 |
+
| `Jev-Style-Qwen3.5-2B-Decision-Q8_0.gguf` | 2.1 GB | 99.4% | 81.6% |
|
| 30 |
+
| `Jev-Style-Qwen3.5-2B-Decision-BF16.gguf` | 3.9 GB | 99.8% | 81.6% |
|
| 31 |
+
|
| 32 |
+
MLX bf16 build for Apple Silicon: [chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-MLX-bf16](https://huggingface.co/chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-MLX-bf16)
|
| 33 |
+
|
| 34 |
+
## Results
|
| 35 |
+
|
| 36 |
+
Everything below is measured on data the model never trained on, with the probabilities **exactly as the released weights produce them** (no post-processing).
|
| 37 |
+
|
| 38 |
+
| | Qwen3.5-2B-Base, zero-shot | **This model** |
|
| 39 |
+
|---|---|---|
|
| 40 |
+
| Accuracy, 5 decision tasks (1,500 held-out examples) | 65.9% | **82.3%** |
|
| 41 |
+
| Calibration error (ECE) on those tasks | 0.065 | **0.017** |
|
| 42 |
+
| Negative log-likelihood / Brier score | 0.786 / 0.446 | **0.418 / 0.242** |
|
| 43 |
+
| Calibration error on task types never seen in training | 0.155 | **0.075** |
|
| 44 |
+
| Latency per decision (M1 Max, MLX bf16) | 76 ms | **77 ms** (no added cost) |
|
| 45 |
+
|
| 46 |
+
- **Calibrated out of the box.** An ECE of 0.017 on 1,500 examples is statistically indistinguishable from a *perfectly* calibrated model: simulating labels from the model's own probabilities gives an expected ECE of 0.017 (95th percentile 0.025) from sampling noise alone. When this model says 80%, it is right about 80% of the time.
|
| 47 |
+
- **Large accuracy gains where the base model struggled:** MNLI 52.3% -> 86.7%, SST-5 32.0% -> 61.7%, BoolQ 73.0% -> 82.7%, SST-2 87.3% -> 92.7%, AG News 84.7% -> 87.7%.
|
| 48 |
+
- **Calibration transfers to new task types:** on emotion classification and RTE (never seen in training) the calibration error is halved (0.155 -> 0.075) at unchanged accuracy (64.5%).
|
| 49 |
+
- **Zero-cost calibration.** A temperature fitted on 4,366 held-out examples is folded into the final RMSNorm weight, so every logit is already calibrated. Nothing to apply at inference time.
|
| 50 |
+
- **Quantisation-friendly.** Q8_0 makes the same decision as bf16 on 99.4% of examples; Q4_K_M (1.3 GB) keeps 82.4% accuracy.
|
| 51 |
+
- **Trained on a laptop.** The whole run (17.5k examples, LoRA rank 16 on all linear layers, log-score loss) took about 80 minutes on one M1 Max, using a custom chunk-parallel, differentiable Gated DeltaNet forward that matches the per-token training path to 1e-6 (outputs, state and all gradients) and is 6.5x faster per step (measured on the 0.8B sibling model).
|
| 52 |
+
|
| 53 |
+

|
| 54 |
+
## What "Jev-style" means
|
| 55 |
+
|
| 56 |
+
[Jev](https://typesafe.ai/blog/introducing-system-one-models-and-jev) (TypeSafe AI, 2026) introduced *System One* models: instead of generating text, the model takes a state plus a typed question and returns a **decision with calibrated probabilities** in a single pass. This model follows that pattern on top of an open base model:
|
| 57 |
+
|
| 58 |
+
- **Choice** - pick one of N declared options, with a probability for each
|
| 59 |
+
- **Bool** - probability that a proposition is true
|
| 60 |
+
- **Score** - a distribution over ordered levels, and its expectation as a continuous score
|
| 61 |
+
|
| 62 |
+
It cannot answer outside the declared options, it does not decode text, and one prefill pass gives the whole distribution.
|
| 63 |
+
|
| 64 |
+
> This is an independent, from-scratch reproduction of the publicly described idea. It is not affiliated with TypeSafe AI and is not the Jev model.
|
| 65 |
+
|
| 66 |
+
## Quick start
|
| 67 |
+
|
| 68 |
+
**LM Studio** - download a file from this repo, load it, start the local server (Developer tab), then:
|
| 69 |
+
|
| 70 |
+
```bash
|
| 71 |
+
python jev_style_client.py --url http://localhost:1234 --model jev-style-qwen3.5-2b-decision
|
| 72 |
+
```
|
| 73 |
+
|
| 74 |
+
**llama.cpp**
|
| 75 |
+
|
| 76 |
+
```bash
|
| 77 |
+
llama-server -hf chaoliangUNSW/Jev-Style-Qwen3.5-2B-Decision-GGUF:Q8_0 --port 8080
|
| 78 |
+
python jev_style_client.py --url http://localhost:8080
|
| 79 |
+
```
|
| 80 |
+
|
| 81 |
+
`jev_style_client.py` (standard library only) asks for one token with `top_logprobs` on `/v1/chat/completions` and renormalises the option letters:
|
| 82 |
+
|
| 83 |
+
```python
|
| 84 |
+
from jev_style_client import decide, decide_bool, decide_score
|
| 85 |
+
|
| 86 |
+
decide("http://localhost:1234",
|
| 87 |
+
"Shares of the chipmaker jumped 8% after it raised its revenue forecast.",
|
| 88 |
+
"Which news section does this article belong to?",
|
| 89 |
+
["World", "Sports", "Business", "Science/Technology"],
|
| 90 |
+
model="jev-style-qwen3.5-2b-decision")
|
| 91 |
+
# [('Business', 0.68), ('Science/Technology', 0.31), ('World', 0.005), ('Sports', 0.002)]
|
| 92 |
+
```
|
| 93 |
+
|
| 94 |
+
Verified end to end through LM Studio's server on 500 held-out examples: 81.6% accuracy, ECE 0.028, about 110 ms per decision over HTTP on an M1 Max. In the LM Studio chat window you can also paste the prompt below and the model replies with the option letter.
|
| 95 |
+
|
| 96 |
+
## Prompt format
|
| 97 |
+
|
| 98 |
+
```
|
| 99 |
+
You are a decision function. Read the state, then answer the question by choosing exactly one option.
|
| 100 |
+
|
| 101 |
+
[State]
|
| 102 |
+
{state}
|
| 103 |
+
|
| 104 |
+
[Question]
|
| 105 |
+
{question}
|
| 106 |
+
|
| 107 |
+
[Options]
|
| 108 |
+
A. {option 1}
|
| 109 |
+
B. {option 2}
|
| 110 |
+
|
| 111 |
+
Answer:
|
| 112 |
+
```
|
| 113 |
+
|
| 114 |
+
The next token is the option letter (` A`, ` B`, ...). Its probability, renormalised over the declared letters, is the decision distribution. For **Score**, list the levels in order; for **Bool**, use `yes` / `no`. The repository ships a pass-through chat template, so chat endpoints and the LM Studio chat window pass this text to the model verbatim.
|
| 115 |
+
## Scope
|
| 116 |
+
|
| 117 |
+
- A decision function, not a chat model: send the prompt format above.
|
| 118 |
+
- Trained on five English task families (sentiment, natural-language inference, topic, yes/no question answering, 5-level rating). On unseen task types it keeps the base model's accuracy with better, though not perfect, calibration.
|
| 119 |
+
- Up to 26 options (20 when probabilities are read through a server's `top_logprobs`).
|
| 120 |
+
|
| 121 |
+
## Training data and licence
|
| 122 |
+
|
| 123 |
+
SST-2 and MNLI (GLUE), AG News, BoolQ and SST-5, 22k examples converted to typed decisions; 80% for LoRA training, 20% held out for the calibration temperature. AG News is distributed for research / non-commercial use. Weights: Apache-2.0, same as [Qwen/Qwen3.5-2B-Base](https://huggingface.co/Qwen/Qwen3.5-2B-Base).
|
calibration.png
ADDED
|
Git LFS Details
|
jev_style_client.py
ADDED
|
@@ -0,0 +1,91 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Typed decisions with calibrated probabilities from a local OpenAI-compatible server.
|
| 2 |
+
|
| 3 |
+
The model never writes text: one token is requested, and the log-probs of the option
|
| 4 |
+
letters at that position are renormalised into the decision distribution. The
|
| 5 |
+
calibration temperature is already baked into the weights, so no post-processing
|
| 6 |
+
beyond the renormalisation is needed.
|
| 7 |
+
|
| 8 |
+
# LM Studio: load the model, start the local server, then
|
| 9 |
+
python jev_style_client.py --url http://localhost:1234 --model jev-style-qwen3.5-2b-decision
|
| 10 |
+
# llama.cpp: llama-server -m Jev-Style-Qwen3.5-2B-Decision-Q8_0.gguf --port 8080
|
| 11 |
+
python jev_style_client.py --url http://localhost:8080
|
| 12 |
+
|
| 13 |
+
Only the Python standard library is used.
|
| 14 |
+
"""
|
| 15 |
+
|
| 16 |
+
import argparse
|
| 17 |
+
import json
|
| 18 |
+
import math
|
| 19 |
+
import urllib.request
|
| 20 |
+
|
| 21 |
+
LETTERS = "ABCDEFGHIJKLMNOPQRSTUVWXYZ"
|
| 22 |
+
HEADER = ("You are a decision function. Read the state, then answer the question "
|
| 23 |
+
"by choosing exactly one option.\n\n")
|
| 24 |
+
MAX_OPTIONS = 20 # servers return at most ~20 candidate tokens per position
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
def build_prompt(state, question, options):
|
| 28 |
+
lines = "\n".join(f"{LETTERS[i]}. {o}" for i, o in enumerate(options))
|
| 29 |
+
return f"{HEADER}[State]\n{state}\n\n[Question]\n{question}\n\n[Options]\n{lines}\n\nAnswer:"
|
| 30 |
+
|
| 31 |
+
|
| 32 |
+
def _post(url, payload):
|
| 33 |
+
req = urllib.request.Request(url, json.dumps(payload).encode(), {"Content-Type": "application/json"})
|
| 34 |
+
with urllib.request.urlopen(req, timeout=120) as r:
|
| 35 |
+
return json.loads(r.read())
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
def _top_logprobs(base_url, prompt, model):
|
| 39 |
+
"""-> {token_text: logprob} for the first generated position.
|
| 40 |
+
|
| 41 |
+
Uses /v1/chat/completions: the released model ships a pass-through chat template, so the
|
| 42 |
+
prompt reaches the model verbatim, and both LM Studio and llama-server return candidate
|
| 43 |
+
log-probs on this endpoint (LM Studio does not on /v1/completions).
|
| 44 |
+
"""
|
| 45 |
+
out = _post(base_url.rstrip("/") + "/v1/chat/completions",
|
| 46 |
+
{"model": model, "messages": [{"role": "user", "content": prompt}], "max_tokens": 1,
|
| 47 |
+
"temperature": 0, "logprobs": True, "top_logprobs": 20})
|
| 48 |
+
return {t["token"]: t["logprob"] for t in out["choices"][0]["logprobs"]["content"][0]["top_logprobs"]}
|
| 49 |
+
|
| 50 |
+
|
| 51 |
+
def decide(base_url, state, question, options, model="jev-style"):
|
| 52 |
+
"""Choice: -> list of (option, probability), most likely first."""
|
| 53 |
+
assert 2 <= len(options) <= MAX_OPTIONS
|
| 54 |
+
top = _top_logprobs(base_url, build_prompt(state, question, options), model)
|
| 55 |
+
floor = min(top.values()) - 5.0 # option letter outside the returned candidates: negligible mass
|
| 56 |
+
logits = [max((lp for tok, lp in top.items() if tok.strip() == LETTERS[i]), default=floor)
|
| 57 |
+
for i in range(len(options))]
|
| 58 |
+
z = max(logits)
|
| 59 |
+
exp = [math.exp(x - z) for x in logits]
|
| 60 |
+
probs = [e / sum(exp) for e in exp]
|
| 61 |
+
return sorted(zip(options, probs), key=lambda t: -t[1])
|
| 62 |
+
|
| 63 |
+
|
| 64 |
+
def decide_bool(base_url, state, proposition, model="jev-style"):
|
| 65 |
+
"""Bool: -> probability that the proposition is true."""
|
| 66 |
+
return dict(decide(base_url, state, proposition, ["yes", "no"], model))["yes"]
|
| 67 |
+
|
| 68 |
+
|
| 69 |
+
def decide_score(base_url, state, question, levels, model="jev-style"):
|
| 70 |
+
"""Score: ordered levels -> (expected level index in [0, len-1], distribution)."""
|
| 71 |
+
dist = dict(decide(base_url, state, question, levels, model))
|
| 72 |
+
return sum(i * dist[l] for i, l in enumerate(levels)), [(l, dist[l]) for l in levels]
|
| 73 |
+
|
| 74 |
+
|
| 75 |
+
if __name__ == "__main__":
|
| 76 |
+
ap = argparse.ArgumentParser()
|
| 77 |
+
ap.add_argument("--url", default="http://localhost:1234")
|
| 78 |
+
ap.add_argument("--model", default="jev-style-qwen3.5-2b-decision")
|
| 79 |
+
args = ap.parse_args()
|
| 80 |
+
url, mid = args.url, args.model
|
| 81 |
+
|
| 82 |
+
review = "The plot is thin, but the two leads are so charming that I left the cinema smiling."
|
| 83 |
+
print("Choice:", decide(url, review, "What is the sentiment of this review?", ["negative", "positive"], mid))
|
| 84 |
+
print("Score :", decide_score(url, review, "Rate the sentiment of this review on an ordered scale.",
|
| 85 |
+
["very negative", "negative", "neutral", "positive", "very positive"], mid))
|
| 86 |
+
print("Bool :", decide_bool(
|
| 87 |
+
url, "Premise: A man is playing a guitar on stage.\nHypothesis: Someone is performing music.",
|
| 88 |
+
"Does the premise entail the hypothesis?", mid))
|
| 89 |
+
news = "Shares of the chipmaker jumped 8% after it raised its full-year revenue forecast."
|
| 90 |
+
print("Choice:", decide(url, news, "Which news section does this article belong to?",
|
| 91 |
+
["World", "Sports", "Business", "Science/Technology"], mid))
|