

Publish completed v2 reporting artifacts; preserve frozen training revision
Browse files- README.md +24 -0
- REPORT.md +202 -0
- gradient-probe.json +0 -0
- native_cpu_smoke.json +12 -0
- report.json +0 -0
- share/SHARE.md +66 -0
- share/stage-comparison.metadata.json +119 -0
- share/stage-comparison.png +3 -0
README.md
ADDED
|
@@ -0,0 +1,24 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
tags: [openenv, synthetic, continual-learning, trackio]
|
| 4 |
+
---
|
| 5 |
+
|
| 6 |
+
# Plan My Day v2: measured follow-up
|
| 7 |
+
|
| 8 |
+
| Arm | Complete schedules | Conflict-free | Correction flags/day |
|
| 9 |
+
|---|---:|---:|---:|
|
| 10 |
+
| Frozen SFT + memory | 65.3% | 70.8% | 1.528 |
|
| 11 |
+
| Continued SFT | 84.3% | 85.2% | 0.829 |
|
| 12 |
+
| Corrected SDPO | 65.7% | 75.5% | 1.602 |
|
| 13 |
+
|
| 14 |
+
Final-stage means: 72 shared synthetic days, three optimizer seeds with one shared warm start; frozen comparator evaluated once. Four offered actions per decision, not general calendar generation. Correction flags are simulated public-cost judgments, not human time saved. These means alone do not establish significance, every-seed retention, monotonic improvement, or real-user efficacy. Training-time matching is approximate; SDPO and SFT see different prompt counts. The original experiment and live demo are unchanged. No personal edits were trained and nothing was posted socially.
|
| 15 |
+
|
| 16 |
+

|
| 17 |
+
|
| 18 |
+
[Full report and uncertainty](REPORT.md) · [Machine-readable results](report.json) · [Share copy and alt text](share/SHARE.md) · [Native integration smoke](native_cpu_smoke.json)
|
| 19 |
+
|
| 20 |
+
[Training-only estimator diagnostic](gradient-probe.json): no test data used; this is not causal proof of regression.
|
| 21 |
+
|
| 22 |
+
[Exact training source](https://huggingface.co/datasets/burtenshaw/plan-my-day-v2-source/tree/fa257386d857130bda7188c6df7e1fdeff20efc8) · [Exact synthetic data](https://huggingface.co/datasets/burtenshaw/plan-my-day-v2-data/tree/8b8f3763cdc52766e84791c28985539ff3db4f69) · [Trackio](https://huggingface.co/spaces/burtenshaw/plan-my-day-trackio)
|
| 23 |
+
|
| 24 |
+
Supplementary reporting scripts are published after completed runs; they do not change the original training source SHA. Code/data are Apache-2.0; separate model weights retain the LFM Open License v1.0.
|
REPORT.md
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Plan My Day v2: measured follow-up
|
| 2 |
+
|
| 3 |
+
Status: **complete**. Generated 2026-09-07T11:40:53.941193+00:00.
|
| 4 |
+
|
| 5 |
+
This report preserves the original pilot. It tests a corrected conversational teacher, matched four-action training probabilities, fixed-student mistake trajectories, and balanced replay.
|
| 6 |
+
|
| 7 |
+
## Teacher signal and development-only selection
|
| 8 |
+
|
| 9 |
+
Development status: **completed**.
|
| 10 |
+
|
| 11 |
+
Common pre-travel SFT baseline, evaluated with the same phase-three memory on all 72 development days: **79.2% complete schedules**, 0.167 hard violations/day, and 0.986 correction flags/day.
|
| 12 |
+
|
| 13 |
+
### Warm-start model
|
| 14 |
+
|
| 15 |
+
| Prompt condition | Accuracy | Correct-action probability | Accuracy on current mistakes | Correct-action probability on current mistakes |
|
| 16 |
+
|---|---:|---:|---:|---:|
|
| 17 |
+
| unconditioned | 59.4% | 49.7% | 0.0% | 18.1% |
|
| 18 |
+
| legacy_malformed | 94.8% | 72.1% | 89.7% | 59.8% |
|
| 19 |
+
| corrected_conversational | 97.9% | 74.9% | 94.9% | 62.7% |
|
| 20 |
+
|
| 21 |
+
Observed current mistakes: 39. Feedback probability gain on those mistakes: +44.7%; corrected-versus-malformed placement: +2.9% (absolute probability differences).
|
| 22 |
+
|
| 23 |
+
Legacy placement only, with the identical richer v2 feedback; not v1 wording replay.
|
| 24 |
+
|
| 25 |
+
### Common pre-travel SFT checkpoint
|
| 26 |
+
|
| 27 |
+
| Prompt condition | Accuracy | Correct-action probability | Accuracy on current mistakes | Correct-action probability on current mistakes |
|
| 28 |
+
|---|---:|---:|---:|---:|
|
| 29 |
+
| unconditioned | 70.8% | 67.8% | 0.0% | 13.8% |
|
| 30 |
+
| legacy_malformed | 94.8% | 84.5% | 82.1% | 68.8% |
|
| 31 |
+
| corrected_conversational | 97.9% | 92.7% | 92.9% | 80.5% |
|
| 32 |
+
|
| 33 |
+
Observed current mistakes: 28. Feedback probability gain on those mistakes: +66.7%; corrected-versus-malformed placement: +11.7% (absolute probability differences).
|
| 34 |
+
|
| 35 |
+
Legacy placement only, with the identical richer v2 feedback; not v1 wording replay.
|
| 36 |
+
|
| 37 |
+
Warm-start teacher gate: `{'correct_probability_gain_on_mistakes': 0.4465137207164215, 'mistake_count': 39, 'passed': True, 'required_gain': 0.05}`.
|
| 38 |
+
|
| 39 |
+
Pre-travel teacher gate: `{'correct_probability_gain_on_mistakes': 0.6671588645216876, 'mistake_count': 28, 'passed': True, 'required_gain': 0.05}`.
|
| 40 |
+
|
| 41 |
+
| Development candidate | Steps | Historical fraction | Distillation weight | Complete schedules | Hard violations/day | Correction flags/day | Promotion gate |
|
| 42 |
+
|---|---:|---:|---:|---:|---:|---:|---|
|
| 43 |
+
| develop-r25-w100-step64 | 64 | 25.0% | 1.0 | 68.1% | 0.264 | 1.153 | False |
|
| 44 |
+
| develop-r25-w100-step192 | 192 | 25.0% | 1.0 | 47.2% | 0.458 | 2.931 | False |
|
| 45 |
+
| develop-r25-w50-step64 | 64 | 25.0% | 0.5 | 68.1% | 0.278 | 1.250 | False |
|
| 46 |
+
| develop-r25-w50-step192 | 192 | 25.0% | 0.5 | 59.7% | 0.347 | 1.542 | False |
|
| 47 |
+
| develop-r50-w100-step64 | 64 | 50.0% | 1.0 | 59.7% | 0.125 | 1.722 | False |
|
| 48 |
+
| develop-r50-w100-step192 | 192 | 50.0% | 1.0 | 63.9% | 0.319 | 1.250 | False |
|
| 49 |
+
| develop-r50-w50-step64 | 64 | 50.0% | 0.5 | 63.9% | 0.153 | 1.736 | False |
|
| 50 |
+
| develop-r50-w50-step192 | 192 | 50.0% | 0.5 | 65.3% | 0.194 | 0.931 | False |
|
| 51 |
+
|
| 52 |
+
Frozen selection: `{'distillation_weight': 1.0, 'lr': 3e-05, 'name': 'r50-w100', 'replay_fraction': 0.5, 'steps': 64}`. Continued-SFT budget: **110 updates/phase**.
|
| 53 |
+
|
| 54 |
+
Selection label: **diagnostic only; no promotion**; eligible development candidates: 0. approximate training wall time, excluding evaluation/upload callbacks; not FLOPs.
|
| 55 |
+
|
| 56 |
+
## Confirmatory held-out results
|
| 57 |
+
|
| 58 |
+
72 shared test days; optimizer seeds 17, 29, 43. The frozen comparator is evaluated once per phase. All trained values below are means of seed-level means.
|
| 59 |
+
|
| 60 |
+
| Arm | After phase | Complete schedules | Conflict-free final schedules | Hard violations/day | Correction flags/day | Deferred tasks/day |
|
| 61 |
+
|---|---|---:|---:|---:|---:|---:|
|
| 62 |
+
| Frozen SFT + memory | 1: normal | 63.9% | 69.4% | 0.375 | 1.556 | 0.111 |
|
| 63 |
+
| Frozen SFT + memory | 2: deadline | 61.1% | 66.7% | 0.472 | 1.556 | 0.083 |
|
| 64 |
+
| Frozen SFT + memory | 3: travel | 65.3% | 70.8% | 0.361 | 1.528 | 0.069 |
|
| 65 |
+
| Continued SFT + memory | 1: normal | 79.6% | 81.5% | 0.185 | 1.093 | 0.019 |
|
| 66 |
+
| Continued SFT + memory | 2: deadline | 77.8% | 80.1% | 0.199 | 0.931 | 0.028 |
|
| 67 |
+
| Continued SFT + memory | 3: travel | 84.3% | 85.2% | 0.148 | 0.829 | 0.009 |
|
| 68 |
+
| Corrected SDPO + memory | 1: normal | 67.6% | 73.1% | 0.296 | 1.352 | 0.088 |
|
| 69 |
+
| Corrected SDPO + memory | 2: deadline | 65.3% | 72.2% | 0.329 | 1.542 | 0.088 |
|
| 70 |
+
| Corrected SDPO + memory | 3: travel | 65.7% | 75.5% | 0.301 | 1.602 | 0.204 |
|
| 71 |
+
|
| 72 |
+
### Paired SDPO minus SFT differences
|
| 73 |
+
|
| 74 |
+
| Stage | Complete schedules, percentage points [95% CI] | Hard violations/day [95% CI] | Correction flags/day [95% CI] |
|
| 75 |
+
|---|---:|---:|---:|
|
| 76 |
+
| 1 | -12.037 [-20.370, -3.704] | +0.111 [+0.019, +0.204] | +0.259 [+0.125, +0.384] |
|
| 77 |
+
| 2 | -12.500 [-21.308, -3.241] | +0.130 [+0.032, +0.231] | +0.611 [+0.449, +0.778] |
|
| 78 |
+
| 3 | -18.519 [-25.926, -10.648] | +0.153 [+0.060, +0.245] | +0.773 [+0.648, +0.898] |
|
| 79 |
+
|
| 80 |
+
Positive completion differences favor SDPO; negative violation/correction differences favor SDPO. Percentile intervals bootstrap the same day IDs jointly across all seed pairs, averaging seeds within each day. They are conditional on these three optimizer seeds and their shared v1 SFT warm start: not 216 independent test days, three independent pretrained models, or uncertainty over every possible training run.
|
| 81 |
+
|
| 82 |
+
### Seed-specific raw checkpoint gates
|
| 83 |
+
|
| 84 |
+
| Arm | Seed | Stage | Versus phase-matched frozen | Versus preceding stage, all weeks | Earlier-week retention |
|
| 85 |
+
|---|---:|---:|---|---|---|
|
| 86 |
+
| sft | 17 | 1 | PASS | n/a | n/a |
|
| 87 |
+
| sft | 17 | 2 | FAIL | FAIL | FAIL |
|
| 88 |
+
| sft | 17 | 3 | PASS | PASS | PASS |
|
| 89 |
+
| sft | 29 | 1 | PASS | n/a | n/a |
|
| 90 |
+
| sft | 29 | 2 | PASS | PASS | PASS |
|
| 91 |
+
| sft | 29 | 3 | PASS | FAIL | FAIL |
|
| 92 |
+
| sft | 43 | 1 | PASS | n/a | n/a |
|
| 93 |
+
| sft | 43 | 2 | PASS | FAIL | FAIL |
|
| 94 |
+
| sft | 43 | 3 | PASS | FAIL | FAIL |
|
| 95 |
+
| sdpo | 17 | 1 | PASS | n/a | n/a |
|
| 96 |
+
| sdpo | 17 | 2 | FAIL | FAIL | FAIL |
|
| 97 |
+
| sdpo | 17 | 3 | FAIL | PASS | PASS |
|
| 98 |
+
| sdpo | 29 | 1 | FAIL | n/a | n/a |
|
| 99 |
+
| sdpo | 29 | 2 | PASS | FAIL | FAIL |
|
| 100 |
+
| sdpo | 29 | 3 | FAIL | FAIL | FAIL |
|
| 101 |
+
| sdpo | 43 | 1 | FAIL | n/a | n/a |
|
| 102 |
+
| sdpo | 43 | 2 | FAIL | FAIL | PASS |
|
| 103 |
+
| sdpo | 43 | 3 | FAIL | FAIL | FAIL |
|
| 104 |
+
|
| 105 |
+
Gates require no measured worsening in hard violations, final conflict-free rate, or complete schedules overall and in each compared week. Correction counts cannot override failures. These are raw checkpoint checks, not a test-selected checkpoint or automatic deployment.
|
| 106 |
+
|
| 107 |
+
### Week-specific means
|
| 108 |
+
|
| 109 |
+
| Arm | Stage | Test week | Complete schedules | Hard violations/day | Correction flags/day |
|
| 110 |
+
|---|---:|---|---:|---:|---:|
|
| 111 |
+
| frozen_sft | 1 | normal | 62.5% | 0.333 | 1.458 |
|
| 112 |
+
| frozen_sft | 1 | deadline | 62.5% | 0.417 | 1.458 |
|
| 113 |
+
| frozen_sft | 1 | travel | 66.7% | 0.375 | 1.750 |
|
| 114 |
+
| frozen_sft | 2 | normal | 62.5% | 0.333 | 1.458 |
|
| 115 |
+
| frozen_sft | 2 | deadline | 58.3% | 0.458 | 1.750 |
|
| 116 |
+
| frozen_sft | 2 | travel | 62.5% | 0.625 | 1.458 |
|
| 117 |
+
| frozen_sft | 3 | normal | 62.5% | 0.333 | 1.458 |
|
| 118 |
+
| frozen_sft | 3 | deadline | 58.3% | 0.458 | 1.750 |
|
| 119 |
+
| frozen_sft | 3 | travel | 75.0% | 0.292 | 1.375 |
|
| 120 |
+
| sft | 1 | normal | 77.8% | 0.208 | 0.861 |
|
| 121 |
+
| sft | 1 | deadline | 84.7% | 0.153 | 1.042 |
|
| 122 |
+
| sft | 1 | travel | 76.4% | 0.194 | 1.375 |
|
| 123 |
+
| sft | 2 | normal | 76.4% | 0.236 | 0.833 |
|
| 124 |
+
| sft | 2 | deadline | 83.3% | 0.167 | 0.889 |
|
| 125 |
+
| sft | 2 | travel | 73.6% | 0.194 | 1.069 |
|
| 126 |
+
| sft | 3 | normal | 83.3% | 0.167 | 0.833 |
|
| 127 |
+
| sft | 3 | deadline | 86.1% | 0.139 | 0.833 |
|
| 128 |
+
| sft | 3 | travel | 83.3% | 0.139 | 0.819 |
|
| 129 |
+
| sdpo | 1 | normal | 62.5% | 0.319 | 1.139 |
|
| 130 |
+
| sdpo | 1 | deadline | 73.6% | 0.222 | 1.264 |
|
| 131 |
+
| sdpo | 1 | travel | 66.7% | 0.347 | 1.653 |
|
| 132 |
+
| sdpo | 2 | normal | 66.7% | 0.292 | 1.347 |
|
| 133 |
+
| sdpo | 2 | deadline | 68.1% | 0.361 | 1.514 |
|
| 134 |
+
| sdpo | 2 | travel | 61.1% | 0.333 | 1.764 |
|
| 135 |
+
| sdpo | 3 | normal | 68.1% | 0.333 | 1.569 |
|
| 136 |
+
| sdpo | 3 | deadline | 72.2% | 0.236 | 1.597 |
|
| 137 |
+
| sdpo | 3 | travel | 56.9% | 0.333 | 1.639 |
|
| 138 |
+
|
| 139 |
+
### Per-seed means
|
| 140 |
+
|
| 141 |
+
| Arm | Stage | Seed | Complete schedules | Hard violations/day | Correction flags/day |
|
| 142 |
+
|---|---:|---:|---:|---:|---:|
|
| 143 |
+
| frozen_sft | 1 | single frozen evaluation | 63.9% | 0.375 | 1.556 |
|
| 144 |
+
| frozen_sft | 2 | single frozen evaluation | 61.1% | 0.472 | 1.556 |
|
| 145 |
+
| frozen_sft | 3 | single frozen evaluation | 65.3% | 0.361 | 1.528 |
|
| 146 |
+
| sft | 1 | 17 | 77.8% | 0.194 | 1.139 |
|
| 147 |
+
| sft | 1 | 29 | 77.8% | 0.208 | 1.014 |
|
| 148 |
+
| sft | 1 | 43 | 83.3% | 0.153 | 1.125 |
|
| 149 |
+
| sft | 2 | 17 | 66.7% | 0.306 | 1.125 |
|
| 150 |
+
| sft | 2 | 29 | 88.9% | 0.083 | 1.000 |
|
| 151 |
+
| sft | 2 | 43 | 77.8% | 0.208 | 0.667 |
|
| 152 |
+
| sft | 3 | 17 | 79.2% | 0.208 | 0.819 |
|
| 153 |
+
| sft | 3 | 29 | 84.7% | 0.139 | 0.847 |
|
| 154 |
+
| sft | 3 | 43 | 88.9% | 0.097 | 0.819 |
|
| 155 |
+
| sdpo | 1 | 17 | 80.6% | 0.181 | 1.222 |
|
| 156 |
+
| sdpo | 1 | 29 | 66.7% | 0.319 | 1.181 |
|
| 157 |
+
| sdpo | 1 | 43 | 55.6% | 0.389 | 1.653 |
|
| 158 |
+
| sdpo | 2 | 17 | 66.7% | 0.361 | 1.250 |
|
| 159 |
+
| sdpo | 2 | 29 | 69.4% | 0.319 | 1.653 |
|
| 160 |
+
| sdpo | 2 | 43 | 59.7% | 0.306 | 1.722 |
|
| 161 |
+
| sdpo | 3 | 17 | 75.0% | 0.167 | 1.097 |
|
| 162 |
+
| sdpo | 3 | 29 | 69.4% | 0.292 | 1.319 |
|
| 163 |
+
| sdpo | 3 | 43 | 52.8% | 0.444 | 2.389 |
|
| 164 |
+
|
| 165 |
+
## Runtime, exposure, and compute
|
| 166 |
+
|
| 167 |
+
Development-calibrated approximate training wall time, not equal optimizer steps, examples, tokens, or FLOPs.
|
| 168 |
+
|
| 169 |
+
| Phase of experiment | Arm | Completed training segments | Optimizer updates | Training seconds excluding callbacks |
|
| 170 |
+
|---|---|---:|---:|---:|
|
| 171 |
+
| develop | sdpo | 4 | 768 | 723.306 |
|
| 172 |
+
| develop | sft | 2 | 128 | 69.881 |
|
| 173 |
+
| final | sdpo | 9 | 576 | 542.453 |
|
| 174 |
+
| final | sft | 9 | 990 | 533.069 |
|
| 175 |
+
|
| 176 |
+
Exposure is not equal just because updates match: SFT nominally presents four examples/update; SDPO draws one prompt with four sampled one-token actions/update. Dataset composition, native observed generation counts, distinct prompt texts, nominal exposures, optimizer continuity, reported token metrics, and individual timings are retained in report.json when present in the source artifacts. Repeated prompt draws are not distinct examples.
|
| 177 |
+
|
| 178 |
+
Recorded Job running time: 4691.000 seconds across 4/4 timed Jobs. Estimated compute: **$1.3031**, covering 4/4 recorded Jobs.
|
| 179 |
+
|
| 180 |
+
Only recorded v2 Job compute, including recorded failed attempts. Estimates are not invoices and exclude hosting, prior pilot runs, and other services.
|
| 181 |
+
|
| 182 |
+
## Boundaries and provenance
|
| 183 |
+
|
| 184 |
+
- Synthetic public-rubric feedback and four offered actions, not measured human effort or real-user efficacy.
|
| 185 |
+
- Correction flags are the original cost-minimization metric, not actual corrections automatically applied to trajectories.
|
| 186 |
+
- Complete schedule means final_feasible and zero deferred tasks; original metrics remain available unchanged.
|
| 187 |
+
- The frozen SFT comparator retains the shared warm-start adapter and receives phase-limited memory; it is evaluated once, not triplicated as an optimizer replicate.
|
| 188 |
+
- Matched teacher-prompt diagnostics use identical v2 feedback in both placements, not an exact v1-wording replay.
|
| 189 |
+
- Paired intervals resample shared day IDs jointly across three observed optimizer seeds; 216 seed/day evaluations are not 216 independent days.
|
| 190 |
+
- All optimizer seeds share one v1 SFT warm-start checkpoint and one pretrained base; uncertainty is conditional on that shared warm start, not three independent pretrained-model replicates.
|
| 191 |
+
- Passing descriptive checkpoint gates is not a statistical guarantee, monotonic learning claim, or live-demo promotion.
|
| 192 |
+
- The fixed collector supplies identical historical student-state data; this is not continually recollected on-policy data for each changing arm.
|
| 193 |
+
|
| 194 |
+
```json
|
| 195 |
+
{
|
| 196 |
+
"data_revision": "8b8f3763cdc52766e84791c28985539ff3db4f69",
|
| 197 |
+
"ledger_hash": "bd33e30f144155374d5af22484cd3d7cdaa575a32f037b51c104547361506ec0",
|
| 198 |
+
"manifest_hash": "45c8c60816f6f02f064ec905ec6240c9d6631ef49182a98c04558bbd5953b8c3",
|
| 199 |
+
"source_revision": "fa257386d857130bda7188c6df7e1fdeff20efc8",
|
| 200 |
+
"development_revision": "3e003eb15fb6a407cf63bdeb968f6b55b96c6ebe"
|
| 201 |
+
}
|
| 202 |
+
```
|
gradient-probe.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
native_cpu_smoke.json
ADDED
|
@@ -0,0 +1,12 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"scope": "Integration smoke only: randomly initialized tiny Llama, pinned production tokenizer, native SDPO trainer and real correction prompt format. Not a task-performance measurement.",
|
| 3 |
+
"optimizer_steps": 2,
|
| 4 |
+
"training_loss": -0.0007046948303468525,
|
| 5 |
+
"first_grad_norm": 0.01433,
|
| 6 |
+
"second_grad_norm": 0.005746,
|
| 7 |
+
"completion_tokens": 1,
|
| 8 |
+
"feedback_used_fraction": 1.0,
|
| 9 |
+
"reprompt_sample_fraction": 1.0,
|
| 10 |
+
"loss_support": ["A", "B", "C", "D"],
|
| 11 |
+
"passed": true
|
| 12 |
+
}
|
report.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
share/SHARE.md
ADDED
|
@@ -0,0 +1,66 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Plan My Day v2: ready-to-share evidence
|
| 2 |
+
|
| 3 |
+
Drafts only. Nothing has been posted.
|
| 4 |
+
|
| 5 |
+
## Tweet
|
| 6 |
+
|
| 7 |
+
Calendar learning, round 2: SDPO 65.7% vs SFT 84.3% complete schedules. Diagnostic recipe; no development promotion.
|
| 8 |
+
|
| 9 |
+
72 synthetic days, 3 optimizer seeds, shared warm start. Four-choice task.
|
| 10 |
+
https://huggingface.co/datasets/burtenshaw/plan-my-day-v2-results
|
| 11 |
+
|
| 12 |
+
Raw character count: 258/280 (including the full URL).
|
| 13 |
+
|
| 14 |
+
## Longer caption
|
| 15 |
+
|
| 16 |
+
Can a small planner learn from its mistakes without forgetting what already worked?
|
| 17 |
+
|
| 18 |
+
The follow-up did not produce a clean SDPO win over continued SFT on safety plus completion. Final mean complete schedules: SDPO 65.7%, SFT 84.3% (-18.5 percentage points). The useful result is a better-controlled experiment and an explicit account of the remaining failures.
|
| 19 |
+
|
| 20 |
+
I kept the same 1.2B model and shared SFT warm start, then repaired the experiment: feedback now appears before the assistant answer begins; native SDPO probabilities use the same four-action support as evaluation; training examples contain the frozen student's actual mistakes; and historical replay is balanced. The recipe was selected on development days before the new test set was evaluated.
|
| 21 |
+
|
| 22 |
+
| Final-stage policy | Complete schedules | Conflict-free final schedules | Hard violations/day | Original correction flags/day |
|
| 23 |
+
|---|---:|---:|---:|---:|
|
| 24 |
+
| Frozen SFT + memory | 65.3% | 70.8% | 0.361 | 1.528 |
|
| 25 |
+
| Continued SFT + memory | 84.3% | 85.2% | 0.148 | 0.829 |
|
| 26 |
+
| Corrected SDPO + memory | 65.7% | 75.5% | 0.301 | 1.602 |
|
| 27 |
+
|
| 28 |
+
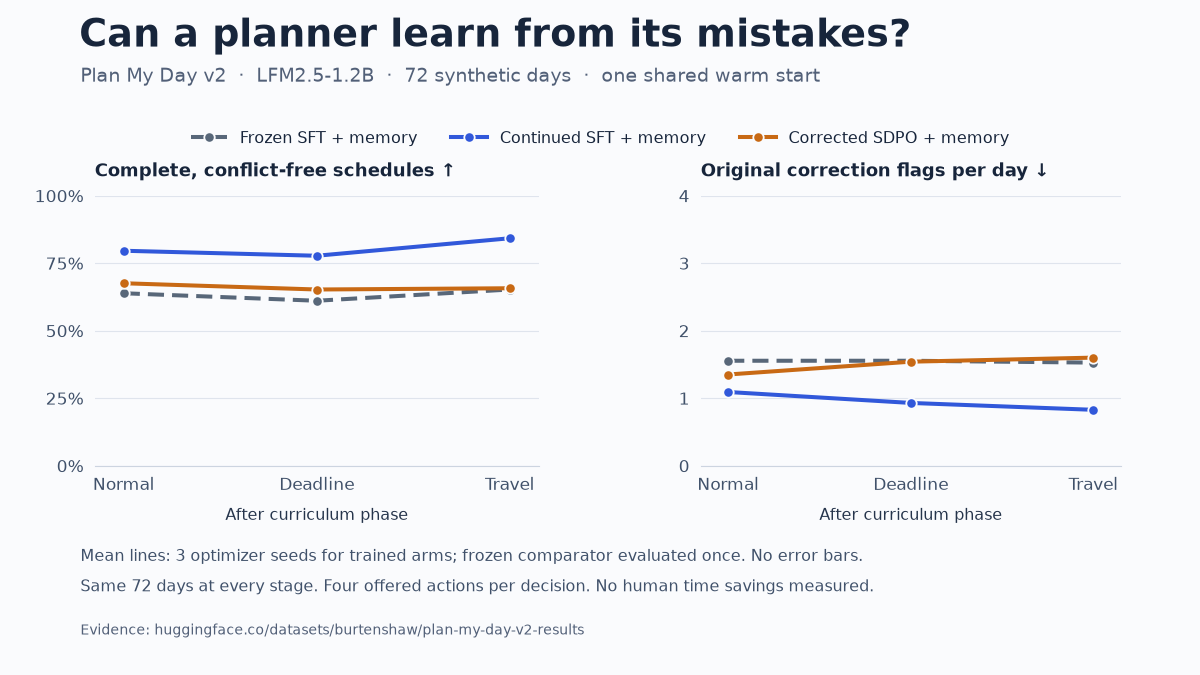
The chart shows all three curriculum stages, not just the endpoint. Lines are measured means, with no uncertainty bands. The full report separately includes paired day-cluster intervals and every optimizer-seed result.
|
| 29 |
+
|
| 30 |
+
- Continued SFT + memory: mean completion was not monotonic across the three phases.
|
| 31 |
+
- Corrected SDPO + memory: mean completion was not monotonic across the three phases.
|
| 32 |
+
|
| 33 |
+
Raw final-checkpoint retention checks:
|
| 34 |
+
- sft: 3/3 seeds passed the phase-matched frozen comparator gate; 1/3 passed earlier-week retention versus the previous stage.
|
| 35 |
+
- sdpo: 0/3 seeds passed the phase-matched frozen comparator gate; 1/3 passed earlier-week retention versus the previous stage.
|
| 36 |
+
|
| 37 |
+
No screened development candidate passed the full promotion gate. The selected recipe was explicitly diagnostic, not eligible for automatic deployment.
|
| 38 |
+
|
| 39 |
+
## Important boundaries
|
| 40 |
+
|
| 41 |
+
- This is a synthetic four-choice planning task, not unrestricted calendar generation or demonstrated real-user benefit.
|
| 42 |
+
- The 72 test days are shared across three optimizer seeds and all stages. Those are not 216 independent days or three independently pretrained models; all runs share one v1 SFT warm start.
|
| 43 |
+
- Complete schedules means no final hard violations and no deferred tasks. Correction flags remain the original public-cost metric; no human time savings were measured.
|
| 44 |
+
- The frozen comparator keeps the same warm-start adapter and receives phase-limited correction memory; it is evaluated once per phase, not counted as three training replicates.
|
| 45 |
+
- All arms use one fixed student-collected correction ledger. This follow-up does not continuously recollect data from each changing model.
|
| 46 |
+
- Continued-SFT compute was approximately matched using development training wall time, not identical steps, examples, tokens, or FLOPs.
|
| 47 |
+
- A higher final mean does not establish monotonic learning, every-seed retention, or statistical significance. Use the complete report and gates.
|
| 48 |
+
- No personal calendar data was used, no visitor edits trained the weights, and no public demo was automatically replaced by this report.
|
| 49 |
+
|
| 50 |
+
## Links
|
| 51 |
+
|
| 52 |
+
- [Results and complete evidence](https://huggingface.co/datasets/burtenshaw/plan-my-day-v2-results)
|
| 53 |
+
- [Source and frozen protocol](https://huggingface.co/datasets/burtenshaw/plan-my-day-v2-source)
|
| 54 |
+
- [Trackio dashboard](https://huggingface.co/spaces/burtenshaw/plan-my-day-trackio) — choose project `plan-my-day-v2`.
|
| 55 |
+
|
| 56 |
+
## Figure
|
| 57 |
+
|
| 58 |
+
Attach `stage-comparison.png` (1200 × 675).
|
| 59 |
+
|
| 60 |
+
Alt text:
|
| 61 |
+
|
| 62 |
+
Two-panel Plan My Day v2 chart. Horizontal axis: after normal, deadline, and travel training phases. Frozen SFT + memory: complete schedules 63.9%, 61.1%, 65.3%; simulated correction flags per day 1.556, 1.556, 1.528. Continued SFT + memory: complete schedules 79.6%, 77.8%, 84.3%; simulated correction flags per day 1.093, 0.931, 0.829. Corrected SDPO + memory: complete schedules 67.6%, 65.3%, 65.7%; simulated correction flags per day 1.352, 1.542, 1.602. Same 72 synthetic days at each stage; four offered actions per decision. Trained lines average three optimizer seeds sharing one warm start; frozen comparator evaluated once. No error bars or confidence bands.
|
| 63 |
+
|
| 64 |
+
## Short demo narration
|
| 65 |
+
|
| 66 |
+
Start with a day that needs repairing after an interruption. Show the same offered actions before and after training. Then reveal all three stage curves and the original correction-count metric. Close on the failed retention gates, if any, and link the full evidence. Do not label a hand-picked example as the aggregate result.
|
share/stage-comparison.metadata.json
ADDED
|
@@ -0,0 +1,119 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"alt_text": "Two-panel Plan My Day v2 chart. Horizontal axis: after normal, deadline, and travel training phases. Frozen SFT + memory: complete schedules 63.9%, 61.1%, 65.3%; simulated correction flags per day 1.556, 1.556, 1.528. Continued SFT + memory: complete schedules 79.6%, 77.8%, 84.3%; simulated correction flags per day 1.093, 0.931, 0.829. Corrected SDPO + memory: complete schedules 67.6%, 65.3%, 65.7%; simulated correction flags per day 1.352, 1.542, 1.602. Same 72 synthetic days at each stage; four offered actions per decision. Trained lines average three optimizer seeds sharing one warm start; frozen comparator evaluated once. No error bars or confidence bands.",
|
| 3 |
+
"chart_values": {
|
| 4 |
+
"frozen_sft": {
|
| 5 |
+
"complete_schedule": [
|
| 6 |
+
0.6388888888888888,
|
| 7 |
+
0.6111111111111112,
|
| 8 |
+
0.6527777777777778
|
| 9 |
+
],
|
| 10 |
+
"constraint_violations": [
|
| 11 |
+
0.375,
|
| 12 |
+
0.4722222222222222,
|
| 13 |
+
0.3611111111111111
|
| 14 |
+
],
|
| 15 |
+
"decisions": [
|
| 16 |
+
4.0,
|
| 17 |
+
4.0,
|
| 18 |
+
4.0
|
| 19 |
+
],
|
| 20 |
+
"final_feasible": [
|
| 21 |
+
0.6944444444444444,
|
| 22 |
+
0.6666666666666666,
|
| 23 |
+
0.7083333333333334
|
| 24 |
+
],
|
| 25 |
+
"simulated_interventions": [
|
| 26 |
+
1.5555555555555556,
|
| 27 |
+
1.5555555555555556,
|
| 28 |
+
1.5277777777777777
|
| 29 |
+
]
|
| 30 |
+
},
|
| 31 |
+
"sdpo": {
|
| 32 |
+
"complete_schedule": [
|
| 33 |
+
0.6759259259259259,
|
| 34 |
+
0.6527777777777778,
|
| 35 |
+
0.6574074074074074
|
| 36 |
+
],
|
| 37 |
+
"constraint_violations": [
|
| 38 |
+
0.2962962962962963,
|
| 39 |
+
0.3287037037037037,
|
| 40 |
+
0.30092592592592593
|
| 41 |
+
],
|
| 42 |
+
"decisions": [
|
| 43 |
+
4.0,
|
| 44 |
+
4.0,
|
| 45 |
+
4.0
|
| 46 |
+
],
|
| 47 |
+
"final_feasible": [
|
| 48 |
+
0.7314814814814815,
|
| 49 |
+
0.7222222222222222,
|
| 50 |
+
0.7546296296296297
|
| 51 |
+
],
|
| 52 |
+
"simulated_interventions": [
|
| 53 |
+
1.3518518518518519,
|
| 54 |
+
1.5416666666666667,
|
| 55 |
+
1.6018518518518519
|
| 56 |
+
]
|
| 57 |
+
},
|
| 58 |
+
"sft": {
|
| 59 |
+
"complete_schedule": [
|
| 60 |
+
0.7962962962962963,
|
| 61 |
+
0.7777777777777778,
|
| 62 |
+
0.8425925925925926
|
| 63 |
+
],
|
| 64 |
+
"constraint_violations": [
|
| 65 |
+
0.1851851851851852,
|
| 66 |
+
0.19907407407407407,
|
| 67 |
+
0.14814814814814814
|
| 68 |
+
],
|
| 69 |
+
"decisions": [
|
| 70 |
+
4.0,
|
| 71 |
+
4.0,
|
| 72 |
+
4.0
|
| 73 |
+
],
|
| 74 |
+
"final_feasible": [
|
| 75 |
+
0.8148148148148148,
|
| 76 |
+
0.8009259259259259,
|
| 77 |
+
0.8518518518518519
|
| 78 |
+
],
|
| 79 |
+
"simulated_interventions": [
|
| 80 |
+
1.0925925925925926,
|
| 81 |
+
0.9305555555555556,
|
| 82 |
+
0.8287037037037037
|
| 83 |
+
]
|
| 84 |
+
}
|
| 85 |
+
},
|
| 86 |
+
"created_at": "2026-09-07T11:41:03.542014+00:00",
|
| 87 |
+
"figure_sha256": "8937aa58adbdef8c47cc0000b32e6b249d64c9061905a52f78567ac0440d3b72",
|
| 88 |
+
"generator_sha256": "02882990b0b309ace012291b8595f0dcc5442580cc60a57346214bf5a8266164",
|
| 89 |
+
"headline_boundary": "Positive wording also requires development eligibility and all three final SDPO retention gates; descriptive checks, not statistical significance or general deployment safety.",
|
| 90 |
+
"links": {
|
| 91 |
+
"results": "https://huggingface.co/datasets/burtenshaw/plan-my-day-v2-results",
|
| 92 |
+
"source": "https://huggingface.co/datasets/burtenshaw/plan-my-day-v2-source",
|
| 93 |
+
"trackio": "https://huggingface.co/spaces/burtenshaw/plan-my-day-trackio"
|
| 94 |
+
},
|
| 95 |
+
"no_uncertainty_bands": true,
|
| 96 |
+
"pixels": [
|
| 97 |
+
1200,
|
| 98 |
+
675
|
| 99 |
+
],
|
| 100 |
+
"positive_sdpo_story": false,
|
| 101 |
+
"positive_story_checks": {
|
| 102 |
+
"all_final_sdpo_earlier_week_retention_passed": false,
|
| 103 |
+
"development_promotion_eligible": false,
|
| 104 |
+
"sdpo_higher_mean_complete_schedule": false,
|
| 105 |
+
"sdpo_no_higher_mean_hard_violations": false,
|
| 106 |
+
"sdpo_no_lower_mean_conflict_free_rate": false
|
| 107 |
+
},
|
| 108 |
+
"provenance": {
|
| 109 |
+
"data_revision": "8b8f3763cdc52766e84791c28985539ff3db4f69",
|
| 110 |
+
"ledger_hash": "bd33e30f144155374d5af22484cd3d7cdaa575a32f037b51c104547361506ec0",
|
| 111 |
+
"manifest_hash": "45c8c60816f6f02f064ec905ec6240c9d6631ef49182a98c04558bbd5953b8c3",
|
| 112 |
+
"source_revision": "fa257386d857130bda7188c6df7e1fdeff20efc8"
|
| 113 |
+
},
|
| 114 |
+
"raw_tweet_characters": 258,
|
| 115 |
+
"report_generated_at": "2026-09-07T11:40:53.941193+00:00",
|
| 116 |
+
"report_sha256": "669c56a9148bc3e9c0ffc56684d539add18528cf65d648ae1aef08c79a5b5b91",
|
| 117 |
+
"social_posted": false,
|
| 118 |
+
"tweet": "Calendar learning, round 2: SDPO 65.7% vs SFT 84.3% complete schedules. Diagnostic recipe; no development promotion.\n\n72 synthetic days, 3 optimizer seeds, shared warm start. Four-choice task.\nhttps://huggingface.co/datasets/burtenshaw/plan-my-day-v2-results"
|
| 119 |
+
}
|
share/stage-comparison.png
ADDED
|
Git LFS Details
|