
Datasets:

sub-10 GB Qwen3.8-27B: Underdog-Saluki-27B study (report, chart, second_tier.csv rows, Field Reports row)
Browse files- dataset/README.md +1 -0
- dataset/second_tier.csv +4 -0
- reports/second-tier-thinkon-16k.md +1 -1
- reports/sub10-qwen38-27b.md +93 -0
- reports/sub10-qwen38-27b.png +3 -0
dataset/README.md
CHANGED
|
@@ -239,6 +239,7 @@ One-shot investigations that don't fit the leaderboard format — claim verifica
|
|
| 239 |
|
| 240 |
| Report | Finding |
|
| 241 |
|---|---|
|
|
|
|
| 242 |
| [This year's AIME and HMMT at a 32k thinking budget: nine local models against their MATH-500 order](reports/matharena-contests-32k.md) · [chart](reports/matharena-contests-32k.png) | The nine second-tier think-on rows on AIME 2026 (30) + HMMT Feb 2026 (33), MathArena sets, `max_tokens 32768`, `ctx 40960`, greedy, strict sympy grader plus an exact-number veto (0 fired; veto takes agreement with MathArena's labels on HMMT from 98.3% to 99.6%). Gemma 4 31B QAT Q4_0 51/63 (third on MATH-500 at 94.0), Qwen3.8-27B UD-IQ3_XXS 48, Q6_K 47, Ornith 1.5 35B 43, Qwen3.6-27B 37, Qwen3.6-35B-A3B 35, Nemotron 3.5 Lightning 34, Ornith 1.5 9B 29, Qwable-27B 29. Gemma's median completion is 8,259.5 / 8,963 tokens and none of its 63 hit the cap; the other eight capped on 6 to 22 problems per contest and are right on 95.5 to 100% of the answers they finish. 13 of 207 capped answers credited. Gemma vs the Qwen3.8 rows is not significant on 63 problems (paired p = 0.45 / 0.34). |
|
| 243 |
| [GPQA Diamond at a 32k thinking budget: the three rows that capped at 16k](reports/gpqa-thinkon-32k.md) | Same 198 questions, only `max_tokens` moved (16,384 to 32,768). Qwable-27B 78.28 to 85.35, Nemotron 3.5 Lightning 30B-A3B 60.61 to 67.17, Qwen3.6-27B 76.77 to 79.80. Every answer that finished inside 16k got the same verdict and completion length at 32k (444/444); every gain is a question that had hit the cap. Nemotron still caps on 19.7% at 32k (a floor). |
|
| 244 |
| [Speculative decoding and prefix caching on one RTX 5090, Qwen3.8-27B Q6_K: the two free speedups on the model this box now serves](reports/spec-cache-study-qwen38.md) · [chart](reports/spec-cache-study-qwen38.png) | Rerun of the spec-cache study on Qwen3.8-27B Q6_K (the served model since 2026-09-13, own MTP head in the unsloth GGUF), same 304-request design, same flag set (llama.cpp b9653, ctx 64k, parallel 1, KV q8_0, batch 1). MTP n=2 lifts decode from 61 to 109-144 tok/s (1.8x prose and chat, 2.3x code and repetitive) for +9 ms TTFT; n=4 reaches 168-184 on code/repetitive and loses 5-8% on prose/chat; n-gram lookup is 1.00x. Prefix cache: TTFT 1.004 s to 0.069 s on a 2,954-token system prompt (15x), 3.814 s to 0.086 s on 11,570 tokens (44x), decode unchanged. Stacked, a short answer to the 11.5k context goes 4.25 s to 0.30 s. Losslessness: MTP byte-identical to plain greedy decode on 59% of answers; all 13 divergences are the target's own second choice at a near-tie (top-2 gap 0.004 to 0.133 nats, median 0.030). Every cell within noise of the Qwen3.6-27B run a week earlier: the speedups belong to the shape and the serving stack, not the generation. |
|
|
|
|
| 239 |
|
| 240 |
| Report | Finding |
|
| 241 |
|---|---|
|
| 242 |
+
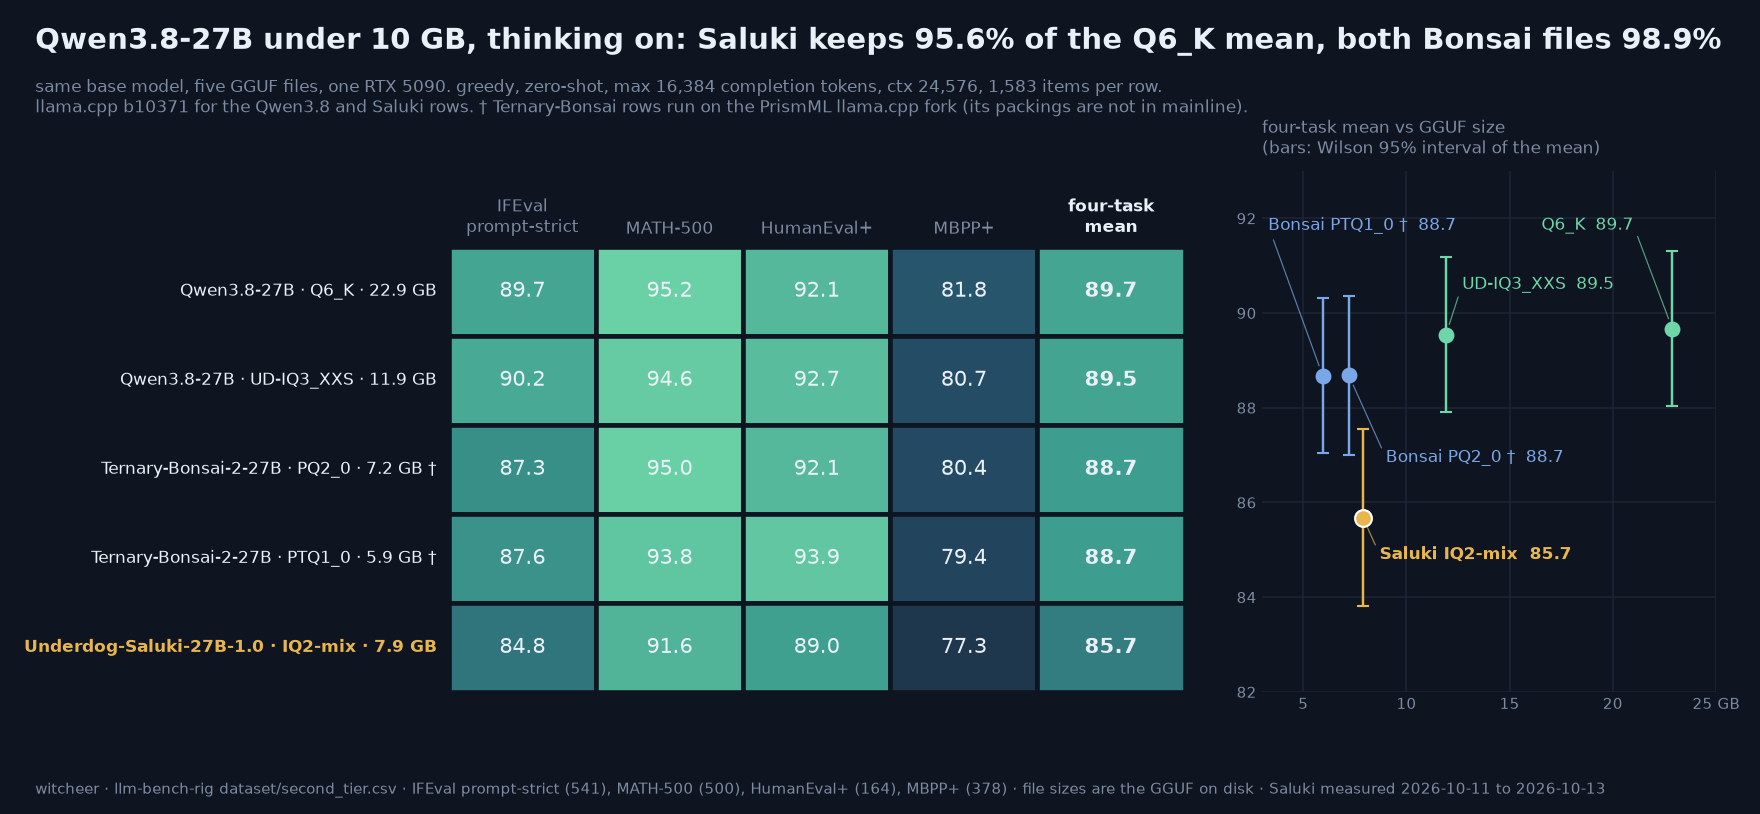
| [Qwen3.8-27B under 10 GB, thinking on: Underdog-Saluki-27B against the 3-bit and ternary files](reports/sub10-qwen38-27b.md) · [chart](reports/sub10-qwen38-27b.png) | Underdog-Saluki-27B-1.0 IQ2-mix (7.9 GB, stock llama.cpp) on the second-tier think-on 16k board, 1,583 items: four-task mean 85.68 against Qwen3.8-27B Q6_K 89.67, UD-IQ3_XXS 89.54, Ternary-Bonsai-2-27B PQ2_0 88.69 and PTQ1_0 88.67 (PrismML fork). Saluki keeps 95.6% of the Q6_K mean, the Bonsai files 98.9%, and trails each of them on all four tasks. Paired on the same items: Q6_K right-only 91 vs 25 (p < 0.0001), PTQ1_0 (1.95 GB smaller) 92 vs 50 (p = 0.0005). Saluki spends 1.5x to 1.8x the tokens per correct answer and capped on 122 of 1,583 generations (Q6_K 42). Tool calling, the model card's headline, is not tested here. |
|
| 243 |
| [This year's AIME and HMMT at a 32k thinking budget: nine local models against their MATH-500 order](reports/matharena-contests-32k.md) · [chart](reports/matharena-contests-32k.png) | The nine second-tier think-on rows on AIME 2026 (30) + HMMT Feb 2026 (33), MathArena sets, `max_tokens 32768`, `ctx 40960`, greedy, strict sympy grader plus an exact-number veto (0 fired; veto takes agreement with MathArena's labels on HMMT from 98.3% to 99.6%). Gemma 4 31B QAT Q4_0 51/63 (third on MATH-500 at 94.0), Qwen3.8-27B UD-IQ3_XXS 48, Q6_K 47, Ornith 1.5 35B 43, Qwen3.6-27B 37, Qwen3.6-35B-A3B 35, Nemotron 3.5 Lightning 34, Ornith 1.5 9B 29, Qwable-27B 29. Gemma's median completion is 8,259.5 / 8,963 tokens and none of its 63 hit the cap; the other eight capped on 6 to 22 problems per contest and are right on 95.5 to 100% of the answers they finish. 13 of 207 capped answers credited. Gemma vs the Qwen3.8 rows is not significant on 63 problems (paired p = 0.45 / 0.34). |
|
| 244 |
| [GPQA Diamond at a 32k thinking budget: the three rows that capped at 16k](reports/gpqa-thinkon-32k.md) | Same 198 questions, only `max_tokens` moved (16,384 to 32,768). Qwable-27B 78.28 to 85.35, Nemotron 3.5 Lightning 30B-A3B 60.61 to 67.17, Qwen3.6-27B 76.77 to 79.80. Every answer that finished inside 16k got the same verdict and completion length at 32k (444/444); every gain is a question that had hit the cap. Nemotron still caps on 19.7% at 32k (a floor). |
|
| 245 |
| [Speculative decoding and prefix caching on one RTX 5090, Qwen3.8-27B Q6_K: the two free speedups on the model this box now serves](reports/spec-cache-study-qwen38.md) · [chart](reports/spec-cache-study-qwen38.png) | Rerun of the spec-cache study on Qwen3.8-27B Q6_K (the served model since 2026-09-13, own MTP head in the unsloth GGUF), same 304-request design, same flag set (llama.cpp b9653, ctx 64k, parallel 1, KV q8_0, batch 1). MTP n=2 lifts decode from 61 to 109-144 tok/s (1.8x prose and chat, 2.3x code and repetitive) for +9 ms TTFT; n=4 reaches 168-184 on code/repetitive and loses 5-8% on prose/chat; n-gram lookup is 1.00x. Prefix cache: TTFT 1.004 s to 0.069 s on a 2,954-token system prompt (15x), 3.814 s to 0.086 s on 11,570 tokens (44x), decode unchanged. Stacked, a short answer to the 11.5k context goes 4.25 s to 0.30 s. Losslessness: MTP byte-identical to plain greedy decode on 59% of answers; all 13 divergences are the target's own second choice at a near-tie (top-2 gap 0.004 to 0.133 nats, median 0.030). Every cell within noise of the Qwen3.6-27B run a week earlier: the speedups belong to the shape and the serving stack, not the generation. |
|
dataset/second_tier.csv
CHANGED
|
@@ -47,3 +47,7 @@ ternary-bonsai-2-27b-pq2-0,Ternary-Bonsai-2-27B,PQ2_0,7206168928,ifeval,prompt_s
|
|
| 47 |
ternary-bonsai-2-27b-pq2-0,Ternary-Bonsai-2-27B,PQ2_0,7206168928,math500,acc,95.0,475,500,11,0.022,6,2075.1,578.0,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
| 48 |
ternary-bonsai-2-27b-pq2-0,Ternary-Bonsai-2-27B,PQ2_0,7206168928,humaneval_plus,pass@1,92.07,151,164,7,0.0427,,1811.9,463.0,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
| 49 |
ternary-bonsai-2-27b-pq2-0,Ternary-Bonsai-2-27B,PQ2_0,7206168928,mbpp_plus,pass@1,80.42,304,378,15,0.0397,,2222.3,369.5,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 47 |
ternary-bonsai-2-27b-pq2-0,Ternary-Bonsai-2-27B,PQ2_0,7206168928,math500,acc,95.0,475,500,11,0.022,6,2075.1,578.0,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
| 48 |
ternary-bonsai-2-27b-pq2-0,Ternary-Bonsai-2-27B,PQ2_0,7206168928,humaneval_plus,pass@1,92.07,151,164,7,0.0427,,1811.9,463.0,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
| 49 |
ternary-bonsai-2-27b-pq2-0,Ternary-Bonsai-2-27B,PQ2_0,7206168928,mbpp_plus,pass@1,80.42,304,378,15,0.0397,,2222.3,369.5,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
| 50 |
+
underdog-saluki-27b-iq2-mix,Underdog-Saluki-27B-1.0,IQ2-mix,7898369152,ifeval,prompt_strict_acc,84.84,459,541,54,0.0998,0,3935.4,1220,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
| 51 |
+
underdog-saluki-27b-iq2-mix,Underdog-Saluki-27B-1.0,IQ2-mix,7898369152,math500,acc,91.6,458,500,27,0.054,18,3022.8,704.5,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
| 52 |
+
underdog-saluki-27b-iq2-mix,Underdog-Saluki-27B-1.0,IQ2-mix,7898369152,humaneval_plus,pass@1,89.02,146,164,12,0.0732,,2748.2,598.0,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
| 53 |
+
underdog-saluki-27b-iq2-mix,Underdog-Saluki-27B-1.0,IQ2-mix,7898369152,mbpp_plus,pass@1,77.25,292,378,29,0.0767,,3145.4,426.5,"think-on, max_tokens 16384, ctx 24576, zero-shot, greedy",
|
reports/second-tier-thinkon-16k.md
CHANGED
|
@@ -71,7 +71,7 @@ Reads:
|
|
| 71 |
3. **The two packings are the same model on this board.** 88.67 vs 88.69; the 1.3 GB smaller PTQ1_0 file costs nothing measurable here.
|
| 72 |
4. **Cost per answer is higher than the 3-bit cut.** MATH-500 tokens per correct 2,075 and 2,127 against 1,780 (Q6_K) and 1,891 (UD-IQ3_XXS). The smaller file buys VRAM, not speed per answer.
|
| 73 |
|
| 74 |
-
In flight on the same two rows: GPQA Diamond thinking on at 16k and this year's AIME and HMMT at 32k, plus two more sub-10 GB Qwen3.8-27B files on this regime (ConwayResearch Underdog-Saluki-27B IQ2-mix and ISTA-DASLab GSQ-RCO IQ2_XS). Those land in a separate report.
|
| 75 |
|
| 76 |
## Worth it if / not if
|
| 77 |
|
|
|
|
| 71 |
3. **The two packings are the same model on this board.** 88.67 vs 88.69; the 1.3 GB smaller PTQ1_0 file costs nothing measurable here.
|
| 72 |
4. **Cost per answer is higher than the 3-bit cut.** MATH-500 tokens per correct 2,075 and 2,127 against 1,780 (Q6_K) and 1,891 (UD-IQ3_XXS). The smaller file buys VRAM, not speed per answer.
|
| 73 |
|
| 74 |
+
In flight on the same two rows: GPQA Diamond thinking on at 16k and this year's AIME and HMMT at 32k, plus two more sub-10 GB Qwen3.8-27B files on this regime (ConwayResearch Underdog-Saluki-27B IQ2-mix and ISTA-DASLab GSQ-RCO IQ2_XS). Those land in a separate report: [Qwen3.8-27B under 10 GB](sub10-qwen38-27b.md) (Saluki published 2026-10-13, GSQ-RCO pending).
|
| 75 |
|
| 76 |
## Worth it if / not if
|
| 77 |
|
reports/sub10-qwen38-27b.md
ADDED
|
@@ -0,0 +1,93 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Qwen3.8-27B under 10 GB, thinking on: Underdog-Saluki-27B against the 3-bit and ternary files
|
| 2 |
+
|
| 3 |
+
**The one line:** Underdog-Saluki-27B-1.0 (7.9 GB) keeps 95.6% of the Qwen3.8-27B Q6_K four-task mean at a 16k thinking budget; the two Ternary-Bonsai-2-27B files (5.9 and 7.2 GB) keep 98.9% and the 11.9 GB UD-IQ3_XXS 99.9%, and Saluki trails each of them on all four tasks.
|
| 4 |
+
|
| 5 |
+
**Rig:** RTX 5090 32GB (capsule), llama-server, batch 1 · **Window:** Saluki 2026-10-11 to 2026-10-13, inside the box's cheap-electricity hours (idle-queue item `65s-sub10-core`) · **Harness:** [llm-bench-rig](https://github.com/notwitcheer/llm-bench-rig) second-tier lane, artefacts in `results/<slug>-thinkon/` · **Data:** [`dataset/second_tier.csv`](../dataset/second_tier.csv) · **Chart:** [`sub10-qwen38-27b.png`](sub10-qwen38-27b.png) · **Parent board:** [thinking on at a 16k budget](second-tier-thinkon-16k.md)
|
| 6 |
+
|
| 7 |
+

|
| 8 |
+
|
| 9 |
+
## TL;DR
|
| 10 |
+
|
| 11 |
+
1. **Saluki lands 4.0 points under Q6_K on the four-task mean (85.68 vs 89.67), the only gap on this page wider than the interval.** The propagated Wilson 95% half-width on a four-task mean is 1.6 to 1.9 points per row here, so the Q6_K, UD-IQ3_XXS and both Bonsai rows (88.67 to 89.67) are one band and Saluki sits below it. On the same 1,583 items, Q6_K is right where Saluki is wrong 91 times and the reverse happens 25 times (exact two-sided sign test on the discordant items, p < 0.0001).
|
| 12 |
+
2. **The smaller ternary file is ahead too.** Ternary-Bonsai-2-27B PTQ1_0 is 1.95 GB smaller and scores 88.67; paired against Saluki it is right-only on 92 items and wrong-only on 50 (p = 0.0005). The Bonsai files need the PrismML llama.cpp fork; Saluki runs on stock llama.cpp, which is the real difference for anyone on an app built on mainline.
|
| 13 |
+
3. **Saluki thinks longer, and the cap catches more of it.** 1.5x to 1.8x the completion tokens per correct answer of Q6_K on every task, 122 of its 1,583 generations reached the 16,384-token cap against 42 for Q6_K, and 104 of its 228 wrong answers were capped. IFEval capped at 9.98%, on the edge of this board's 10% budget-limited flag. The model card says the same in its own words: "with thinking on, it often reasons at length before answering".
|
| 14 |
+
|
| 15 |
+
## Setup
|
| 16 |
+
|
| 17 |
+
- **Regime, every row:** thinking on, `max_tokens 16384`, `ctx 24576`, greedy (`temperature 0`), zero-shot, batch 1 through llama-server's chat-completions endpoint. One pass per item; an item cut by a block's hard stop re-ran from scratch at the next block (the tokens sidecars keep both lines, the detail json counts each item once).
|
| 18 |
+
- **Tasks:** IFEval (541 prompts, prompt-strict; inst-strict in the detail json), MATH-500 (500, vendored Qwen-Math grader; `grade(r'\frac{1}{2}', '0.5')` printed `True` in the run venv, checked 2026-10-13), HumanEval+ (164, pass@1), MBPP+ (378, pass@1).
|
| 19 |
+
- **Subject:** [ConwayResearch/Underdog-Saluki-27B-1.0](https://huggingface.co/ConwayResearch/Underdog-Saluki-27B-1.0), `Underdog-Saluki-27B-1.0-IQ2-mix.gguf`, 7,898,369,152 bytes (`stat -L`). Qwen3.8-27B tuned on top of [ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF](https://huggingface.co/ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF), Apache-2.0, a standard GGUF for stock llama.cpp per its card.
|
| 20 |
+
- **Comparison rows (already on the 16k board, not re-run):** Qwen3.8-27B Q6_K 22,884,408,288 bytes · Qwen3.8-27B UD-IQ3_XXS 11,913,559,104 · Ternary-Bonsai-2-27B PQ2_0 7,206,168,928 · PTQ1_0 5,946,648,928.
|
| 21 |
+
- **Server binaries:** Saluki and both Qwen3.8 rows ran on the rig's mainline llama-server, b10371 (`5d16e81dd`, `config.yaml` `llama_cpp.server_bin`, no override). The two Bonsai rows ran on the PrismML fork (`PrismML-Eng/llama.cpp`, `prism` branch, `4fbda12`, recorded in their detail json's `server_bin`), because PTQ1_0 and PQ2_0 kernels are not in mainline. That is the one condition that differs between rows.
|
| 22 |
+
- **Paired comparisons:** per-item `correct` flags from each task's `*_progress.json`, joined on item key; the test is an exact two-sided binomial on the discordant items. Script: [`scripts/sub10_paired.py`](../scripts/sub10_paired.py), run on the rig against the progress files.
|
| 23 |
+
|
| 24 |
+
## The board
|
| 25 |
+
|
| 26 |
+
Scores are percentages. `cap` is the share of items whose completion reached the 16,384-token budget, on the task that caps most for that row.
|
| 27 |
+
|
| 28 |
+
| Model | Quant | GGUF | IFEval | MATH-500 | HumanEval+ | MBPP+ | Mean | vs Q6_K | IFEval cap | MATH-500 tokens / correct |
|
| 29 |
+
|---|---|---:|---:|---:|---:|---:|---:|---:|---:|---:|
|
| 30 |
+
| Qwen3.8-27B | Q6_K | 22.9 GB | 89.65 | 95.2 | 92.07 | 81.75 | **89.67** | | 2.8% | 1,780 |
|
| 31 |
+
| Qwen3.8-27B | UD-IQ3_XXS | 11.9 GB | 90.2 | 94.6 | 92.68 | 80.69 | **89.54** | -0.12 | 3.3% | 1,891 |
|
| 32 |
+
| Ternary-Bonsai-2-27B † | PQ2_0 | 7.2 GB | 87.25 | 95.0 | 92.07 | 80.42 | **88.69** | -0.98 | 7.4% | 2,075 |
|
| 33 |
+
| Ternary-Bonsai-2-27B † | PTQ1_0 | 5.9 GB | 87.62 | 93.8 | 93.9 | 79.37 | **88.67** | -1.00 | 7.2% | 2,127 |
|
| 34 |
+
| Underdog-Saluki-27B-1.0 | IQ2-mix | 7.9 GB | 84.84 | 91.6 | 89.02 | 77.25 | **85.68** | -3.99 | 9.98% | 3,023 |
|
| 35 |
+
|
| 36 |
+
† PrismML llama.cpp fork `4fbda12`; every other row mainline b10371.
|
| 37 |
+
|
| 38 |
+
Saluki per task, with Wilson 95% half-widths and the cost columns (all from `dataset/second_tier.csv`):
|
| 39 |
+
|
| 40 |
+
| Task | Score | Correct / total | ± (95%) | Capped | Tokens / correct | Median completion | vs Q6_K tokens / correct |
|
| 41 |
+
|---|---:|---:|---:|---:|---:|---:|---:|
|
| 42 |
+
| IFEval prompt-strict | 84.84 | 459 / 541 | 3.0 | 54 (9.98%) | 3,935 | 1,220 | 2,235 |
|
| 43 |
+
| MATH-500 | 91.6 | 458 / 500 | 2.4 | 27 (5.4%), 18 unboxed | 3,023 | 704.5 | 1,780 |
|
| 44 |
+
| HumanEval+ | 89.02 | 146 / 164 | 4.8 | 12 (7.3%) | 2,748 | 598 | 1,713 |
|
| 45 |
+
| MBPP+ | 77.25 | 292 / 378 | 4.2 | 29 (7.7%) | 3,145 | 426.5 | 2,107 |
|
| 46 |
+
|
| 47 |
+
Paired against each row on identical items (A-only = the comparison row right, Saluki wrong; S-only = the reverse):
|
| 48 |
+
|
| 49 |
+
| vs | IFEval A-only / S-only | MATH-500 | HumanEval+ | MBPP+ | All four | p (all four) |
|
| 50 |
+
|---|---:|---:|---:|---:|---:|---:|
|
| 51 |
+
| Qwen3.8-27B Q6_K | 37 / 11 | 22 / 4 | 8 / 3 | 24 / 7 | 91 / 25 | < 0.0001 |
|
| 52 |
+
| Qwen3.8-27B UD-IQ3_XXS | 43 / 14 | 22 / 7 | 9 / 3 | 27 / 14 | 101 / 38 | < 0.0001 |
|
| 53 |
+
| Ternary-Bonsai-2-27B PQ2_0 | 34 / 21 | 20 / 3 | 10 / 5 | 27 / 15 | 91 / 44 | < 0.0001 |
|
| 54 |
+
| Ternary-Bonsai-2-27B PTQ1_0 | 38 / 23 | 19 / 8 | 10 / 2 | 25 / 17 | 92 / 50 | 0.0005 |
|
| 55 |
+
|
| 56 |
+
## Reads
|
| 57 |
+
|
| 58 |
+
1. **The direction is the same on every task against every row.** Saluki is below Q6_K by 4.81 (IFEval), 3.6 (MATH-500), 3.05 (HumanEval+) and 4.5 (MBPP+). Single tasks are noisier than the mean: HumanEval+ alone (8 / 3 against Q6_K) is not significant at 164 items. The four-task paired count is what carries the finding.
|
| 59 |
+
2. **As a ratio, Saluki keeps 94.5% to 96.7% of the Q6_K score per task, 95.6% of the mean.** The model card's "96% average retention across 9 benchmarks" is against the full-size model on a different task set, so the two are not a pair, but the numbers sit close together. What this page adds is that other files of the same base model keep more on these four tasks: 98.9% (both Bonsai packings) and 99.9% (UD-IQ3_XXS).
|
| 60 |
+
3. **A large share of the gap is answers that ran out of budget.** Saluki has 66 fewer correct answers than Q6_K over the four tasks and 80 more capped generations. This does not prove a bigger budget closes the gap (a capped item can be wrong at any budget), but it does mean these scores are partly a 16k-budget read. A 32k pass on the four legs would settle it; it is on the owed list.
|
| 61 |
+
4. **IFEval: the widest instruction-group gap is change_case.** 78 of 89 change_case instructions pass for Saluki against 87 of 89 for Q6_K; startend 60 of 67 against 65 of 67. The card names "letter-level instruction puzzles (palindromes, vowel rules, alphabetical order)" as its weakest area; IFEval has no palindrome or vowel instructions, so change_case (all caps, all lowercase) is only the nearest group, not a check of that sentence.
|
| 62 |
+
5. **MATH-500 is not competition maths.** 91.6 against 95.2 is 96.2% of Q6_K. The card says Saluki keeps "about 82 to 85% of the full model's competition math score" (AIME); AIME 2026 and HMMT Feb 2026 at a 32k budget are queued for this row and will be the comparable number.
|
| 63 |
+
|
| 64 |
+
## The model card's claims, checked where this regime can
|
| 65 |
+
|
| 66 |
+
- **IFEval 93.5 (prompt-loose).** This board grades prompt-strict, a stricter metric: Saluki scores 84.84 prompt-strict and 90.91 inst-strict (730 of 803 instructions). The detail json does not carry a loose score, so the card's number is neither confirmed nor contradicted here. For scale, the same harness gives Q6_K 89.65 prompt-strict and 94.52 inst-strict, so on the strict metrics Saluki is below the base model, where the card's loose figure (93.5) is above its quoted full-size public number (91.5). Different metric, different harness, sampling (the card recommends temperature 0.6 with thinking on; this board is greedy): not a contradiction, but not the same picture either.
|
| 67 |
+
- **MBPP+ 78.0.** This board: 77.25 (292 of 378, ± 4.2). Consistent.
|
| 68 |
+
- **Tool calling (Underdog Bench, 120 BFCL v4 tasks, thinking off): Saluki 88, full size 84, Bonsai 2 70.** Not run here. The card's comparison with Bonsai 2 is on tool calling; this page measures instruction following, maths and code with thinking on, where the 5.95 GB Bonsai 2 file (PTQ1_0 above, same size) scores 88.67 against Saluki's 85.68. Both can be true; the two measurements answer different questions.
|
| 69 |
+
- **Parallel tool calls, SWE-bench Verified, IFBench, MuSR, AIME 2025:** not run here. AIME 2026 is queued (32k, think-on), see Owed.
|
| 70 |
+
|
| 71 |
+
## Worth it if / not if
|
| 72 |
+
|
| 73 |
+
- **Worth it if** you need a sub-8 GB Qwen3.8-27B file that loads on stock llama.cpp or an app built on it, and tool calling is your main use: the vendor's tool-calling numbers are the reason to try it, and this page did not measure them.
|
| 74 |
+
- **Not if** you can run the PrismML fork: Ternary-Bonsai-2-27B PTQ1_0 is 1.95 GB smaller and 3.0 points higher on these four tasks with thinking on.
|
| 75 |
+
- **Not if** the card has 12 GB or more to spare: Qwen3.8-27B UD-IQ3_XXS (11.9 GB) ties the 22.9 GB Q6_K here.
|
| 76 |
+
- **Budget note:** with thinking on, Saluki spends 1.5x to 1.8x the tokens per correct answer of Q6_K, so a reply takes longer at the same decode speed.
|
| 77 |
+
|
| 78 |
+
## Honest limits
|
| 79 |
+
|
| 80 |
+
- One greedy pass per item, one card. The intervals are sampling intervals, not run-to-run variance. The card recommends temperature 0.6 / top-p 0.95 / top-k 20 with thinking on; greedy decoding is held constant across every row on this board for comparability, and a long-reasoning model can loop more under greedy, which would show up as capping.
|
| 81 |
+
- The Bonsai rows ran on a different server binary (PrismML fork); the regime and harness are otherwise identical.
|
| 82 |
+
- The comparison rows were measured 2026-09 (Qwen3.8) and 2026-10-08 to 10 (Bonsai), Saluki 2026-10-11 to 13; build, regime and harness held constant.
|
| 83 |
+
- No speed or memory measurement here; the file size is the GGUF on disk, not peak VRAM.
|
| 84 |
+
- Tool calling, the card's headline, is not measured on this rig.
|
| 85 |
+
- ISTA-DASLab GSQ-RCO IQ2_XS (8.42 GB, the base Saluki builds on) is in flight on the same regime; its row is not on this page yet.
|
| 86 |
+
|
| 87 |
+
## Owed
|
| 88 |
+
|
| 89 |
+
- ISTA-DASLab/Qwen3.8-27B-GSQ-RCO-GGUF IQ2_XS on the same four tasks (running in the cheap-electricity blocks).
|
| 90 |
+
- GPQA Diamond (think-on 16k) and AIME 2026 + HMMT Feb 2026 (think-on 32k) for both sub-10 GB rows (idle-queue item `67-sub10-qwen38-27b`).
|
| 91 |
+
- A 32k pass on Saluki's four legs, to measure how much of the gap is the 16k budget.
|
| 92 |
+
|
| 93 |
+
*Sources: `results/underdog-saluki-27b-iq2-mix-thinkon/{ifeval,math500,humaneval_plus,mbpp_plus}_detail.json` and `*_progress.json` on the rig, read 2026-10-13; `dataset/second_tier.csv` in this commit; model card [ConwayResearch/Underdog-Saluki-27B-1.0](https://huggingface.co/ConwayResearch/Underdog-Saluki-27B-1.0), read 2026-10-13; chart `scripts/chart_sub10_qwen38.py`.*
|
reports/sub10-qwen38-27b.png
ADDED
|
Git LFS Details
|