


 **Optimized version of [nvidia/Cosmos-Reason2-2B](https://huggingface.co/nvidia/Cosmos-Reason2-2B) using quantization and targeted mixed-precision exclusions.**
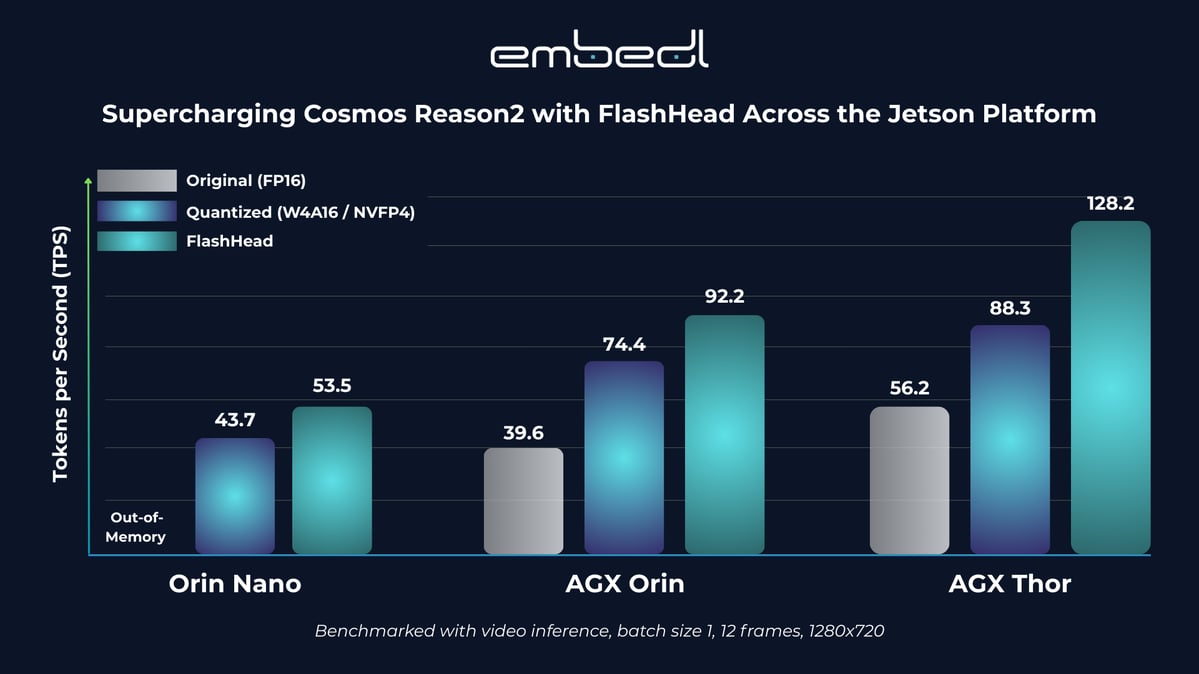
This release is based on the W4A16 line and adds a **mixed precision quantization** recipe resulting in **almost no accuracy drop** while preserving the **2x speedup**.
This model was created by quantizing the base language model to **INT4 weights** while keeping activations and a small selection of sensitive layers in **FP16** precision.
The model preserves Text + Image / Video -> Text behavior and reasoning capabilities while reducing memory footprint, enabling the Cosmos-Reason2 model to run even on an **NVIDIA Jetson Orin Nano Super**.
For more efficient inference, Embedl proprietary optimizations and architectural enhancements may require patched vLLM on some edge setups.
### Output Example
Real output captured from NVIDIA Jetson Orin Nano Super.
> system: You are a helpful assistant.
>
> user: Describe the sequence of actions from start to end, and explain what changes over time in this video: https://nvidia-cosmos.github.io/cosmos-cookbook/gallery/assets/kitchen_fridge_input.mp4
>
> assistant:
> Initially, the skeleton character stands facing the refrigerator, positioned on the left side of the frame.
>
> The skeleton character then reaches out with its right hand to open the refrigerator door.
>
> As the skeleton opens the refrigerator, the door swings outward, revealing the interior shelves.
---
## Model Details
| **Field** | **Value** |
|--------------------|-----------|
| **Model** | [embedl/Cosmos-Reason2-2B-W4A16-Edge2](https://huggingface.co/embedl/Cosmos-Reason2-2B-W4A16-Edge2) |
| **Base Model** | [nvidia/Cosmos-Reason2-2B](https://huggingface.co/nvidia/Cosmos-Reason2-2B) |
| **Input / Output** | Text + Image / Video -> Text |
| **Release Date** | 2026-02-25 |
| **Version** | 1.0 |
| **Optimizations** | Quantization (W4A16) + Mixed Precision Exclusions (`edge2`) |
| **Developers** | Embedl |
| **Licenses** | Upstream: [NVIDIA Open Model License](https://www.nvidia.com/en-us/agreements/enterprise-software/nvidia-open-model-license).
 ---
## Optimizations
- **Quantization (W4A16)**: INT4 weights + FP16 activations.
- **Edge2 mixed exclusions**: Keep sensitive layers in FP16 precision.
---
## Benchmarks
Accuracy and on-device latency benchmarks can be explored on [embedl/Edge-Inference-Benchmarks](https://huggingface.co/spaces/embedl/Edge-Inference-Benchmarks).
 ---
## Usage Examples
### vLLM Video Inference
**vLLM image:** NVIDIA vLLM 0.14.0 for Jetson
**Test Hardware (serve command): NVIDIA Jetson AGX Orin**
```bash
docker run --rm -it \
--network host \
--shm-size=8g \
--ulimit memlock=-1 \
--ulimit stack=67108864 \
--runtime=nvidia \
--name=vllm-serve \
-e HF_TOKEN=hf_*** \
-e HF_HOME=/root/.cache/huggingface \
ghcr.io/nvidia-ai-iot/vllm:latest-jetson-orin \
vllm serve "embedl/Cosmos-Reason2-2B-W4A16-Edge2" \
--max-model-len 8192 \
--gpu-memory-utilization 0.75 \
--max-num-seqs 2
```
**Test Hardware (Python example): NVIDIA Jetson AGX Orin, NVIDIA Jetson Orin Nano Super**
```python
from vllm import LLM, SamplingParams
if __name__ == "__main__":
model = "embedl/Cosmos-Reason2-2B-W4A16-Edge2"
video_url = "https://nvidia-cosmos.github.io/cosmos-cookbook/gallery/vs_assets/clip_1_short.mp4"
messages = [
{
"role": "system",
"content": [{"type": "text", "text": "You are a helpful assistant."}],
},
{
"role": "user",
"content": [
{"type": "video_url", "video_url": {"url": video_url, "fps": 4}},
{"type": "text", "text": "Describe this video in detail."},
],
},
]
llm = LLM(
model=model,
limit_mm_per_prompt={
"video": {"count": 1, "num_frames": 12, "width": 1280, "height": 720},
"image": 0,
"audio": 0,
},
media_io_kwargs={"video": {"num_frames": -1}},
max_model_len=8192,
mm_processor_kwargs={"truncation": False},
gpu_memory_utilization=0.75,
max_num_seqs=2,
)
output = llm.chat(messages, sampling_params=SamplingParams(temperature=0.0, max_tokens=256))
print(output[0].outputs[0].text)
```
### Transformers Inference
**Test Hardware:** NVIDIA L4 GPU
```python
import transformers
if __name__ == "__main__":
model_name = "embedl/Cosmos-Reason2-2B-W4A16-Edge2"
model = transformers.Qwen3VLForConditionalGeneration.from_pretrained(
model_name,
device_map="auto",
attn_implementation="sdpa",
)
processor = transformers.AutoProcessor.from_pretrained(model_name)
messages = [
{
"role": "user",
"content": [{"type": "text", "text": "Write me a short story about an elephant."}],
}
]
inputs = processor.apply_chat_template(
messages,
tokenize=True,
add_generation_prompt=True,
return_dict=True,
return_tensors="pt",
truncation=False,
).to(model.device)
generated_ids = model.generate(**inputs, max_new_tokens=256)
generated_ids_trimmed = [
out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids, strict=False)
]
output_text = processor.batch_decode(
generated_ids_trimmed,
skip_special_tokens=True,
clean_up_tokenization_spaces=False,
)
print(output_text[0])
```
## License
**Built on NVIDIA Cosmos**
This model is a derivative of **nvidia/Cosmos-Reason2-2B**.
> Licensed by NVIDIA Corporation under the NVIDIA Open Model License
- **Upstream:** [NVIDIA Open Model License](https://www.nvidia.com/en-us/agreements/enterprise-software/nvidia-open-model-license)
- **Additional Information:** [Apache License 2.0](https://huggingface.co/datasets/choosealicense/licenses/blob/main/markdown/apache-2.0.md)
- **Optimized Components:** Embedl Models Community Licence v1.0 *(no redistribution)*
---
## Contact
- Enterprise and Commercial Inquiries: `sales@embedl.com`
- Technical Issues and Early Access: `https://github.com/embedl/embedl-models`
- More Information and Model Releases: `https://embedl.com`
### Partner & Developer Opportunities
If you are evaluating on-device inference, building products on this model, or exploring custom model optimization, reach out for:
- Engineering support for on-prem and edge deployments
- Early access and partner co-marketing opportunities
Contact: `sales@embedl.com`