

Update bilingual model cards and benchmark figures
Browse files- .gitattributes +5 -0
- README.en.md +33 -22
- README.md +72 -59
- README.zh-CN.md +33 -22
- benchmark_case_epyc.json +62 -0
- bit-jev-case-memory.en.png +3 -0
- bit-jev-case-memory.zh-CN.png +3 -0
- bit-jev-case-speed.en.png +3 -0
- bit-jev-case-speed.zh-CN.png +3 -0
- bit-jev-logo.png +3 -0
.gitattributes
CHANGED
|
@@ -43,3 +43,8 @@ project-cover.zh-CN.png filter=lfs diff=lfs merge=lfs -text
|
|
| 43 |
decision-engine.png filter=lfs diff=lfs merge=lfs -text
|
| 44 |
project-flow.en.png filter=lfs diff=lfs merge=lfs -text
|
| 45 |
project-flow.zh-CN.png filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 43 |
decision-engine.png filter=lfs diff=lfs merge=lfs -text
|
| 44 |
project-flow.en.png filter=lfs diff=lfs merge=lfs -text
|
| 45 |
project-flow.zh-CN.png filter=lfs diff=lfs merge=lfs -text
|
| 46 |
+
bit-jev-logo.png filter=lfs diff=lfs merge=lfs -text
|
| 47 |
+
bit-jev-case-speed.zh-CN.png filter=lfs diff=lfs merge=lfs -text
|
| 48 |
+
bit-jev-case-speed.en.png filter=lfs diff=lfs merge=lfs -text
|
| 49 |
+
bit-jev-case-memory.zh-CN.png filter=lfs diff=lfs merge=lfs -text
|
| 50 |
+
bit-jev-case-memory.en.png filter=lfs diff=lfs merge=lfs -text
|
README.en.md
CHANGED
|
@@ -14,18 +14,18 @@ tags:
|
|
| 14 |
|
| 15 |
# bit-jev-2b-distilled
|
| 16 |
|
| 17 |
-
[中文模型卡](README.
|
| 18 |
|
| 19 |
-

|
| 31 |
|
|
@@ -70,37 +70,48 @@ This release contains the I2_S artifacts for the native CPU runner, matching tok
|
|
| 70 |
|
| 71 |
## Inference
|
| 72 |
|
| 73 |
-
Install the Python package. On Windows x64 with an AVX2 CPU, the bit-jev 0.
|
| 74 |
-
|
| 75 |
-
```bash
|
| 76 |
-
pip install bit-jev
|
| 77 |
-
```
|
| 78 |
|
| 79 |
```python
|
| 80 |
-
from bit_jev import BitJev
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 81 |
|
| 82 |
-
request = {"state": "A customer reports a duplicate charge.", "questions": {"team": {"type": "choice", "instructions": "Which team should handle it?", "criteria": {"billing": "Payment and refunds", "shipping": "Delivery"}}}}
|
| 83 |
with BitJev.from_pretrained(device="cpu", threads=8) as model:
|
| 84 |
-
|
|
|
|
|
|
|
| 85 |
```
|
| 86 |
|
| 87 |
`device="gpu"` selects Vulkan; `device="cuda"` selects a CUDA build. `infer()` reuses the resident model. See the [GGUF package guide](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.md) for CLI, offline directories, and build details. This model repository contains model files; both precompiled runners are distributed in the PyPI Windows x64 wheel.
|
| 88 |
|
| 89 |
-
## AutoDL case study:
|
| 90 |
|
| 91 |
-
The measurements below use one fixed development request with 703 input tokens and 77 options.
|
| 92 |
|
| 93 |
| Path | Mean inference time | Repetitions | Observed memory |
|
| 94 |
| --- | ---: | ---: | ---: |
|
| 95 |
-
|
|
| 96 |
-
|
|
| 97 |
-
|
|
|
|
|
|
|
|
|
|
|
| 98 |
|
| 99 |
-
 · [Source repository](https://github.com/Zeaulo/bit-jev) · [pip package](https://pypi.org/project/bit-jev/) · [ModelScope mirror](https://www.modelscope.cn/models/JingHao9616/bit-jev-2b-distilled)
|
| 18 |
|
| 19 |
+

|
| 20 |
|
| 21 |
+
On Windows x64 with Python 3.11/3.12, install the current release with the interpreter that will run inference, then check the distribution version and import path:
|
| 22 |
|
| 23 |
```bash
|
| 24 |
+
python -m pip install --upgrade --no-cache-dir bit-jev==0.12.10 -i https://pypi.org/simple
|
| 25 |
+
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 26 |
```
|
| 27 |
|
| 28 |
+
The version should be `0.12.10`, and the import path should point into the active environment's `site-packages/bit_jev`. Then run the Python example below, which does not depend on the `bit-jev-demo` console script being on PATH. The first model load downloads roughly 1.19 GB; later runs reuse the cache. The default first tries Hugging Face and falls back to ModelScope if the connection fails. Use `source="modelscope"` to select ModelScope directly. See the [install guide](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.md) for stale mirrors and mixed environments.
|
| 29 |
|
| 30 |

|
| 31 |
|
|
|
|
| 70 |
|
| 71 |
## Inference
|
| 72 |
|
| 73 |
+
Install the Python package. On Windows x64 with an AVX2 CPU, the bit-jev 0.12.10 wheel includes precompiled CPU and Vulkan GPU runners. For `device="cpu"` or `device="gpu"`, inference needs no Git, CMake, compiler, or Vulkan SDK. Vulkan needs a compatible graphics driver that supplies `vulkan-1.dll`. The roughly 1.19 GB model still downloads on first use. Other platforms and CUDA build from pinned source and require Git, CMake 3.28+, and a C++17 compiler; CUDA needs the CUDA Toolkit.
|
|
|
|
|
|
|
|
|
|
|
|
|
| 74 |
|
| 75 |
```python
|
| 76 |
+
from bit_jev.gguf import BitJev
|
| 77 |
+
|
| 78 |
+
request = {
|
| 79 |
+
"state": "A customer reports a duplicate charge on the same order.",
|
| 80 |
+
"questions": {
|
| 81 |
+
"team": {
|
| 82 |
+
"type": "choice",
|
| 83 |
+
"instructions": "Which team should handle it?",
|
| 84 |
+
"criteria": {"billing": "Payment and refunds", "shipping": "Delivery"},
|
| 85 |
+
}
|
| 86 |
+
},
|
| 87 |
+
}
|
| 88 |
|
|
|
|
| 89 |
with BitJev.from_pretrained(device="cpu", threads=8) as model:
|
| 90 |
+
result = model.infer(request)
|
| 91 |
+
print(result["answers"])
|
| 92 |
+
print(result["latency_ms"])
|
| 93 |
```
|
| 94 |
|
| 95 |
`device="gpu"` selects Vulkan; `device="cuda"` selects a CUDA build. `infer()` reuses the resident model. See the [GGUF package guide](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.md) for CLI, offline directories, and build details. This model repository contains model files; both precompiled runners are distributed in the PyPI Windows x64 wheel.
|
| 96 |
|
| 97 |
+
## AutoDL case study: EPYC 9654 CPU and RTX 5090 on another host
|
| 98 |
|
| 99 |
+
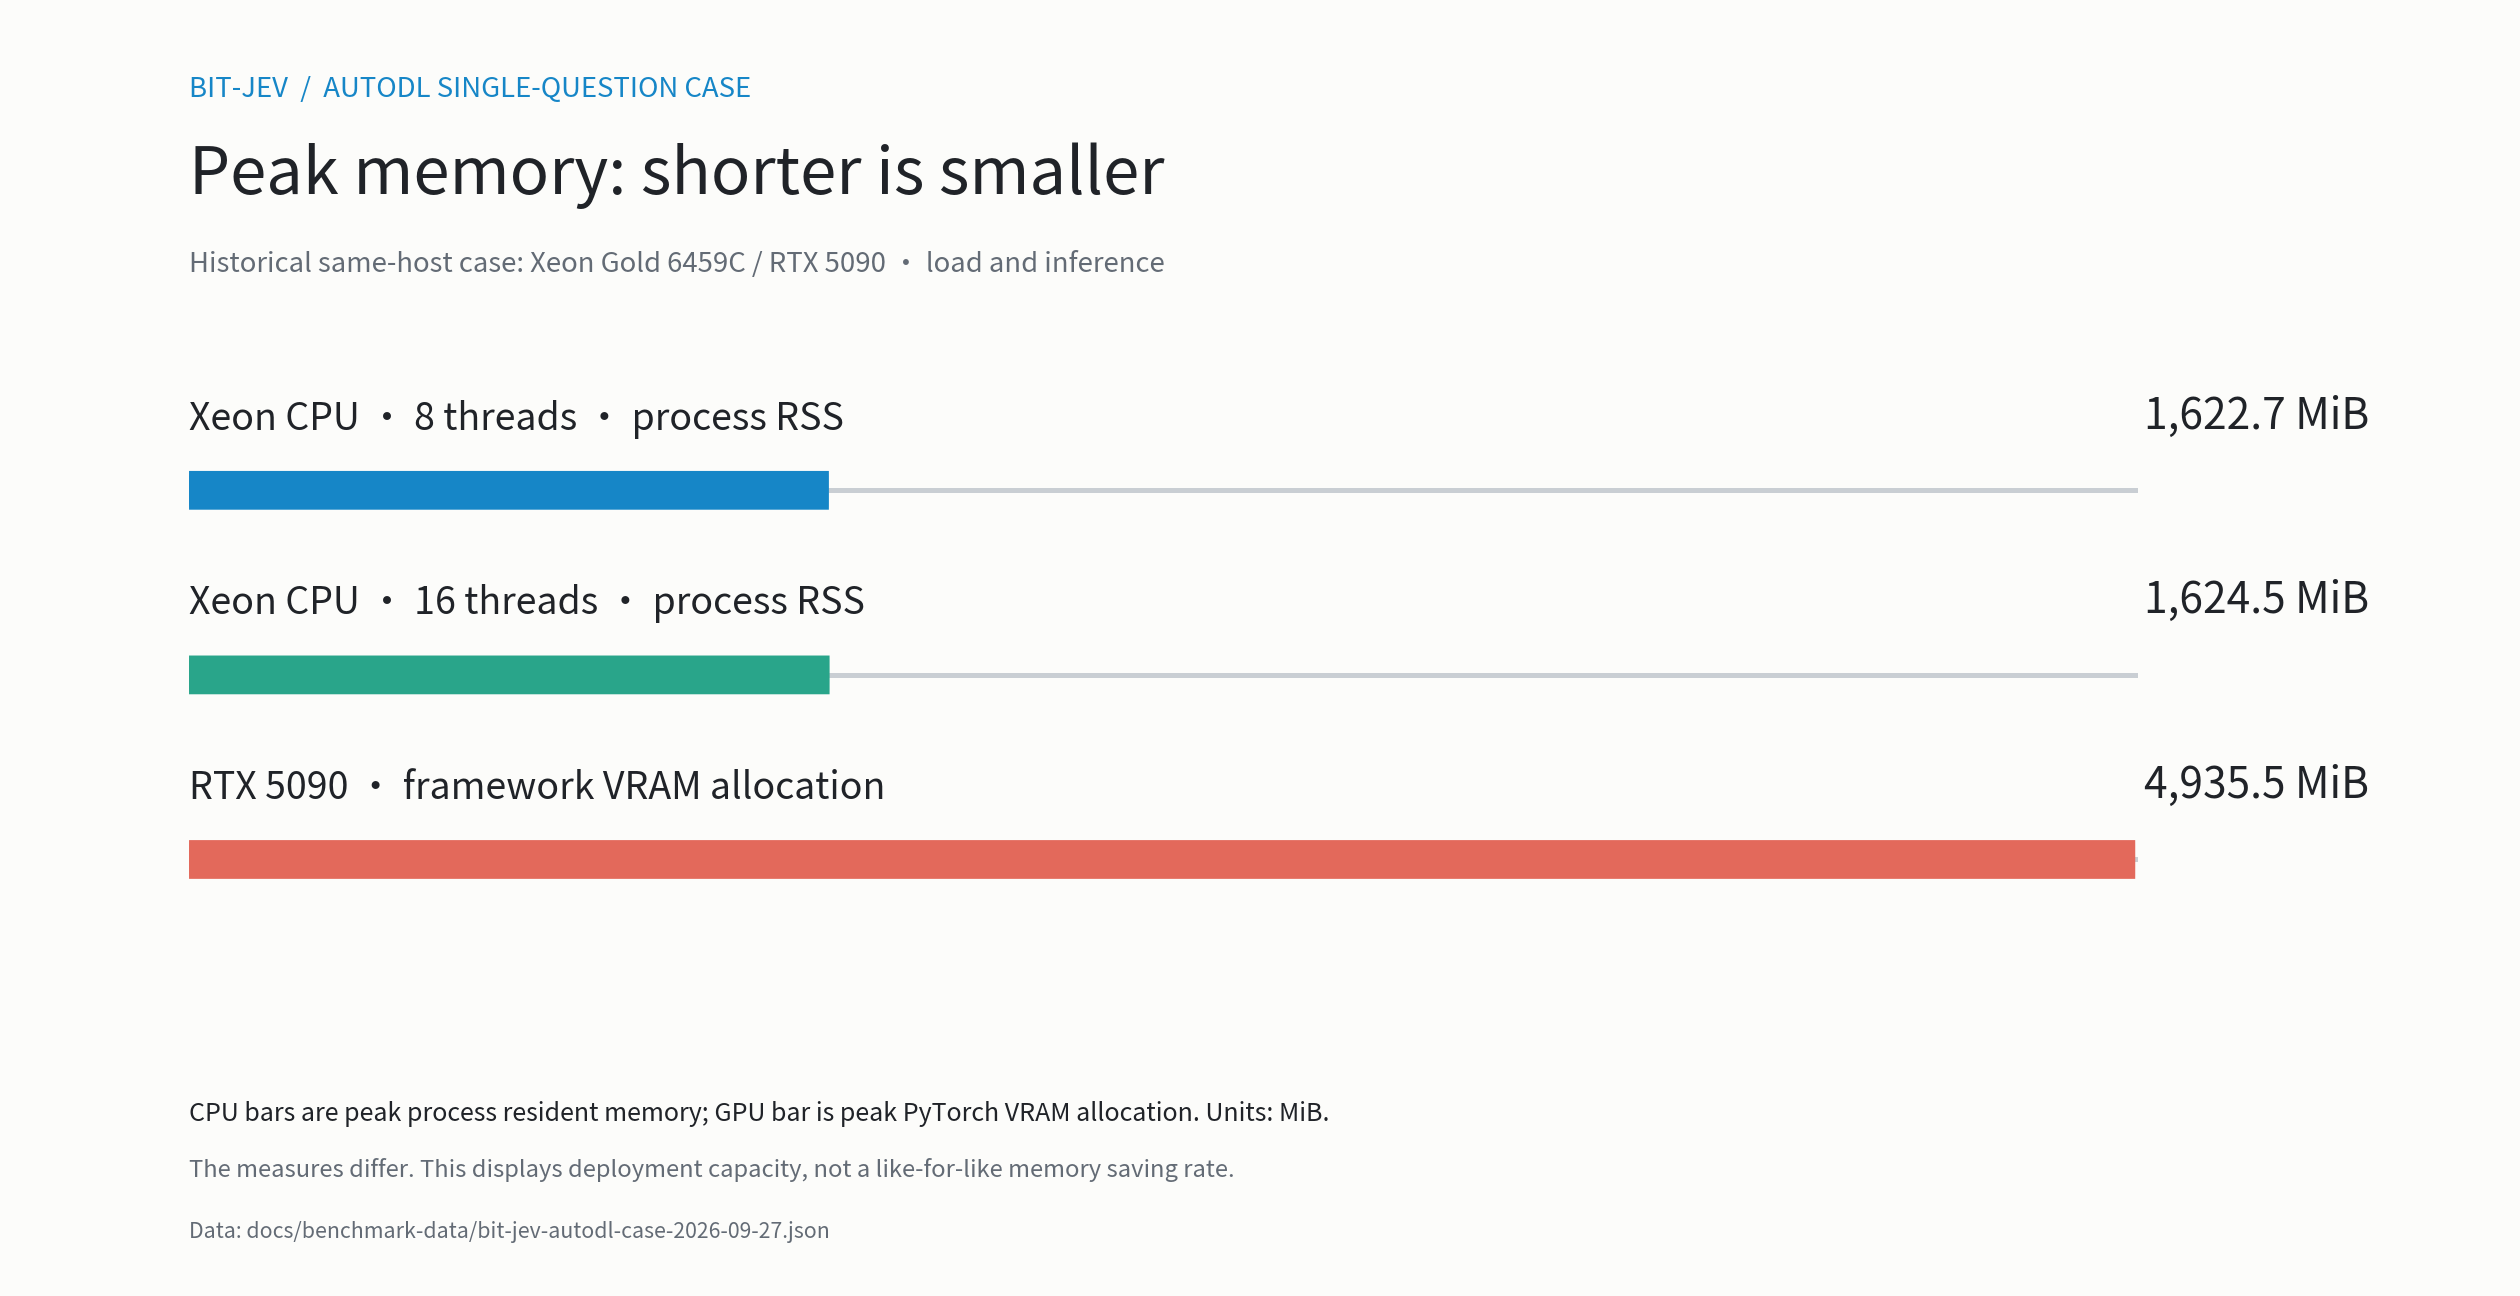
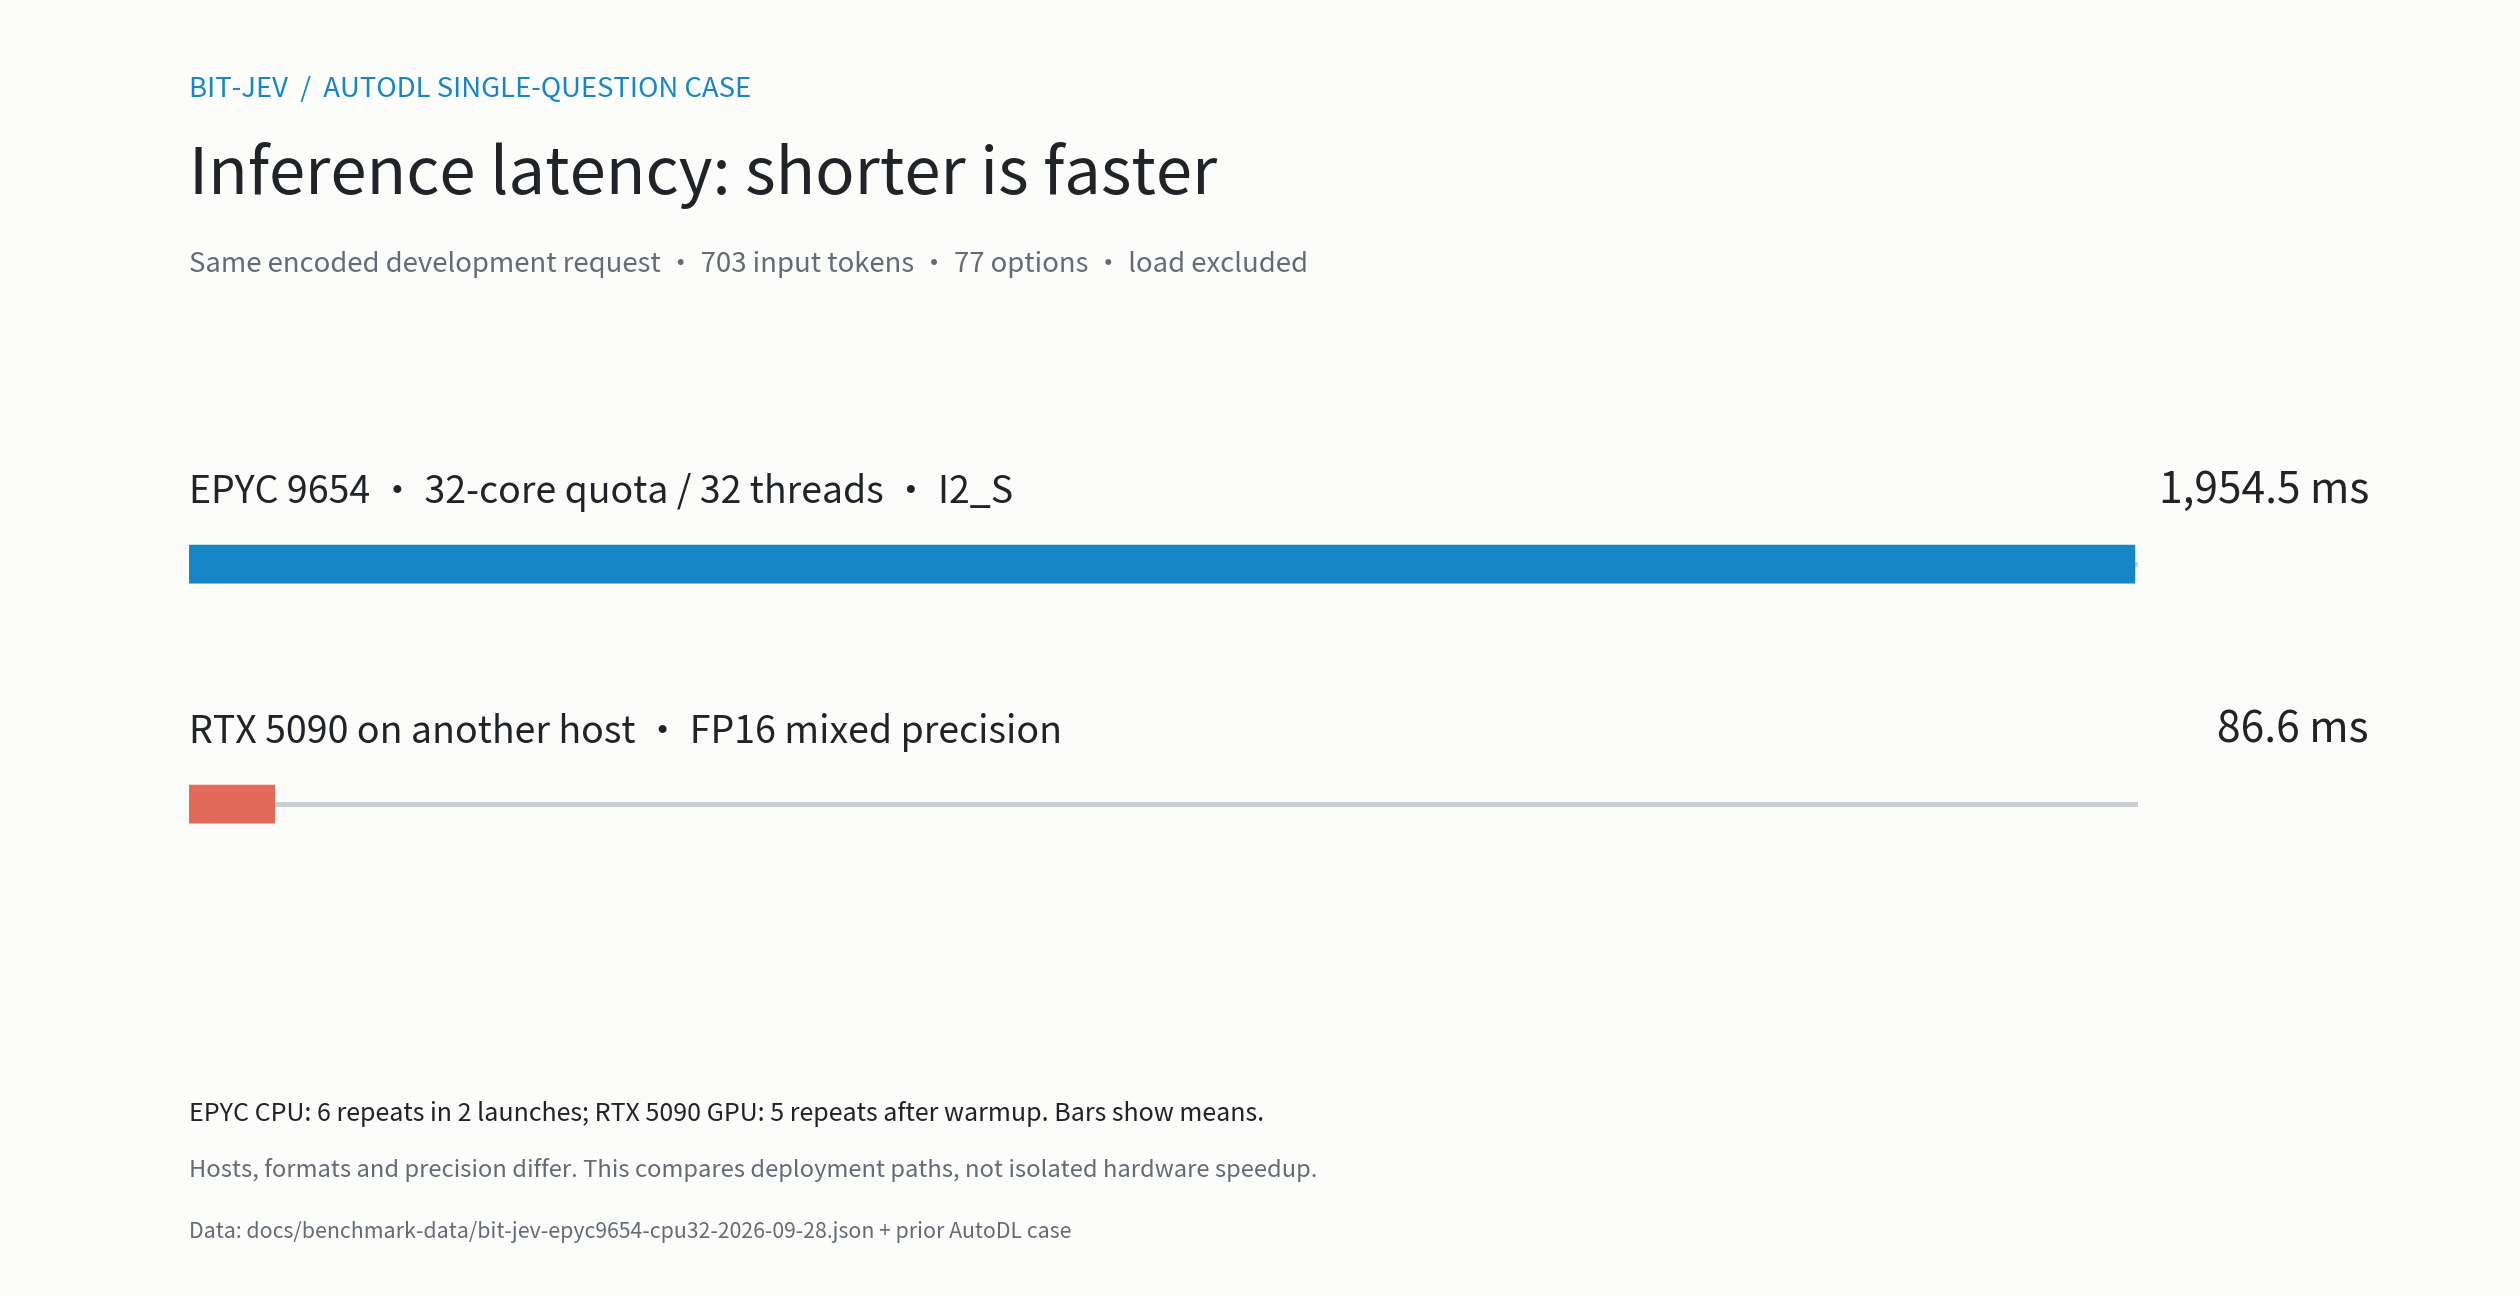
The measurements below use one fixed development request with 703 input tokens and 77 options. Native inference timing excludes model loading. The latency chart pairs a new EPYC 9654 container measurement with a 32-core quota and 32 native I2_S threads with a historical RTX 5090 FP16 mixed-precision PyTorch path from another host. The memory chart retains the original same-host Xeon Gold 6459C / RTX 5090 observations. These GPU numbers do not benchmark the pip package's GGUF/Vulkan or GGUF/CUDA path.
|
| 100 |
|
| 101 |
| Path | Mean inference time | Repetitions | Observed memory |
|
| 102 |
| --- | ---: | ---: | ---: |
|
| 103 |
+
| EPYC 9654, 32-core quota / 32 threads, I2_S | 1,954.46 ms | 6 | 1,625.88 MiB peak process RSS |
|
| 104 |
+
| Xeon Gold 6459C, 8 threads (historical) | 3,127.88 ms | 3 | 1,622.74 MiB peak process RSS |
|
| 105 |
+
| Xeon Gold 6459C, 16 threads (historical) | 1,972.17 ms | 3 | 1,624.52 MiB peak process RSS |
|
| 106 |
+
| RTX 5090 on another host, FP16 | 86.56 ms | 5 | 4,935.53 MiB peak GPU allocation |
|
| 107 |
+
|
| 108 |
+

|
| 109 |
|
| 110 |
+

|
| 111 |
|
| 112 |
+
[中文图表](bit-jev-case-speed.zh-CN.png)
|
| 113 |
|
| 114 |
+
On the same EPYC container, a supplemental 16-thread run averaged 3,210.12 ms, so 32 threads were about 1.64 times faster. The CPU and GPU paths in the chart ran on different hosts and used different weight formats and numeric precision; their ratio is not an isolated hardware speedup. CPU RSS and GPU allocation are different measures. This small case study is not a general throughput or accuracy claim. The [EPYC 32-thread samples](https://github.com/Zeaulo/bit-jev/blob/main/docs/benchmark-data/bit-jev-epyc9654-cpu32-2026-09-28.json) and the original same-host case in `benchmark_case_autodl.json` include no input, option text, or predictions. Generated tokens/s does not apply because the model scores options and emits structured decisions. No auditable held-out report for accuracy, Brier, NLL, or ECE is available, so no such values are claimed.
|
| 115 |
|
| 116 |
## Data provenance and use
|
| 117 |
|
README.md
CHANGED
|
@@ -14,109 +14,122 @@ tags:
|
|
| 14 |
|
| 15 |
# bit-jev-2b-distilled
|
| 16 |
|
| 17 |
-
[
|
| 18 |
|
| 19 |
-
![bit-jev
|
| 20 |
|
| 21 |
-
|
| 22 |
|
| 23 |
```bash
|
| 24 |
-
python -m pip install --upgrade bit-jev
|
| 25 |
-
bit-jev
|
| 26 |
```
|
| 27 |
|
| 28 |
-
|
| 29 |
|
| 30 |
-
![bit-jev
|
| 31 |
|
| 32 |
-
|
| 33 |
|
| 34 |
-
>
|
| 35 |
|
| 36 |
-
##
|
| 37 |
|
| 38 |
-
bit-jev-2b-distilled
|
| 39 |
|
| 40 |
-
|
|
|
|
|
|
|
| 41 |
| --- | --- | --- |
|
| 42 |
-
| `choice` |
|
| 43 |
-
| `noul` |
|
| 44 |
-
| `score` |
|
| 45 |
|
| 46 |
-
##
|
| 47 |
|
| 48 |
```text
|
| 49 |
Microsoft BitNet b1.58 2B BF16
|
| 50 |
-
↓ LoRA
|
| 51 |
-
|
| 52 |
-
+
|
| 53 |
-
|
| 54 |
-
↓ I2_S
|
| 55 |
-
I2_S GGUF + float32
|
| 56 |
```
|
| 57 |
|
| 58 |
-
|
| 59 |
|
| 60 |
-
##
|
| 61 |
|
| 62 |
-
|
|
| 63 |
| --- | --- | ---: |
|
| 64 |
-
| `backbone-i2_s.gguf` |
|
| 65 |
-
| `head.f32` |
|
| 66 |
-
| `pointer.json` |
|
| 67 |
-
|
|
| 68 |
-
|
| 69 |
-
`SHA256SUMS.json` lists sizes and SHA-256 hashes for inference-package files; it does not hash itself. BF16 safetensors shards, training data, training logs, and raw reviews are not included.
|
| 70 |
|
| 71 |
-
|
| 72 |
|
| 73 |
-
|
| 74 |
|
| 75 |
-
```
|
| 76 |
-
pip install bit-jev
|
| 77 |
-
```
|
| 78 |
|
| 79 |
```python
|
| 80 |
-
from bit_jev import BitJev
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 81 |
|
| 82 |
-
request = {"state": "A customer reports a duplicate charge.", "questions": {"team": {"type": "choice", "instructions": "Which team should handle it?", "criteria": {"billing": "Payment and refunds", "shipping": "Delivery"}}}}
|
| 83 |
with BitJev.from_pretrained(device="cpu", threads=8) as model:
|
| 84 |
-
|
|
|
|
|
|
|
| 85 |
```
|
| 86 |
|
| 87 |
-
`device="gpu"`
|
| 88 |
|
| 89 |
-
## AutoDL
|
| 90 |
|
| 91 |
-
|
| 92 |
|
| 93 |
-
|
|
| 94 |
| --- | ---: | ---: | ---: |
|
| 95 |
-
|
|
| 96 |
-
|
|
| 97 |
-
|
|
|
|
|
|
|
|
|
|
|
| 98 |
|
| 99 |
-
![bit-jev AutoDL
|
| 100 |
|
| 101 |
-
[
|
| 102 |
|
| 103 |
-
|
| 104 |
|
| 105 |
-
##
|
| 106 |
|
| 107 |
-
|
| 108 |
|
| 109 |
-
**
|
| 110 |
|
| 111 |
-
##
|
| 112 |
|
| 113 |
-
-
|
| 114 |
-
-
|
| 115 |
-
-
|
| 116 |
-
-
|
| 117 |
-
-
|
| 118 |
|
| 119 |
-
##
|
| 120 |
|
| 121 |
```bibtex
|
| 122 |
@misc{bitjev2026,
|
|
|
|
| 14 |
|
| 15 |
# bit-jev-2b-distilled
|
| 16 |
|
| 17 |
+
[English model card](README.en.md) · [源码仓库](https://github.com/Zeaulo/bit-jev) · [pip 安装](https://pypi.org/project/bit-jev/) · [ModelScope 镜像](https://www.modelscope.cn/models/JingHao9616/bit-jev-2b-distilled)
|
| 18 |
|
| 19 |
+

|
| 20 |
|
| 21 |
+
在运行推理的同一个 Python 3.11/3.12 环境中安装并核对版本:
|
| 22 |
|
| 23 |
```bash
|
| 24 |
+
python -m pip install --upgrade --no-cache-dir bit-jev==0.12.10 -i https://pypi.org/simple
|
| 25 |
+
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 26 |
```
|
| 27 |
|
| 28 |
+
版本应为 `0.12.10`,导入路径应指向当前环境的 `site-packages/bit_jev`。然后直接运行下方的 Python 示例;无需依赖 `bit-jev-demo` 命令的 PATH。首次加载会下载约 1.19 GB 模型,后续复用缓存。默认先尝试 Hugging Face,连接失败时回退 ModelScope;国内网络可在 `from_pretrained()` 中传入 `source="modelscope"`。镜像版本滞后及环境混用的处理见[安装指南](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.zh-CN.md)。
|
| 29 |
|
| 30 |
+

|
| 31 |
|
| 32 |
+
图中三值只代表量化 BitLinear 权重;训练与推理是分开的流程。
|
| 33 |
|
| 34 |
+
> 本仓库提供 bit-jev 的 I2_S GGUF 模型包,可通过 `bit-jev` Python 包进行 CPU 或 GPU 推理。权重来自包含 Yelp 评论数据的多源决策训练集。Yelp 权利方许可申请已发出,截至 2026-09-28 尚未收到书面答复。本模型卡公开说明来源与限制;项目代码仓库的 Apache-2.0 许可证不自动适用于此检查点。
|
| 35 |
|
| 36 |
+
## 模型简介
|
| 37 |
|
| 38 |
+
bit-jev-2b-distilled 是一个结构化判断学生模型。输入包含共享 `state` 和一个或多个问题;指针头直接对输入中的候选项打分,返回选择、概率或有序等级。模型不会逐 token 生成自然语言答案。
|
| 39 |
|
| 40 |
+
支持的问题类型:
|
| 41 |
+
|
| 42 |
+
| 类型 | 输入 | 结构化输出 |
|
| 43 |
| --- | --- | --- |
|
| 44 |
+
| `choice` | 一组选项及说明 | 选择项、分数、概率 |
|
| 45 |
+
| `noul` | 是/否问题 | 两类分数与概率 |
|
| 46 |
+
| `score` | 有序等级及说明 | 等级分数、期望值、概率 |
|
| 47 |
|
| 48 |
+
## 训练与导出流程
|
| 49 |
|
| 50 |
```text
|
| 51 |
Microsoft BitNet b1.58 2B BF16
|
| 52 |
+
↓ LoRA 微调 + 指针头训练
|
| 53 |
+
bit-jev 初始模型与指针头
|
| 54 |
+
+ Kev 9B 教师候选项 logits
|
| 55 |
+
完整学生骨干蒸馏 + 指针头
|
| 56 |
+
↓ I2_S 量化导出
|
| 57 |
+
I2_S GGUF + float32 指针头
|
| 58 |
```
|
| 59 |
|
| 60 |
+
发布包仅含面向原生 CPU runner 的 I2_S 产物、匹配的 tokenizer/config 和头部元数据。训练配置记录了 3,144 步、2 个 epoch、BF16、学习率 `2e-5`、批量 2、梯度累积 4、蒸馏温度 2.0 与权重 1.0。推理头温度在 `pointer.json` 中为 2.35。
|
| 61 |
|
| 62 |
+
## 文件与内存规模
|
| 63 |
|
| 64 |
+
| 文件 | 用途 | 大小 |
|
| 65 |
| --- | --- | ---: |
|
| 66 |
+
| `backbone-i2_s.gguf` | 量化 BitNet 骨干 | 1,187,288,192 字节(约 1.106 GiB) |
|
| 67 |
+
| `head.f32` | float32 指针头 | 5,244,948 字节 |
|
| 68 |
+
| `pointer.json` | 头部形状、边界 token 与温度 | 770 字节 |
|
| 69 |
+
| tokenizer/config 文件 | 请求编码和模型配置 | 约 17.2 MB |
|
|
|
|
|
|
|
| 70 |
|
| 71 |
+
`SHA256SUMS.json` 列出推理包文件的大小和 SHA-256。它不包含自身的哈希。发布包未提供 BF16 safetensors 分片,也未包含训练数据、训练日志或原始评论。
|
| 72 |
|
| 73 |
+
## 推理示例
|
| 74 |
|
| 75 |
+
推荐使用 pip 包。Windows x64 且 CPU 支持 AVX2 时,bit-jev 0.12.10 wheel 已携带 CPU 与 Vulkan GPU 原生 runner;首次加载会按需下载约 1.19 GB 的模型。使用 `device="cpu"` 或 `device="gpu"` 推理无需 Git、CMake、C++ 编译器或 Vulkan SDK;Vulkan GPU 需要显卡驱动提供 `vulkan-1.dll`。其他系统和 CUDA 后端按需从固定源码构建,需要 Git、CMake 3.28+ 与 C++17 编译器;CUDA 构建还需要 CUDA Toolkit。
|
|
|
|
|
|
|
| 76 |
|
| 77 |
```python
|
| 78 |
+
from bit_jev.gguf import BitJev
|
| 79 |
+
|
| 80 |
+
request = {
|
| 81 |
+
"state": "客户报告同一订单被重复扣款。",
|
| 82 |
+
"questions": {
|
| 83 |
+
"team": {
|
| 84 |
+
"type": "choice",
|
| 85 |
+
"instructions": "哪个团队应处理?",
|
| 86 |
+
"criteria": {"billing": "支付与退款", "shipping": "物流配送"},
|
| 87 |
+
}
|
| 88 |
+
},
|
| 89 |
+
}
|
| 90 |
|
|
|
|
| 91 |
with BitJev.from_pretrained(device="cpu", threads=8) as model:
|
| 92 |
+
result = model.infer(request)
|
| 93 |
+
print(result["answers"])
|
| 94 |
+
print(result["latency_ms"])
|
| 95 |
```
|
| 96 |
|
| 97 |
+
`device="gpu"` 使用 Vulkan;`device="cuda"` 使用 CUDA 构建。`infer()` 复用常驻模型并返回答案、logits、概率和原生推理耗时。完整 CLI、离线目录和构建细节见[GGUF 安装与推理指南](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.zh-CN.md)。本模型仓库只保存模型文件;两个预编译 runner 位于 PyPI 的 Windows x64 wheel。
|
| 98 |
|
| 99 |
+
## 性能案例:AutoDL EPYC 9654 CPU 与另一台 RTX 5090
|
| 100 |
|
| 101 |
+
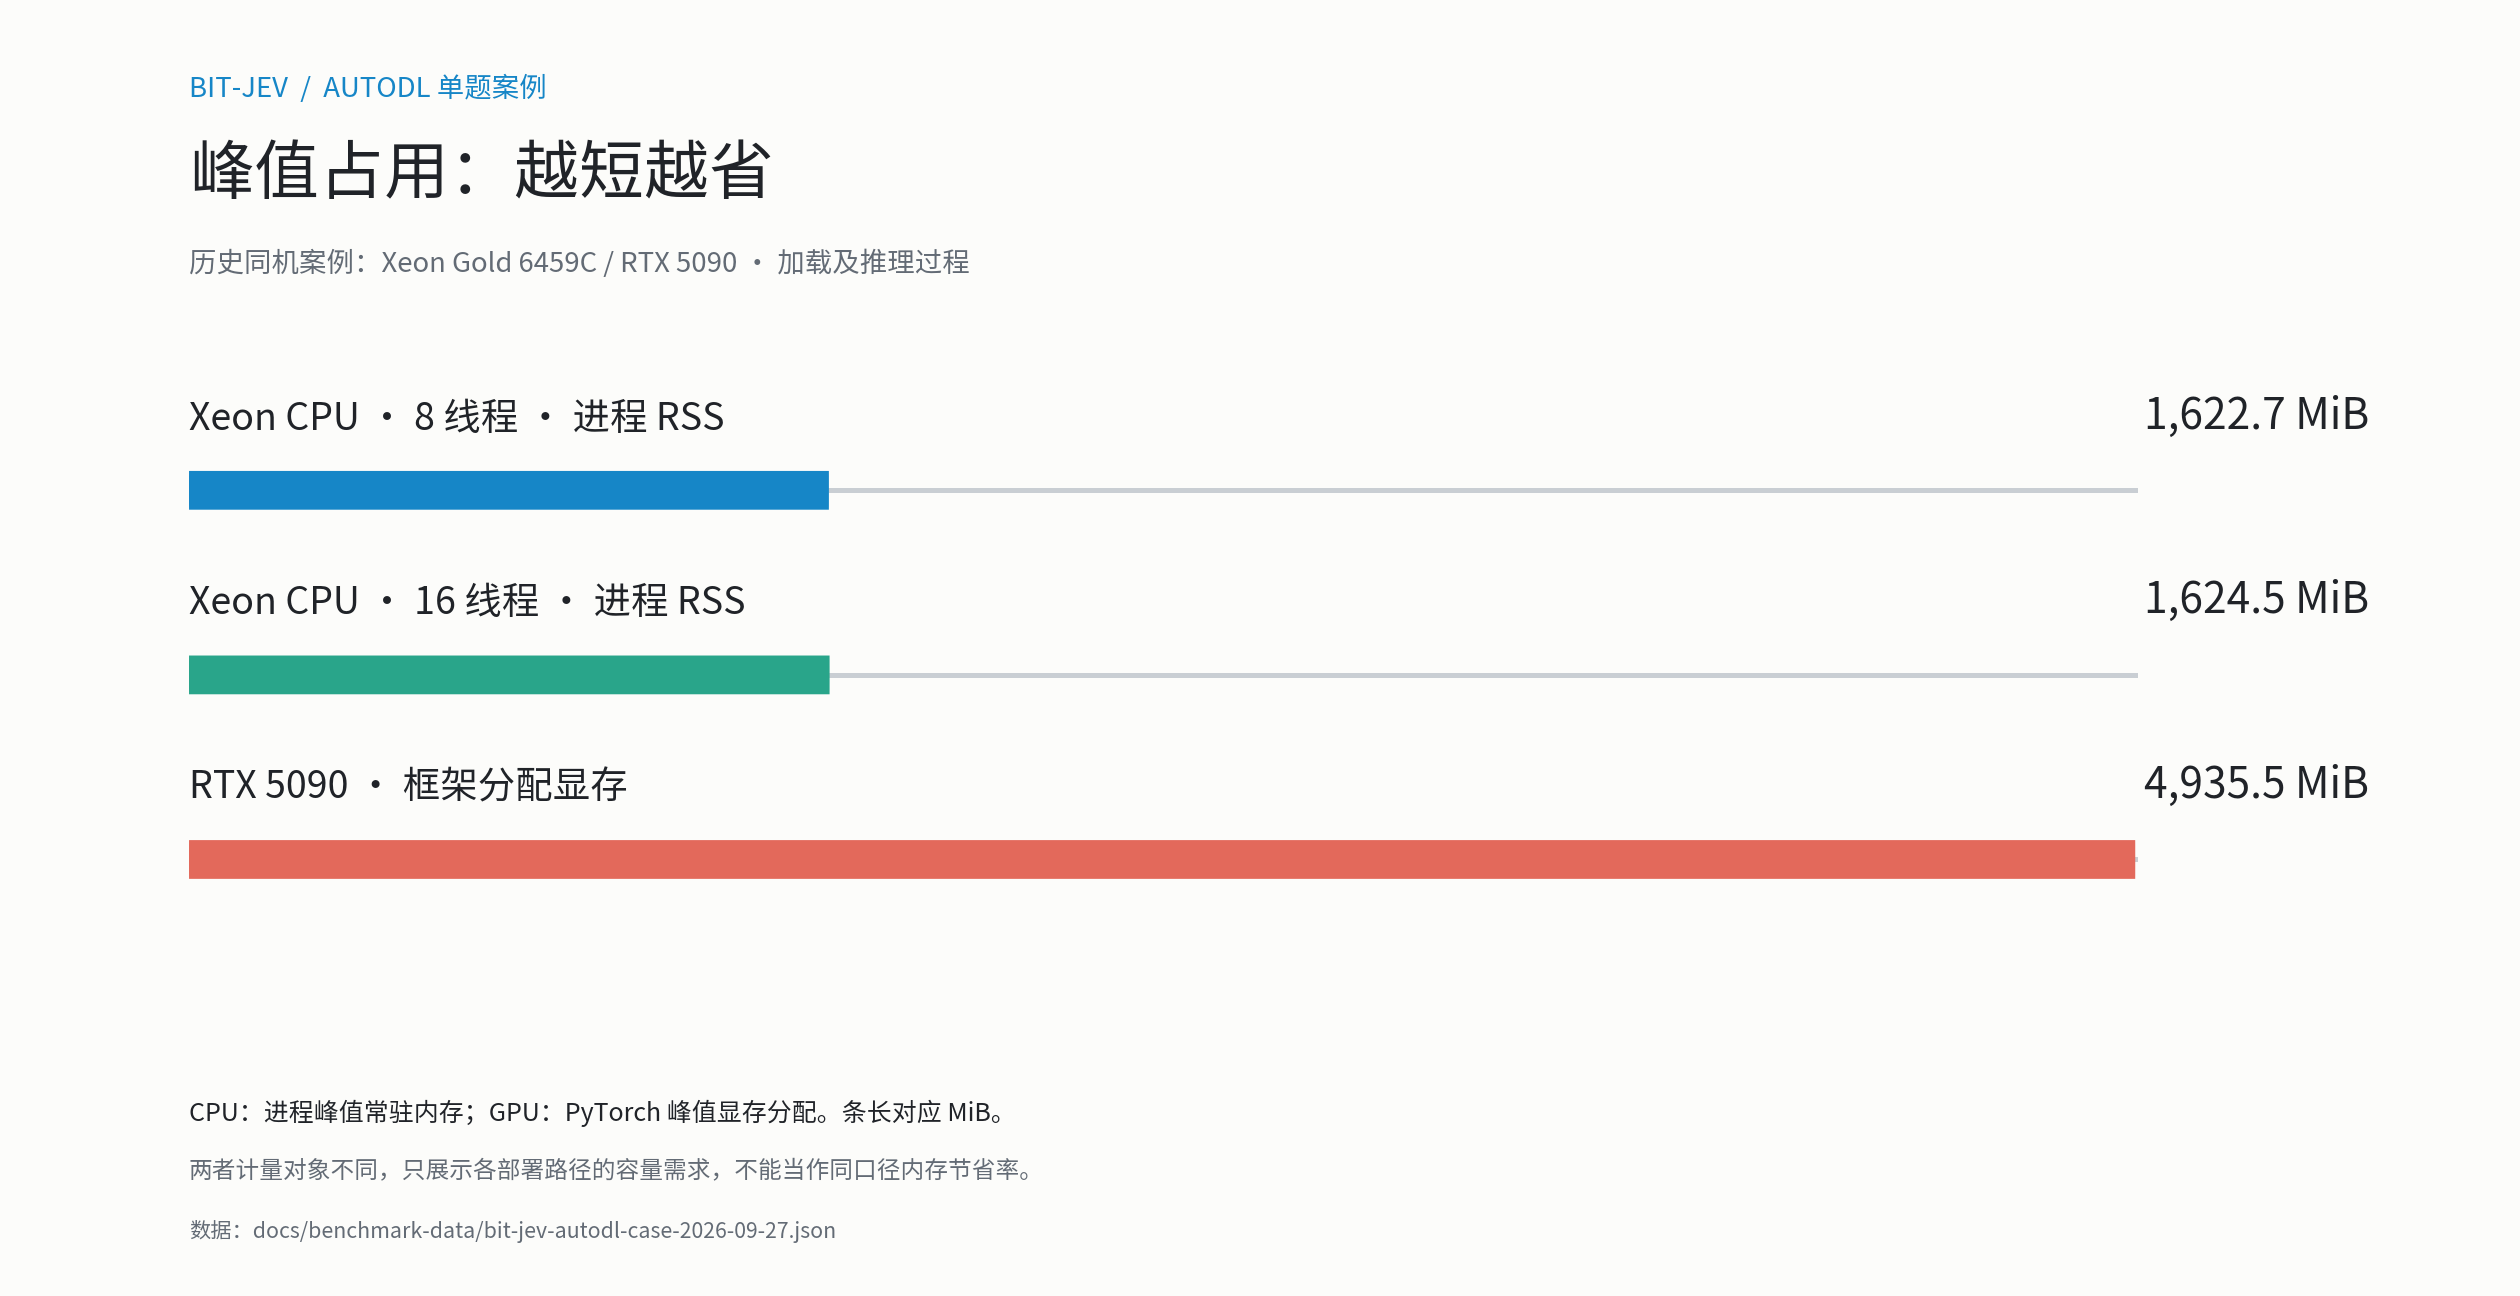
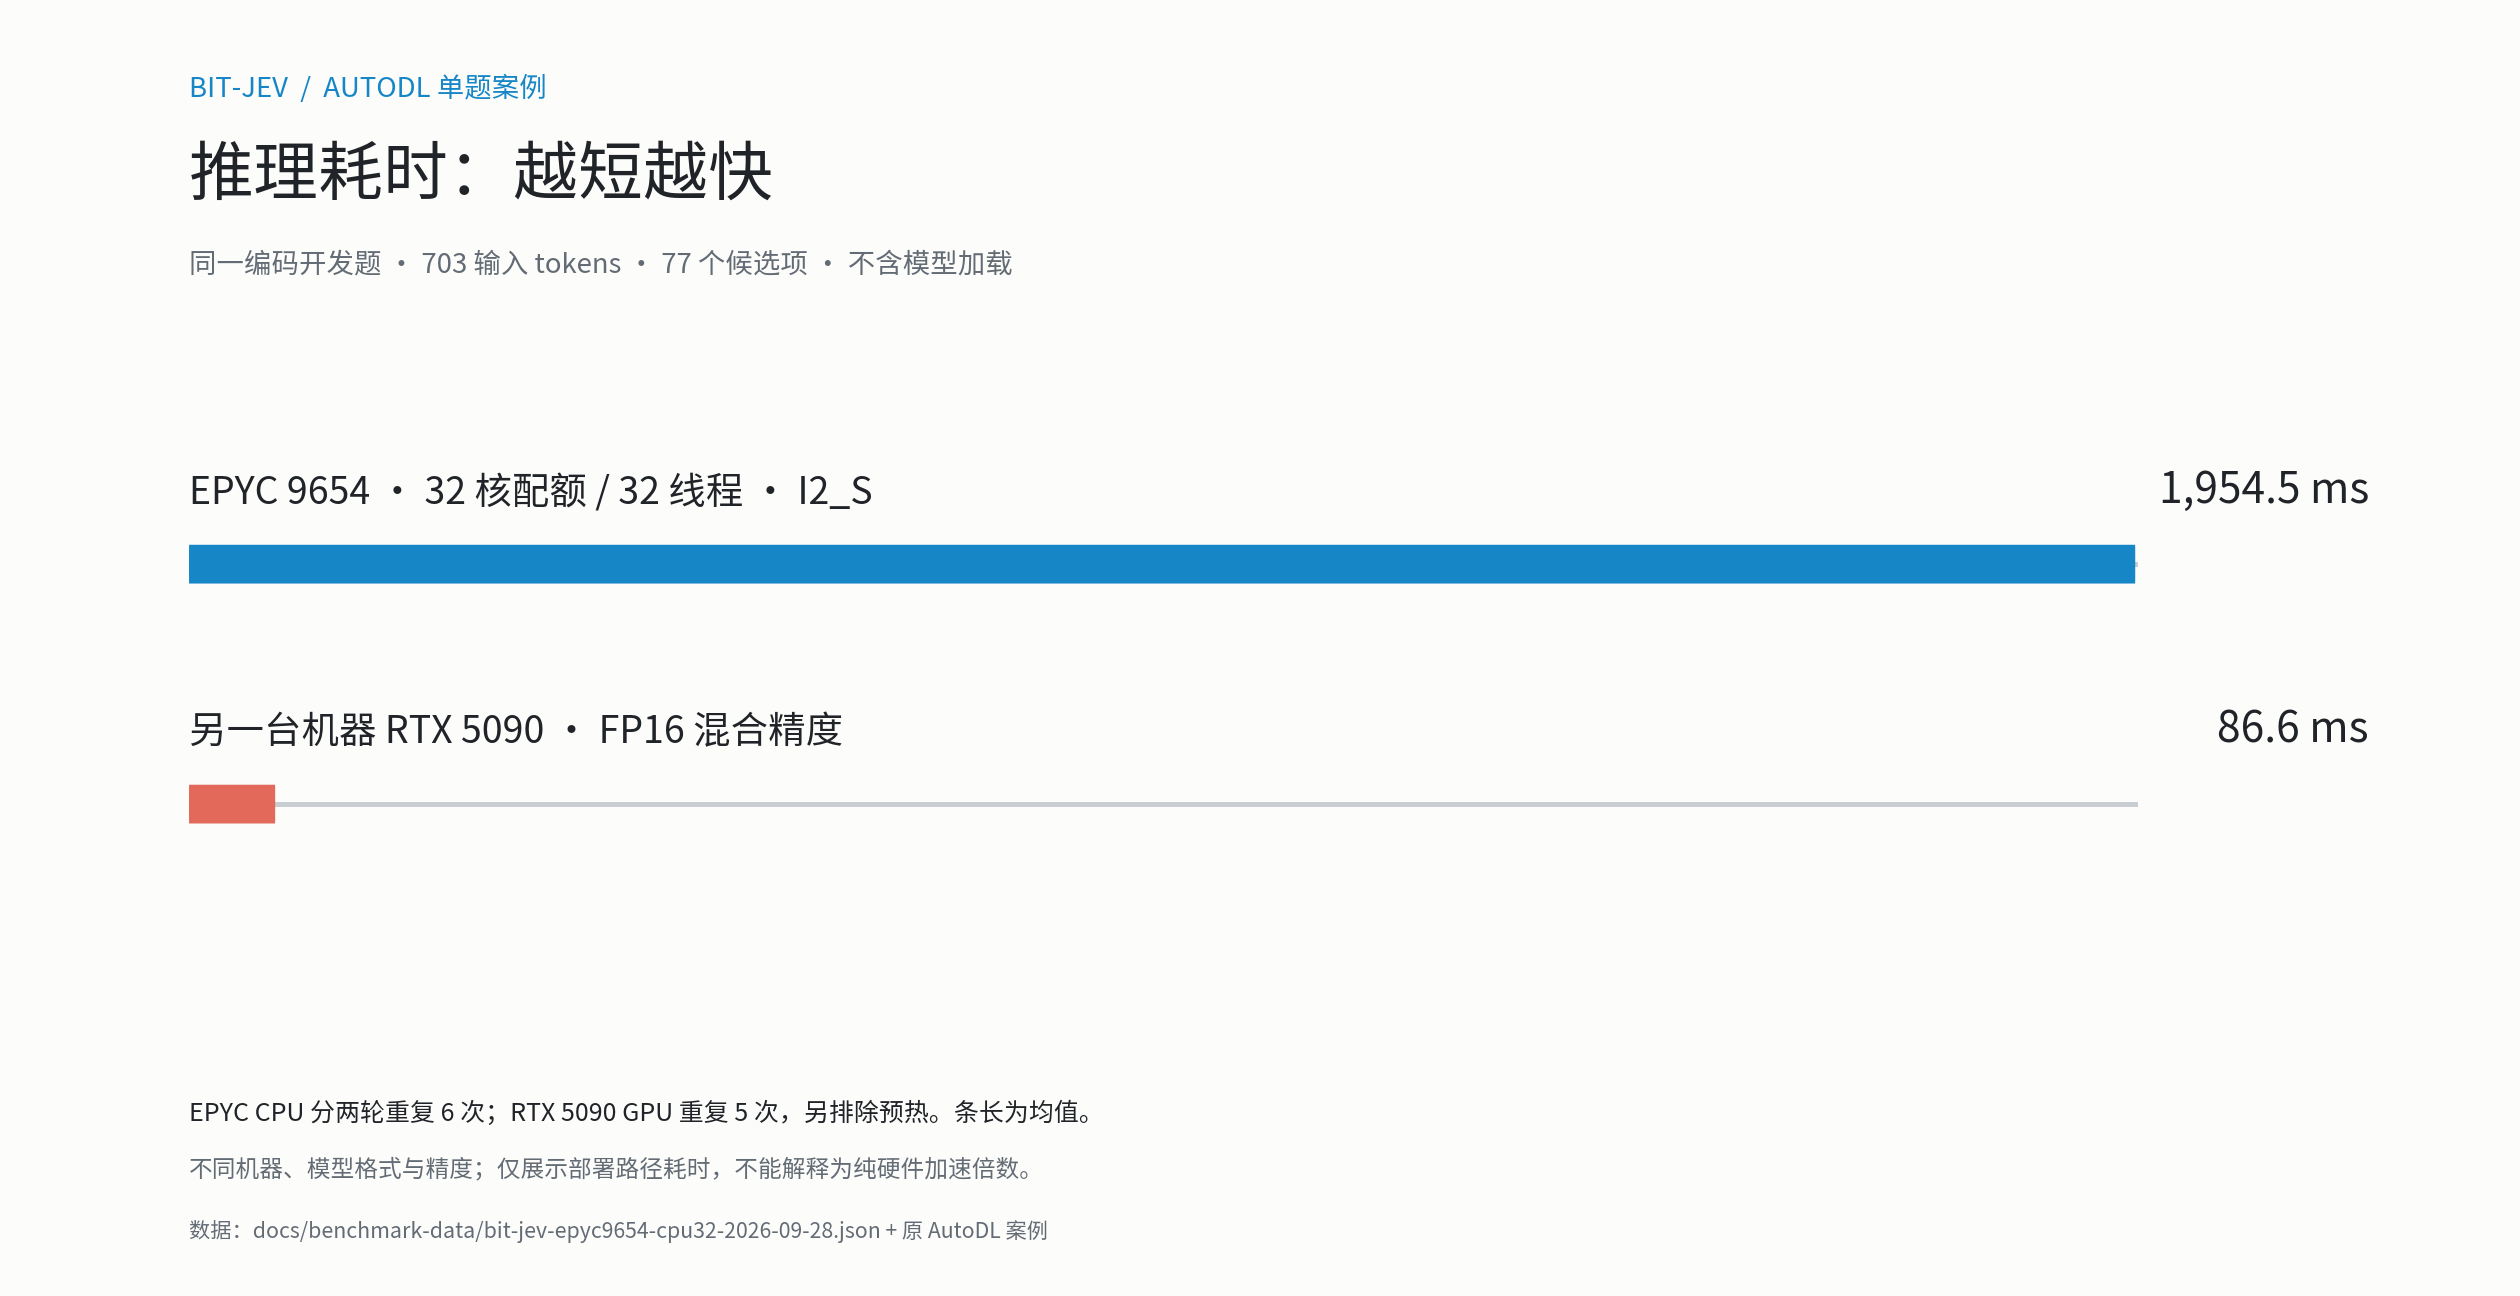
以下测量来自同一道固定开发题,输入 703 tokens、77 个候选项;原生推理计时不含模型加载。速度图采用 EPYC 9654 容器 32 核配额 / 32 线程 I2_S 新测量与另一台机器的历史 RTX 5090 FP16 混合精度 PyTorch 路径;内存图仍展示原 Xeon Gold 6459C / RTX 5090 同机案例。这组 GPU 数字不是新 pip 包的 GGUF/Vulkan 或 GGUF/CUDA 测试结果。
|
| 102 |
|
| 103 |
+
| 路径 | 平均推理时间 | 重复次数 | 观测内存 |
|
| 104 |
| --- | ---: | ---: | ---: |
|
| 105 |
+
| EPYC 9654,32 核配额 / 32 线程,I2_S | 1,954.46 ms | 6 | 进程峰值 RSS 1,625.88 MiB |
|
| 106 |
+
| Xeon Gold 6459C,8 线程(历史) | 3,127.88 ms | 3 | 进程峰值 RSS 1,622.74 MiB |
|
| 107 |
+
| Xeon Gold 6459C,16 线程(历史) | 1,972.17 ms | 3 | 进程峰值 RSS 1,624.52 MiB |
|
| 108 |
+
| 另一台机器 RTX 5090,FP16 | 86.56 ms | 5 | GPU 峰值分配 4,935.53 MiB |
|
| 109 |
+
|
| 110 |
+

|
| 111 |
|
| 112 |
+

|
| 113 |
|
| 114 |
+
[English charts](bit-jev-case-speed.en.png)
|
| 115 |
|
| 116 |
+
EPYC 同机 16 线程补充测试均值 3,210.12 ms,32 线程约快 1.64 倍。图中 CPU 与 GPU 路径来自不同机器,且使用不同权重格式和数值精度,因此不能解释为纯硬件加速比。CPU RSS 与 GPU 分配量是不同口径。此单题少量重复只作为案例,不代表通用吞吐或准确率承诺。[EPYC 32 线程逐次数据](https://github.com/Zeaulo/bit-jev/blob/main/docs/benchmark-data/bit-jev-epyc9654-cpu32-2026-09-28.json)与原同机案例 `benchmark_case_autodl.json` 均不含输入文本、候选内容或预测结果。模型不生成答案 token,因此不适用生成 tokens/s 指标。准确率、Brier、NLL 与 ECE 尚无可复核的公开留出集报告,本页不填入推测值。
|
| 117 |
|
| 118 |
+
## 数据来源与使用边界
|
| 119 |
|
| 120 |
+
训练数据是本地 `decision-v7` 多源决策集,包含 Yelp 评论记录;教师监督来自 Kev 9B 候选项 logits。仓库不包含 Yelp 原始记录。项目已向 Yelp 发送关于衍生权重和指标发布范围的许可申请,截至 2026-09-28 未收到书面答复。下载者应自行审查适用的 Yelp 数据条款及其对衍生权重的影响。
|
| 121 |
|
| 122 |
+
本模型**没有单独授予开放权重许可证**。代码仓库的 Apache-2.0、Microsoft 基础模型许可证及 Kev 源码许可证分别适用于各自作品,不能视为对 Yelp 数据或本衍生检查点的许可。此卡记录项目当前公开状态,不构成法律意见。
|
| 123 |
|
| 124 |
+
## 评测范围与局限
|
| 125 |
|
| 126 |
+
- 当前公开的 bit-jev 结果只有上表的单题延迟与内存案例;微软原版 BitNet 的基础模型基准是另一组独立测量,不能当成本模型成绩。
|
| 127 |
+
- 没有提供完整训练/测试来源拆分上的 Accuracy、Brier、NLL、ECE 或置信区间。
|
| 128 |
+
- 测试题为开发案例,重复次数少,不能外推到长输入、多问题请求或其他 CPU/GPU。
|
| 129 |
+
- 当前原生 CPU runner 每个问题执行一条因果序列;多问题请求会重复处理共享 state。
|
| 130 |
+
- 选择结果受候选项措辞、顺序、长度与训练分布影响。重要决策需在目标数据上验证并保留人工复核。
|
| 131 |
|
| 132 |
+
## 引用
|
| 133 |
|
| 134 |
```bibtex
|
| 135 |
@misc{bitjev2026,
|
README.zh-CN.md
CHANGED
|
@@ -14,18 +14,18 @@ tags:
|
|
| 14 |
|
| 15 |
# bit-jev-2b-distilled
|
| 16 |
|
| 17 |
-
[English model card](README.en.md) · [源码仓库](https://github.com/Zeaulo/bit-jev) · [pip 安装](https://pypi.org/project/bit-jev/)
|
| 18 |
|
| 19 |
-

|
| 31 |
|
|
@@ -72,37 +72,48 @@ I2_S GGUF + float32 指针头
|
|
| 72 |
|
| 73 |
## 推理示例
|
| 74 |
|
| 75 |
-
推荐使用 pip 包。Windows x64 且 CPU 支持 AVX2 时,bit-jev 0.
|
| 76 |
-
|
| 77 |
-
```bash
|
| 78 |
-
pip install bit-jev
|
| 79 |
-
```
|
| 80 |
|
| 81 |
```python
|
| 82 |
-
from bit_jev import BitJev
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 83 |
|
| 84 |
-
request = {"state": "客户报告重复扣款。", "questions": {"team": {"type": "choice", "instructions": "哪个团队处理?", "criteria": {"billing": "支付退款", "shipping": "物流配送"}}}}
|
| 85 |
with BitJev.from_pretrained(device="cpu", threads=8) as model:
|
| 86 |
-
|
|
|
|
|
|
|
| 87 |
```
|
| 88 |
|
| 89 |
`device="gpu"` 使用 Vulkan;`device="cuda"` 使用 CUDA 构建。`infer()` 复用常驻模型并返回答案、logits、概率和原生推理耗时。完整 CLI、离线目录和构建细节见[GGUF 安装与推理指南](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.zh-CN.md)。本模型仓库只保存模型文件;两个预编译 runner 位于 PyPI 的 Windows x64 wheel。
|
| 90 |
|
| 91 |
-
## 性能案例:AutoDL
|
| 92 |
|
| 93 |
-
以下测量来自一道固定开发题,输入 703 tokens、77 个候选项;推理计时不含加载。
|
| 94 |
|
| 95 |
| 路径 | 平均推理时间 | 重复次数 | 观测内存 |
|
| 96 |
| --- | ---: | ---: | ---: |
|
| 97 |
-
|
|
| 98 |
-
|
|
| 99 |
-
|
|
|
|
|
|
|
|
|
|
|
| 100 |
|
| 101 |
-
![bit-jev AutoDL
|
| 102 |
|
| 103 |
-
[English
|
| 104 |
|
| 105 |
-
同
|
| 106 |
|
| 107 |
## 数据来源与使用边界
|
| 108 |
|
|
|
|
| 14 |
|
| 15 |
# bit-jev-2b-distilled
|
| 16 |
|
| 17 |
+
[English model card](README.en.md) · [源码仓库](https://github.com/Zeaulo/bit-jev) · [pip 安装](https://pypi.org/project/bit-jev/) · [ModelScope 镜像](https://www.modelscope.cn/models/JingHao9616/bit-jev-2b-distilled)
|
| 18 |
|
| 19 |
+

|
| 20 |
|
| 21 |
+
在运行推理的同一个 Python 3.11/3.12 环境中安装并核对版本:
|
| 22 |
|
| 23 |
```bash
|
| 24 |
+
python -m pip install --upgrade --no-cache-dir bit-jev==0.12.10 -i https://pypi.org/simple
|
| 25 |
+
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 26 |
```
|
| 27 |
|
| 28 |
+
版本应为 `0.12.10`,导入路径应指向当前环境的 `site-packages/bit_jev`。然后直接运行下方的 Python 示例;无需依赖 `bit-jev-demo` 命令的 PATH。首次加载会下载约 1.19 GB 模型,后续复用缓存。默认先尝试 Hugging Face,连接失败时回退 ModelScope;国内网络可在 `from_pretrained()` 中传入 `source="modelscope"`。镜像版本滞后及环境混用的处理见[安装指南](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.zh-CN.md)。
|
| 29 |
|
| 30 |

|
| 31 |
|
|
|
|
| 72 |
|
| 73 |
## 推理示例
|
| 74 |
|
| 75 |
+
推荐使用 pip 包。Windows x64 且 CPU 支持 AVX2 时,bit-jev 0.12.10 wheel 已携带 CPU 与 Vulkan GPU 原生 runner;首次加载会按需下载约 1.19 GB 的模型。使用 `device="cpu"` 或 `device="gpu"` 推理无需 Git、CMake、C++ 编译器或 Vulkan SDK;Vulkan GPU 需要显卡驱动提供 `vulkan-1.dll`。其他系统和 CUDA 后端按需从固定源码构建,需要 Git、CMake 3.28+ 与 C++17 编译器;CUDA 构建还需要 CUDA Toolkit。
|
|
|
|
|
|
|
|
|
|
|
|
|
| 76 |
|
| 77 |
```python
|
| 78 |
+
from bit_jev.gguf import BitJev
|
| 79 |
+
|
| 80 |
+
request = {
|
| 81 |
+
"state": "客户报告同一订单被重复扣款。",
|
| 82 |
+
"questions": {
|
| 83 |
+
"team": {
|
| 84 |
+
"type": "choice",
|
| 85 |
+
"instructions": "哪个团队应处理?",
|
| 86 |
+
"criteria": {"billing": "支付与退款", "shipping": "物流配送"},
|
| 87 |
+
}
|
| 88 |
+
},
|
| 89 |
+
}
|
| 90 |
|
|
|
|
| 91 |
with BitJev.from_pretrained(device="cpu", threads=8) as model:
|
| 92 |
+
result = model.infer(request)
|
| 93 |
+
print(result["answers"])
|
| 94 |
+
print(result["latency_ms"])
|
| 95 |
```
|
| 96 |
|
| 97 |
`device="gpu"` 使用 Vulkan;`device="cuda"` 使用 CUDA 构建。`infer()` 复用常驻模型并返回答案、logits、概率和原生推理耗时。完整 CLI、离线目录和构建细节见[GGUF 安装与推理指南](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.zh-CN.md)。本模型仓库只保存模型文件;两个预编译 runner 位于 PyPI 的 Windows x64 wheel。
|
| 98 |
|
| 99 |
+
## 性能案例:AutoDL EPYC 9654 CPU 与另一台 RTX 5090
|
| 100 |
|
| 101 |
+
以下测量来自同一道固定开发题,输入 703 tokens、77 个候选项;原生推理计时不含模型加载。速度图采用 EPYC 9654 容器 32 核配额 / 32 线程 I2_S 新测量与另一台机器的历史 RTX 5090 FP16 混合精度 PyTorch 路径;内存图仍展示原 Xeon Gold 6459C / RTX 5090 同机案例。这组 GPU 数字不是新 pip 包的 GGUF/Vulkan 或 GGUF/CUDA 测试结果。
|
| 102 |
|
| 103 |
| 路径 | 平均推理时间 | 重复次数 | 观测内存 |
|
| 104 |
| --- | ---: | ---: | ---: |
|
| 105 |
+
| EPYC 9654,32 核配额 / 32 线程,I2_S | 1,954.46 ms | 6 | 进程峰值 RSS 1,625.88 MiB |
|
| 106 |
+
| Xeon Gold 6459C,8 线程(历史) | 3,127.88 ms | 3 | 进程峰值 RSS 1,622.74 MiB |
|
| 107 |
+
| Xeon Gold 6459C,16 线程(历史) | 1,972.17 ms | 3 | 进程峰值 RSS 1,624.52 MiB |
|
| 108 |
+
| 另一台机器 RTX 5090,FP16 | 86.56 ms | 5 | GPU 峰值分配 4,935.53 MiB |
|
| 109 |
+
|
| 110 |
+

|
| 111 |
|
| 112 |
+

|
| 113 |
|
| 114 |
+
[English charts](bit-jev-case-speed.en.png)
|
| 115 |
|
| 116 |
+
EPYC 同机 16 线程补充测试均值 3,210.12 ms,32 线程约快 1.64 倍。图中 CPU 与 GPU 路径来自不同机器,且使用不同权重格式和数值精度,因此不能解释为纯硬件加速比。CPU RSS 与 GPU 分配量是不同口径。此单题少量重复只作为案例,不代表通用吞吐或准确率承诺。[EPYC 32 线程逐次数据](https://github.com/Zeaulo/bit-jev/blob/main/docs/benchmark-data/bit-jev-epyc9654-cpu32-2026-09-28.json)与原同机案例 `benchmark_case_autodl.json` 均不含输入文本、候选内容或预测结果。模型不生成答案 token,因此不适用生成 tokens/s 指标。准确率、Brier、NLL 与 ECE 尚无可复核的公开留出集报告,本页不填入推测值。
|
| 117 |
|
| 118 |
## 数据来源与使用边界
|
| 119 |
|
benchmark_case_epyc.json
ADDED
|
@@ -0,0 +1,62 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "bit-jev-epyc9654-cpu32-case-v1",
|
| 3 |
+
"publication_status": "public_sanitized_case_study",
|
| 4 |
+
"checkpoint": {
|
| 5 |
+
"name": "bit-jev-2b-distilled",
|
| 6 |
+
"cpu_format": "I2_S GGUF with float32 pointer head",
|
| 7 |
+
"cpu_gguf_sha256": "731700ba3112e35dc9bbecf54fe97b79d91b69246d765413ce683e06250773ff",
|
| 8 |
+
"head_f32_sha256": "a3b3df8f5d4803d575e64c4f15e8ab09c00762e4140917c07925705ba43c1b27"
|
| 9 |
+
},
|
| 10 |
+
"workload": {
|
| 11 |
+
"questions": 1,
|
| 12 |
+
"input_tokens": 703,
|
| 13 |
+
"options": 77,
|
| 14 |
+
"encoded_input_sha256": "2d2921d9d0e46c1540f71c283b07668ff0fe8ac5d2fa52911588f65d0be4c9c6",
|
| 15 |
+
"input_contents_included": false
|
| 16 |
+
},
|
| 17 |
+
"hardware": {
|
| 18 |
+
"cpu": "AMD EPYC 9654 96-Core Processor",
|
| 19 |
+
"platform": "AutoDL Ubuntu 22.04 container, Linux x86_64",
|
| 20 |
+
"host_logical_cpus_visible_to_lscpu": 192,
|
| 21 |
+
"container_cpu_quota_cores": 32,
|
| 22 |
+
"container_cpuset": "64-95",
|
| 23 |
+
"numa_nodes_visible": 1
|
| 24 |
+
},
|
| 25 |
+
"build": {
|
| 26 |
+
"project_commit": "4272aacc0cabc167077e61df86acaedfab5fd35f",
|
| 27 |
+
"bitnet_commit": "0b341e582afbf9e1011f24744b554c96a3477eb5",
|
| 28 |
+
"llama_cpp_commit": "390c307752ab78fd8189f359d6954c9ba1be74af",
|
| 29 |
+
"cmake": "3.31.10",
|
| 30 |
+
"compiler": "g++ 11.4.0",
|
| 31 |
+
"configuration": "Release, GGML_NATIVE=ON, GGML_OPENMP=ON, Vulkan=OFF, CUDA=OFF",
|
| 32 |
+
"native_binary_sha256": "8f24ada846ab1f30b2b1ae4ac0a35d007747d3a95f5ae1c6cf66b465e5081077"
|
| 33 |
+
},
|
| 34 |
+
"timing_protocol": {
|
| 35 |
+
"native_runner_threads": 32,
|
| 36 |
+
"batch": 128,
|
| 37 |
+
"process_launches": 2,
|
| 38 |
+
"requests_per_launch": 3,
|
| 39 |
+
"model_loading_included_in_native_latency": false,
|
| 40 |
+
"explicit_cpu_warmup": false,
|
| 41 |
+
"same_encoded_request_repeated": true
|
| 42 |
+
},
|
| 43 |
+
"measurement": {
|
| 44 |
+
"path": "native_cpu_i2_s_32_threads",
|
| 45 |
+
"inference_ms_by_launch": [
|
| 46 |
+
[1979.920258, 1946.525392, 1949.816113],
|
| 47 |
+
[1971.828346, 1949.075305, 1929.623975]
|
| 48 |
+
],
|
| 49 |
+
"peak_process_rss_mib_by_launch": [1625.8828125, 1625.7265625]
|
| 50 |
+
},
|
| 51 |
+
"diagnostic_16_thread_run": {
|
| 52 |
+
"inference_ms": [3225.943667, 3196.725099, 3207.690814],
|
| 53 |
+
"peak_process_rss_mib": 1623.09375
|
| 54 |
+
},
|
| 55 |
+
"comparison_boundary": {
|
| 56 |
+
"historical_gpu_source": "bit-jev-autodl-case-2026-09-27.json",
|
| 57 |
+
"gpu_hardware": "NVIDIA GeForce RTX 5090 on a different AutoDL host",
|
| 58 |
+
"gpu_path": "experimental FP16 mixed-precision PyTorch",
|
| 59 |
+
"note": "The speed figure juxtaposes deployment paths measured on different hosts and weight formats. It is not an isolated CPU-versus-GPU hardware speedup."
|
| 60 |
+
},
|
| 61 |
+
"rights_note": "The training set included Yelp review records. The maintainer directed publication of sanitized timing aggregates; no request text, options, prediction, or raw review record is included. No written Yelp response had been received on 2026-09-28."
|
| 62 |
+
}
|
bit-jev-case-memory.en.png
ADDED
|
Git LFS Details
|
bit-jev-case-memory.zh-CN.png
ADDED
|
Git LFS Details
|
bit-jev-case-speed.en.png
ADDED
|
Git LFS Details
|
bit-jev-case-speed.zh-CN.png
ADDED
|
Git LFS Details
|
bit-jev-logo.png
ADDED
|
Git LFS Details
|