

Add bilingual AutoDL benchmark figures
Browse files- .gitattributes +2 -0
- README.en.md +8 -2
- README.md +8 -2
- bit-jev-autodl-case.en.png +3 -0
- bit-jev-autodl-case.zh-CN.png +3 -0
.gitattributes
CHANGED
|
@@ -36,3 +36,5 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 36 |
backbone-i2_s.gguf filter=lfs diff=lfs merge=lfs -text
|
| 37 |
head.f32 filter=lfs diff=lfs merge=lfs -text
|
| 38 |
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
| 36 |
backbone-i2_s.gguf filter=lfs diff=lfs merge=lfs -text
|
| 37 |
head.f32 filter=lfs diff=lfs merge=lfs -text
|
| 38 |
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
bit-jev-autodl-case.en.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
bit-jev-autodl-case.zh-CN.png filter=lfs diff=lfs merge=lfs -text
|
README.en.md
CHANGED
|
@@ -32,8 +32,8 @@ bit-jev-2b-distilled is a structured-decision student model. An input contains a
|
|
| 32 |
```text
|
| 33 |
Microsoft BitNet b1.58 2B BF16
|
| 34 |
↓ LoRA fine-tuning + pointer-head training
|
| 35 |
-
Initial bit-jev
|
| 36 |
-
|
| 37 |
Full-student distillation + pointer head
|
| 38 |
↓ I2_S quantized export
|
| 39 |
I2_S GGUF + float32 pointer head
|
|
@@ -79,6 +79,10 @@ The measurements below use one fixed development request with 703 input tokens a
|
|
| 79 |
| CPU, 16 threads | 1,972.17 ms | 3 | 1,624.52 MiB peak process RSS |
|
| 80 |
| RTX 5090 | 86.56 ms | 5 | 4,935.53 MiB peak GPU allocation |
|
| 81 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 82 |
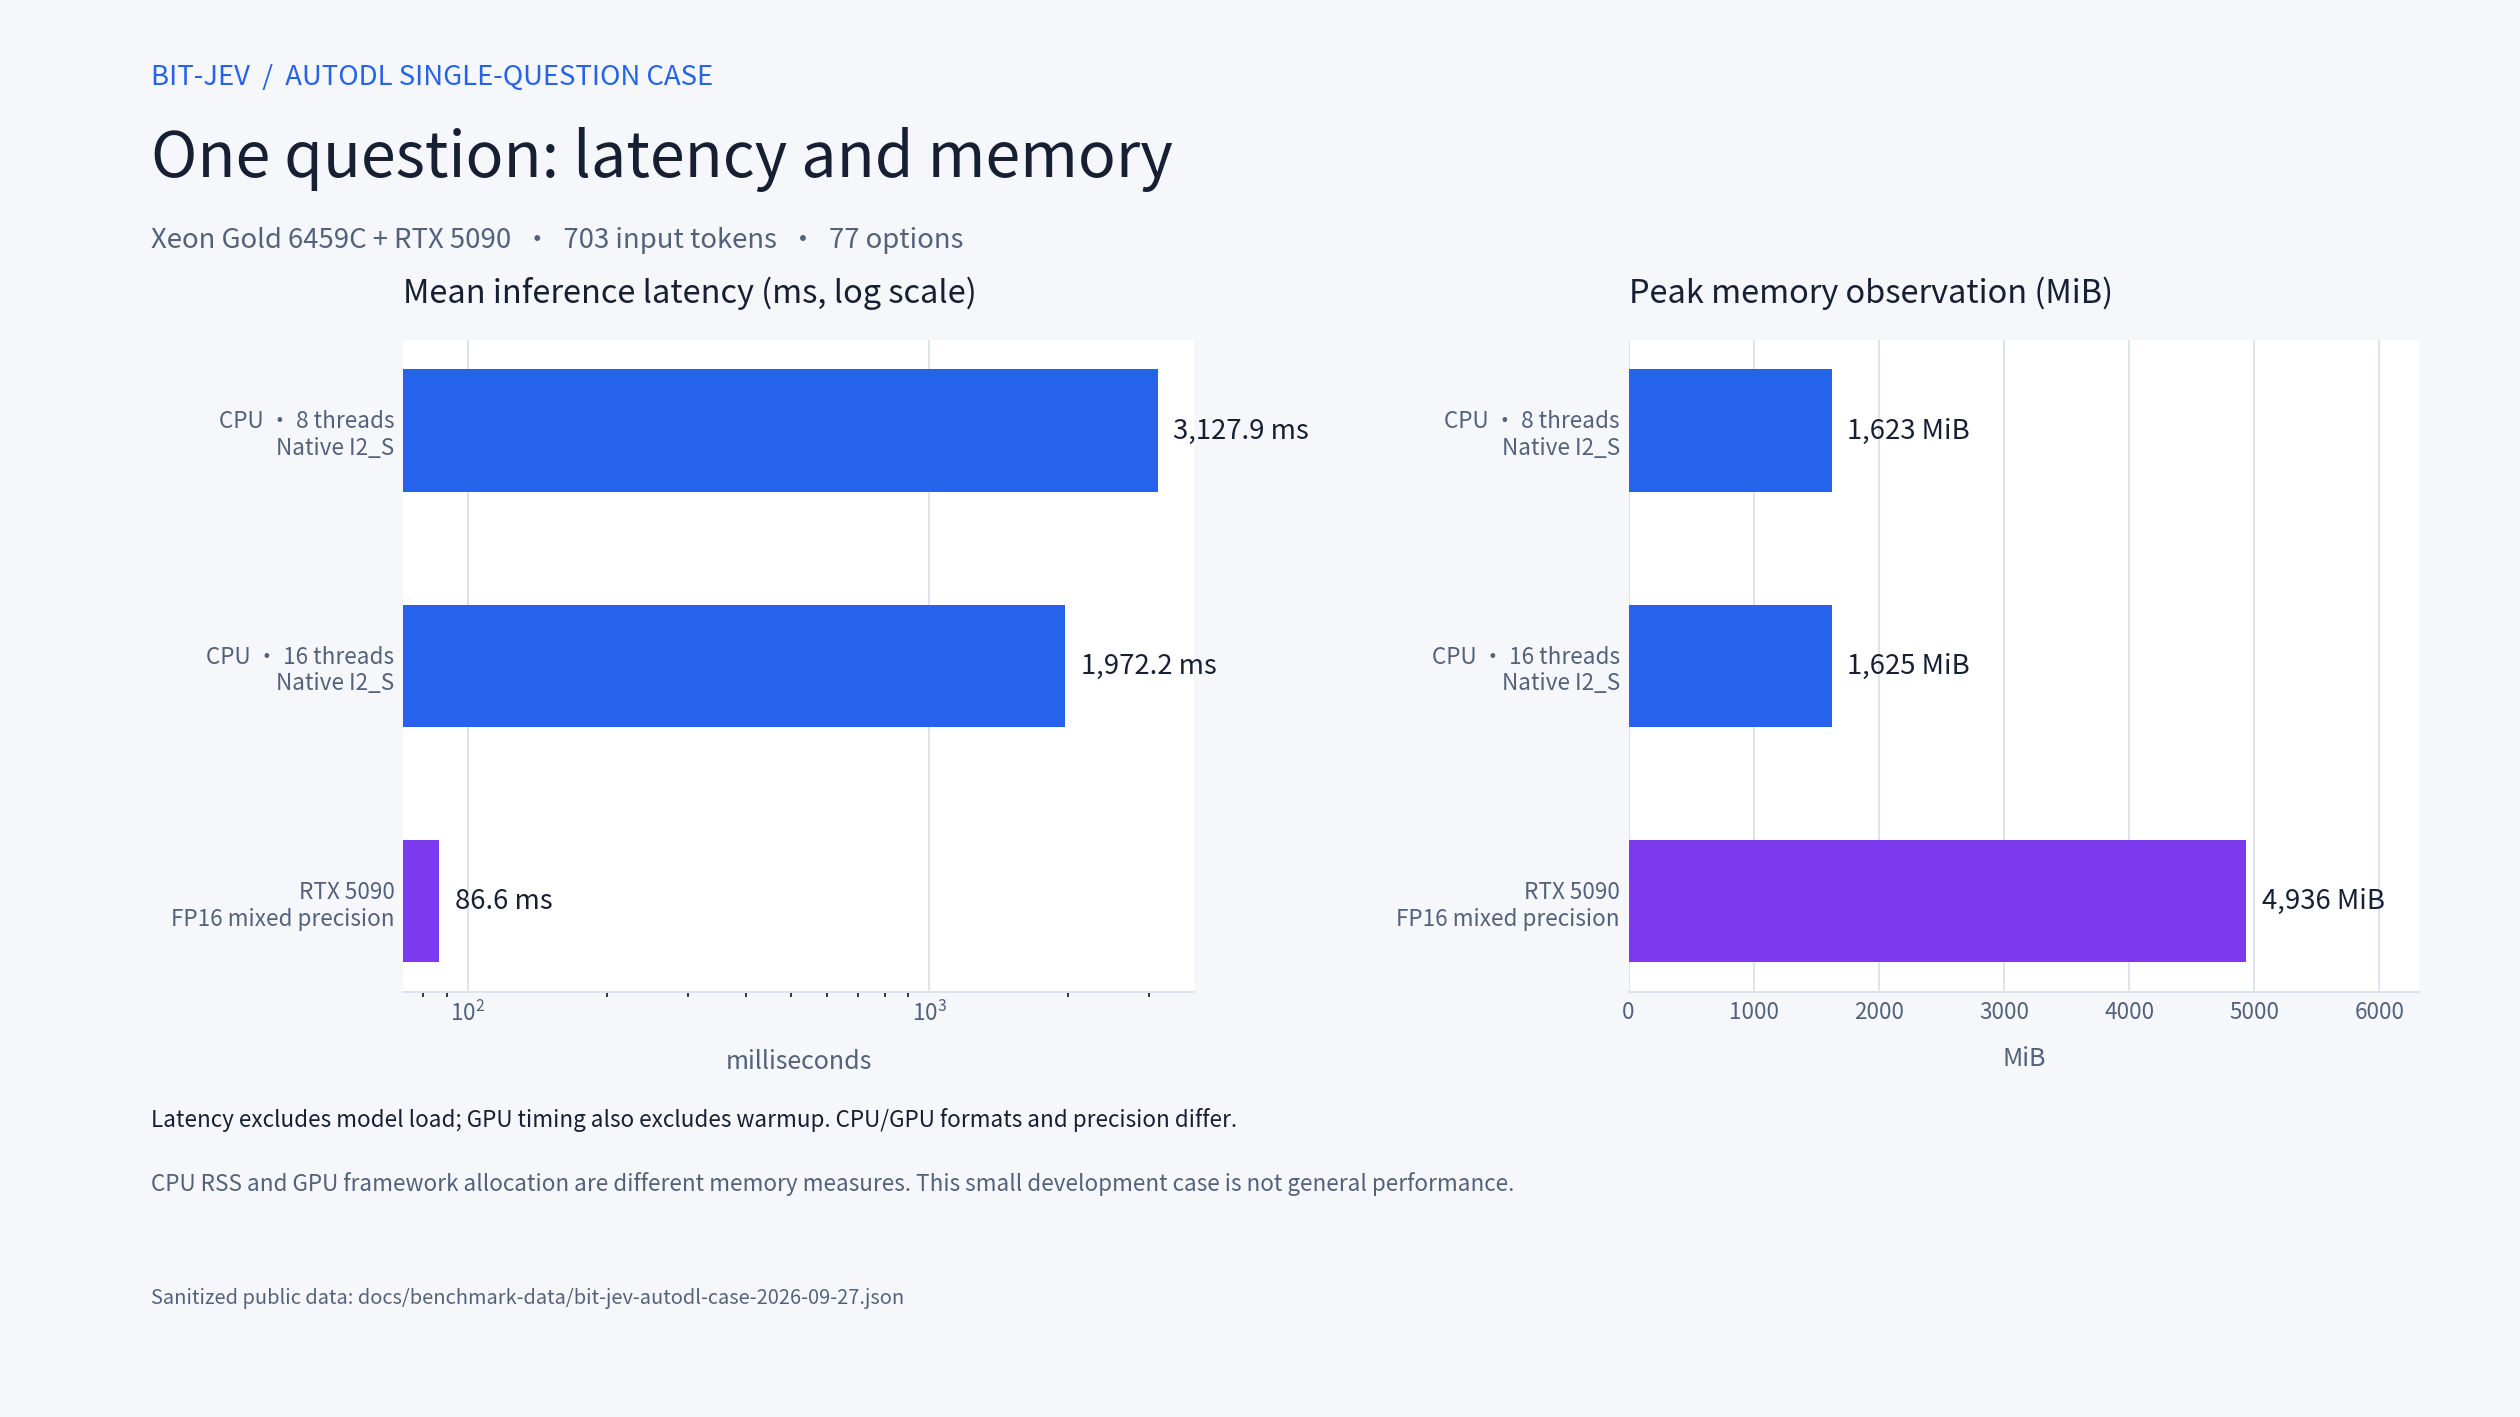
For this one request, the 16-thread CPU to RTX 5090 latency ratio is about 22.8. The paths use different weight formats and numeric precision, so this is not an isolated hardware speedup. CPU RSS and GPU allocation are different measures. This small case study is not a general throughput or accuracy claim. Sanitized timings are in `benchmark_case_autodl.json`; the input, options, and predictions are not included. Generated tokens/s does not apply because the model scores options and emits structured decisions. No auditable held-out report for accuracy, Brier, NLL, or ECE is available, so no such values are claimed.
|
| 83 |
|
| 84 |
## Data provenance and use
|
|
@@ -106,3 +110,5 @@ Training used the local multi-source `decision-v7` decision set, which includes
|
|
| 106 |
}
|
| 107 |
```
|
| 108 |
|
|
|
|
|
|
|
|
|
| 32 |
```text
|
| 33 |
Microsoft BitNet b1.58 2B BF16
|
| 34 |
↓ LoRA fine-tuning + pointer-head training
|
| 35 |
+
Initial bit-jev model and pointer head
|
| 36 |
+
+ candidate logits from the Kev 9B teacher
|
| 37 |
Full-student distillation + pointer head
|
| 38 |
↓ I2_S quantized export
|
| 39 |
I2_S GGUF + float32 pointer head
|
|
|
|
| 79 |
| CPU, 16 threads | 1,972.17 ms | 3 | 1,624.52 MiB peak process RSS |
|
| 80 |
| RTX 5090 | 86.56 ms | 5 | 4,935.53 MiB peak GPU allocation |
|
| 81 |
|
| 82 |
+

|
| 83 |
+
|
| 84 |
+
[中文图表](bit-jev-autodl-case.zh-CN.png)
|
| 85 |
+
|
| 86 |
For this one request, the 16-thread CPU to RTX 5090 latency ratio is about 22.8. The paths use different weight formats and numeric precision, so this is not an isolated hardware speedup. CPU RSS and GPU allocation are different measures. This small case study is not a general throughput or accuracy claim. Sanitized timings are in `benchmark_case_autodl.json`; the input, options, and predictions are not included. Generated tokens/s does not apply because the model scores options and emits structured decisions. No auditable held-out report for accuracy, Brier, NLL, or ECE is available, so no such values are claimed.
|
| 87 |
|
| 88 |
## Data provenance and use
|
|
|
|
| 110 |
}
|
| 111 |
```
|
| 112 |
|
| 113 |
+
|
| 114 |
+
|
README.md
CHANGED
|
@@ -34,8 +34,8 @@ bit-jev-2b-distilled 是一个结构化判断学生模型。输入包含共享 `
|
|
| 34 |
```text
|
| 35 |
Microsoft BitNet b1.58 2B BF16
|
| 36 |
↓ LoRA 微调 + 指针头训练
|
| 37 |
-
bit-jev 初始
|
| 38 |
-
|
| 39 |
完整学生骨干蒸馏 + 指针头
|
| 40 |
↓ I2_S 量化导出
|
| 41 |
I2_S GGUF + float32 指针头
|
|
@@ -81,6 +81,10 @@ Linux 用户将二进制路径改为 `./core/build/bit-jev-cpu/bit-jev-cpu`。JS
|
|
| 81 |
| CPU,16 线程 | 1,972.17 ms | 3 | 进程峰值 RSS 1,624.52 MiB |
|
| 82 |
| RTX 5090 | 86.56 ms | 5 | GPU 峰值分配 4,935.53 MiB |
|
| 83 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 84 |
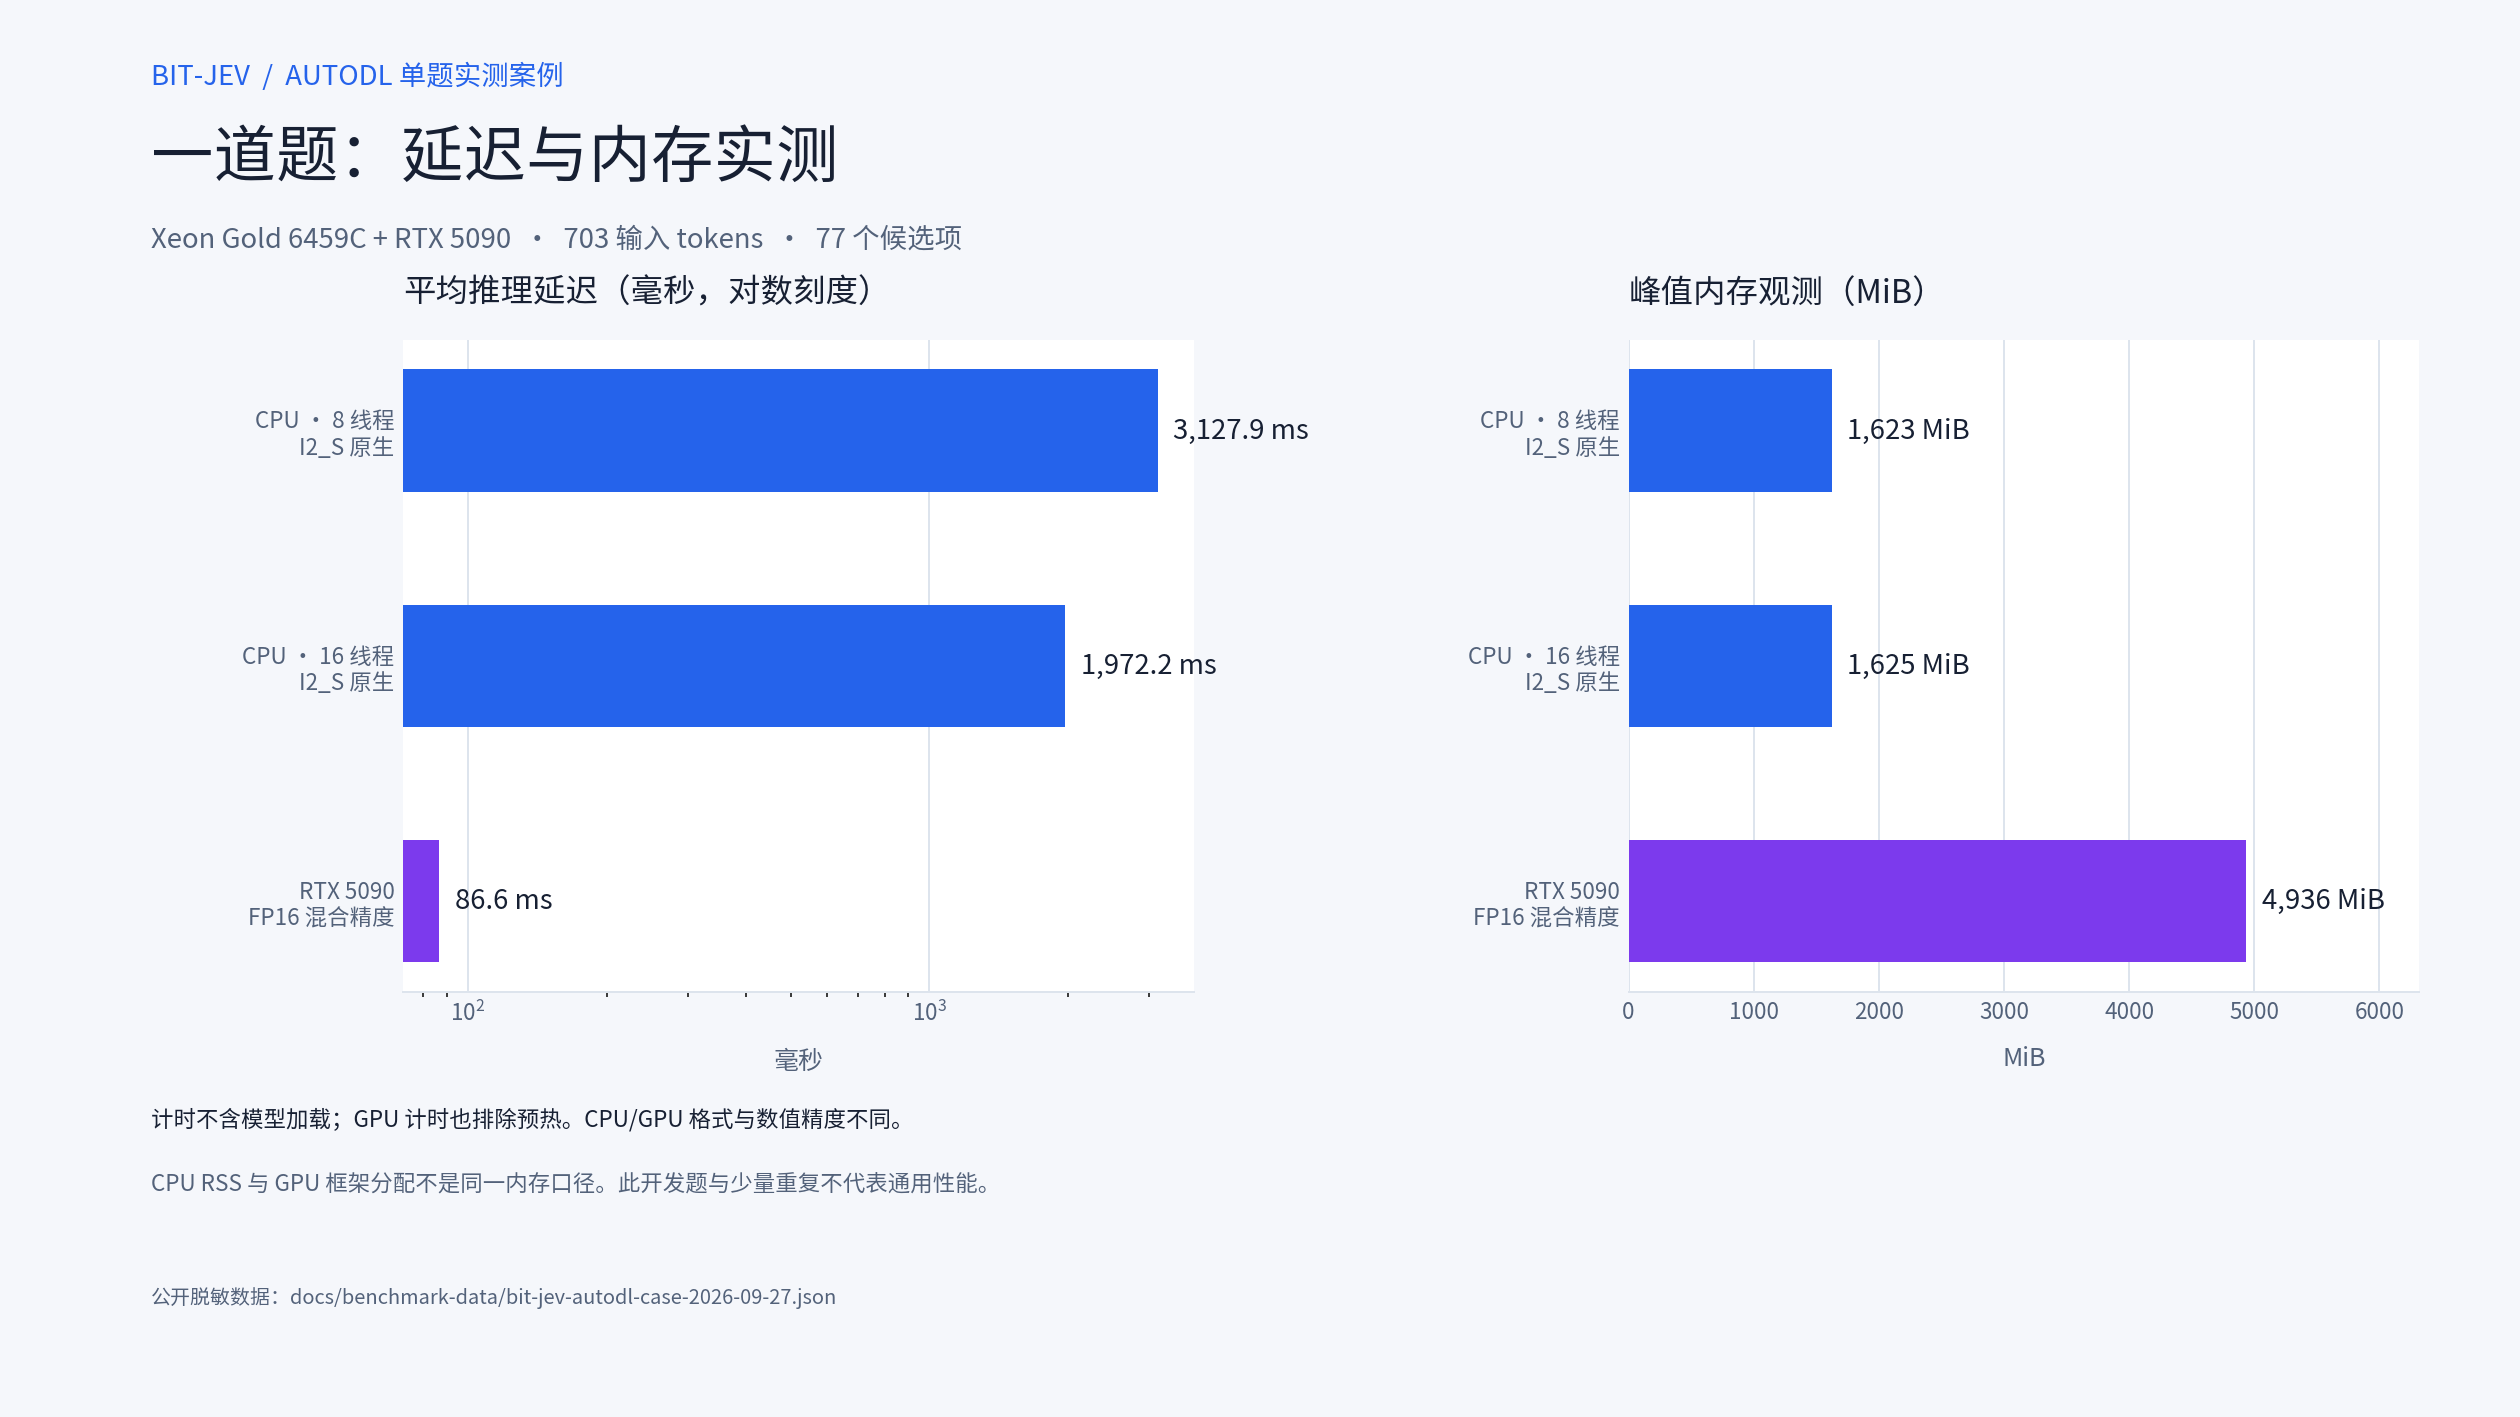
同一道题上,16 线程 CPU 与 RTX 5090 GPU 路径的延迟比约为 22.8。两条路径使用不同权重格式和数值精度,因此该比值不能解释为纯硬件加速比。CPU RSS 与 GPU 分配量是不同口径。此单题少量重复只作为案例,不代表通用吞吐或准确率承诺。详细的脱敏计时数据见 `benchmark_case_autodl.json`;本包没有收录输入文本、候选内容或预测结果。模型不生成答案 token,因此不适用生成 tokens/s 指标。准确率、Brier、NLL 与 ECE 尚无可复核的公开留出集报告,本页不填入推测值。
|
| 85 |
|
| 86 |
## 数据来源与使用边界
|
|
@@ -108,3 +112,5 @@ Linux 用户将二进制路径改为 `./core/build/bit-jev-cpu/bit-jev-cpu`。JS
|
|
| 108 |
}
|
| 109 |
```
|
| 110 |
|
|
|
|
|
|
|
|
|
| 34 |
```text
|
| 35 |
Microsoft BitNet b1.58 2B BF16
|
| 36 |
↓ LoRA 微调 + 指针头训练
|
| 37 |
+
bit-jev 初始模型与指针头
|
| 38 |
+
+ Kev 9B 教师候选项 logits
|
| 39 |
完整学生骨干蒸馏 + 指针头
|
| 40 |
↓ I2_S 量化导出
|
| 41 |
I2_S GGUF + float32 指针头
|
|
|
|
| 81 |
| CPU,16 线程 | 1,972.17 ms | 3 | 进程峰值 RSS 1,624.52 MiB |
|
| 82 |
| RTX 5090 | 86.56 ms | 5 | GPU 峰值分配 4,935.53 MiB |
|
| 83 |
|
| 84 |
+

|
| 85 |
+
|
| 86 |
+
[English chart](bit-jev-autodl-case.en.png)
|
| 87 |
+
|
| 88 |
同一道题上,16 线程 CPU 与 RTX 5090 GPU 路径的延迟比约为 22.8。两条路径使用不同权重格式和数值精度,因此该比值不能解释为纯硬件加速比。CPU RSS 与 GPU 分配量是不同口径。此单题少量重复只作为案例,不代表通用吞吐或准确率承诺。详细的脱敏计时数据见 `benchmark_case_autodl.json`;本包没有收录输入文本、候选内容或预测结果。模型不生成答案 token,因此不适用生成 tokens/s 指标。准确率、Brier、NLL 与 ECE 尚无可复核的公开留出集报告,本页不填入推测值。
|
| 89 |
|
| 90 |
## 数据来源与使用边界
|
|
|
|
| 112 |
}
|
| 113 |
```
|
| 114 |
|
| 115 |
+
|
| 116 |
+
|
bit-jev-autodl-case.en.png
ADDED
|
Git LFS Details
|
bit-jev-autodl-case.zh-CN.png
ADDED
|
Git LFS Details
|