

Update bilingual local web guides and flow figures
Browse files- README.en.md +4 -3
- README.md +4 -3
- README.zh-CN.md +4 -3
- project-flow.en.png +2 -2
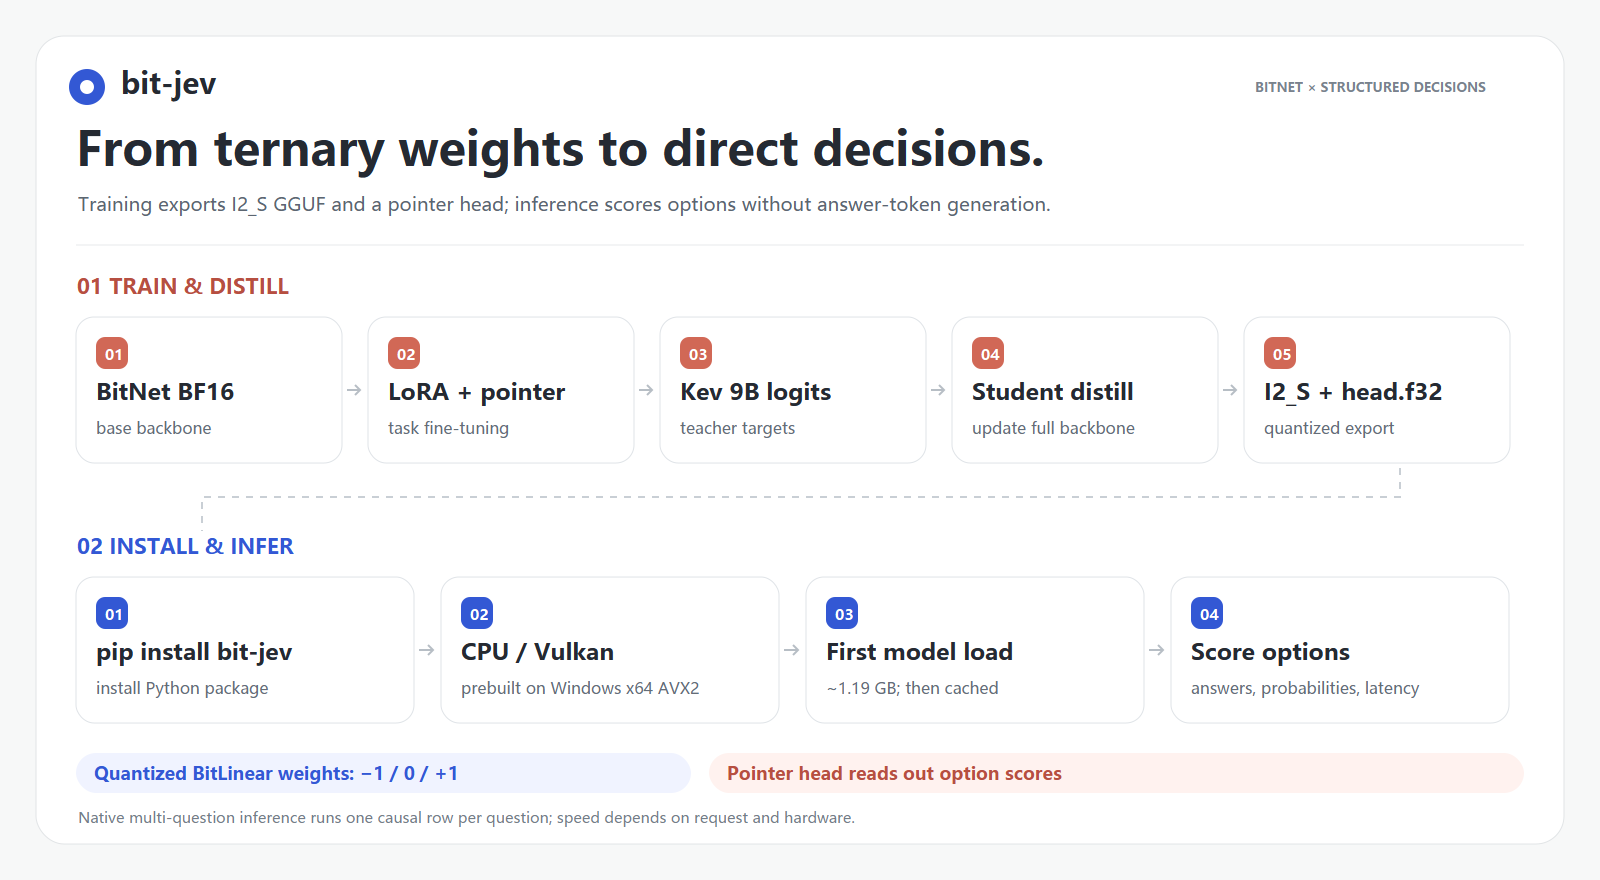
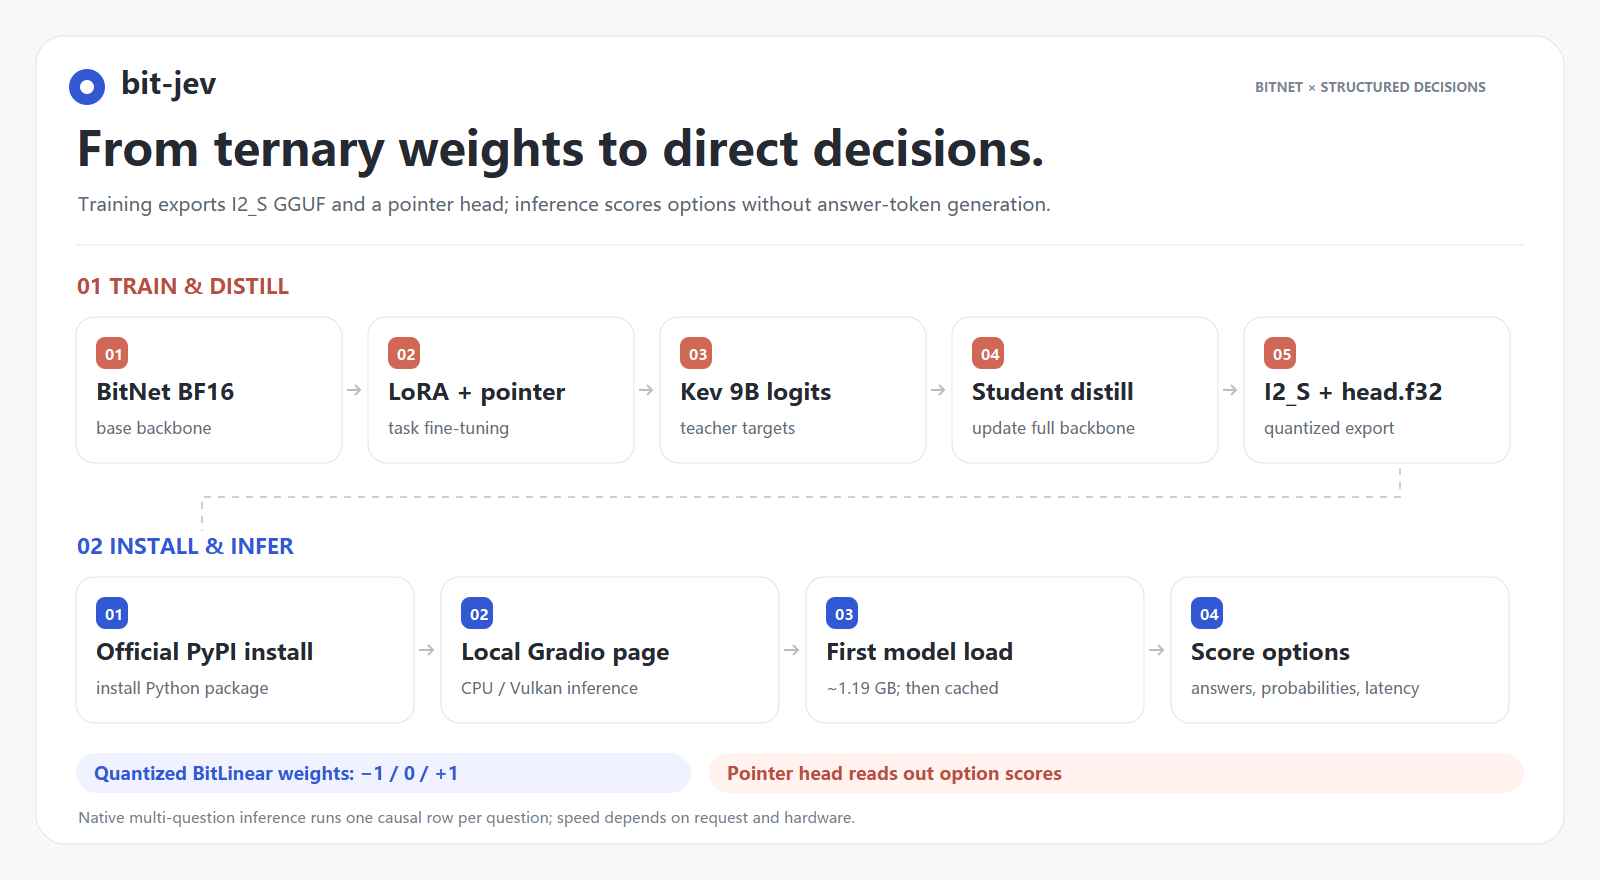
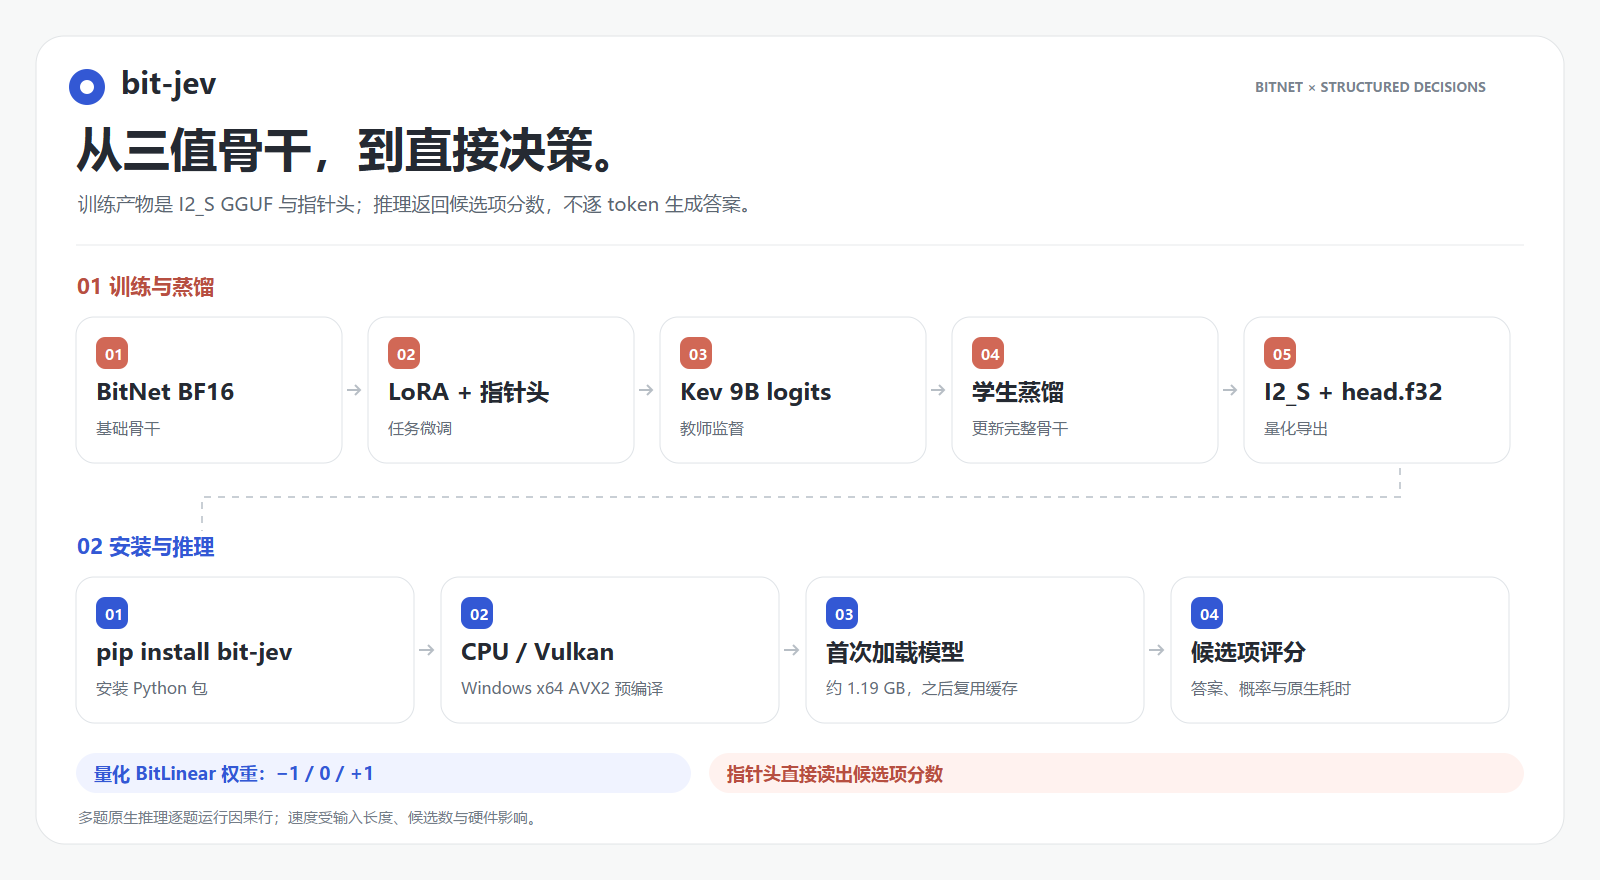
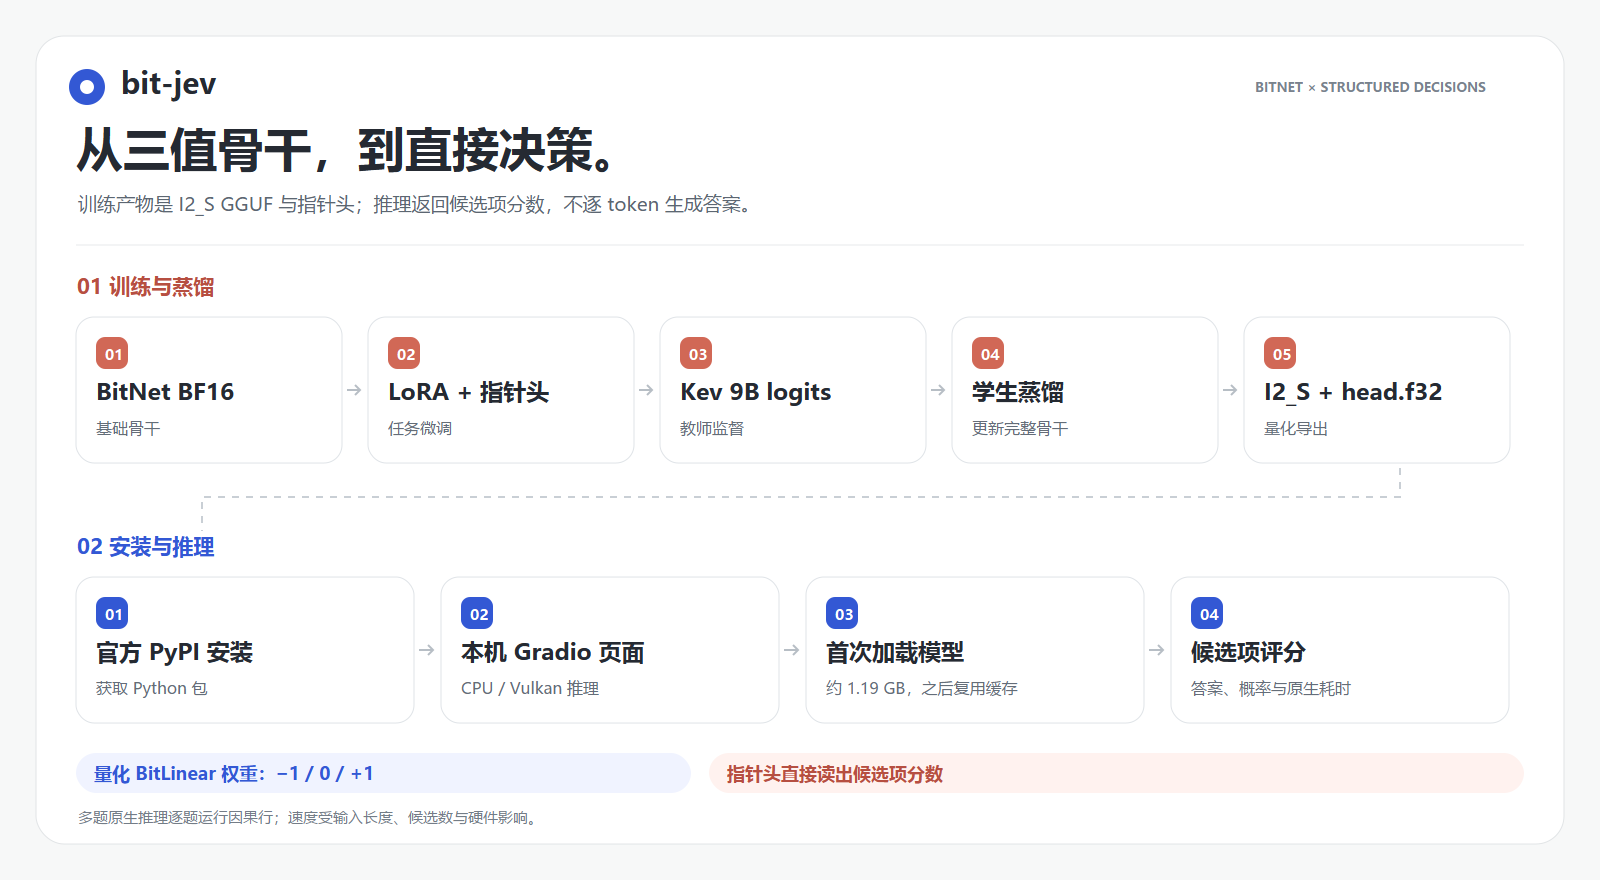
- project-flow.zh-CN.png +2 -2
README.en.md
CHANGED
|
@@ -23,11 +23,12 @@ The bilingual test page lets you edit a customer support scenario and inspect th
|
|
| 23 |
On Windows x64 with Python 3.11/3.12, install the current release with the interpreter that will run inference, then check the distribution version and import path:
|
| 24 |
|
| 25 |
```bash
|
| 26 |
-
|
|
|
|
| 27 |
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 28 |
```
|
| 29 |
|
| 30 |
-
The version should be `0.
|
| 31 |
|
| 32 |

|
| 33 |
|
|
@@ -72,7 +73,7 @@ This release contains the I2_S artifacts for the native CPU runner, matching tok
|
|
| 72 |
|
| 73 |
## Inference
|
| 74 |
|
| 75 |
-
Install the Python package. On Windows x64 with an AVX2 CPU, the bit-jev 0.
|
| 76 |
|
| 77 |
```python
|
| 78 |
from bit_jev.gguf import BitJev
|
|
|
|
| 23 |
On Windows x64 with Python 3.11/3.12, install the current release with the interpreter that will run inference, then check the distribution version and import path:
|
| 24 |
|
| 25 |
```bash
|
| 26 |
+
pip install bit-jev -i https://pypi.org/simple --upgrade
|
| 27 |
+
python -m bit_jev.demo
|
| 28 |
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 29 |
```
|
| 30 |
|
| 31 |
+
The version should be `0.13.10`, and the import path should point into the active environment's `site-packages/bit_jev`. The second command opens a local Choice, Noul, and Score page; the first submitted question downloads and loads roughly 1.19 GB, and later requests reuse the model. Add `--source modelscope` to choose ModelScope directly, `--device gpu` for Vulkan, or `--once` for the former one-shot JSON output. The Python API example below remains available. See the [install guide](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.md) for stale mirrors and mixed environments.
|
| 32 |
|
| 33 |

|
| 34 |
|
|
|
|
| 73 |
|
| 74 |
## Inference
|
| 75 |
|
| 76 |
+
Install the Python package. On Windows x64 with an AVX2 CPU, the bit-jev 0.13.10 wheel includes precompiled CPU and Vulkan GPU runners. For `device="cpu"` or `device="gpu"`, inference needs no Git, CMake, compiler, or Vulkan SDK. Vulkan needs a compatible graphics driver that supplies `vulkan-1.dll`. The roughly 1.19 GB model still downloads on first use. Other platforms and CUDA build from pinned source and require Git, CMake 3.28+, and a C++17 compiler; CUDA needs the CUDA Toolkit.
|
| 77 |
|
| 78 |
```python
|
| 79 |
from bit_jev.gguf import BitJev
|
README.md
CHANGED
|
@@ -23,11 +23,12 @@ tags:
|
|
| 23 |
在运行推理的同一个 Python 3.11/3.12 环境中安装并核对版本:
|
| 24 |
|
| 25 |
```bash
|
| 26 |
-
|
|
|
|
| 27 |
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 28 |
```
|
| 29 |
|
| 30 |
-
版本应为 `0.
|
| 31 |
|
| 32 |

|
| 33 |
|
|
@@ -74,7 +75,7 @@ I2_S GGUF + float32 指针头
|
|
| 74 |
|
| 75 |
## 推理示例
|
| 76 |
|
| 77 |
-
推荐使用 pip 包。Windows x64 且 CPU 支持 AVX2 时,bit-jev 0.
|
| 78 |
|
| 79 |
```python
|
| 80 |
from bit_jev.gguf import BitJev
|
|
|
|
| 23 |
在运行推理的同一个 Python 3.11/3.12 环境中安装并核对版本:
|
| 24 |
|
| 25 |
```bash
|
| 26 |
+
pip install bit-jev -i https://pypi.org/simple --upgrade
|
| 27 |
+
python -m bit_jev.demo
|
| 28 |
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 29 |
```
|
| 30 |
|
| 31 |
+
版本应为 `0.13.10`,导入路径应指向当前环境的 `site-packages/bit_jev`。第二条命令会在本机打开与在线测试同源的 Choice、Noul、Score 页面;首次提交才下载约 1.19 GB 模型。需要从 ModelScope 直接下载时可加 `--source modelscope`,使用 Vulkan 可加 `--device gpu`,旧式单题 JSON 可加 `--once`。下方仍保留完整 Python API 示例。镜像版本滞后及环境混用的处理见[安装指南](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.zh-CN.md)。
|
| 32 |
|
| 33 |

|
| 34 |
|
|
|
|
| 75 |
|
| 76 |
## 推理示例
|
| 77 |
|
| 78 |
+
推荐使用 pip 包。Windows x64 且 CPU 支持 AVX2 时,bit-jev 0.13.10 wheel 已携带 CPU 与 Vulkan GPU 原生 runner;首次加载会按需下载约 1.19 GB 的模型。使用 `device="cpu"` 或 `device="gpu"` 推理无需 Git、CMake、C++ 编译器或 Vulkan SDK;Vulkan GPU 需要显卡驱动提供 `vulkan-1.dll`。其他系统和 CUDA 后端按需从固定源码构建,需要 Git、CMake 3.28+ 与 C++17 编译器;CUDA 构建还需要 CUDA Toolkit。
|
| 79 |
|
| 80 |
```python
|
| 81 |
from bit_jev.gguf import BitJev
|
README.zh-CN.md
CHANGED
|
@@ -23,11 +23,12 @@ tags:
|
|
| 23 |
在运行推理的同一个 Python 3.11/3.12 环境中安装并核对版本:
|
| 24 |
|
| 25 |
```bash
|
| 26 |
-
|
|
|
|
| 27 |
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 28 |
```
|
| 29 |
|
| 30 |
-
版本应为 `0.
|
| 31 |
|
| 32 |

|
| 33 |
|
|
@@ -74,7 +75,7 @@ I2_S GGUF + float32 指针头
|
|
| 74 |
|
| 75 |
## 推理示例
|
| 76 |
|
| 77 |
-
推荐使用 pip 包。Windows x64 且 CPU 支持 AVX2 时,bit-jev 0.
|
| 78 |
|
| 79 |
```python
|
| 80 |
from bit_jev.gguf import BitJev
|
|
|
|
| 23 |
在运行推理的同一个 Python 3.11/3.12 环境中安装并核对版本:
|
| 24 |
|
| 25 |
```bash
|
| 26 |
+
pip install bit-jev -i https://pypi.org/simple --upgrade
|
| 27 |
+
python -m bit_jev.demo
|
| 28 |
python -c "from importlib.metadata import version; import bit_jev; print(version('bit-jev'), bit_jev.__file__)"
|
| 29 |
```
|
| 30 |
|
| 31 |
+
版本应为 `0.13.10`,导入路径应指向当前环境的 `site-packages/bit_jev`。第二条命令会在本机打开与在线测试同源的 Choice、Noul、Score 页面;首次提交才下载约 1.19 GB 模型。需要从 ModelScope 直接下载时可加 `--source modelscope`,使用 Vulkan 可加 `--device gpu`,旧式单题 JSON 可加 `--once`。下方仍保留完整 Python API 示例。镜像版本滞后及环境混用的处理见[安装指南](https://github.com/Zeaulo/bit-jev/blob/main/docs/GGUF_PACKAGE.zh-CN.md)。
|
| 32 |
|
| 33 |

|
| 34 |
|
|
|
|
| 75 |
|
| 76 |
## 推理示例
|
| 77 |
|
| 78 |
+
推荐使用 pip 包。Windows x64 且 CPU 支持 AVX2 时,bit-jev 0.13.10 wheel 已携带 CPU 与 Vulkan GPU 原生 runner;首次加载会按需下载约 1.19 GB 的模型。使用 `device="cpu"` 或 `device="gpu"` 推理无需 Git、CMake、C++ 编译器或 Vulkan SDK;Vulkan GPU 需要显卡驱动提供 `vulkan-1.dll`。其他系统和 CUDA 后端按需从固定源码构建,需要 Git、CMake 3.28+ 与 C++17 编译器;CUDA 构建还需要 CUDA Toolkit。
|
| 79 |
|
| 80 |
```python
|
| 81 |
from bit_jev.gguf import BitJev
|
project-flow.en.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
project-flow.zh-CN.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|