


Release measured Decision 1.0 decoder
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +11 -0
- ATTRIBUTIONS.md +14 -0
- Dockerfile.runtime +12 -0
- EVALUATION.md +147 -0
- FIGURE-NOTICES.md +10 -0
- LICENSE +202 -0
- QWEN-LICENSE +202 -0
- README.md +118 -0
- RUNTIME.md +52 -0
- TIMING.md +164 -0
- USAGE.md +66 -0
- assets/architecture-atlas.pdf +3 -0
- assets/architecture.pdf +3 -0
- assets/architecture.png +3 -0
- assets/architecture.svg +160 -0
- assets/decision-capabilities.pdf +3 -0
- assets/decision-capabilities.png +3 -0
- assets/decision-capabilities.svg +0 -0
- assets/decision-family-header.png +3 -0
- assets/decision-mark.png +3 -0
- assets/decision-quality.pdf +0 -0
- assets/decision-quality.png +3 -0
- assets/decision-quality.svg +0 -0
- assets/readout.pdf +3 -0
- assets/readout.png +3 -0
- assets/readout.svg +92 -0
- backbone/config.json +83 -0
- backbone/model-00001-of-00003.safetensors +3 -0
- backbone/model-00002-of-00003.safetensors +3 -0
- backbone/model-00003-of-00003.safetensors +3 -0
- backbone/model.safetensors.index.json +434 -0
- bundle-manifest.json +173 -0
- chat_template.jinja +154 -0
- code/decision_api.py +112 -0
- code/decision_model.py +173 -0
- code/predict.py +43 -0
- decision_config.json +19 -0
- decision_head.safetensors +3 -0
- metrics/asset-hashes.json +17 -0
- metrics/quality-aggregate.json +0 -0
- metrics/timing-aggregate.json +0 -0
- model-card-example.json +69 -0
- pyproject.toml +19 -0
- release-manifest.json +328 -0
- runtime-build-provenance.json +65 -0
- runtime-fla-requirements.lock +4 -0
- runtime-provenance.json +172 -0
- runtime.json +23 -0
- src/decision/__init__.py +5 -0
- src/decision/example.py +61 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,14 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
assets/architecture-atlas.pdf filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
assets/architecture.pdf filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
assets/architecture.png filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
assets/decision-capabilities.pdf filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
assets/decision-capabilities.png filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
assets/decision-family-header.png filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
assets/decision-mark.png filter=lfs diff=lfs merge=lfs -text
|
| 43 |
+
assets/decision-quality.png filter=lfs diff=lfs merge=lfs -text
|
| 44 |
+
assets/readout.pdf filter=lfs diff=lfs merge=lfs -text
|
| 45 |
+
assets/readout.png filter=lfs diff=lfs merge=lfs -text
|
| 46 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
ATTRIBUTIONS.md
ADDED
|
@@ -0,0 +1,14 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Base and training-data attribution
|
| 2 |
+
|
| 3 |
+
The text backbone and tokenizer derive from Qwen3.5 post-trained models by Alibaba Cloud, under Apache License2.0. The unmodified upstream license is retained as QWEN-LICENSE (SHA256 bbedc3fda3305820b977265f01b8619d87570a6739de3a5582c3464840f1e57a). The vision tower and vocabulary-generation readout are not used by the decision forward pass. The tied token-embedding weights remain in the text backbone; omitting the vocabulary readout does not imply saving another independent embedding matrix. A shared candidate head and decision-specific training are research modifications.
|
| 4 |
+
|
| 5 |
+
- Qwen/Qwen3.5-2B, revision15852e8c16360a2fea060d615a32b45270f8a8fc: https://huggingface.co/Qwen/Qwen3.5-2B/tree/15852e8c16360a2fea060d615a32b45270f8a8fc
|
| 6 |
+
- Qwen/Qwen3.5-4B, revision851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a: https://huggingface.co/Qwen/Qwen3.5-4B/tree/851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a
|
| 7 |
+
- BANKING77 training data from PolyAI's task-specific-datasets repository, revision57ec275d8078af65b7731c2a98be812d844a6d6b, CC-BY4.0: https://github.com/PolyAI-LDN/task-specific-datasets/tree/57ec275d8078af65b7731c2a98be812d844a6d6b/banking_data
|
| 8 |
+
- CLINC150 training data from CLINC's oos-eval repository, revision828f8093932c8fe6ca7936c3d2e52903b1c523de, CC-BY3.0: https://github.com/clinc/oos-eval/tree/828f8093932c8fe6ca7936c3d2e52903b1c523de
|
| 9 |
+
|
| 10 |
+
Intent utterances retain their source labels; training converts them into varied decision prompts, options and arbitrary option keys. BANKING77 ten reserved labels and CLINC150 three reserved domains are excluded from custom training. Programmatically generated decision tasks are additional research data; objective labels are independently recomputed from inputs. Official Jev outputs are not used as training labels.
|
| 11 |
+
|
| 12 |
+
AG News and DBpedia-14 are used only in evaluation and excluded from custom training. No raw evaluation text is included in a model bundle. Exclusion from custom training does not establish absence from base-model pretraining.
|
| 13 |
+
|
| 14 |
+
Sol inherits 200 primary backbone updates, 100 decision-head warmup updates, 800 bucket-mixed Stage2 updates and 200 Stage3 updates. Nox inherits 748 primary backbone updates, 100 decision-head warmup updates, 200 Stage2 updates and 800 Stage3 updates. Head-only warmup does not update the backbone. These are different training histories, not a controlled size-only experiment. Discarded training branches are not part of either released checkpoint. Stage3 contains 47,000 newly generated training rows and 22,000 replay rows; a separate 1,000 generated rows form internal validation.
|
Dockerfile.runtime
ADDED
|
@@ -0,0 +1,12 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Public base verified by manifest digest and critical PyTorch file hashes.
|
| 2 |
+
# CPU build/import validation is separate from model GPU qualification; see RUNTIME.md.
|
| 3 |
+
FROM vllm/vllm-openai-rocm@sha256:1fd21abe66455b4df5a2e83629e97cdcc9d58913b16052d8118b92b239792339
|
| 4 |
+
COPY runtime-fla-requirements.lock /tmp/runtime-fla-requirements.lock
|
| 5 |
+
RUN python3 -m pip install --no-cache-dir --no-index --no-deps --require-hashes --target /opt/decision-fla -r /tmp/runtime-fla-requirements.lock
|
| 6 |
+
ENV PYTHONPATH=/opt/decision-fla
|
| 7 |
+
COPY pyproject.toml /opt/decision-wrapper/pyproject.toml
|
| 8 |
+
COPY src/ /opt/decision-wrapper/src/
|
| 9 |
+
RUN python3 -m pip install --no-cache-dir --no-deps --no-build-isolation /opt/decision-wrapper
|
| 10 |
+
WORKDIR /model
|
| 11 |
+
ENTRYPOINT []
|
| 12 |
+
CMD ["/bin/bash"]
|
EVALUATION.md
ADDED
|
@@ -0,0 +1,147 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Decision 1.0 decoder evaluation
|
| 2 |
+
|
| 3 |
+
Measured on 21 September 2026. These results describe the first released Sol and Nox checkpoints, compared on the same frozen requests with official Jev, released open decision models and their untuned Qwen parents. They are a bounded evaluation, not proof of universal superiority or recovery of Jev's internal architecture.
|
| 4 |
+
|
| 5 |
+
## What the main score means
|
| 6 |
+
|
| 7 |
+
The main score is **native decision accuracy, averaged equally across ten task families**. The core has **880 questions, 432 semantic groups, English and Chinese, and 2–14 candidates**: 752 Choice, 64 Noul and 64 Score questions. It combines 640 constructed decision tasks, 128 official AG News test examples and 112 official DBpedia-14 test examples. The natural-intent slice has only 16 underlying groups and 64 views. No benchmark-specific adaptation was performed on these evaluation rows.
|
| 8 |
+
|
| 9 |
+
The same core examples and family weights apply to every model. Choice and Score use the selected/max-probability category; Noul uses P(true) ≥ 0.5. Score accuracy is ordinal-bin accuracy, not accuracy of a rounded expected scalar. The Choice/Noul/Score columns pool examples of each type and therefore do not average to the ten-family overall score. Missing or invalid decisions count as incorrect. Different accepted subsets are not silently substituted.
|
| 10 |
+
|
| 11 |
+
Confidence intervals use 10,000 percentile bootstrap resamples of semantic groups **within each family**, followed by the equal-weight family mean. Related translations and option variants remain grouped. Paired differences reuse the same sampled groups for both models. These are not simultaneous confidence intervals for every family.
|
| 12 |
+
|
| 13 |
+
| Model | Overall accuracy ↑ | 95% CI | Choice ↑ | Noul ↑ | Score ↑ |
|
| 14 |
+
| --- | ---: | ---: | ---: | ---: | ---: |
|
| 15 |
+
| Nox · 4B | 79.32 | 75.74–82.98 | 76.06 | 90.62 | 87.50 |
|
| 16 |
+
| Jev 1.13.0 | 79.10 | 76.17–82.05 | 72.61 | 100.00 | 100.00 |
|
| 17 |
+
| Qwen3.5 · 4B, untuned | 69.89 | 66.23–73.40 | 68.48 | 62.50 | 90.62 |
|
| 18 |
+
| Sol · 2B | 66.25 | 61.94–70.64 | 71.41 | 42.19 | 43.75 |
|
| 19 |
+
| Decider · 2B | 64.01 | 59.88–68.11 | 60.77 | 71.88 | 84.38 |
|
| 20 |
+
| Qwen3.5 · 2B, untuned | 57.12 | 53.45–60.65 | 56.38 | 37.50 | 81.25 |
|
| 21 |
+
| Laya · EN/ML routed | 57.01 | 53.16–60.88 | 64.10 | 43.75 | 18.75 |
|
| 22 |
+
| Laya · English | 56.54 | 52.60–60.49 | 63.70 | 43.75 | 18.75 |
|
| 23 |
+
| Laya · Multilingual | 47.25 | 43.44–51.12 | 53.72 | 39.06 | 12.50 |
|
| 24 |
+
|
| 25 |
+
All entries are accuracy percentages. “Untuned” means the exact **post-trained Qwen3.5 parent before our decision adaptation**, not a Qwen `-Base` checkpoint. Its frozen adapter scores A–Z with the pretrained LM head, with thinking disabled; no random classifier is used. The tested adapter supports at most 26 candidates. These are adapter-specific zero-additional-training results, not an upper bound on everything the parent language model can do. Comparing the release with this baseline measures the whole adaptation package (new head plus supervised backbone updates), not a pure head-only or backbone-only ablation.
|
| 26 |
+
|
| 27 |
+
Laya routed uses its published input-based English/multilingual routing policy, fixed before scoring, with automatic task detection disabled. The two individual Laya checkpoints are shown separately. The official Jev API reported version 1.13.0; hosted internals and server-side truncation are not observable. We do not infer an encoder/decoder attention mask from response behavior.
|
| 28 |
+
|
| 29 |
+
## Every family
|
| 30 |
+
|
| 31 |
+
| Family | Questions | Nox · 4B | Jev 1.13.0 | Qwen3.5 · 4B, untuned | Sol · 2B | Decider · 2B | Qwen3.5 · 2B, untuned | Laya · EN/ML routed |
|
| 32 |
+
| --- | ---: | ---: | ---: | ---: | ---: | ---: | ---: | ---: |
|
| 33 |
+
| Natural intents | 64 | 100.00 | 100.00 | 100.00 | 100.00 | 100.00 | 96.88 | 85.94 |
|
| 34 |
+
| AG News | 128 | 82.03 | 85.16 | 84.38 | 82.81 | 86.72 | 80.47 | 91.41 |
|
| 35 |
+
| DBpedia-14 | 112 | 95.54 | 96.43 | 97.32 | 93.75 | 98.21 | 92.86 | 83.93 |
|
| 36 |
+
| Boolean constraints | 64 | 90.62 | 100.00 | 62.50 | 42.19 | 71.88 | 37.50 | 43.75 |
|
| 37 |
+
| Ordered rubrics | 64 | 87.50 | 100.00 | 90.62 | 43.75 | 84.38 | 81.25 | 18.75 |
|
| 38 |
+
| Relational composition | 96 | 41.67 | 56.25 | 51.04 | 45.83 | 54.17 | 48.96 | 25.00 |
|
| 39 |
+
| Scoped evidence | 96 | 72.92 | 89.58 | 51.04 | 54.17 | 47.92 | 36.46 | 37.50 |
|
| 40 |
+
| State tracking | 96 | 35.42 | 33.33 | 28.12 | 18.75 | 29.17 | 25.00 | 23.96 |
|
| 41 |
+
| Unknown rejection | 64 | 87.50 | 100.00 | 60.94 | 81.25 | 59.38 | 62.50 | 64.06 |
|
| 42 |
+
| Option carriers | 96 | 100.00 | 30.21 | 72.92 | 100.00 | 8.33 | 9.38 | 95.83 |
|
| 43 |
+
|
| 44 |
+
The option-carrier family deliberately stresses binding evidence and arbitrary candidate representations. Its weight is one tenth of the headline score; this is **not** an estimate of its frequency in user workloads. AG News and DBpedia-14 favor several reference models. Relational composition and state tracking remain difficult for both releases. A high aggregate must not be read as an all-family win. The unknown-rejection slice tests whether a known value is inside or outside the supplied menu; it does not establish recognition of unknown real-world facts.
|
| 45 |
+
|
| 46 |
+
## Paired differences and release scope
|
| 47 |
+
|
| 48 |
+
| Candidate | Reference | Difference (pp) | Paired 95% CI (pp) |
|
| 49 |
+
| --- | ---: | ---: | ---: |
|
| 50 |
+
| Nox · 4B | Jev 1.13.0 | +0.22 | -3.58 to +4.05 |
|
| 51 |
+
| Nox · 4B | Laya · EN/ML routed | +22.31 | +17.50 to +27.08 |
|
| 52 |
+
| Nox · 4B | Decider · 2B | +15.31 | +11.28 to +19.51 |
|
| 53 |
+
| Nox · 4B | Qwen3.5 · 4B, untuned | +9.43 | +4.82 to +14.15 |
|
| 54 |
+
| Sol · 2B | Jev 1.13.0 | -12.85 | -17.71 to -8.00 |
|
| 55 |
+
| Sol · 2B | Laya · EN/ML routed | +9.24 | +4.20 to +14.22 |
|
| 56 |
+
| Sol · 2B | Decider · 2B | +2.24 | -1.83 to +6.39 |
|
| 57 |
+
| Sol · 2B | Qwen3.5 · 2B, untuned | +9.13 | +4.45 to +13.90 |
|
| 58 |
+
|
| 59 |
+
Nox has a higher average than Laya and Decider on this panel. Its mean is close to Jev's, but the interval does not establish equivalence and its calibration and several task families remain behind. Sol's point estimate exceeds Laya and Decider, but its paired interval against Decider includes zero; it is materially below Jev overall.
|
| 60 |
+
|
| 61 |
+
The original preregistered v2 policy required stricter per-family/calibration conditions; **neither candidate passed that policy**. After seeing these results, the project owner authorized first releases based on average superiority over Laya and Decider, independently for each model. This publication decision did not change the examples, weights, candidate selection, temperatures or reported measurements. The original failed gates remain in [the aggregate record](metrics/quality-aggregate.json). These now-observed panels become regression tests; later generalization claims require new independent evaluations.
|
| 62 |
+
|
| 63 |
+
## Probabilities and typed decisions
|
| 64 |
+
|
| 65 |
+
Brier below is the equal-family mean of the multiclass squared-probability error (sum across classes, not divided by K). NLL uses natural logarithms without epsilon clipping; a returned zero probability for the correct class yields infinity under the reported-distribution metric. For hosted APIs with rounded outputs, this does not prove that the unobserved internal probability is exactly zero. RPS averages squared cumulative errors over K−1 ordinal boundaries. Native Score MAE divides the absolute expected-index error by K−1. All core targets are hard labels, so this release does not establish quality on soft business targets.
|
| 66 |
+
|
| 67 |
+
| Model | Macro Brier ↓ | Choice NLL ↓ | False recall ↑ | True recall ↑ | Noul balanced ↑ | Score RPS ↓ | Score MAE ↓ |
|
| 68 |
+
| --- | ---: | ---: | ---: | ---: | ---: | ---: | ---: |
|
| 69 |
+
| Nox · 4B | 0.3577 | 2.0021 | 85.00 | 100.00 | 92.50 | 0.0291 | 0.0302 |
|
| 70 |
+
| Jev 1.13.0 | 0.2481 | infinity | 100.00 | 100.00 | 100.00 | 0.0000 | 0.0000 |
|
| 71 |
+
| Qwen3.5 · 4B, untuned | 0.4271 | 0.8927 | 40.00 | 100.00 | 70.00 | 0.0214 | 0.0484 |
|
| 72 |
+
| Sol · 2B | 0.5187 | 1.4094 | 10.00 | 95.83 | 52.92 | 0.1946 | 0.2638 |
|
| 73 |
+
| Decider · 2B | 0.4425 | 0.8561 | 55.00 | 100.00 | 77.50 | 0.0730 | 0.1744 |
|
| 74 |
+
| Qwen3.5 · 2B, untuned | 0.5724 | 1.1525 | 0.00 | 100.00 | 50.00 | 0.0560 | 0.1033 |
|
| 75 |
+
| Laya · EN/ML routed | 0.5710 | infinity | 20.00 | 83.33 | 51.67 | 0.2003 | 0.3122 |
|
| 76 |
+
| Laya · English | 0.5708 | infinity | 20.00 | 83.33 | 51.67 | 0.2003 | 0.3122 |
|
| 77 |
+
| Laya · Multilingual | 0.6314 | 1.0724 | 7.50 | 91.67 | 49.58 | 0.2817 | 0.4104 |
|
| 78 |
+
|
| 79 |
+
Noul has 40 false and 24 true cases. In particular, Sol's false recall is only 10% here: a syntactically valid yes/no answer is not a correctness guarantee. Do not use its raw confidence as an automatic escalation threshold without application-specific validation.
|
| 80 |
+
|
| 81 |
+
Both checkpoints keep the **single temperature fitted on development data before final evaluation**: Sol T=0.7033302993804421; Nox T=0.5332910931023557. On this final panel, the shipped temperatures worsen family-macro Brier relative to raw T=1 (Sol 0.5187 vs 0.4857; Nox 0.3577 vs 0.3253). They were not switched after seeing final results. Jev's corresponding Brier is 0.2481. The aggregate preserves raw and shipped proper scores separately. “Confidence” in the public Choice/Score schema is (K·max(p)−1)/(K−1), a concentration statistic, not a proven calibrated probability of correctness or a recovered Jev formula.
|
| 82 |
+
|
| 83 |
+
An analytic uniform-probability control and its fixed-tie versus expected-random accuracy are included in the aggregate. A global training-class prior is not meaningful for request-specific arbitrary candidate IDs and is omitted with that reason.
|
| 84 |
+
|
| 85 |
+
## Input support and separate native probe
|
| 86 |
+
|
| 87 |
+
Core probabilities are valid on all 880 questions for every primary model. Sol, Nox, Decider and the untuned Qwen adapters reported no core truncations. Each Laya variant reported truncation on 112 core questions; this is a comparison of the released interfaces on identical requests, not a claim that every implementation consumed identical token content. Jev does not expose enough information to verify server-side truncation.
|
| 88 |
+
|
| 89 |
+
The independent native probe has **68 requests containing 220 questions**. It includes structured inputs, multiple questions, lengths and candidate counts up to 255. It is reported separately and does not contribute to the main ranking. Validity and semantic correctness are different measurements; unsupported requests remain in the all-requested denominator.
|
| 90 |
+
|
| 91 |
+
| Model | Accepted requests / 68 | Valid questions / 220 | Correct questions / 220 |
|
| 92 |
+
| --- | ---: | ---: | ---: |
|
| 93 |
+
| Nox · 4B | 68 | 220 | 162 |
|
| 94 |
+
| Jev 1.13.0 | 68 | 220 | 203 |
|
| 95 |
+
| Qwen3.5 · 4B, untuned | 44 | 196 | 112 |
|
| 96 |
+
| Sol · 2B | 68 | 220 | 116 |
|
| 97 |
+
| Decider · 2B | 68 | 220 | 111 |
|
| 98 |
+
| Qwen3.5 · 2B, untuned | 44 | 196 | 86 |
|
| 99 |
+
| Laya · EN/ML routed | 56 | 208 | 88 |
|
| 100 |
+
| Laya · English | 56 | 208 | 88 |
|
| 101 |
+
| Laya · Multilingual | 62 | 214 | 58 |
|
| 102 |
+
|
| 103 |
+
Sol and Nox both accepted all questions without truncation. Each scored 23/42 on the large-candidate probe and 9/9 on the length probe. Nox scored 162/220 and Sol 116/220 overall, versus Jev's 203/220. This is a substantial remaining native-capability gap despite Nox's similar core macro accuracy. The untuned Qwen adapter rejected candidate sets beyond A–Z explicitly. Laya's accepted subsets differ and are not interchangeable paired comparisons.
|
| 104 |
+
|
| 105 |
+
The Decision engine supports Choice 2–255, Noul false/true, and Score 2–10 ordered descriptions. Score returns an expected **index**; arbitrary supplied numeric values are not implemented in this release. Each complete question—including state, instructions, all candidates and special tokens—must fit 16,384 tokens. Overflow rejects the complete call before inference; it is never silently truncated. This is a verified input budget, not a claim of uniformly strong reasoning across the full context. Questions execute independently in batches of eight with no cross-question state-prefix cache.
|
| 106 |
+
|
| 107 |
+
## Additional open references
|
| 108 |
+
|
| 109 |
+
These models used the same core and the matched FLA runtime where relevant. They are additional measured references, not additional release gates or evidence of significant wins against every model.
|
| 110 |
+
|
| 111 |
+
| Open reference | Macro accuracy (%) | 95% CI |
|
| 112 |
+
| --- | ---: | ---: |
|
| 113 |
+
| kev-0.8b | 60.70 | 56.88–64.40 |
|
| 114 |
+
| kev-4b | 71.28 | 67.41–75.10 |
|
| 115 |
+
| kev-9b | 76.36 | 72.94–79.81 |
|
| 116 |
+
| nimble-9b | 78.85 | 75.65–82.02 |
|
| 117 |
+
| llm2jev-2b | 62.60 | 59.08–66.08 |
|
| 118 |
+
| llm2jev-4b | 69.91 | 66.36–73.41 |
|
| 119 |
+
|
| 120 |
+
## Training, selection and provenance
|
| 121 |
+
|
| 122 |
+
The text-only backbones are Qwen/Qwen3.5-2B at `15852e8c16360a2fea060d615a32b45270f8a8fc` and Qwen/Qwen3.5-4B at `851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a`. Both are post-trained parents. The shared candidate head is trained with the text backbone. Selected checkpoints were frozen before final scoring: Sol at Stage3 step 200 and Nox at Stage3 step 800, selected among the scheduled checkpoints using production batch-size-eight development accuracy. They have unequal inherited training histories; the comparison does not isolate model size as the sole cause of differences.
|
| 123 |
+
|
| 124 |
+
Stage3 uses 69,000 training rows: 47,000 new generated rows plus 22,000 replay rows; a separate 1,000 generated rows are internal validation. Training mixes programmatically verified decision tasks with licensed BANKING77 and CLINC150 training data, using varied instructions, structured views and candidate permutations. Reserved intent labels/domains are excluded from adaptation. AG News and DBpedia-14 are evaluation-only. The Stage3 overlap audit found no exact or token-Jaccard ≥0.5 matches against the final core; short overlaps with earlier development intent examples are a separate development limitation. Upstream pretraining exposure remains unknown. No official Jev predictions were used as training labels. Source licenses and exact training lineage are in [ATTRIBUTIONS.md](ATTRIBUTIONS.md).
|
| 125 |
+
|
| 126 |
+
The actual architecture and numerical inference source are shipped with each model. Standalone export/reload with network access disabled reproduced all 256 development logits bit-exactly; emitted probabilities differed by at most 2.384×10⁻⁷ and selected decisions did not change. Real packaged Choice/Noul/Score inference also passed in the publicly rebuildable ROCm runtime; see [RUNTIME.md](RUNTIME.md). That small runtime equivalence probe is distinct from a complete benchmark rerun.
|
| 127 |
+
|
| 128 |
+
The Laya checkpoint is `convaiinnovations/laya` at `1c5edc17a7acd8701df6fc341c0d179f1c62c982` (English root and multilingual subfolder). Its native router follows source commit `42626c348753fbb17572a813127df2278a1ec527`. Decider is `Mapika/decider-2b` at `b37f7e1ba3fbc9238004cf531fabbee2619973fd`; its released numerical interface is retained. Full aggregate metrics and immutable source/prediction fingerprints are in [metrics/quality-aggregate.json](metrics/quality-aggregate.json).
|
| 129 |
+
|
| 130 |
+
## Efficiency
|
| 131 |
+
|
| 132 |
+
The completed quiet benchmark uses one AMD gfx942 accelerator with 261824 MiB visible memory. It includes all six local primary models, independently randomized model order in three blocks, 30 repetitions per supported cell, and separate Choice and Noul/Score panels. All 36 quality/runtime identity checks match. The 114 complete-input cells provide 3,420 measured request times; truncated and unsupported inputs are explicit exclusions rather than short-input substitutions.
|
| 133 |
+
|
| 134 |
+
Latency includes rendering, tokenization, device transfers, model forward and answer assembly, but excludes loading, diagnostics, warmup, network and post-response shape checks. No other training/inference GPU process ran during measurement. CPU affinity and clocks were not locked, and telemetry counters on otherwise idle devices occasionally reported 1–3%; this is an empirical quiet request benchmark, not a noise-free hardware microbenchmark. After a transient process was caught by preflight before job 26, only the remaining jobs resumed; no timing job was repeated.
|
| 135 |
+
|
| 136 |
+
| Model | Actual tokens | p50 / p95 (ms) | Peak allocated GiB |
|
| 137 |
+
| --- | ---: | ---: | ---: |
|
| 138 |
+
| Nox · 4B | 309 | 27.37 / 28.95 | 8.06 |
|
| 139 |
+
| Qwen3.5 · 4B, untuned | 296 | 27.47 / 28.76 | 8.04 |
|
| 140 |
+
| Sol · 2B | 309 | 21.04 / 21.41 | 3.61 |
|
| 141 |
+
| Decider · 2B | 250 | 23.35 / 23.91 | 3.62 |
|
| 142 |
+
| Qwen3.5 · 2B, untuned | 296 | 20.51 / 20.71 | 3.60 |
|
| 143 |
+
| Laya · EN/ML routed | 228 | 11.54 / 12.21 | 3.56 |
|
| 144 |
+
|
| 145 |
+
This table uses the same short English state, one question and four options. Native token counts vary with the prompt/template. Laya uses its English branch. Sol is faster than Decider here, but Decider is faster on multiquestion Choice and K=255; neither Decision release establishes universal speed superiority. Nox trades higher quality on the measured panel for more memory and latency. Hosted Jev wall time includes service and network cost and is not included in this local timing comparison.
|
| 146 |
+
|
| 147 |
+
See [TIMING.md](TIMING.md) for every length/question-count/candidate-count/type cell, questions/s and peak-memory definitions, and [metrics/timing-aggregate.json](metrics/timing-aggregate.json) for machine-readable measurements and runtime pairing. The full request benchmark and the small publicly rebuilt runtime parity test are separate evidence.
|
FIGURE-NOTICES.md
ADDED
|
@@ -0,0 +1,10 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Figure provenance
|
| 2 |
+
|
| 3 |
+
The architecture figures describe the shipped Decision implementation. Backbone operator details were checked against the actual Qwen3.5 implementation in Transformers 5.17.0 and the pinned parent configurations. They do not claim to reveal Jev's unpublished architecture.
|
| 4 |
+
|
| 5 |
+
- [Qwen3.5-2B configuration](https://huggingface.co/Qwen/Qwen3.5-2B/blob/15852e8c16360a2fea060d615a32b45270f8a8fc/config.json)
|
| 6 |
+
- [Qwen3.5-4B configuration](https://huggingface.co/Qwen/Qwen3.5-4B/blob/851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a/config.json)
|
| 7 |
+
- [Transformers source and Apache 2.0 license](https://github.com/huggingface/transformers)
|
| 8 |
+
- [Decision family visual guide](https://gist.github.com/Xunzhuo/4020f574e3d38e5e5eae00063bdf9dce)
|
| 9 |
+
|
| 10 |
+
The rank and capability figures are generated from the same aggregate evidence linked in EVALUATION.md. The supplied Decision mark is included unchanged; chart backgrounds are white. SVG and PDF preserve the chart/architecture geometry and typography as vectors; the branding mark is a raster asset.
|
LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
Apache License
|
| 3 |
+
Version 2.0, January 2004
|
| 4 |
+
http://www.apache.org/licenses/
|
| 5 |
+
|
| 6 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 7 |
+
|
| 8 |
+
1. Definitions.
|
| 9 |
+
|
| 10 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 11 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 12 |
+
|
| 13 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 14 |
+
the copyright owner that is granting the License.
|
| 15 |
+
|
| 16 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 17 |
+
other entities that control, are controlled by, or are under common
|
| 18 |
+
control with that entity. For the purposes of this definition,
|
| 19 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 20 |
+
direction or management of such entity, whether by contract or
|
| 21 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 22 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 23 |
+
|
| 24 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 25 |
+
exercising permissions granted by this License.
|
| 26 |
+
|
| 27 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 28 |
+
including but not limited to software source code, documentation
|
| 29 |
+
source, and configuration files.
|
| 30 |
+
|
| 31 |
+
"Object" form shall mean any form resulting from mechanical
|
| 32 |
+
transformation or translation of a Source form, including but
|
| 33 |
+
not limited to compiled object code, generated documentation,
|
| 34 |
+
and conversions to other media types.
|
| 35 |
+
|
| 36 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 37 |
+
Object form, made available under the License, as indicated by a
|
| 38 |
+
copyright notice that is included in or attached to the work
|
| 39 |
+
(an example is provided in the Appendix below).
|
| 40 |
+
|
| 41 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 42 |
+
form, that is based on (or derived from) the Work and for which the
|
| 43 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 44 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 45 |
+
of this License, Derivative Works shall not include works that remain
|
| 46 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 47 |
+
the Work and Derivative Works thereof.
|
| 48 |
+
|
| 49 |
+
"Contribution" shall mean any work of authorship, including
|
| 50 |
+
the original version of the Work and any modifications or additions
|
| 51 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 52 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 53 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 54 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 55 |
+
means any form of electronic, verbal, or written communication sent
|
| 56 |
+
to the Licensor or its representatives, including but not limited to
|
| 57 |
+
communication on electronic mailing lists, source code control systems,
|
| 58 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 59 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 60 |
+
excluding communication that is conspicuously marked or otherwise
|
| 61 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 62 |
+
|
| 63 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 64 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 65 |
+
subsequently incorporated within the Work.
|
| 66 |
+
|
| 67 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 68 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 69 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 70 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 71 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 72 |
+
Work and such Derivative Works in Source or Object form.
|
| 73 |
+
|
| 74 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 75 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 76 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 77 |
+
(except as stated in this section) patent license to make, have made,
|
| 78 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 79 |
+
where such license applies only to those patent claims licensable
|
| 80 |
+
by such Contributor that are necessarily infringed by their
|
| 81 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 82 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 83 |
+
institute patent litigation against any entity (including a
|
| 84 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 85 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 86 |
+
or contributory patent infringement, then any patent licenses
|
| 87 |
+
granted to You under this License for that Work shall terminate
|
| 88 |
+
as of the date such litigation is filed.
|
| 89 |
+
|
| 90 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 91 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 92 |
+
modifications, and in Source or Object form, provided that You
|
| 93 |
+
meet the following conditions:
|
| 94 |
+
|
| 95 |
+
(a) You must give any other recipients of the Work or
|
| 96 |
+
Derivative Works a copy of this License; and
|
| 97 |
+
|
| 98 |
+
(b) You must cause any modified files to carry prominent notices
|
| 99 |
+
stating that You changed the files; and
|
| 100 |
+
|
| 101 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 102 |
+
that You distribute, all copyright, patent, trademark, and
|
| 103 |
+
attribution notices from the Source form of the Work,
|
| 104 |
+
excluding those notices that do not pertain to any part of
|
| 105 |
+
the Derivative Works; and
|
| 106 |
+
|
| 107 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 108 |
+
distribution, then any Derivative Works that You distribute must
|
| 109 |
+
include a readable copy of the attribution notices contained
|
| 110 |
+
within such NOTICE file, excluding those notices that do not
|
| 111 |
+
pertain to any part of the Derivative Works, in at least one
|
| 112 |
+
of the following places: within a NOTICE text file distributed
|
| 113 |
+
as part of the Derivative Works; within the Source form or
|
| 114 |
+
documentation, if provided along with the Derivative Works; or,
|
| 115 |
+
within a display generated by the Derivative Works, if and
|
| 116 |
+
wherever such third-party notices normally appear. The contents
|
| 117 |
+
of the NOTICE file are for informational purposes only and
|
| 118 |
+
do not modify the License. You may add Your own attribution
|
| 119 |
+
notices within Derivative Works that You distribute, alongside
|
| 120 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 121 |
+
that such additional attribution notices cannot be construed
|
| 122 |
+
as modifying the License.
|
| 123 |
+
|
| 124 |
+
You may add Your own copyright statement to Your modifications and
|
| 125 |
+
may provide additional or different license terms and conditions
|
| 126 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 127 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 128 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 129 |
+
the conditions stated in this License.
|
| 130 |
+
|
| 131 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 132 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 133 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 134 |
+
this License, without any additional terms or conditions.
|
| 135 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 136 |
+
the terms of any separate license agreement you may have executed
|
| 137 |
+
with Licensor regarding such Contributions.
|
| 138 |
+
|
| 139 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 140 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 141 |
+
except as required for reasonable and customary use in describing the
|
| 142 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 143 |
+
|
| 144 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 145 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 146 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 147 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 148 |
+
implied, including, without limitation, any warranties or conditions
|
| 149 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 150 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 151 |
+
appropriateness of using or redistributing the Work and assume any
|
| 152 |
+
risks associated with Your exercise of permissions under this License.
|
| 153 |
+
|
| 154 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 155 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 156 |
+
unless required by applicable law (such as deliberate and grossly
|
| 157 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 158 |
+
liable to You for damages, including any direct, indirect, special,
|
| 159 |
+
incidental, or consequential damages of any character arising as a
|
| 160 |
+
result of this License or out of the use or inability to use the
|
| 161 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 162 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 163 |
+
other commercial damages or losses), even if such Contributor
|
| 164 |
+
has been advised of the possibility of such damages.
|
| 165 |
+
|
| 166 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 167 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 168 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 169 |
+
or other liability obligations and/or rights consistent with this
|
| 170 |
+
License. However, in accepting such obligations, You may act only
|
| 171 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 172 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 173 |
+
defend, and hold each Contributor harmless for any liability
|
| 174 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 175 |
+
of your accepting any such warranty or additional liability.
|
| 176 |
+
|
| 177 |
+
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright 2026 Alibaba Cloud
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
QWEN-LICENSE
ADDED
|
@@ -0,0 +1,202 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
|
| 2 |
+
Apache License
|
| 3 |
+
Version 2.0, January 2004
|
| 4 |
+
http://www.apache.org/licenses/
|
| 5 |
+
|
| 6 |
+
TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION
|
| 7 |
+
|
| 8 |
+
1. Definitions.
|
| 9 |
+
|
| 10 |
+
"License" shall mean the terms and conditions for use, reproduction,
|
| 11 |
+
and distribution as defined by Sections 1 through 9 of this document.
|
| 12 |
+
|
| 13 |
+
"Licensor" shall mean the copyright owner or entity authorized by
|
| 14 |
+
the copyright owner that is granting the License.
|
| 15 |
+
|
| 16 |
+
"Legal Entity" shall mean the union of the acting entity and all
|
| 17 |
+
other entities that control, are controlled by, or are under common
|
| 18 |
+
control with that entity. For the purposes of this definition,
|
| 19 |
+
"control" means (i) the power, direct or indirect, to cause the
|
| 20 |
+
direction or management of such entity, whether by contract or
|
| 21 |
+
otherwise, or (ii) ownership of fifty percent (50%) or more of the
|
| 22 |
+
outstanding shares, or (iii) beneficial ownership of such entity.
|
| 23 |
+
|
| 24 |
+
"You" (or "Your") shall mean an individual or Legal Entity
|
| 25 |
+
exercising permissions granted by this License.
|
| 26 |
+
|
| 27 |
+
"Source" form shall mean the preferred form for making modifications,
|
| 28 |
+
including but not limited to software source code, documentation
|
| 29 |
+
source, and configuration files.
|
| 30 |
+
|
| 31 |
+
"Object" form shall mean any form resulting from mechanical
|
| 32 |
+
transformation or translation of a Source form, including but
|
| 33 |
+
not limited to compiled object code, generated documentation,
|
| 34 |
+
and conversions to other media types.
|
| 35 |
+
|
| 36 |
+
"Work" shall mean the work of authorship, whether in Source or
|
| 37 |
+
Object form, made available under the License, as indicated by a
|
| 38 |
+
copyright notice that is included in or attached to the work
|
| 39 |
+
(an example is provided in the Appendix below).
|
| 40 |
+
|
| 41 |
+
"Derivative Works" shall mean any work, whether in Source or Object
|
| 42 |
+
form, that is based on (or derived from) the Work and for which the
|
| 43 |
+
editorial revisions, annotations, elaborations, or other modifications
|
| 44 |
+
represent, as a whole, an original work of authorship. For the purposes
|
| 45 |
+
of this License, Derivative Works shall not include works that remain
|
| 46 |
+
separable from, or merely link (or bind by name) to the interfaces of,
|
| 47 |
+
the Work and Derivative Works thereof.
|
| 48 |
+
|
| 49 |
+
"Contribution" shall mean any work of authorship, including
|
| 50 |
+
the original version of the Work and any modifications or additions
|
| 51 |
+
to that Work or Derivative Works thereof, that is intentionally
|
| 52 |
+
submitted to Licensor for inclusion in the Work by the copyright owner
|
| 53 |
+
or by an individual or Legal Entity authorized to submit on behalf of
|
| 54 |
+
the copyright owner. For the purposes of this definition, "submitted"
|
| 55 |
+
means any form of electronic, verbal, or written communication sent
|
| 56 |
+
to the Licensor or its representatives, including but not limited to
|
| 57 |
+
communication on electronic mailing lists, source code control systems,
|
| 58 |
+
and issue tracking systems that are managed by, or on behalf of, the
|
| 59 |
+
Licensor for the purpose of discussing and improving the Work, but
|
| 60 |
+
excluding communication that is conspicuously marked or otherwise
|
| 61 |
+
designated in writing by the copyright owner as "Not a Contribution."
|
| 62 |
+
|
| 63 |
+
"Contributor" shall mean Licensor and any individual or Legal Entity
|
| 64 |
+
on behalf of whom a Contribution has been received by Licensor and
|
| 65 |
+
subsequently incorporated within the Work.
|
| 66 |
+
|
| 67 |
+
2. Grant of Copyright License. Subject to the terms and conditions of
|
| 68 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 69 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 70 |
+
copyright license to reproduce, prepare Derivative Works of,
|
| 71 |
+
publicly display, publicly perform, sublicense, and distribute the
|
| 72 |
+
Work and such Derivative Works in Source or Object form.
|
| 73 |
+
|
| 74 |
+
3. Grant of Patent License. Subject to the terms and conditions of
|
| 75 |
+
this License, each Contributor hereby grants to You a perpetual,
|
| 76 |
+
worldwide, non-exclusive, no-charge, royalty-free, irrevocable
|
| 77 |
+
(except as stated in this section) patent license to make, have made,
|
| 78 |
+
use, offer to sell, sell, import, and otherwise transfer the Work,
|
| 79 |
+
where such license applies only to those patent claims licensable
|
| 80 |
+
by such Contributor that are necessarily infringed by their
|
| 81 |
+
Contribution(s) alone or by combination of their Contribution(s)
|
| 82 |
+
with the Work to which such Contribution(s) was submitted. If You
|
| 83 |
+
institute patent litigation against any entity (including a
|
| 84 |
+
cross-claim or counterclaim in a lawsuit) alleging that the Work
|
| 85 |
+
or a Contribution incorporated within the Work constitutes direct
|
| 86 |
+
or contributory patent infringement, then any patent licenses
|
| 87 |
+
granted to You under this License for that Work shall terminate
|
| 88 |
+
as of the date such litigation is filed.
|
| 89 |
+
|
| 90 |
+
4. Redistribution. You may reproduce and distribute copies of the
|
| 91 |
+
Work or Derivative Works thereof in any medium, with or without
|
| 92 |
+
modifications, and in Source or Object form, provided that You
|
| 93 |
+
meet the following conditions:
|
| 94 |
+
|
| 95 |
+
(a) You must give any other recipients of the Work or
|
| 96 |
+
Derivative Works a copy of this License; and
|
| 97 |
+
|
| 98 |
+
(b) You must cause any modified files to carry prominent notices
|
| 99 |
+
stating that You changed the files; and
|
| 100 |
+
|
| 101 |
+
(c) You must retain, in the Source form of any Derivative Works
|
| 102 |
+
that You distribute, all copyright, patent, trademark, and
|
| 103 |
+
attribution notices from the Source form of the Work,
|
| 104 |
+
excluding those notices that do not pertain to any part of
|
| 105 |
+
the Derivative Works; and
|
| 106 |
+
|
| 107 |
+
(d) If the Work includes a "NOTICE" text file as part of its
|
| 108 |
+
distribution, then any Derivative Works that You distribute must
|
| 109 |
+
include a readable copy of the attribution notices contained
|
| 110 |
+
within such NOTICE file, excluding those notices that do not
|
| 111 |
+
pertain to any part of the Derivative Works, in at least one
|
| 112 |
+
of the following places: within a NOTICE text file distributed
|
| 113 |
+
as part of the Derivative Works; within the Source form or
|
| 114 |
+
documentation, if provided along with the Derivative Works; or,
|
| 115 |
+
within a display generated by the Derivative Works, if and
|
| 116 |
+
wherever such third-party notices normally appear. The contents
|
| 117 |
+
of the NOTICE file are for informational purposes only and
|
| 118 |
+
do not modify the License. You may add Your own attribution
|
| 119 |
+
notices within Derivative Works that You distribute, alongside
|
| 120 |
+
or as an addendum to the NOTICE text from the Work, provided
|
| 121 |
+
that such additional attribution notices cannot be construed
|
| 122 |
+
as modifying the License.
|
| 123 |
+
|
| 124 |
+
You may add Your own copyright statement to Your modifications and
|
| 125 |
+
may provide additional or different license terms and conditions
|
| 126 |
+
for use, reproduction, or distribution of Your modifications, or
|
| 127 |
+
for any such Derivative Works as a whole, provided Your use,
|
| 128 |
+
reproduction, and distribution of the Work otherwise complies with
|
| 129 |
+
the conditions stated in this License.
|
| 130 |
+
|
| 131 |
+
5. Submission of Contributions. Unless You explicitly state otherwise,
|
| 132 |
+
any Contribution intentionally submitted for inclusion in the Work
|
| 133 |
+
by You to the Licensor shall be under the terms and conditions of
|
| 134 |
+
this License, without any additional terms or conditions.
|
| 135 |
+
Notwithstanding the above, nothing herein shall supersede or modify
|
| 136 |
+
the terms of any separate license agreement you may have executed
|
| 137 |
+
with Licensor regarding such Contributions.
|
| 138 |
+
|
| 139 |
+
6. Trademarks. This License does not grant permission to use the trade
|
| 140 |
+
names, trademarks, service marks, or product names of the Licensor,
|
| 141 |
+
except as required for reasonable and customary use in describing the
|
| 142 |
+
origin of the Work and reproducing the content of the NOTICE file.
|
| 143 |
+
|
| 144 |
+
7. Disclaimer of Warranty. Unless required by applicable law or
|
| 145 |
+
agreed to in writing, Licensor provides the Work (and each
|
| 146 |
+
Contributor provides its Contributions) on an "AS IS" BASIS,
|
| 147 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or
|
| 148 |
+
implied, including, without limitation, any warranties or conditions
|
| 149 |
+
of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A
|
| 150 |
+
PARTICULAR PURPOSE. You are solely responsible for determining the
|
| 151 |
+
appropriateness of using or redistributing the Work and assume any
|
| 152 |
+
risks associated with Your exercise of permissions under this License.
|
| 153 |
+
|
| 154 |
+
8. Limitation of Liability. In no event and under no legal theory,
|
| 155 |
+
whether in tort (including negligence), contract, or otherwise,
|
| 156 |
+
unless required by applicable law (such as deliberate and grossly
|
| 157 |
+
negligent acts) or agreed to in writing, shall any Contributor be
|
| 158 |
+
liable to You for damages, including any direct, indirect, special,
|
| 159 |
+
incidental, or consequential damages of any character arising as a
|
| 160 |
+
result of this License or out of the use or inability to use the
|
| 161 |
+
Work (including but not limited to damages for loss of goodwill,
|
| 162 |
+
work stoppage, computer failure or malfunction, or any and all
|
| 163 |
+
other commercial damages or losses), even if such Contributor
|
| 164 |
+
has been advised of the possibility of such damages.
|
| 165 |
+
|
| 166 |
+
9. Accepting Warranty or Additional Liability. While redistributing
|
| 167 |
+
the Work or Derivative Works thereof, You may choose to offer,
|
| 168 |
+
and charge a fee for, acceptance of support, warranty, indemnity,
|
| 169 |
+
or other liability obligations and/or rights consistent with this
|
| 170 |
+
License. However, in accepting such obligations, You may act only
|
| 171 |
+
on Your own behalf and on Your sole responsibility, not on behalf
|
| 172 |
+
of any other Contributor, and only if You agree to indemnify,
|
| 173 |
+
defend, and hold each Contributor harmless for any liability
|
| 174 |
+
incurred by, or claims asserted against, such Contributor by reason
|
| 175 |
+
of your accepting any such warranty or additional liability.
|
| 176 |
+
|
| 177 |
+
END OF TERMS AND CONDITIONS
|
| 178 |
+
|
| 179 |
+
APPENDIX: How to apply the Apache License to your work.
|
| 180 |
+
|
| 181 |
+
To apply the Apache License to your work, attach the following
|
| 182 |
+
boilerplate notice, with the fields enclosed by brackets "[]"
|
| 183 |
+
replaced with your own identifying information. (Don't include
|
| 184 |
+
the brackets!) The text should be enclosed in the appropriate
|
| 185 |
+
comment syntax for the file format. We also recommend that a
|
| 186 |
+
file or class name and description of purpose be included on the
|
| 187 |
+
same "printed page" as the copyright notice for easier
|
| 188 |
+
identification within third-party archives.
|
| 189 |
+
|
| 190 |
+
Copyright 2026 Alibaba Cloud
|
| 191 |
+
|
| 192 |
+
Licensed under the Apache License, Version 2.0 (the "License");
|
| 193 |
+
you may not use this file except in compliance with the License.
|
| 194 |
+
You may obtain a copy of the License at
|
| 195 |
+
|
| 196 |
+
http://www.apache.org/licenses/LICENSE-2.0
|
| 197 |
+
|
| 198 |
+
Unless required by applicable law or agreed to in writing, software
|
| 199 |
+
distributed under the License is distributed on an "AS IS" BASIS,
|
| 200 |
+
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 201 |
+
See the License for the specific language governing permissions and
|
| 202 |
+
limitations under the License.
|
README.md
ADDED
|
@@ -0,0 +1,118 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
license: apache-2.0
|
| 3 |
+
language:
|
| 4 |
+
- en
|
| 5 |
+
- zh
|
| 6 |
+
base_model: Qwen/Qwen3.5-4B
|
| 7 |
+
base_model_relation: finetune
|
| 8 |
+
tags:
|
| 9 |
+
- decision-model
|
| 10 |
+
- classification
|
| 11 |
+
- qwen3_5
|
| 12 |
+
- custom-code
|
| 13 |
+
- pytorch
|
| 14 |
+
- rocm
|
| 15 |
+
- choice
|
| 16 |
+
- noul
|
| 17 |
+
- scoring
|
| 18 |
+
datasets:
|
| 19 |
+
- PolyAI/banking77
|
| 20 |
+
- clinc/clinc_oos
|
| 21 |
+
---
|
| 22 |
+
|
| 23 |
+

|
| 24 |
+
|
| 25 |
+
# Decision-1.0-Nox
|
| 26 |
+
|
| 27 |
+
**Your move. State in. Decisions out.**
|
| 28 |
+
|
| 29 |
+
**A capable decoder for runtime-defined decisions.** Nox turns your state and questions into choices, yes/no judgments and rubric scores in one numerical forward pass per question.
|
| 30 |
+
|
| 31 |
+
**4.208B parameters · 16,384-token complete-question budget · English / Chinese evaluated · Apache 2.0**
|
| 32 |
+
|
| 33 |
+
| Choose | Judge | Score |
|
| 34 |
+
|---|---|---|
|
| 35 |
+
| Select an action from 2–255 candidates you provide. | Return P(true) for a condition applied to the supplied state. | Apply 2–10 ordered criteria and return the expected index. |
|
| 36 |
+
|
| 37 |
+
Each response preserves your question names and candidate IDs. There is no explanatory token generation and no fixed application label set.
|
| 38 |
+
|
| 39 |
+
## Measured capability
|
| 40 |
+
|
| 41 |
+
Nox reaches **79.32%** overall: **+22.31 points over Laya**, **+15.31 over Decider**, and **+9.43 over its untuned 4B parent**. Jev scores 79.10% on the same panel; similar averages do not establish equivalent capability.
|
| 42 |
+
|
| 43 |
+
| Model | Overall accuracy ↑ | Choice ↑ | Noul ↑ | Score ↑ |
|
| 44 |
+
| --- | ---: | ---: | ---: | ---: |
|
| 45 |
+
| Nox · 4B | 79.32 | 76.06 | 90.62 | 87.50 |
|
| 46 |
+
| Jev 1.13.0 | 79.10 | 72.61 | 100.00 | 100.00 |
|
| 47 |
+
| Qwen3.5 · 4B, untuned | 69.89 | 68.48 | 62.50 | 90.62 |
|
| 48 |
+
| Sol · 2B | 66.25 | 71.41 | 42.19 | 43.75 |
|
| 49 |
+
| Decider · 2B | 64.01 | 60.77 | 71.88 | 84.38 |
|
| 50 |
+
| Qwen3.5 · 2B, untuned | 57.12 | 56.38 | 37.50 | 81.25 |
|
| 51 |
+
| Laya · EN/ML routed | 57.01 | 64.10 | 43.75 | 18.75 |
|
| 52 |
+
|
| 53 |
+
Accuracy (%), higher is better. Overall is the equal-weight mean across **10 families / 880 questions / 432 semantic groups**, not the average of the three type columns. Models receive the same frozen requests; no benchmark-specific adaptation. Laya uses its fixed EN/ML router and reports 112 truncated core inputs. Untuned Qwen uses the exact post-trained parent and a frozen LM-head adapter. [Methods, uncertainty and all input-support details](EVALUATION.md).
|
| 54 |
+
|
| 55 |
+

|
| 56 |
+
|
| 57 |
+

|
| 58 |
+
|
| 59 |
+
Relational composition, state tracking, probability calibration and the separate native-capability probe remain important gaps, including against Jev. These models judge supplied evidence; they do not browse for current facts or retrieve private information. Use an explicit unknown option when the evidence may be insufficient.
|
| 60 |
+
|
| 61 |
+
## Inference cost
|
| 62 |
+
|
| 63 |
+
| Choice workload | Tokens / question | p50 ms | p95 ms | Peak GiB |
|
| 64 |
+
| --- | ---: | ---: | ---: | ---: |
|
| 65 |
+
| Short · 1 question / 4 options | 309 | 27.37 | 28.95 | 8.06 |
|
| 66 |
+
| Short · 8 questions / 4 options | 309 | 69.25 | 69.84 | 8.35 |
|
| 67 |
+
| Long · 1 question / 4 options | 8863 | 278.96 | 296.37 | 9.25 |
|
| 68 |
+
| 1 question / 255 options | 7870 | 248.31 | 249.58 | 9.10 |
|
| 69 |
+
|
| 70 |
+
Measured on one AMD gfx942 GPU (261824 MiB), BF16 backbone / FP32 head, with the exact quality-tested runtime. Local Python-request latency includes rendering, tokenization, transfer, forward and answer assembly; loading, warmup and network are excluded. Thirty measurements per cell across three randomized blocks. Q8 means eight questions in one request, not eight concurrent clients. Memory is peak PyTorch allocation including weights. [All models, typed workloads and measurement details](TIMING.md).
|
| 71 |
+
|
| 72 |
+
## Try it
|
| 73 |
+
|
| 74 |
+
With the Hugging Face CLI and Docker installed, download this release and follow the tested [public ROCm runtime recipe](RUNTIME.md). It builds from a public digest-pinned image and installs the lightweight `decision-local` wrapper included here. No API key is needed for local inference.
|
| 75 |
+
|
| 76 |
+
```bash
|
| 77 |
+
hf download llm-semantic-router/Decision-1.0-Nox --revision v1.0 --local-dir decision-model
|
| 78 |
+
cd decision-model
|
| 79 |
+
docker build --pull -f Dockerfile.runtime -t decision-runtime:1.0 .
|
| 80 |
+
mkdir -p runtime-output
|
| 81 |
+
docker run --rm --device=/dev/kfd --device=/dev/dri --group-add video --ipc=host \
|
| 82 |
+
-v "$PWD":/model:ro -v "$PWD/runtime-output":/output \
|
| 83 |
+
decision-runtime:1.0 \
|
| 84 |
+
python3 -m decision.example /model --local-files-only --output /output/example.json
|
| 85 |
+
```
|
| 86 |
+
|
| 87 |
+
This executes the packaged three-question billing example, checks the wrapper against the direct numerical engine, and verifies explicit overflow rejection. The recorded output selected **billing**, returned **P(refund requested) = 1.000000**, and scored urgency **0.999770** on the three-level 0–2 rubric. [Exact request and full measured response](model-card-example.json).
|
| 88 |
+
|
| 89 |
+
From Python inside that runtime:
|
| 90 |
+
|
| 91 |
+
```python
|
| 92 |
+
from decision import DecisionModel
|
| 93 |
+
from decision.example import REQUEST
|
| 94 |
+
|
| 95 |
+
model = DecisionModel.from_pretrained("/model", local_files_only=True)
|
| 96 |
+
result = model.decide(**REQUEST)
|
| 97 |
+
print(result["answers"])
|
| 98 |
+
```
|
| 99 |
+
|
| 100 |
+
The complete state, instructions and candidates must fit the token budget for **every question**; overflow rejects the call instead of truncating. Score returns an expected ordinal index, not arbitrary supplied numerical values. [Interface and loading reference](USAGE.md).
|
| 101 |
+
|
| 102 |
+
## Architecture
|
| 103 |
+
|
| 104 |
+

|
| 105 |
+
|
| 106 |
+
The text-only Qwen3.5 backbone combines gated linear-attention blocks with full causal attention. A shared head reads candidate endpoints together with a final query vector, then returns a masked softmax over the current candidates. The backbone runs in BF16 and the small decision head in FP32. Questions execute independently in batches of eight; this release does not cache a shared state prefix across questions.
|
| 107 |
+
|
| 108 |
+

|
| 109 |
+
|
| 110 |
+
Editable [architecture SVG](assets/architecture.svg), [readout SVG](assets/readout.svg), and [vector PDF](assets/architecture-atlas.pdf). [Exact architecture and inference source](code/decision_model.py).
|
| 111 |
+
|
| 112 |
+
## Deployment and scope
|
| 113 |
+
|
| 114 |
+
The packaged runtime is validated on an AMD GPU with the gfx942 architecture and ROCm. CPU/MPS inference is not implemented, and NVIDIA compatibility has not been qualified. [Runtime, dependency pins and reproduction](RUNTIME.md).
|
| 115 |
+
|
| 116 |
+
This is a general decision checkpoint adapted from [Qwen3.5-4B](https://huggingface.co/Qwen/Qwen3.5-4B); it is not a chat generator. English and Chinese were measured on the declared suite; other languages and application-specific reliability require evaluation. Probabilities can be overconfident, and the concentration-based confidence field is not a correctness guarantee.
|
| 117 |
+
|
| 118 |
+
Weights and code are distributed under [Apache 2.0](LICENSE), with [upstream and training-data attribution](ATTRIBUTIONS.md). Explore the [Decision collection](https://huggingface.co/collections/llm-semantic-router/decision-10-6ab12177bd0002394d8409f9).
|
RUNTIME.md
ADDED
|
@@ -0,0 +1,52 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Public ROCm runtime
|
| 2 |
+
|
| 3 |
+
The package has a public, digest-pinned installation path. `Dockerfile.runtime` starts from `vllm/vllm-openai-rocm@sha256:1fd21abe66455b4df5a2e83629e97cdcc9d58913b16052d8118b92b239792339`, adds two hash-checked FLA wheels, and installs this repository's loading wrapper. It keeps the base image's ROCm PyTorch and Triton builds. The vLLM server is not used by Decision inference.
|
| 4 |
+
|
| 5 |
+
**Validation boundary:** the public registry manifest, base-image ancestry, package metadata and critical PyTorch binary hashes have been checked. The recipe built successfully and passed CPU imports and real AMD ROCm gfx942 GPU GPU inference for both released bundles. On the packaged three-question Choice/Noul/Score example, its complete responses matched the qualified research runtime exactly; the wrapper matched the direct engine and rejected an oversized complete input. Evidence is in `runtime-build-provenance.json`. This example establishes a working public installation path; it is not a full rerun of the quality or timing benchmark. Published benchmark results use the qualified runtime in each bundle's `runtime.json`.
|
| 6 |
+
|
| 7 |
+
## Build and run
|
| 8 |
+
|
| 9 |
+
Use an AMD ROCm-compatible Linux host with Docker and the required GPU driver. Check the [AMD PyTorch installation and host prerequisites](https://rocm.docs.amd.com/projects/ai-ecosystem/en/latest/frameworks/pytorch/install.html). CPU and MPS inference are not supported by this model engine; no NVIDIA validation is claimed.
|
| 10 |
+
|
| 11 |
+
Run these commands from the downloaded model repository containing `Dockerfile.runtime`, `runtime-fla-requirements.lock`, `pyproject.toml`, `src/`, and the model bundle:
|
| 12 |
+
|
| 13 |
+
```bash
|
| 14 |
+
docker build --pull -f Dockerfile.runtime -t decision-runtime:1.0 .
|
| 15 |
+
mkdir -p runtime-output
|
| 16 |
+
docker run --rm \
|
| 17 |
+
--device=/dev/kfd --device=/dev/dri --group-add video --ipc=host \
|
| 18 |
+
-v "$PWD":/model:ro -v "$PWD/runtime-output":/output \
|
| 19 |
+
decision-runtime:1.0 \
|
| 20 |
+
python3 -m decision.example /model --local-files-only --output /output/example.json
|
| 21 |
+
```
|
| 22 |
+
|
| 23 |
+
This loads locally without a Hub token. The example tests Choice, Noul and Score through the wrapper and compares them with the frozen direct engine; inspect its actual result rather than assuming a predicted answer. Keep the runtime checks enabled. If they report a mismatch, resolve the cause before using this environment to reproduce benchmark claims. The explicit `allow_unvalidated_runtime=True` option is for separately labeled experiments, not benchmark reproduction.
|
| 24 |
+
|
| 25 |
+
The image is large because its public base includes the vLLM development environment. No Decision weights, dataset, user credentials or private runtime image are required to build it. Model weights are mounted at execution time.
|
| 26 |
+
|
| 27 |
+
## What is pinned
|
| 28 |
+
|
| 29 |
+
The public base locks the existing OS, ROCm libraries and Python dependency environment by content digest. Its exact observed core versions are:
|
| 30 |
+
|
| 31 |
+
| Component | Observed value |
|
| 32 |
+
|---|---|
|
| 33 |
+
| Python | 3.12.13 |
|
| 34 |
+
| PyTorch | 2.12.0+git6bbd260 |
|
| 35 |
+
| PyTorch commit | 6bbd26020da1c6dc198625dfcdd968b1e4e6b1c5 |
|
| 36 |
+
| ROCm userspace / HIP build | 7.2.3 / 7.2.53211 |
|
| 37 |
+
| Triton distribution / imported version | 3.7.1+gitf0b55c07 / 3.7.1 |
|
| 38 |
+
| Transformers | 5.17.0 |
|
| 39 |
+
| Tokenizers / Safetensors | 0.23.2 / 0.8.0 |
|
| 40 |
+
| NumPy / Einops | 2.3.5 / 0.8.2 |
|
| 41 |
+
| Hugging Face Hub | 1.31.0 |
|
| 42 |
+
| FLA core / Flash Linear Attention | 0.5.2 / 0.5.2 |
|
| 43 |
+
|
| 44 |
+
`runtime-provenance.json` records the live registry manifest response, 36 shared base layers, selected actual binary SHA256 values, observed versions, wheel URLs and wheel hashes. The FLA wheels were downloaded and their SHA256 values matched the qualified overlay. `runtime-fla-requirements.lock` intentionally covers only that overlay; it is not a standalone dependency lock for an arbitrary system.
|
| 45 |
+
|
| 46 |
+
The official [FLA installation guide](https://github.com/fla-org/flash-linear-attention/blob/main/INSTALL.md) separates backend PyTorch installation from FLA and documents `--no-deps` for pre-release/custom Torch builds. This recipe uses that boundary and never asks pip to replace Torch or Triton. Transformers is supplied by the pinned base; see its [official installation documentation](https://huggingface.co/docs/transformers/installation) for the general package installation model.
|
| 47 |
+
|
| 48 |
+
## Portability boundary
|
| 49 |
+
|
| 50 |
+
The public [PyTorch ROCm 7.2 wheel index](https://download.pytorch.org/whl/rocm7.2/torch/) contains ordinary release wheels such as `2.12.0+rocm7.2`. They are a different artifact from the qualified `2.12.0+git6bbd260` build and are not interchangeable evidence. The latter's [source commit is public](https://github.com/pytorch/pytorch/commit/6bbd26020da1c6dc198625dfcdd968b1e4e6b1c5), but a source commit alone does not reproduce compiler flags, linked libraries and binary behavior.
|
| 51 |
+
|
| 52 |
+
An alternative runtime must recheck the installed versions, actual FLA Gated DeltaNet dispatch, BF16 backbone plus FP32 head, fixed prompt rendering, batch size eight, and model output agreement. Runtime changes can shift probabilities near a decision boundary even with identical weights. The supplied engine uses FLA Gated DeltaNet, reference PyTorch causal convolution and SDPA; selecting a different kernel is a new runtime configuration.
|
TIMING.md
ADDED
|
@@ -0,0 +1,164 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Local request efficiency
|
| 2 |
+
|
| 3 |
+
One AMD gfx942 accelerator, 261824 MiB visible device memory; the same physical device for every model.
|
| 4 |
+
|
| 5 |
+
Synchronized local API request latency including input rendering, tokenization, transfers, forward passes, and answer assembly. Excludes model loading, eligibility diagnostics, warmup, network, and post-response shape validation.
|
| 6 |
+
|
| 7 |
+
Three outer blocks with independently randomized model order. Each model is reloaded per panel/block, with three warmups per case followed by ten timed repetitions. Case order is shuffled within each block. 30 timings per eligible cell.
|
| 8 |
+
|
| 9 |
+
No other training or inference GPU process during measurement; each job has two idle-process preflight checks. ROCm telemetry is sampled during execution. CPU affinity, host services, and clocks are not locked; this is a GPU-quiet reproducible request benchmark, not a noise-free hardware microbenchmark.
|
| 10 |
+
|
| 11 |
+
One API request at a time; Q1/Q8/Q32 are questions within one request, not concurrent client requests. Native adapters retain their question packing/batch strategy. No cross-request cache.
|
| 12 |
+
|
| 13 |
+
Qwen/Decider backbone BF16, Sol/Nox decision head FP32; Laya preserves upstream FP32 parameters with native BF16 autocast. GDN-capable Qwen paths use FLA 0.5.2; Laya architecture has no GDN.
|
| 14 |
+
|
| 15 |
+
The timing panel contains English states and questions. Routed Laya selects its English branch here; these speeds do not characterize its multilingual branch.
|
| 16 |
+
|
| 17 |
+
p50/p95 are empirical percentiles of 30 observations, not confidence intervals. Questions/s equals 1000 times total questions divided by total measured milliseconds; it is not maximum concurrent-serving capacity.
|
| 18 |
+
|
| 19 |
+
Peak PyTorch allocated memory, including resident model parameters, in GiB. Excludes allocator-reserved memory, non-PyTorch allocations, and device-driver overhead.
|
| 20 |
+
|
| 21 |
+
All models receive identical byte-level states and question specifications. Token counts differ by native tokenizer/template. Truncated/unsupported cells are explicitly excluded; no short-input substitution. These repeated timing prompts do not measure semantic accuracy.
|
| 22 |
+
|
| 23 |
+
Every timing model_runtime_key is identical to that model’s reported final-quality key. No reference-quality/optimized-speed mixture.
|
| 24 |
+
|
| 25 |
+
After 25 successful jobs, preflight detected a transient ROCm process before starting job 26. The process exited; an explicit resume executed only the remaining 11 jobs after idle checks. No timing job was repeated.
|
| 26 |
+
|
| 27 |
+
No comparable local GPU timing is available for hosted Jev. Existing API wall times are a different workload/network measure and are not in the local latency ranking.
|
| 28 |
+
|
| 29 |
+
## choice
|
| 30 |
+
|
| 31 |
+
| Model | Case | Q / K | Tokens per row | p50 / p95 ms | Questions/s | Peak GiB |
|
| 32 |
+
|---|---|---:|---:|---:|---:|---:|
|
| 33 |
+
| Sol 2B | short-q1 | 1 / 4 | 309–309 | 21.04 / 21.41 | 47.6 | 3.61 |
|
| 34 |
+
| Sol 2B | medium-q1 | 1 / 4 | 2243–2243 | 35.88 / 36.10 | 27.9 | 3.76 |
|
| 35 |
+
| Sol 2B | long-q1 | 1 / 4 | 8863–8863 | 134.31 / 135.52 | 7.4 | 4.33 |
|
| 36 |
+
| Sol 2B | short-q8 | 8 / 4 | 309–309 | 37.29 / 37.51 | 214.3 | 3.78 |
|
| 37 |
+
| Sol 2B | medium-q8 | 8 / 4 | 2243–2243 | 216.20 / 216.66 | 37.0 | 5.00 |
|
| 38 |
+
| Sol 2B | short-q32 | 32 / 4 | 309–309 | 147.50 / 147.91 | 216.8 | 3.78 |
|
| 39 |
+
| Sol 2B | short-k255 | 1 / 255 | 7870–7870 | 118.33 / 119.12 | 8.4 | 4.24 |
|
| 40 |
+
| Nox 4B | short-q1 | 1 / 4 | 309–309 | 27.37 / 28.95 | 36.0 | 8.06 |
|
| 41 |
+
| Nox 4B | medium-q1 | 1 / 4 | 2243–2243 | 68.72 / 78.11 | 14.3 | 8.32 |
|
| 42 |
+
| Nox 4B | long-q1 | 1 / 4 | 8863–8863 | 278.96 / 296.37 | 3.6 | 9.25 |
|
| 43 |
+
| Nox 4B | short-q8 | 8 / 4 | 309–309 | 69.25 / 69.84 | 115.4 | 8.35 |
|
| 44 |
+
| Nox 4B | medium-q8 | 8 / 4 | 2243–2243 | 442.80 / 445.90 | 18.0 | 10.43 |
|
| 45 |
+
| Nox 4B | short-q32 | 32 / 4 | 309–309 | 275.65 / 278.26 | 115.8 | 8.35 |
|
| 46 |
+
| Nox 4B | short-k255 | 1 / 255 | 7870–7870 | 248.31 / 249.58 | 4.0 | 9.10 |
|
| 47 |
+
| Laya routed | short-q1 | 1 / 4 | 228–228 | 11.54 / 12.21 | 85.8 | 3.56 |
|
| 48 |
+
| Laya routed | medium-q1 | 1 / 4 | — | input_truncated | — | — |
|
| 49 |
+
| Laya routed | long-q1 | 1 / 4 | — | input_truncated | — | — |
|
| 50 |
+
| Laya routed | short-q8 | 8 / 4 | 228–228 | 14.56 / 15.02 | 548.5 | 3.61 |
|
| 51 |
+
| Laya routed | medium-q8 | 8 / 4 | — | input_truncated | — | — |
|
| 52 |
+
| Laya routed | short-q32 | 32 / 4 | 228–228 | 37.89 / 38.30 | 843.8 | 3.78 |
|
| 53 |
+
| Laya routed | short-k255 | 1 / 255 | — | unsupported | — | — |
|
| 54 |
+
| Decider 2B | short-q1 | 1 / 4 | 250–250 | 23.35 / 23.91 | 42.9 | 3.62 |
|
| 55 |
+
| Decider 2B | medium-q1 | 1 / 4 | 2184–2184 | 35.24 / 35.41 | 28.4 | 3.80 |
|
| 56 |
+
| Decider 2B | long-q1 | 1 / 4 | 8804–8804 | 131.47 / 131.99 | 7.6 | 4.42 |
|
| 57 |
+
| Decider 2B | short-q8 | 8 / 4 | 250–250 | 31.59 / 31.77 | 253.4 | 3.90 |
|
| 58 |
+
| Decider 2B | medium-q8 | 8 / 4 | 2184–2184 | 209.86 / 210.64 | 38.1 | 5.28 |
|
| 59 |
+
| Decider 2B | short-q32 | 32 / 4 | 250–250 | 96.67 / 97.02 | 330.9 | 4.87 |
|
| 60 |
+
| Decider 2B | short-k255 | 1 / 255 | 5556–5556 | 78.83 / 79.27 | 12.7 | 4.10 |
|
| 61 |
+
| Qwen3.5 2B LM-head | short-q1 | 1 / 4 | 296–296 | 20.51 / 20.71 | 49.2 | 3.60 |
|
| 62 |
+
| Qwen3.5 2B LM-head | medium-q1 | 1 / 4 | 2230–2230 | 35.22 / 35.53 | 28.4 | 3.74 |
|
| 63 |
+
| Qwen3.5 2B LM-head | long-q1 | 1 / 4 | 8850–8850 | 129.02 / 131.25 | 7.7 | 4.21 |
|
| 64 |
+
| Qwen3.5 2B LM-head | short-q8 | 8 / 4 | 296–296 | 37.32 / 37.61 | 214.5 | 3.75 |
|
| 65 |
+
| Qwen3.5 2B LM-head | medium-q8 | 8 / 4 | 2230–2230 | 202.06 / 202.75 | 39.6 | 4.86 |
|
| 66 |
+
| Qwen3.5 2B LM-head | short-q32 | 32 / 4 | 296–296 | 146.88 / 147.16 | 218.3 | 3.75 |
|
| 67 |
+
| Qwen3.5 2B LM-head | short-k255 | 1 / 255 | — | unsupported | — | — |
|
| 68 |
+
| Qwen3.5 4B LM-head | short-q1 | 1 / 4 | 296–296 | 27.47 / 28.76 | 36.3 | 8.04 |
|
| 69 |
+
| Qwen3.5 4B LM-head | medium-q1 | 1 / 4 | 2230–2230 | 66.97 / 67.66 | 14.9 | 8.29 |
|
| 70 |
+
| Qwen3.5 4B LM-head | long-q1 | 1 / 4 | 8850–8850 | 257.47 / 258.85 | 3.9 | 9.12 |
|
| 71 |
+
| Qwen3.5 4B LM-head | short-q8 | 8 / 4 | 296–296 | 69.03 / 69.46 | 115.8 | 8.31 |
|
| 72 |
+
| Qwen3.5 4B LM-head | medium-q8 | 8 / 4 | 2230–2230 | 414.85 / 415.72 | 19.3 | 10.25 |
|
| 73 |
+
| Qwen3.5 4B LM-head | short-q32 | 32 / 4 | 296–296 | 274.69 / 275.19 | 116.5 | 8.31 |
|
| 74 |
+
| Qwen3.5 4B LM-head | short-k255 | 1 / 255 | — | unsupported | — | — |
|
| 75 |
+
|
| 76 |
+
## noul-score
|
| 77 |
+
|
| 78 |
+
| Model | Case | Q / K | Tokens per row | p50 / p95 ms | Questions/s | Peak GiB |
|
| 79 |
+
|---|---|---:|---:|---:|---:|---:|
|
| 80 |
+
| Sol 2B | noul-short-q1 | 1 / 2 | 262–262 | 20.84 / 21.38 | 47.8 | 3.61 |
|
| 81 |
+
| Sol 2B | noul-medium-q1 | 1 / 2 | 2196–2196 | 34.86 / 35.12 | 28.7 | 3.76 |
|
| 82 |
+
| Sol 2B | noul-long-q1 | 1 / 2 | 8816–8816 | 131.69 / 132.53 | 7.6 | 4.33 |
|
| 83 |
+
| Sol 2B | noul-short-q8 | 8 / 2 | 262–262 | 33.20 / 33.91 | 239.9 | 3.76 |
|
| 84 |
+
| Sol 2B | noul-medium-q8 | 8 / 2 | 2196–2196 | 207.14 / 208.02 | 38.6 | 4.96 |
|
| 85 |
+
| Sol 2B | noul-short-q32 | 32 / 2 | 262–262 | 131.43 / 132.38 | 243.5 | 3.77 |
|
| 86 |
+
| Sol 2B | score-short-q1 | 1 / 4 | 307–307 | 20.91 / 21.50 | 47.6 | 3.61 |
|
| 87 |
+
| Sol 2B | score-medium-q1 | 1 / 4 | 2241–2241 | 35.80 / 36.03 | 27.9 | 3.76 |
|
| 88 |
+
| Sol 2B | score-long-q1 | 1 / 4 | 8861–8861 | 134.45 / 135.55 | 7.4 | 4.33 |
|
| 89 |
+
| Sol 2B | score-short-q8 | 8 / 4 | 307–307 | 37.37 / 37.68 | 214.1 | 3.78 |
|
| 90 |
+
| Sol 2B | score-medium-q8 | 8 / 4 | 2241–2241 | 215.72 / 216.75 | 37.1 | 5.00 |
|
| 91 |
+
| Sol 2B | score-short-q32 | 32 / 4 | 307–307 | 146.54 / 147.00 | 218.4 | 3.78 |
|
| 92 |
+
| Sol 2B | score-short-q1-levels2 | 1 / 2 | 274–274 | 20.99 / 22.65 | 47.2 | 3.61 |
|
| 93 |
+
| Sol 2B | score-short-q1-levels10 | 1 / 10 | 490–490 | 21.10 / 21.56 | 47.3 | 3.63 |
|
| 94 |
+
| Nox 4B | noul-short-q1 | 1 / 2 | 262–262 | 27.44 / 29.16 | 35.8 | 8.05 |
|
| 95 |
+
| Nox 4B | noul-medium-q1 | 1 / 2 | 2196–2196 | 67.56 / 67.75 | 14.8 | 8.31 |
|
| 96 |
+
| Nox 4B | noul-long-q1 | 1 / 2 | 8816–8816 | 273.90 / 275.65 | 3.6 | 9.25 |
|
| 97 |
+
| Nox 4B | noul-short-q8 | 8 / 2 | 262–262 | 64.61 / 64.87 | 124.2 | 8.32 |
|
| 98 |
+
| Nox 4B | noul-medium-q8 | 8 / 2 | 2196–2196 | 427.53 / 429.06 | 18.7 | 10.36 |
|
| 99 |
+
| Nox 4B | noul-short-q32 | 32 / 2 | 262–262 | 256.45 / 257.09 | 124.8 | 8.32 |
|
| 100 |
+
| Nox 4B | score-short-q1 | 1 / 4 | 307–307 | 27.41 / 29.51 | 35.7 | 8.06 |
|
| 101 |
+
| Nox 4B | score-medium-q1 | 1 / 4 | 2241–2241 | 68.76 / 69.12 | 14.5 | 8.32 |
|
| 102 |
+
| Nox 4B | score-long-q1 | 1 / 4 | 8861–8861 | 279.43 / 280.17 | 3.6 | 9.25 |
|
| 103 |
+
| Nox 4B | score-short-q8 | 8 / 4 | 307–307 | 69.56 / 69.74 | 115.4 | 8.35 |
|
| 104 |
+
| Nox 4B | score-medium-q8 | 8 / 4 | 2241–2241 | 442.15 / 443.60 | 18.1 | 10.43 |
|
| 105 |
+
| Nox 4B | score-short-q32 | 32 / 4 | 307–307 | 277.89 / 278.51 | 115.1 | 8.35 |
|
| 106 |
+
| Nox 4B | score-short-q1-levels2 | 1 / 2 | 274–274 | 27.76 / 28.89 | 35.8 | 8.05 |
|
| 107 |
+
| Nox 4B | score-short-q1-levels10 | 1 / 10 | 490–490 | 27.75 / 29.39 | 35.4 | 8.08 |
|
| 108 |
+
| Laya routed | noul-short-q1 | 1 / 2 | 202–202 | 12.05 / 12.24 | 84.2 | 3.56 |
|
| 109 |
+
| Laya routed | noul-medium-q1 | 1 / 2 | — | input_truncated | — | — |
|
| 110 |
+
| Laya routed | noul-long-q1 | 1 / 2 | — | input_truncated | — | — |
|
| 111 |
+
| Laya routed | noul-short-q8 | 8 / 2 | 202–202 | 13.83 / 14.32 | 577.7 | 3.60 |
|
| 112 |
+
| Laya routed | noul-medium-q8 | 8 / 2 | — | input_truncated | — | — |
|
| 113 |
+
| Laya routed | noul-short-q32 | 32 / 2 | 202–202 | 34.38 / 34.68 | 929.9 | 3.75 |
|
| 114 |
+
| Laya routed | score-short-q1 | 1 / 4 | 231–231 | 12.17 / 12.59 | 83.3 | 3.56 |
|
| 115 |
+
| Laya routed | score-medium-q1 | 1 / 4 | — | input_truncated | — | — |
|
| 116 |
+
| Laya routed | score-long-q1 | 1 / 4 | — | input_truncated | — | — |
|
| 117 |
+
| Laya routed | score-short-q8 | 8 / 4 | 231–231 | 16.92 / 17.22 | 471.6 | 3.61 |
|
| 118 |
+
| Laya routed | score-medium-q8 | 8 / 4 | — | input_truncated | — | — |
|
| 119 |
+
| Laya routed | score-short-q32 | 32 / 4 | 231–231 | 38.64 / 38.95 | 827.9 | 3.79 |
|
| 120 |
+
| Laya routed | score-short-q1-levels2 | 1 / 2 | 216–216 | 11.73 / 11.98 | 86.4 | 3.56 |
|
| 121 |
+
| Laya routed | score-short-q1-levels10 | 1 / 10 | 328–328 | 11.91 / 12.54 | 84.4 | 3.56 |
|
| 122 |
+
| Decider 2B | noul-short-q1 | 1 / 2 | 204–204 | 23.29 / 23.83 | 42.9 | 3.62 |
|
| 123 |
+
| Decider 2B | noul-medium-q1 | 1 / 2 | 2138–2138 | 34.91 / 35.29 | 28.6 | 3.79 |
|
| 124 |
+
| Decider 2B | noul-long-q1 | 1 / 2 | 8758–8758 | 132.39 / 133.57 | 7.5 | 4.41 |
|
| 125 |
+
| Decider 2B | noul-short-q8 | 8 / 2 | 204–204 | 31.21 / 31.46 | 256.5 | 3.90 |
|
| 126 |
+
| Decider 2B | noul-medium-q8 | 8 / 2 | 2138–2138 | 204.89 / 205.29 | 39.1 | 5.24 |
|
| 127 |
+
| Decider 2B | noul-short-q32 | 32 / 2 | 204–204 | 95.38 / 95.82 | 335.8 | 4.87 |
|
| 128 |
+
| Decider 2B | score-short-q1 | 1 / 4 | 222–225 | 24.42 / 24.66 | 41.2 | 3.74 |
|
| 129 |
+
| Decider 2B | score-medium-q1 | 1 / 4 | 2156–2159 | 107.51 / 108.72 | 9.3 | 4.41 |
|
| 130 |
+
| Decider 2B | score-long-q1 | 1 / 4 | 8776–8779 | 469.64 / 472.21 | 2.1 | 6.93 |
|
| 131 |
+
| Decider 2B | score-short-q8 | 8 / 4 | 222–225 | 96.03 / 96.75 | 83.2 | 4.87 |
|
| 132 |
+
| Decider 2B | score-medium-q8 | 8 / 4 | 2156–2159 | 773.01 / 774.95 | 10.4 | 9.79 |
|
| 133 |
+
| Decider 2B | score-short-q32 | 32 / 4 | 222–225 | 353.70 / 355.63 | 90.4 | 8.71 |
|
| 134 |
+
| Decider 2B | score-short-q1-levels2 | 1 / 2 | 234–234 | 23.60 / 24.24 | 42.3 | 3.66 |
|
| 135 |
+
| Decider 2B | score-short-q1-levels10 | 1 / 10 | 234–234 | 37.79 / 38.16 | 26.4 | 3.98 |
|
| 136 |
+
| Qwen3.5 2B LM-head | noul-short-q1 | 1 / 2 | 263–263 | 19.87 / 20.91 | 49.8 | 3.60 |
|
| 137 |
+
| Qwen3.5 2B LM-head | noul-medium-q1 | 1 / 2 | 2197–2197 | 34.91 / 35.11 | 28.6 | 3.74 |
|
| 138 |
+
| Qwen3.5 2B LM-head | noul-long-q1 | 1 / 2 | 8817–8817 | 127.50 / 128.67 | 7.8 | 4.21 |
|
| 139 |
+
| Qwen3.5 2B LM-head | noul-short-q8 | 8 / 2 | 263–263 | 34.26 / 34.58 | 233.3 | 3.73 |
|
| 140 |
+
| Qwen3.5 2B LM-head | noul-medium-q8 | 8 / 2 | 2197–2197 | 199.54 / 200.27 | 40.1 | 4.83 |
|
| 141 |
+
| Qwen3.5 2B LM-head | noul-short-q32 | 32 / 2 | 263–263 | 134.40 / 136.62 | 237.4 | 3.74 |
|
| 142 |
+
| Qwen3.5 2B LM-head | score-short-q1 | 1 / 4 | 303–303 | 19.90 / 20.24 | 50.2 | 3.60 |
|
| 143 |
+
| Qwen3.5 2B LM-head | score-medium-q1 | 1 / 4 | 2237–2237 | 35.52 / 35.90 | 28.1 | 3.74 |
|
| 144 |
+
| Qwen3.5 2B LM-head | score-long-q1 | 1 / 4 | 8857–8857 | 128.28 / 129.84 | 7.8 | 4.21 |
|
| 145 |
+
| Qwen3.5 2B LM-head | score-short-q8 | 8 / 4 | 303–303 | 37.81 / 37.98 | 211.6 | 3.75 |
|
| 146 |
+
| Qwen3.5 2B LM-head | score-medium-q8 | 8 / 4 | 2237–2237 | 202.06 / 202.79 | 39.6 | 4.86 |
|
| 147 |
+
| Qwen3.5 2B LM-head | score-short-q32 | 32 / 4 | 303–303 | 148.68 / 149.07 | 215.8 | 3.76 |
|
| 148 |
+
| Qwen3.5 2B LM-head | score-short-q1-levels2 | 1 / 2 | 286–286 | 19.93 / 20.44 | 50.0 | 3.60 |
|
| 149 |
+
| Qwen3.5 2B LM-head | score-short-q1-levels10 | 1 / 10 | 438–438 | 20.13 / 20.45 | 49.6 | 3.61 |
|
| 150 |
+
| Qwen3.5 4B LM-head | noul-short-q1 | 1 / 2 | 263–263 | 26.61 / 26.89 | 37.6 | 8.04 |
|
| 151 |
+
| Qwen3.5 4B LM-head | noul-medium-q1 | 1 / 2 | 2197–2197 | 65.78 / 65.96 | 15.2 | 8.28 |
|
| 152 |
+
| Qwen3.5 4B LM-head | noul-long-q1 | 1 / 2 | 8817–8817 | 256.56 / 258.56 | 3.9 | 9.11 |
|
| 153 |
+
| Qwen3.5 4B LM-head | noul-short-q8 | 8 / 2 | 263–263 | 64.86 / 64.99 | 123.3 | 8.27 |
|
| 154 |
+
| Qwen3.5 4B LM-head | noul-medium-q8 | 8 / 2 | 2197–2197 | 410.51 / 411.79 | 19.5 | 10.22 |
|
| 155 |
+
| Qwen3.5 4B LM-head | noul-short-q32 | 32 / 2 | 263–263 | 257.86 / 258.60 | 124.4 | 8.28 |
|
| 156 |
+
| Qwen3.5 4B LM-head | score-short-q1 | 1 / 4 | 303–303 | 26.60 / 26.74 | 37.6 | 8.04 |
|
| 157 |
+
| Qwen3.5 4B LM-head | score-medium-q1 | 1 / 4 | 2237–2237 | 66.41 / 80.27 | 14.7 | 8.29 |
|
| 158 |
+
| Qwen3.5 4B LM-head | score-long-q1 | 1 / 4 | 8857–8857 | 257.84 / 258.14 | 3.9 | 9.12 |
|
| 159 |
+
| Qwen3.5 4B LM-head | score-short-q8 | 8 / 4 | 303–303 | 69.96 / 70.42 | 114.3 | 8.31 |
|
| 160 |
+
| Qwen3.5 4B LM-head | score-medium-q8 | 8 / 4 | 2237–2237 | 416.17 / 446.59 | 19.0 | 10.26 |
|
| 161 |
+
| Qwen3.5 4B LM-head | score-short-q32 | 32 / 4 | 303–303 | 278.88 / 280.80 | 114.7 | 8.31 |
|
| 162 |
+
| Qwen3.5 4B LM-head | score-short-q1-levels2 | 1 / 2 | 286–286 | 26.65 / 30.12 | 36.4 | 8.04 |
|
| 163 |
+
| Qwen3.5 4B LM-head | score-short-q1-levels10 | 1 / 10 | 438–438 | 26.82 / 27.25 | 37.2 | 8.06 |
|
| 164 |
+
|
USAGE.md
ADDED
|
@@ -0,0 +1,66 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Load Decision locally
|
| 2 |
+
|
| 3 |
+
This package loads the exported Sol/Nox decoder bundles and delegates to their frozen numerical engine. It does not use text generation or alter the trained prompt, candidate readout, temperature, or probability semantics.
|
| 4 |
+
|
| 5 |
+
Install from a downloaded model repository containing this `pyproject.toml` and `src/decision/`:
|
| 6 |
+
|
| 7 |
+
```bash
|
| 8 |
+
python -m pip install .
|
| 9 |
+
# Optional, only for resolving models through Hugging Face:
|
| 10 |
+
python -m pip install '.[hub]'
|
| 11 |
+
```
|
| 12 |
+
|
| 13 |
+
There is no requirement to install an identically named package from PyPI. These commands install this repository's wrapper. They deliberately do not replace your GPU PyTorch installation. The full inference environment is recorded in the model's `runtime.json`: the qualified run used PyTorch 2.12.0+git6bbd260 / ROCm 7.2.53211, Transformers 5.17.0, FLA 0.5.2, Triton 3.7.1, tokenizers 0.23.2 and safetensors 0.8.0. The recorded PyTorch build is not promised to exist on ordinary PyPI. Use the public digest-pinned build recipe in [RUNTIME.md](RUNTIME.md); installation of this lightweight wrapper alone is not installation of that GPU runtime.
|
| 14 |
+
|
| 15 |
+
Local loading is offline and requires no Hub client or credentials:
|
| 16 |
+
|
| 17 |
+
```python
|
| 18 |
+
from decision import DecisionModel
|
| 19 |
+
|
| 20 |
+
model = DecisionModel.from_pretrained(
|
| 21 |
+
"./Decision-1.0-Sol", local_files_only=True, device="cuda:0"
|
| 22 |
+
)
|
| 23 |
+
result = model.decide(
|
| 24 |
+
state="The customer reports a duplicate invoice charge and asks for a refund.",
|
| 25 |
+
questions={
|
| 26 |
+
"destination": {
|
| 27 |
+
"type": "choice",
|
| 28 |
+
"instructions": "Choose the team that handles this request.",
|
| 29 |
+
"criteria": {
|
| 30 |
+
"billing": "Invoices, payments, refunds and duplicate charges",
|
| 31 |
+
"technical": "Product errors and troubleshooting",
|
| 32 |
+
},
|
| 33 |
+
}
|
| 34 |
+
},
|
| 35 |
+
)
|
| 36 |
+
print(result)
|
| 37 |
+
```
|
| 38 |
+
|
| 39 |
+
The saved model-card example runner includes Choice, Noul and Score together, compares its actual output with the direct frozen engine, and checks that an overflowing input raises an error:
|
| 40 |
+
|
| 41 |
+
```bash
|
| 42 |
+
decision-example ./Decision-1.0-Sol --local-files-only --output actual-example.json
|
| 43 |
+
# Or: python -m decision.example ...
|
| 44 |
+
```
|
| 45 |
+
|
| 46 |
+
The model card must publish output from that model's real run; this document invents no prediction. To load a cached or remote Hub snapshot, pass the published repository ID as the first argument to `DecisionModel.from_pretrained` and its full commit SHA as `revision`. `local_files_only=True` restricts this lookup to already cached files. A local directory always bypasses Hub lookup. The model loads Python inference source from its verified bundle, like other local model packages; choose a repository you trust.
|
| 47 |
+
|
| 48 |
+
## Interface
|
| 49 |
+
|
| 50 |
+
| Type | Input criteria | Answer |
|
| 51 |
+
|---|---|---|
|
| 52 |
+
| Choice | Ordered mapping of 2–255 external IDs to complete descriptions | `probabilities`, selected `choice` ID, `confidence` |
|
| 53 |
+
| Noul | Optional mapping containing only `false` / `true` descriptions | `noul`: P(true); a hard judgment uses `>= 0.5` |
|
| 54 |
+
| Score | Ordered list of 2–10 rubric descriptions | `probabilities` over string indices, expected level index `score`, `legend`, `confidence` |
|
| 55 |
+
|
| 56 |
+
Response shape is `{"model": name, "answers": {question_name: answer}, "usage": {"input_tokens": total, "scored_questions": count}}`. Choice ties select the earliest candidate in insertion order. Score returns the expected ordinal **index**, not an arbitrary supplied numeric value; this adapter does not implement a supplied-values extension. Noul 0.5 is interpreted as true. Confidence is `(K * max(p) - 1)/(K - 1)`, clipped to [0,1], and is not a claimed reproduction of Jev's confidence statistic. Shipped temperature calibration does not make every confidence value a correctness guarantee.
|
| 57 |
+
|
| 58 |
+
Question names are preserved as opaque bookkeeping IDs; candidate IDs and descriptions use the frozen renderer. Native objects are deterministically serialized with sorted JSON keys; strings preserve their contents. Do not interpret object/string field-order differences as identical token inputs. Non-finite or non-JSON inputs are rejected.
|
| 59 |
+
|
| 60 |
+
The bound is **16,384 tokens per complete question**, including its state, instructions, all candidates and readout suffix. Questions are separate sequences, grouped in fixed batches of eight; the state is repeated for each question and counted repeatedly in `usage.input_tokens`. All questions are encoded before any forward pass. If any exceeds the bound, the whole call raises `ValueError` without truncation or partial answers. A lower `max_length` can be chosen at load time; a higher limit is rejected. This native wrapper does not impose the Studio's separate 16-question UI limit.
|
| 61 |
+
|
| 62 |
+
## Runtime boundary
|
| 63 |
+
|
| 64 |
+
The qualified device is an AMD ROCm GPU accessed as `cuda:0` in PyTorch. Backbone parameters remain BF16, the candidate head FP32, with FLA Gated DeltaNet and SDPA. CPU and MPS inference are not implemented by the current engine and are rejected explicitly. Other GPU/runtime combinations require validation. The loader checks manifest hashes and the recorded runtime before loading. `allow_unvalidated_runtime=True` downgrades runtime differences to an explicit warning for experiments; it does not silently substitute a claimed validated environment or bypass unsupported CPU execution.
|
| 65 |
+
|
| 66 |
+
This package is a loading wrapper, not a trainer, HTTP service or new model selection policy. No prediction logs or private local paths are required by the bundle.
|
assets/architecture-atlas.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d1582ac115aa6a40129b6221e15a197e33d20847e03d69396f02fdab82771376
|
| 3 |
+
size 306242
|
assets/architecture.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ee87f997a0aa4343c2ec66038b7526361e0a3c0ae02b383f8928aac9dd9bd74c
|
| 3 |
+
size 183111
|
assets/architecture.png
ADDED
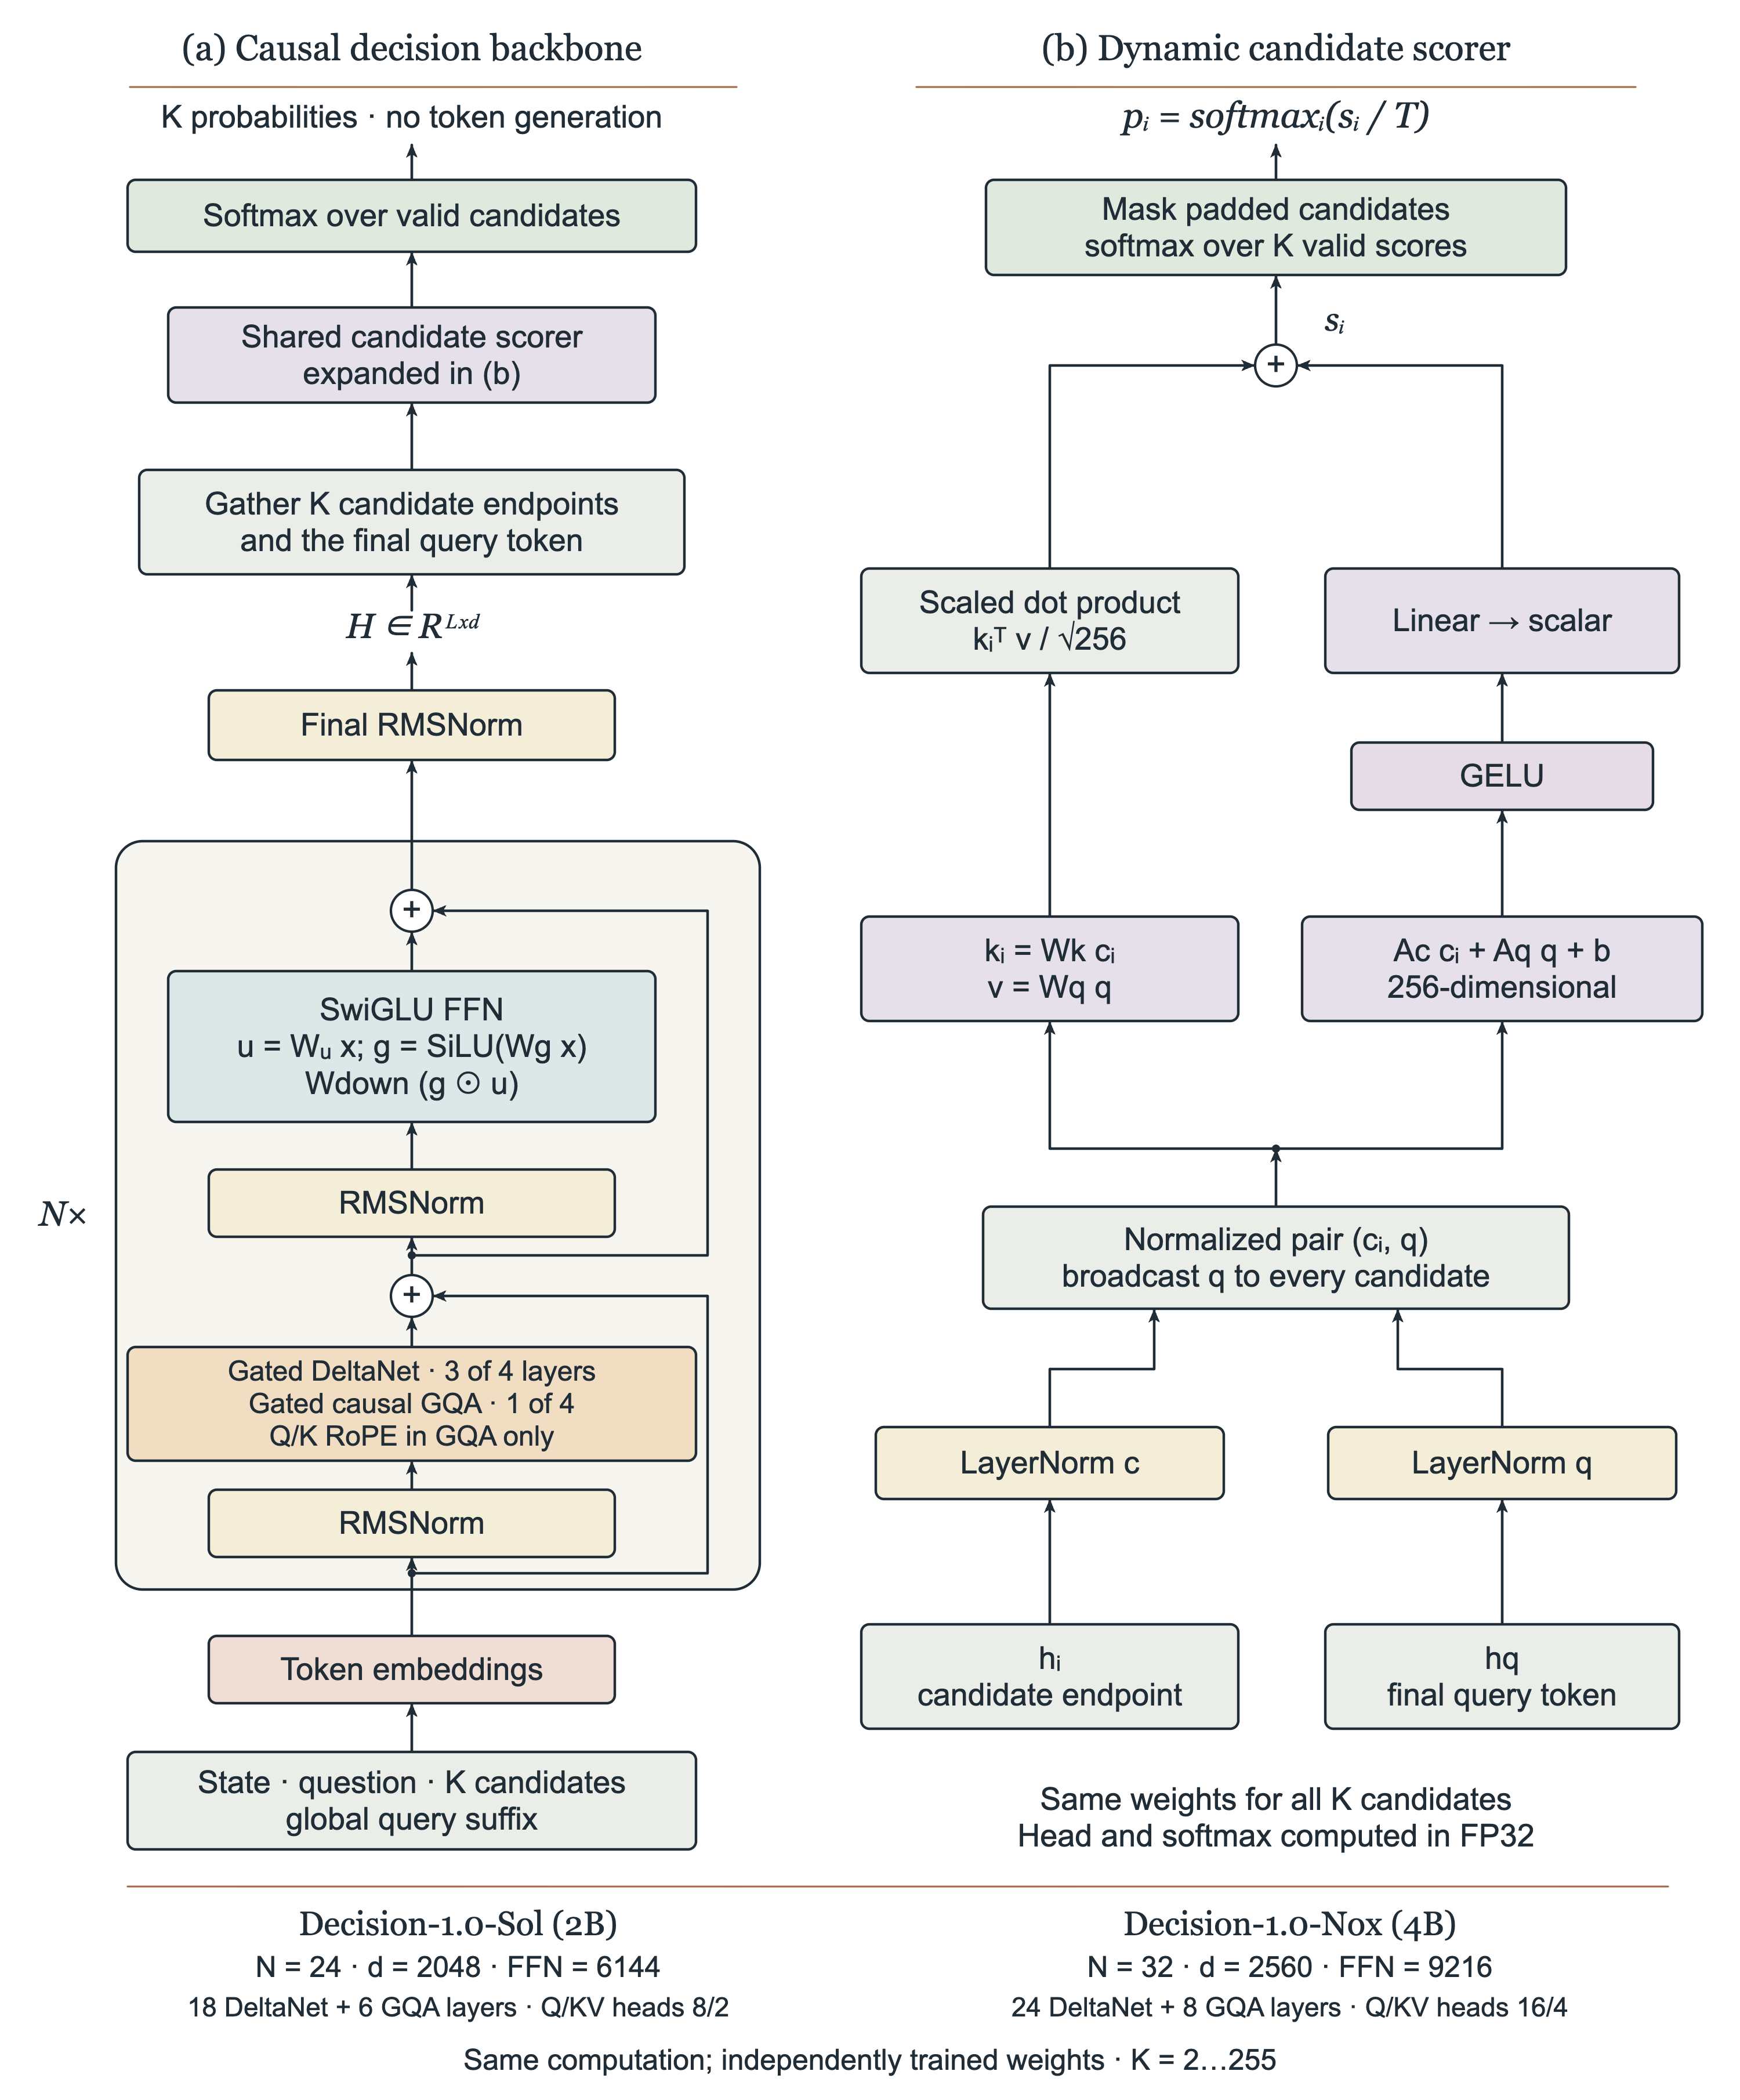
|
Git LFS Details
|
assets/architecture.svg
ADDED
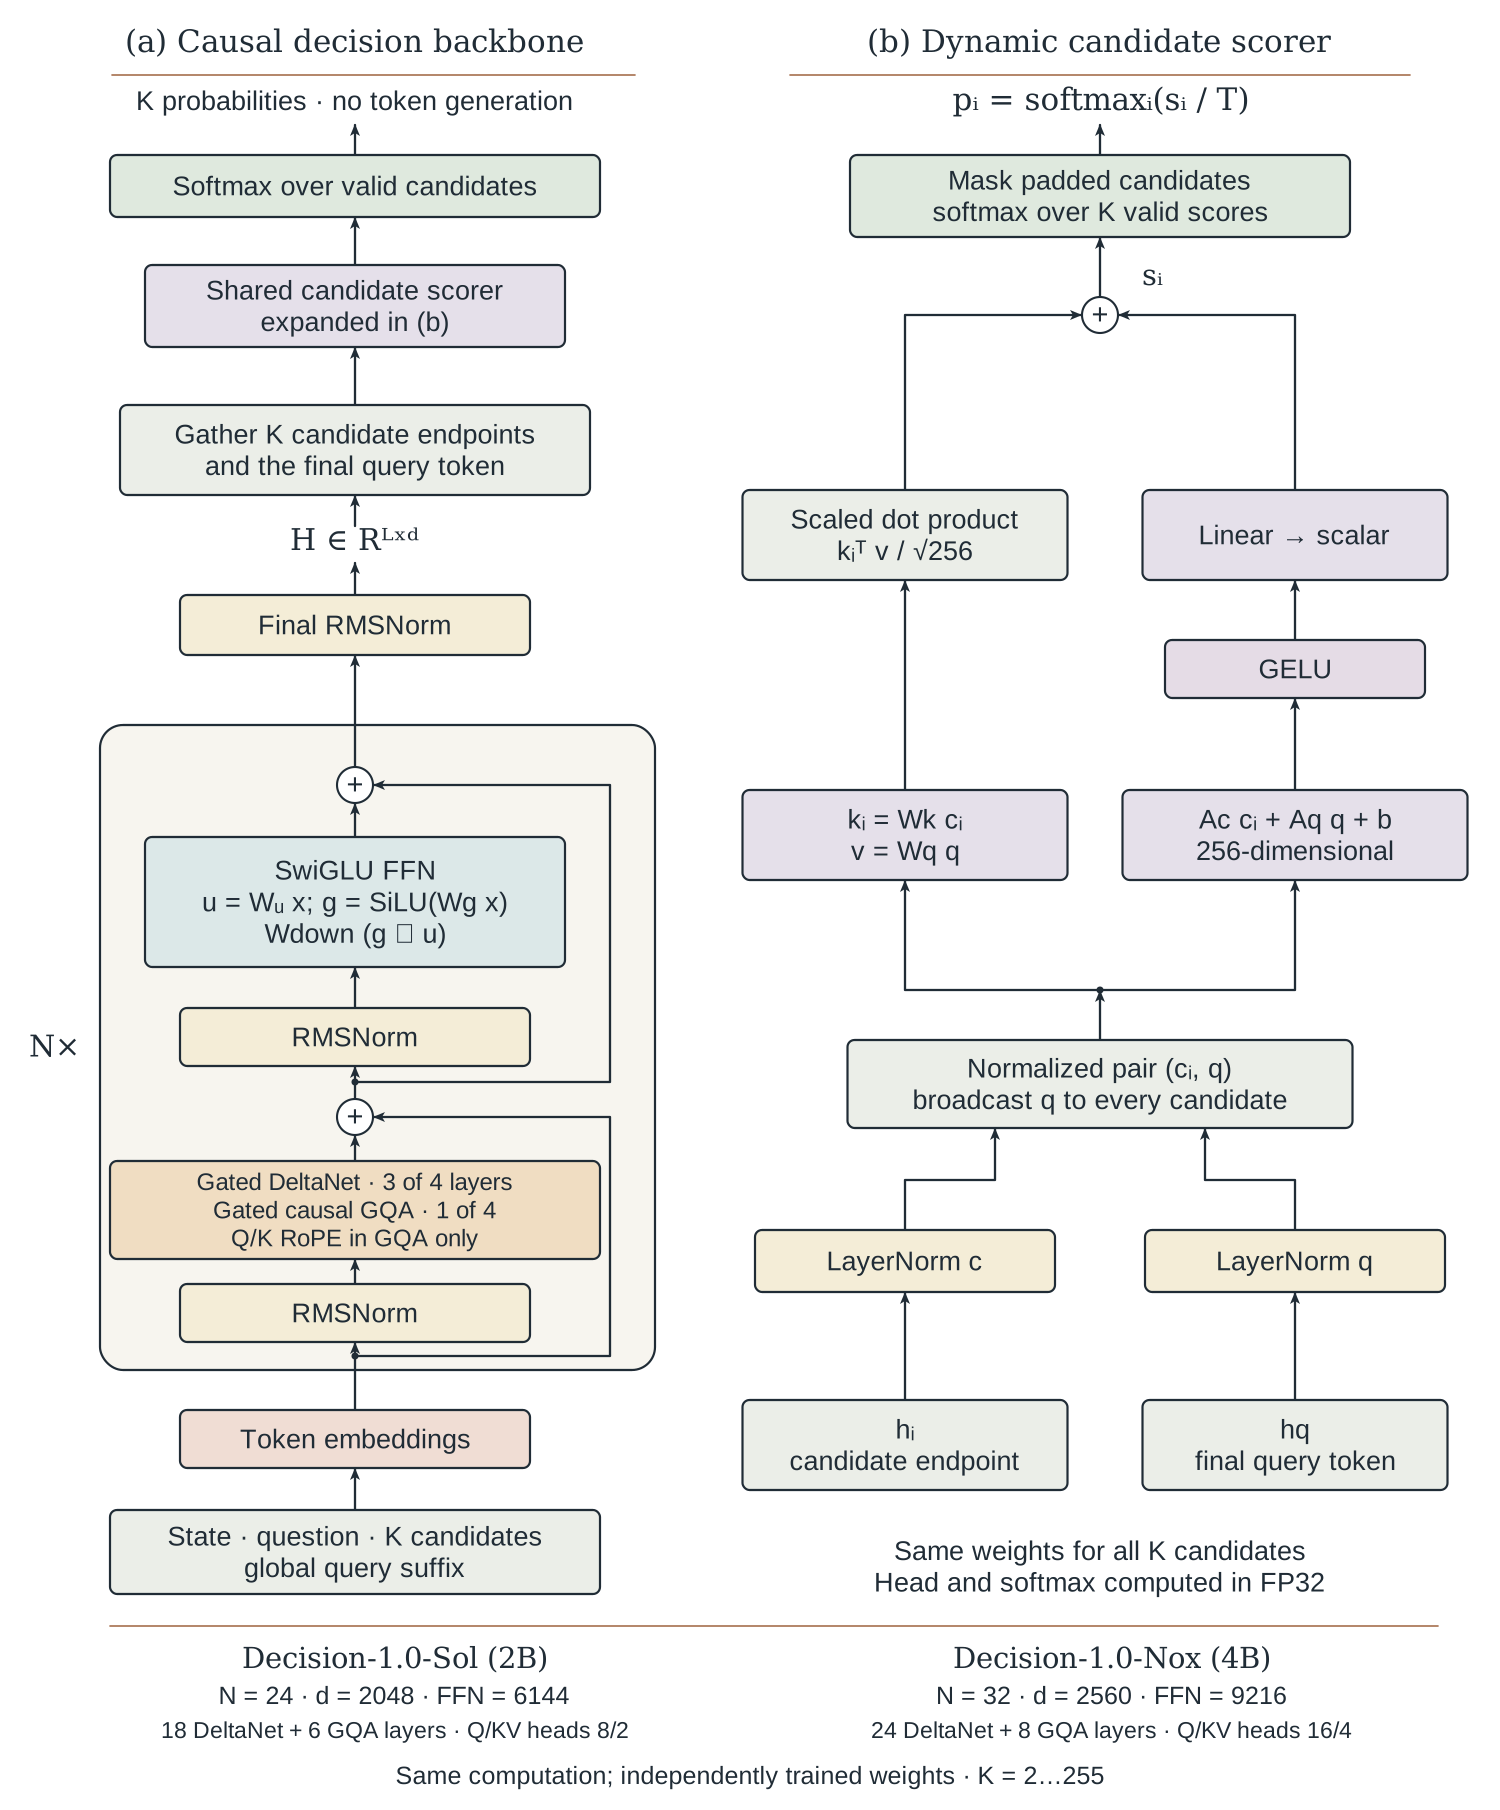
|
assets/decision-capabilities.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8cd467055c05d5c7616e776174ed0e3e953e71672558ea346e347e8663b5e5ce
|
| 3 |
+
size 106372
|
assets/decision-capabilities.png
ADDED
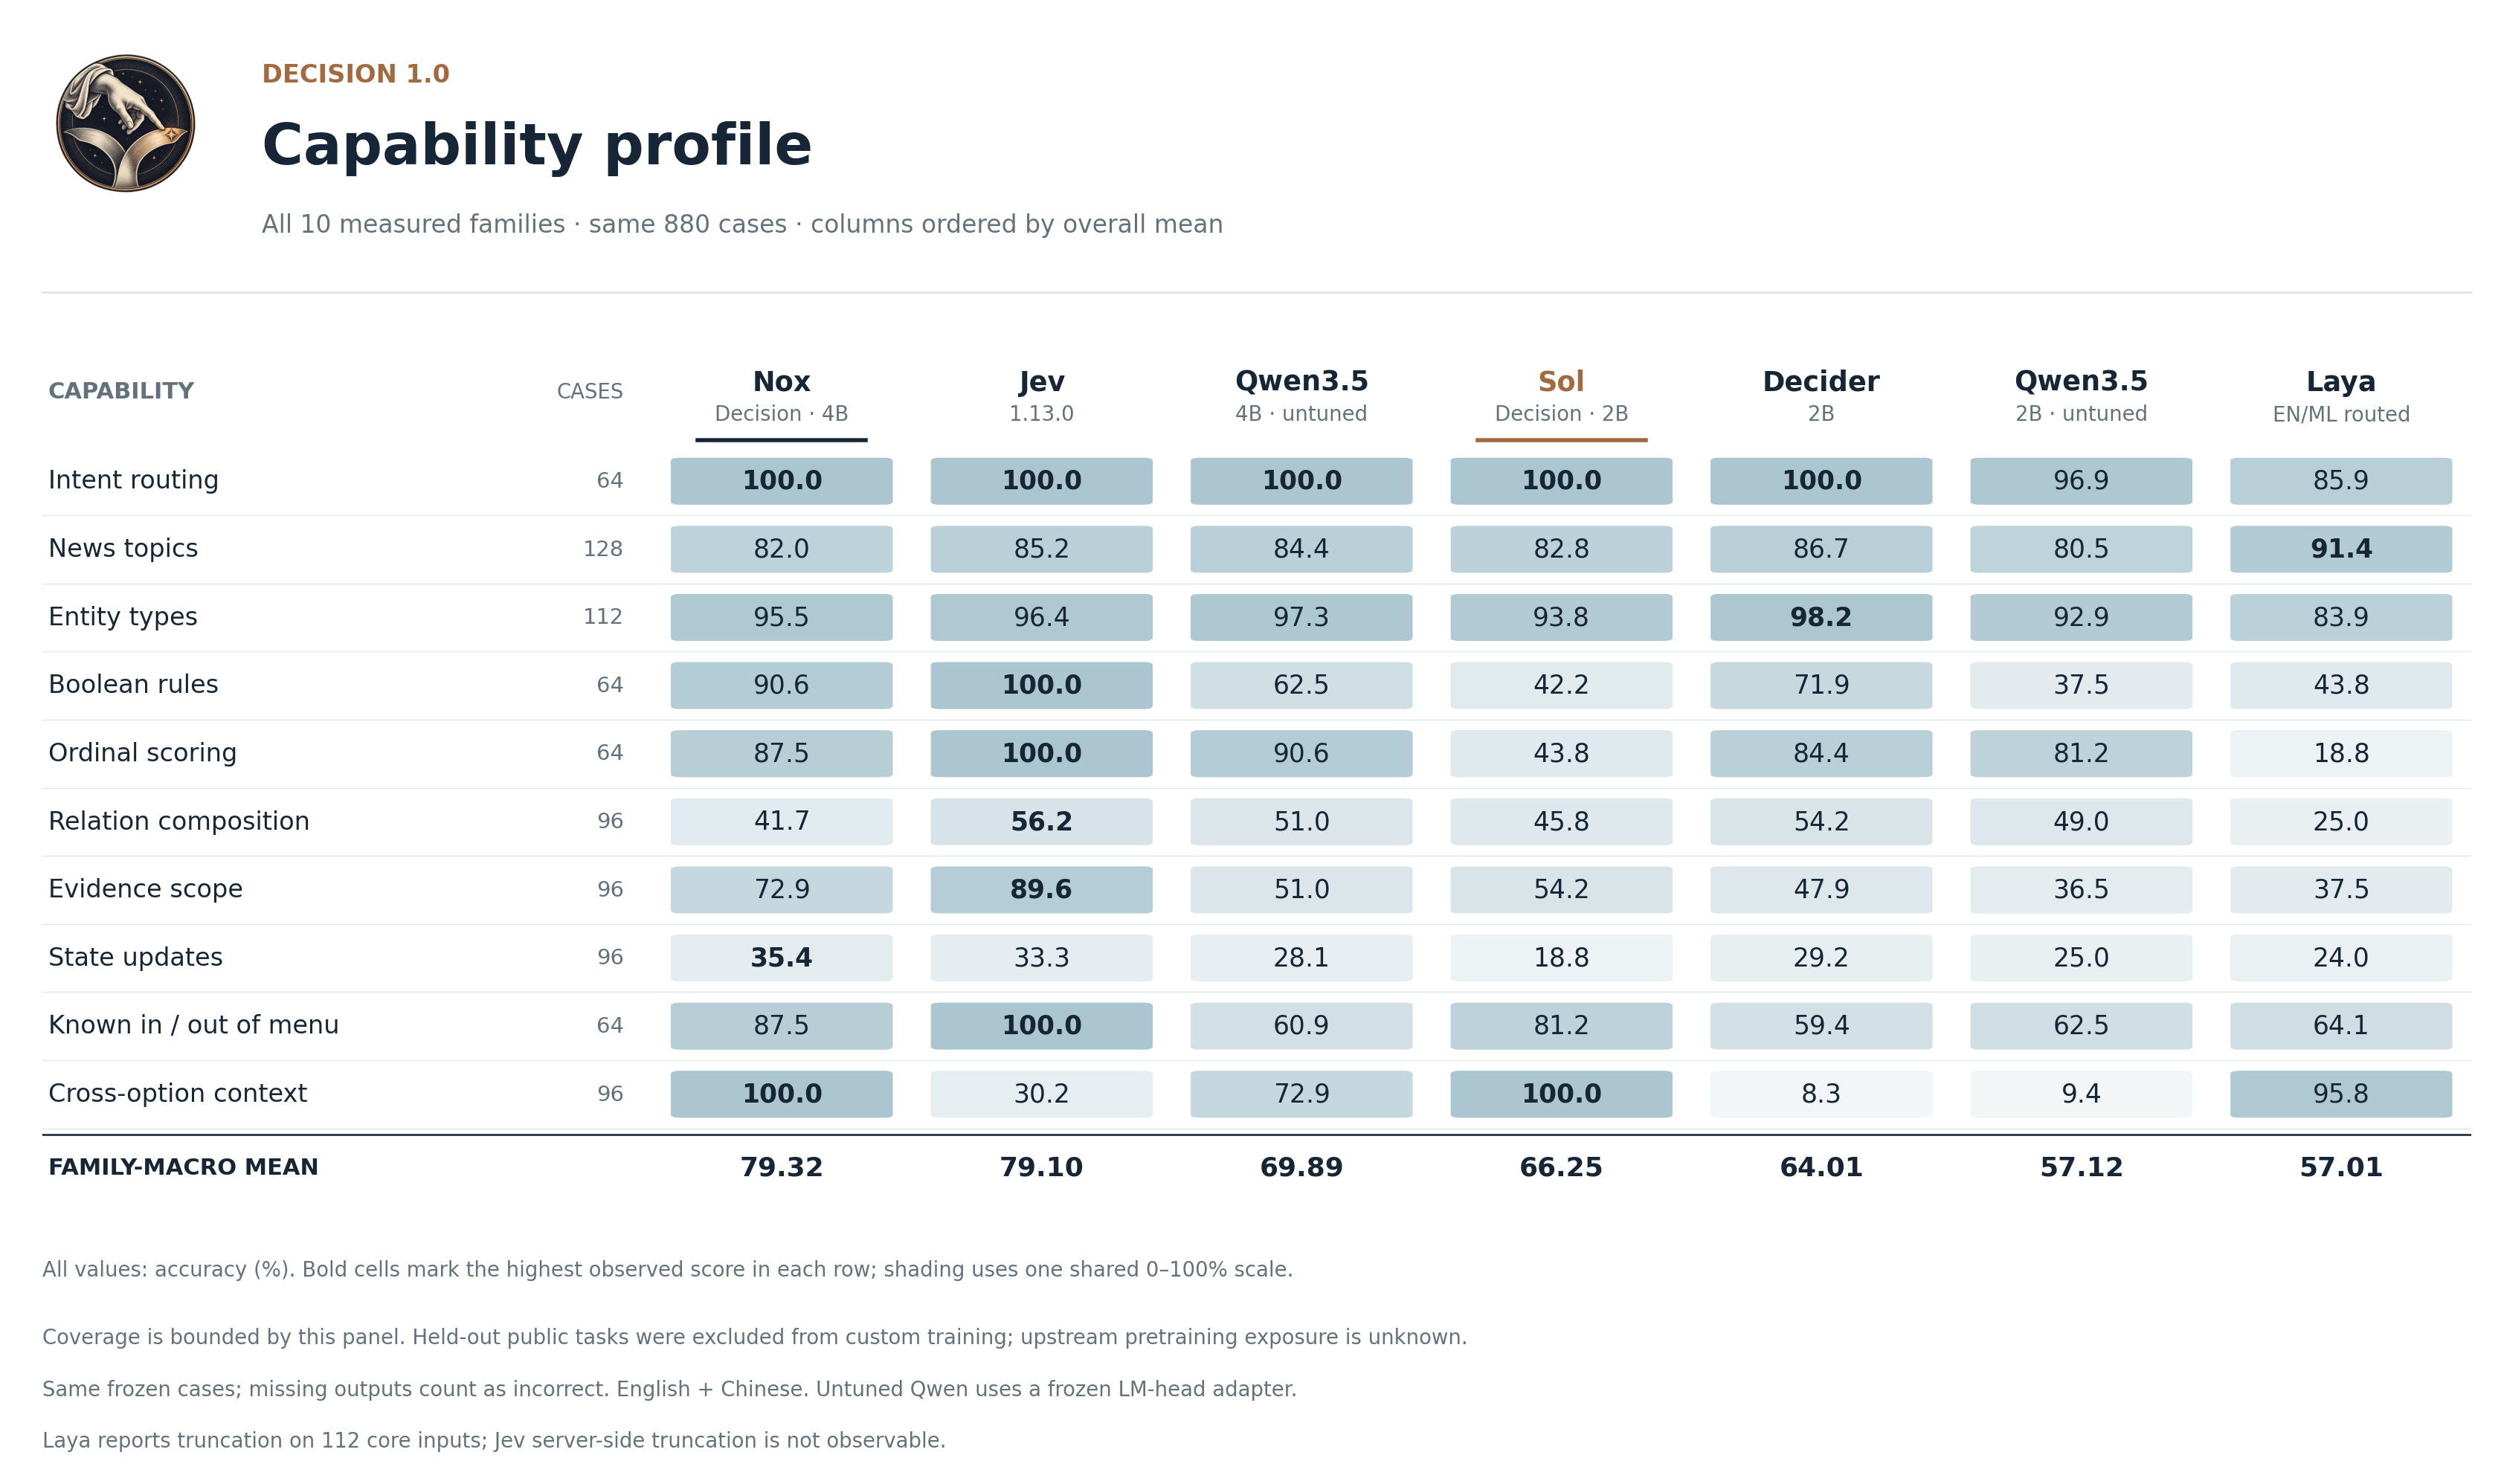
|
Git LFS Details
|
assets/decision-capabilities.svg
ADDED
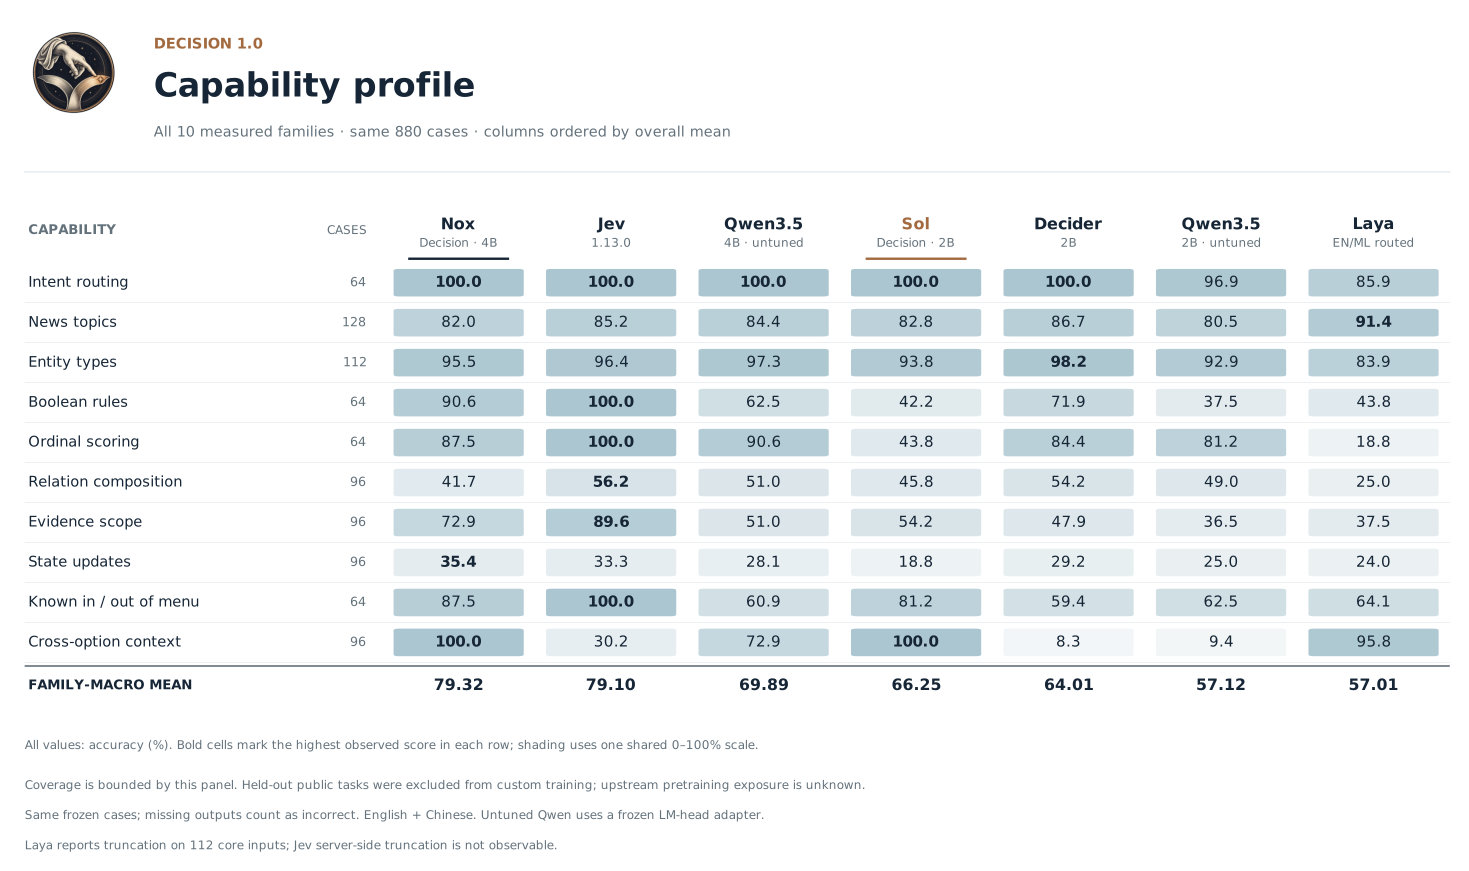
|
assets/decision-family-header.png
ADDED
|
Git LFS Details
|
assets/decision-mark.png
ADDED
|
Git LFS Details
|
assets/decision-quality.pdf
ADDED
|
Binary file (92.4 kB). View file
|
|
|
assets/decision-quality.png
ADDED
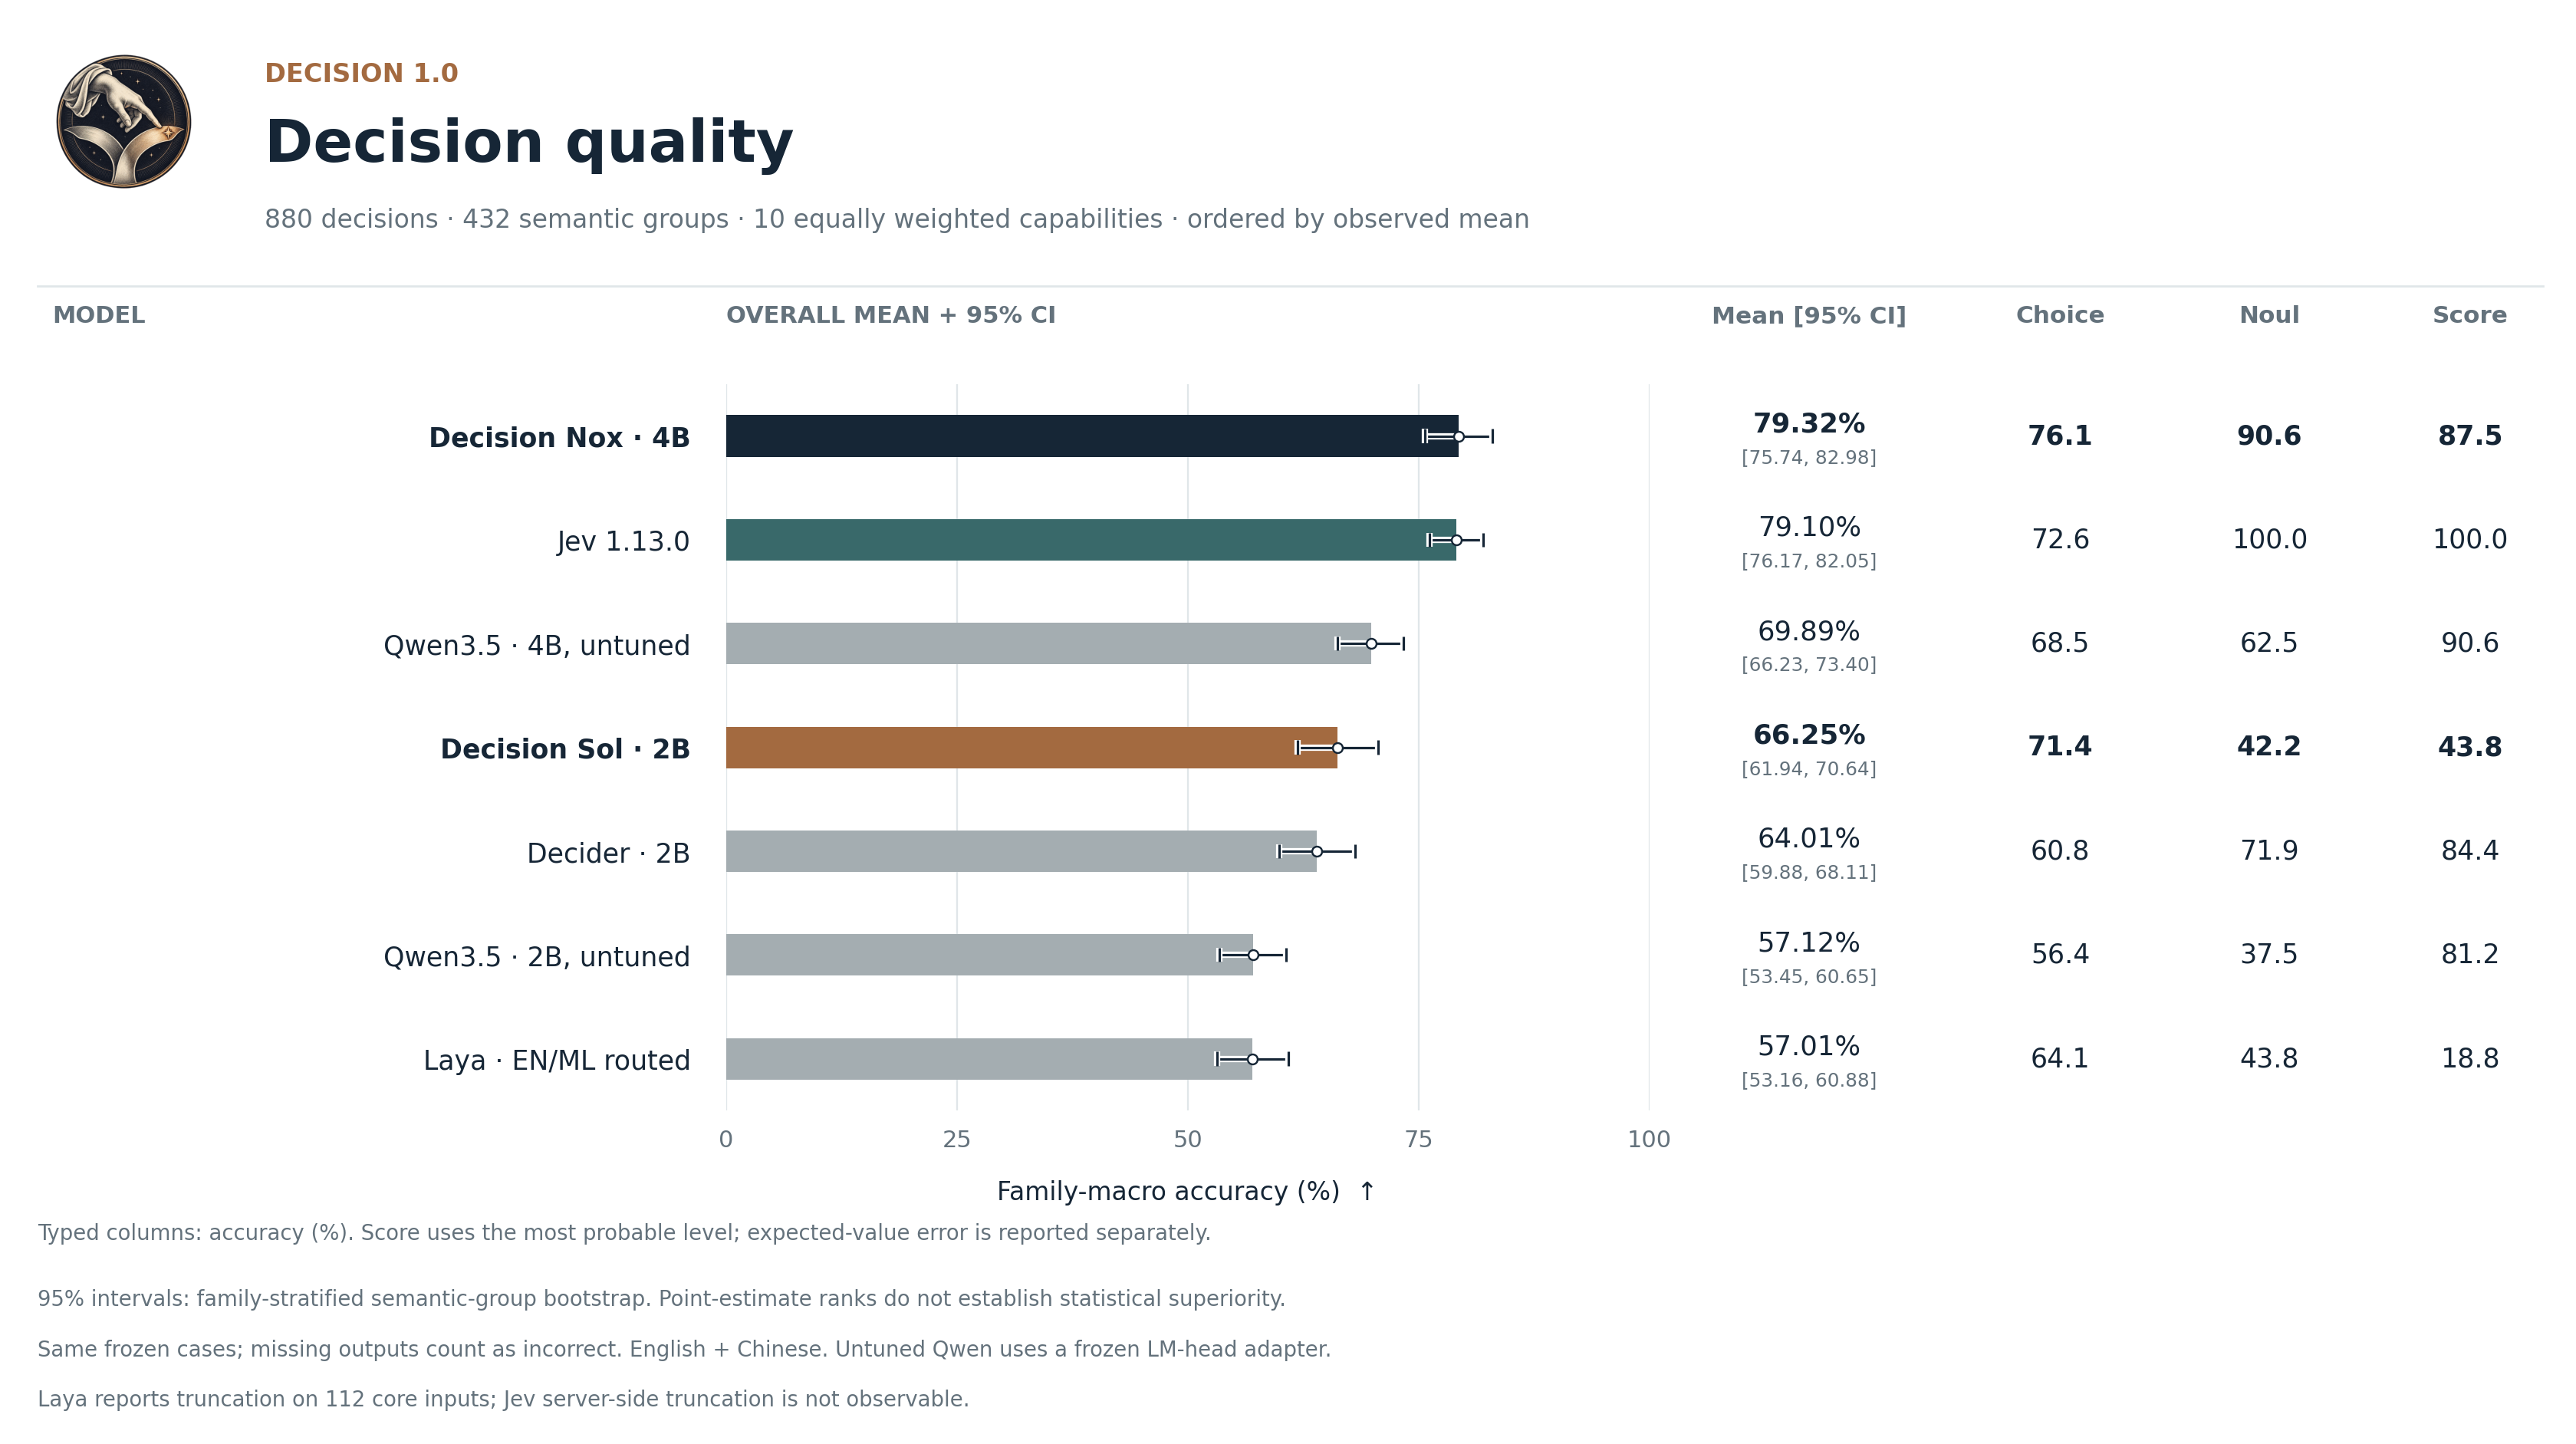
|
Git LFS Details
|
assets/decision-quality.svg
ADDED
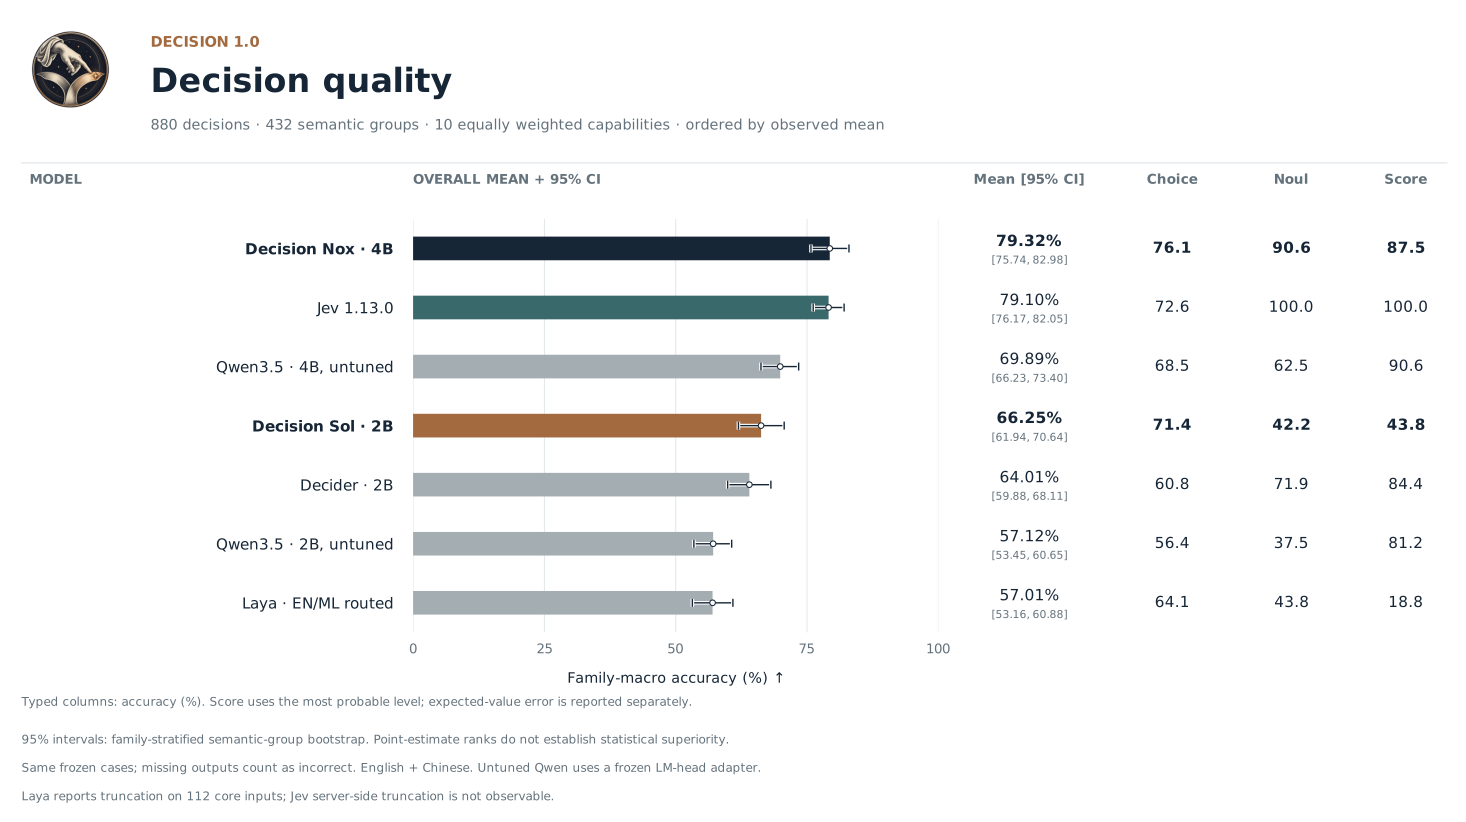
|
assets/readout.pdf
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d489b0d1814e37495a8612c12fabd3bf4a6e73d11c7e356bf1ce0cedded8a745
|
| 3 |
+
size 123008
|
assets/readout.png
ADDED
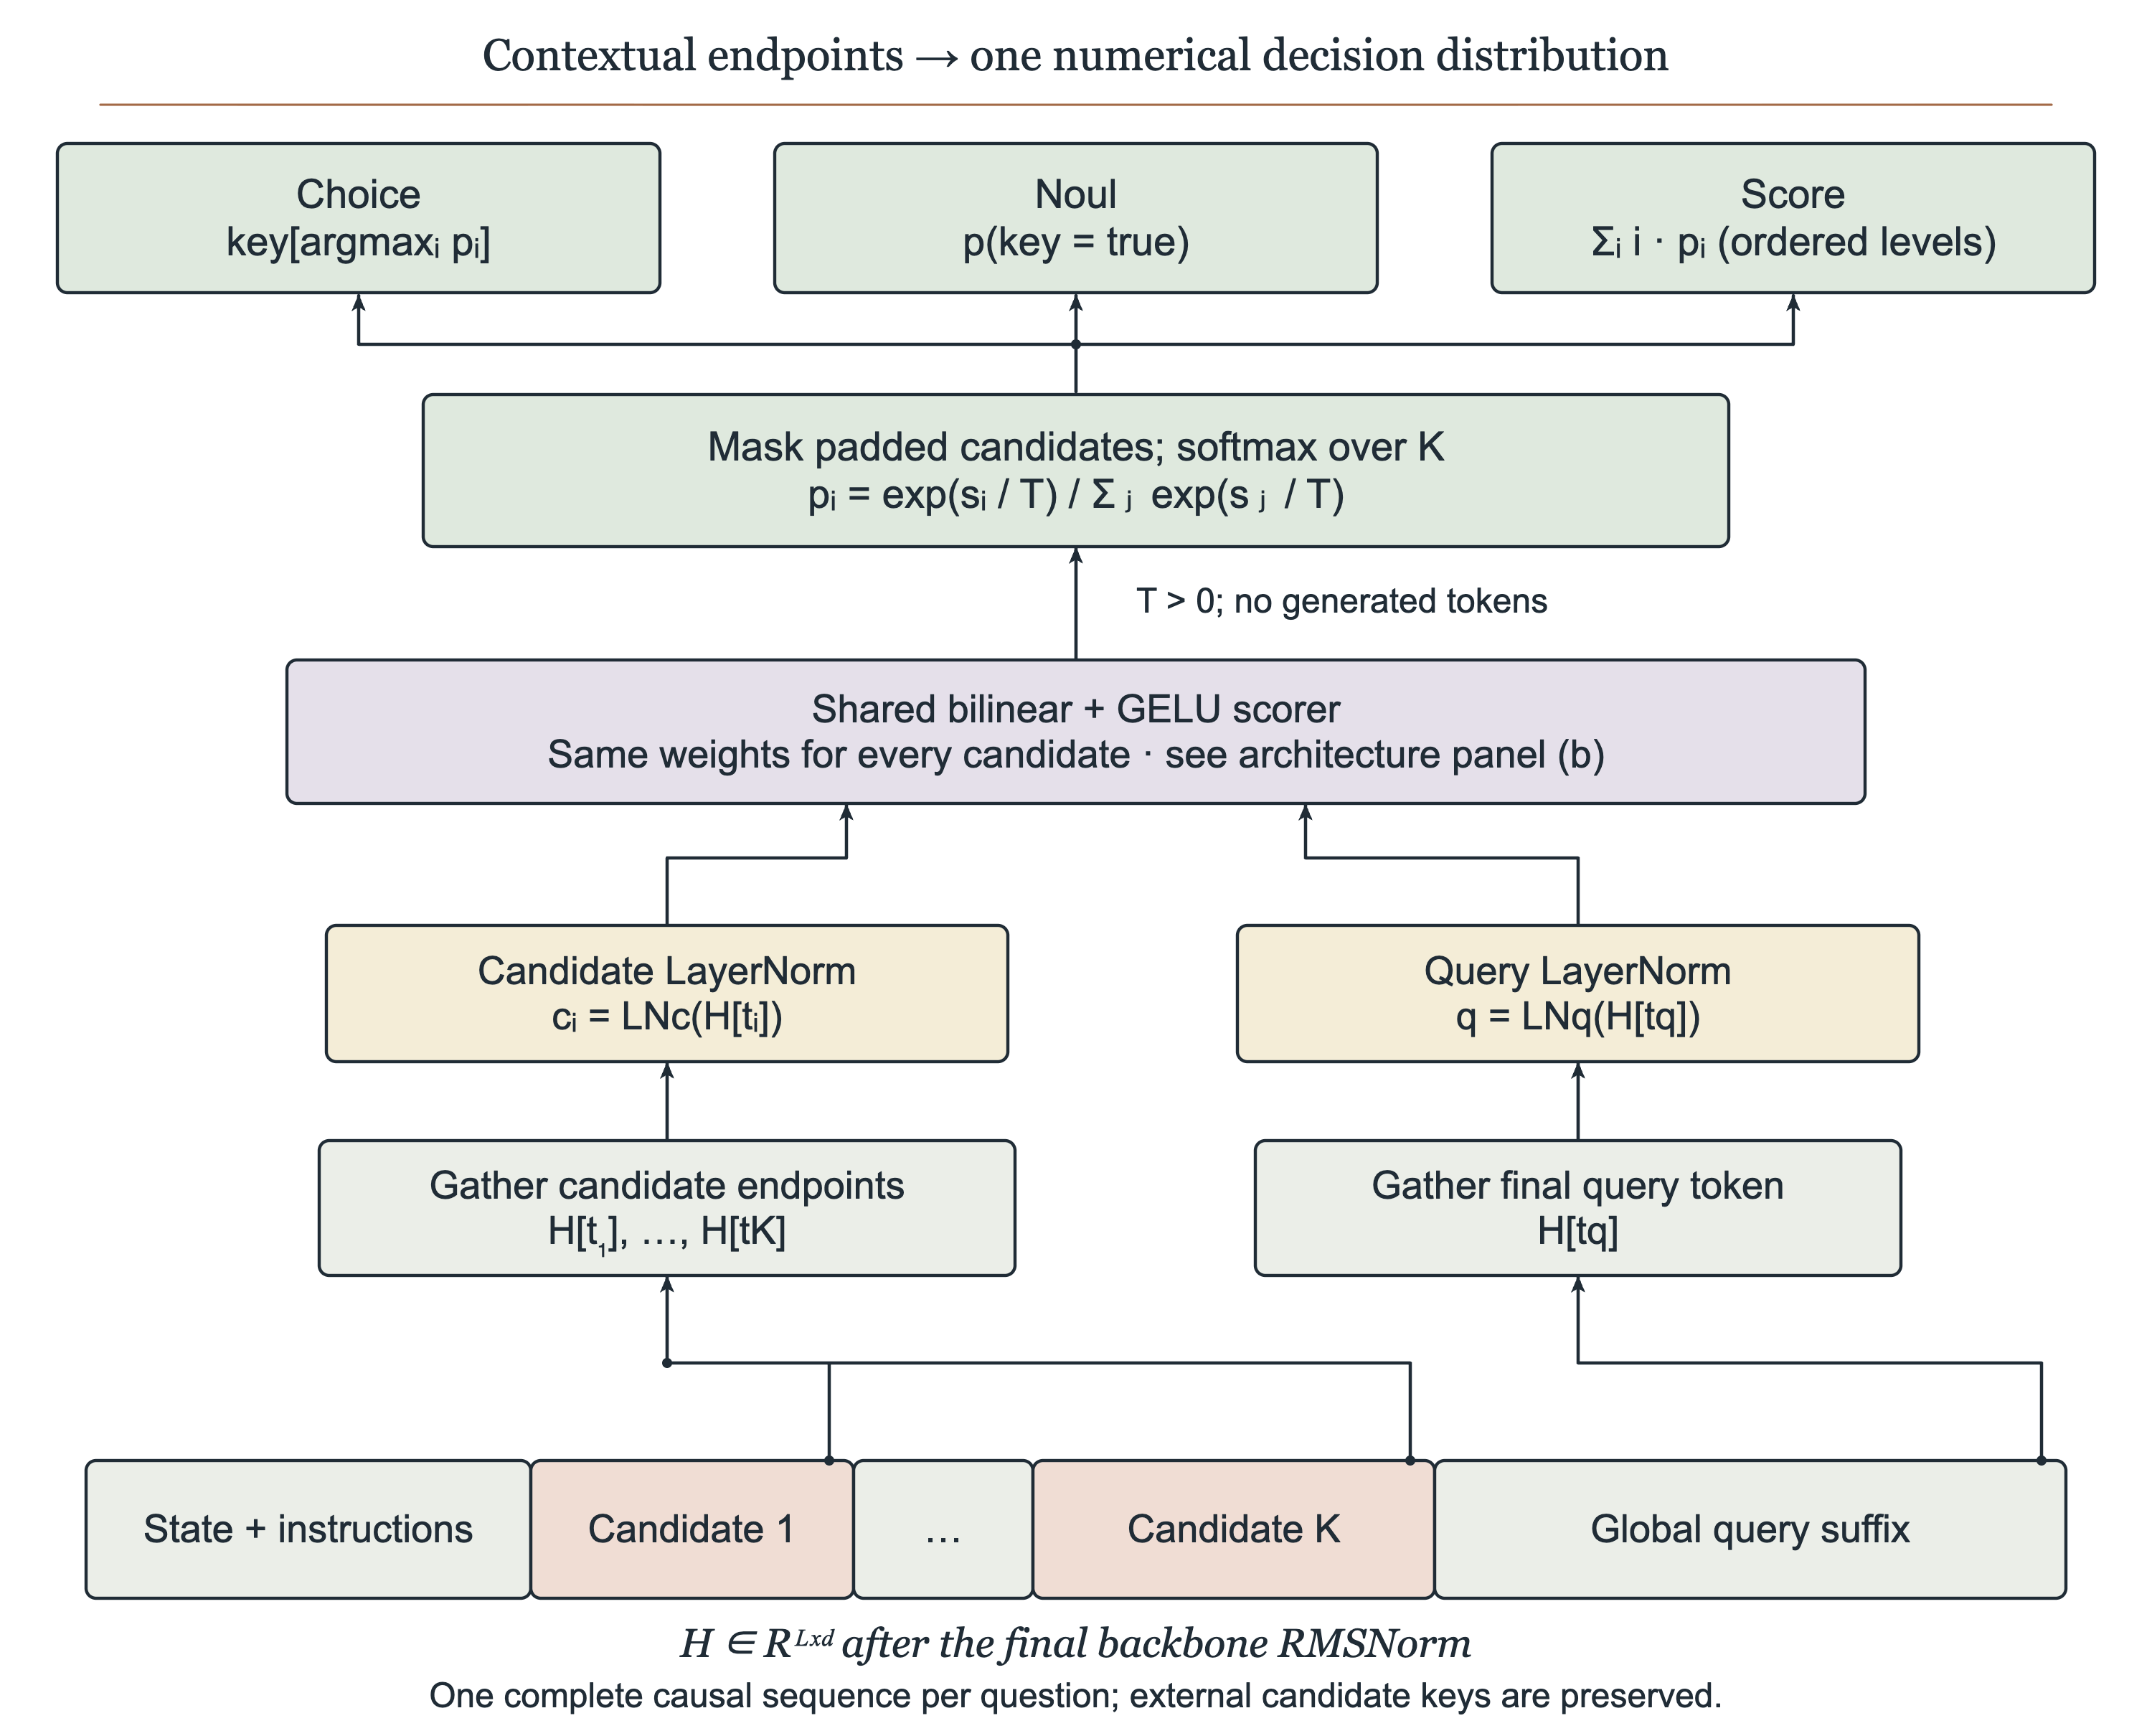
|
Git LFS Details
|
assets/readout.svg
ADDED
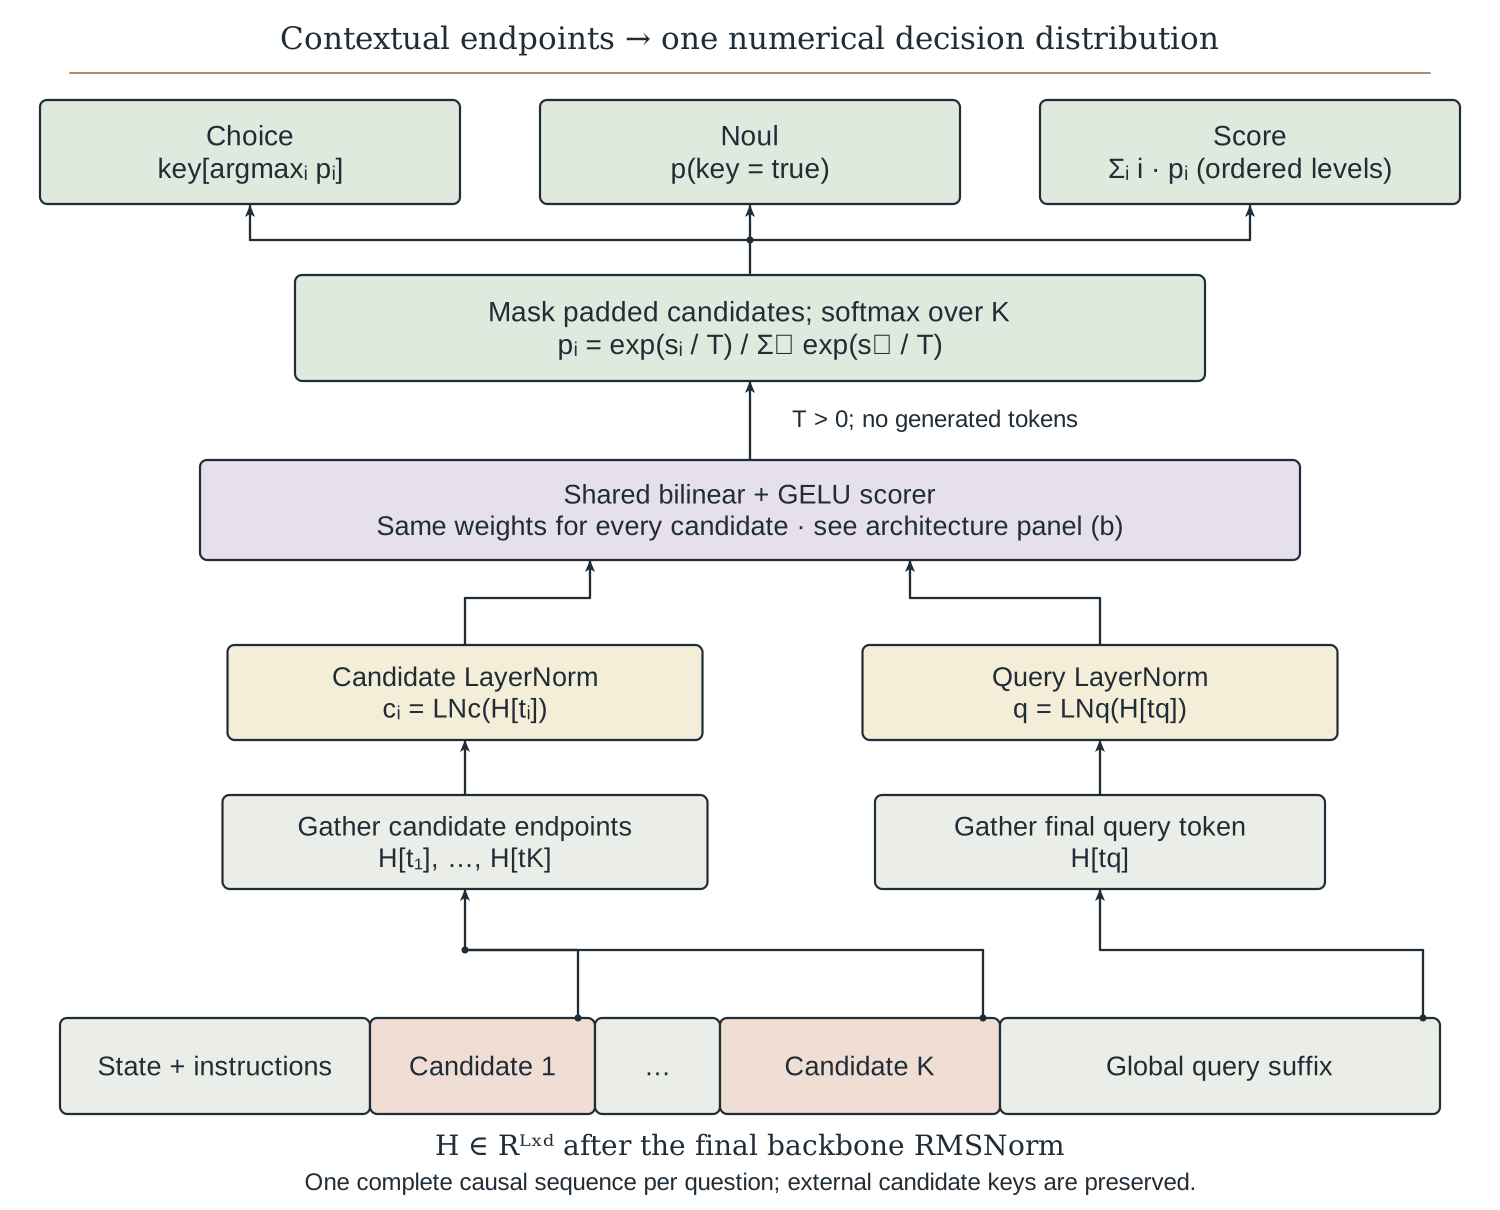
|
backbone/config.json
ADDED
|
@@ -0,0 +1,83 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"architectures": [
|
| 3 |
+
"Qwen3_5TextModel"
|
| 4 |
+
],
|
| 5 |
+
"attention_bias": false,
|
| 6 |
+
"attention_dropout": 0.0,
|
| 7 |
+
"attn_output_gate": true,
|
| 8 |
+
"bos_token_id": null,
|
| 9 |
+
"dtype": "bfloat16",
|
| 10 |
+
"eos_token_id": 248044,
|
| 11 |
+
"full_attention_interval": 4,
|
| 12 |
+
"head_dim": 256,
|
| 13 |
+
"hidden_act": "silu",
|
| 14 |
+
"hidden_size": 2560,
|
| 15 |
+
"initializer_range": 0.02,
|
| 16 |
+
"intermediate_size": 9216,
|
| 17 |
+
"layer_types": [
|
| 18 |
+
"linear_attention",
|
| 19 |
+
"linear_attention",
|
| 20 |
+
"linear_attention",
|
| 21 |
+
"full_attention",
|
| 22 |
+
"linear_attention",
|
| 23 |
+
"linear_attention",
|
| 24 |
+
"linear_attention",
|
| 25 |
+
"full_attention",
|
| 26 |
+
"linear_attention",
|
| 27 |
+
"linear_attention",
|
| 28 |
+
"linear_attention",
|
| 29 |
+
"full_attention",
|
| 30 |
+
"linear_attention",
|
| 31 |
+
"linear_attention",
|
| 32 |
+
"linear_attention",
|
| 33 |
+
"full_attention",
|
| 34 |
+
"linear_attention",
|
| 35 |
+
"linear_attention",
|
| 36 |
+
"linear_attention",
|
| 37 |
+
"full_attention",
|
| 38 |
+
"linear_attention",
|
| 39 |
+
"linear_attention",
|
| 40 |
+
"linear_attention",
|
| 41 |
+
"full_attention",
|
| 42 |
+
"linear_attention",
|
| 43 |
+
"linear_attention",
|
| 44 |
+
"linear_attention",
|
| 45 |
+
"full_attention",
|
| 46 |
+
"linear_attention",
|
| 47 |
+
"linear_attention",
|
| 48 |
+
"linear_attention",
|
| 49 |
+
"full_attention"
|
| 50 |
+
],
|
| 51 |
+
"linear_conv_kernel_dim": 4,
|
| 52 |
+
"linear_key_head_dim": 128,
|
| 53 |
+
"linear_num_key_heads": 16,
|
| 54 |
+
"linear_num_value_heads": 32,
|
| 55 |
+
"linear_value_head_dim": 128,
|
| 56 |
+
"mamba_ssm_dtype": "float32",
|
| 57 |
+
"max_position_embeddings": 262144,
|
| 58 |
+
"mlp_only_layers": [],
|
| 59 |
+
"model_type": "qwen3_5_text",
|
| 60 |
+
"mtp_num_hidden_layers": 1,
|
| 61 |
+
"mtp_use_dedicated_embeddings": false,
|
| 62 |
+
"num_attention_heads": 16,
|
| 63 |
+
"num_hidden_layers": 32,
|
| 64 |
+
"num_key_value_heads": 4,
|
| 65 |
+
"pad_token_id": null,
|
| 66 |
+
"partial_rotary_factor": 0.25,
|
| 67 |
+
"rms_norm_eps": 1e-06,
|
| 68 |
+
"rope_parameters": {
|
| 69 |
+
"mrope_interleaved": true,
|
| 70 |
+
"mrope_section": [
|
| 71 |
+
11,
|
| 72 |
+
11,
|
| 73 |
+
10
|
| 74 |
+
],
|
| 75 |
+
"partial_rotary_factor": 0.25,
|
| 76 |
+
"rope_theta": 10000000,
|
| 77 |
+
"rope_type": "default"
|
| 78 |
+
},
|
| 79 |
+
"tie_word_embeddings": true,
|
| 80 |
+
"transformers_version": "5.17.0",
|
| 81 |
+
"use_cache": false,
|
| 82 |
+
"vocab_size": 248320
|
| 83 |
+
}
|
backbone/model-00001-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5162db199021e5507c0bfd7ea0fb8ee7126392e84a2e6578ed9e5e032fa03024
|
| 3 |
+
size 3991295368
|
backbone/model-00002-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:f994436085feea7a0fe18bed4fcb00e12e449daaea1021dab0accdc7c0107114
|
| 3 |
+
size 3979828128
|
backbone/model-00003-of-00003.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a34a119d6438cbb87578370fa64a6b938a2f2b4fe462cfd4badf52b5d0b8ffe2
|
| 3 |
+
size 440425856
|
backbone/model.safetensors.index.json
ADDED
|
@@ -0,0 +1,434 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"metadata": {
|
| 3 |
+
"total_parameters": 4205751296,
|
| 4 |
+
"total_size": 8411502592
|
| 5 |
+
},
|
| 6 |
+
"weight_map": {
|
| 7 |
+
"embed_tokens.weight": "model-00001-of-00003.safetensors",
|
| 8 |
+
"layers.0.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 9 |
+
"layers.0.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 10 |
+
"layers.0.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 11 |
+
"layers.0.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 12 |
+
"layers.0.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 13 |
+
"layers.0.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 14 |
+
"layers.0.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 15 |
+
"layers.0.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 16 |
+
"layers.0.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 17 |
+
"layers.0.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 18 |
+
"layers.0.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 19 |
+
"layers.0.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 20 |
+
"layers.0.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 21 |
+
"layers.0.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 22 |
+
"layers.1.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 23 |
+
"layers.1.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 24 |
+
"layers.1.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 25 |
+
"layers.1.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 26 |
+
"layers.1.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 27 |
+
"layers.1.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 28 |
+
"layers.1.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 29 |
+
"layers.1.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 30 |
+
"layers.1.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 31 |
+
"layers.1.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 32 |
+
"layers.1.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 33 |
+
"layers.1.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 34 |
+
"layers.1.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 35 |
+
"layers.1.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 36 |
+
"layers.10.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 37 |
+
"layers.10.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 38 |
+
"layers.10.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 39 |
+
"layers.10.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 40 |
+
"layers.10.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 41 |
+
"layers.10.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 42 |
+
"layers.10.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 43 |
+
"layers.10.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 44 |
+
"layers.10.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 45 |
+
"layers.10.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 46 |
+
"layers.10.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 47 |
+
"layers.10.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 48 |
+
"layers.10.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 49 |
+
"layers.10.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 50 |
+
"layers.11.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 51 |
+
"layers.11.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 52 |
+
"layers.11.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 53 |
+
"layers.11.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 54 |
+
"layers.11.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 55 |
+
"layers.11.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 56 |
+
"layers.11.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 57 |
+
"layers.11.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 58 |
+
"layers.11.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 59 |
+
"layers.11.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 60 |
+
"layers.11.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 61 |
+
"layers.12.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 62 |
+
"layers.12.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 63 |
+
"layers.12.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 64 |
+
"layers.12.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 65 |
+
"layers.12.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 66 |
+
"layers.12.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 67 |
+
"layers.12.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 68 |
+
"layers.12.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 69 |
+
"layers.12.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 70 |
+
"layers.12.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 71 |
+
"layers.12.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 72 |
+
"layers.12.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 73 |
+
"layers.12.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 74 |
+
"layers.12.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 75 |
+
"layers.13.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 76 |
+
"layers.13.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 77 |
+
"layers.13.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 78 |
+
"layers.13.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 79 |
+
"layers.13.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 80 |
+
"layers.13.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 81 |
+
"layers.13.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 82 |
+
"layers.13.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 83 |
+
"layers.13.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 84 |
+
"layers.13.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 85 |
+
"layers.13.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 86 |
+
"layers.13.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 87 |
+
"layers.13.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 88 |
+
"layers.13.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 89 |
+
"layers.14.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 90 |
+
"layers.14.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 91 |
+
"layers.14.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 92 |
+
"layers.14.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 93 |
+
"layers.14.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 94 |
+
"layers.14.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 95 |
+
"layers.14.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 96 |
+
"layers.14.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 97 |
+
"layers.14.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 98 |
+
"layers.14.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 99 |
+
"layers.14.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 100 |
+
"layers.14.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 101 |
+
"layers.14.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 102 |
+
"layers.14.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 103 |
+
"layers.15.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 104 |
+
"layers.15.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 105 |
+
"layers.15.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 106 |
+
"layers.15.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 107 |
+
"layers.15.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 108 |
+
"layers.15.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 109 |
+
"layers.15.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 110 |
+
"layers.15.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 111 |
+
"layers.15.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 112 |
+
"layers.15.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 113 |
+
"layers.15.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 114 |
+
"layers.16.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 115 |
+
"layers.16.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 116 |
+
"layers.16.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 117 |
+
"layers.16.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 118 |
+
"layers.16.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 119 |
+
"layers.16.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 120 |
+
"layers.16.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 121 |
+
"layers.16.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 122 |
+
"layers.16.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 123 |
+
"layers.16.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 124 |
+
"layers.16.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 125 |
+
"layers.16.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 126 |
+
"layers.16.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 127 |
+
"layers.16.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 128 |
+
"layers.17.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 129 |
+
"layers.17.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 130 |
+
"layers.17.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 131 |
+
"layers.17.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 132 |
+
"layers.17.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 133 |
+
"layers.17.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 134 |
+
"layers.17.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 135 |
+
"layers.17.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 136 |
+
"layers.17.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 137 |
+
"layers.17.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 138 |
+
"layers.17.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 139 |
+
"layers.17.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 140 |
+
"layers.17.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 141 |
+
"layers.17.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 142 |
+
"layers.18.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 143 |
+
"layers.18.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 144 |
+
"layers.18.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 145 |
+
"layers.18.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 146 |
+
"layers.18.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 147 |
+
"layers.18.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 148 |
+
"layers.18.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 149 |
+
"layers.18.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 150 |
+
"layers.18.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 151 |
+
"layers.18.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 152 |
+
"layers.18.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 153 |
+
"layers.18.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 154 |
+
"layers.18.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 155 |
+
"layers.18.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 156 |
+
"layers.19.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 157 |
+
"layers.19.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 158 |
+
"layers.19.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 159 |
+
"layers.19.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 160 |
+
"layers.19.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 161 |
+
"layers.19.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 162 |
+
"layers.19.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 163 |
+
"layers.19.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 164 |
+
"layers.19.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 165 |
+
"layers.19.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 166 |
+
"layers.19.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 167 |
+
"layers.2.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 168 |
+
"layers.2.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 169 |
+
"layers.2.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 170 |
+
"layers.2.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 171 |
+
"layers.2.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 172 |
+
"layers.2.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 173 |
+
"layers.2.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 174 |
+
"layers.2.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 175 |
+
"layers.2.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 176 |
+
"layers.2.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 177 |
+
"layers.2.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 178 |
+
"layers.2.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 179 |
+
"layers.2.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 180 |
+
"layers.2.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 181 |
+
"layers.20.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 182 |
+
"layers.20.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 183 |
+
"layers.20.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 184 |
+
"layers.20.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 185 |
+
"layers.20.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 186 |
+
"layers.20.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 187 |
+
"layers.20.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 188 |
+
"layers.20.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 189 |
+
"layers.20.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 190 |
+
"layers.20.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 191 |
+
"layers.20.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 192 |
+
"layers.20.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 193 |
+
"layers.20.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 194 |
+
"layers.20.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 195 |
+
"layers.21.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 196 |
+
"layers.21.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 197 |
+
"layers.21.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 198 |
+
"layers.21.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 199 |
+
"layers.21.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 200 |
+
"layers.21.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 201 |
+
"layers.21.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 202 |
+
"layers.21.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 203 |
+
"layers.21.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 204 |
+
"layers.21.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 205 |
+
"layers.21.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 206 |
+
"layers.21.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 207 |
+
"layers.21.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 208 |
+
"layers.21.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 209 |
+
"layers.22.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 210 |
+
"layers.22.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 211 |
+
"layers.22.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 212 |
+
"layers.22.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 213 |
+
"layers.22.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 214 |
+
"layers.22.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 215 |
+
"layers.22.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 216 |
+
"layers.22.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 217 |
+
"layers.22.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 218 |
+
"layers.22.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 219 |
+
"layers.22.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 220 |
+
"layers.22.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 221 |
+
"layers.22.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 222 |
+
"layers.22.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 223 |
+
"layers.23.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 224 |
+
"layers.23.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 225 |
+
"layers.23.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 226 |
+
"layers.23.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 227 |
+
"layers.23.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 228 |
+
"layers.23.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 229 |
+
"layers.23.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 230 |
+
"layers.23.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 231 |
+
"layers.23.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 232 |
+
"layers.23.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 233 |
+
"layers.23.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 234 |
+
"layers.24.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 235 |
+
"layers.24.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 236 |
+
"layers.24.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 237 |
+
"layers.24.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 238 |
+
"layers.24.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 239 |
+
"layers.24.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 240 |
+
"layers.24.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 241 |
+
"layers.24.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 242 |
+
"layers.24.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 243 |
+
"layers.24.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 244 |
+
"layers.24.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 245 |
+
"layers.24.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 246 |
+
"layers.24.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 247 |
+
"layers.24.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 248 |
+
"layers.25.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 249 |
+
"layers.25.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 250 |
+
"layers.25.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 251 |
+
"layers.25.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 252 |
+
"layers.25.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 253 |
+
"layers.25.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 254 |
+
"layers.25.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 255 |
+
"layers.25.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 256 |
+
"layers.25.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 257 |
+
"layers.25.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 258 |
+
"layers.25.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 259 |
+
"layers.25.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 260 |
+
"layers.25.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 261 |
+
"layers.25.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 262 |
+
"layers.26.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 263 |
+
"layers.26.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 264 |
+
"layers.26.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 265 |
+
"layers.26.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 266 |
+
"layers.26.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 267 |
+
"layers.26.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 268 |
+
"layers.26.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 269 |
+
"layers.26.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 270 |
+
"layers.26.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 271 |
+
"layers.26.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 272 |
+
"layers.26.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 273 |
+
"layers.26.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 274 |
+
"layers.26.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 275 |
+
"layers.26.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 276 |
+
"layers.27.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 277 |
+
"layers.27.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 278 |
+
"layers.27.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 279 |
+
"layers.27.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 280 |
+
"layers.27.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 281 |
+
"layers.27.self_attn.k_norm.weight": "model-00002-of-00003.safetensors",
|
| 282 |
+
"layers.27.self_attn.k_proj.weight": "model-00002-of-00003.safetensors",
|
| 283 |
+
"layers.27.self_attn.o_proj.weight": "model-00002-of-00003.safetensors",
|
| 284 |
+
"layers.27.self_attn.q_norm.weight": "model-00002-of-00003.safetensors",
|
| 285 |
+
"layers.27.self_attn.q_proj.weight": "model-00002-of-00003.safetensors",
|
| 286 |
+
"layers.27.self_attn.v_proj.weight": "model-00002-of-00003.safetensors",
|
| 287 |
+
"layers.28.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 288 |
+
"layers.28.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 289 |
+
"layers.28.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 290 |
+
"layers.28.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 291 |
+
"layers.28.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 292 |
+
"layers.28.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 293 |
+
"layers.28.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 294 |
+
"layers.28.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 295 |
+
"layers.28.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 296 |
+
"layers.28.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 297 |
+
"layers.28.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 298 |
+
"layers.28.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 299 |
+
"layers.28.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 300 |
+
"layers.28.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 301 |
+
"layers.29.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 302 |
+
"layers.29.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 303 |
+
"layers.29.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 304 |
+
"layers.29.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 305 |
+
"layers.29.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 306 |
+
"layers.29.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 307 |
+
"layers.29.linear_attn.in_proj_qkv.weight": "model-00002-of-00003.safetensors",
|
| 308 |
+
"layers.29.linear_attn.in_proj_z.weight": "model-00002-of-00003.safetensors",
|
| 309 |
+
"layers.29.linear_attn.norm.weight": "model-00002-of-00003.safetensors",
|
| 310 |
+
"layers.29.linear_attn.out_proj.weight": "model-00002-of-00003.safetensors",
|
| 311 |
+
"layers.29.mlp.down_proj.weight": "model-00002-of-00003.safetensors",
|
| 312 |
+
"layers.29.mlp.gate_proj.weight": "model-00002-of-00003.safetensors",
|
| 313 |
+
"layers.29.mlp.up_proj.weight": "model-00002-of-00003.safetensors",
|
| 314 |
+
"layers.29.post_attention_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 315 |
+
"layers.3.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 316 |
+
"layers.3.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 317 |
+
"layers.3.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 318 |
+
"layers.3.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 319 |
+
"layers.3.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 320 |
+
"layers.3.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 321 |
+
"layers.3.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 322 |
+
"layers.3.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 323 |
+
"layers.3.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 324 |
+
"layers.3.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 325 |
+
"layers.3.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 326 |
+
"layers.30.input_layernorm.weight": "model-00002-of-00003.safetensors",
|
| 327 |
+
"layers.30.linear_attn.A_log": "model-00002-of-00003.safetensors",
|
| 328 |
+
"layers.30.linear_attn.conv1d.weight": "model-00002-of-00003.safetensors",
|
| 329 |
+
"layers.30.linear_attn.dt_bias": "model-00002-of-00003.safetensors",
|
| 330 |
+
"layers.30.linear_attn.in_proj_a.weight": "model-00002-of-00003.safetensors",
|
| 331 |
+
"layers.30.linear_attn.in_proj_b.weight": "model-00002-of-00003.safetensors",
|
| 332 |
+
"layers.30.linear_attn.in_proj_qkv.weight": "model-00003-of-00003.safetensors",
|
| 333 |
+
"layers.30.linear_attn.in_proj_z.weight": "model-00003-of-00003.safetensors",
|
| 334 |
+
"layers.30.linear_attn.norm.weight": "model-00003-of-00003.safetensors",
|
| 335 |
+
"layers.30.linear_attn.out_proj.weight": "model-00003-of-00003.safetensors",
|
| 336 |
+
"layers.30.mlp.down_proj.weight": "model-00003-of-00003.safetensors",
|
| 337 |
+
"layers.30.mlp.gate_proj.weight": "model-00003-of-00003.safetensors",
|
| 338 |
+
"layers.30.mlp.up_proj.weight": "model-00003-of-00003.safetensors",
|
| 339 |
+
"layers.30.post_attention_layernorm.weight": "model-00003-of-00003.safetensors",
|
| 340 |
+
"layers.31.input_layernorm.weight": "model-00003-of-00003.safetensors",
|
| 341 |
+
"layers.31.mlp.down_proj.weight": "model-00003-of-00003.safetensors",
|
| 342 |
+
"layers.31.mlp.gate_proj.weight": "model-00003-of-00003.safetensors",
|
| 343 |
+
"layers.31.mlp.up_proj.weight": "model-00003-of-00003.safetensors",
|
| 344 |
+
"layers.31.post_attention_layernorm.weight": "model-00003-of-00003.safetensors",
|
| 345 |
+
"layers.31.self_attn.k_norm.weight": "model-00003-of-00003.safetensors",
|
| 346 |
+
"layers.31.self_attn.k_proj.weight": "model-00003-of-00003.safetensors",
|
| 347 |
+
"layers.31.self_attn.o_proj.weight": "model-00003-of-00003.safetensors",
|
| 348 |
+
"layers.31.self_attn.q_norm.weight": "model-00003-of-00003.safetensors",
|
| 349 |
+
"layers.31.self_attn.q_proj.weight": "model-00003-of-00003.safetensors",
|
| 350 |
+
"layers.31.self_attn.v_proj.weight": "model-00003-of-00003.safetensors",
|
| 351 |
+
"layers.4.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 352 |
+
"layers.4.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 353 |
+
"layers.4.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 354 |
+
"layers.4.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 355 |
+
"layers.4.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 356 |
+
"layers.4.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 357 |
+
"layers.4.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 358 |
+
"layers.4.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 359 |
+
"layers.4.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 360 |
+
"layers.4.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 361 |
+
"layers.4.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 362 |
+
"layers.4.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 363 |
+
"layers.4.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 364 |
+
"layers.4.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 365 |
+
"layers.5.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 366 |
+
"layers.5.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 367 |
+
"layers.5.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 368 |
+
"layers.5.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 369 |
+
"layers.5.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 370 |
+
"layers.5.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 371 |
+
"layers.5.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 372 |
+
"layers.5.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 373 |
+
"layers.5.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 374 |
+
"layers.5.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 375 |
+
"layers.5.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 376 |
+
"layers.5.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 377 |
+
"layers.5.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 378 |
+
"layers.5.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 379 |
+
"layers.6.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 380 |
+
"layers.6.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 381 |
+
"layers.6.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 382 |
+
"layers.6.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 383 |
+
"layers.6.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 384 |
+
"layers.6.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 385 |
+
"layers.6.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 386 |
+
"layers.6.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 387 |
+
"layers.6.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 388 |
+
"layers.6.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 389 |
+
"layers.6.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 390 |
+
"layers.6.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 391 |
+
"layers.6.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 392 |
+
"layers.6.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 393 |
+
"layers.7.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 394 |
+
"layers.7.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 395 |
+
"layers.7.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 396 |
+
"layers.7.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 397 |
+
"layers.7.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 398 |
+
"layers.7.self_attn.k_norm.weight": "model-00001-of-00003.safetensors",
|
| 399 |
+
"layers.7.self_attn.k_proj.weight": "model-00001-of-00003.safetensors",
|
| 400 |
+
"layers.7.self_attn.o_proj.weight": "model-00001-of-00003.safetensors",
|
| 401 |
+
"layers.7.self_attn.q_norm.weight": "model-00001-of-00003.safetensors",
|
| 402 |
+
"layers.7.self_attn.q_proj.weight": "model-00001-of-00003.safetensors",
|
| 403 |
+
"layers.7.self_attn.v_proj.weight": "model-00001-of-00003.safetensors",
|
| 404 |
+
"layers.8.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 405 |
+
"layers.8.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 406 |
+
"layers.8.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 407 |
+
"layers.8.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 408 |
+
"layers.8.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 409 |
+
"layers.8.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 410 |
+
"layers.8.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 411 |
+
"layers.8.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 412 |
+
"layers.8.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 413 |
+
"layers.8.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 414 |
+
"layers.8.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 415 |
+
"layers.8.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 416 |
+
"layers.8.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 417 |
+
"layers.8.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 418 |
+
"layers.9.input_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 419 |
+
"layers.9.linear_attn.A_log": "model-00001-of-00003.safetensors",
|
| 420 |
+
"layers.9.linear_attn.conv1d.weight": "model-00001-of-00003.safetensors",
|
| 421 |
+
"layers.9.linear_attn.dt_bias": "model-00001-of-00003.safetensors",
|
| 422 |
+
"layers.9.linear_attn.in_proj_a.weight": "model-00001-of-00003.safetensors",
|
| 423 |
+
"layers.9.linear_attn.in_proj_b.weight": "model-00001-of-00003.safetensors",
|
| 424 |
+
"layers.9.linear_attn.in_proj_qkv.weight": "model-00001-of-00003.safetensors",
|
| 425 |
+
"layers.9.linear_attn.in_proj_z.weight": "model-00001-of-00003.safetensors",
|
| 426 |
+
"layers.9.linear_attn.norm.weight": "model-00001-of-00003.safetensors",
|
| 427 |
+
"layers.9.linear_attn.out_proj.weight": "model-00001-of-00003.safetensors",
|
| 428 |
+
"layers.9.mlp.down_proj.weight": "model-00001-of-00003.safetensors",
|
| 429 |
+
"layers.9.mlp.gate_proj.weight": "model-00001-of-00003.safetensors",
|
| 430 |
+
"layers.9.mlp.up_proj.weight": "model-00001-of-00003.safetensors",
|
| 431 |
+
"layers.9.post_attention_layernorm.weight": "model-00001-of-00003.safetensors",
|
| 432 |
+
"norm.weight": "model-00003-of-00003.safetensors"
|
| 433 |
+
}
|
| 434 |
+
}
|
bundle-manifest.json
ADDED
|
@@ -0,0 +1,173 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "research-pointer-bundle-v1",
|
| 3 |
+
"status": "candidate-export-awaiting-independent-reload-and-quality-gates",
|
| 4 |
+
"files": [
|
| 5 |
+
{
|
| 6 |
+
"file": "backbone/config.json",
|
| 7 |
+
"bytes": 1978,
|
| 8 |
+
"sha256": "ae3a463b32e95b6cc207a7af4f1defb4195f388eb6f9ff19d2690b73d4966953"
|
| 9 |
+
},
|
| 10 |
+
{
|
| 11 |
+
"file": "backbone/model-00001-of-00003.safetensors",
|
| 12 |
+
"bytes": 3991295368,
|
| 13 |
+
"sha256": "5162db199021e5507c0bfd7ea0fb8ee7126392e84a2e6578ed9e5e032fa03024"
|
| 14 |
+
},
|
| 15 |
+
{
|
| 16 |
+
"file": "backbone/model-00002-of-00003.safetensors",
|
| 17 |
+
"bytes": 3979828128,
|
| 18 |
+
"sha256": "f994436085feea7a0fe18bed4fcb00e12e449daaea1021dab0accdc7c0107114"
|
| 19 |
+
},
|
| 20 |
+
{
|
| 21 |
+
"file": "backbone/model-00003-of-00003.safetensors",
|
| 22 |
+
"bytes": 440425856,
|
| 23 |
+
"sha256": "a34a119d6438cbb87578370fa64a6b938a2f2b4fe462cfd4badf52b5d0b8ffe2"
|
| 24 |
+
},
|
| 25 |
+
{
|
| 26 |
+
"file": "backbone/model.safetensors.index.json",
|
| 27 |
+
"bytes": 33047,
|
| 28 |
+
"sha256": "1602d52e38d81586af85bc4ce29ce082c5fc5877c763b1ebcab7545320016599"
|
| 29 |
+
},
|
| 30 |
+
{
|
| 31 |
+
"file": "chat_template.jinja",
|
| 32 |
+
"bytes": 7756,
|
| 33 |
+
"sha256": "a4aee8afcf2e0711942cf848899be66016f8d14a889ff9ede07bca099c28f715"
|
| 34 |
+
},
|
| 35 |
+
{
|
| 36 |
+
"file": "code/decision_api.py",
|
| 37 |
+
"bytes": 6724,
|
| 38 |
+
"sha256": "147b2fec32cbbbbb1b92cf2a19bb887f9d945e4974e141ca7ea93b8c542f5b21"
|
| 39 |
+
},
|
| 40 |
+
{
|
| 41 |
+
"file": "code/decision_model.py",
|
| 42 |
+
"bytes": 10114,
|
| 43 |
+
"sha256": "d3e28489c09f3bd7130e2d43d92e0b5c4a08e25b09b21303904defb0ff1c3646"
|
| 44 |
+
},
|
| 45 |
+
{
|
| 46 |
+
"file": "code/predict.py",
|
| 47 |
+
"bytes": 3164,
|
| 48 |
+
"sha256": "02352e8385ab47157b6459910da54d962e5da4bb4940d571faedc86bc5da9aee"
|
| 49 |
+
},
|
| 50 |
+
{
|
| 51 |
+
"file": "decision_config.json",
|
| 52 |
+
"bytes": 753,
|
| 53 |
+
"sha256": "443a9b3f191a8387915c606de8303700fc1a069fe7c8ad46a0eba5528a2549a8"
|
| 54 |
+
},
|
| 55 |
+
{
|
| 56 |
+
"file": "decision_head.safetensors",
|
| 57 |
+
"bytes": 10529624,
|
| 58 |
+
"sha256": "751dc1ceb4ea9cea2d3154f9eafe49e61a993f57e22b7b890f5f982c98043c9c"
|
| 59 |
+
},
|
| 60 |
+
{
|
| 61 |
+
"file": "runtime.json",
|
| 62 |
+
"bytes": 952,
|
| 63 |
+
"sha256": "7ed527476826756d6076f23d0eaa8b4b53ff34b9f8bd57ae8e65b50e4d28cfa6"
|
| 64 |
+
},
|
| 65 |
+
{
|
| 66 |
+
"file": "temperature.json",
|
| 67 |
+
"bytes": 668,
|
| 68 |
+
"sha256": "f45db64f2b58f1dd3b3f7af4adaee79935a57daac0976ee77a28191ed3454865"
|
| 69 |
+
},
|
| 70 |
+
{
|
| 71 |
+
"file": "tokenizer.json",
|
| 72 |
+
"bytes": 19989325,
|
| 73 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523"
|
| 74 |
+
},
|
| 75 |
+
{
|
| 76 |
+
"file": "tokenizer_config.json",
|
| 77 |
+
"bytes": 1123,
|
| 78 |
+
"sha256": "bee8eba30f0eb4af73c0fe2cd06d0f89b657d7819941c438157ec42f7c80ea87"
|
| 79 |
+
}
|
| 80 |
+
],
|
| 81 |
+
"tensors": [
|
| 82 |
+
{
|
| 83 |
+
"file": "backbone/model-00001-of-00003.safetensors",
|
| 84 |
+
"elements": 1995638528,
|
| 85 |
+
"elements_by_dtype": {
|
| 86 |
+
"BF16": 1995638528
|
| 87 |
+
}
|
| 88 |
+
},
|
| 89 |
+
{
|
| 90 |
+
"file": "backbone/model-00002-of-00003.safetensors",
|
| 91 |
+
"elements": 1989900928,
|
| 92 |
+
"elements_by_dtype": {
|
| 93 |
+
"BF16": 1989900928
|
| 94 |
+
}
|
| 95 |
+
},
|
| 96 |
+
{
|
| 97 |
+
"file": "backbone/model-00003-of-00003.safetensors",
|
| 98 |
+
"elements": 220211840,
|
| 99 |
+
"elements_by_dtype": {
|
| 100 |
+
"BF16": 220211840
|
| 101 |
+
}
|
| 102 |
+
},
|
| 103 |
+
{
|
| 104 |
+
"file": "decision_head.safetensors",
|
| 105 |
+
"elements": 2632192,
|
| 106 |
+
"elements_by_dtype": {
|
| 107 |
+
"F32": 2632192
|
| 108 |
+
}
|
| 109 |
+
}
|
| 110 |
+
],
|
| 111 |
+
"source_checkpoint_files": [
|
| 112 |
+
{
|
| 113 |
+
"file": "backbone/config.json",
|
| 114 |
+
"bytes": 1977,
|
| 115 |
+
"sha256": "a5ed4156fda05f0f9149c66964d6165916754e7355488a8a07d9b0398acdbdb9"
|
| 116 |
+
},
|
| 117 |
+
{
|
| 118 |
+
"file": "backbone/model-00001-of-00005.safetensors",
|
| 119 |
+
"bytes": 3992269864,
|
| 120 |
+
"sha256": "9f69abec2eacbbebcd072d50f8dd08027ab738e0c5e57941e3da8b6a251f11de"
|
| 121 |
+
},
|
| 122 |
+
{
|
| 123 |
+
"file": "backbone/model-00002-of-00005.safetensors",
|
| 124 |
+
"bytes": 3990302320,
|
| 125 |
+
"sha256": "d98bdca173c023e7d5db16ebe18f04692297974e58c201c2137dc13200a95ef8"
|
| 126 |
+
},
|
| 127 |
+
{
|
| 128 |
+
"file": "backbone/model-00003-of-00005.safetensors",
|
| 129 |
+
"bytes": 3937871784,
|
| 130 |
+
"sha256": "4ad308b67e58f1342fa2a3f20a30d3917f6426c03792225e3bf2c950caeaec1e"
|
| 131 |
+
},
|
| 132 |
+
{
|
| 133 |
+
"file": "backbone/model-00004-of-00005.safetensors",
|
| 134 |
+
"bytes": 3926578128,
|
| 135 |
+
"sha256": "3428bff4f127cf725fdee2627475994595fffa5b179032c8295be254e800f8c7"
|
| 136 |
+
},
|
| 137 |
+
{
|
| 138 |
+
"file": "backbone/model-00005-of-00005.safetensors",
|
| 139 |
+
"bytes": 976029360,
|
| 140 |
+
"sha256": "f2ee4a3f3f74bcc8502e283cbba296b6a2ae6d9dad9866a80eb37e5152b9b059"
|
| 141 |
+
},
|
| 142 |
+
{
|
| 143 |
+
"file": "decision_config.json",
|
| 144 |
+
"bytes": 1118,
|
| 145 |
+
"sha256": "69deec6c1f35641267510f25aaf099abfe31d3c880e2e0caa730b78e3541f889"
|
| 146 |
+
},
|
| 147 |
+
{
|
| 148 |
+
"file": "decision_head.safetensors",
|
| 149 |
+
"bytes": 10529624,
|
| 150 |
+
"sha256": "751dc1ceb4ea9cea2d3154f9eafe49e61a993f57e22b7b890f5f982c98043c9c"
|
| 151 |
+
},
|
| 152 |
+
{
|
| 153 |
+
"file": "tokenizer.json",
|
| 154 |
+
"bytes": 19989325,
|
| 155 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523"
|
| 156 |
+
},
|
| 157 |
+
{
|
| 158 |
+
"file": "tokenizer_config.json",
|
| 159 |
+
"bytes": 1123,
|
| 160 |
+
"sha256": "bee8eba30f0eb4af73c0fe2cd06d0f89b657d7819941c438157ec42f7c80ea87"
|
| 161 |
+
}
|
| 162 |
+
],
|
| 163 |
+
"source_model_code_sha256": "d3e28489c09f3bd7130e2d43d92e0b5c4a08e25b09b21303904defb0ff1c3646",
|
| 164 |
+
"source_api_code_sha256": "147b2fec32cbbbbb1b92cf2a19bb887f9d945e4974e141ca7ea93b8c542f5b21",
|
| 165 |
+
"dev_sha256": "a38f9be168553d5a82a91991aca86aaa602e1951957bac7c475abcec8dcc232d",
|
| 166 |
+
"production_predictions_sha256": "25281339c318c1646f2771c4705c1e1da544bb901f9124f5812b04fcaacb4e9d",
|
| 167 |
+
"temperature_sha256": "f45db64f2b58f1dd3b3f7af4adaee79935a57daac0976ee77a28191ed3454865",
|
| 168 |
+
"runtime_sha256": "7ed527476826756d6076f23d0eaa8b4b53ff34b9f8bd57ae8e65b50e4d28cfa6",
|
| 169 |
+
"production_batch_size": 8,
|
| 170 |
+
"input_length_limit": 16384,
|
| 171 |
+
"original_checkpoint_name": "checkpoint-000800",
|
| 172 |
+
"no_publication_performed": true
|
| 173 |
+
}
|
chat_template.jinja
ADDED
|
@@ -0,0 +1,154 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{%- set image_count = namespace(value=0) %}
|
| 2 |
+
{%- set video_count = namespace(value=0) %}
|
| 3 |
+
{%- macro render_content(content, do_vision_count, is_system_content=false) %}
|
| 4 |
+
{%- if content is string %}
|
| 5 |
+
{{- content }}
|
| 6 |
+
{%- elif content is iterable and content is not mapping %}
|
| 7 |
+
{%- for item in content %}
|
| 8 |
+
{%- if 'image' in item or 'image_url' in item or item.type == 'image' %}
|
| 9 |
+
{%- if is_system_content %}
|
| 10 |
+
{{- raise_exception('System message cannot contain images.') }}
|
| 11 |
+
{%- endif %}
|
| 12 |
+
{%- if do_vision_count %}
|
| 13 |
+
{%- set image_count.value = image_count.value + 1 %}
|
| 14 |
+
{%- endif %}
|
| 15 |
+
{%- if add_vision_id %}
|
| 16 |
+
{{- 'Picture ' ~ image_count.value ~ ': ' }}
|
| 17 |
+
{%- endif %}
|
| 18 |
+
{{- '<|vision_start|><|image_pad|><|vision_end|>' }}
|
| 19 |
+
{%- elif 'video' in item or item.type == 'video' %}
|
| 20 |
+
{%- if is_system_content %}
|
| 21 |
+
{{- raise_exception('System message cannot contain videos.') }}
|
| 22 |
+
{%- endif %}
|
| 23 |
+
{%- if do_vision_count %}
|
| 24 |
+
{%- set video_count.value = video_count.value + 1 %}
|
| 25 |
+
{%- endif %}
|
| 26 |
+
{%- if add_vision_id %}
|
| 27 |
+
{{- 'Video ' ~ video_count.value ~ ': ' }}
|
| 28 |
+
{%- endif %}
|
| 29 |
+
{{- '<|vision_start|><|video_pad|><|vision_end|>' }}
|
| 30 |
+
{%- elif 'text' in item %}
|
| 31 |
+
{{- item.text }}
|
| 32 |
+
{%- else %}
|
| 33 |
+
{{- raise_exception('Unexpected item type in content.') }}
|
| 34 |
+
{%- endif %}
|
| 35 |
+
{%- endfor %}
|
| 36 |
+
{%- elif content is none or content is undefined %}
|
| 37 |
+
{{- '' }}
|
| 38 |
+
{%- else %}
|
| 39 |
+
{{- raise_exception('Unexpected content type.') }}
|
| 40 |
+
{%- endif %}
|
| 41 |
+
{%- endmacro %}
|
| 42 |
+
{%- if not messages %}
|
| 43 |
+
{{- raise_exception('No messages provided.') }}
|
| 44 |
+
{%- endif %}
|
| 45 |
+
{%- if tools and tools is iterable and tools is not mapping %}
|
| 46 |
+
{{- '<|im_start|>system\n' }}
|
| 47 |
+
{{- "# Tools\n\nYou have access to the following functions:\n\n<tools>" }}
|
| 48 |
+
{%- for tool in tools %}
|
| 49 |
+
{{- "\n" }}
|
| 50 |
+
{{- tool | tojson }}
|
| 51 |
+
{%- endfor %}
|
| 52 |
+
{{- "\n</tools>" }}
|
| 53 |
+
{{- '\n\nIf you choose to call a function ONLY reply in the following format with NO suffix:\n\n<tool_call>\n<function=example_function_name>\n<parameter=example_parameter_1>\nvalue_1\n</parameter>\n<parameter=example_parameter_2>\nThis is the value for the second parameter\nthat can span\nmultiple lines\n</parameter>\n</function>\n</tool_call>\n\n<IMPORTANT>\nReminder:\n- Function calls MUST follow the specified format: an inner <function=...></function> block must be nested within <tool_call></tool_call> XML tags\n- Required parameters MUST be specified\n- You may provide optional reasoning for your function call in natural language BEFORE the function call, but NOT after\n- If there is no function call available, answer the question like normal with your current knowledge and do not tell the user about function calls\n</IMPORTANT>' }}
|
| 54 |
+
{%- if messages[0].role == 'system' %}
|
| 55 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 56 |
+
{%- if content %}
|
| 57 |
+
{{- '\n\n' + content }}
|
| 58 |
+
{%- endif %}
|
| 59 |
+
{%- endif %}
|
| 60 |
+
{{- '<|im_end|>\n' }}
|
| 61 |
+
{%- else %}
|
| 62 |
+
{%- if messages[0].role == 'system' %}
|
| 63 |
+
{%- set content = render_content(messages[0].content, false, true)|trim %}
|
| 64 |
+
{{- '<|im_start|>system\n' + content + '<|im_end|>\n' }}
|
| 65 |
+
{%- endif %}
|
| 66 |
+
{%- endif %}
|
| 67 |
+
{%- set ns = namespace(multi_step_tool=true, last_query_index=messages|length - 1) %}
|
| 68 |
+
{%- for message in messages[::-1] %}
|
| 69 |
+
{%- set index = (messages|length - 1) - loop.index0 %}
|
| 70 |
+
{%- if ns.multi_step_tool and message.role == "user" %}
|
| 71 |
+
{%- set content = render_content(message.content, false)|trim %}
|
| 72 |
+
{%- if not(content.startswith('<tool_response>') and content.endswith('</tool_response>')) %}
|
| 73 |
+
{%- set ns.multi_step_tool = false %}
|
| 74 |
+
{%- set ns.last_query_index = index %}
|
| 75 |
+
{%- endif %}
|
| 76 |
+
{%- endif %}
|
| 77 |
+
{%- endfor %}
|
| 78 |
+
{%- if ns.multi_step_tool %}
|
| 79 |
+
{{- raise_exception('No user query found in messages.') }}
|
| 80 |
+
{%- endif %}
|
| 81 |
+
{%- for message in messages %}
|
| 82 |
+
{%- set content = render_content(message.content, true)|trim %}
|
| 83 |
+
{%- if message.role == "system" %}
|
| 84 |
+
{%- if not loop.first %}
|
| 85 |
+
{{- raise_exception('System message must be at the beginning.') }}
|
| 86 |
+
{%- endif %}
|
| 87 |
+
{%- elif message.role == "user" %}
|
| 88 |
+
{{- '<|im_start|>' + message.role + '\n' + content + '<|im_end|>' + '\n' }}
|
| 89 |
+
{%- elif message.role == "assistant" %}
|
| 90 |
+
{%- set reasoning_content = '' %}
|
| 91 |
+
{%- if message.reasoning_content is string %}
|
| 92 |
+
{%- set reasoning_content = message.reasoning_content %}
|
| 93 |
+
{%- else %}
|
| 94 |
+
{%- if '</think>' in content %}
|
| 95 |
+
{%- set reasoning_content = content.split('</think>')[0].rstrip('\n').split('<think>')[-1].lstrip('\n') %}
|
| 96 |
+
{%- set content = content.split('</think>')[-1].lstrip('\n') %}
|
| 97 |
+
{%- endif %}
|
| 98 |
+
{%- endif %}
|
| 99 |
+
{%- set reasoning_content = reasoning_content|trim %}
|
| 100 |
+
{%- if loop.index0 > ns.last_query_index %}
|
| 101 |
+
{{- '<|im_start|>' + message.role + '\n<think>\n' + reasoning_content + '\n</think>\n\n' + content }}
|
| 102 |
+
{%- else %}
|
| 103 |
+
{{- '<|im_start|>' + message.role + '\n' + content }}
|
| 104 |
+
{%- endif %}
|
| 105 |
+
{%- if message.tool_calls and message.tool_calls is iterable and message.tool_calls is not mapping %}
|
| 106 |
+
{%- for tool_call in message.tool_calls %}
|
| 107 |
+
{%- if tool_call.function is defined %}
|
| 108 |
+
{%- set tool_call = tool_call.function %}
|
| 109 |
+
{%- endif %}
|
| 110 |
+
{%- if loop.first %}
|
| 111 |
+
{%- if content|trim %}
|
| 112 |
+
{{- '\n\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 113 |
+
{%- else %}
|
| 114 |
+
{{- '<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 115 |
+
{%- endif %}
|
| 116 |
+
{%- else %}
|
| 117 |
+
{{- '\n<tool_call>\n<function=' + tool_call.name + '>\n' }}
|
| 118 |
+
{%- endif %}
|
| 119 |
+
{%- if tool_call.arguments is defined %}
|
| 120 |
+
{%- for args_name, args_value in tool_call.arguments|items %}
|
| 121 |
+
{{- '<parameter=' + args_name + '>\n' }}
|
| 122 |
+
{%- set args_value = args_value | tojson | safe if args_value is mapping or (args_value is sequence and args_value is not string) else args_value | string %}
|
| 123 |
+
{{- args_value }}
|
| 124 |
+
{{- '\n</parameter>\n' }}
|
| 125 |
+
{%- endfor %}
|
| 126 |
+
{%- endif %}
|
| 127 |
+
{{- '</function>\n</tool_call>' }}
|
| 128 |
+
{%- endfor %}
|
| 129 |
+
{%- endif %}
|
| 130 |
+
{{- '<|im_end|>\n' }}
|
| 131 |
+
{%- elif message.role == "tool" %}
|
| 132 |
+
{%- if loop.previtem and loop.previtem.role != "tool" %}
|
| 133 |
+
{{- '<|im_start|>user' }}
|
| 134 |
+
{%- endif %}
|
| 135 |
+
{{- '\n<tool_response>\n' }}
|
| 136 |
+
{{- content }}
|
| 137 |
+
{{- '\n</tool_response>' }}
|
| 138 |
+
{%- if not loop.last and loop.nextitem.role != "tool" %}
|
| 139 |
+
{{- '<|im_end|>\n' }}
|
| 140 |
+
{%- elif loop.last %}
|
| 141 |
+
{{- '<|im_end|>\n' }}
|
| 142 |
+
{%- endif %}
|
| 143 |
+
{%- else %}
|
| 144 |
+
{{- raise_exception('Unexpected message role.') }}
|
| 145 |
+
{%- endif %}
|
| 146 |
+
{%- endfor %}
|
| 147 |
+
{%- if add_generation_prompt %}
|
| 148 |
+
{{- '<|im_start|>assistant\n' }}
|
| 149 |
+
{%- if enable_thinking is defined and enable_thinking is false %}
|
| 150 |
+
{{- '<think>\n\n</think>\n\n' }}
|
| 151 |
+
{%- else %}
|
| 152 |
+
{{- '<think>\n' }}
|
| 153 |
+
{%- endif %}
|
| 154 |
+
{%- endif %}
|
code/decision_api.py
ADDED
|
@@ -0,0 +1,112 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Typed local inference adapter for the research decision checkpoints.
|
| 2 |
+
|
| 3 |
+
The response schema resembles TypeSafe's primitives. Confidence uses this
|
| 4 |
+
implementation's documented normalized maximum probability, not a claimed
|
| 5 |
+
reimplementation of TypeSafe's unpublished statistic. No text generation.
|
| 6 |
+
"""
|
| 7 |
+
from __future__ import annotations
|
| 8 |
+
import importlib.util
|
| 9 |
+
import math
|
| 10 |
+
from pathlib import Path
|
| 11 |
+
|
| 12 |
+
|
| 13 |
+
def question_row(state, name, question):
|
| 14 |
+
kind=question.get('type')
|
| 15 |
+
if kind not in {'choice','noul','score'}:raise ValueError('Unknown question type')
|
| 16 |
+
if 'instructions' not in question:raise ValueError('instructions is required')
|
| 17 |
+
criteria=question.get('criteria')
|
| 18 |
+
if kind=='noul':
|
| 19 |
+
criteria={} if criteria is None else criteria
|
| 20 |
+
if not isinstance(criteria,dict) or set(criteria)-{'true','false'}:
|
| 21 |
+
raise ValueError('noul criteria may contain only true and false')
|
| 22 |
+
options=[{'key':'false','description':criteria.get('false','The answer to the question is no.')},
|
| 23 |
+
{'key':'true','description':criteria.get('true','The answer to the question is yes.')}]
|
| 24 |
+
elif kind=='score':
|
| 25 |
+
if not isinstance(criteria,list) or not 2<=len(criteria)<=10:
|
| 26 |
+
raise ValueError('score requires an ordered list of 2..10 criteria')
|
| 27 |
+
options=[{'key':str(i),'description':value} for i,value in enumerate(criteria)]
|
| 28 |
+
else:
|
| 29 |
+
if not isinstance(criteria,dict) or not 2<=len(criteria)<=255:
|
| 30 |
+
raise ValueError('choice requires a mapping of 2..255 criteria')
|
| 31 |
+
if not all(isinstance(k,str) for k in criteria):raise ValueError('Choice keys must be strings')
|
| 32 |
+
options=[{'key':key,'description':value} for key,value in criteria.items()]
|
| 33 |
+
# The question name is used for bookkeeping only; encoders never render id.
|
| 34 |
+
return {'id':name,'state':state,'instructions':question['instructions'],
|
| 35 |
+
'options':options,'task_type':kind,'family':'inference'}
|
| 36 |
+
|
| 37 |
+
|
| 38 |
+
def typed_answer(row, probabilities):
|
| 39 |
+
p=[float(v) for v in probabilities];k=len(row['options'])
|
| 40 |
+
if len(p)!=k or any(not math.isfinite(v) or v<0 for v in p):
|
| 41 |
+
raise ValueError('Invalid probability vector')
|
| 42 |
+
total=sum(p)
|
| 43 |
+
if total<=0 or abs(total-1)>1e-4:raise ValueError('Probabilities must sum to one')
|
| 44 |
+
p=[v/total for v in p];selected=max(range(k),key=p.__getitem__)
|
| 45 |
+
kind=row['task_type']
|
| 46 |
+
if kind=='noul':
|
| 47 |
+
keys=[o['key'] for o in row['options']]
|
| 48 |
+
if set(keys)!={'false','true'}:raise ValueError('Native noul rows require false/true keys')
|
| 49 |
+
return {'type':'noul','noul':p[keys.index('true')]}
|
| 50 |
+
answer={'type':kind,'probabilities':{o['key']:v for o,v in zip(row['options'],p)},
|
| 51 |
+
'confidence':max(0.,min(1.,(k*max(p)-1)/(k-1)))}
|
| 52 |
+
if kind=='choice':answer['choice']=row['options'][selected]['key']
|
| 53 |
+
else:
|
| 54 |
+
if [o['key'] for o in row['options']] != [str(i) for i in range(k)]:
|
| 55 |
+
raise ValueError('Native score rows require ordered numeric level keys')
|
| 56 |
+
answer['score']=sum(i*v for i,v in enumerate(p))
|
| 57 |
+
answer['legend']={str(i):o['description'] for i,o in enumerate(row['options'])}
|
| 58 |
+
return answer
|
| 59 |
+
|
| 60 |
+
|
| 61 |
+
class DecisionEngine:
|
| 62 |
+
def __init__(self, checkpoint, model_code, *, device='cuda:0', max_length=16384,
|
| 63 |
+
batch_size=8, temperatures=None, model_name='local-decision-research'):
|
| 64 |
+
import torch
|
| 65 |
+
path=Path(model_code)/'decision_model.py'
|
| 66 |
+
spec=importlib.util.spec_from_file_location('research_decision_runtime',path)
|
| 67 |
+
module=importlib.util.module_from_spec(spec);spec.loader.exec_module(module)
|
| 68 |
+
model,tokenizer=module.DecisionModel.from_checkpoint(checkpoint,dtype=torch.bfloat16)
|
| 69 |
+
self.model=model.to(device).eval();self.tokenizer=tokenizer;self.module=module
|
| 70 |
+
self.device=device;self.max_length=max_length;self.batch_size=batch_size
|
| 71 |
+
self.temperatures=temperatures or {};self.model_name=model_name
|
| 72 |
+
if batch_size<1 or max_length<1:raise ValueError('Positive batch_size/max_length required')
|
| 73 |
+
if any(not math.isfinite(v) or v<=0 for v in self.temperatures.values()):
|
| 74 |
+
raise ValueError('Temperatures must be finite positive numbers')
|
| 75 |
+
|
| 76 |
+
def predict_rows(self, rows):
|
| 77 |
+
import torch
|
| 78 |
+
encoded=[self.module.encode(row,self.tokenizer,self.max_length) for row in rows]
|
| 79 |
+
pad=self.tokenizer.pad_token_id if self.tokenizer.pad_token_id is not None else self.tokenizer.eos_token_id
|
| 80 |
+
records=[]
|
| 81 |
+
with torch.inference_mode():
|
| 82 |
+
for start in range(0,len(rows),self.batch_size):
|
| 83 |
+
items=encoded[start:start+self.batch_size]
|
| 84 |
+
batch={key:value.to(self.device) if torch.is_tensor(value) else value
|
| 85 |
+
for key,value in self.module.collate(items,pad).items()}
|
| 86 |
+
with torch.autocast('cuda',dtype=torch.bfloat16):logits=self.model(**batch)
|
| 87 |
+
for row,item,values in zip(rows[start:start+self.batch_size],items,logits):
|
| 88 |
+
k=len(row['options']);values=values[:k].float()
|
| 89 |
+
temperature=self.temperatures.get(row['task_type'],1.)
|
| 90 |
+
probabilities=(values/temperature).softmax(-1).tolist()
|
| 91 |
+
answer=typed_answer(row,probabilities)
|
| 92 |
+
prediction=max(range(k),key=probabilities.__getitem__)
|
| 93 |
+
if row['task_type']=='noul':
|
| 94 |
+
chosen='true' if answer['noul']>=.5 else 'false'
|
| 95 |
+
prediction=[o['key'] for o in row['options']].index(chosen)
|
| 96 |
+
rec={'id':row['id'],'status':'ok','prediction':prediction,
|
| 97 |
+
'probabilities':probabilities,'logits':values.tolist(),'temperature':temperature,
|
| 98 |
+
'native_contract':True,'truncated':False,'input_tokens':len(item['ids']),
|
| 99 |
+
'prompt_sha256':item['prompt_sha256'],'answer':answer}
|
| 100 |
+
if row['task_type']=='noul':rec['native_noul']=answer['noul']
|
| 101 |
+
if row['task_type']=='score':rec['native_score']=answer['score']
|
| 102 |
+
records.append(rec)
|
| 103 |
+
return records
|
| 104 |
+
|
| 105 |
+
def decide(self, state, questions):
|
| 106 |
+
if not isinstance(questions,dict) or not questions:
|
| 107 |
+
raise ValueError('questions must be a nonempty mapping')
|
| 108 |
+
if not all(isinstance(name,str) for name in questions):raise ValueError('Question names must be strings')
|
| 109 |
+
rows=[question_row(state,name,q) for name,q in questions.items()]
|
| 110 |
+
result=self.predict_rows(rows)
|
| 111 |
+
return {'model':self.model_name,'answers':{r['id']:r['answer'] for r in result},
|
| 112 |
+
'usage':{'input_tokens':sum(r['input_tokens'] for r in result),'scored_questions':len(result)}}
|
code/decision_model.py
ADDED
|
@@ -0,0 +1,173 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Dynamic candidate readout over a causal Qwen3.5 text backbone.
|
| 2 |
+
|
| 3 |
+
Candidate endpoints retain their contextual vectors. A final global-query
|
| 4 |
+
vector can incorporate all options before a shared bilinear + MLP scorer
|
| 5 |
+
scores every candidate. This is a research architecture, not a Jev claim.
|
| 6 |
+
"""
|
| 7 |
+
import hashlib
|
| 8 |
+
import json
|
| 9 |
+
import math
|
| 10 |
+
from pathlib import Path
|
| 11 |
+
|
| 12 |
+
import torch
|
| 13 |
+
from torch import nn
|
| 14 |
+
import torch.nn.functional as F
|
| 15 |
+
from safetensors.torch import load_file, save_file
|
| 16 |
+
from transformers import AutoTokenizer, Qwen3_5ForConditionalGeneration
|
| 17 |
+
from transformers.models.qwen3_5.modeling_qwen3_5 import Qwen3_5TextModel
|
| 18 |
+
|
| 19 |
+
PROMPT_VERSION = "structured-segmented-candidate-endpoints-global-query-v2"
|
| 20 |
+
MAX_OPTIONS = 255
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
def canonical(value):
|
| 24 |
+
return json.dumps(value, ensure_ascii=False, sort_keys=True, separators=(",", ":"))
|
| 25 |
+
|
| 26 |
+
|
| 27 |
+
def payload(value):
|
| 28 |
+
return value if isinstance(value, str) else canonical(value)
|
| 29 |
+
|
| 30 |
+
|
| 31 |
+
def segments(row):
|
| 32 |
+
opts = row["options"]
|
| 33 |
+
if not 2 <= len(opts) <= MAX_OPTIONS:
|
| 34 |
+
raise ValueError(f"{row['id']}: expected 2..255 options")
|
| 35 |
+
if not all(isinstance(o["key"], str) for o in opts):
|
| 36 |
+
raise ValueError("Option keys must be strings")
|
| 37 |
+
if len({o["key"] for o in opts}) != len(opts):
|
| 38 |
+
raise ValueError("Duplicate option keys")
|
| 39 |
+
prefix = f"Context:\n{payload(row['state'])}\n\nTask type: {row.get('task_type', 'choice')}\nQuestion:\n{payload(row['instructions'])}\nOptions:"
|
| 40 |
+
# Tokenize each part separately. This deliberately fixes boundaries and
|
| 41 |
+
# avoids guessing endpoint indices from merged BPE character offsets.
|
| 42 |
+
options = ["\n<option>\n" + canonical({"key": o["key"], "description": o.get("description")}) + "\n</option>" for o in opts]
|
| 43 |
+
suffix = "\n\nSelect the single option best supported by the context and instructions.\nDecision:"
|
| 44 |
+
return prefix, options, suffix
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
def render(row):
|
| 48 |
+
prefix, opts, suffix = segments(row)
|
| 49 |
+
return prefix + "".join(opts) + suffix
|
| 50 |
+
|
| 51 |
+
|
| 52 |
+
def encode(row, tokenizer, max_length=16384):
|
| 53 |
+
prefix, opts, suffix = segments(row)
|
| 54 |
+
ids = tokenizer.encode(prefix, add_special_tokens=False)
|
| 55 |
+
candidate_positions = []
|
| 56 |
+
for option in opts:
|
| 57 |
+
part = tokenizer.encode(option, add_special_tokens=False)
|
| 58 |
+
if not part:
|
| 59 |
+
raise ValueError("Empty tokenized candidate")
|
| 60 |
+
ids.extend(part)
|
| 61 |
+
candidate_positions.append(len(ids) - 1)
|
| 62 |
+
ids.extend(tokenizer.encode(suffix, add_special_tokens=False))
|
| 63 |
+
if len(ids) > max_length:
|
| 64 |
+
raise ValueError(f"{row['id']}: {len(ids)} tokens exceeds max_length={max_length}; no truncation allowed")
|
| 65 |
+
label = row.get("label", -1)
|
| 66 |
+
if label != -1 and not 0 <= label < len(opts):
|
| 67 |
+
raise ValueError("Invalid label")
|
| 68 |
+
prompt = prefix + "".join(opts) + suffix
|
| 69 |
+
return {"id": row["id"], "ids": ids, "label": label, "nopts": len(opts), "family": row.get("family", "unspecified"), "candidate_positions": candidate_positions, "query_position": len(ids) - 1, "target_probs": row.get("target_probs"), "prompt_sha256": hashlib.sha256(prompt.encode()).hexdigest(), "token_ids_sha256": hashlib.sha256(canonical(ids).encode()).hexdigest(), "segmented_tokenization": True}
|
| 70 |
+
|
| 71 |
+
|
| 72 |
+
def collate(items, pad_id):
|
| 73 |
+
length = ((max(len(x["ids"]) for x in items) + 31) // 32) * 32
|
| 74 |
+
nopts = max(x["nopts"] for x in items)
|
| 75 |
+
ids = torch.full((len(items), length), pad_id, dtype=torch.long)
|
| 76 |
+
mask = torch.zeros_like(ids)
|
| 77 |
+
positions = torch.zeros((len(items), nopts), dtype=torch.long)
|
| 78 |
+
candidate_mask = torch.zeros((len(items), nopts), dtype=torch.bool)
|
| 79 |
+
for i, item in enumerate(items):
|
| 80 |
+
if len(item["candidate_positions"]) != item["nopts"]:
|
| 81 |
+
raise ValueError("Candidate count does not match endpoint count")
|
| 82 |
+
if not all(0 <= p < item["query_position"] < len(item["ids"]) for p in item["candidate_positions"]):
|
| 83 |
+
raise ValueError("Candidate endpoints must precede global query")
|
| 84 |
+
if len(set(item["candidate_positions"])) != item["nopts"]:
|
| 85 |
+
raise ValueError("Duplicate candidate endpoint")
|
| 86 |
+
ids[i, :len(item["ids"])] = torch.tensor(item["ids"])
|
| 87 |
+
mask[i, :len(item["ids"])] = 1
|
| 88 |
+
positions[i, :item["nopts"]] = torch.tensor(item["candidate_positions"])
|
| 89 |
+
candidate_mask[i, :item["nopts"]] = True
|
| 90 |
+
return {"input_ids": ids, "attention_mask": mask, "candidate_positions": positions, "candidate_mask": candidate_mask, "query_positions": torch.tensor([x["query_position"] for x in items]), "labels": torch.tensor([x["label"] for x in items]), "nopts": torch.tensor([x["nopts"] for x in items]), "ids": [x["id"] for x in items], "families": [x["family"] for x in items]}
|
| 91 |
+
|
| 92 |
+
|
| 93 |
+
class CandidateHead(nn.Module):
|
| 94 |
+
def __init__(self, hidden_size, head_dim=256):
|
| 95 |
+
super().__init__()
|
| 96 |
+
self.head_dim = head_dim
|
| 97 |
+
self.candidate_norm = nn.LayerNorm(hidden_size)
|
| 98 |
+
self.query_norm = nn.LayerNorm(hidden_size)
|
| 99 |
+
self.key = nn.Linear(hidden_size, head_dim, bias=False)
|
| 100 |
+
self.query = nn.Linear(hidden_size, head_dim, bias=False)
|
| 101 |
+
self.candidate_mlp = nn.Linear(hidden_size, head_dim, bias=True)
|
| 102 |
+
self.query_mlp = nn.Linear(hidden_size, head_dim, bias=False)
|
| 103 |
+
self.scalar = nn.Linear(head_dim, 1, bias=False)
|
| 104 |
+
nn.init.normal_(self.scalar.weight, mean=0., std=0.01)
|
| 105 |
+
|
| 106 |
+
def forward(self, candidates, query):
|
| 107 |
+
# Keep the small shared head in FP32 even when the backbone uses BF16.
|
| 108 |
+
# The v1 letter head exhibited BF16 ties sensitive to batch padding.
|
| 109 |
+
with torch.autocast(device_type=candidates.device.type, enabled=False):
|
| 110 |
+
c = self.candidate_norm(candidates.float())
|
| 111 |
+
q = self.query_norm(query.float())
|
| 112 |
+
bilinear = (self.key(c) * self.query(q)[:, None, :]).sum(-1) / math.sqrt(self.head_dim)
|
| 113 |
+
interaction = self.scalar(F.gelu(self.candidate_mlp(c) + self.query_mlp(q)[:, None, :])).squeeze(-1)
|
| 114 |
+
return bilinear + interaction
|
| 115 |
+
|
| 116 |
+
|
| 117 |
+
class DecisionModel(nn.Module):
|
| 118 |
+
def __init__(self, backbone, head, metadata):
|
| 119 |
+
super().__init__()
|
| 120 |
+
self.backbone, self.head, self.metadata = backbone, head, metadata
|
| 121 |
+
|
| 122 |
+
@classmethod
|
| 123 |
+
def from_base(cls, path, revision="local", dtype=torch.bfloat16, attention="sdpa", head_dim=256):
|
| 124 |
+
tokenizer = AutoTokenizer.from_pretrained(path, local_files_only=True)
|
| 125 |
+
full, info = Qwen3_5ForConditionalGeneration.from_pretrained(path, dtype=dtype, local_files_only=True, attn_implementation=attention, output_loading_info=True)
|
| 126 |
+
if any(info.get(k) for k in ("missing_keys", "mismatched_keys", "error_msgs")):
|
| 127 |
+
raise RuntimeError(f"Incomplete base loading: {info}")
|
| 128 |
+
backbone = full.model.language_model
|
| 129 |
+
backbone.config.use_cache = False
|
| 130 |
+
head = CandidateHead(backbone.config.hidden_size, head_dim)
|
| 131 |
+
metadata = {"base_revision": revision, "text_parameter_count": sum(p.numel() for p in backbone.parameters()), "prompt_version": PROMPT_VERSION, "attention": attention, "head_dim": head_dim, "max_options": MAX_OPTIONS, "architecture": "contextual-candidate-endpoint-plus-global-query-shared-bilinear-mlp", "head_initialization": "random-shared-content-scorer", "head_precision": "float32-outside-autocast"}
|
| 132 |
+
return cls(backbone, head, metadata), tokenizer
|
| 133 |
+
|
| 134 |
+
@classmethod
|
| 135 |
+
def from_decision_checkpoint(cls, path, dtype=torch.bfloat16, attention="sdpa", head_dim=256):
|
| 136 |
+
"""Warm-start the backbone of a trained v1 model; initialize a new head."""
|
| 137 |
+
path = Path(path)
|
| 138 |
+
metadata = json.loads((path / "decision_config.json").read_text())
|
| 139 |
+
backbone = Qwen3_5TextModel.from_pretrained(path / "backbone", dtype=dtype, local_files_only=True, attn_implementation=attention)
|
| 140 |
+
backbone.config.use_cache = False
|
| 141 |
+
head = CandidateHead(backbone.config.hidden_size, head_dim)
|
| 142 |
+
metadata.update({"prompt_version": PROMPT_VERSION, "head_dim": head_dim, "max_options": MAX_OPTIONS, "architecture": "contextual-candidate-endpoint-plus-global-query-shared-bilinear-mlp", "head_initialization": "random-shared-content-scorer", "warm_start": "trained-v1-text-backbone", "head_precision": "float32-outside-autocast"})
|
| 143 |
+
return cls(backbone, head, metadata), AutoTokenizer.from_pretrained(path, local_files_only=True)
|
| 144 |
+
|
| 145 |
+
@classmethod
|
| 146 |
+
def from_checkpoint(cls, path, dtype=torch.bfloat16, attention="sdpa"):
|
| 147 |
+
path = Path(path)
|
| 148 |
+
metadata = json.loads((path / "decision_config.json").read_text())
|
| 149 |
+
if metadata["prompt_version"] != PROMPT_VERSION:
|
| 150 |
+
raise ValueError("Not a pointer-v2 checkpoint; use from_decision_checkpoint for warm start")
|
| 151 |
+
backbone = Qwen3_5TextModel.from_pretrained(path / "backbone", dtype=dtype, local_files_only=True, attn_implementation=attention)
|
| 152 |
+
head = CandidateHead(backbone.config.hidden_size, metadata["head_dim"])
|
| 153 |
+
head.load_state_dict(load_file(path / "decision_head.safetensors"))
|
| 154 |
+
return cls(backbone, head, metadata), AutoTokenizer.from_pretrained(path, local_files_only=True)
|
| 155 |
+
|
| 156 |
+
def forward(self, input_ids, attention_mask, candidate_positions, candidate_mask, query_positions, **unused):
|
| 157 |
+
hidden = self.backbone(input_ids=input_ids, attention_mask=attention_mask, use_cache=False).last_hidden_state
|
| 158 |
+
batches = torch.arange(hidden.shape[0], device=hidden.device)
|
| 159 |
+
candidates = hidden[batches[:, None], candidate_positions]
|
| 160 |
+
query = hidden[batches, query_positions]
|
| 161 |
+
scores = self.head(candidates, query).float()
|
| 162 |
+
return scores.masked_fill(~candidate_mask, -float("inf"))
|
| 163 |
+
|
| 164 |
+
def save(self, path, tokenizer):
|
| 165 |
+
path = Path(path); path.mkdir(parents=True, exist_ok=True)
|
| 166 |
+
self.backbone.save_pretrained(path / "backbone", safe_serialization=True, max_shard_size="4GB")
|
| 167 |
+
save_file({n: v.detach().cpu().contiguous() for n, v in self.head.state_dict().items()}, str(path / "decision_head.safetensors"))
|
| 168 |
+
tokenizer.save_pretrained(path)
|
| 169 |
+
(path / "decision_config.json").write_text(json.dumps(self.metadata, indent=2) + "\n")
|
| 170 |
+
|
| 171 |
+
|
| 172 |
+
def classification_loss(logits, labels):
|
| 173 |
+
return F.cross_entropy(logits, labels)
|
code/predict.py
ADDED
|
@@ -0,0 +1,43 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Portable one-GPU JSONL inference for frozen dynamic-option checkpoints."""
|
| 2 |
+
import argparse
|
| 3 |
+
import hashlib
|
| 4 |
+
import json
|
| 5 |
+
from pathlib import Path
|
| 6 |
+
import time
|
| 7 |
+
import torch
|
| 8 |
+
from decision_model import DecisionModel, encode, collate
|
| 9 |
+
|
| 10 |
+
p = argparse.ArgumentParser()
|
| 11 |
+
p.add_argument("--model", required=True)
|
| 12 |
+
p.add_argument("--base", action="store_true")
|
| 13 |
+
p.add_argument("--revision", default="local-checkpoint")
|
| 14 |
+
p.add_argument("--input", required=True)
|
| 15 |
+
p.add_argument("--output", required=True)
|
| 16 |
+
p.add_argument("--batch-size", type=int, default=8)
|
| 17 |
+
p.add_argument("--max-length", type=int, default=4096)
|
| 18 |
+
p.add_argument("--temperature", type=float, default=1.0)
|
| 19 |
+
a = p.parse_args()
|
| 20 |
+
assert a.temperature > 0
|
| 21 |
+
torch.cuda.set_device(0)
|
| 22 |
+
model, tokenizer = DecisionModel.from_base(a.model, a.revision) if a.base else DecisionModel.from_checkpoint(a.model)
|
| 23 |
+
model = model.cuda().eval()
|
| 24 |
+
rows = [json.loads(line) for line in Path(a.input).read_text().splitlines() if line.strip()]
|
| 25 |
+
encoded = [encode(row, tokenizer, a.max_length) for row in rows]
|
| 26 |
+
assert len({row["id"] for row in rows}) == len(rows)
|
| 27 |
+
output = Path(a.output); output.parent.mkdir(parents=True, exist_ok=True)
|
| 28 |
+
if output.exists(): raise RuntimeError("Refusing to overwrite predictions")
|
| 29 |
+
with torch.inference_mode(), output.open("w") as f:
|
| 30 |
+
for start in range(0, len(encoded), a.batch_size):
|
| 31 |
+
examples = encoded[start:start + a.batch_size]
|
| 32 |
+
batch = {key: value.cuda() if torch.is_tensor(value) else value for key, value in collate(examples, tokenizer.pad_token_id if tokenizer.pad_token_id is not None else tokenizer.eos_token_id).items()}
|
| 33 |
+
torch.cuda.synchronize(); tick = time.perf_counter()
|
| 34 |
+
with torch.autocast("cuda", dtype=torch.bfloat16): logits = model(**batch)
|
| 35 |
+
torch.cuda.synchronize(); elapsed = time.perf_counter() - tick
|
| 36 |
+
probabilities = (logits / a.temperature).softmax(-1).cpu().tolist(); scores = logits.cpu().tolist()
|
| 37 |
+
for row, example, prob, score in zip(rows[start:start + a.batch_size], examples, probabilities, scores):
|
| 38 |
+
k = example["nopts"]; pred = max(range(k), key=lambda i: prob[i])
|
| 39 |
+
rec = {"id": row["id"], "family": row.get("family"), "label": row.get("label"), "prediction": pred, "prediction_key": row["options"][pred]["key"], "probabilities": prob[:k], "logits": score[:k], "temperature": a.temperature, "input_tokens": len(example["ids"]), "prompt_sha256": example["prompt_sha256"], "batch_elapsed_seconds": elapsed, "batch_size": len(examples)}
|
| 40 |
+
if "score_values" in row: rec["expected_score"] = sum(value * probability for value, probability in zip(row["score_values"], prob[:k]))
|
| 41 |
+
f.write(json.dumps(rec, ensure_ascii=False) + "\n")
|
| 42 |
+
f.flush(); print(json.dumps({"completed": min(start + a.batch_size, len(rows)), "total": len(rows)}), flush=True)
|
| 43 |
+
Path(str(output) + ".metadata.json").write_text(json.dumps({"model": a.model, "revision": a.revision, "temperature": a.temperature, "input_sha256": hashlib.sha256(Path(a.input).read_bytes()).hexdigest(), "predictions_sha256": hashlib.sha256(output.read_bytes()).hexdigest(), "rows": len(rows), "model_metadata": model.metadata}, indent=2))
|
decision_config.json
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"base_revision": "851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a",
|
| 3 |
+
"text_parameter_count": 4205751296,
|
| 4 |
+
"full_source_parameter_count": 4539265536,
|
| 5 |
+
"prompt_version": "structured-segmented-candidate-endpoints-global-query-v2",
|
| 6 |
+
"attention": "sdpa",
|
| 7 |
+
"head_dim": 256,
|
| 8 |
+
"max_options": 255,
|
| 9 |
+
"architecture": "contextual-candidate-endpoint-plus-global-query-shared-bilinear-mlp",
|
| 10 |
+
"warm_start": "trained-v1-text-backbone",
|
| 11 |
+
"head_precision": "float32-outside-autocast",
|
| 12 |
+
"backbone_parameter_dtype": "bfloat16",
|
| 13 |
+
"head_parameter_dtype": "float32",
|
| 14 |
+
"training_master_parameter_dtype": "float32",
|
| 15 |
+
"backbone_autocast_dtype": "bfloat16",
|
| 16 |
+
"base_model": "Qwen/Qwen3.5-4B",
|
| 17 |
+
"calibration_file": "temperature.json",
|
| 18 |
+
"runtime_file": "runtime.json"
|
| 19 |
+
}
|
decision_head.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:751dc1ceb4ea9cea2d3154f9eafe49e61a993f57e22b7b890f5f982c98043c9c
|
| 3 |
+
size 10529624
|
metrics/asset-hashes.json
ADDED
|
@@ -0,0 +1,17 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"readout.png": "fb6b3d1cf149a1a3ccb584eb1c213df73c07bcd328732b4238928e2a2a4af085",
|
| 3 |
+
"readout.pdf": "d489b0d1814e37495a8612c12fabd3bf4a6e73d11c7e356bf1ce0cedded8a745",
|
| 4 |
+
"decision-family-header.png": "213511289ce8df038d938ac470e803c427ed57f0f85cc397dd4d79964b866541",
|
| 5 |
+
"readout.svg": "701084bf7b0858a3adb247ae446df737b77d4b75004341dfd5f956b933f3d253",
|
| 6 |
+
"architecture.svg": "215d9af6f94cc24847fc1d23a0b2a287b36afdc1e10ea4f5c82895b2fe103002",
|
| 7 |
+
"decision-quality.png": "50af70f9120e1f13024a18b264d9471c0f441464f33188306e5f5e0dc0cc4955",
|
| 8 |
+
"decision-capabilities.png": "ec86958b569c84c9ed8fcd8180095f88bbc3fe8f8ded70f685b08bd6f59f2ef6",
|
| 9 |
+
"decision-capabilities.pdf": "8cd467055c05d5c7616e776174ed0e3e953e71672558ea346e347e8663b5e5ce",
|
| 10 |
+
"decision-quality.pdf": "403a02af4ba6292d27fe2863dc568a026278002fbb58082befed37ac55f31ce4",
|
| 11 |
+
"architecture-atlas.pdf": "d1582ac115aa6a40129b6221e15a197e33d20847e03d69396f02fdab82771376",
|
| 12 |
+
"decision-mark.png": "d83cf7878c3839f3085feb8c02334217ad2fef0a615b805e1726b292552c46e8",
|
| 13 |
+
"decision-capabilities.svg": "e3b03c292b420b039b972756ae40e93e73c0610672a9bca5d795736faeb7f697",
|
| 14 |
+
"decision-quality.svg": "b430df49b3c74fa0cd8b7e39ab1a7f6768295feaa423213816fa6ce8f2fde8a2",
|
| 15 |
+
"architecture.pdf": "ee87f997a0aa4343c2ec66038b7526361e0a3c0ae02b383f8928aac9dd9bd74c",
|
| 16 |
+
"architecture.png": "8fcfa10b3941ee4aec1f5fba20a25e382a7d5de83074071c9ef68e627996de40"
|
| 17 |
+
}
|
metrics/quality-aggregate.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
metrics/timing-aggregate.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
model-card-example.json
ADDED
|
@@ -0,0 +1,69 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"request": {
|
| 3 |
+
"state": "The customer reports that the same invoice was charged twice. They ask for a refund. There is no product outage.",
|
| 4 |
+
"questions": {
|
| 5 |
+
"destination": {
|
| 6 |
+
"type": "choice",
|
| 7 |
+
"instructions": "Choose the team that handles this request.",
|
| 8 |
+
"criteria": {
|
| 9 |
+
"billing": "Invoices, payments, refunds and duplicate charges",
|
| 10 |
+
"technical": "Product errors and troubleshooting"
|
| 11 |
+
}
|
| 12 |
+
},
|
| 13 |
+
"refund_requested": {
|
| 14 |
+
"type": "noul",
|
| 15 |
+
"instructions": "Does the customer explicitly ask for a refund?"
|
| 16 |
+
},
|
| 17 |
+
"urgency": {
|
| 18 |
+
"type": "score",
|
| 19 |
+
"instructions": "Rate urgency using only these ordered levels.",
|
| 20 |
+
"criteria": [
|
| 21 |
+
"Routine information request with no payment problem or outage",
|
| 22 |
+
"A payment or billing problem, with no product outage",
|
| 23 |
+
"An active product outage stopping the customer from working"
|
| 24 |
+
]
|
| 25 |
+
}
|
| 26 |
+
}
|
| 27 |
+
},
|
| 28 |
+
"response": {
|
| 29 |
+
"model": "Decision-1.0-Nox",
|
| 30 |
+
"answers": {
|
| 31 |
+
"destination": {
|
| 32 |
+
"type": "choice",
|
| 33 |
+
"probabilities": {
|
| 34 |
+
"billing": 0.9999999999800775,
|
| 35 |
+
"technical": 1.9922419616394405e-11
|
| 36 |
+
},
|
| 37 |
+
"confidence": 0.999999999960155,
|
| 38 |
+
"choice": "billing"
|
| 39 |
+
},
|
| 40 |
+
"refund_requested": {
|
| 41 |
+
"type": "noul",
|
| 42 |
+
"noul": 0.9999999999999927
|
| 43 |
+
},
|
| 44 |
+
"urgency": {
|
| 45 |
+
"type": "score",
|
| 46 |
+
"probabilities": {
|
| 47 |
+
"0": 0.00023021107567649225,
|
| 48 |
+
"1": 0.9997697889240532,
|
| 49 |
+
"2": 2.70304948552699e-13
|
| 50 |
+
},
|
| 51 |
+
"confidence": 0.9996546833860798,
|
| 52 |
+
"score": 0.9997697889245938,
|
| 53 |
+
"legend": {
|
| 54 |
+
"0": "Routine information request with no payment problem or outage",
|
| 55 |
+
"1": "A payment or billing problem, with no product outage",
|
| 56 |
+
"2": "An active product outage stopping the customer from working"
|
| 57 |
+
}
|
| 58 |
+
}
|
| 59 |
+
},
|
| 60 |
+
"usage": {
|
| 61 |
+
"input_tokens": 355,
|
| 62 |
+
"scored_questions": 3
|
| 63 |
+
}
|
| 64 |
+
},
|
| 65 |
+
"direct_engine_exact_response": true,
|
| 66 |
+
"overflow_rejected": true,
|
| 67 |
+
"bundle_manifest_sha256": "adf5d88146d4f4a7fdcf0b265aa0c804a6116537c1e92bd620e40dfdf6803550",
|
| 68 |
+
"example_source_sha256": "d52c20b602bd1049aecda55244e71c27d8ce44bd1aa8b1941db62ae41d31ba12"
|
| 69 |
+
}
|
pyproject.toml
ADDED
|
@@ -0,0 +1,19 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
[build-system]
|
| 2 |
+
requires = ["setuptools>=68"]
|
| 3 |
+
build-backend = "setuptools.build_meta"
|
| 4 |
+
|
| 5 |
+
[project]
|
| 6 |
+
name = "decision-local"
|
| 7 |
+
version = "1.0.0"
|
| 8 |
+
description = "Local typed inference for exported Decision decoder models"
|
| 9 |
+
requires-python = ">=3.10"
|
| 10 |
+
dependencies = []
|
| 11 |
+
|
| 12 |
+
[project.optional-dependencies]
|
| 13 |
+
hub = ["huggingface-hub==1.31.0"]
|
| 14 |
+
|
| 15 |
+
[project.scripts]
|
| 16 |
+
decision-example = "decision.example:main"
|
| 17 |
+
|
| 18 |
+
[tool.setuptools.packages.find]
|
| 19 |
+
where = ["src"]
|
release-manifest.json
ADDED
|
@@ -0,0 +1,328 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"format": "decision-public-release-v1",
|
| 3 |
+
"status": "assembled-not-published",
|
| 4 |
+
"bundle_manifest_sha256": "adf5d88146d4f4a7fdcf0b265aa0c804a6116537c1e92bd620e40dfdf6803550",
|
| 5 |
+
"readiness_sha256": "d5b4d11c20f886845577a43314802bbeef51f7fa4f2c1f438c4236323f4182d0",
|
| 6 |
+
"model_card_sha256": "57c4022b8a683383db0e5e5270827029764d83ee49d742f712da22a88fa7f133",
|
| 7 |
+
"repo_id": "llm-semantic-router/Decision-1.0-Nox",
|
| 8 |
+
"assembly_script_sha256": "0ca32612da99c16b9801149d69f375b157e51b6e426b0a74efa3efb6bcb9f792",
|
| 9 |
+
"original_bundle_manifest_preserved": true,
|
| 10 |
+
"files_exclude_this_manifest": true,
|
| 11 |
+
"files": [
|
| 12 |
+
{
|
| 13 |
+
"file": "ATTRIBUTIONS.md",
|
| 14 |
+
"bytes": 2610,
|
| 15 |
+
"sha256": "47c35fdcde567fb511f31d1d7d0f2e2ba21daef0beb31217c025132aafe0d2e9"
|
| 16 |
+
},
|
| 17 |
+
{
|
| 18 |
+
"file": "Dockerfile.runtime",
|
| 19 |
+
"bytes": 751,
|
| 20 |
+
"sha256": "36e81318bed2b6005ff46d6aa949533924b17d88ab8013a56caab77b1a0b5cf7"
|
| 21 |
+
},
|
| 22 |
+
{
|
| 23 |
+
"file": "EVALUATION.md",
|
| 24 |
+
"bytes": 16973,
|
| 25 |
+
"sha256": "1f4f7bc151e757da8e35db2bf690cd13839ab67de130655004400c2bd425ffb3"
|
| 26 |
+
},
|
| 27 |
+
{
|
| 28 |
+
"file": "FIGURE-NOTICES.md",
|
| 29 |
+
"bytes": 1041,
|
| 30 |
+
"sha256": "d70794c70cc8811a74ef19e9dbeb7368d3ff89b71e0117bff40149dc9b72055d"
|
| 31 |
+
},
|
| 32 |
+
{
|
| 33 |
+
"file": "LICENSE",
|
| 34 |
+
"bytes": 11544,
|
| 35 |
+
"sha256": "bbedc3fda3305820b977265f01b8619d87570a6739de3a5582c3464840f1e57a"
|
| 36 |
+
},
|
| 37 |
+
{
|
| 38 |
+
"file": "QWEN-LICENSE",
|
| 39 |
+
"bytes": 11544,
|
| 40 |
+
"sha256": "bbedc3fda3305820b977265f01b8619d87570a6739de3a5582c3464840f1e57a"
|
| 41 |
+
},
|
| 42 |
+
{
|
| 43 |
+
"file": "README.md",
|
| 44 |
+
"bytes": 6981,
|
| 45 |
+
"sha256": "57c4022b8a683383db0e5e5270827029764d83ee49d742f712da22a88fa7f133"
|
| 46 |
+
},
|
| 47 |
+
{
|
| 48 |
+
"file": "RUNTIME.md",
|
| 49 |
+
"bytes": 5205,
|
| 50 |
+
"sha256": "be35b2f8a9c977f38be9b5eb892fdc809db5167c327575c9311355aae3e781c7"
|
| 51 |
+
},
|
| 52 |
+
{
|
| 53 |
+
"file": "TIMING.md",
|
| 54 |
+
"bytes": 13432,
|
| 55 |
+
"sha256": "bdf371d3e93056125840829105b7f5a91abce343889530c8f7cb339f6612f9a6"
|
| 56 |
+
},
|
| 57 |
+
{
|
| 58 |
+
"file": "USAGE.md",
|
| 59 |
+
"bytes": 5435,
|
| 60 |
+
"sha256": "46ec1078d2bb8cb54a1850809a101f07a77bb54c18b92276cb89d40245dbbc8f"
|
| 61 |
+
},
|
| 62 |
+
{
|
| 63 |
+
"file": "assets/architecture-atlas.pdf",
|
| 64 |
+
"bytes": 306242,
|
| 65 |
+
"sha256": "d1582ac115aa6a40129b6221e15a197e33d20847e03d69396f02fdab82771376"
|
| 66 |
+
},
|
| 67 |
+
{
|
| 68 |
+
"file": "assets/architecture.pdf",
|
| 69 |
+
"bytes": 183111,
|
| 70 |
+
"sha256": "ee87f997a0aa4343c2ec66038b7526361e0a3c0ae02b383f8928aac9dd9bd74c"
|
| 71 |
+
},
|
| 72 |
+
{
|
| 73 |
+
"file": "assets/architecture.png",
|
| 74 |
+
"bytes": 511058,
|
| 75 |
+
"sha256": "8fcfa10b3941ee4aec1f5fba20a25e382a7d5de83074071c9ef68e627996de40"
|
| 76 |
+
},
|
| 77 |
+
{
|
| 78 |
+
"file": "assets/architecture.svg",
|
| 79 |
+
"bytes": 14718,
|
| 80 |
+
"sha256": "215d9af6f94cc24847fc1d23a0b2a287b36afdc1e10ea4f5c82895b2fe103002"
|
| 81 |
+
},
|
| 82 |
+
{
|
| 83 |
+
"file": "assets/decision-capabilities.pdf",
|
| 84 |
+
"bytes": 106372,
|
| 85 |
+
"sha256": "8cd467055c05d5c7616e776174ed0e3e953e71672558ea346e347e8663b5e5ce"
|
| 86 |
+
},
|
| 87 |
+
{
|
| 88 |
+
"file": "assets/decision-capabilities.png",
|
| 89 |
+
"bytes": 483212,
|
| 90 |
+
"sha256": "ec86958b569c84c9ed8fcd8180095f88bbc3fe8f8ded70f685b08bd6f59f2ef6"
|
| 91 |
+
},
|
| 92 |
+
{
|
| 93 |
+
"file": "assets/decision-capabilities.svg",
|
| 94 |
+
"bytes": 153471,
|
| 95 |
+
"sha256": "e3b03c292b420b039b972756ae40e93e73c0610672a9bca5d795736faeb7f697"
|
| 96 |
+
},
|
| 97 |
+
{
|
| 98 |
+
"file": "assets/decision-family-header.png",
|
| 99 |
+
"bytes": 2962868,
|
| 100 |
+
"sha256": "213511289ce8df038d938ac470e803c427ed57f0f85cc397dd4d79964b866541"
|
| 101 |
+
},
|
| 102 |
+
{
|
| 103 |
+
"file": "assets/decision-mark.png",
|
| 104 |
+
"bytes": 1828679,
|
| 105 |
+
"sha256": "d83cf7878c3839f3085feb8c02334217ad2fef0a615b805e1726b292552c46e8"
|
| 106 |
+
},
|
| 107 |
+
{
|
| 108 |
+
"file": "assets/decision-quality.pdf",
|
| 109 |
+
"bytes": 92352,
|
| 110 |
+
"sha256": "403a02af4ba6292d27fe2863dc568a026278002fbb58082befed37ac55f31ce4"
|
| 111 |
+
},
|
| 112 |
+
{
|
| 113 |
+
"file": "assets/decision-quality.png",
|
| 114 |
+
"bytes": 383098,
|
| 115 |
+
"sha256": "50af70f9120e1f13024a18b264d9471c0f441464f33188306e5f5e0dc0cc4955"
|
| 116 |
+
},
|
| 117 |
+
{
|
| 118 |
+
"file": "assets/decision-quality.svg",
|
| 119 |
+
"bytes": 111684,
|
| 120 |
+
"sha256": "b430df49b3c74fa0cd8b7e39ab1a7f6768295feaa423213816fa6ce8f2fde8a2"
|
| 121 |
+
},
|
| 122 |
+
{
|
| 123 |
+
"file": "assets/readout.pdf",
|
| 124 |
+
"bytes": 123008,
|
| 125 |
+
"sha256": "d489b0d1814e37495a8612c12fabd3bf4a6e73d11c7e356bf1ce0cedded8a745"
|
| 126 |
+
},
|
| 127 |
+
{
|
| 128 |
+
"file": "assets/readout.png",
|
| 129 |
+
"bytes": 285481,
|
| 130 |
+
"sha256": "fb6b3d1cf149a1a3ccb584eb1c213df73c07bcd328732b4238928e2a2a4af085"
|
| 131 |
+
},
|
| 132 |
+
{
|
| 133 |
+
"file": "assets/readout.svg",
|
| 134 |
+
"bytes": 8067,
|
| 135 |
+
"sha256": "701084bf7b0858a3adb247ae446df737b77d4b75004341dfd5f956b933f3d253"
|
| 136 |
+
},
|
| 137 |
+
{
|
| 138 |
+
"file": "backbone/config.json",
|
| 139 |
+
"bytes": 1978,
|
| 140 |
+
"sha256": "ae3a463b32e95b6cc207a7af4f1defb4195f388eb6f9ff19d2690b73d4966953"
|
| 141 |
+
},
|
| 142 |
+
{
|
| 143 |
+
"file": "backbone/model-00001-of-00003.safetensors",
|
| 144 |
+
"bytes": 3991295368,
|
| 145 |
+
"sha256": "5162db199021e5507c0bfd7ea0fb8ee7126392e84a2e6578ed9e5e032fa03024"
|
| 146 |
+
},
|
| 147 |
+
{
|
| 148 |
+
"file": "backbone/model-00002-of-00003.safetensors",
|
| 149 |
+
"bytes": 3979828128,
|
| 150 |
+
"sha256": "f994436085feea7a0fe18bed4fcb00e12e449daaea1021dab0accdc7c0107114"
|
| 151 |
+
},
|
| 152 |
+
{
|
| 153 |
+
"file": "backbone/model-00003-of-00003.safetensors",
|
| 154 |
+
"bytes": 440425856,
|
| 155 |
+
"sha256": "a34a119d6438cbb87578370fa64a6b938a2f2b4fe462cfd4badf52b5d0b8ffe2"
|
| 156 |
+
},
|
| 157 |
+
{
|
| 158 |
+
"file": "backbone/model.safetensors.index.json",
|
| 159 |
+
"bytes": 33047,
|
| 160 |
+
"sha256": "1602d52e38d81586af85bc4ce29ce082c5fc5877c763b1ebcab7545320016599"
|
| 161 |
+
},
|
| 162 |
+
{
|
| 163 |
+
"file": "bundle-manifest.json",
|
| 164 |
+
"bytes": 5647,
|
| 165 |
+
"sha256": "adf5d88146d4f4a7fdcf0b265aa0c804a6116537c1e92bd620e40dfdf6803550"
|
| 166 |
+
},
|
| 167 |
+
{
|
| 168 |
+
"file": "chat_template.jinja",
|
| 169 |
+
"bytes": 7756,
|
| 170 |
+
"sha256": "a4aee8afcf2e0711942cf848899be66016f8d14a889ff9ede07bca099c28f715"
|
| 171 |
+
},
|
| 172 |
+
{
|
| 173 |
+
"file": "code/decision_api.py",
|
| 174 |
+
"bytes": 6724,
|
| 175 |
+
"sha256": "147b2fec32cbbbbb1b92cf2a19bb887f9d945e4974e141ca7ea93b8c542f5b21"
|
| 176 |
+
},
|
| 177 |
+
{
|
| 178 |
+
"file": "code/decision_model.py",
|
| 179 |
+
"bytes": 10114,
|
| 180 |
+
"sha256": "d3e28489c09f3bd7130e2d43d92e0b5c4a08e25b09b21303904defb0ff1c3646"
|
| 181 |
+
},
|
| 182 |
+
{
|
| 183 |
+
"file": "code/predict.py",
|
| 184 |
+
"bytes": 3164,
|
| 185 |
+
"sha256": "02352e8385ab47157b6459910da54d962e5da4bb4940d571faedc86bc5da9aee"
|
| 186 |
+
},
|
| 187 |
+
{
|
| 188 |
+
"file": "decision_config.json",
|
| 189 |
+
"bytes": 753,
|
| 190 |
+
"sha256": "443a9b3f191a8387915c606de8303700fc1a069fe7c8ad46a0eba5528a2549a8"
|
| 191 |
+
},
|
| 192 |
+
{
|
| 193 |
+
"file": "decision_head.safetensors",
|
| 194 |
+
"bytes": 10529624,
|
| 195 |
+
"sha256": "751dc1ceb4ea9cea2d3154f9eafe49e61a993f57e22b7b890f5f982c98043c9c"
|
| 196 |
+
},
|
| 197 |
+
{
|
| 198 |
+
"file": "metrics/asset-hashes.json",
|
| 199 |
+
"bytes": 1394,
|
| 200 |
+
"sha256": "b4aec27dd4a4032c37ef013cda0cb72161b6c1de25161d61864a5f1971af952a"
|
| 201 |
+
},
|
| 202 |
+
{
|
| 203 |
+
"file": "metrics/quality-aggregate.json",
|
| 204 |
+
"bytes": 1214948,
|
| 205 |
+
"sha256": "b2181b7636f0ddace6af33a45010bfb4e62fb32f987f4abe2d2a4d58b3a007e4"
|
| 206 |
+
},
|
| 207 |
+
{
|
| 208 |
+
"file": "metrics/timing-aggregate.json",
|
| 209 |
+
"bytes": 148812,
|
| 210 |
+
"sha256": "a0e5f1c94277b31a922ae1e1a708ce70a2f03b5e49996a688112fc1e9697615a"
|
| 211 |
+
},
|
| 212 |
+
{
|
| 213 |
+
"file": "model-card-example.json",
|
| 214 |
+
"bytes": 2274,
|
| 215 |
+
"sha256": "82deb4ad0eadf14a410a8f98f512abba9f57d445a137d183e20b8695313f6dad"
|
| 216 |
+
},
|
| 217 |
+
{
|
| 218 |
+
"file": "pyproject.toml",
|
| 219 |
+
"bytes": 436,
|
| 220 |
+
"sha256": "6a557fbe472027af103ca2cfc07e977caab3e257de930aa57cf9fea8cf90f8a0"
|
| 221 |
+
},
|
| 222 |
+
{
|
| 223 |
+
"file": "runtime-build-provenance.json",
|
| 224 |
+
"bytes": 2894,
|
| 225 |
+
"sha256": "61d064b0db35d0ebd04a038e376896d2aab8b69e6525a8ec1f317f73b5284345"
|
| 226 |
+
},
|
| 227 |
+
{
|
| 228 |
+
"file": "runtime-fla-requirements.lock",
|
| 229 |
+
"bytes": 654,
|
| 230 |
+
"sha256": "35e1fedff9ca49092a7ada277bbd794abe7e8474e14a678a7e4bcec6406d0eb5"
|
| 231 |
+
},
|
| 232 |
+
{
|
| 233 |
+
"file": "runtime-provenance.json",
|
| 234 |
+
"bytes": 5805,
|
| 235 |
+
"sha256": "307e865c47e9f6120b50d8be4f7c5071a116e6f8a50d40c5424ab0232b6fe690"
|
| 236 |
+
},
|
| 237 |
+
{
|
| 238 |
+
"file": "runtime.json",
|
| 239 |
+
"bytes": 952,
|
| 240 |
+
"sha256": "7ed527476826756d6076f23d0eaa8b4b53ff34b9f8bd57ae8e65b50e4d28cfa6"
|
| 241 |
+
},
|
| 242 |
+
{
|
| 243 |
+
"file": "src/decision/__init__.py",
|
| 244 |
+
"bytes": 167,
|
| 245 |
+
"sha256": "70de37df98b6fc8e3b9f9d43935ba31a32350496214c11adf8c5fba72c433313"
|
| 246 |
+
},
|
| 247 |
+
{
|
| 248 |
+
"file": "src/decision/example.py",
|
| 249 |
+
"bytes": 3381,
|
| 250 |
+
"sha256": "d52c20b602bd1049aecda55244e71c27d8ce44bd1aa8b1941db62ae41d31ba12"
|
| 251 |
+
},
|
| 252 |
+
{
|
| 253 |
+
"file": "src/decision/model.py",
|
| 254 |
+
"bytes": 8790,
|
| 255 |
+
"sha256": "ab428234d508a1245d3723c5a5bb0c796685abebd0447f77c7fbed9113954b21"
|
| 256 |
+
},
|
| 257 |
+
{
|
| 258 |
+
"file": "temperature.json",
|
| 259 |
+
"bytes": 668,
|
| 260 |
+
"sha256": "f45db64f2b58f1dd3b3f7af4adaee79935a57daac0976ee77a28191ed3454865"
|
| 261 |
+
},
|
| 262 |
+
{
|
| 263 |
+
"file": "tokenizer.json",
|
| 264 |
+
"bytes": 19989325,
|
| 265 |
+
"sha256": "06b9509352d2af50381ab2247e083b80d32d5c0aba91c272ca9ff729b6a0e523"
|
| 266 |
+
},
|
| 267 |
+
{
|
| 268 |
+
"file": "tokenizer_config.json",
|
| 269 |
+
"bytes": 1123,
|
| 270 |
+
"sha256": "bee8eba30f0eb4af73c0fe2cd06d0f89b657d7819941c438157ec42f7c80ea87"
|
| 271 |
+
}
|
| 272 |
+
],
|
| 273 |
+
"staging_methods": {
|
| 274 |
+
"ATTRIBUTIONS.md": "copy",
|
| 275 |
+
"Dockerfile.runtime": "copy",
|
| 276 |
+
"EVALUATION.md": "copy",
|
| 277 |
+
"FIGURE-NOTICES.md": "copy",
|
| 278 |
+
"LICENSE": "copy",
|
| 279 |
+
"QWEN-LICENSE": "copy",
|
| 280 |
+
"README.md": "copy",
|
| 281 |
+
"RUNTIME.md": "copy",
|
| 282 |
+
"TIMING.md": "copy",
|
| 283 |
+
"USAGE.md": "copy",
|
| 284 |
+
"assets/architecture-atlas.pdf": "copy",
|
| 285 |
+
"assets/architecture.pdf": "copy",
|
| 286 |
+
"assets/architecture.png": "copy",
|
| 287 |
+
"assets/architecture.svg": "copy",
|
| 288 |
+
"assets/decision-capabilities.pdf": "copy",
|
| 289 |
+
"assets/decision-capabilities.png": "copy",
|
| 290 |
+
"assets/decision-capabilities.svg": "copy",
|
| 291 |
+
"assets/decision-family-header.png": "copy",
|
| 292 |
+
"assets/decision-mark.png": "copy",
|
| 293 |
+
"assets/decision-quality.pdf": "copy",
|
| 294 |
+
"assets/decision-quality.png": "copy",
|
| 295 |
+
"assets/decision-quality.svg": "copy",
|
| 296 |
+
"assets/readout.pdf": "copy",
|
| 297 |
+
"assets/readout.png": "copy",
|
| 298 |
+
"assets/readout.svg": "copy",
|
| 299 |
+
"backbone/config.json": "copy",
|
| 300 |
+
"backbone/model-00001-of-00003.safetensors": "hardlink",
|
| 301 |
+
"backbone/model-00002-of-00003.safetensors": "hardlink",
|
| 302 |
+
"backbone/model-00003-of-00003.safetensors": "hardlink",
|
| 303 |
+
"backbone/model.safetensors.index.json": "copy",
|
| 304 |
+
"bundle-manifest.json": "copy",
|
| 305 |
+
"chat_template.jinja": "copy",
|
| 306 |
+
"code/decision_api.py": "copy",
|
| 307 |
+
"code/decision_model.py": "copy",
|
| 308 |
+
"code/predict.py": "copy",
|
| 309 |
+
"decision_config.json": "copy",
|
| 310 |
+
"decision_head.safetensors": "hardlink",
|
| 311 |
+
"metrics/asset-hashes.json": "copy",
|
| 312 |
+
"metrics/quality-aggregate.json": "copy",
|
| 313 |
+
"metrics/timing-aggregate.json": "copy",
|
| 314 |
+
"model-card-example.json": "copy",
|
| 315 |
+
"pyproject.toml": "copy",
|
| 316 |
+
"runtime-build-provenance.json": "copy",
|
| 317 |
+
"runtime-fla-requirements.lock": "copy",
|
| 318 |
+
"runtime-provenance.json": "copy",
|
| 319 |
+
"runtime.json": "copy",
|
| 320 |
+
"src/decision/__init__.py": "copy",
|
| 321 |
+
"src/decision/example.py": "copy",
|
| 322 |
+
"src/decision/model.py": "copy",
|
| 323 |
+
"temperature.json": "copy",
|
| 324 |
+
"tokenizer.json": "copy",
|
| 325 |
+
"tokenizer_config.json": "copy"
|
| 326 |
+
},
|
| 327 |
+
"scope": "Inference weights, original numerical code, calibrated runtime metadata, wrapper, model card, license, attribution and approved assets only."
|
| 328 |
+
}
|
runtime-build-provenance.json
ADDED
|
@@ -0,0 +1,65 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"image_id": "sha256:ef8192e3dbaadf97a03f1d0bf87ee63ae16d9ffdc5ee209b199ed17e773b438e",
|
| 3 |
+
"created": "2026-09-21T12:56:59.399496065Z",
|
| 4 |
+
"layer_count": 42,
|
| 5 |
+
"cpu_import_probe": {
|
| 6 |
+
"exit_code": 0,
|
| 7 |
+
"result": {
|
| 8 |
+
"torch": "2.12.0+git6bbd260",
|
| 9 |
+
"torch_git": "6bbd26020da1c6dc198625dfcdd968b1e4e6b1c5",
|
| 10 |
+
"hip": "7.2.53211",
|
| 11 |
+
"cuda_initialized": false,
|
| 12 |
+
"transformers": "5.17.0",
|
| 13 |
+
"wrapper_imported": true,
|
| 14 |
+
"packages": {
|
| 15 |
+
"triton": "3.7.1+gitf0b55c07",
|
| 16 |
+
"fla-core": "0.5.2",
|
| 17 |
+
"flash-linear-attention": "0.5.2",
|
| 18 |
+
"decision-local": "1.0.0"
|
| 19 |
+
}
|
| 20 |
+
},
|
| 21 |
+
"stderr_last_line": []
|
| 22 |
+
},
|
| 23 |
+
"schema_version": 1,
|
| 24 |
+
"public_base": "vllm/vllm-openai-rocm@sha256:1fd21abe66455b4df5a2e83629e97cdcc9d58913b16052d8118b92b239792339",
|
| 25 |
+
"build_exit_code": 0,
|
| 26 |
+
"gpu_validation": {
|
| 27 |
+
"status": "passed",
|
| 28 |
+
"scope": "Real packaged three-question example and explicit complete-input overflow rejection for each bundle. Exact response equality against qualified runtime on this request; not a replacement for full benchmark rerun.",
|
| 29 |
+
"models": {
|
| 30 |
+
"Decision-1.0-Sol": {
|
| 31 |
+
"bundle_manifest_sha256": "076558961011e924bf17084f940401150245bae6e135d4b1b0a6ee16be01f13c",
|
| 32 |
+
"example_source_sha256": "d52c20b602bd1049aecda55244e71c27d8ce44bd1aa8b1941db62ae41d31ba12",
|
| 33 |
+
"gpu": "AMD ROCm gfx942",
|
| 34 |
+
"request_count": 1,
|
| 35 |
+
"typed_questions": 3,
|
| 36 |
+
"response_bit_exact_against_qualified_runtime": true,
|
| 37 |
+
"matches_validated_runtime": true,
|
| 38 |
+
"wrapper_equals_direct_engine": true,
|
| 39 |
+
"overflow_rejected": true,
|
| 40 |
+
"board_product_name_verified": false
|
| 41 |
+
},
|
| 42 |
+
"Decision-1.0-Nox": {
|
| 43 |
+
"bundle_manifest_sha256": "adf5d88146d4f4a7fdcf0b265aa0c804a6116537c1e92bd620e40dfdf6803550",
|
| 44 |
+
"example_source_sha256": "d52c20b602bd1049aecda55244e71c27d8ce44bd1aa8b1941db62ae41d31ba12",
|
| 45 |
+
"gpu": "AMD ROCm gfx942",
|
| 46 |
+
"request_count": 1,
|
| 47 |
+
"typed_questions": 3,
|
| 48 |
+
"response_bit_exact_against_qualified_runtime": true,
|
| 49 |
+
"matches_validated_runtime": true,
|
| 50 |
+
"wrapper_equals_direct_engine": true,
|
| 51 |
+
"overflow_rejected": true,
|
| 52 |
+
"board_product_name_verified": false
|
| 53 |
+
}
|
| 54 |
+
}
|
| 55 |
+
},
|
| 56 |
+
"built_utc": "2026-09-21T12:57:54.147566+00:00",
|
| 57 |
+
"files": {
|
| 58 |
+
"Dockerfile.runtime": "36e81318bed2b6005ff46d6aa949533924b17d88ab8013a56caab77b1a0b5cf7",
|
| 59 |
+
"runtime-fla-requirements.lock": "35e1fedff9ca49092a7ada277bbd794abe7e8474e14a678a7e4bcec6406d0eb5",
|
| 60 |
+
"pyproject.toml": "6a557fbe472027af103ca2cfc07e977caab3e257de930aa57cf9fea8cf90f8a0",
|
| 61 |
+
"src/decision/__init__.py": "70de37df98b6fc8e3b9f9d43935ba31a32350496214c11adf8c5fba72c433313",
|
| 62 |
+
"src/decision/example.py": "d52c20b602bd1049aecda55244e71c27d8ce44bd1aa8b1941db62ae41d31ba12",
|
| 63 |
+
"src/decision/model.py": "ab428234d508a1245d3723c5a5bb0c796685abebd0447f77c7fbed9113954b21"
|
| 64 |
+
}
|
| 65 |
+
}
|
runtime-fla-requirements.lock
ADDED
|
@@ -0,0 +1,4 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Only the FLA overlay; all other dependencies are fixed by the public base digest.
|
| 2 |
+
# Install with --no-deps --require-hashes to preserve the ROCm Torch/Triton builds.
|
| 3 |
+
fla-core @ https://files.pythonhosted.org/packages/2d/ed/dfe19c4da779957eb6a42a26812f9b4e2280bf757a17a71933ff59ffcb98/fla_core-0.5.2-py3-none-any.whl --hash=sha256:5e830c85bad3d0d34677f98ac7074d08687a3756f0f0499d95ceb96eb6920761
|
| 4 |
+
flash-linear-attention @ https://files.pythonhosted.org/packages/90/d2/2070e3cf2148c5cce99ca4876633c4b7b89ec085323600bd3d47aeacd306/flash_linear_attention-0.5.2-py3-none-any.whl --hash=sha256:dcf405d81f5426393b59037097aa700d0f4a841465d5028d5aa543f4502f2400
|
runtime-provenance.json
ADDED
|
@@ -0,0 +1,172 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"public_base": "vllm/vllm-openai-rocm@sha256:1fd21abe66455b4df5a2e83629e97cdcc9d58913b16052d8118b92b239792339",
|
| 3 |
+
"registry": {
|
| 4 |
+
"status": 200,
|
| 5 |
+
"manifest_digest": "sha256:1fd21abe66455b4df5a2e83629e97cdcc9d58913b16052d8118b92b239792339",
|
| 6 |
+
"config_digest": "sha256:72b270afcf4b9b45f6ad0d76917415d206efc8c9d05399af065b53d6891c781a",
|
| 7 |
+
"layers": 36
|
| 8 |
+
},
|
| 9 |
+
"common_prefix_layers": 36,
|
| 10 |
+
"qualified_total_layers": 48,
|
| 11 |
+
"cpu_read_only_file_audits": [
|
| 12 |
+
{
|
| 13 |
+
"kind": "qualified_image",
|
| 14 |
+
"returncode": 0,
|
| 15 |
+
"data": {
|
| 16 |
+
"python": "3.12.13",
|
| 17 |
+
"versions": {
|
| 18 |
+
"__all__": [
|
| 19 |
+
"__version__",
|
| 20 |
+
"debug",
|
| 21 |
+
"cuda",
|
| 22 |
+
"git_version",
|
| 23 |
+
"hip",
|
| 24 |
+
"rocm",
|
| 25 |
+
"xpu"
|
| 26 |
+
],
|
| 27 |
+
"__version__": "2.12.0+git6bbd260",
|
| 28 |
+
"debug": false,
|
| 29 |
+
"cuda": null,
|
| 30 |
+
"git_version": "6bbd26020da1c6dc198625dfcdd968b1e4e6b1c5",
|
| 31 |
+
"hip": "7.2.53211",
|
| 32 |
+
"rocm": "7.2.3",
|
| 33 |
+
"xpu": null
|
| 34 |
+
},
|
| 35 |
+
"files": {
|
| 36 |
+
"version.py": {
|
| 37 |
+
"sha256": "94650c6ec9f5dc786a2b36ee2b7485b4d68e5c6bf1fdf01d0b12da19fde8bc70",
|
| 38 |
+
"bytes": 330
|
| 39 |
+
},
|
| 40 |
+
"__init__.py": {
|
| 41 |
+
"sha256": "d9dfff4b75d46e4c75572200a3466b70231d05b0318e38ac1bd121789165fb49",
|
| 42 |
+
"bytes": 109312
|
| 43 |
+
},
|
| 44 |
+
"_C.cpython-312-x86_64-linux-gnu.so": {
|
| 45 |
+
"sha256": "ca9f553cbb03d07a28f9de4a4e7a14510a26f1611bea2559aaa8ceb93065c1ce",
|
| 46 |
+
"bytes": 22632
|
| 47 |
+
},
|
| 48 |
+
"lib/libtorch_hip.so": {
|
| 49 |
+
"sha256": "72d4b50fef7ee355ad49b7cbaea3ebe982187b05116a9ef7b50321449cffa0ce",
|
| 50 |
+
"bytes": 415569576
|
| 51 |
+
},
|
| 52 |
+
"lib/libtorch_cpu.so": {
|
| 53 |
+
"sha256": "c0c8bb597e689b8e67266a21c7a65f0eac3089cb94e0c4ed8274b7d30db804ea",
|
| 54 |
+
"bytes": 340291896
|
| 55 |
+
}
|
| 56 |
+
},
|
| 57 |
+
"packages": {
|
| 58 |
+
"torch": "2.12.0+git6bbd260",
|
| 59 |
+
"triton": "3.7.1+gitf0b55c07",
|
| 60 |
+
"transformers": "5.17.0",
|
| 61 |
+
"tokenizers": "0.23.2",
|
| 62 |
+
"safetensors": "0.8.0",
|
| 63 |
+
"numpy": "2.3.5",
|
| 64 |
+
"einops": "0.8.2",
|
| 65 |
+
"packaging": "26.3",
|
| 66 |
+
"huggingface-hub": "1.31.0",
|
| 67 |
+
"fla-core": null,
|
| 68 |
+
"flash-linear-attention": null,
|
| 69 |
+
"ninja": "1.13.2",
|
| 70 |
+
"PyYAML": "6.0.3",
|
| 71 |
+
"regex": "2026.9.10",
|
| 72 |
+
"tqdm": "4.70.1",
|
| 73 |
+
"filelock": "3.32.7"
|
| 74 |
+
}
|
| 75 |
+
},
|
| 76 |
+
"error_tail": []
|
| 77 |
+
},
|
| 78 |
+
{
|
| 79 |
+
"kind": "public_base",
|
| 80 |
+
"returncode": 0,
|
| 81 |
+
"data": {
|
| 82 |
+
"python": "3.12.13",
|
| 83 |
+
"versions": {
|
| 84 |
+
"__all__": [
|
| 85 |
+
"__version__",
|
| 86 |
+
"debug",
|
| 87 |
+
"cuda",
|
| 88 |
+
"git_version",
|
| 89 |
+
"hip",
|
| 90 |
+
"rocm",
|
| 91 |
+
"xpu"
|
| 92 |
+
],
|
| 93 |
+
"__version__": "2.12.0+git6bbd260",
|
| 94 |
+
"debug": false,
|
| 95 |
+
"cuda": null,
|
| 96 |
+
"git_version": "6bbd26020da1c6dc198625dfcdd968b1e4e6b1c5",
|
| 97 |
+
"hip": "7.2.53211",
|
| 98 |
+
"rocm": "7.2.3",
|
| 99 |
+
"xpu": null
|
| 100 |
+
},
|
| 101 |
+
"files": {
|
| 102 |
+
"version.py": {
|
| 103 |
+
"sha256": "94650c6ec9f5dc786a2b36ee2b7485b4d68e5c6bf1fdf01d0b12da19fde8bc70",
|
| 104 |
+
"bytes": 330
|
| 105 |
+
},
|
| 106 |
+
"__init__.py": {
|
| 107 |
+
"sha256": "d9dfff4b75d46e4c75572200a3466b70231d05b0318e38ac1bd121789165fb49",
|
| 108 |
+
"bytes": 109312
|
| 109 |
+
},
|
| 110 |
+
"_C.cpython-312-x86_64-linux-gnu.so": {
|
| 111 |
+
"sha256": "ca9f553cbb03d07a28f9de4a4e7a14510a26f1611bea2559aaa8ceb93065c1ce",
|
| 112 |
+
"bytes": 22632
|
| 113 |
+
},
|
| 114 |
+
"lib/libtorch_hip.so": {
|
| 115 |
+
"sha256": "72d4b50fef7ee355ad49b7cbaea3ebe982187b05116a9ef7b50321449cffa0ce",
|
| 116 |
+
"bytes": 415569576
|
| 117 |
+
},
|
| 118 |
+
"lib/libtorch_cpu.so": {
|
| 119 |
+
"sha256": "c0c8bb597e689b8e67266a21c7a65f0eac3089cb94e0c4ed8274b7d30db804ea",
|
| 120 |
+
"bytes": 340291896
|
| 121 |
+
}
|
| 122 |
+
},
|
| 123 |
+
"packages": {
|
| 124 |
+
"torch": "2.12.0+git6bbd260",
|
| 125 |
+
"triton": "3.7.1+gitf0b55c07",
|
| 126 |
+
"transformers": "5.17.0",
|
| 127 |
+
"tokenizers": "0.23.2",
|
| 128 |
+
"safetensors": "0.8.0",
|
| 129 |
+
"numpy": "2.3.5",
|
| 130 |
+
"einops": "0.8.2",
|
| 131 |
+
"packaging": "26.3",
|
| 132 |
+
"huggingface-hub": "1.31.0",
|
| 133 |
+
"fla-core": null,
|
| 134 |
+
"flash-linear-attention": null,
|
| 135 |
+
"ninja": "1.13.2",
|
| 136 |
+
"PyYAML": "6.0.3",
|
| 137 |
+
"regex": "2026.9.10",
|
| 138 |
+
"tqdm": "4.70.1",
|
| 139 |
+
"filelock": "3.32.7"
|
| 140 |
+
}
|
| 141 |
+
},
|
| 142 |
+
"error_tail": []
|
| 143 |
+
}
|
| 144 |
+
],
|
| 145 |
+
"history_source_pins": {
|
| 146 |
+
"rocm_dev": "rocm/dev-ubuntu-22.04:7.2.3-complete",
|
| 147 |
+
"torch_commit": "6bbd26020da1c6dc198625dfcdd968b1e4e6b1c5",
|
| 148 |
+
"triton_short_commit": "f0b55c0"
|
| 149 |
+
},
|
| 150 |
+
"validation_boundary": "Public base provenance and CPU metadata/file comparison only; no GPU inference or rebuilt-image qualification in this audit.",
|
| 151 |
+
"fla_wheels": [
|
| 152 |
+
{
|
| 153 |
+
"name": "fla-core",
|
| 154 |
+
"version": "0.5.2",
|
| 155 |
+
"filename": "fla_core-0.5.2-py3-none-any.whl",
|
| 156 |
+
"url": "https://files.pythonhosted.org/packages/2d/ed/dfe19c4da779957eb6a42a26812f9b4e2280bf757a17a71933ff59ffcb98/fla_core-0.5.2-py3-none-any.whl",
|
| 157 |
+
"sha256": "5e830c85bad3d0d34677f98ac7074d08687a3756f0f0499d95ceb96eb6920761",
|
| 158 |
+
"download_sha256_verified": true,
|
| 159 |
+
"bytes": 819225
|
| 160 |
+
},
|
| 161 |
+
{
|
| 162 |
+
"name": "flash-linear-attention",
|
| 163 |
+
"version": "0.5.2",
|
| 164 |
+
"filename": "flash_linear_attention-0.5.2-py3-none-any.whl",
|
| 165 |
+
"url": "https://files.pythonhosted.org/packages/90/d2/2070e3cf2148c5cce99ca4876633c4b7b89ec085323600bd3d47aeacd306/flash_linear_attention-0.5.2-py3-none-any.whl",
|
| 166 |
+
"sha256": "dcf405d81f5426393b59037097aa700d0f4a841465d5028d5aa543f4502f2400",
|
| 167 |
+
"download_sha256_verified": true,
|
| 168 |
+
"bytes": 399590
|
| 169 |
+
}
|
| 170 |
+
],
|
| 171 |
+
"verified_utc": "2026-09-21"
|
| 172 |
+
}
|
runtime.json
ADDED
|
@@ -0,0 +1,23 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"torch": "2.12.0+git6bbd260",
|
| 3 |
+
"torch_git": "6bbd26020da1c6dc198625dfcdd968b1e4e6b1c5",
|
| 4 |
+
"hip": "7.2.53211",
|
| 5 |
+
"triton": "3.7.1",
|
| 6 |
+
"fla": "0.5.2",
|
| 7 |
+
"image_digest": "sha256:670f9f4cced18cccfb196188a3d42ff81ab617f17c447bfe033e150824d3448b",
|
| 8 |
+
"wheels": {
|
| 9 |
+
"fla_core-0.5.2-py3-none-any.whl": "5e830c85bad3d0d34677f98ac7074d08687a3756f0f0499d95ceb96eb6920761",
|
| 10 |
+
"flash_linear_attention-0.5.2-py3-none-any.whl": "dcf405d81f5426393b59037097aa700d0f4a841465d5028d5aa543f4502f2400"
|
| 11 |
+
},
|
| 12 |
+
"gated_delta": "fla.ops.gated_delta_rule.chunk",
|
| 13 |
+
"causal_conv": "transformers-reference-PyTorch",
|
| 14 |
+
"full_attention": "sdpa",
|
| 15 |
+
"runtime_installation": "isolated PYTHONPATH, no shared image mutation",
|
| 16 |
+
"warm_start": "successful pointer head warmup checkpoint100; no failed smoke weights reused",
|
| 17 |
+
"transformers": "5.17.0",
|
| 18 |
+
"tokenizers": "0.23.2",
|
| 19 |
+
"safetensors": "0.8.0",
|
| 20 |
+
"huggingface-hub": "1.31.0",
|
| 21 |
+
"accelerate": "1.15.0",
|
| 22 |
+
"numpy": "2.3.5"
|
| 23 |
+
}
|
src/decision/__init__.py
ADDED
|
@@ -0,0 +1,5 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""The installable wrapper delegates numerical inference to the bundled engine."""
|
| 2 |
+
from .model import DecisionModel
|
| 3 |
+
|
| 4 |
+
__all__ = ["DecisionModel"]
|
| 5 |
+
__version__ = "1.0.0"
|
src/decision/example.py
ADDED
|
@@ -0,0 +1,61 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Run the real model-card request and save outputs; no invented predictions."""
|
| 2 |
+
import argparse
|
| 3 |
+
import hashlib
|
| 4 |
+
import json
|
| 5 |
+
from pathlib import Path
|
| 6 |
+
|
| 7 |
+
from .model import DecisionModel
|
| 8 |
+
|
| 9 |
+
REQUEST = {
|
| 10 |
+
'state': 'The customer reports that the same invoice was charged twice. They ask for a refund. There is no product outage.',
|
| 11 |
+
'questions': {
|
| 12 |
+
'destination': {'type': 'choice', 'instructions': 'Choose the team that handles this request.',
|
| 13 |
+
'criteria': {'billing': 'Invoices, payments, refunds and duplicate charges',
|
| 14 |
+
'technical': 'Product errors and troubleshooting'}},
|
| 15 |
+
'refund_requested': {'type': 'noul', 'instructions': 'Does the customer explicitly ask for a refund?'},
|
| 16 |
+
'urgency': {'type': 'score', 'instructions': 'Rate urgency using only these ordered levels.',
|
| 17 |
+
'criteria': ['Routine information request with no payment problem or outage',
|
| 18 |
+
'A payment or billing problem, with no product outage',
|
| 19 |
+
'An active product outage stopping the customer from working']},
|
| 20 |
+
},
|
| 21 |
+
}
|
| 22 |
+
|
| 23 |
+
|
| 24 |
+
def main():
|
| 25 |
+
parser = argparse.ArgumentParser()
|
| 26 |
+
parser.add_argument('model', help='Exported local directory or Hugging Face repo ID')
|
| 27 |
+
parser.add_argument('--revision', help='Required for a repo ID; prefer a full commit SHA')
|
| 28 |
+
parser.add_argument('--device', default='cuda:0')
|
| 29 |
+
parser.add_argument('--local-files-only', action='store_true')
|
| 30 |
+
parser.add_argument('--allow-unvalidated-runtime', action='store_true')
|
| 31 |
+
parser.add_argument('--output', type=Path, required=True)
|
| 32 |
+
args = parser.parse_args()
|
| 33 |
+
model = DecisionModel.from_pretrained(args.model, revision=args.revision, device=args.device,
|
| 34 |
+
local_files_only=args.local_files_only,
|
| 35 |
+
allow_unvalidated_runtime=args.allow_unvalidated_runtime)
|
| 36 |
+
response = model.decide(**REQUEST)
|
| 37 |
+
# Prove wrapper pass-through against the unchanged engine on this exact request.
|
| 38 |
+
reference = model._engine.decide(**REQUEST)
|
| 39 |
+
if response != reference:
|
| 40 |
+
raise AssertionError('Wrapper/direct-engine response mismatch')
|
| 41 |
+
overflow_message = None
|
| 42 |
+
try:
|
| 43 |
+
model.decide('overflow-test ' * 20000, {'check': {'type': 'noul', 'instructions': 'Is this a test?'}})
|
| 44 |
+
except ValueError as exc:
|
| 45 |
+
if 'no truncation allowed' not in str(exc):
|
| 46 |
+
raise
|
| 47 |
+
overflow_message = str(exc)
|
| 48 |
+
if overflow_message is None:
|
| 49 |
+
raise AssertionError('Oversized complete input was not rejected')
|
| 50 |
+
record = {'request': REQUEST, 'response': response, 'direct_engine_exact_response': True,
|
| 51 |
+
'overflow_rejected': True, 'overflow_message': overflow_message,
|
| 52 |
+
'bundle_manifest_sha256': hashlib.sha256((model.bundle_path / 'bundle-manifest.json').read_bytes()).hexdigest(),
|
| 53 |
+
'runtime': model.runtime, 'revision': args.revision, 'device': args.device,
|
| 54 |
+
'model_name': response['model'], 'example_source_sha256': hashlib.sha256(Path(__file__).read_bytes()).hexdigest()}
|
| 55 |
+
args.output.parent.mkdir(parents=True, exist_ok=True)
|
| 56 |
+
args.output.write_text(json.dumps(record, ensure_ascii=False, indent=2) + '\n')
|
| 57 |
+
print(json.dumps(response, ensure_ascii=False, indent=2))
|
| 58 |
+
|
| 59 |
+
|
| 60 |
+
if __name__ == '__main__':
|
| 61 |
+
main()
|