

Focus model card on published keyboard models and direct correction pilot
Browse files- README.md +13 -32
- comparison.png +2 -2
README.md
CHANGED
|
@@ -24,11 +24,9 @@ Chime is a small English model that predicts the next word and completes the wor
|
|
| 24 |
|
| 25 |
**2.03M parameters · 2.22 MB int8 · 161.6M training words · 2h 2m on one A100 · 3.09–3.24 ms warm p95 on two Pixels**
|
| 26 |
|
| 27 |
-
Chime
|
| 28 |
|
| 29 |
-
|
| 30 |
-
|
| 31 |
-

|
| 32 |
|
| 33 |
## Model details
|
| 34 |
|
|
@@ -57,39 +55,24 @@ A trailing space asks for the next word; without one, the last word is completed
|
|
| 57 |
|
| 58 |
`cifg_int8.bin` is the int8 model with its vocabulary, the file LocalType ships, and `read_bin` in `inference.py` reads both. `model.safetensors` holds the float32 weights; `config.json` lists their shapes.
|
| 59 |
|
| 60 |
-
##
|
| 61 |
-
|
| 62 |
-
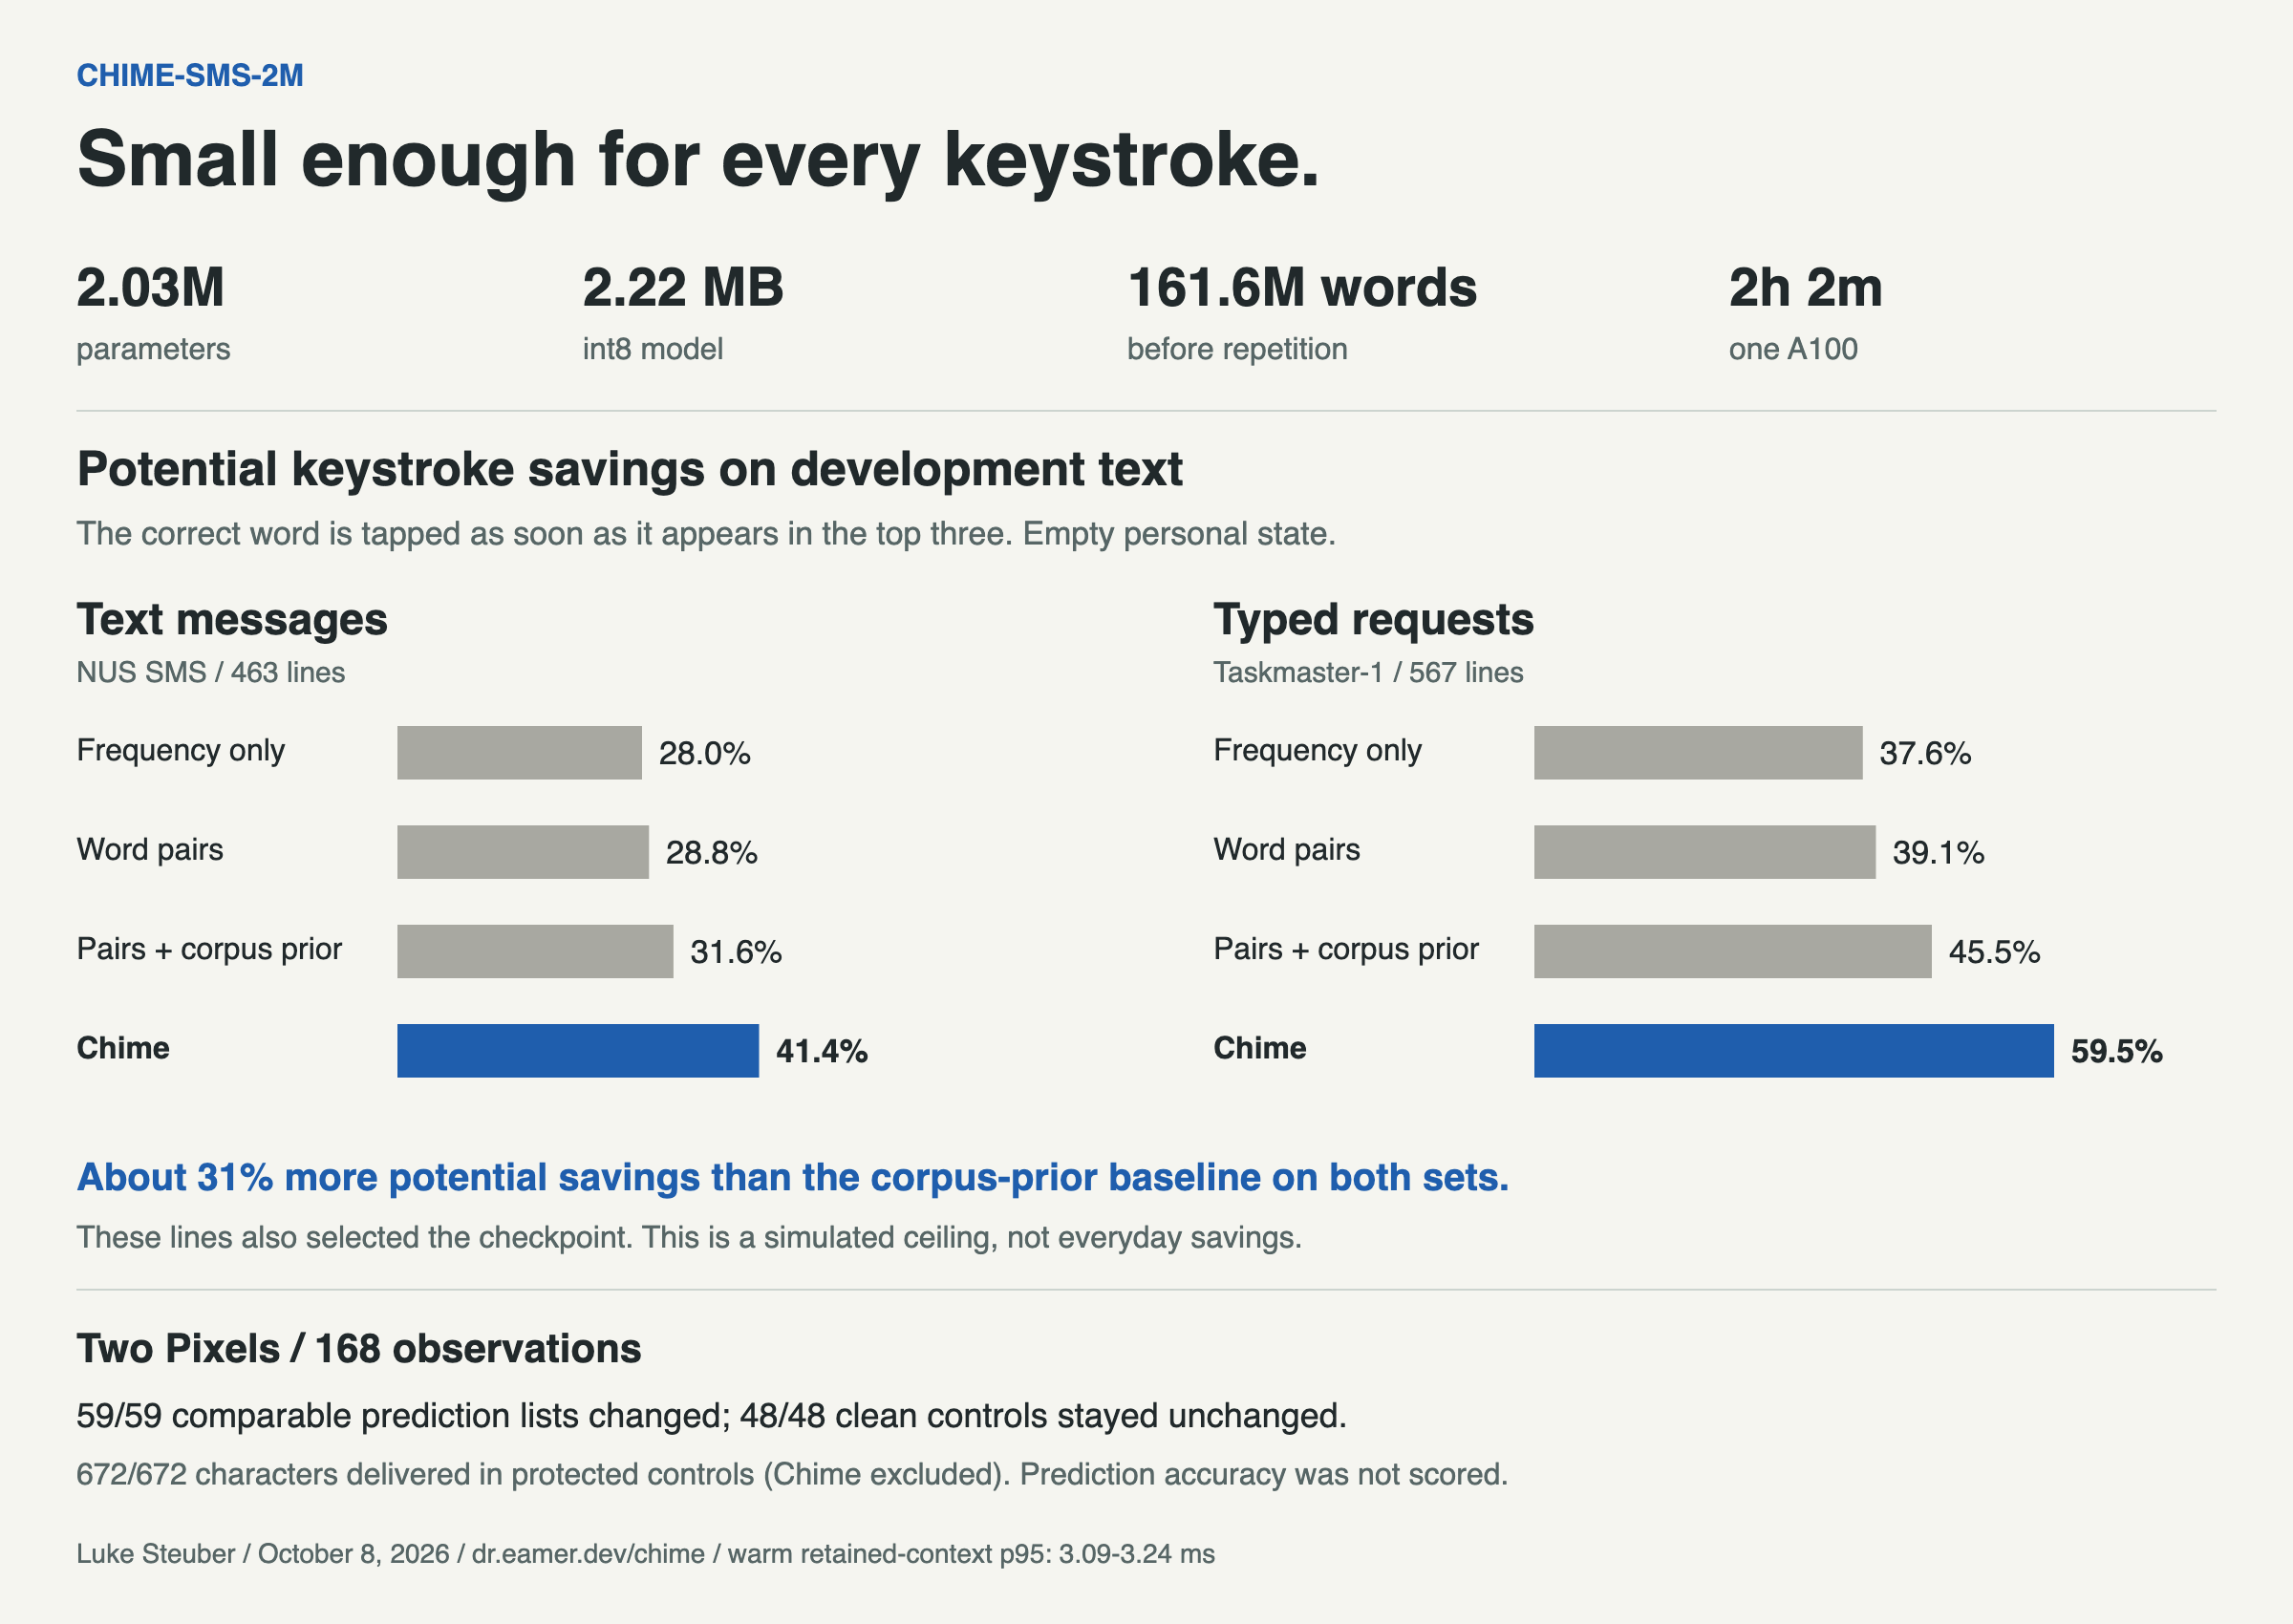
Each ranker was scored by the same code on development text Chime was not trained on: 463 lines of the NUS SMS corpus and 567 written requests from Taskmaster-1, with nothing learned about the person typing. *Keystrokes saved* counts the characters skipped by tapping the right word as soon as it appears among three suggestions. *Top 3* is how often the next word is one of the first three suggestions.
|
| 63 |
-
|
| 64 |
-
| Ranker | Keystrokes saved, SMS | Keystrokes saved, Taskmaster-1 | Top 3, SMS | Top 3, Taskmaster-1 |
|
| 65 |
-
| --- | ---: | ---: | ---: | ---: |
|
| 66 |
-
| Word frequency only | 28.0% | 37.6% | 6.1% | 9.0% |
|
| 67 |
-
| N-gram ranker | 28.8% | 39.1% | 7.3% | 11.1% |
|
| 68 |
-
| N-gram ranker with corpus prior | 31.6% | 45.5% | 12.8% | 23.9% |
|
| 69 |
-
| **Chime-SMS-2M** | **41.4%** | **59.5%** | **19.3%** | **42.3%** |
|
| 70 |
-
|
| 71 |
-
Against the strongest baseline, Chime offers about 31% more potential keystroke savings on both sets. The same lines were used to choose the checkpoint, so these are development results, not a held-out test.
|
| 72 |
|
| 73 |
-
|
| 74 |
|
| 75 |
-
|
| 76 |
|
| 77 |
-
|
| 78 |
-
|
| 79 |
-
|
|
| 80 |
-
|
|
| 81 |
-
| Pixel 9a | 12/12 | 12/12 | 24/24 unchanged | 24/24 exact |
|
| 82 |
-
| Pixel 10 | 11/12 | 12/12 | 24/24 unchanged | 24/24 exact |
|
| 83 |
-
|
| 84 |
-
No wrong isolated replacements occurred. Live neural suggestions were verified in all 60 eligible on-arm observations. Among the 59 ordinary pairs with identical final editor text, every post-typing prediction list differed. For example, after `please right `, Chime offered `away / now / ahead`; the non-neural arm offered `to / now / away`, on both phones.
|
| 85 |
|
| 86 |
-
|
| 87 |
|
| 88 |
-
|
| 89 |
|
| 90 |
-
|
| 91 |
|
| 92 |
-
|
| 93 |
|
| 94 |
## Runtime comparison
|
| 95 |
|
|
@@ -140,8 +123,6 @@ I trained it from scratch for three passes (102,195 updates) on one A100 in abou
|
|
| 140 |
|
| 141 |
×8 means repeating NUS SMS, Taskmaster-1 and OpenAssistant lines eight times per pass, while Taskmaster-3 and SODA appear once. It changes exposure, not parameter count or context size. Human-written lines form 12.868% of the weighted pass; SODA remains the majority. Repeated tokens are not additional unique data. The earlier ×4 checkpoint has the same architecture and is retained for comparison and rollback.
|
| 142 |
|
| 143 |
-
On the same Kotlin development scorer, ×4/×8 potential savings were 40.70/41.44% on SMS and 58.61/59.50% on Taskmaster-1. Paired differences were +0.73 percentage points [95% interval +0.40, +1.07] and +0.89 [+0.62, +1.17]. The mostly synthetic 5,000-line sample fell from 65.04% to 64.93% (−0.12 points [−0.17, −0.06], using unrounded scores). These checkpoints differ in training backend and update count, so the comparison does not isolate oversampling. Intervals use 2,000 line-bootstrap resamples; dialogue clustering and SMS sender overlap limit their interpretation.
|
| 144 |
-
|
| 145 |
## Limitations
|
| 146 |
|
| 147 |
- English only. Suggestions reflect older Singapore texting, task dialogue, assistant prompts and synthetic dialogue, and the fixed vocabulary will not learn new words or names.
|
|
|
|
| 24 |
|
| 25 |
**2.03M parameters · 2.22 MB int8 · 161.6M training words · 2h 2m on one A100 · 3.09–3.24 ms warm p95 on two Pixels**
|
| 26 |
|
| 27 |
+
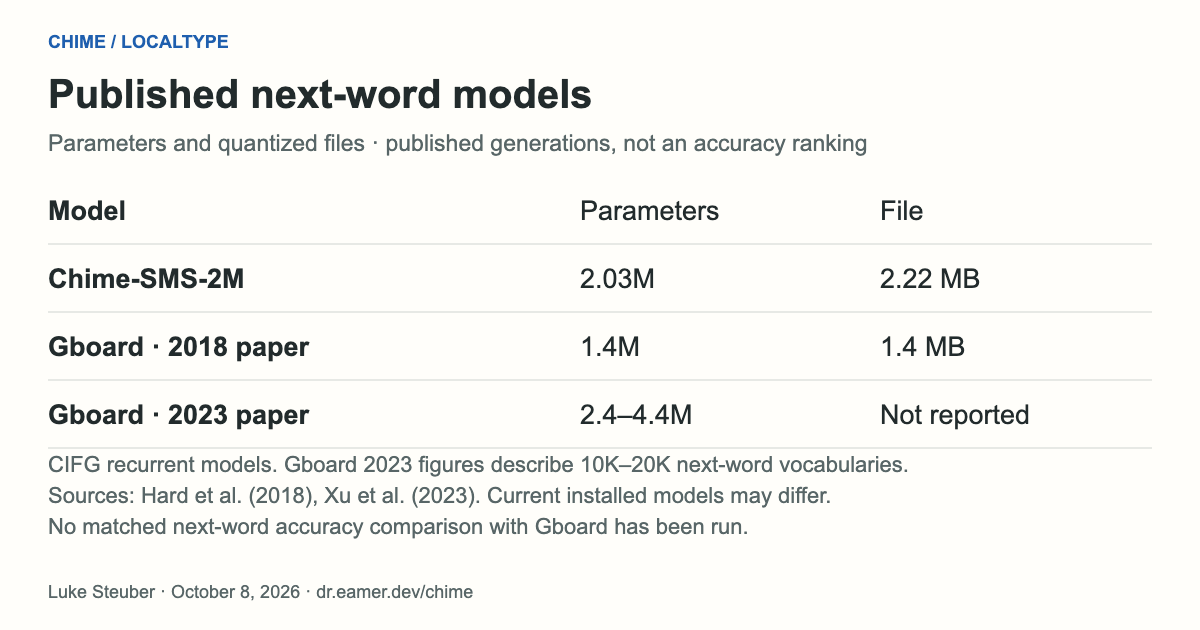
Chime uses the CIFG recurrent architecture described for Gboard in 2018. Its 2.03M parameters sit alongside the published 1.4M model (2018) and 2.4–4.4M next-word models (2023). This compares published model sizes, not current installed models or prediction accuracy. [Keyboard comparisons and shareable cards](https://dr.eamer.dev/chime/writeup.html) report the separate physical correction pilot.
|
| 28 |
|
| 29 |
+

|
|
|
|
|
|
|
| 30 |
|
| 31 |
## Model details
|
| 32 |
|
|
|
|
| 55 |
|
| 56 |
`cifg_int8.bin` is the int8 model with its vocabulary, the file LocalType ships, and `read_bin` in `inference.py` reads both. `model.safetensors` holds the float32 weights; `config.json` lists their shapes.
|
| 57 |
|
| 58 |
+
## Comparison with other keyboards
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 59 |
|
| 60 |
+
The architecture comparison comes from [Hard et al. (2018)](https://arxiv.org/abs/1811.03604) and [Xu et al. (2023)](https://arxiv.org/abs/2305.18465). These papers describe generations of Gboard models, not necessarily the model in a current installation. Chime and Gboard have not been scored on a matched next-word evaluation. Different papers’ data and metrics cannot establish an accuracy ranking.
|
| 61 |
|
| 62 |
+
A separate automated touch pilot compared installed LocalType 0.5.9 (29) with Gboard 18.4.1.985164140-beta-arm64-v8a on 42 invented inputs per keyboard per phone. No-learning fields excluded Chime; existing personal state was retained.
|
| 63 |
|
| 64 |
+
| Phone | LocalType isolated repairs | Gboard isolated repairs |
|
| 65 |
+
| --- | ---: | ---: |
|
| 66 |
+
| Pixel 9a | 11/12 | 12/12 |
|
| 67 |
+
| Pixel 10 | 9/12 | 11/12 |
|
|
|
|
|
|
|
|
|
|
|
|
|
| 68 |
|
| 69 |
+
Neither keyboard made a wrong replacement in the isolated typo cases. Both preserved all 48 ordinary clean controls and 672 characters in 48 protected delivery cases. In the separate identifier probe, LocalType changed `xkcd` to `did` on both phones; Gboard preserved it. Gboard added the apostrophe in `lukes keyboard`; LocalType left it unchanged. This is a small correction and delivery pilot, not a test of Chime’s next-word quality. [Methods and remaining phrase outputs](https://dr.eamer.dev/chime/methods.html#phone-comparison).
|
| 70 |
|
| 71 |
+
## Development prediction measurements
|
| 72 |
|
| 73 |
+
On 463 NUS SMS development lines, Chime scored 41.44% potential keystroke savings and 19.32% next-word top-three accuracy. On 567 Taskmaster-1 requests it scored 59.50% and 42.34%. The same Kotlin scorer started with no personal learning. Potential savings assumes the correct word is tapped as soon as it appears among three suggestions, so it is a simulated ceiling. These lines were not training text but were used to select the checkpoint; no held-out or everyday savings result is claimed. These measurements cannot be compared with correction counts or another keyboard’s prediction scores on different data.
|
| 74 |
|
| 75 |
+
A separate ordinary-field integration pilot verified live Chime predictions in all 60 eligible observations, with empty isolated learning before each case. It preserved the tested clean text and protected delivery controls. No next-word target was scored or prediction tapped. Different field and learning policies prevent combining that run with the Gboard pilot into a model ranking.
|
| 76 |
|
| 77 |
## Runtime comparison
|
| 78 |
|
|
|
|
| 123 |
|
| 124 |
×8 means repeating NUS SMS, Taskmaster-1 and OpenAssistant lines eight times per pass, while Taskmaster-3 and SODA appear once. It changes exposure, not parameter count or context size. Human-written lines form 12.868% of the weighted pass; SODA remains the majority. Repeated tokens are not additional unique data. The earlier ×4 checkpoint has the same architecture and is retained for comparison and rollback.
|
| 125 |
|
|
|
|
|
|
|
| 126 |
## Limitations
|
| 127 |
|
| 128 |
- English only. Suggestions reflect older Singapore texting, task dialogue, assistant prompts and synthetic dialogue, and the fixed vocabulary will not learn new words or names.
|
comparison.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|