

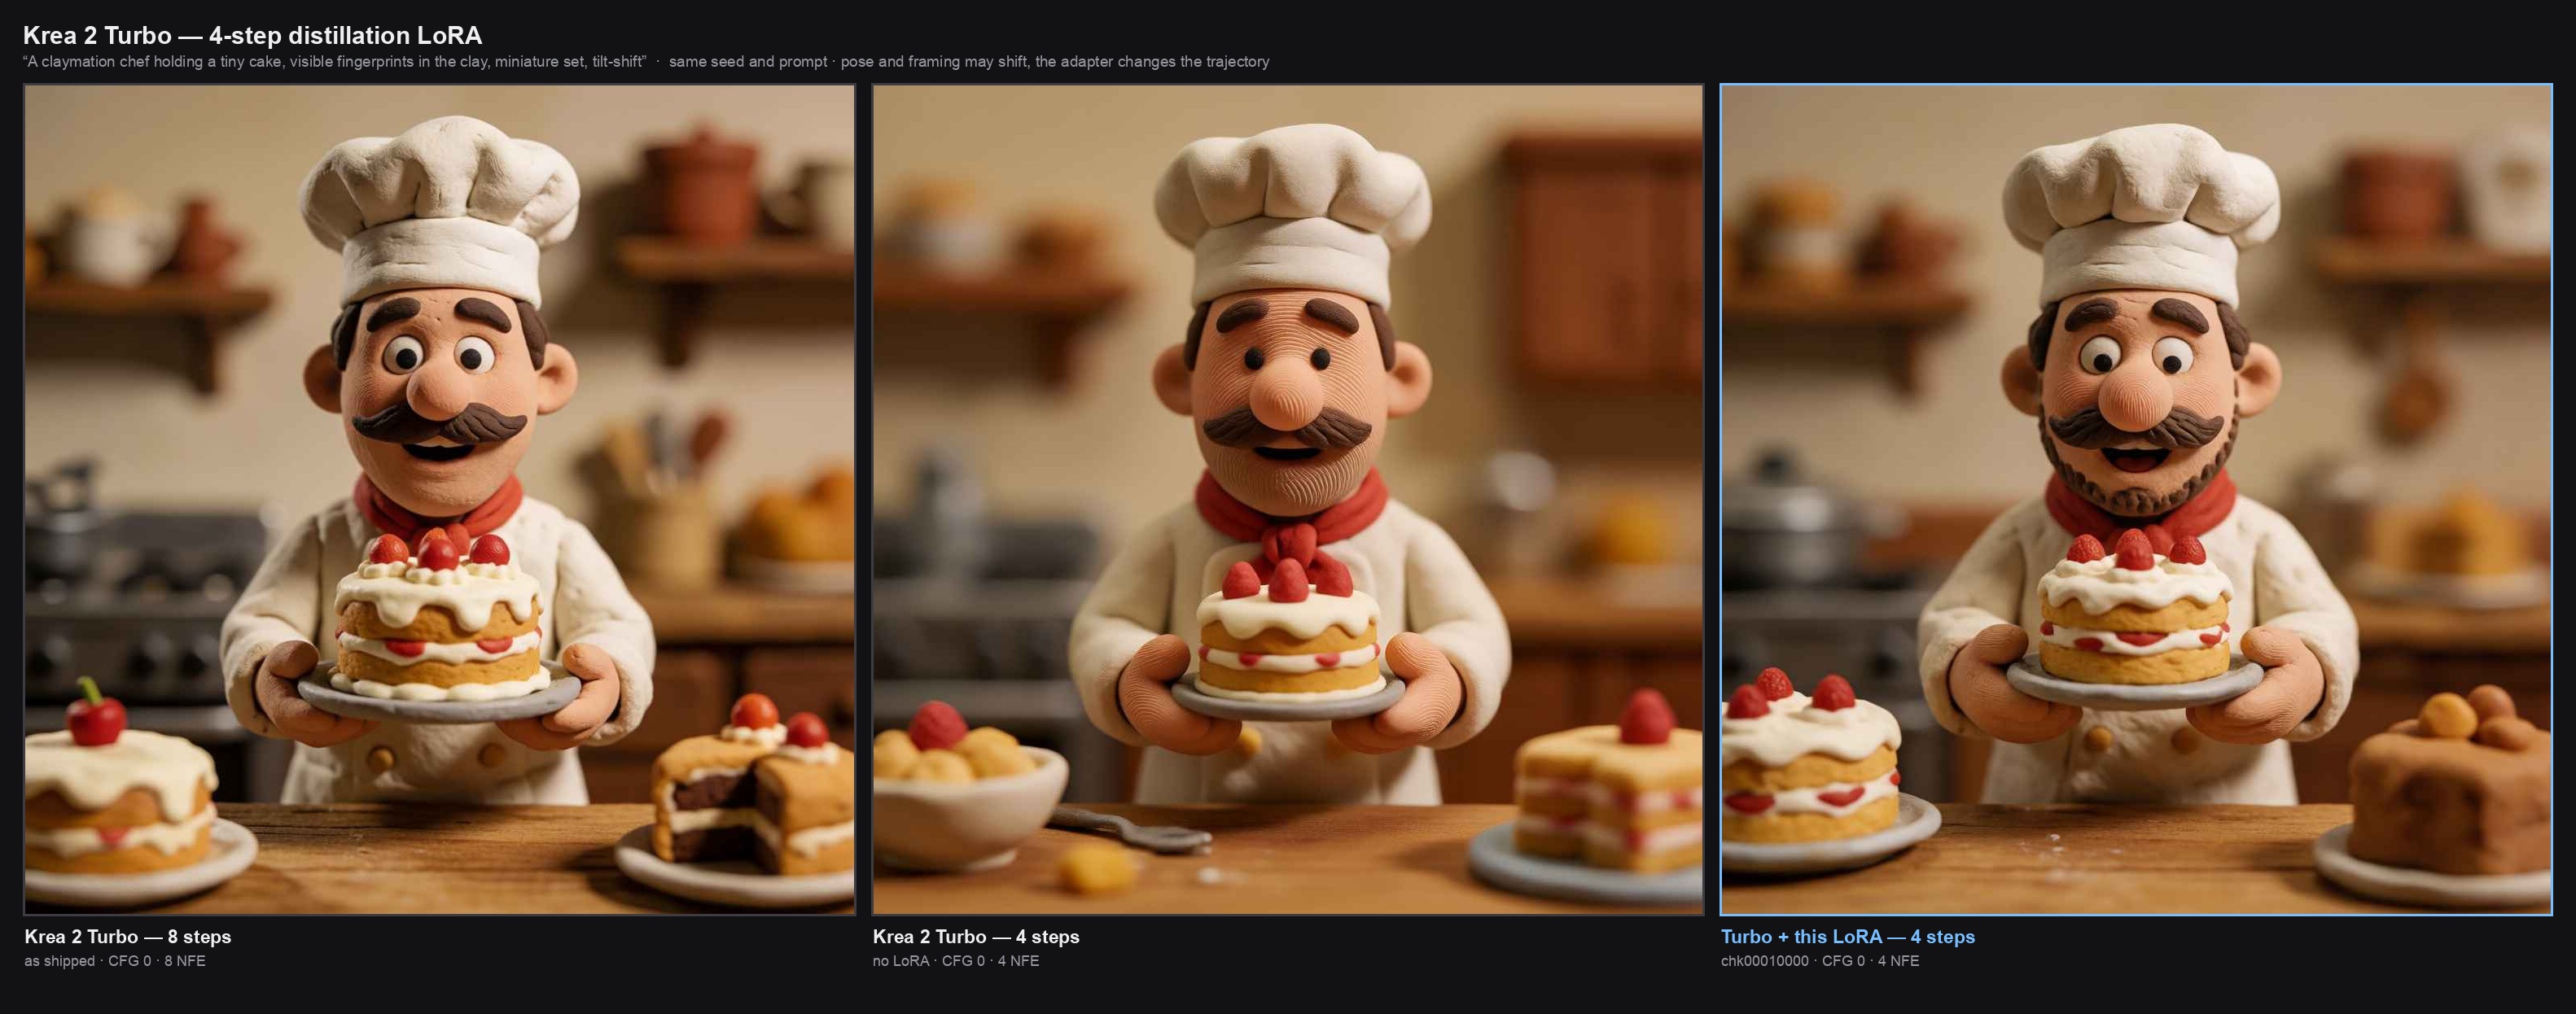
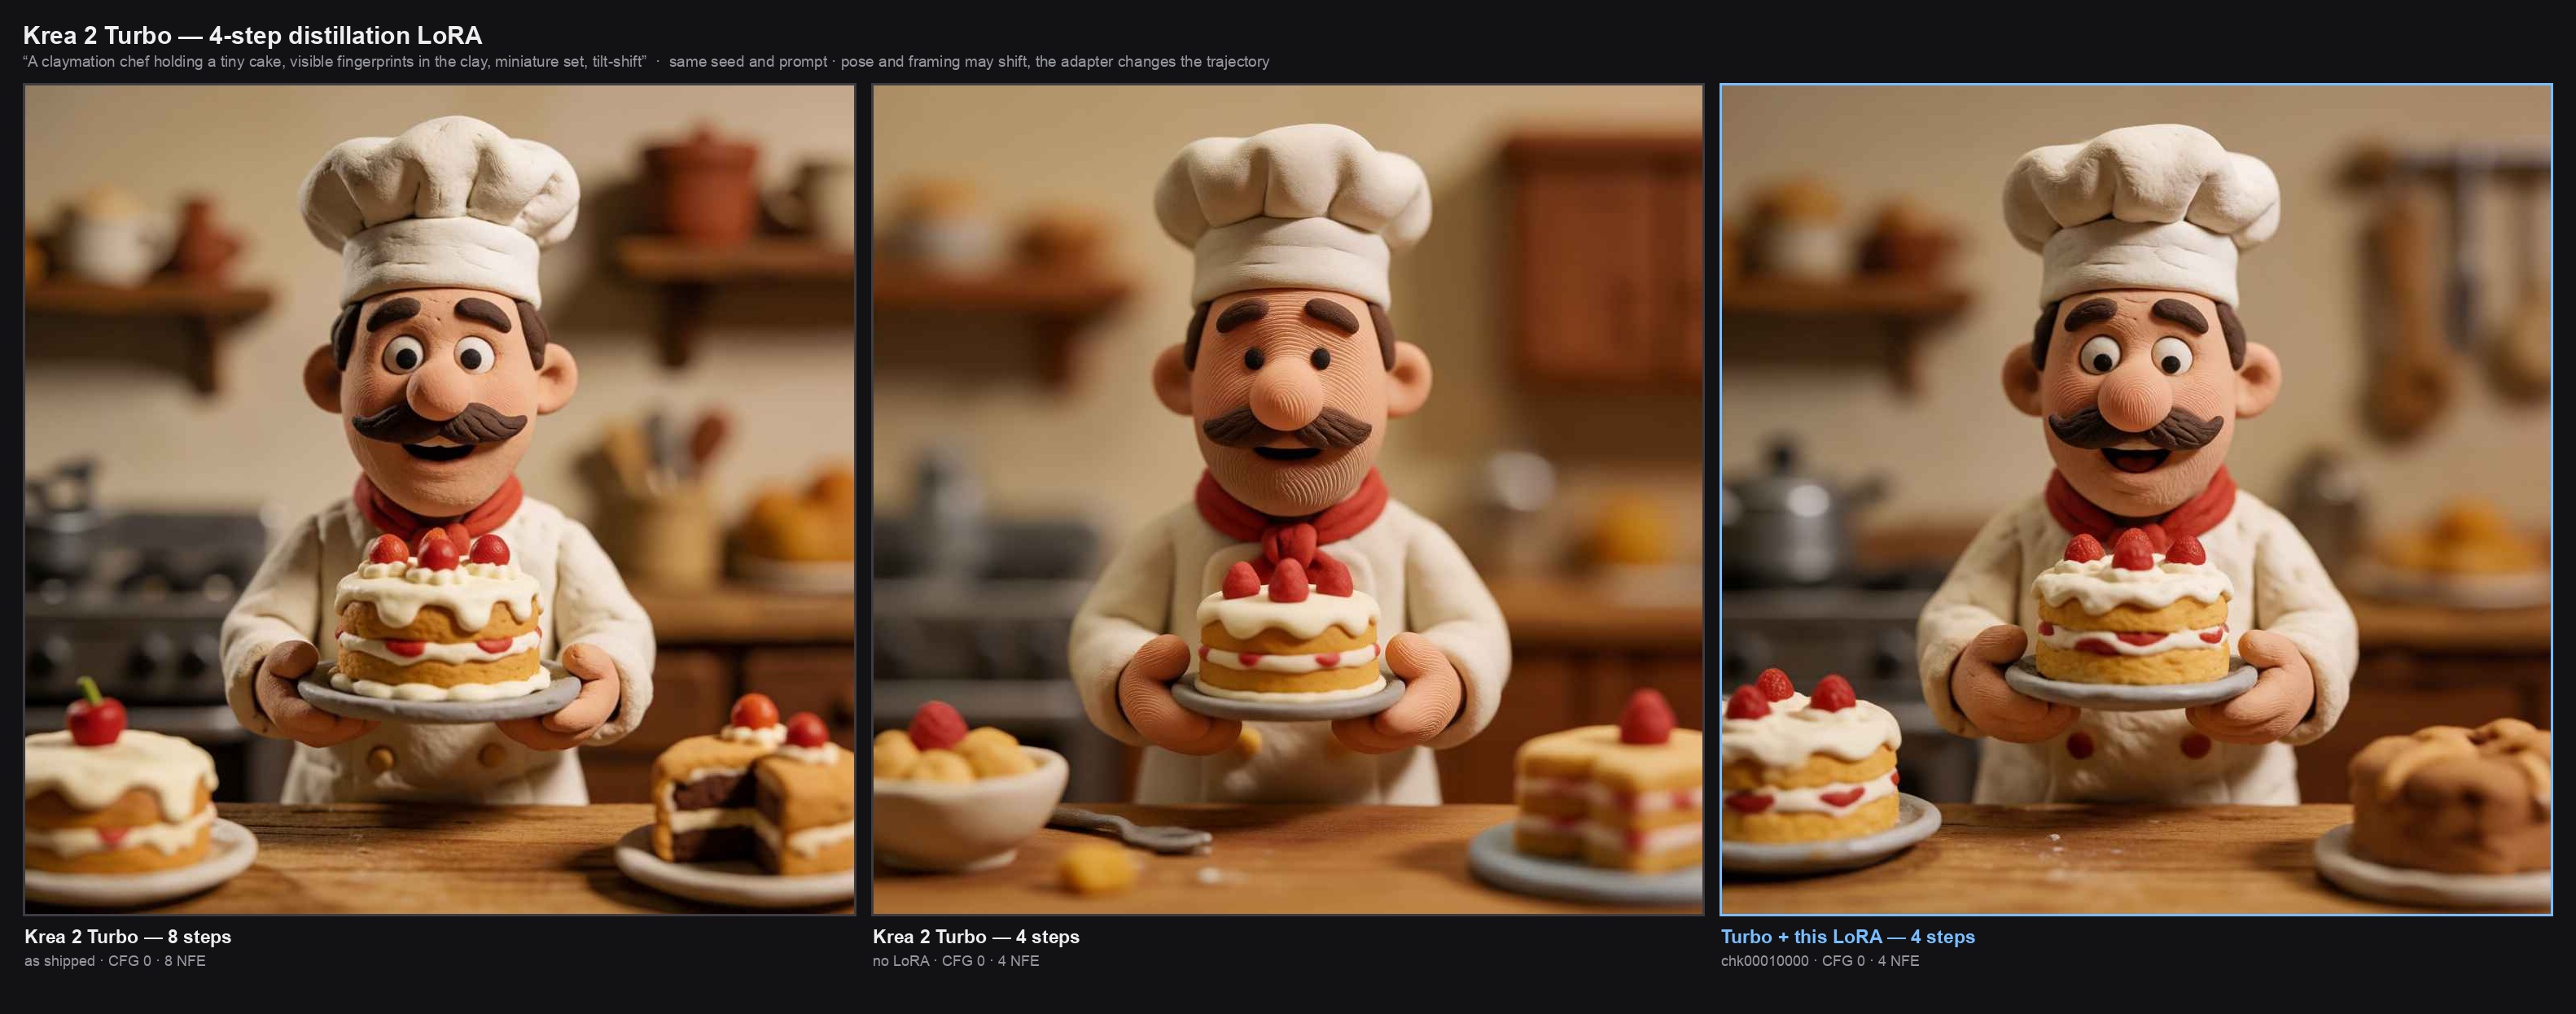
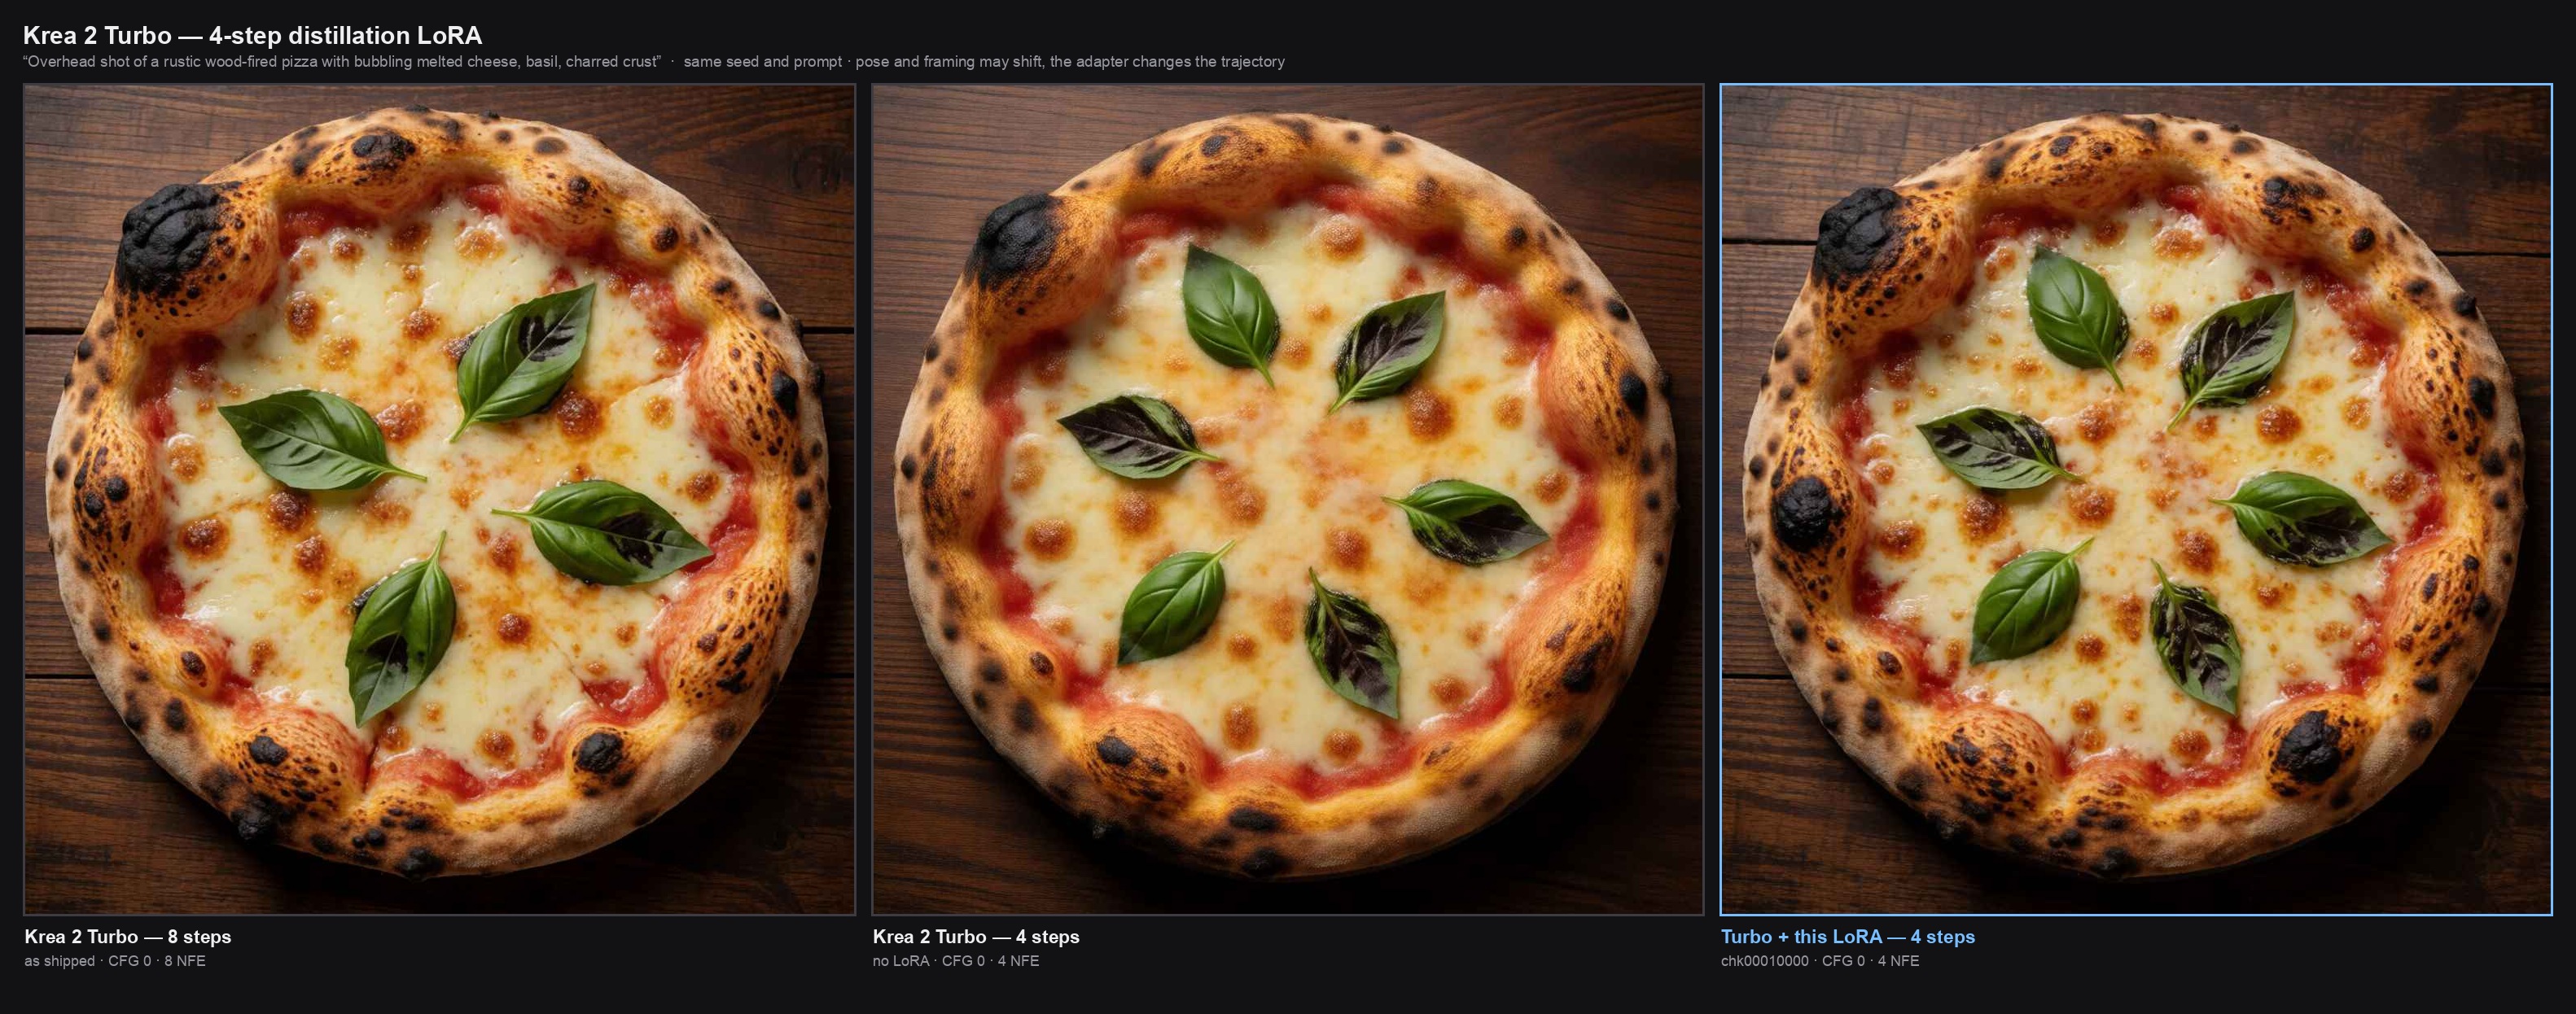
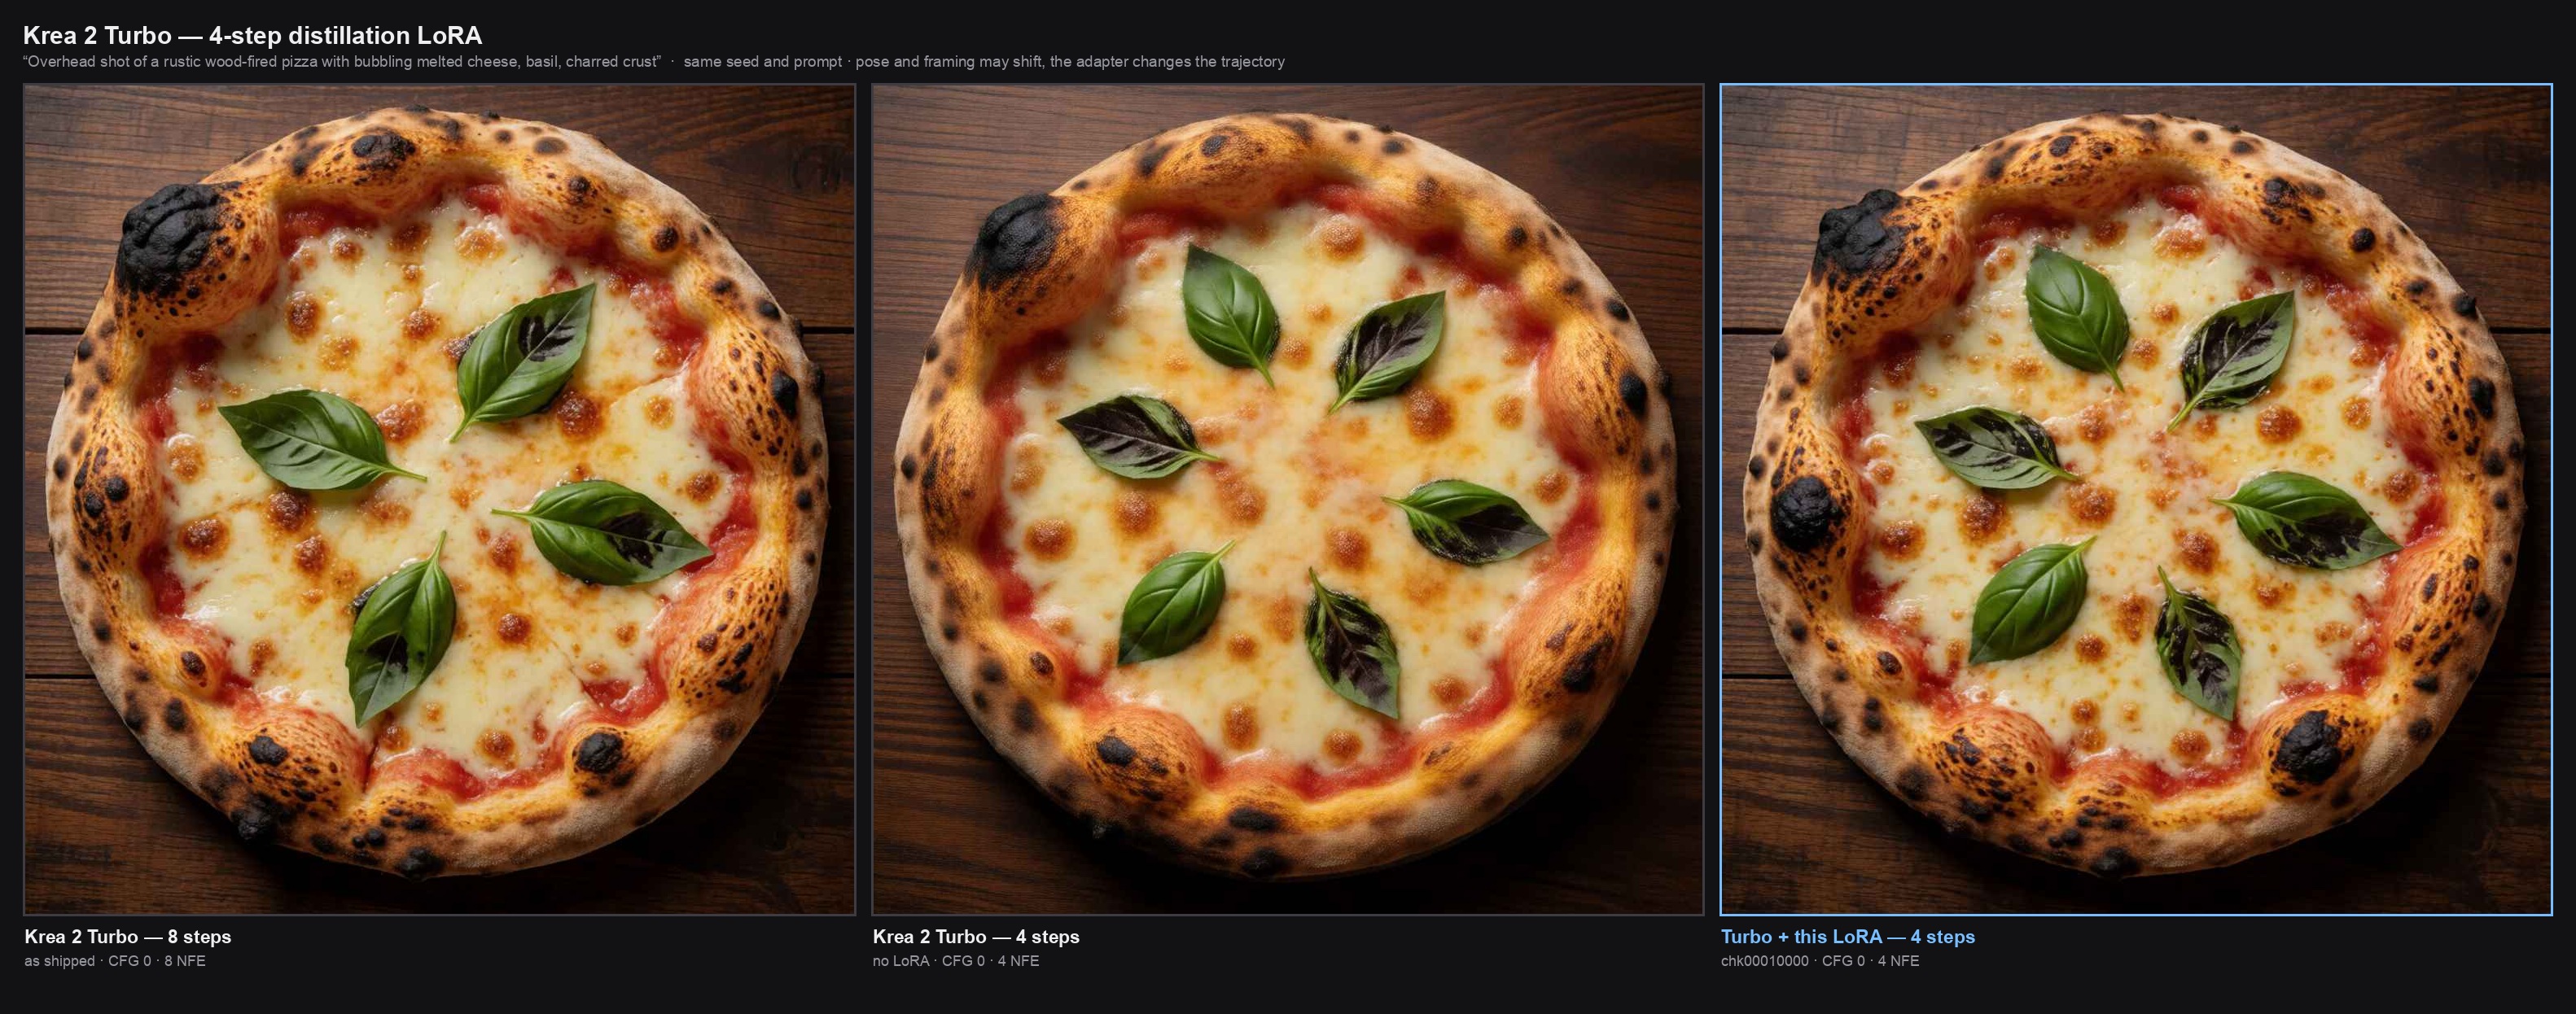
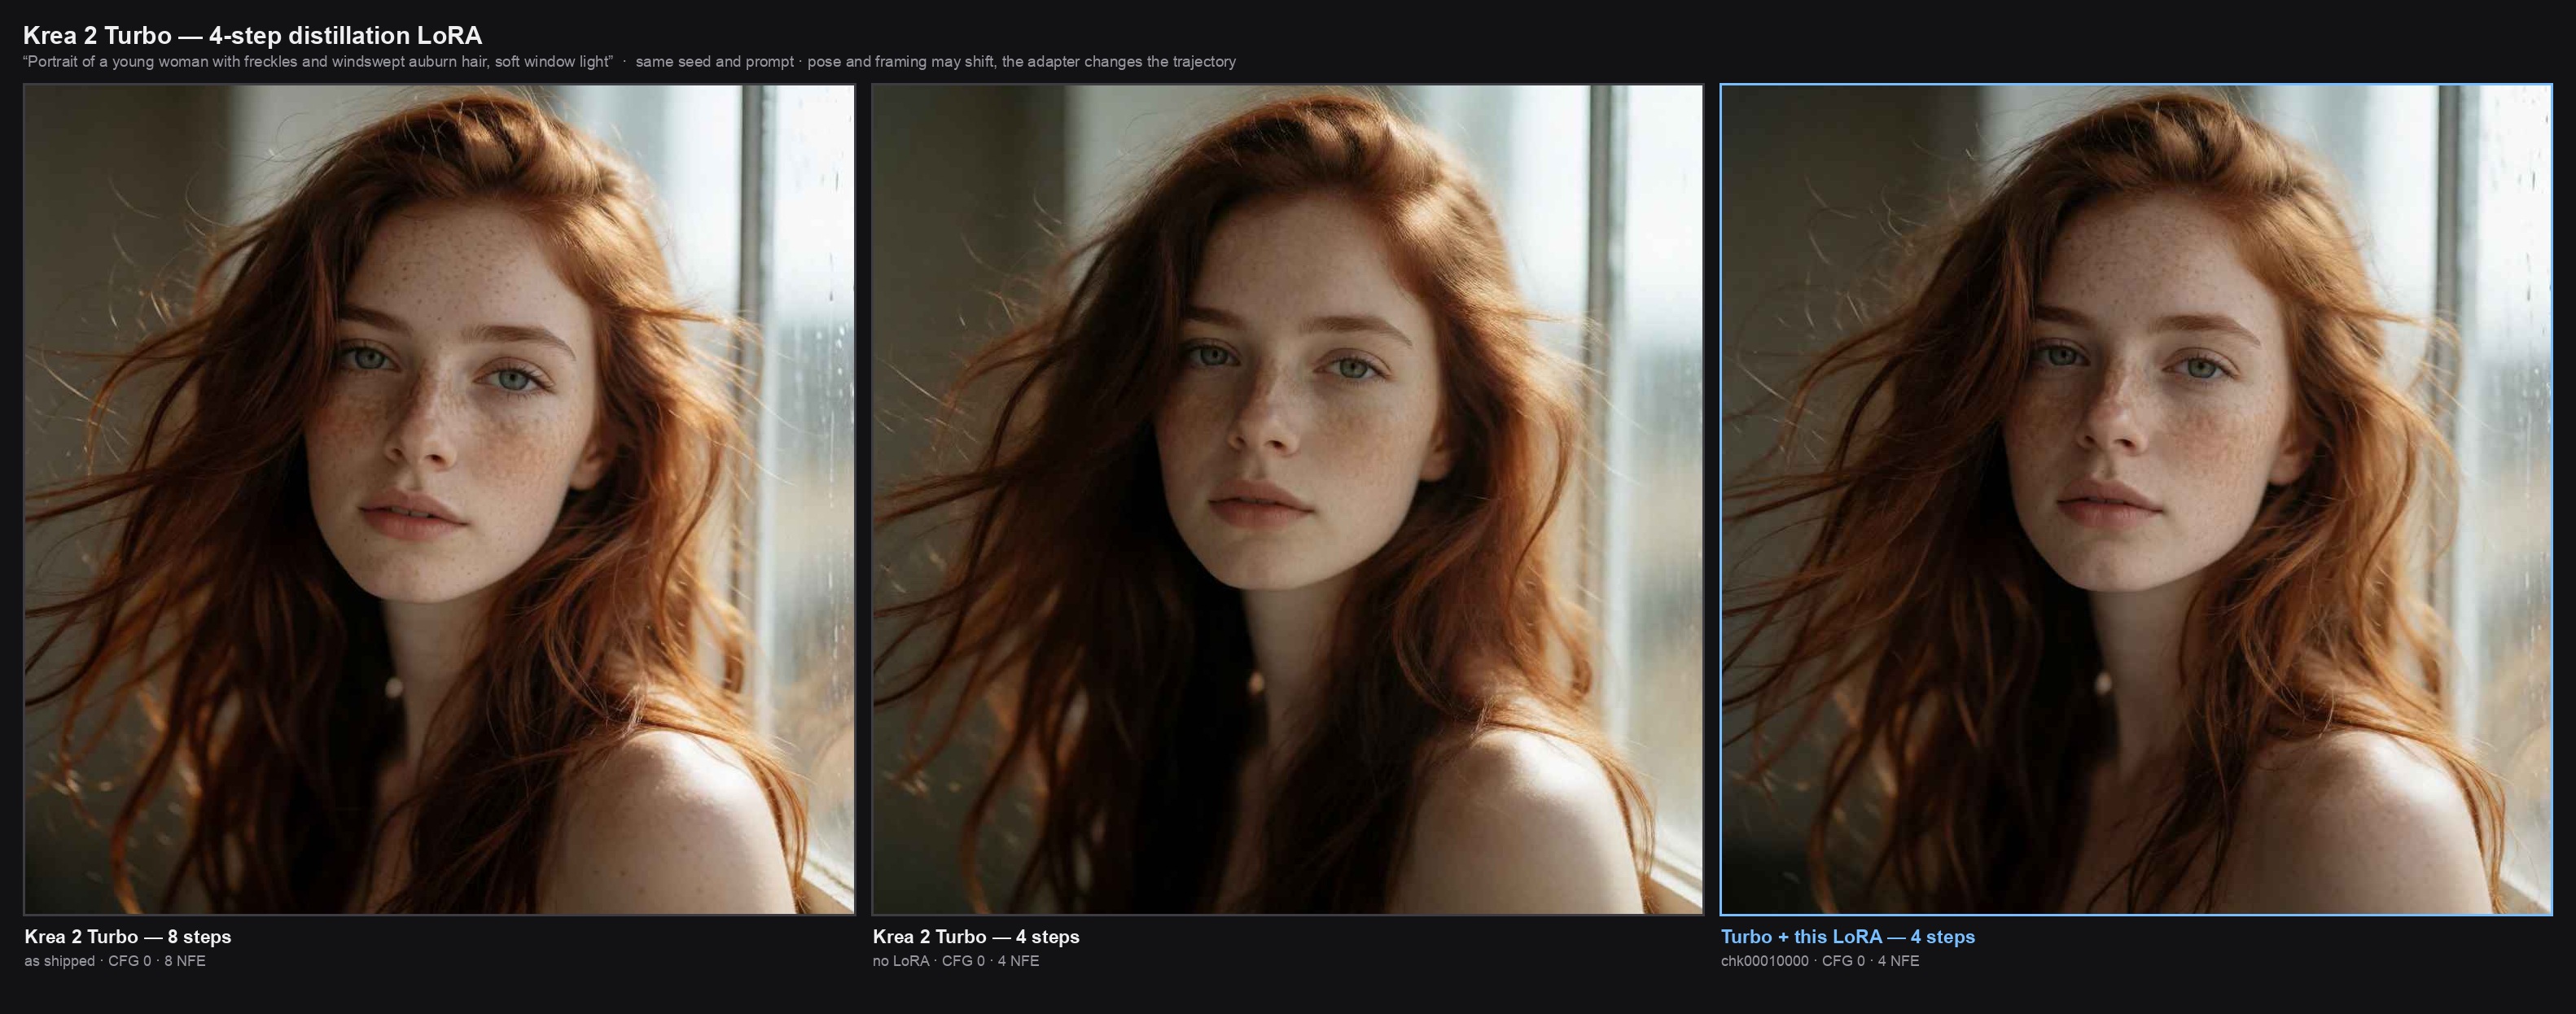
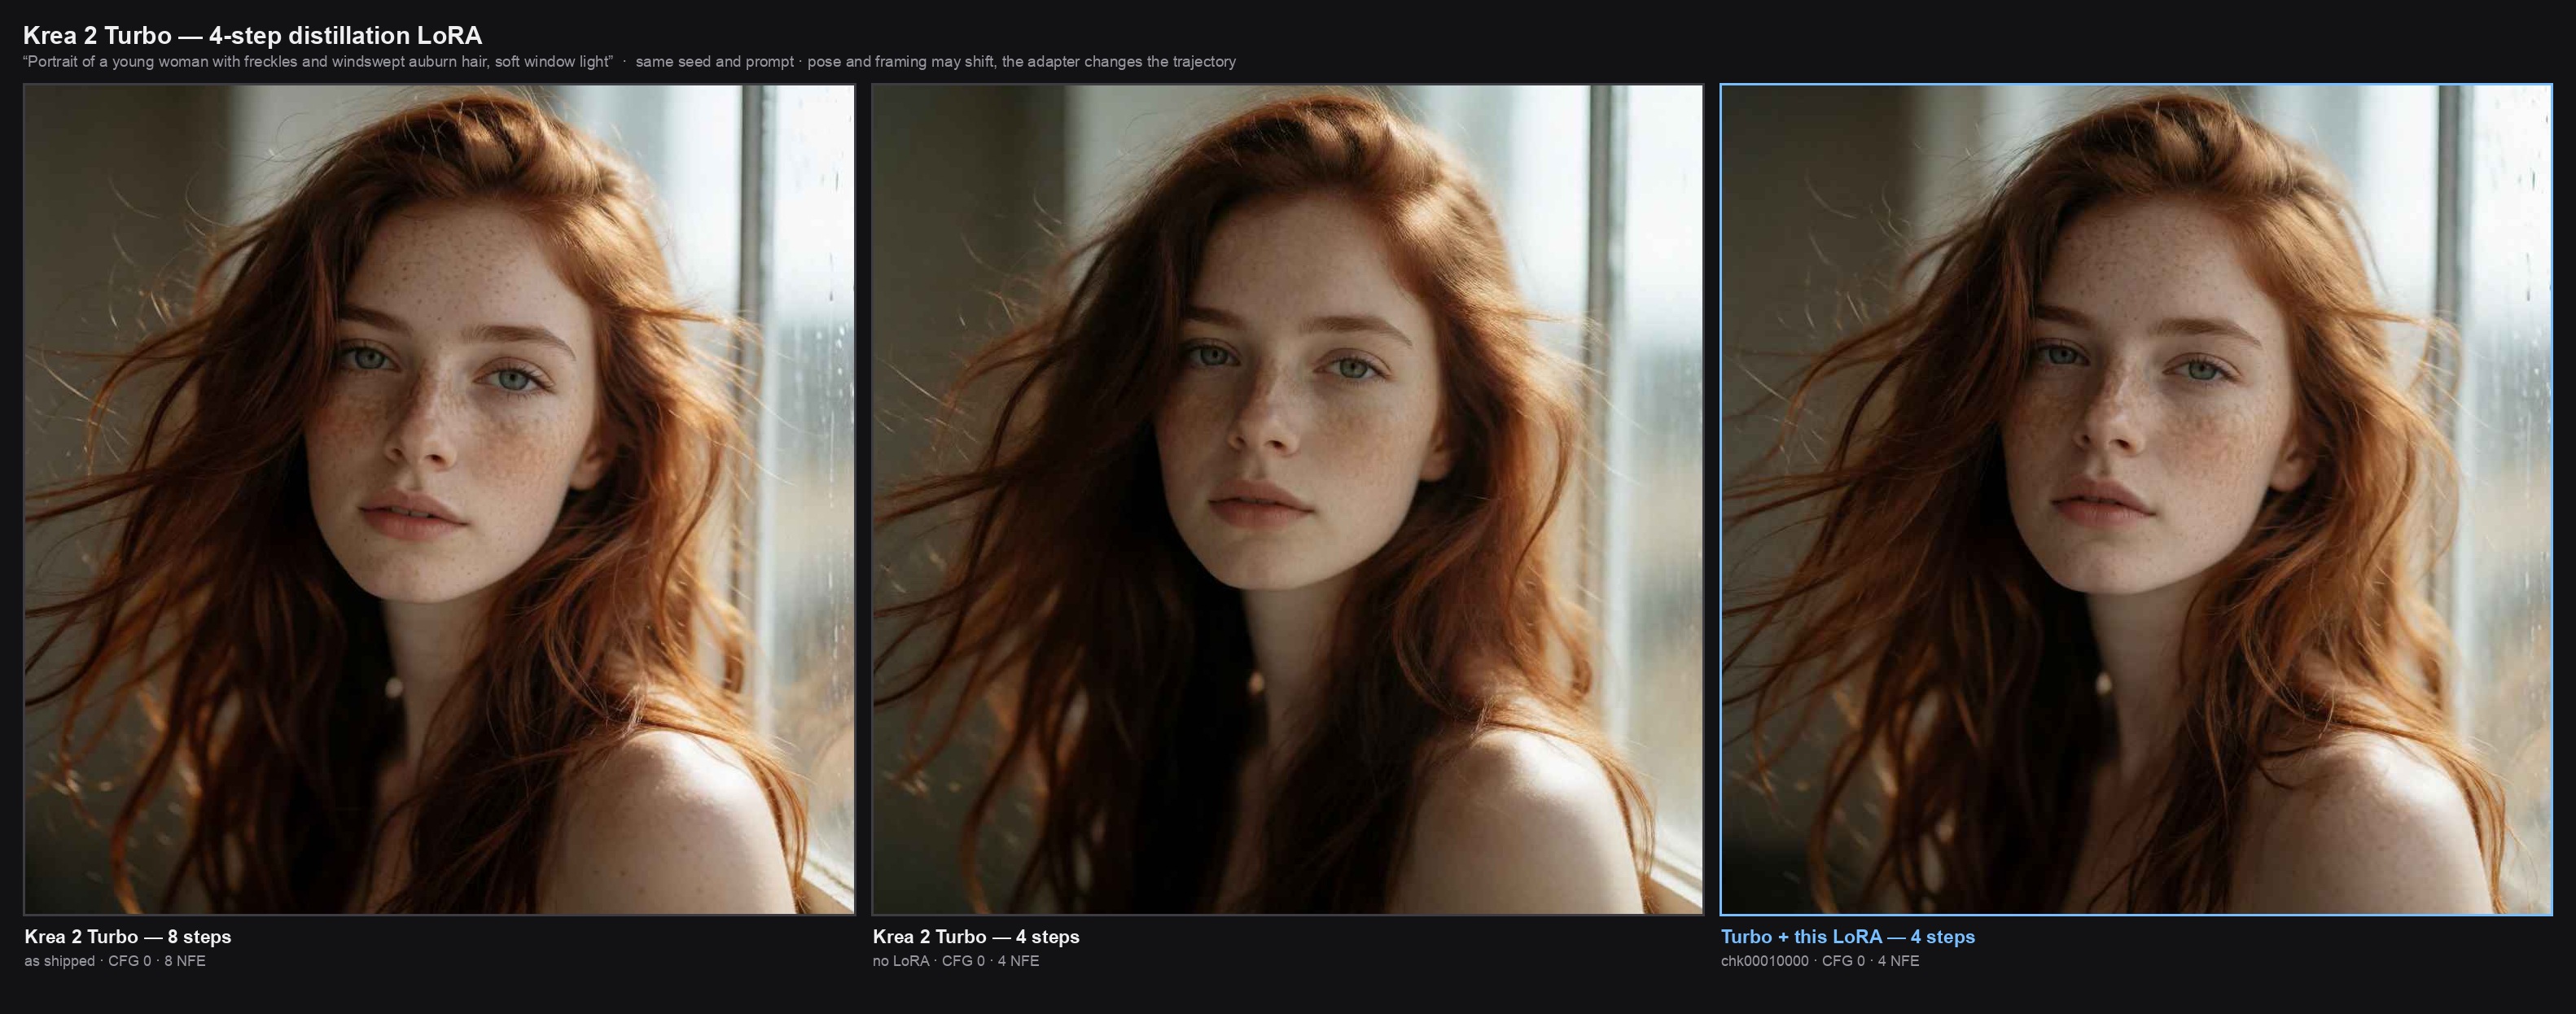
Checkpoint 14K which removes 44% of the prediction error a plain 4-step run has against the 8-step teacher
Browse filesThis view is limited to 50 files because it contains too many changes. See raw diff
- README.md +81 -47
- assets/claychef_compare_turbo.jpg +2 -2
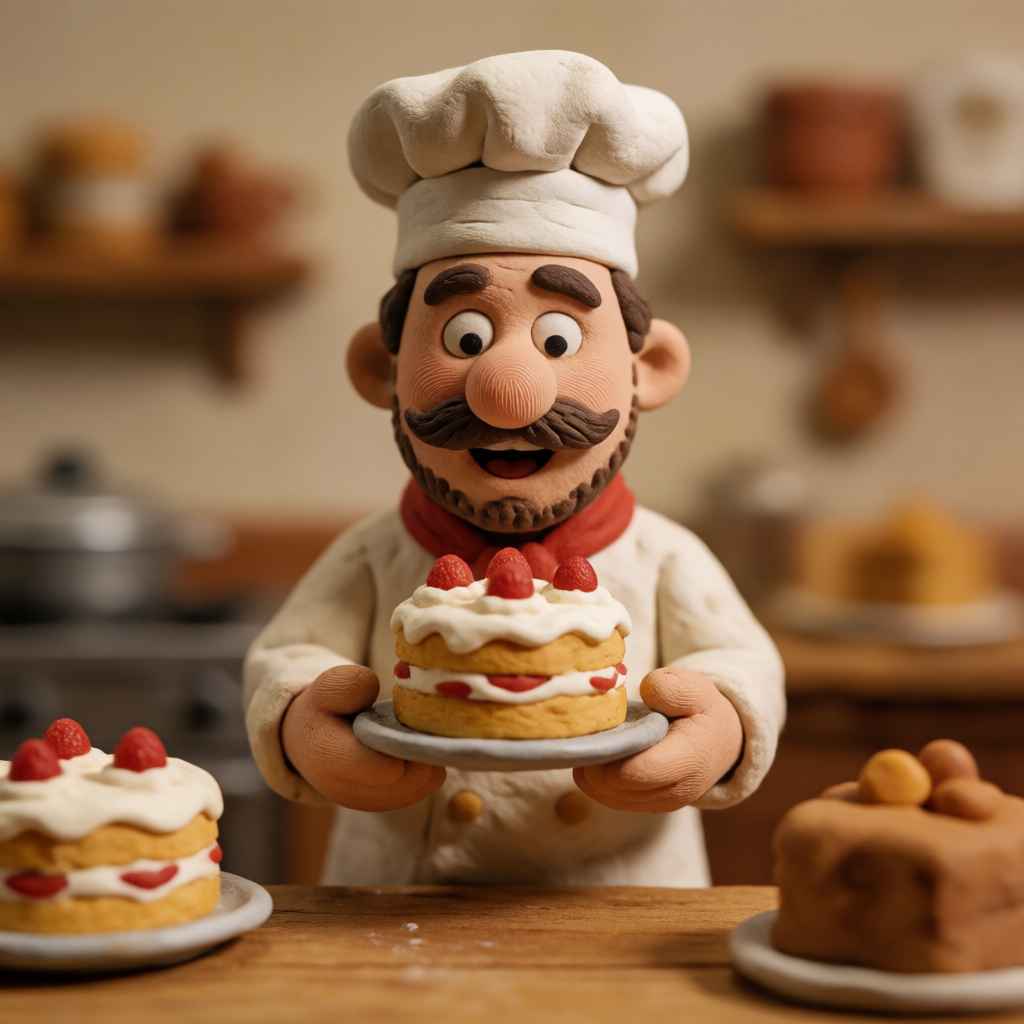
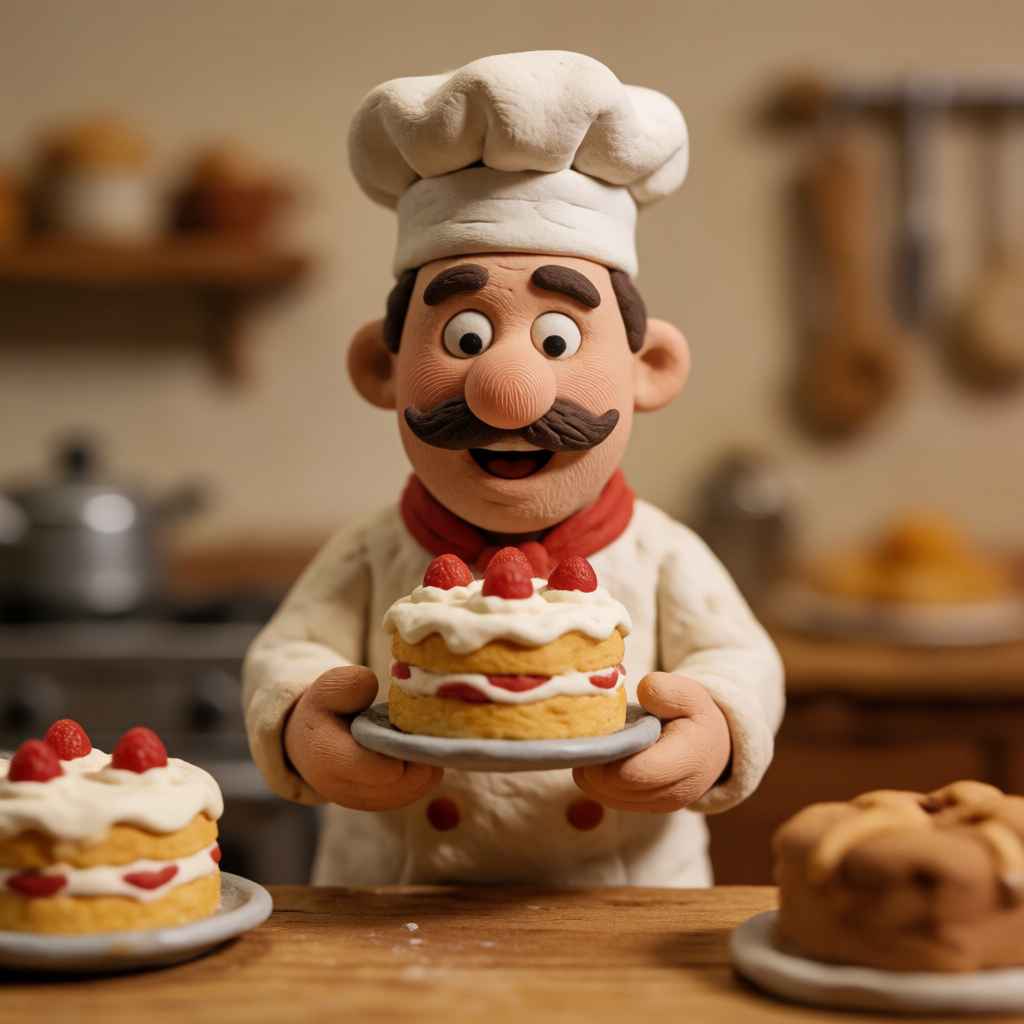
- assets/claychef_turbo_4step_lora_latest.jpg +0 -0
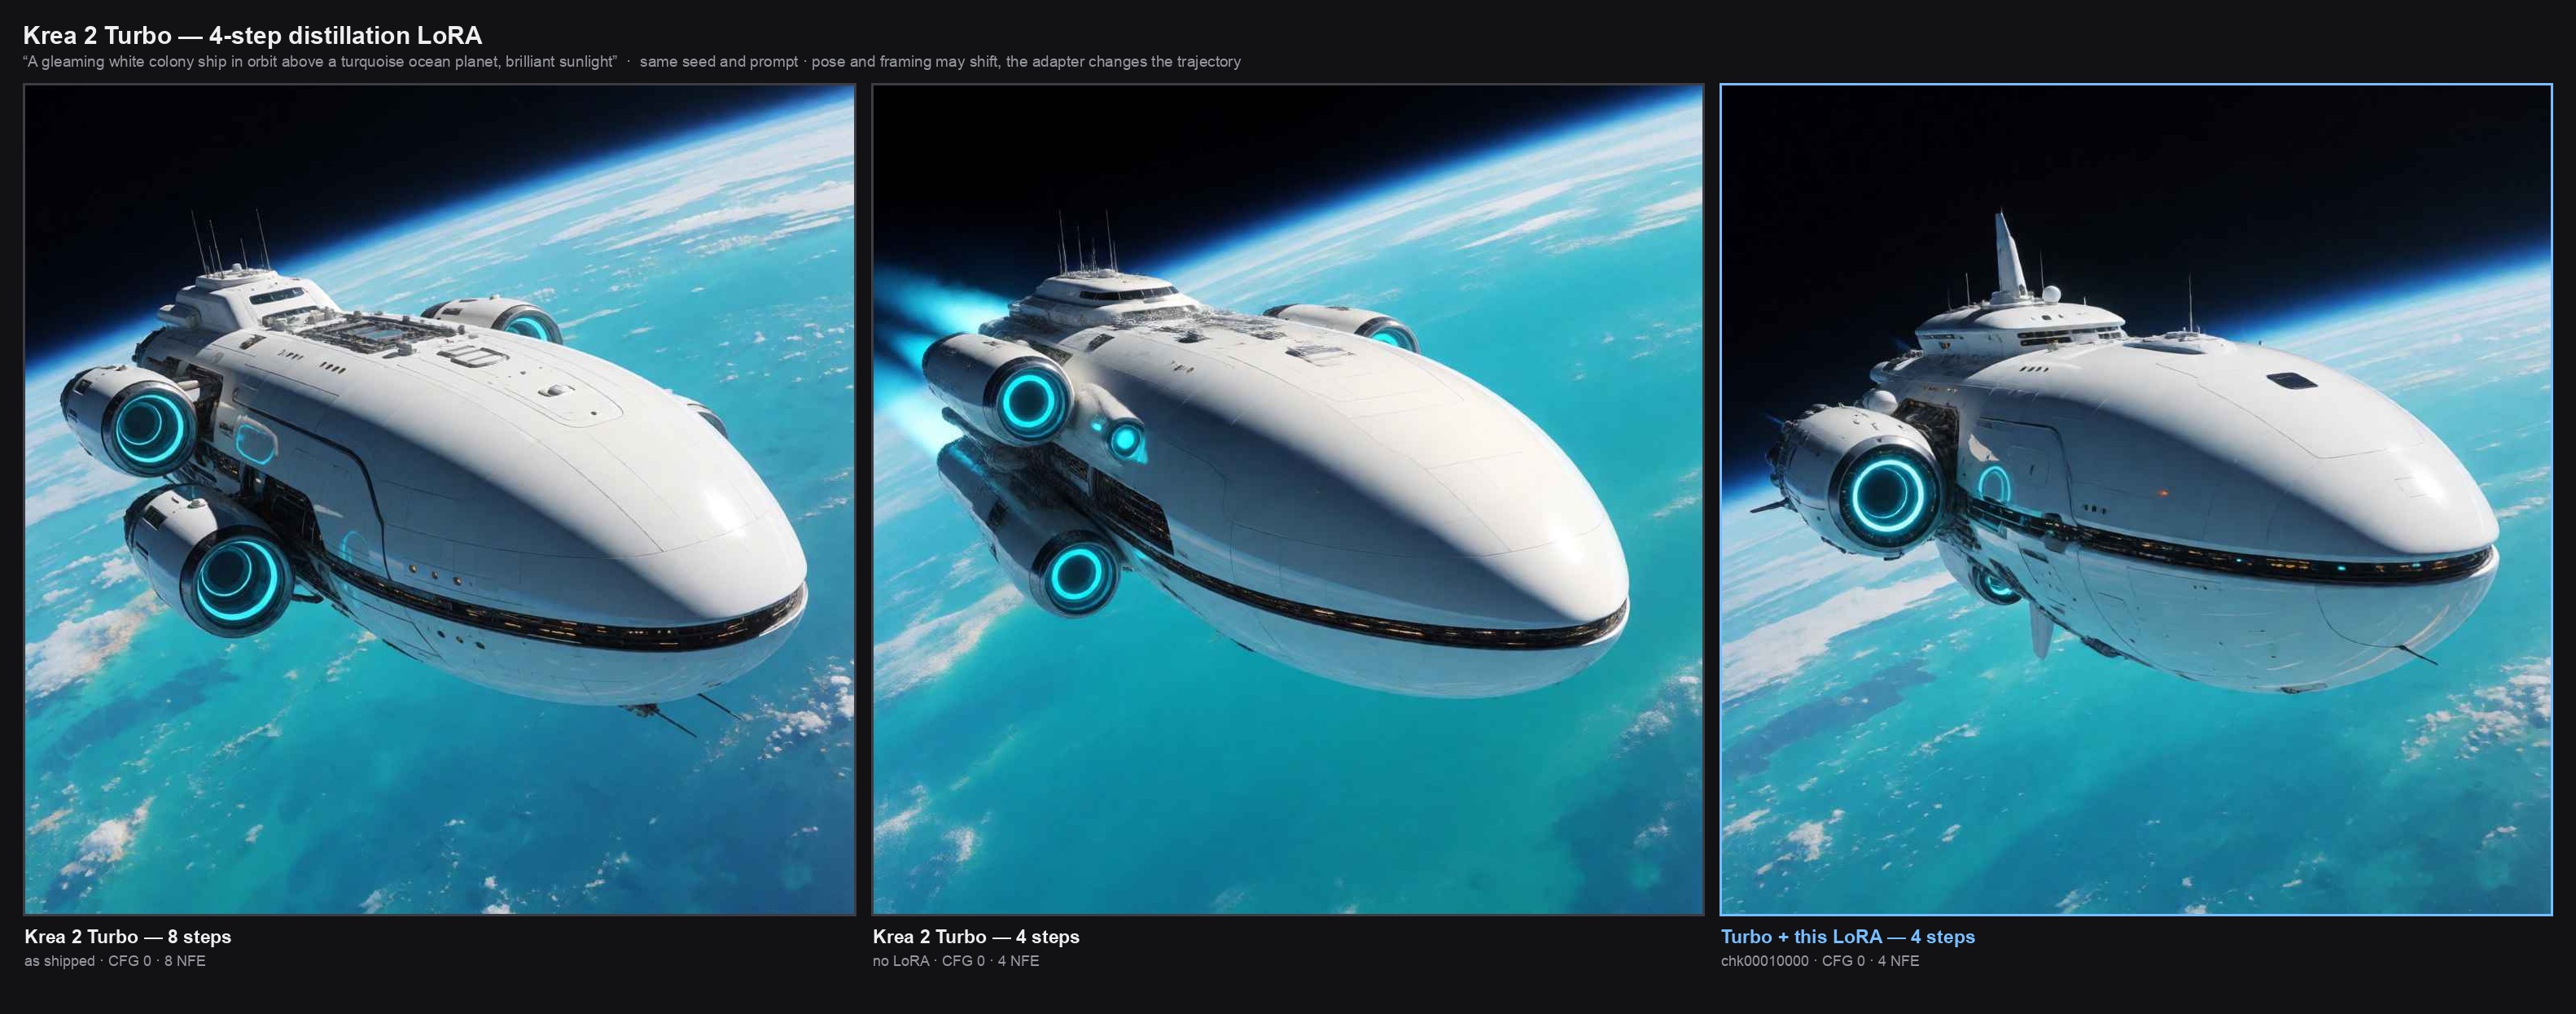
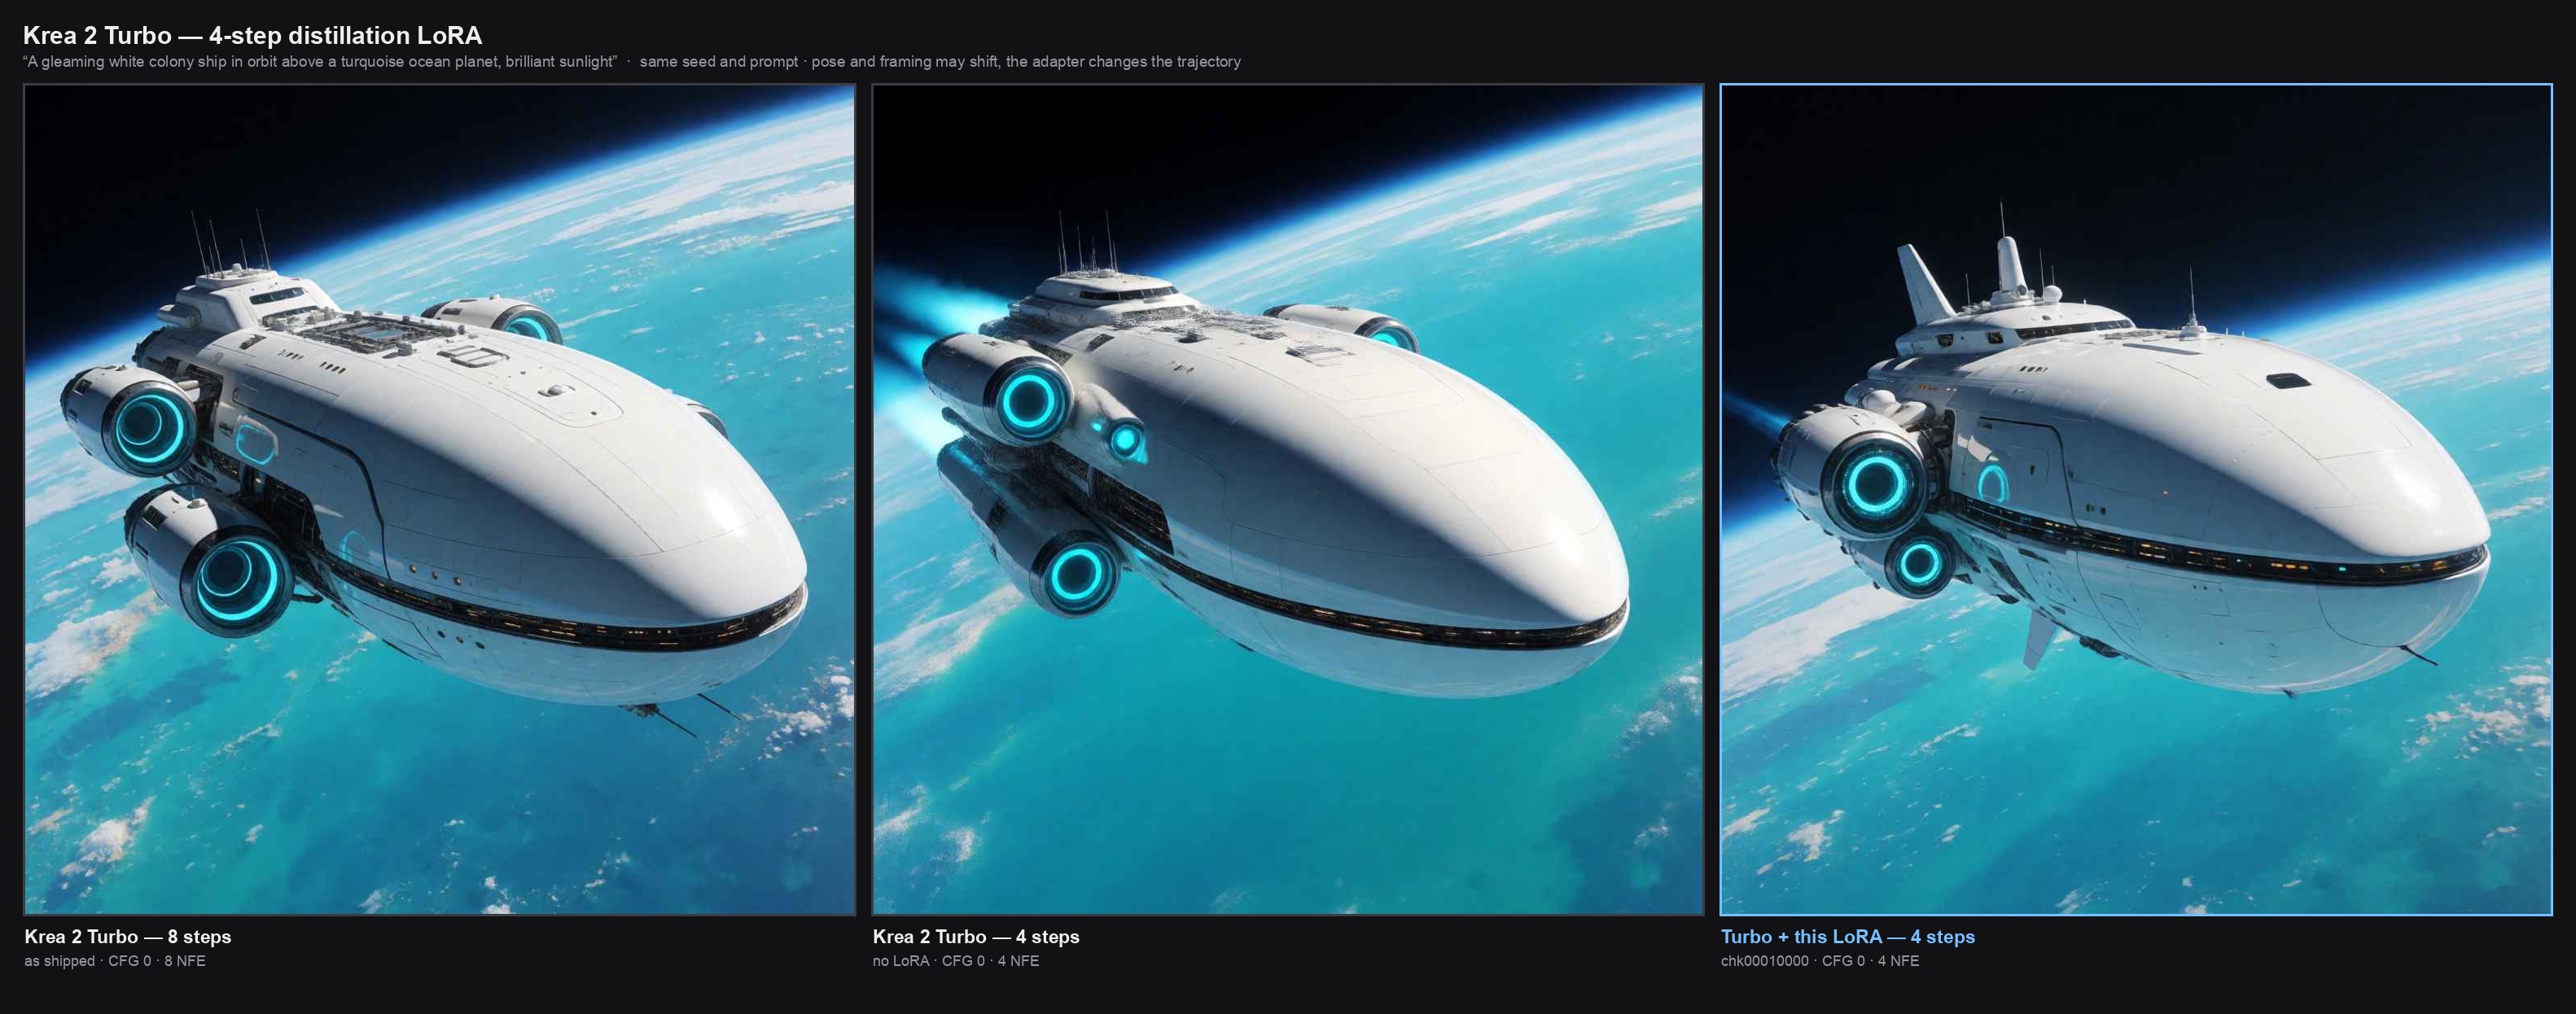
- assets/colonyship_compare_turbo.jpg +2 -2
- assets/colonyship_turbo_4step_lora_latest.jpg +0 -0
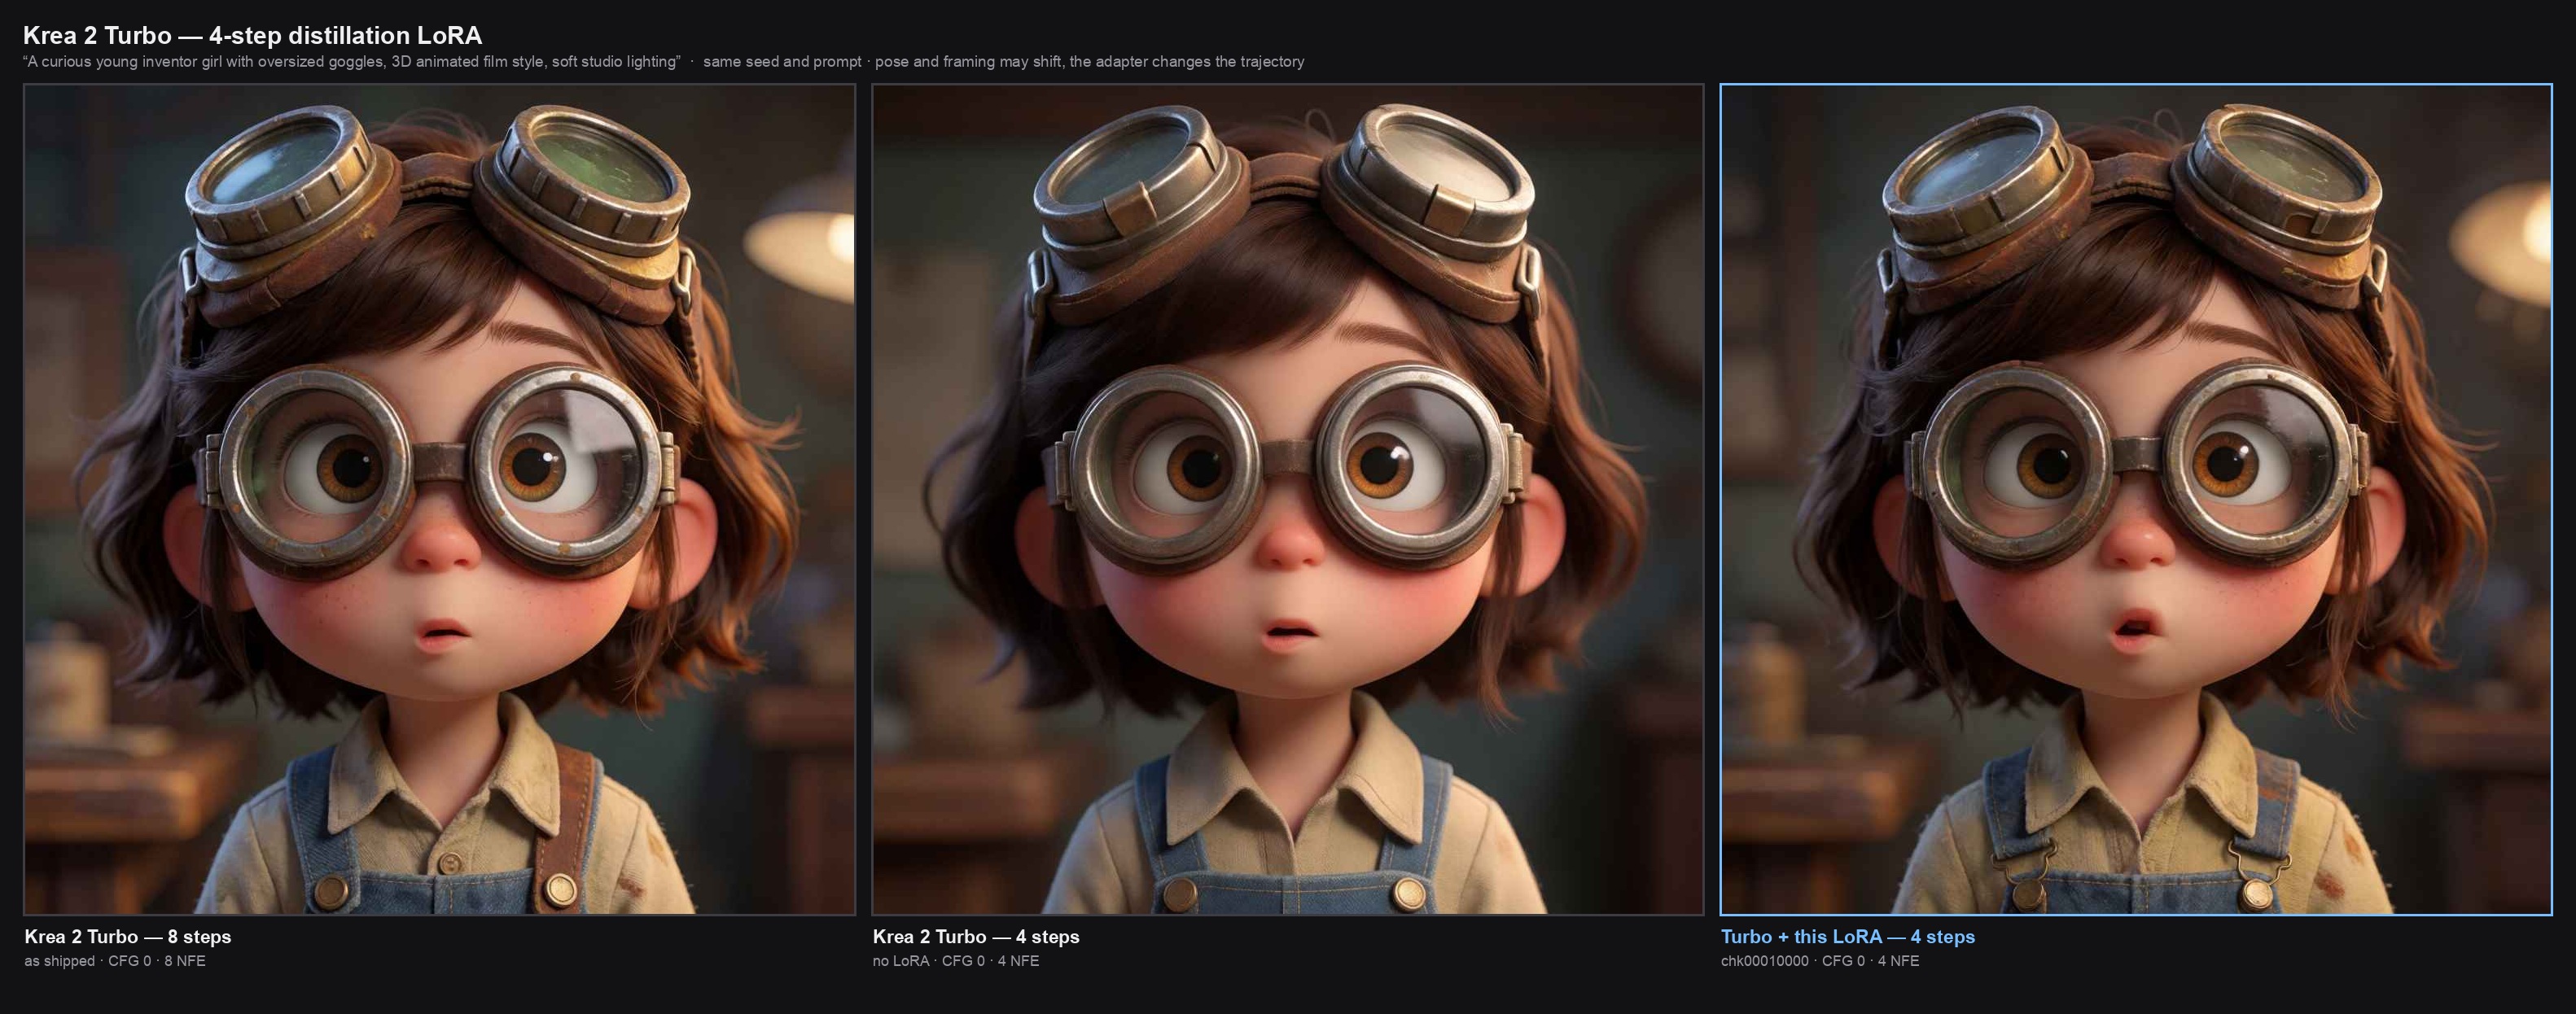
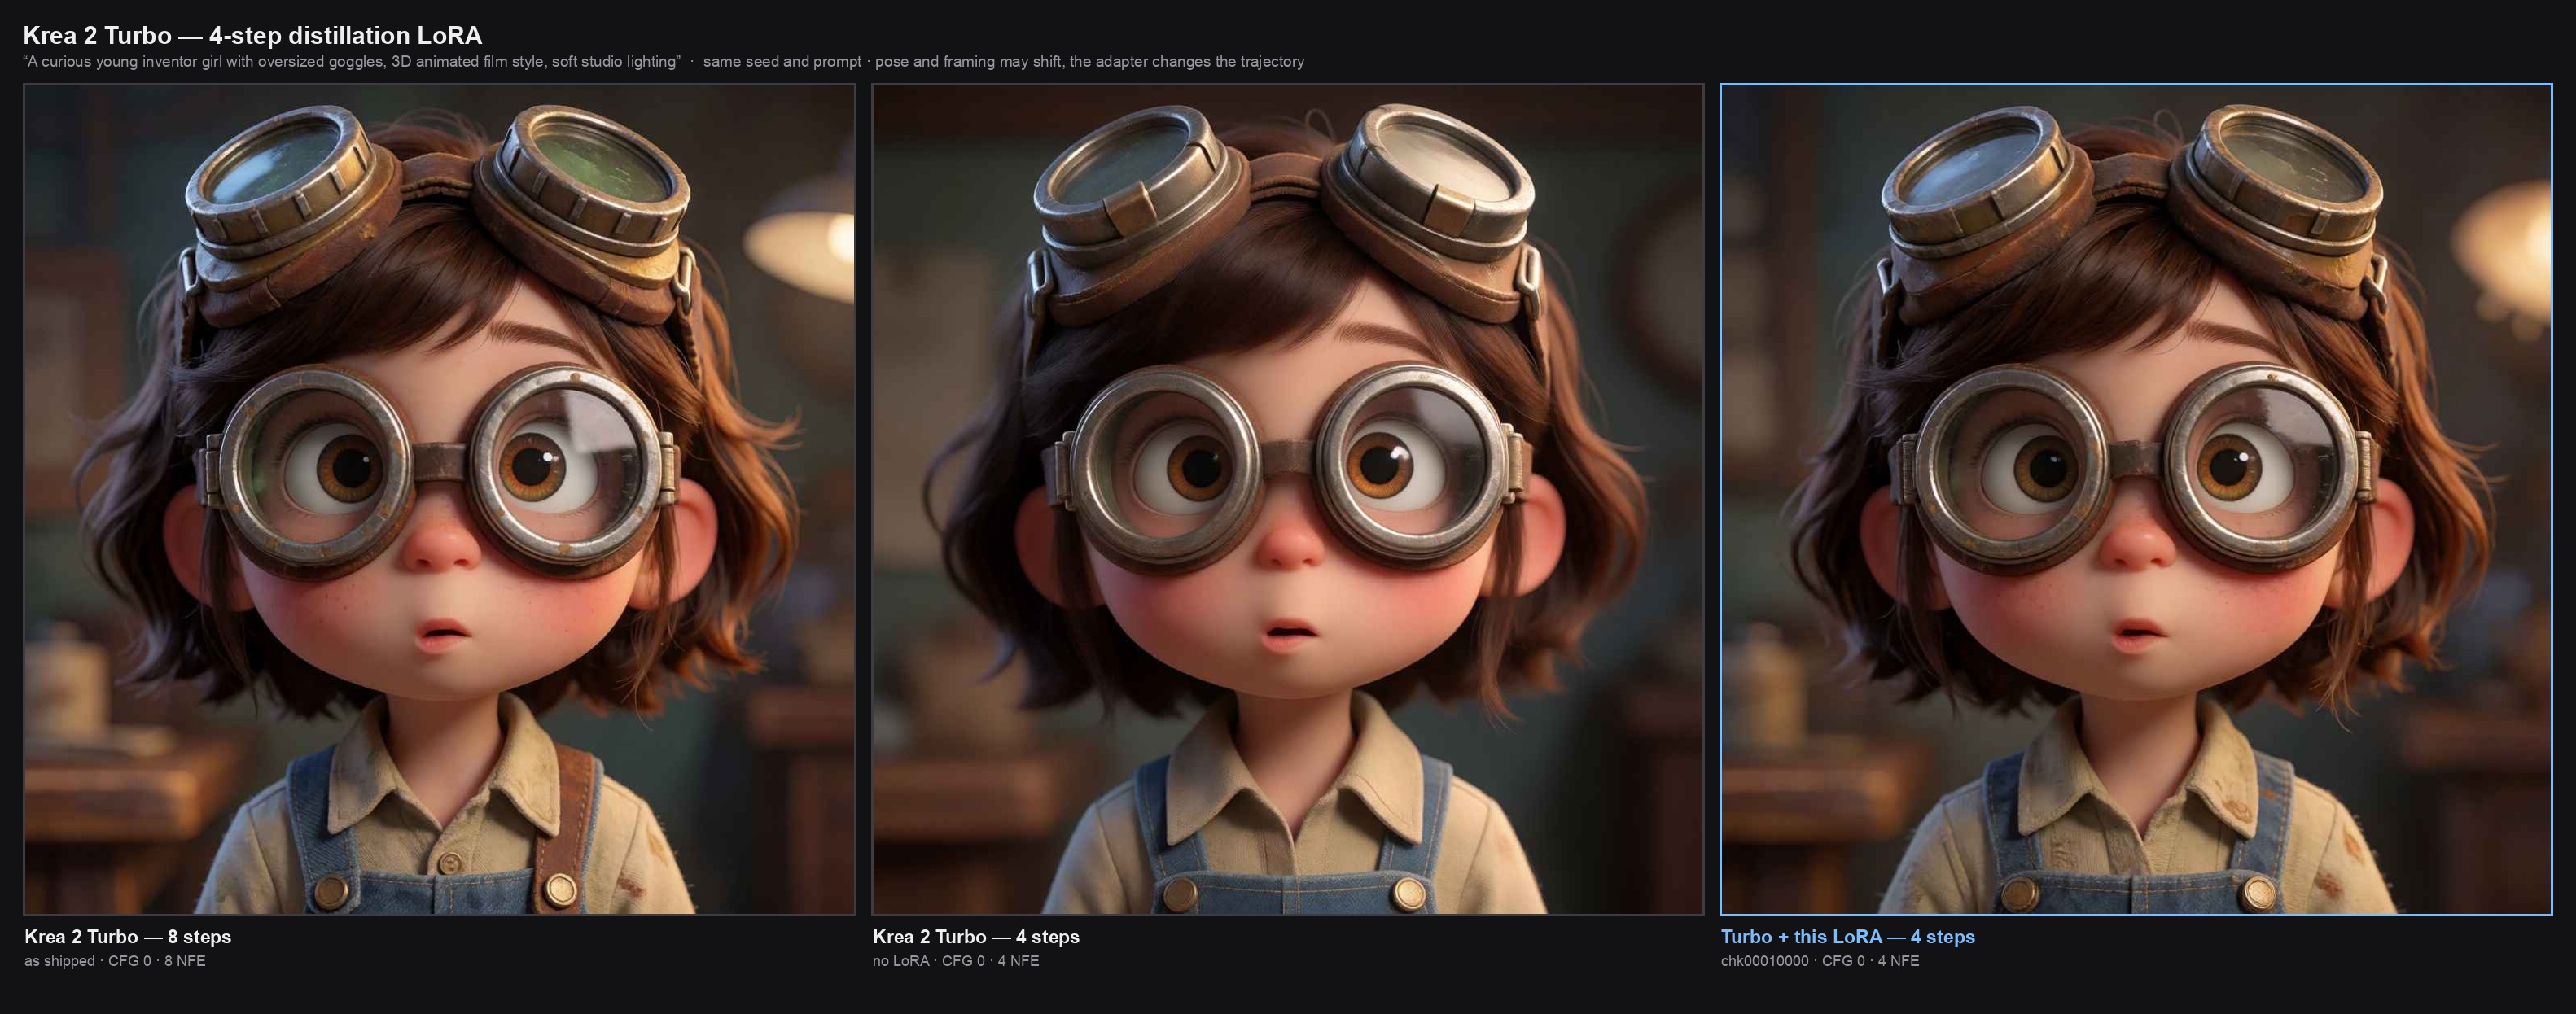
- assets/inventor_compare_turbo.jpg +2 -2
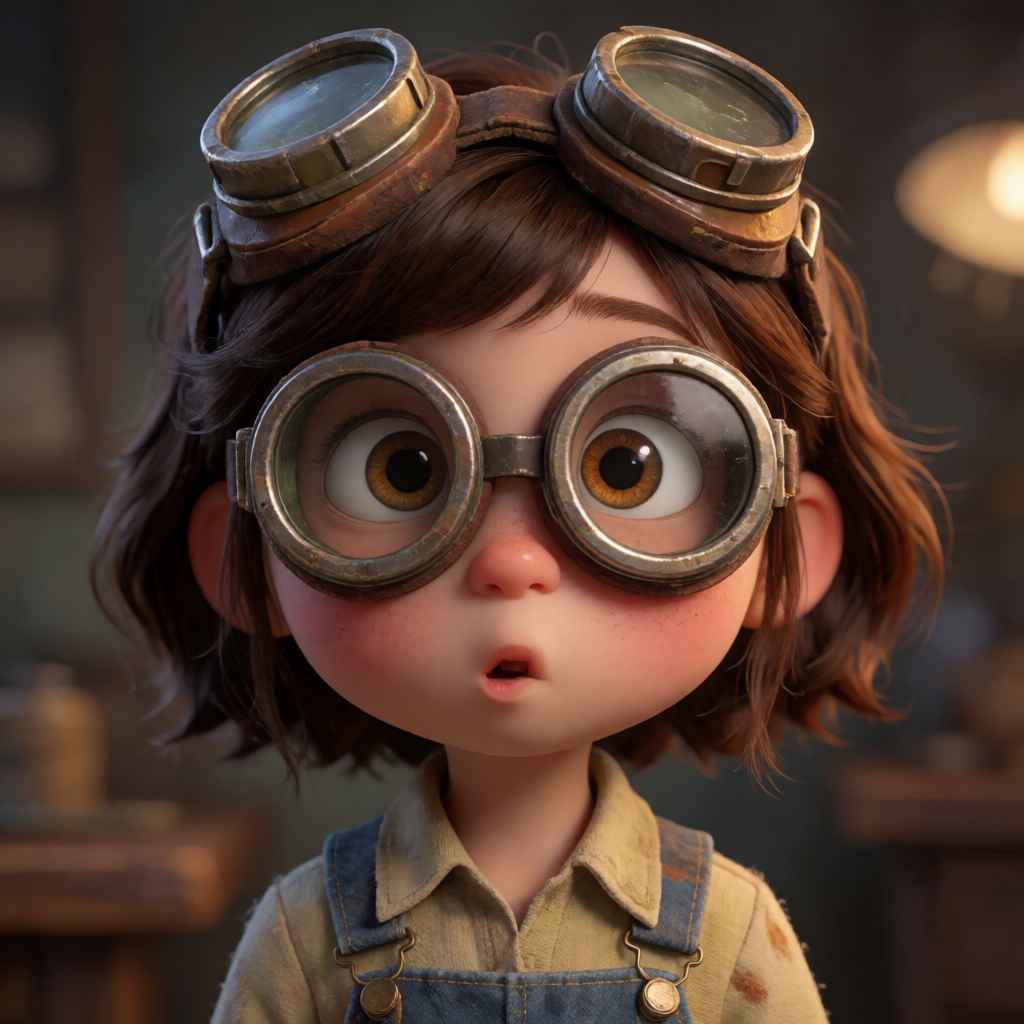
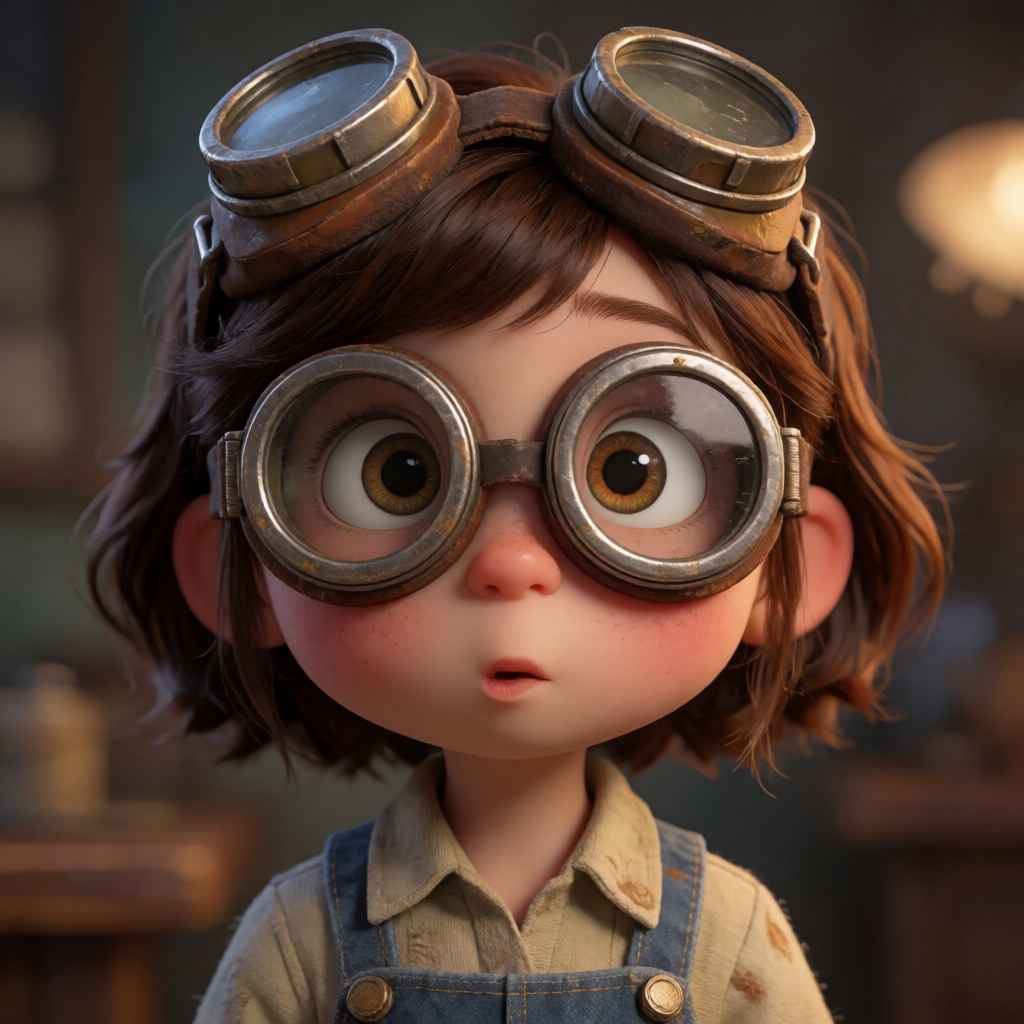
- assets/inventor_turbo_4step_lora_latest.jpg +0 -0
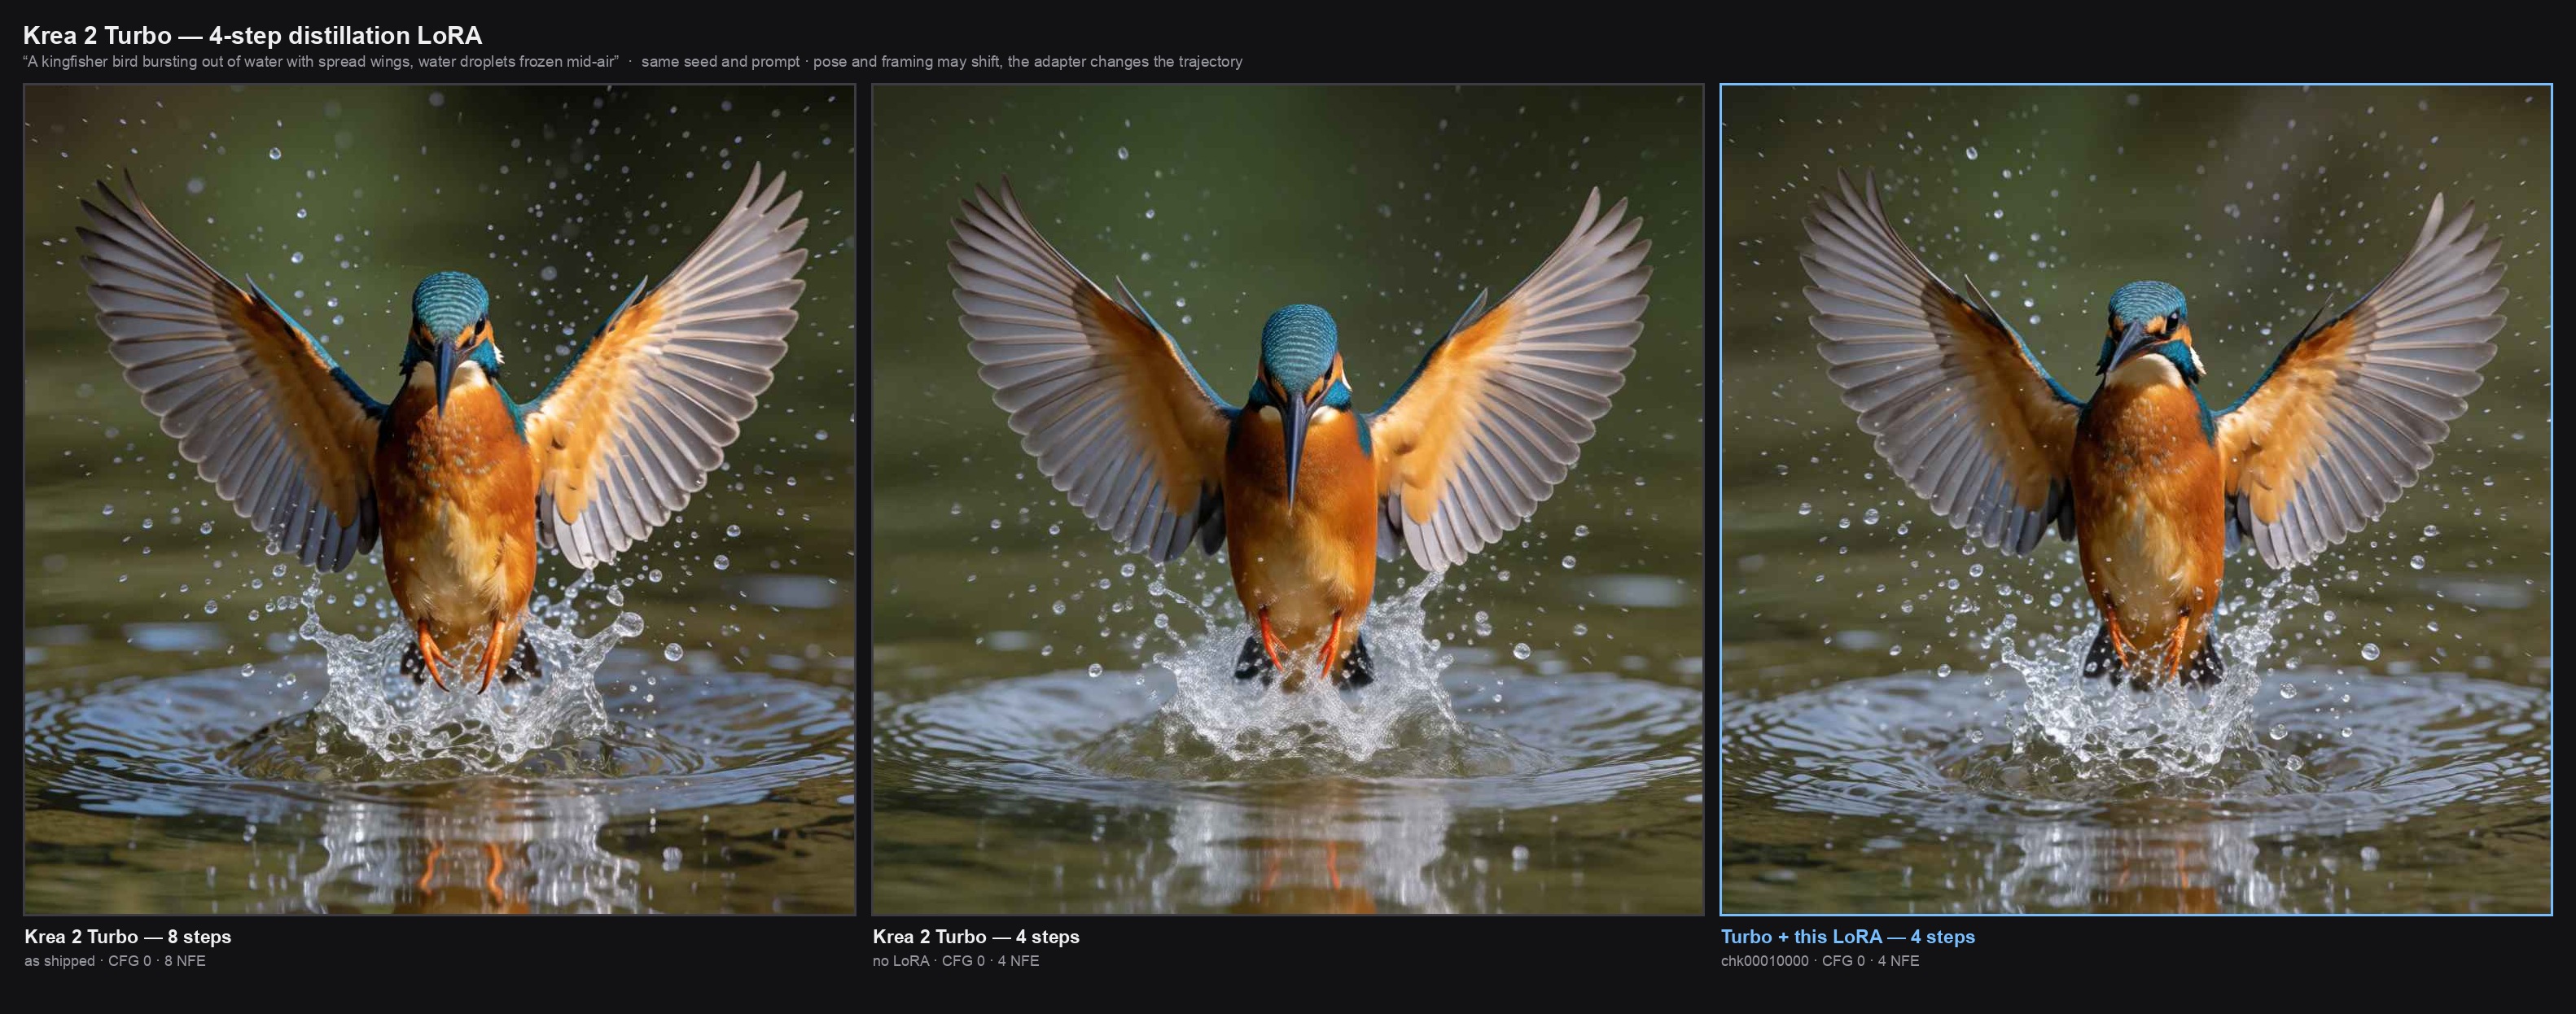
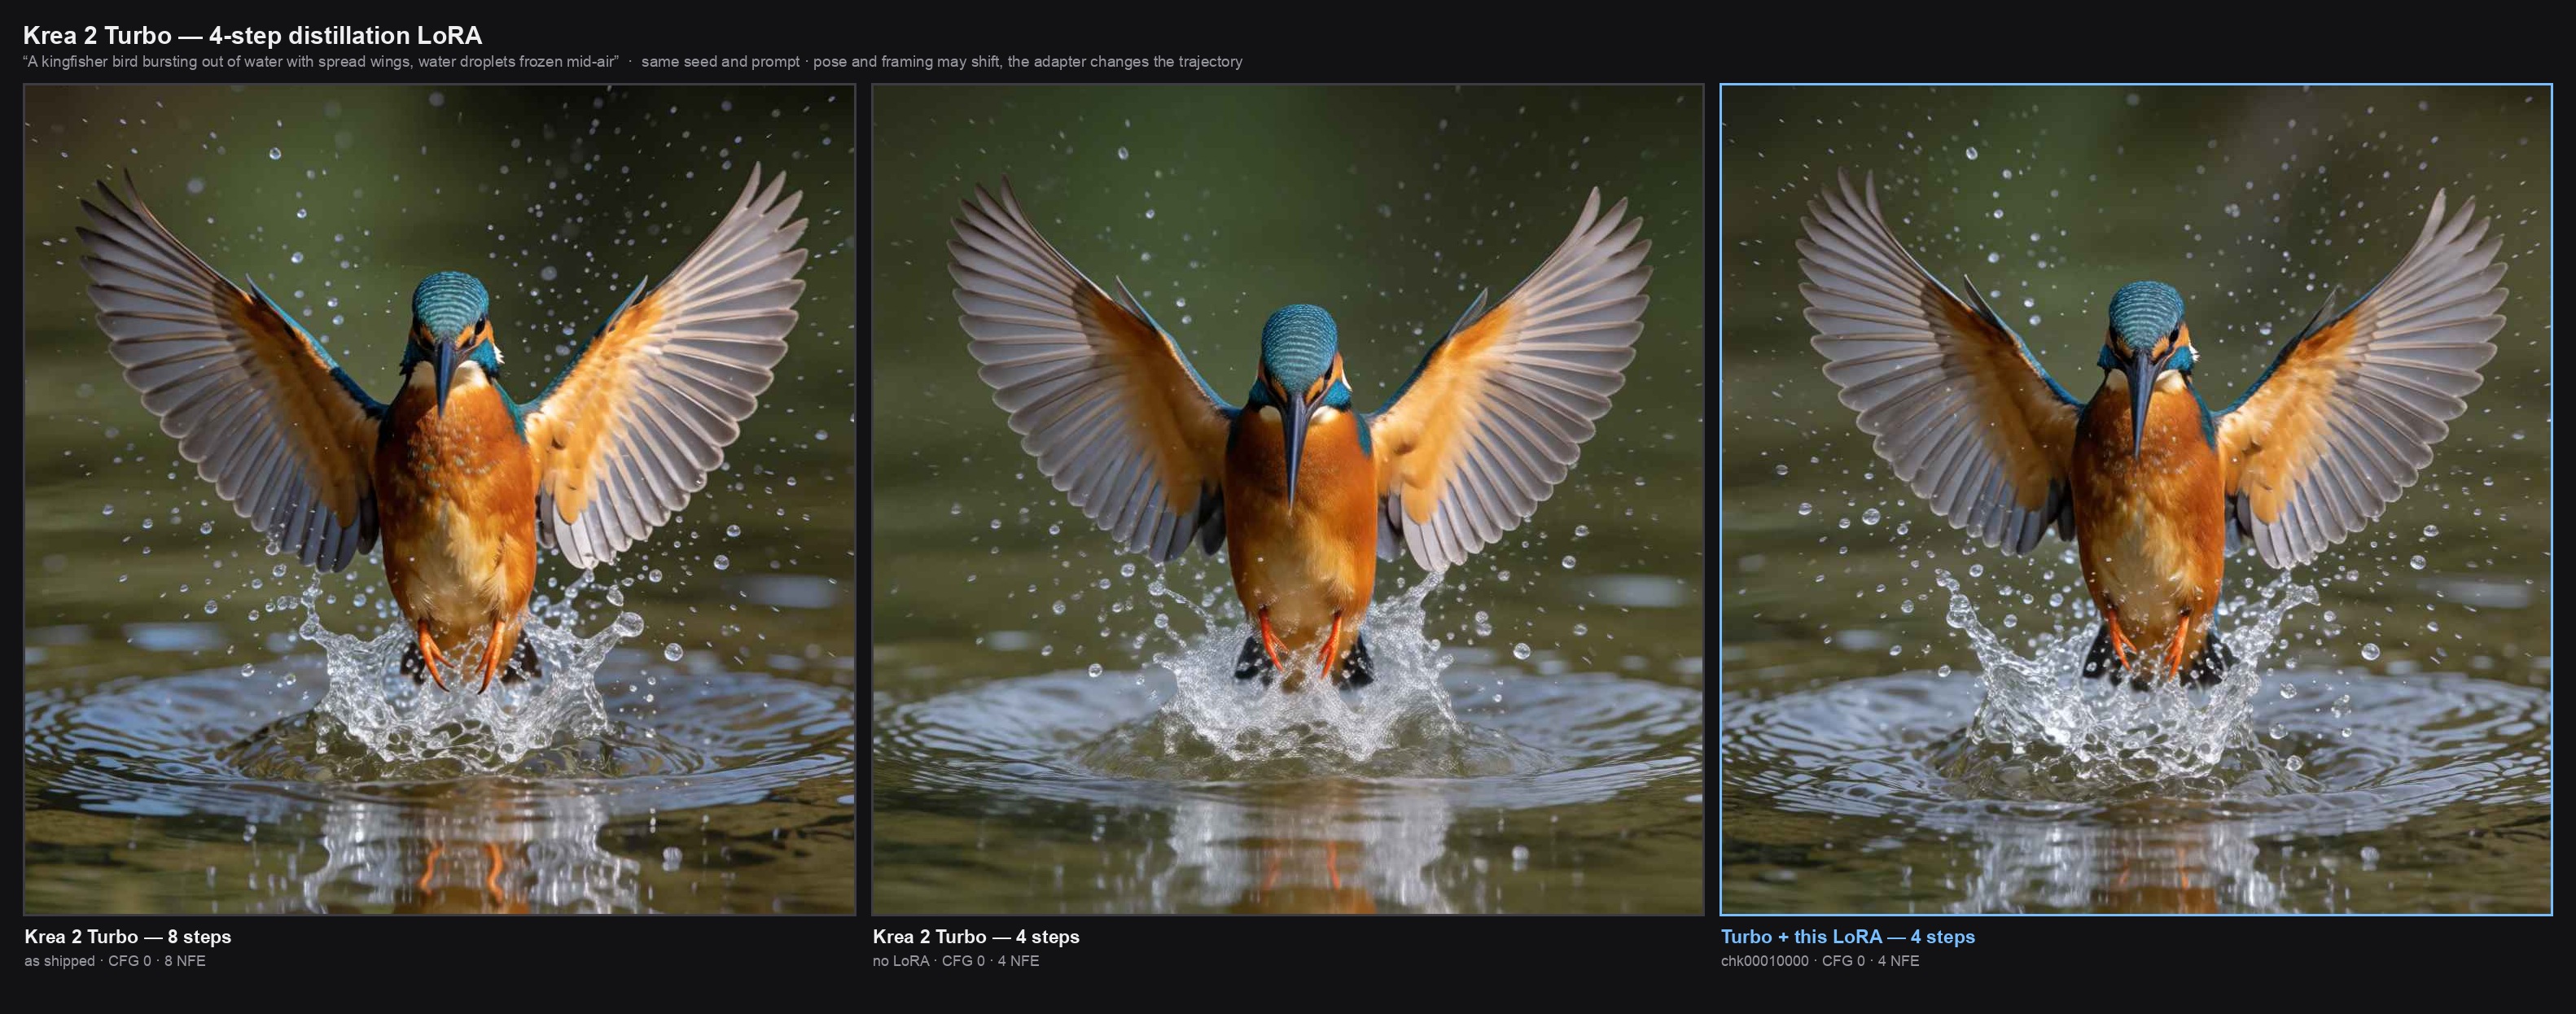
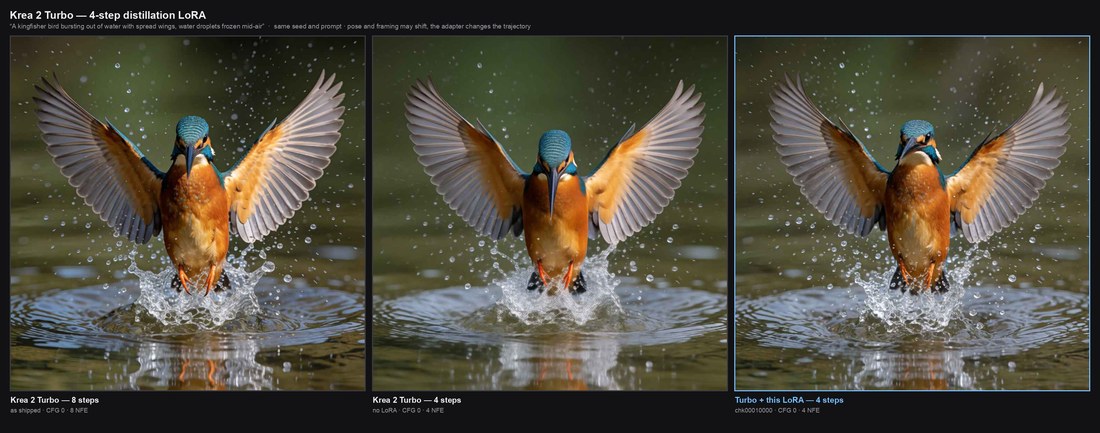
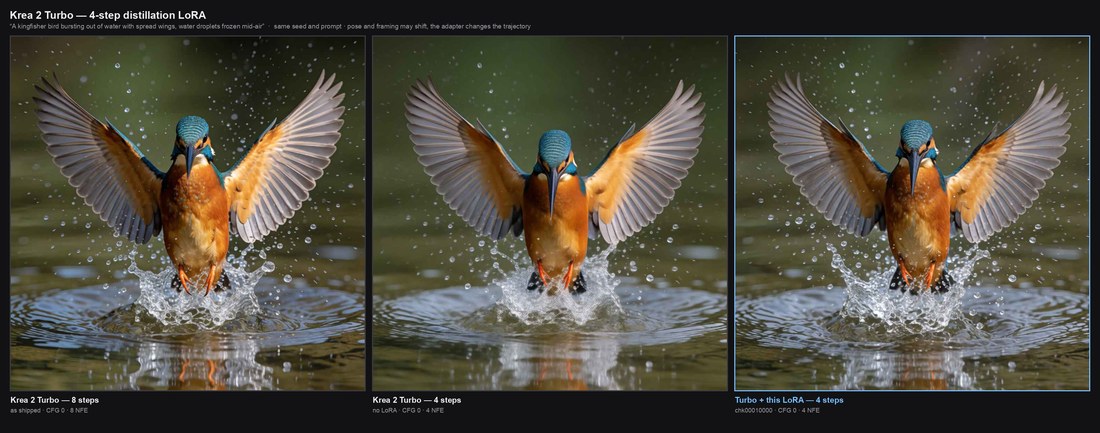
- assets/kingfisher_compare_turbo.jpg +2 -2
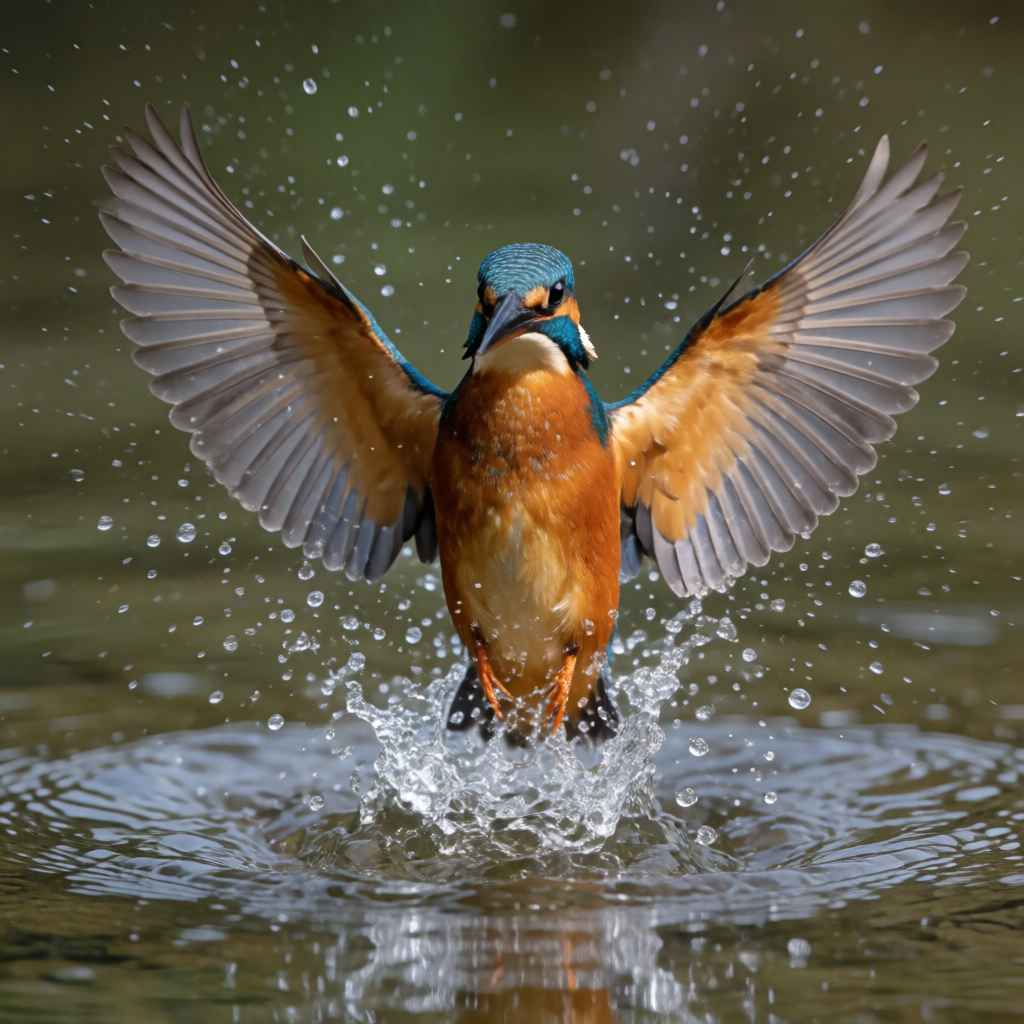
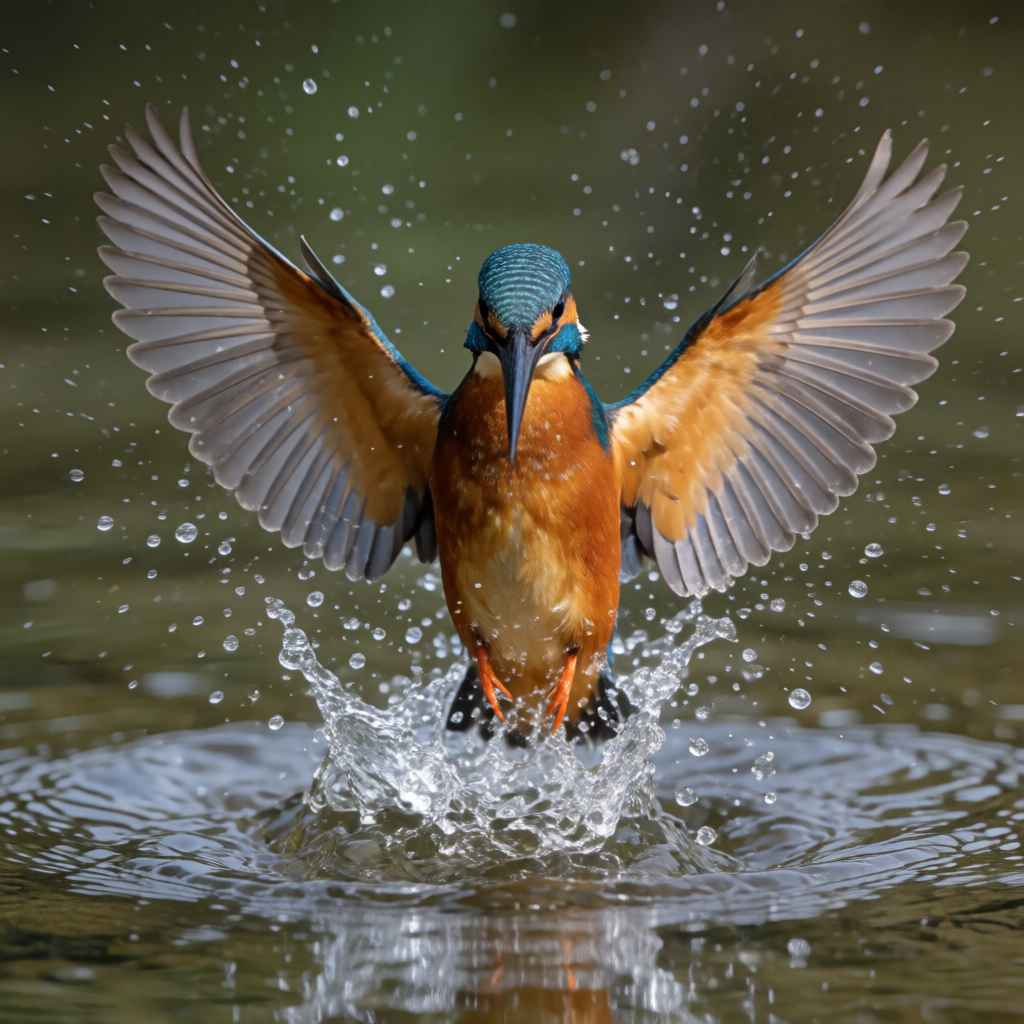
- assets/kingfisher_turbo_4step_lora_latest.jpg +0 -0
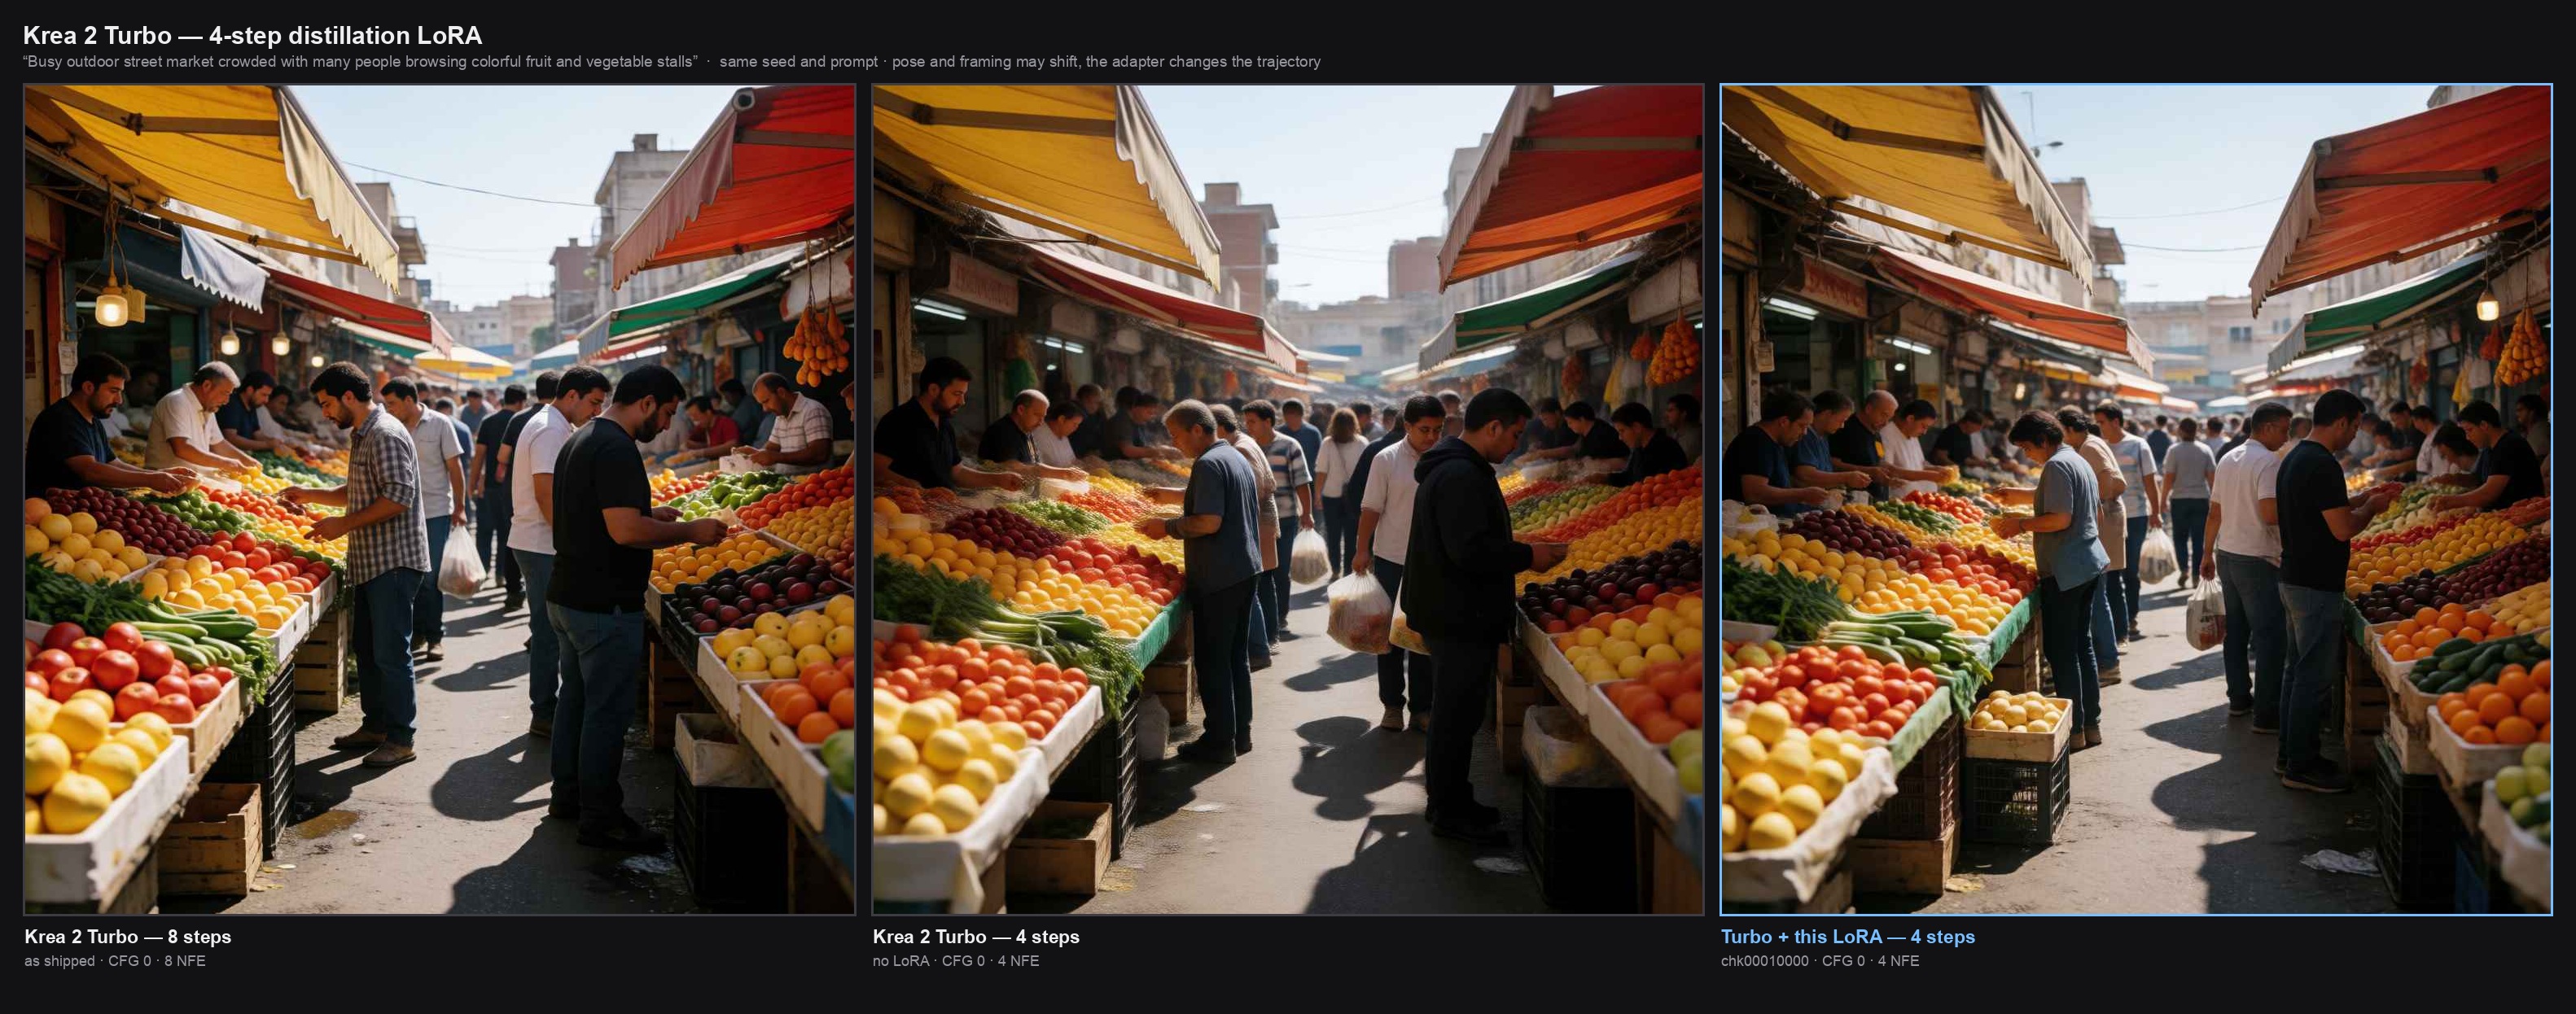
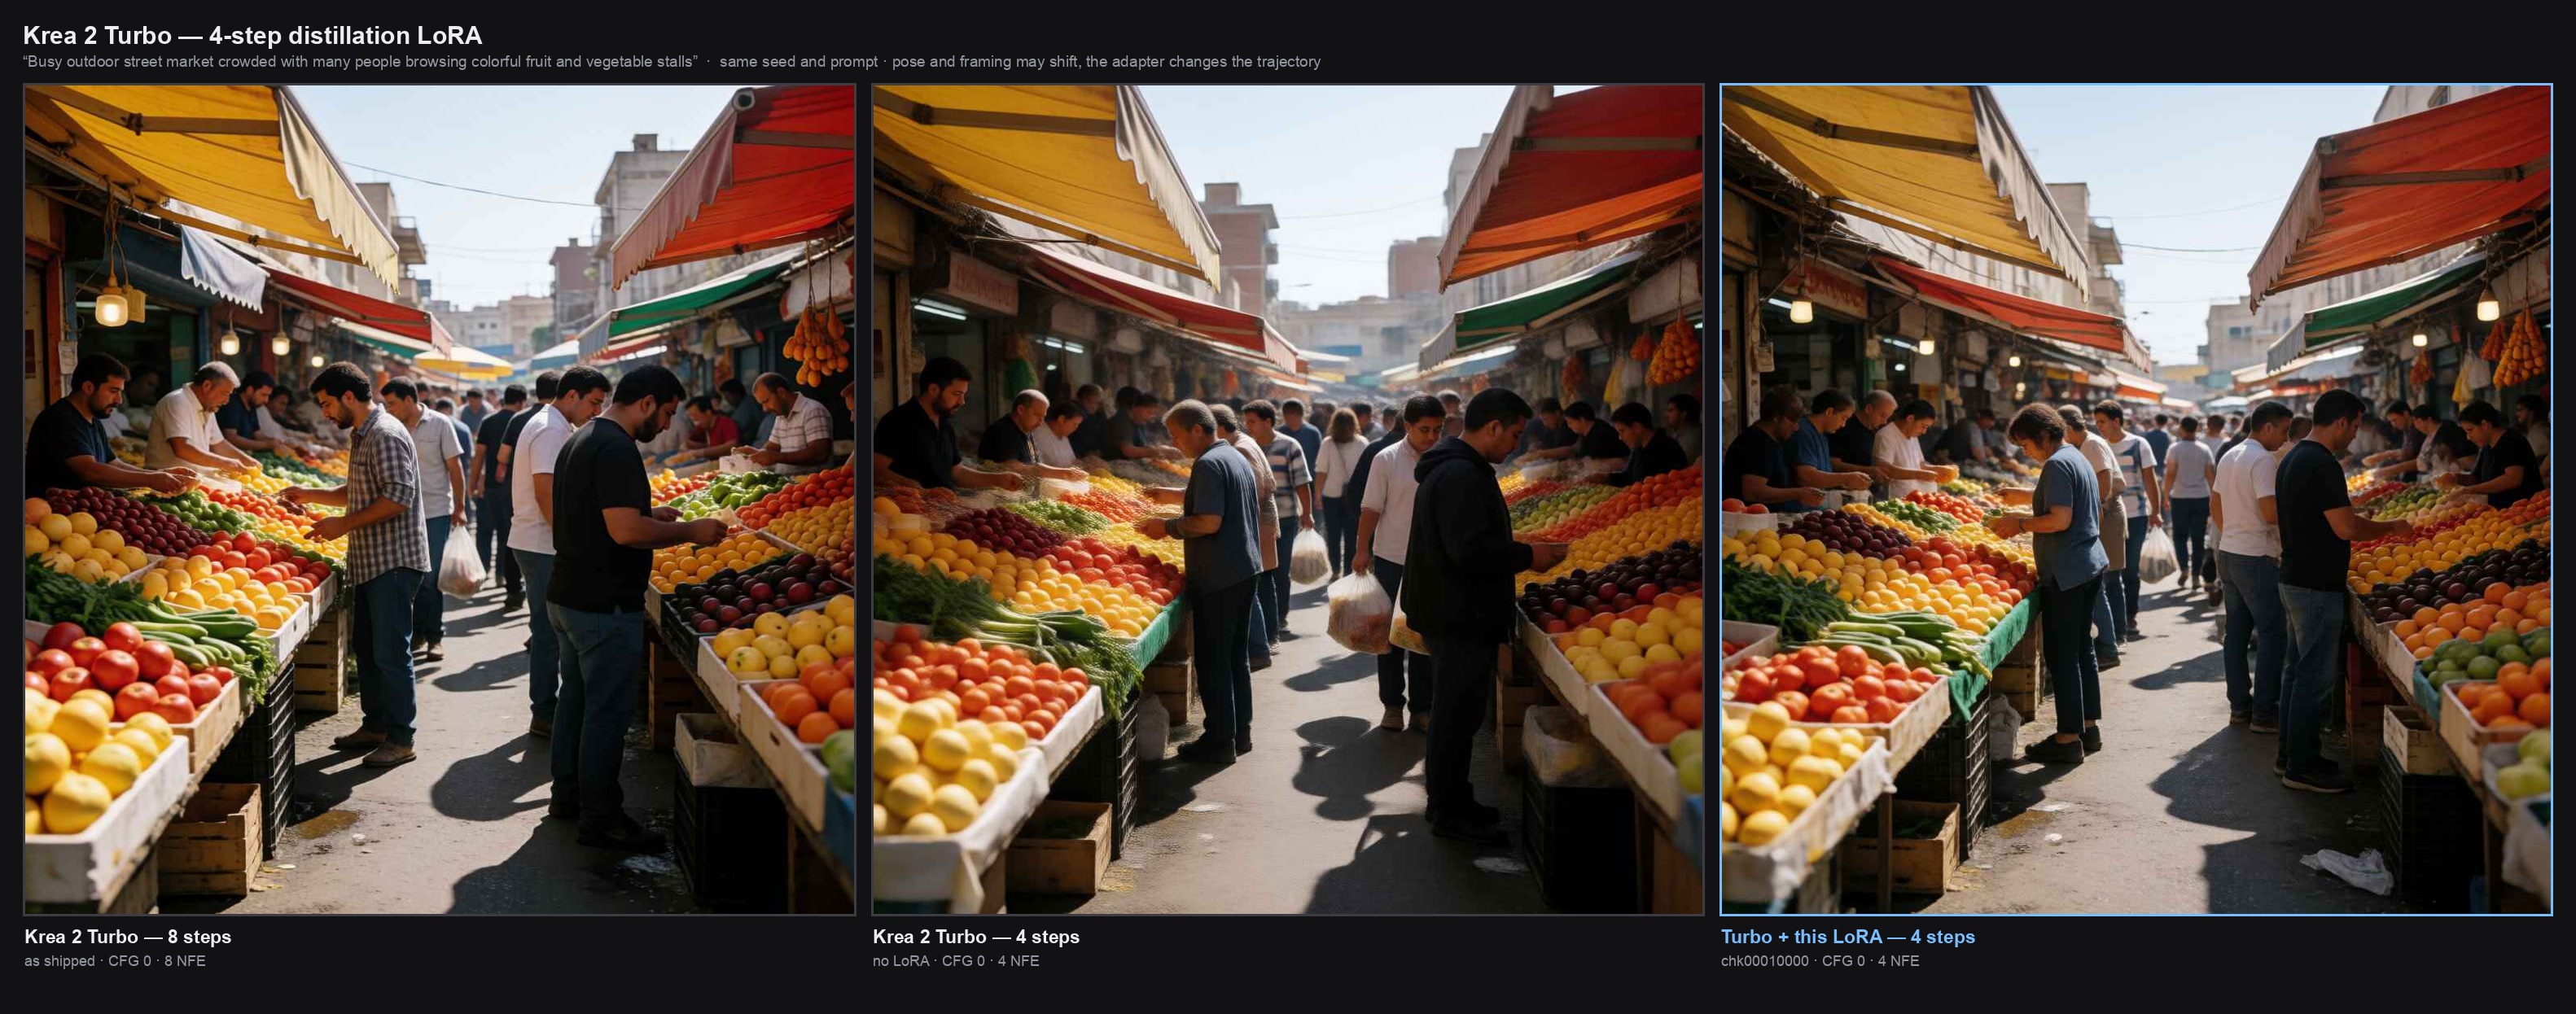
- assets/market_compare_turbo.jpg +2 -2
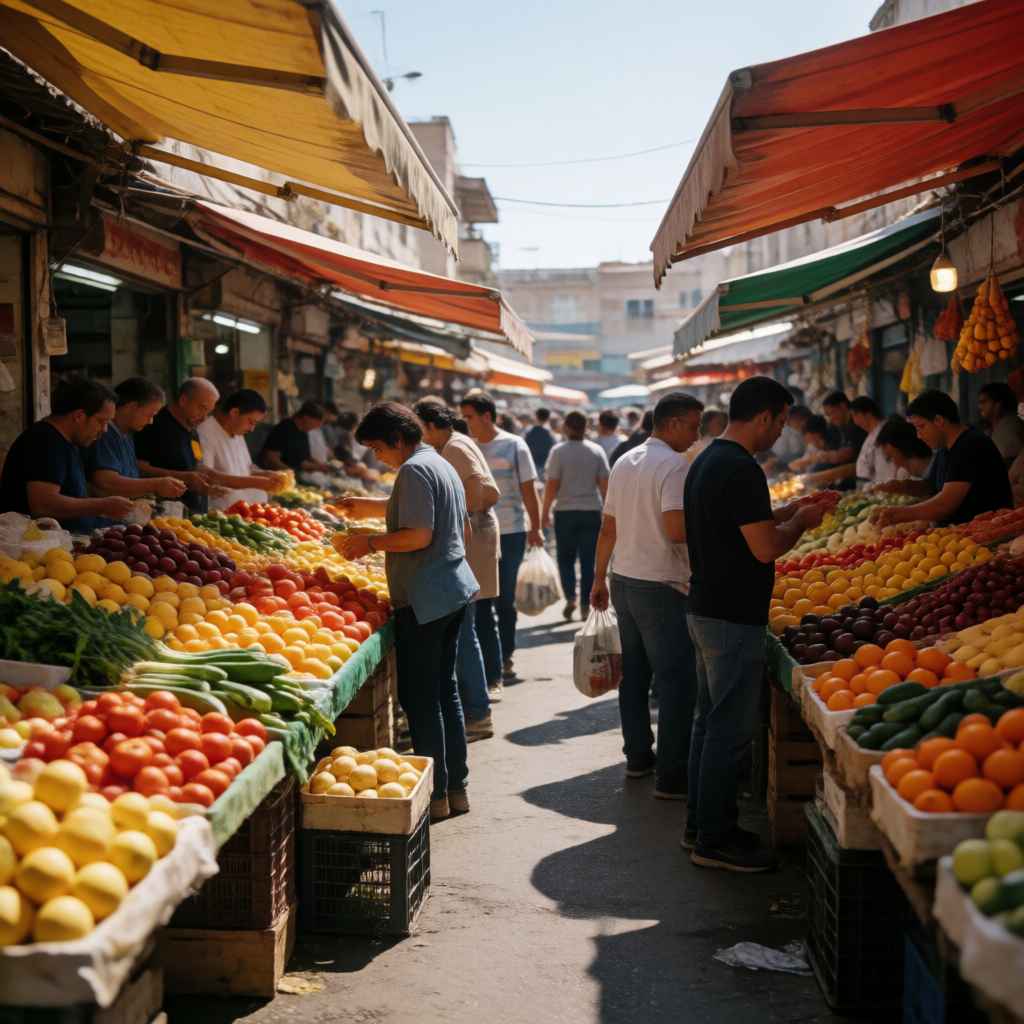
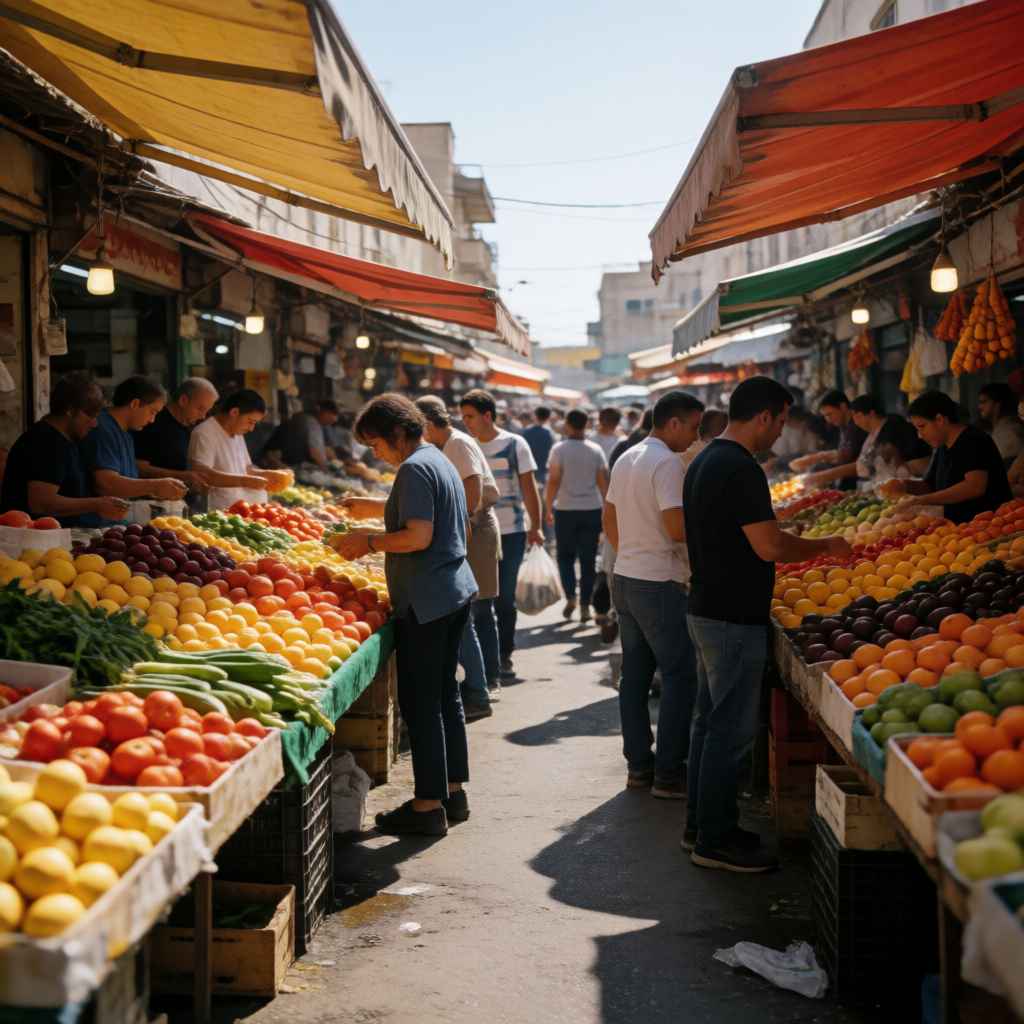
- assets/market_turbo_4step_lora_latest.jpg +0 -0
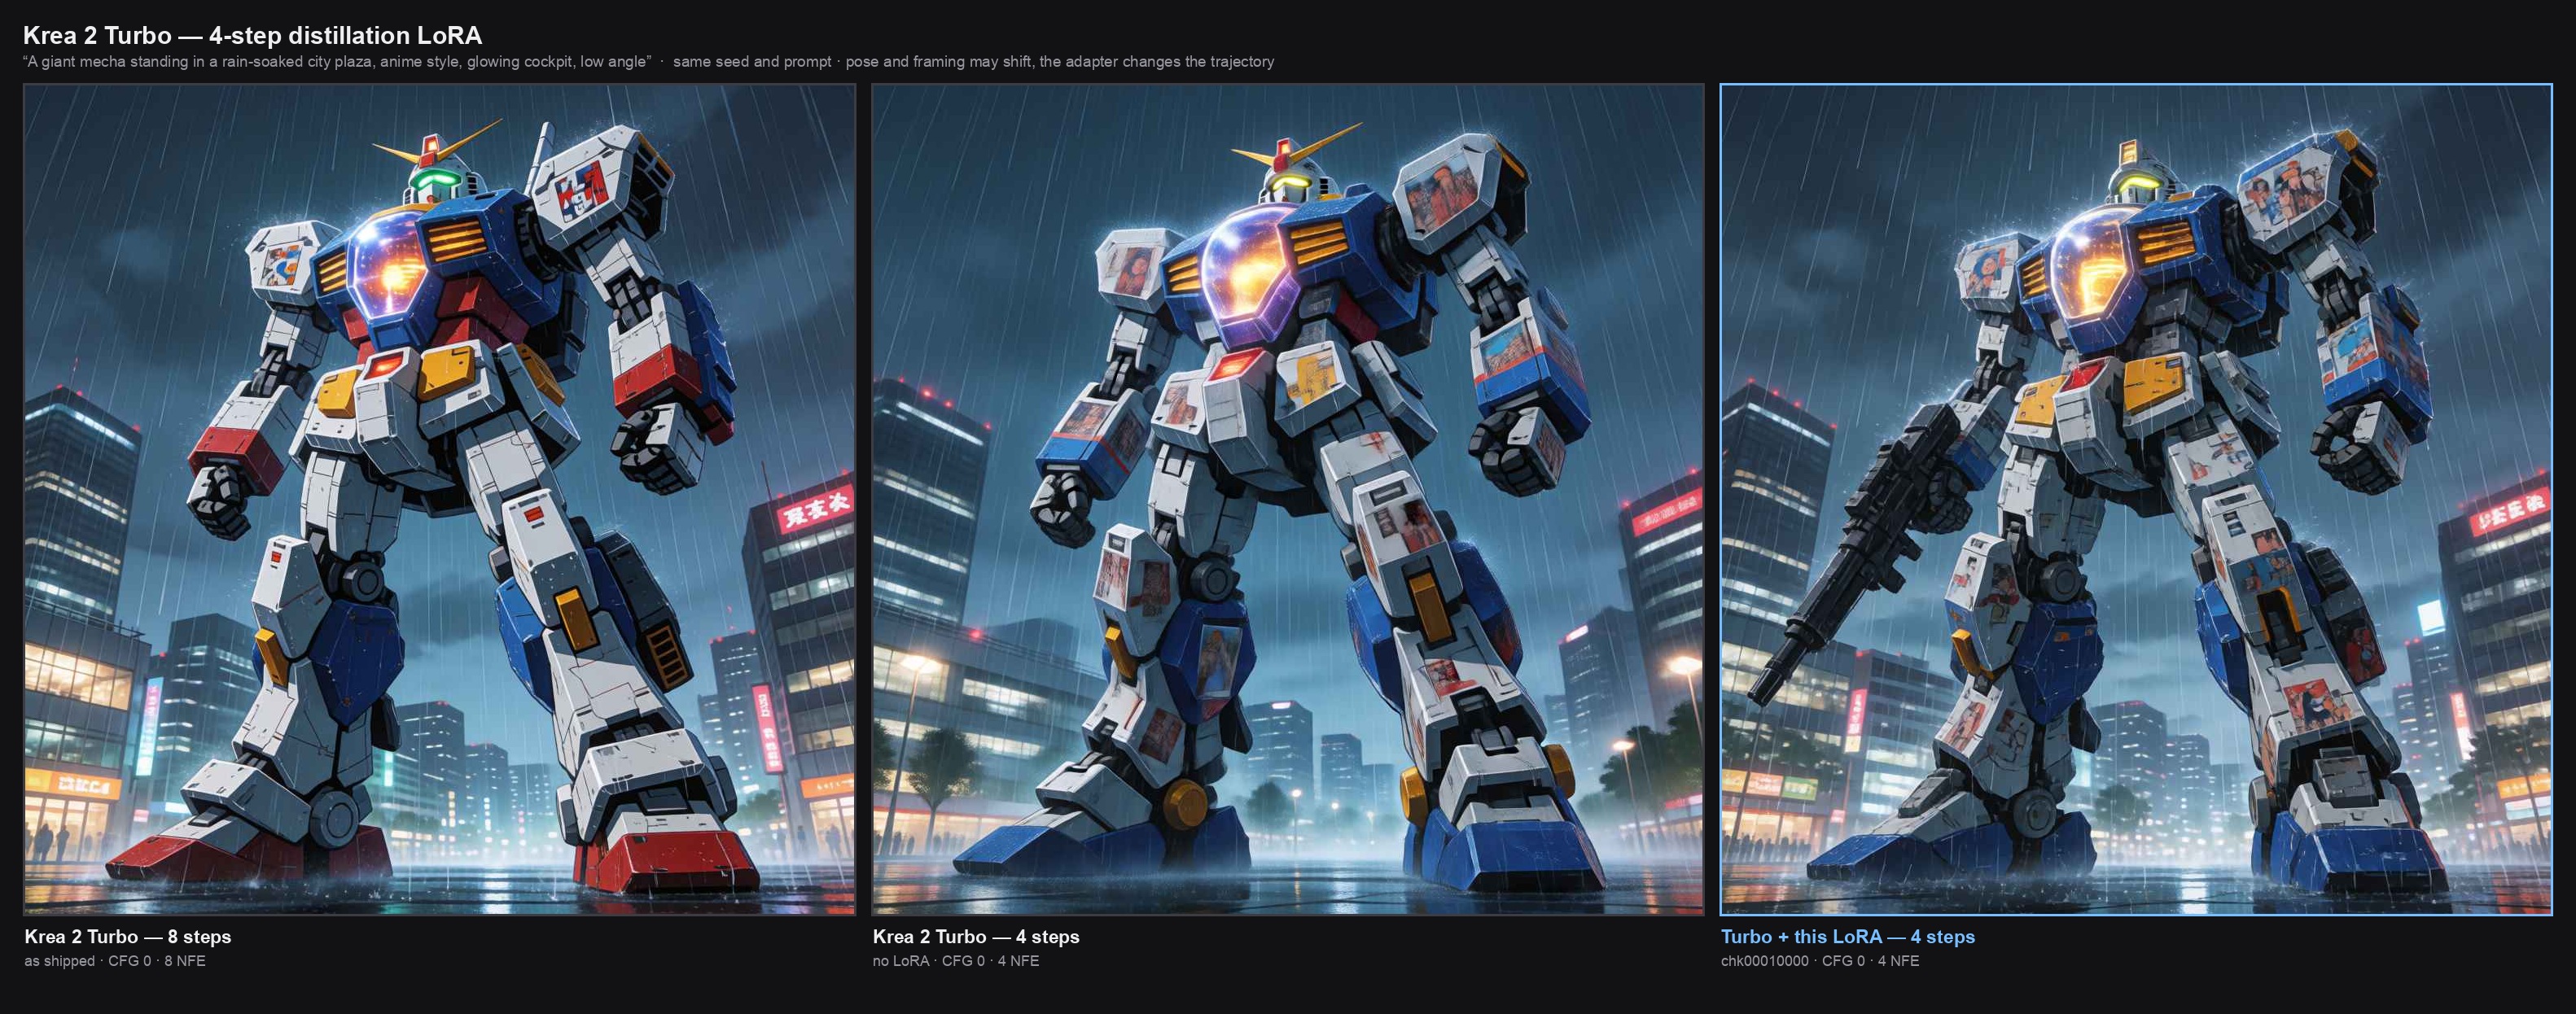
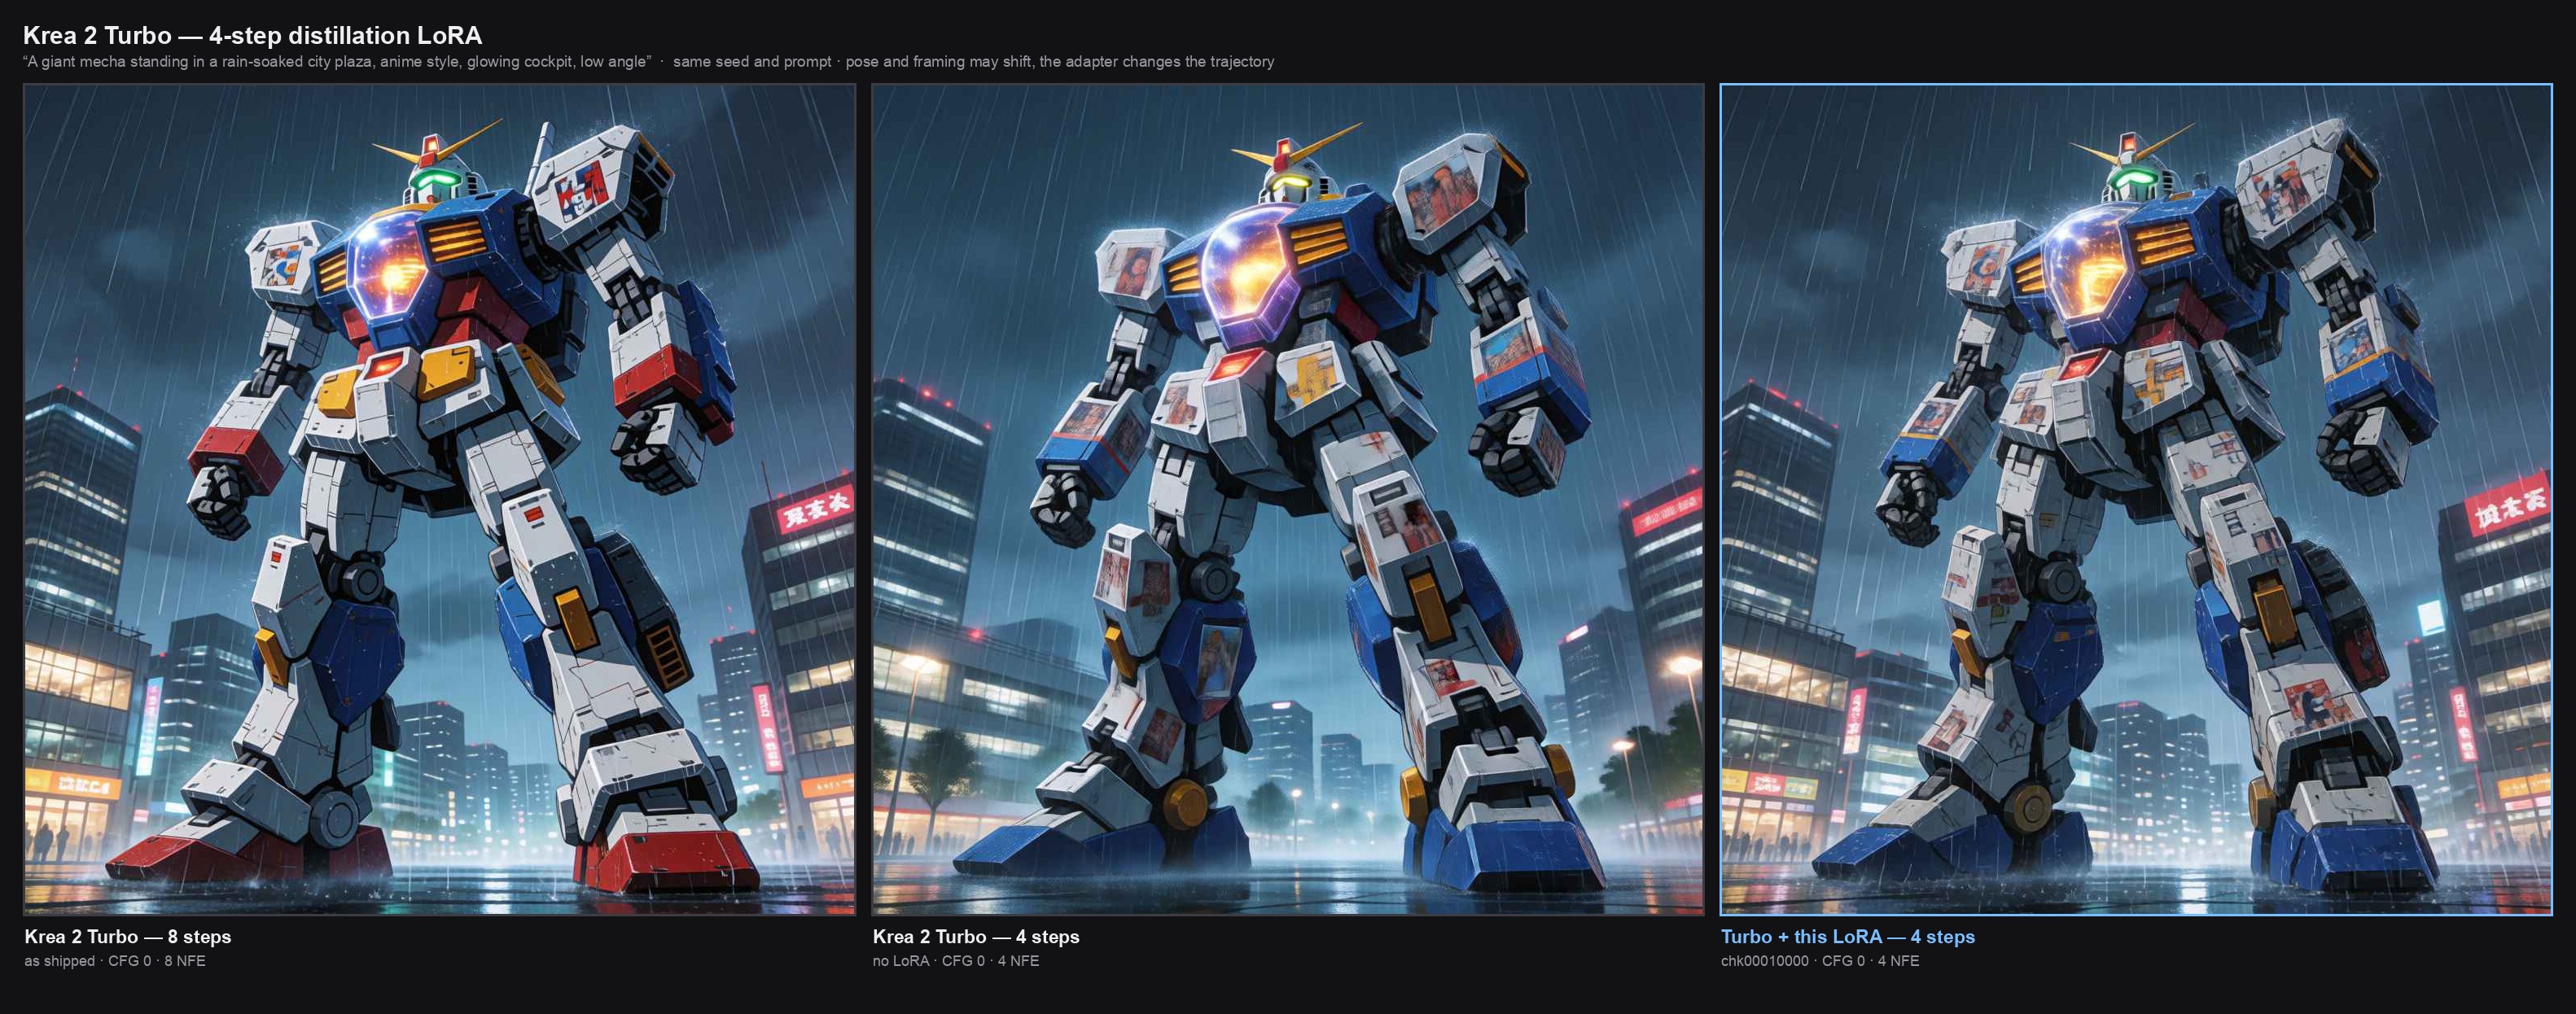
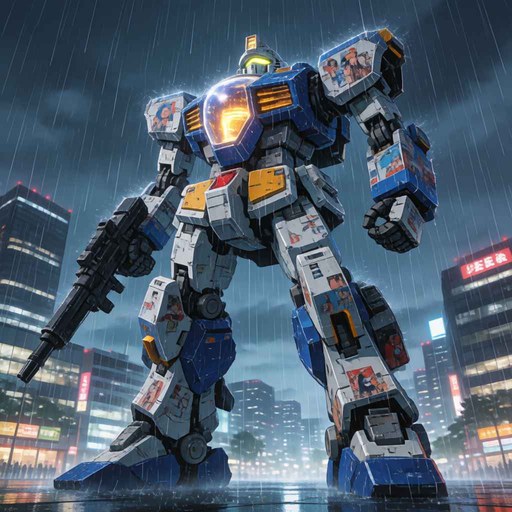
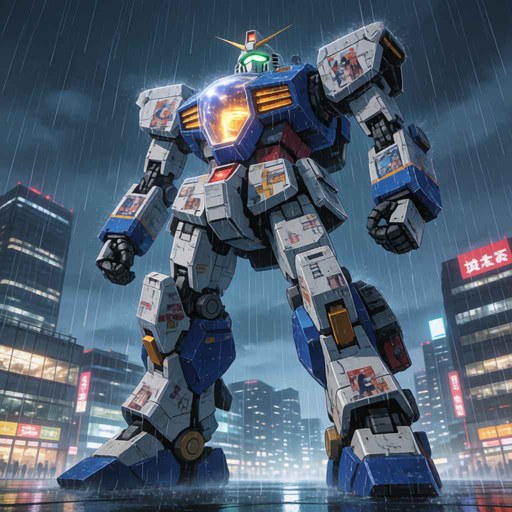
- assets/mecha_compare_turbo.jpg +2 -2
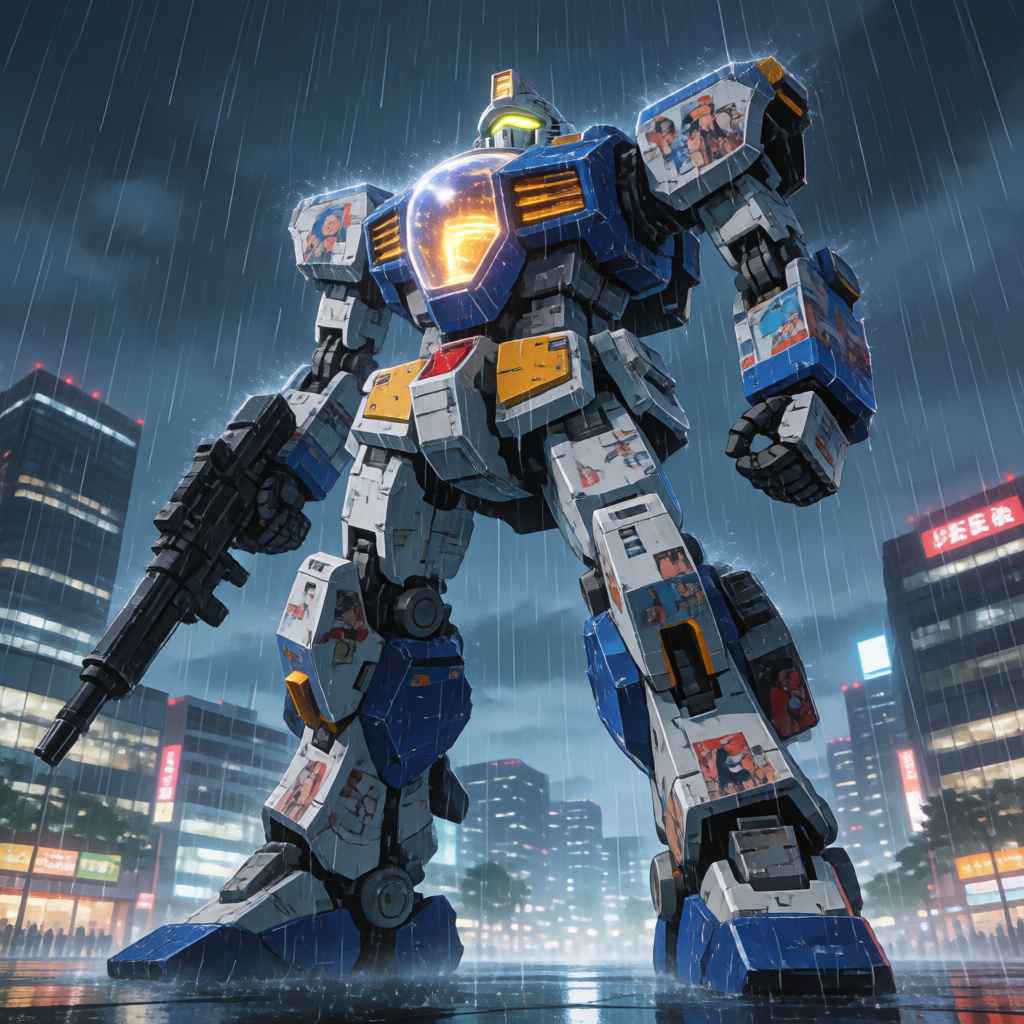
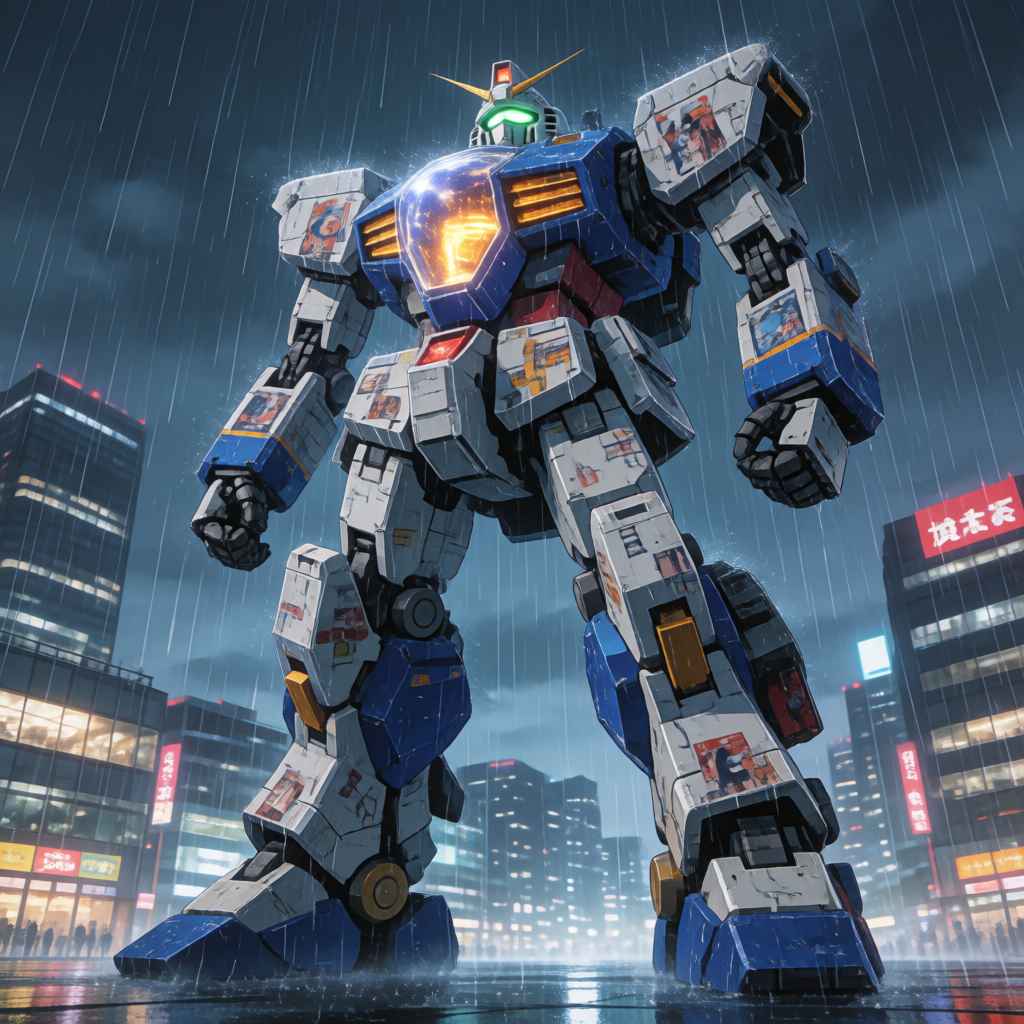
- assets/mecha_turbo_4step_lora_latest.jpg +0 -0
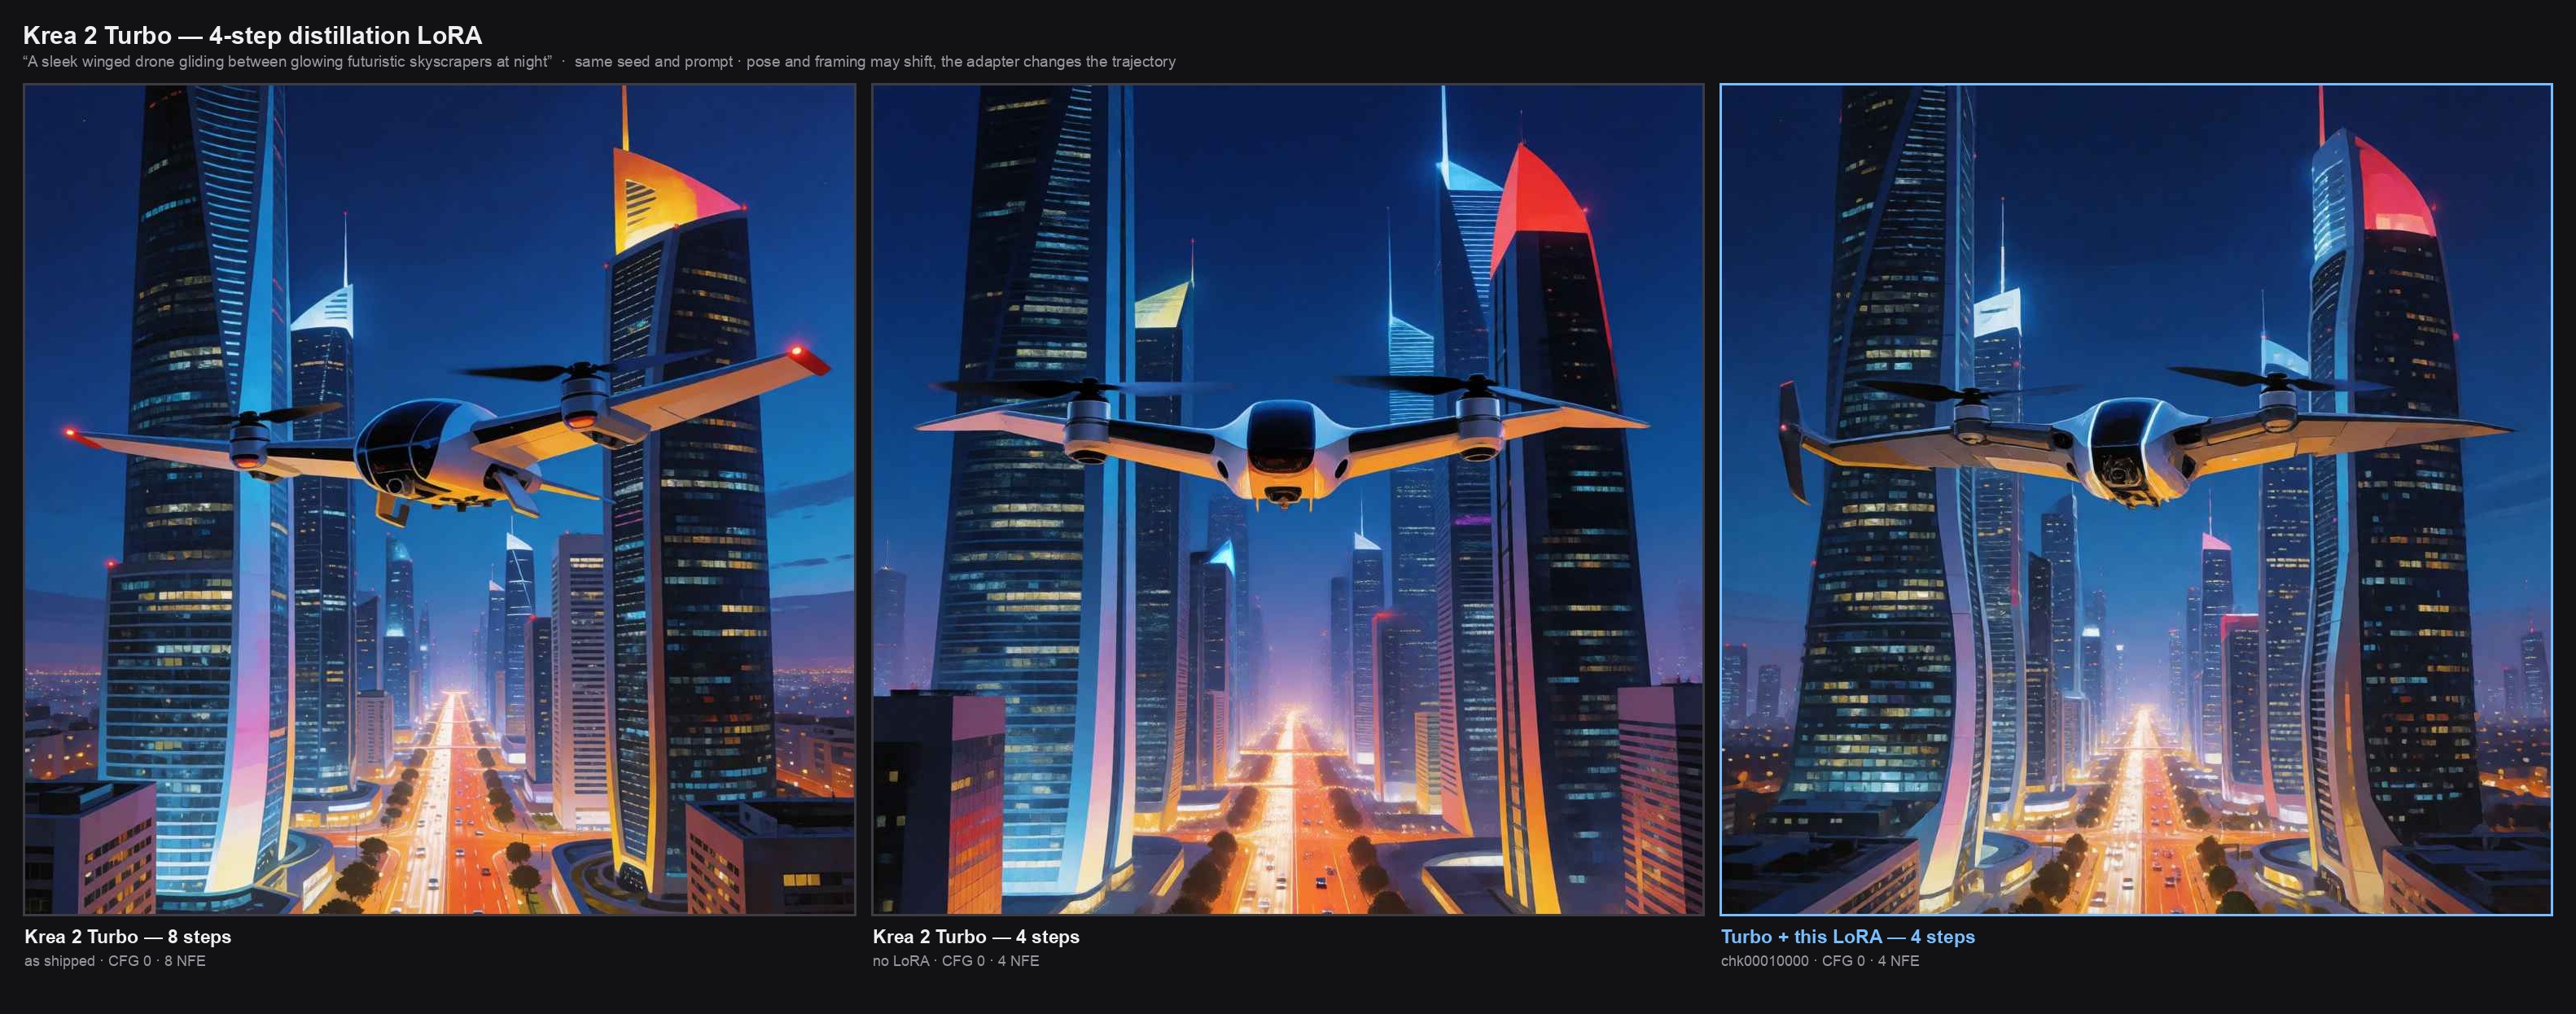
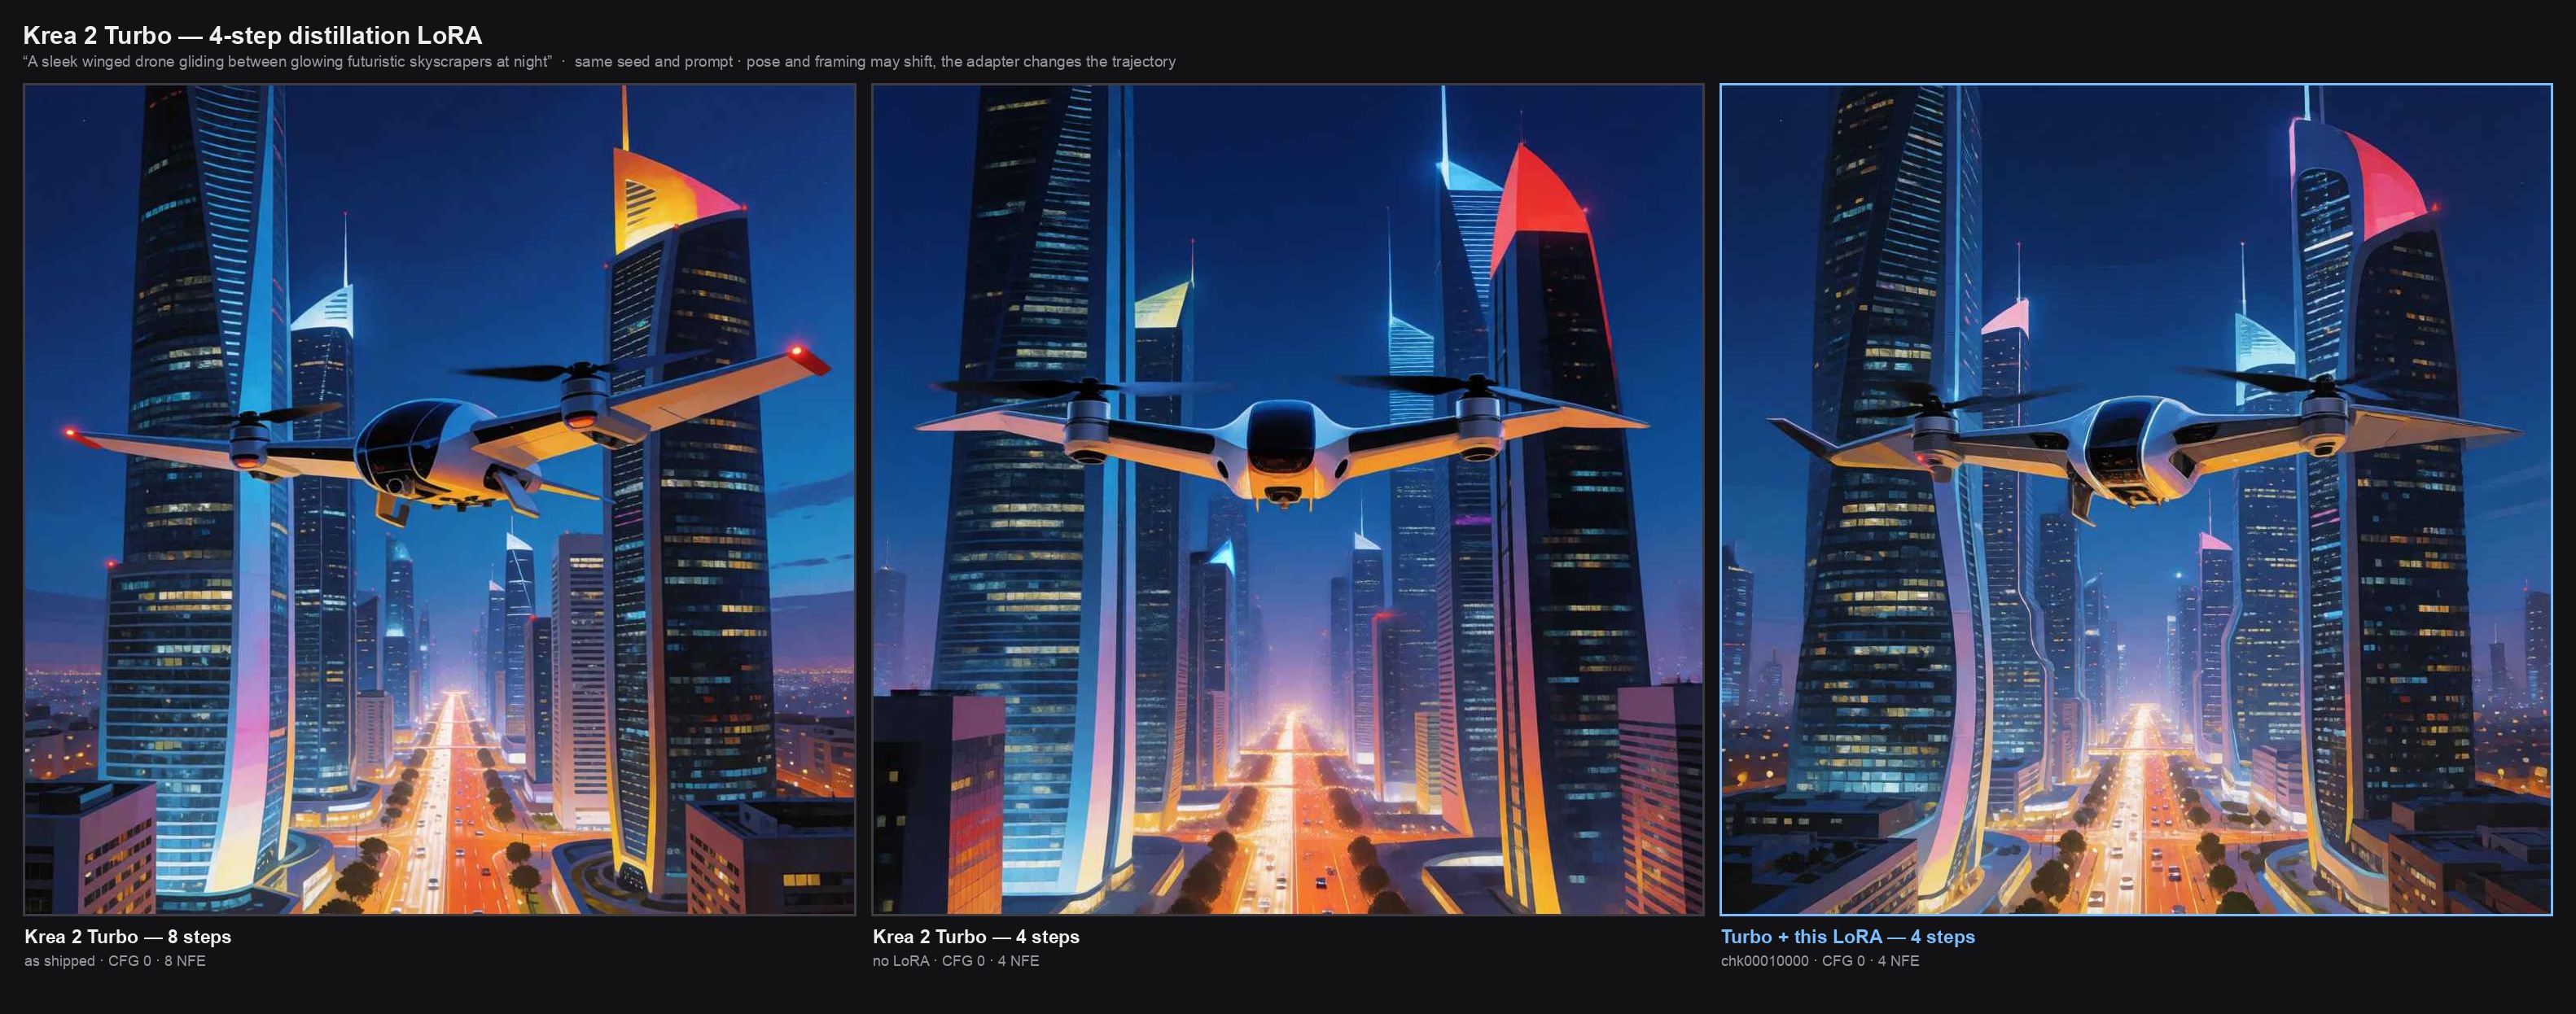
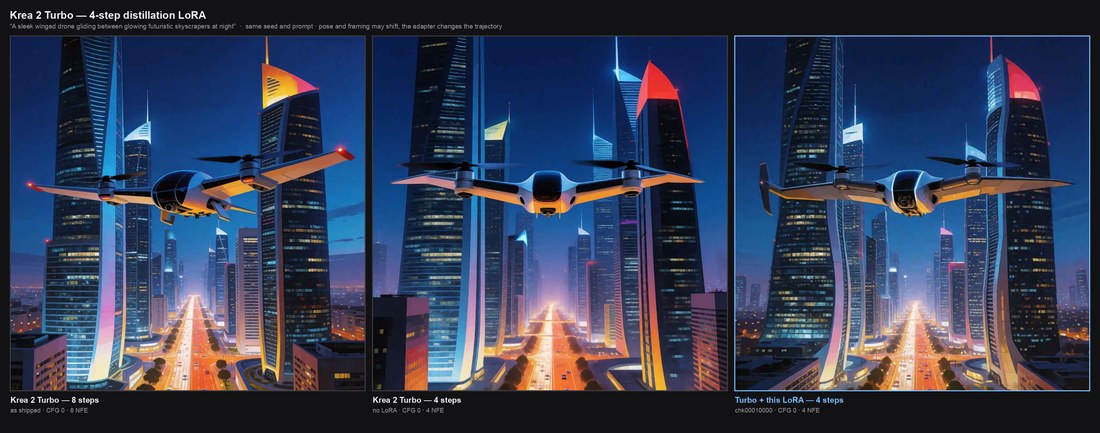
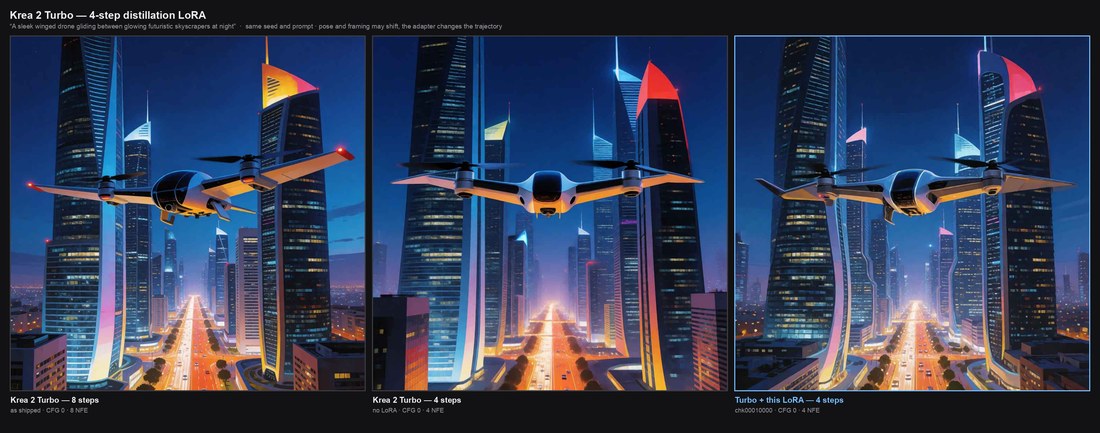
- assets/megacity_compare_turbo.jpg +2 -2
- assets/megacity_turbo_4step_lora_latest.jpg +0 -0
- assets/neonstreet_compare_turbo.jpg +2 -2
- assets/neonstreet_turbo_4step_lora_latest.jpg +0 -0
- assets/pizza_compare_turbo.jpg +2 -2
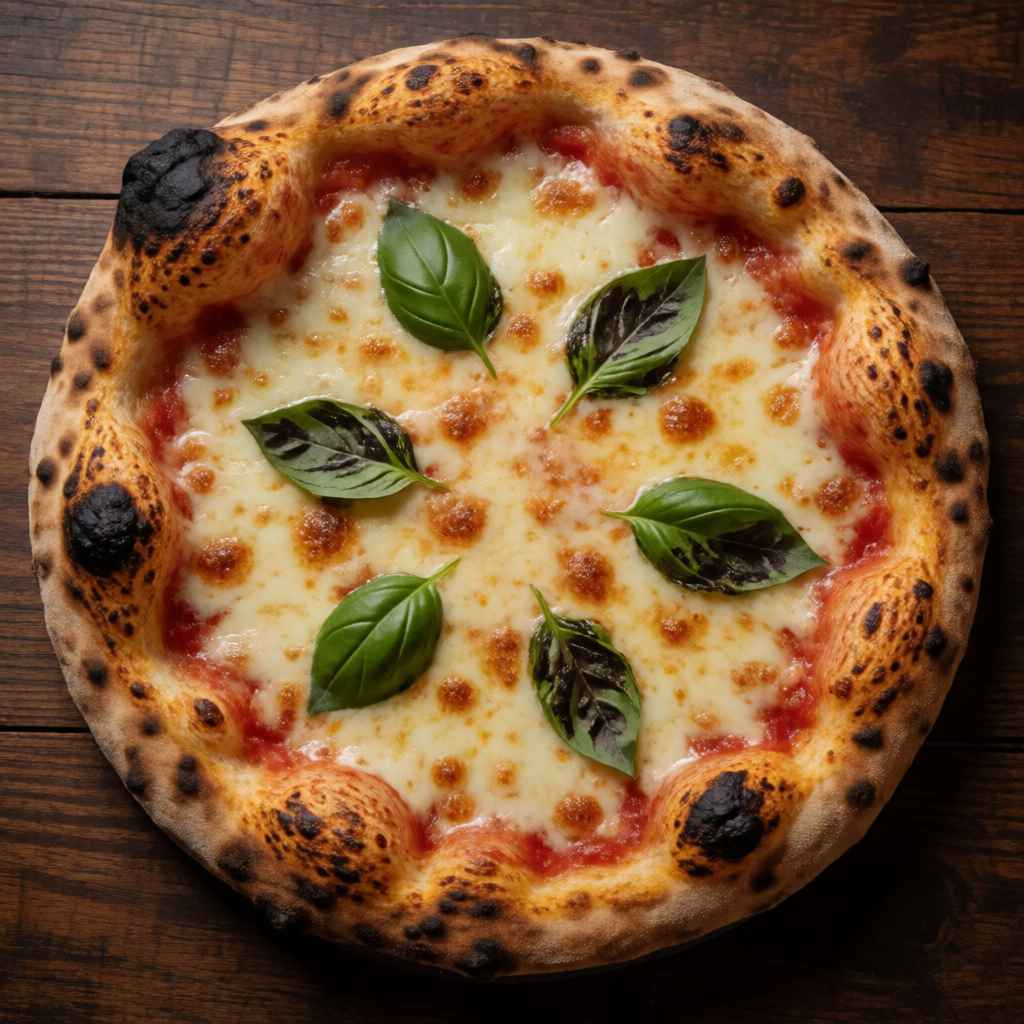
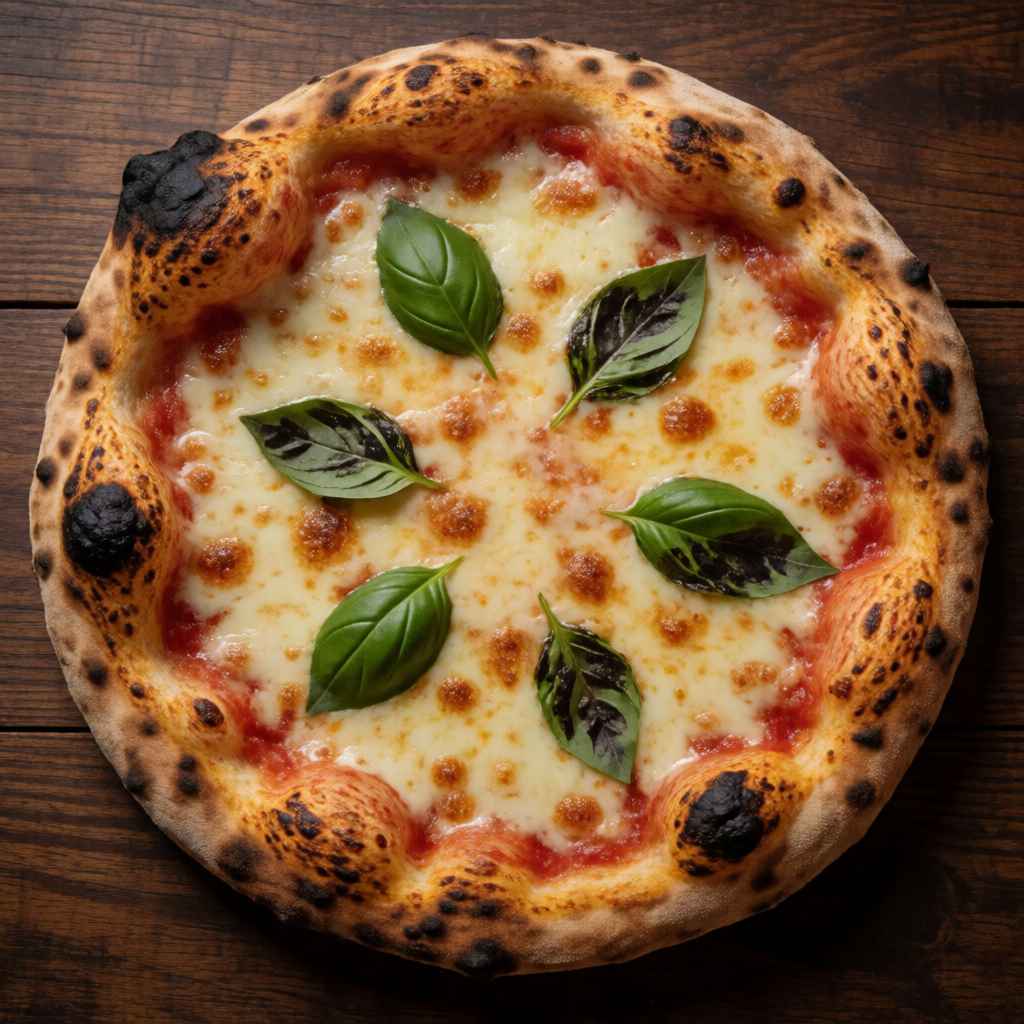
- assets/pizza_turbo_4step_lora_latest.jpg +0 -0
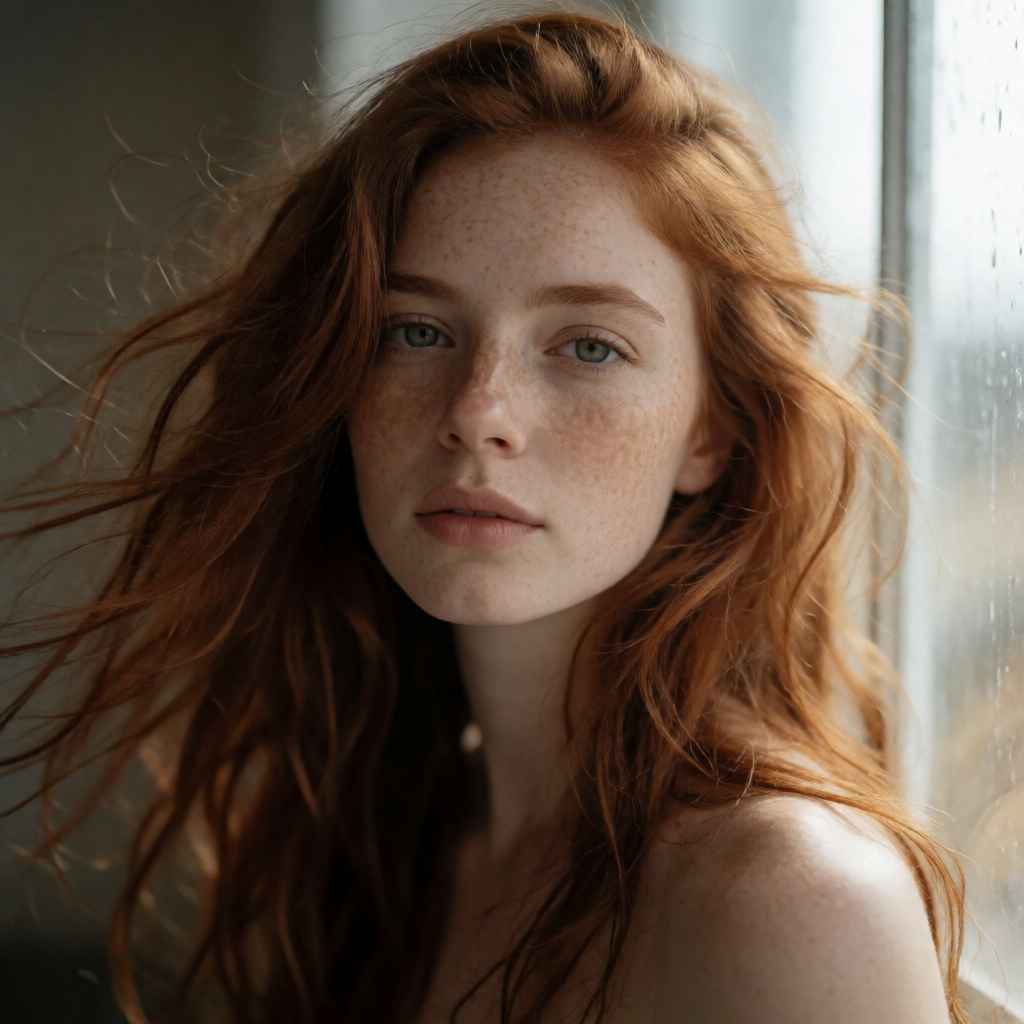
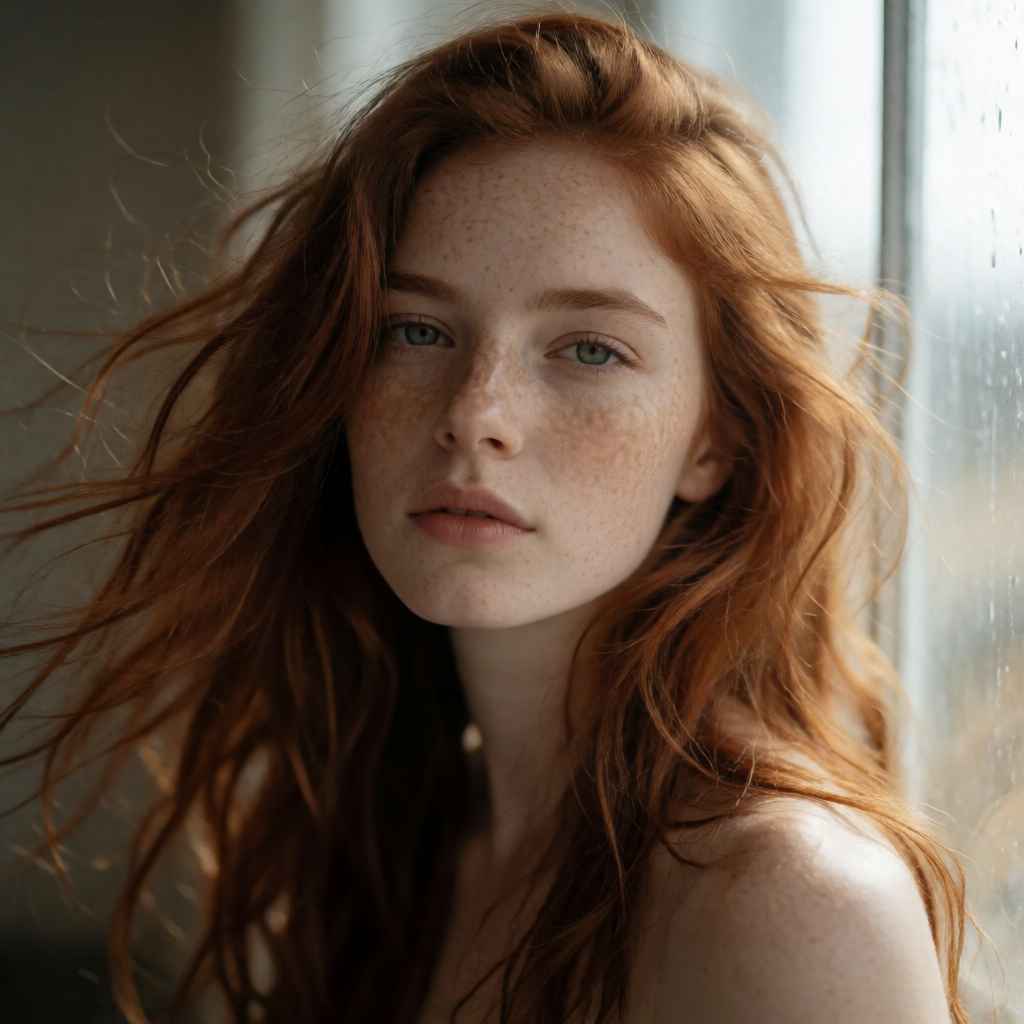
- assets/portrait_compare_turbo.jpg +2 -2
- assets/portrait_strength_0.5.jpg +0 -0
- assets/portrait_strength_1.0.jpg +0 -0
- assets/portrait_strength_1.5.jpg +0 -0
- assets/portrait_strength_2.0.jpg +0 -0
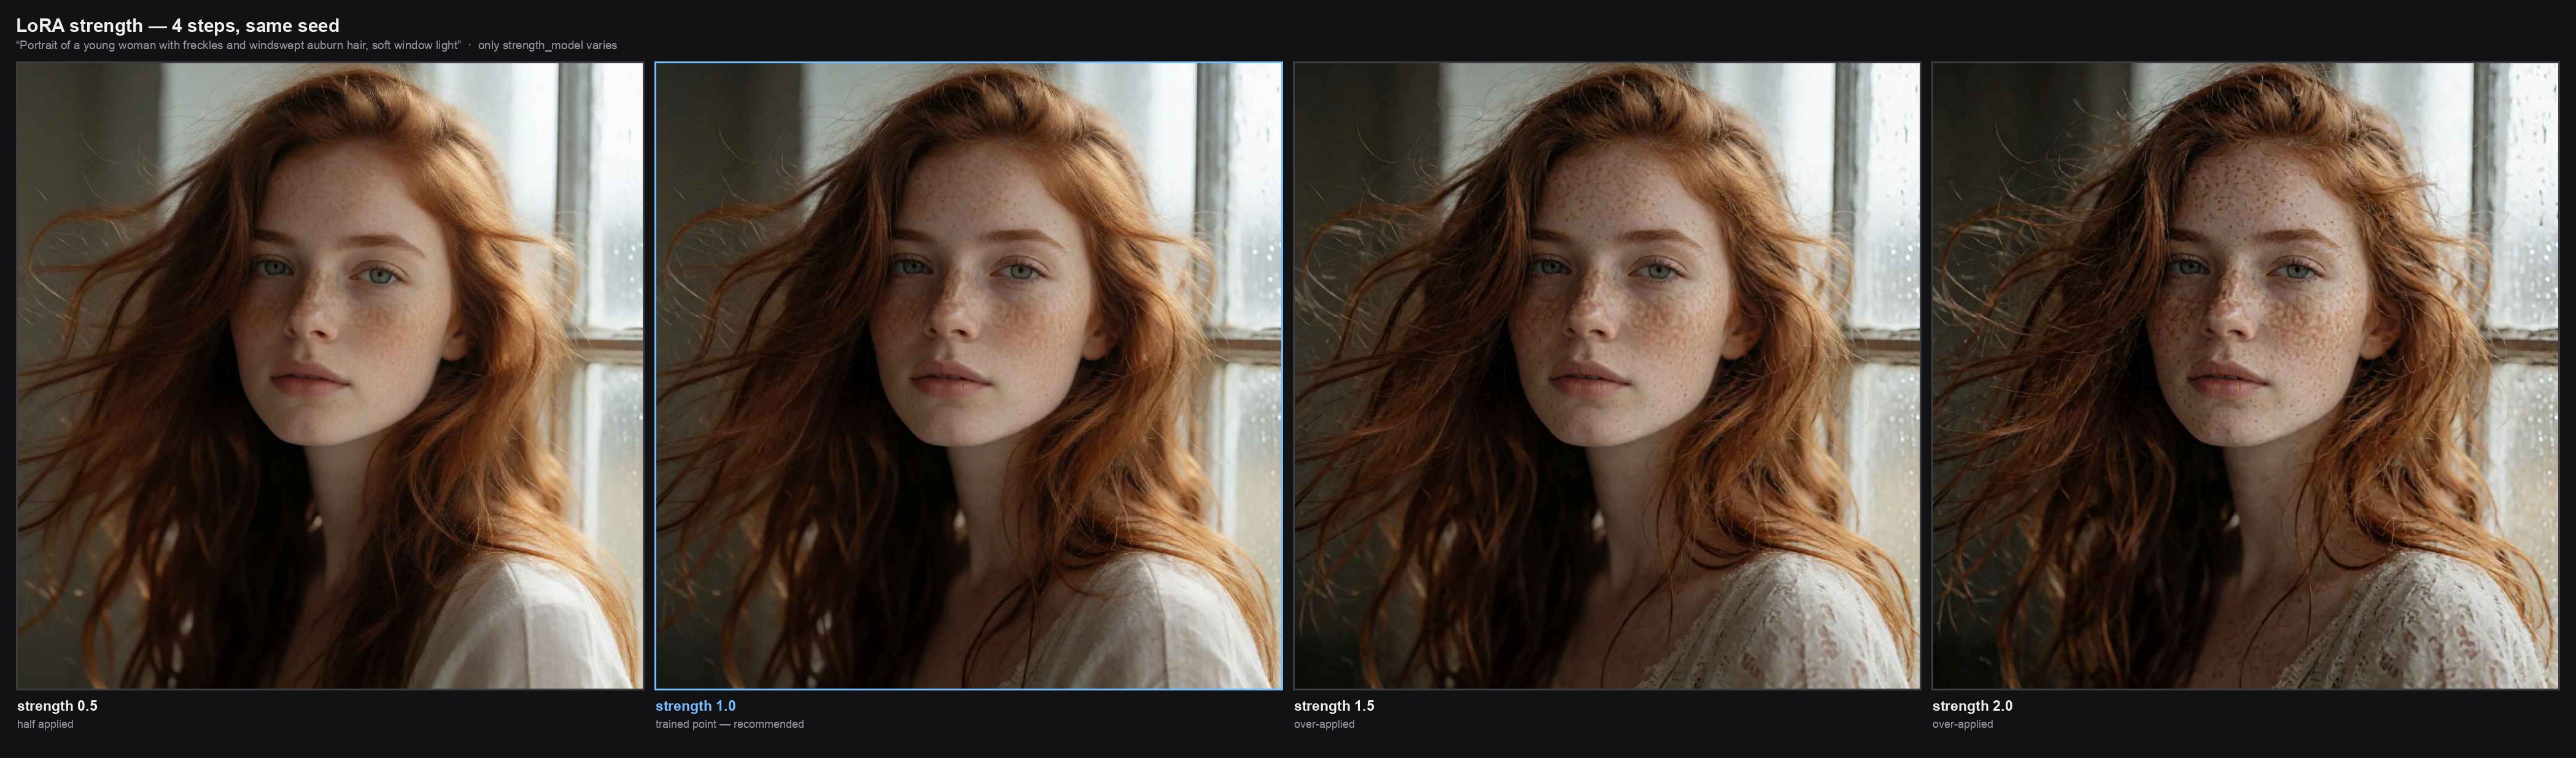
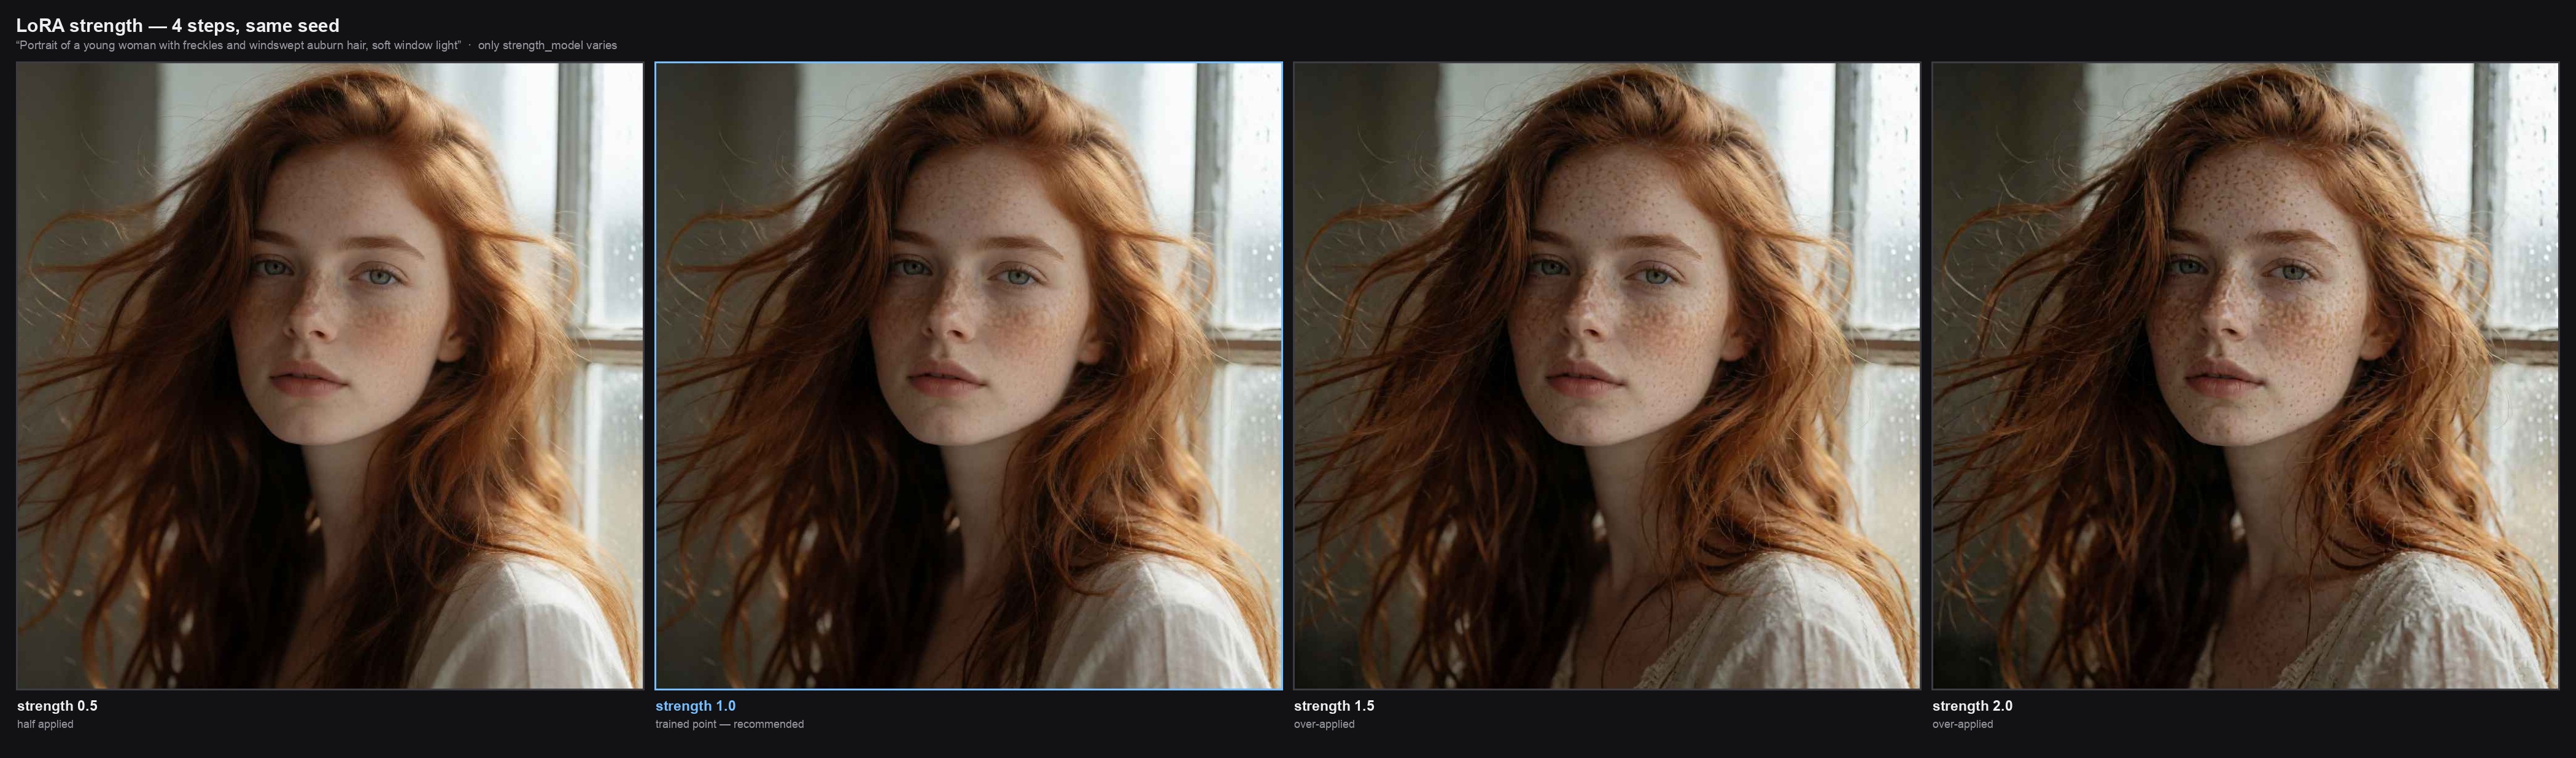
- assets/portrait_strength_sweep.jpg +2 -2
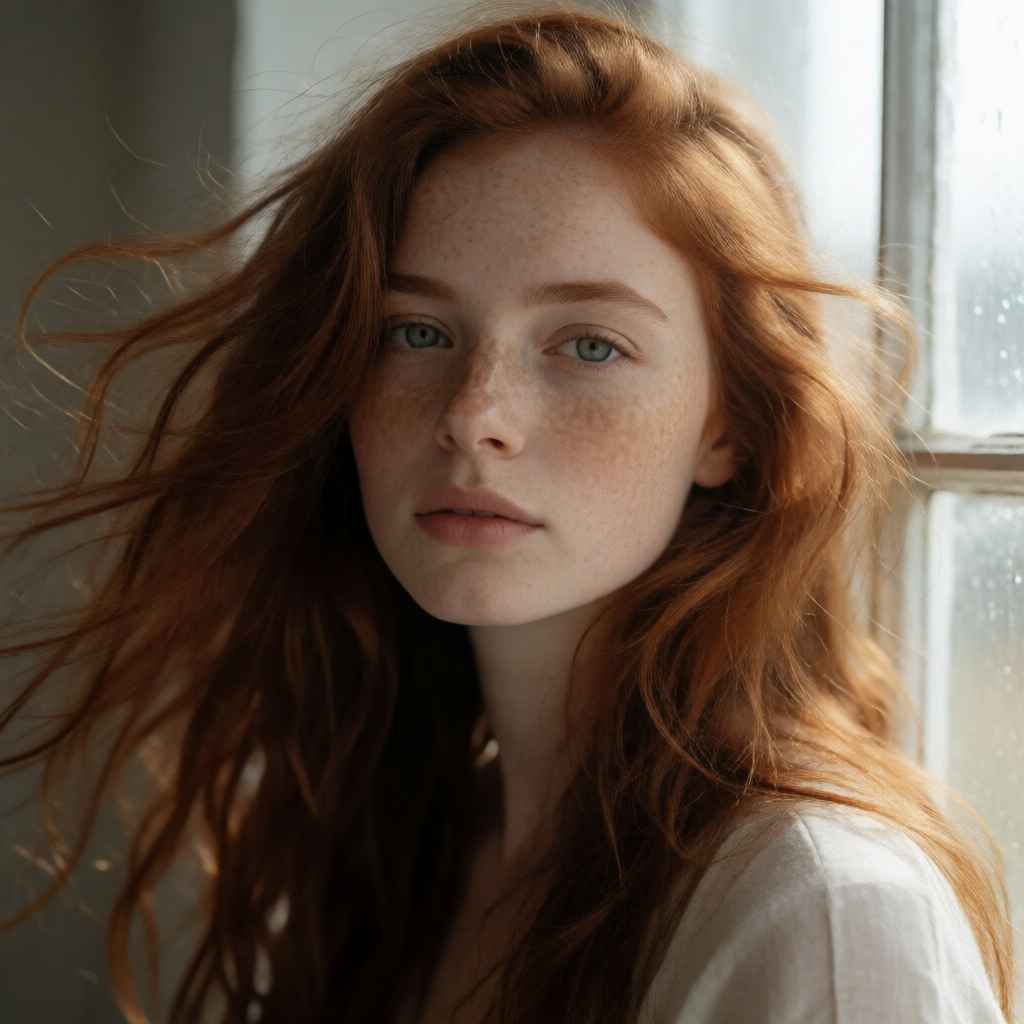
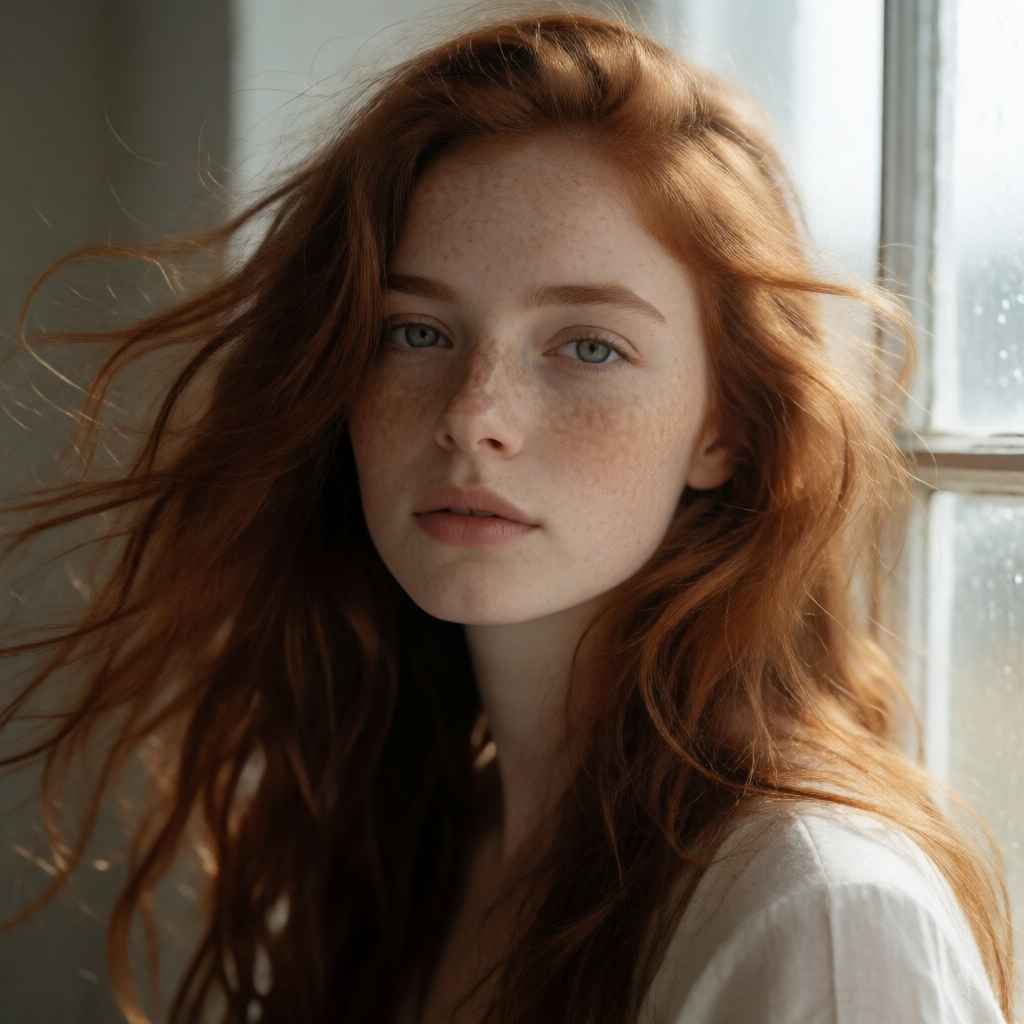
- assets/portrait_turbo_4step_lora_latest.jpg +0 -0
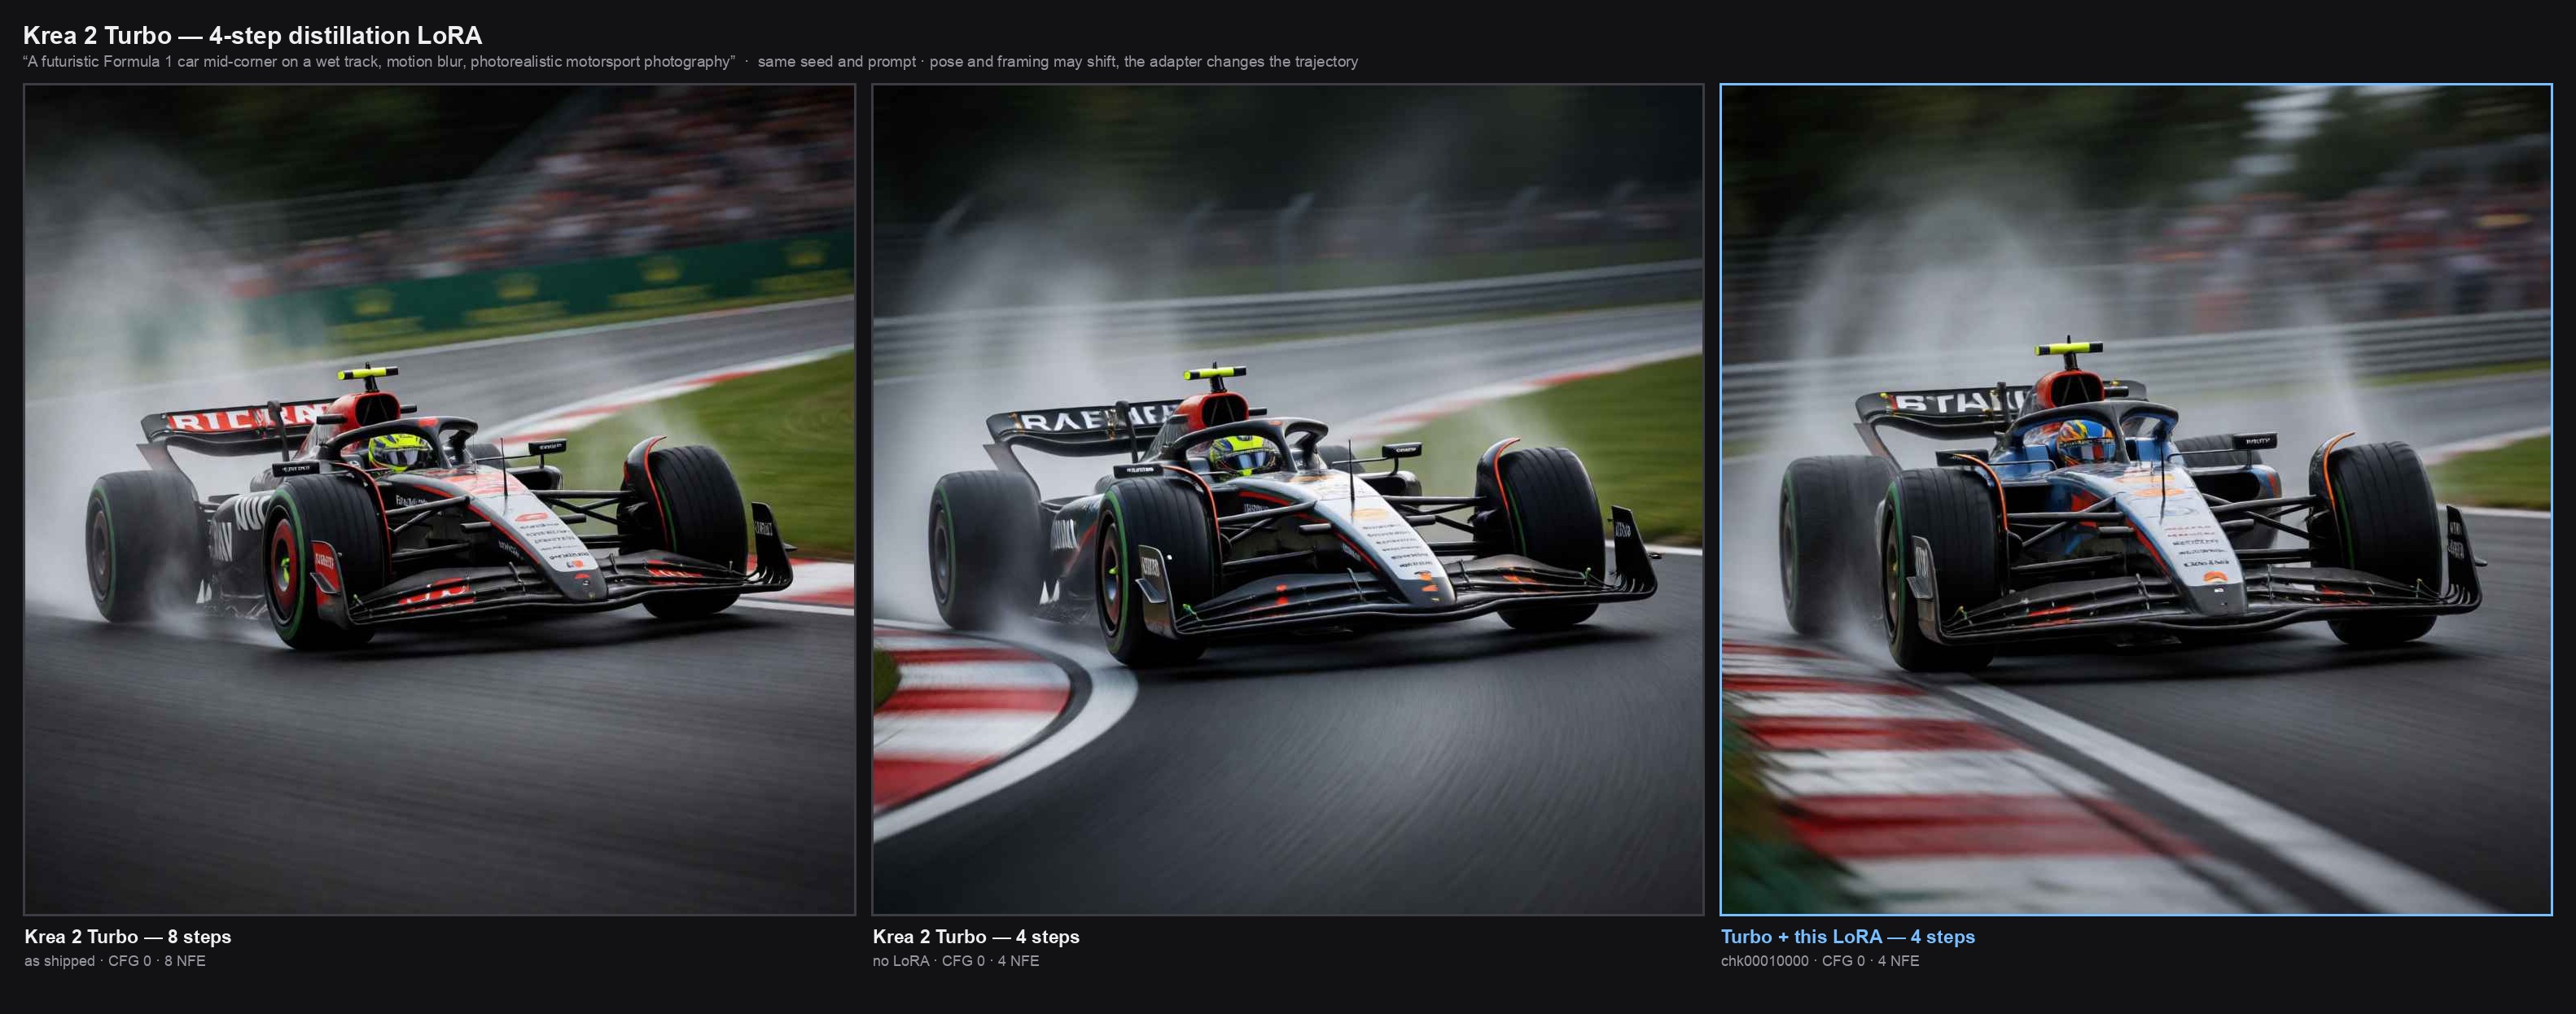
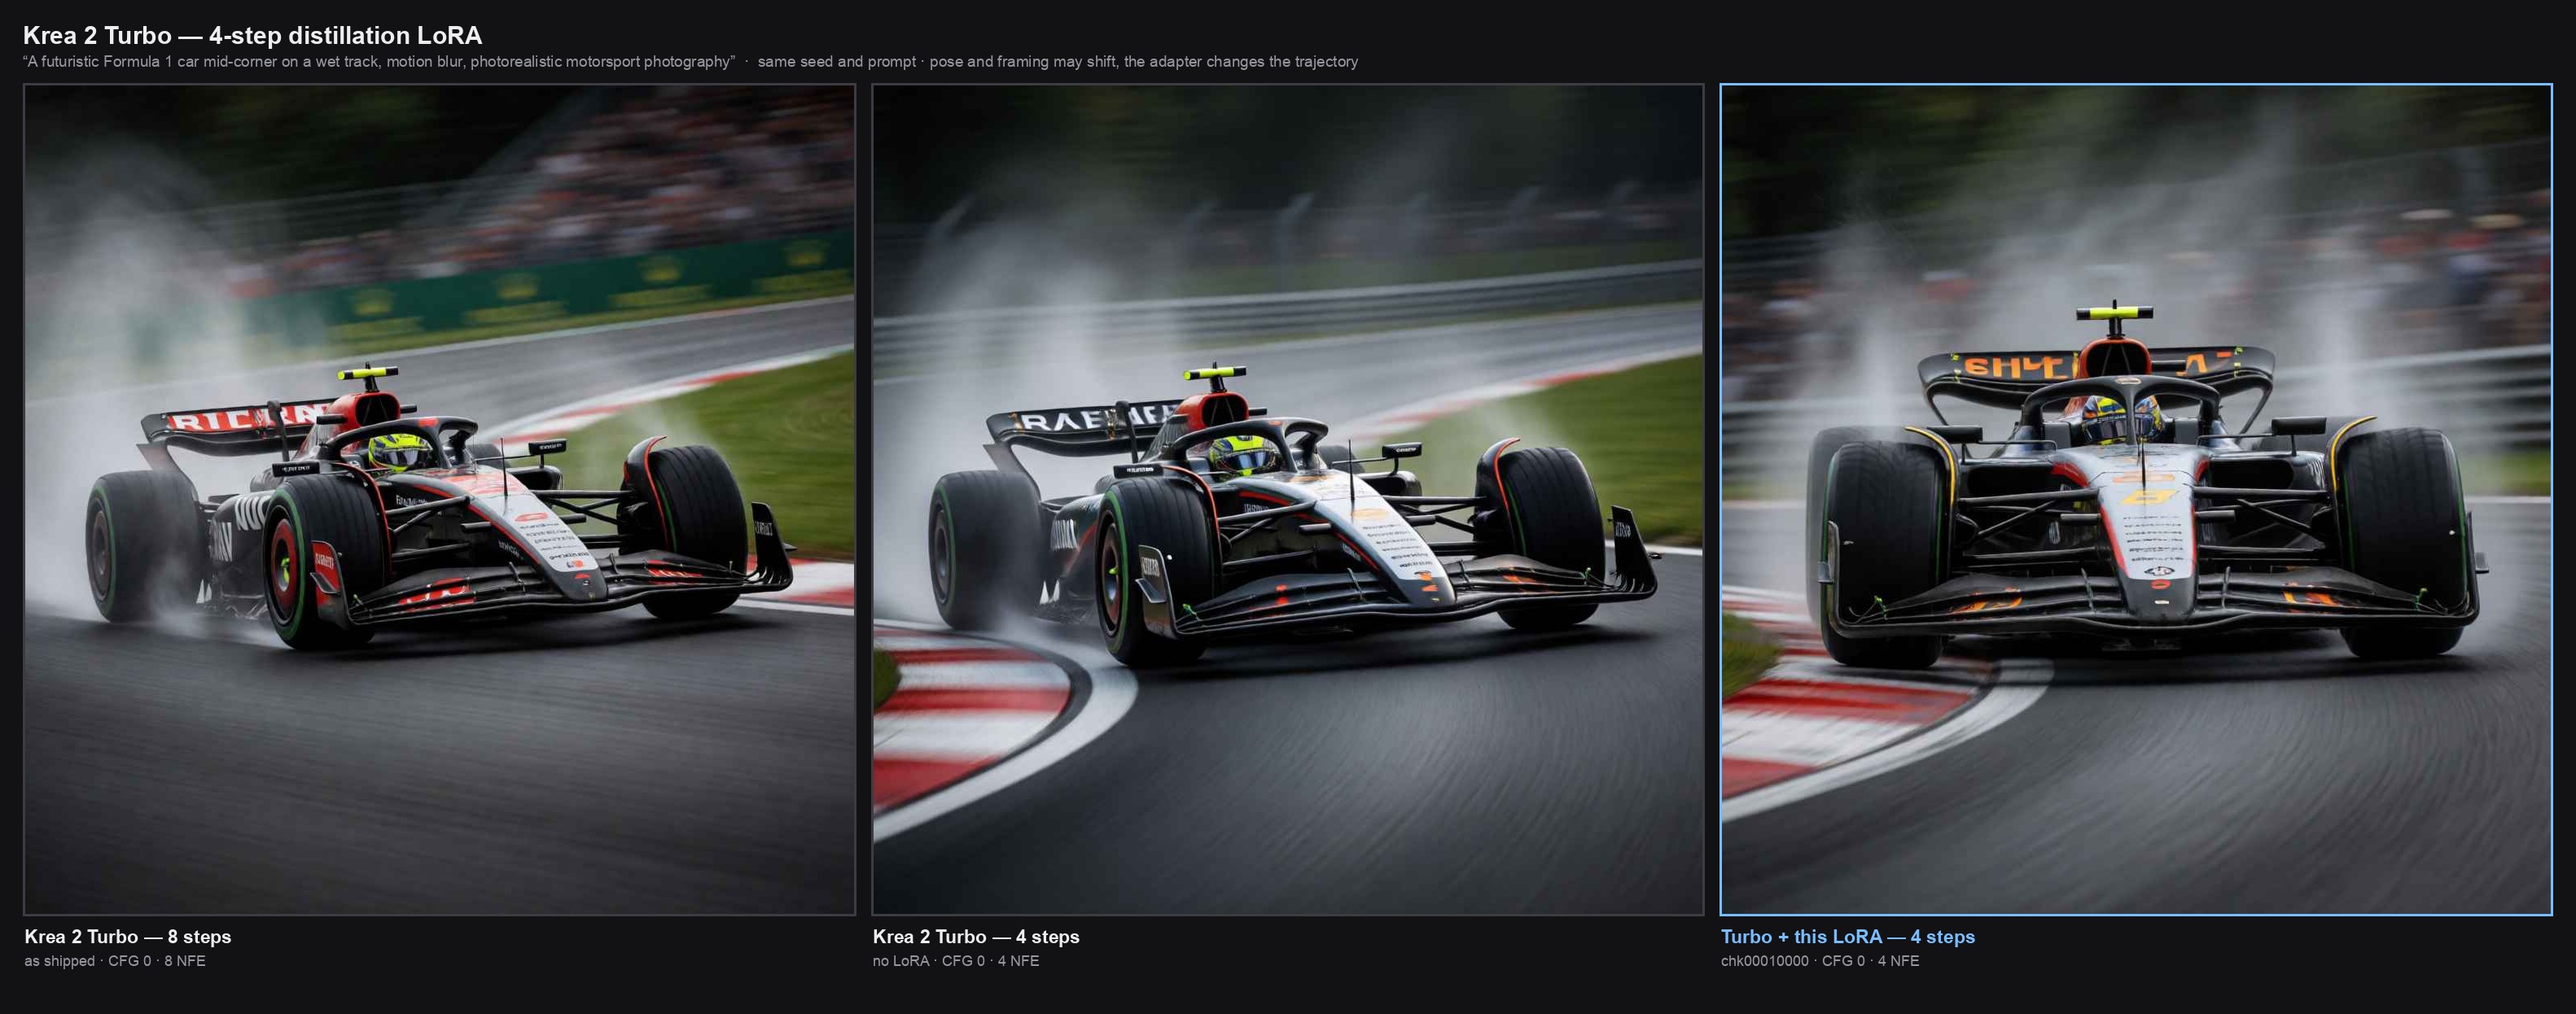
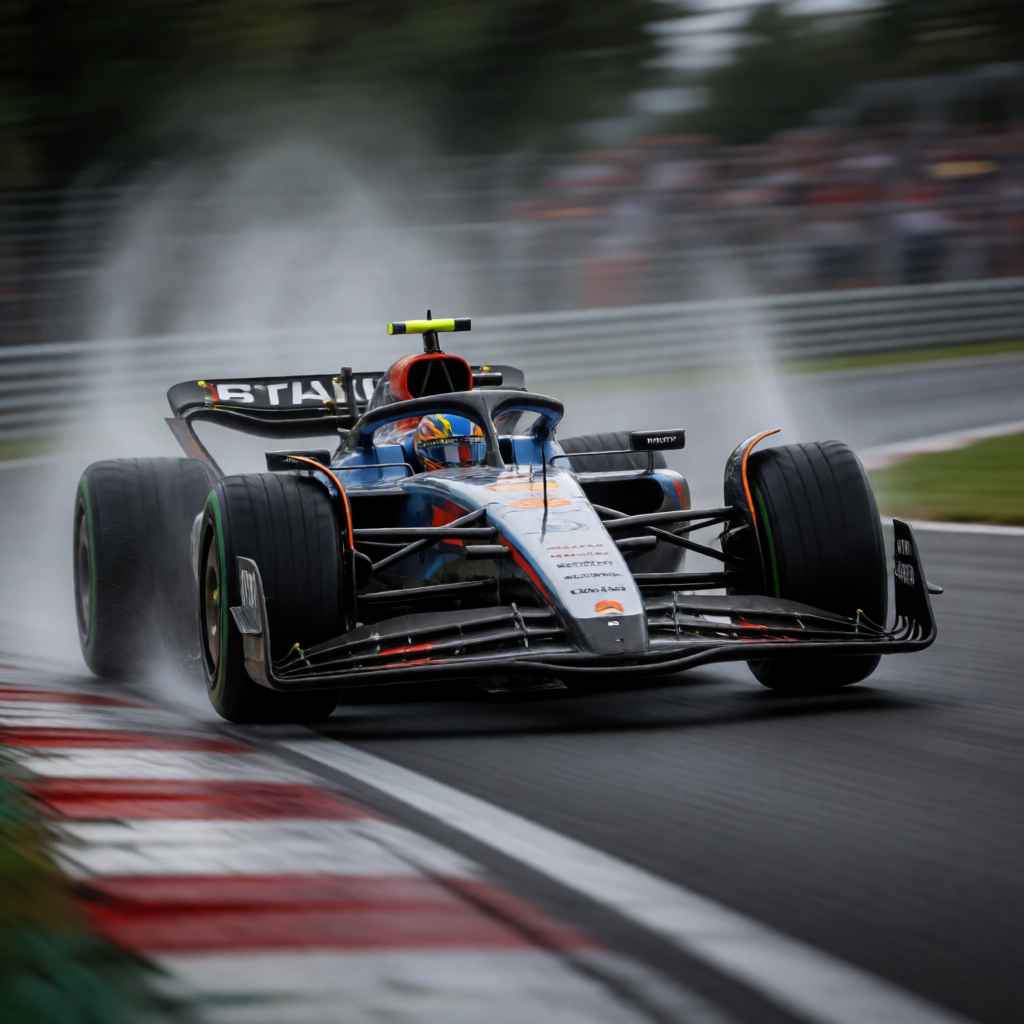
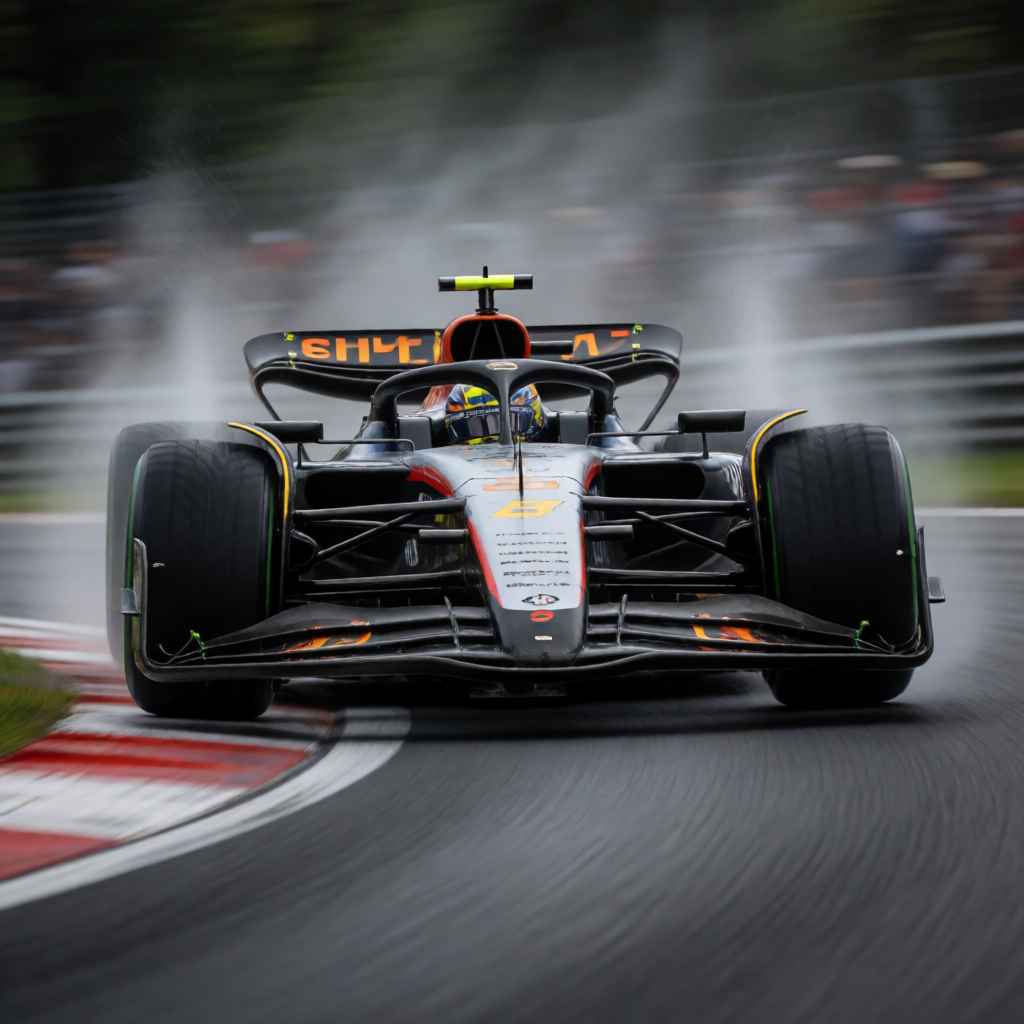
- assets/racecar_compare_turbo.jpg +2 -2
- assets/racecar_turbo_4step_lora_latest.jpg +0 -0
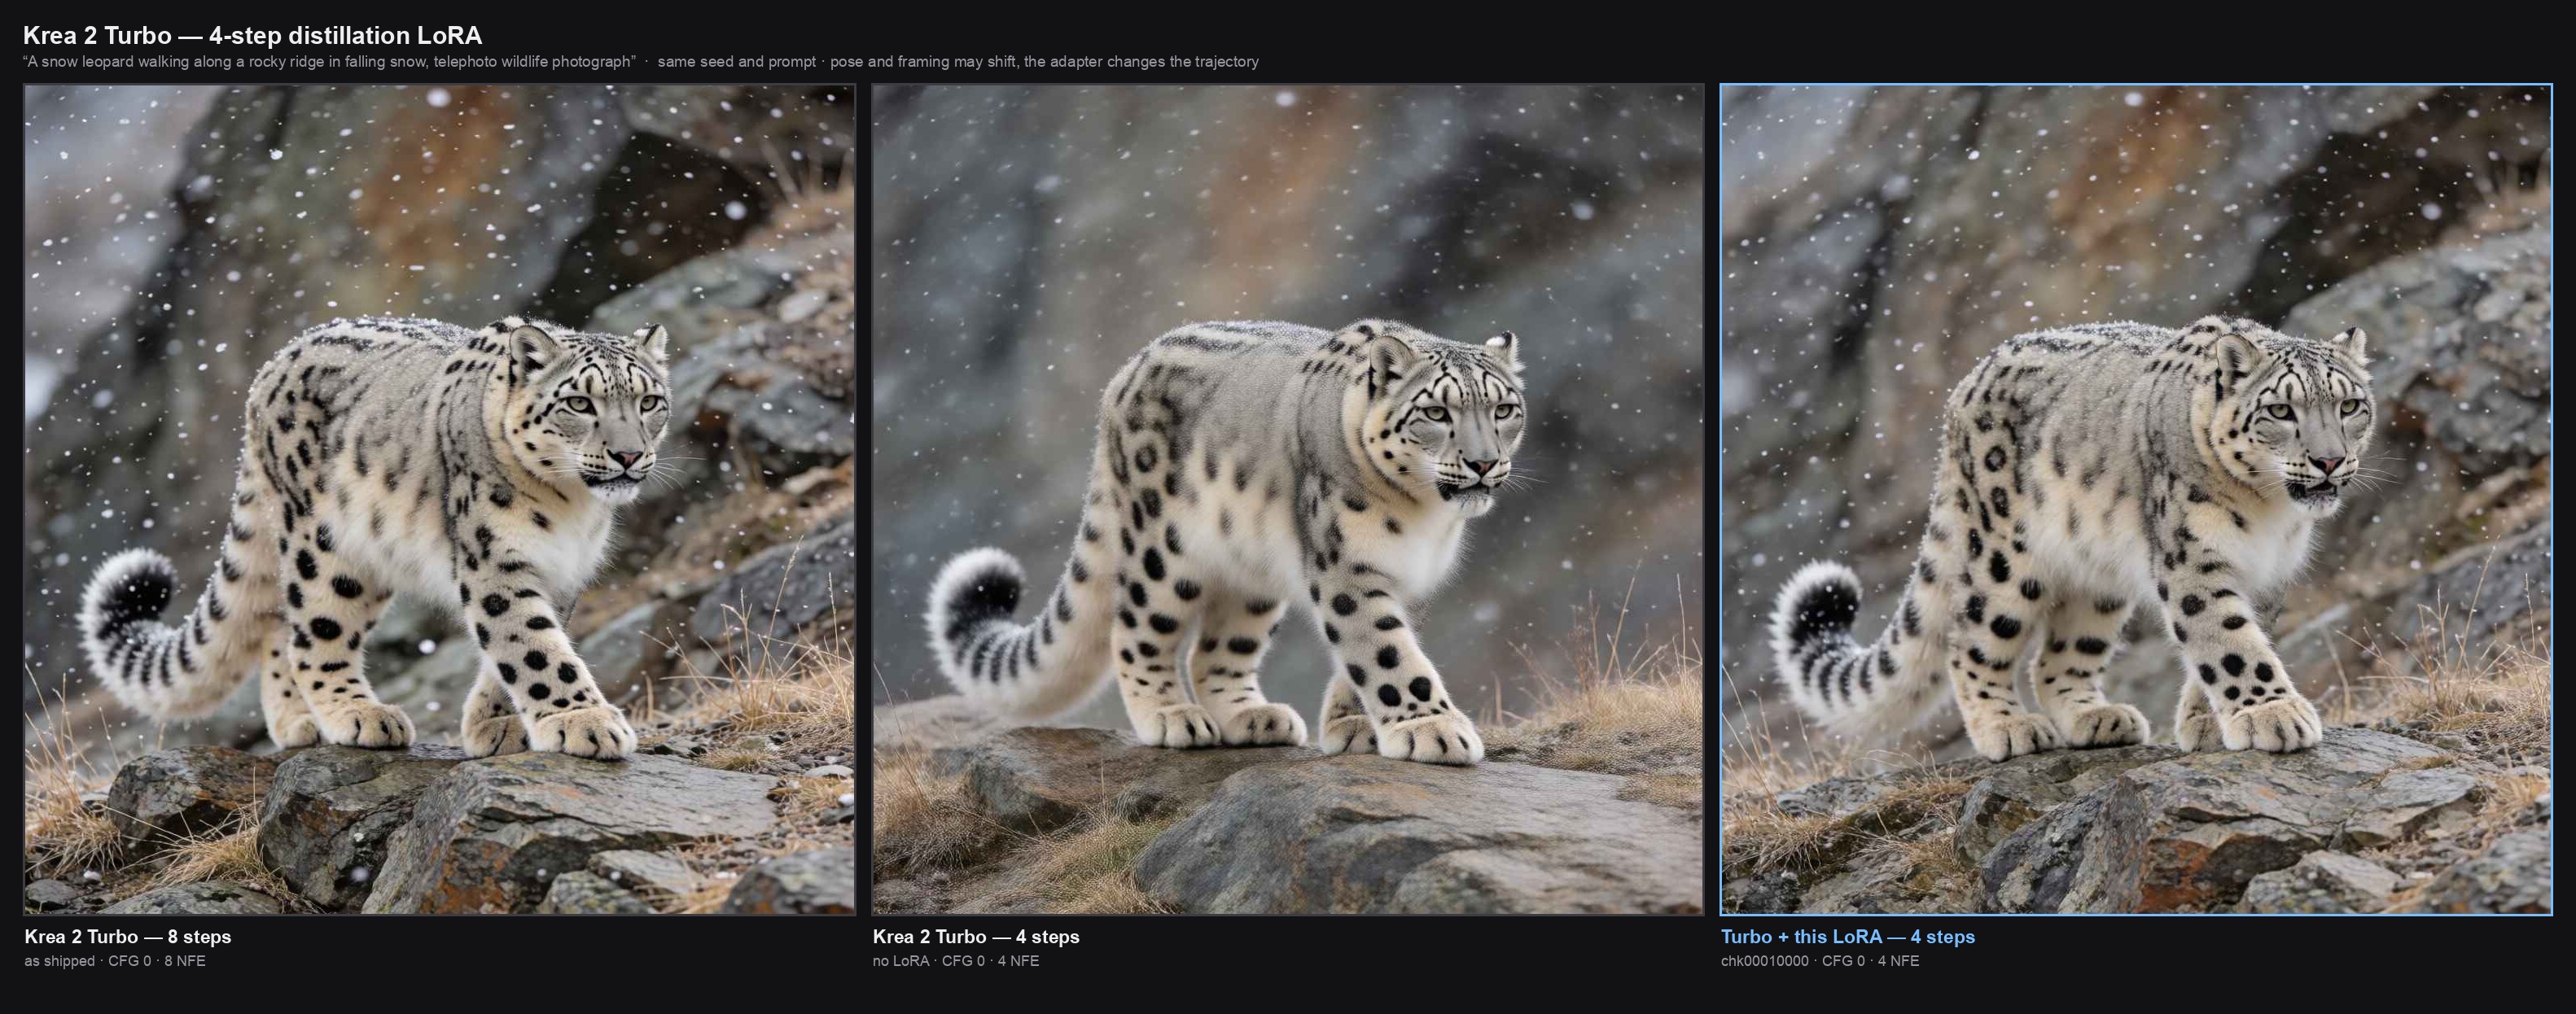
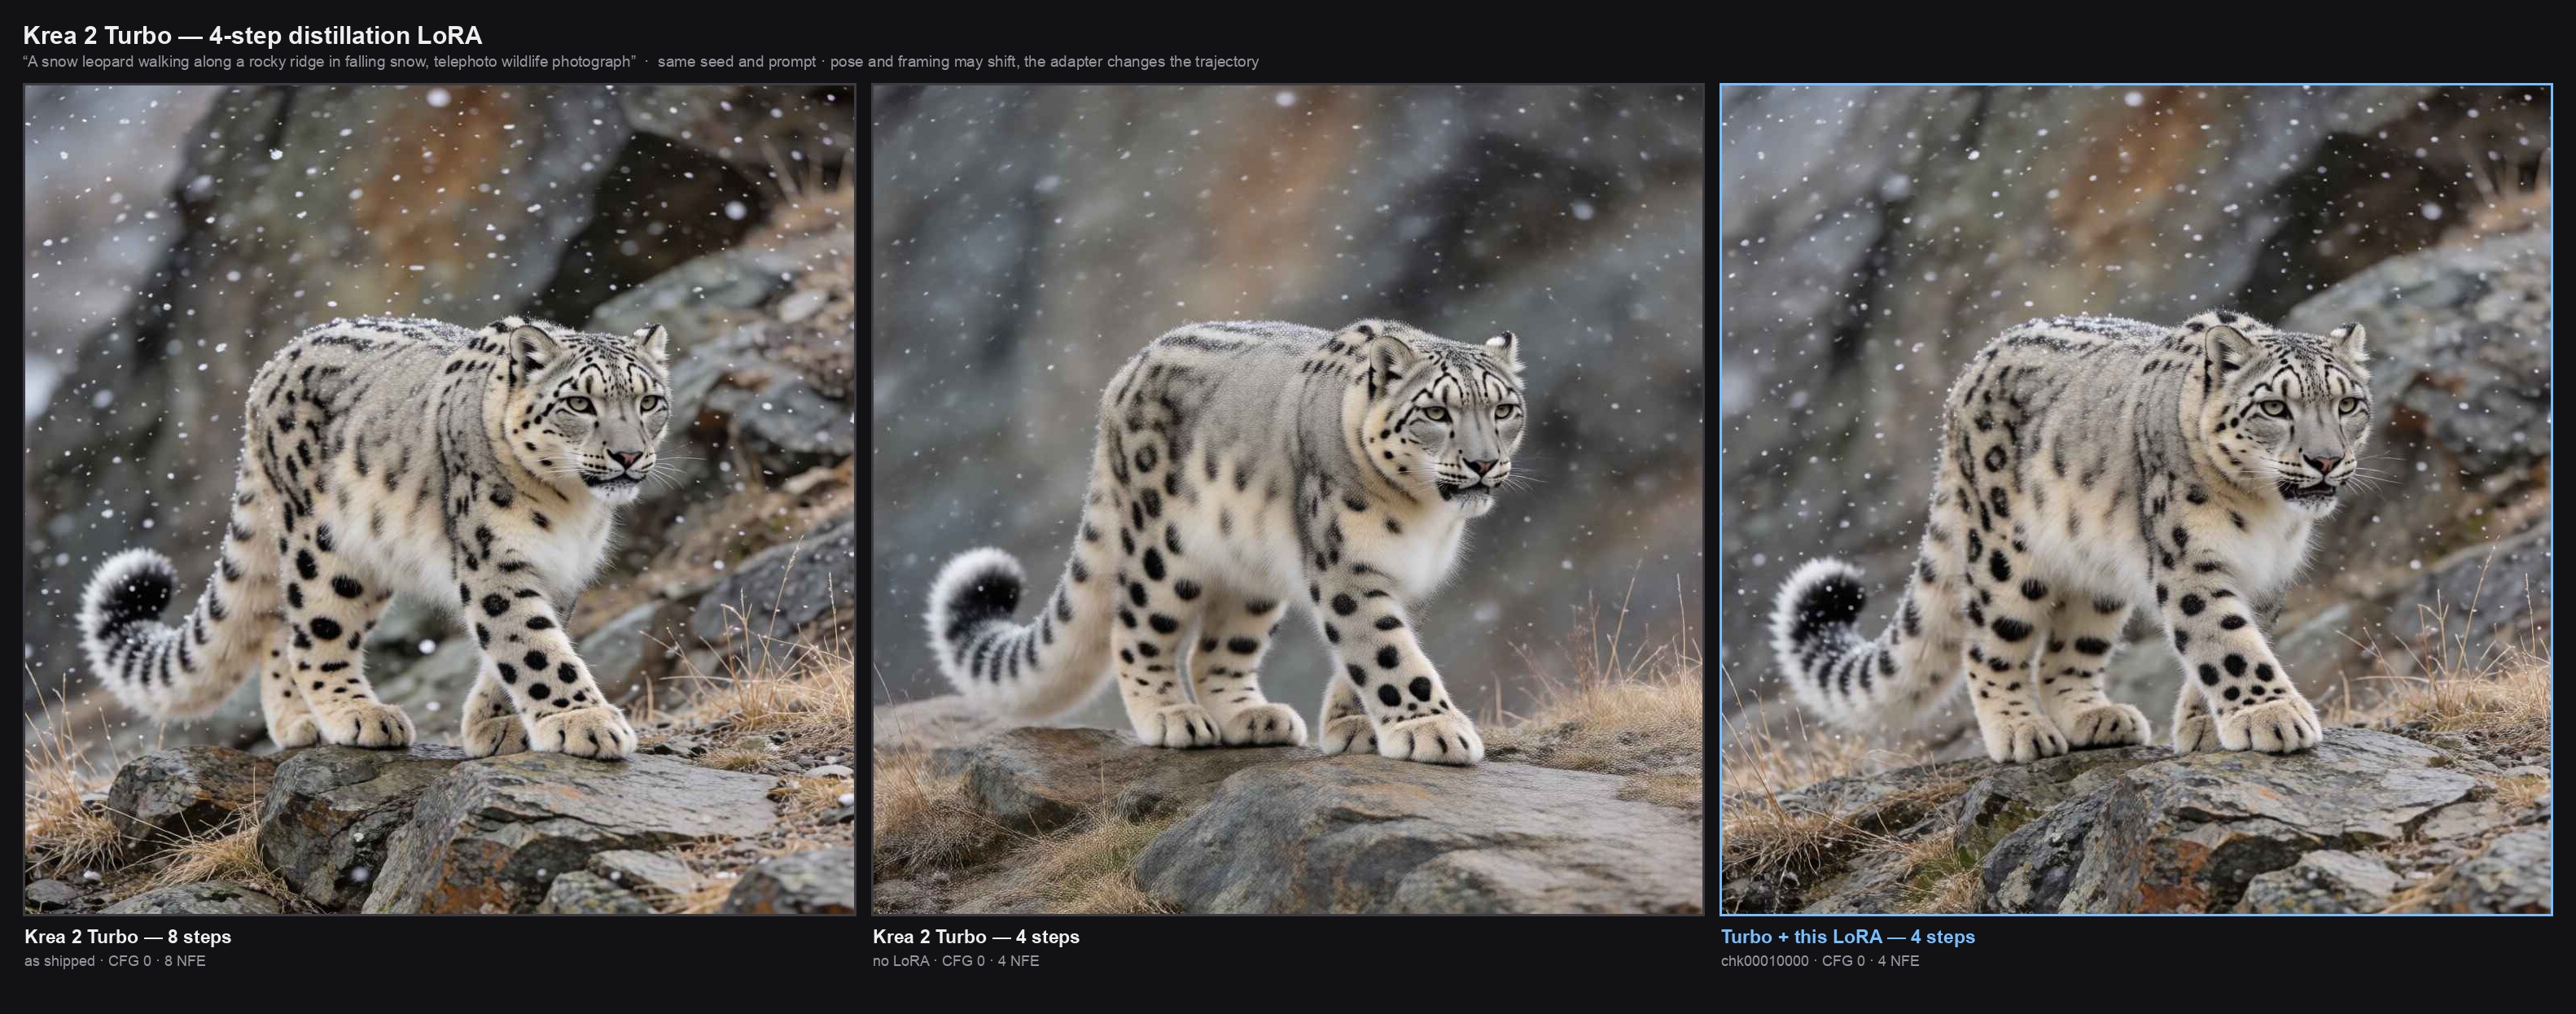
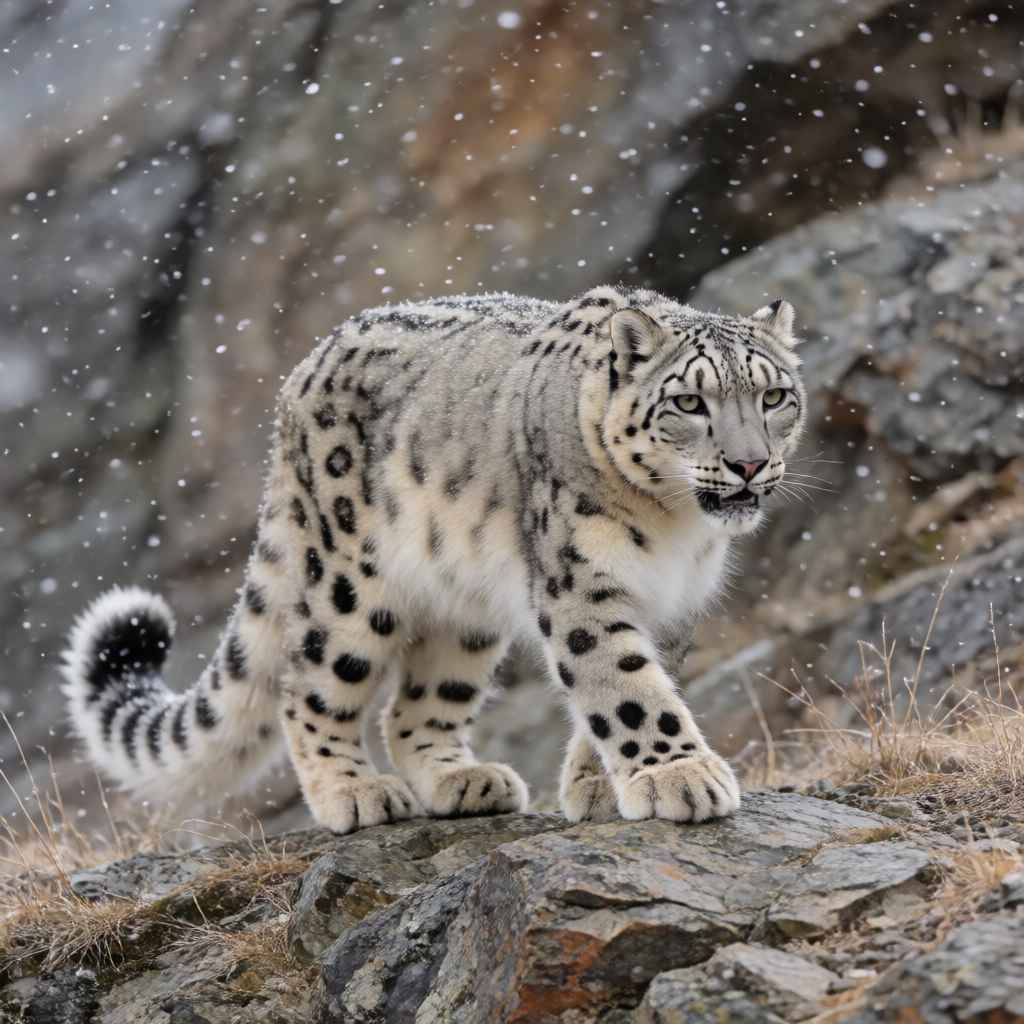
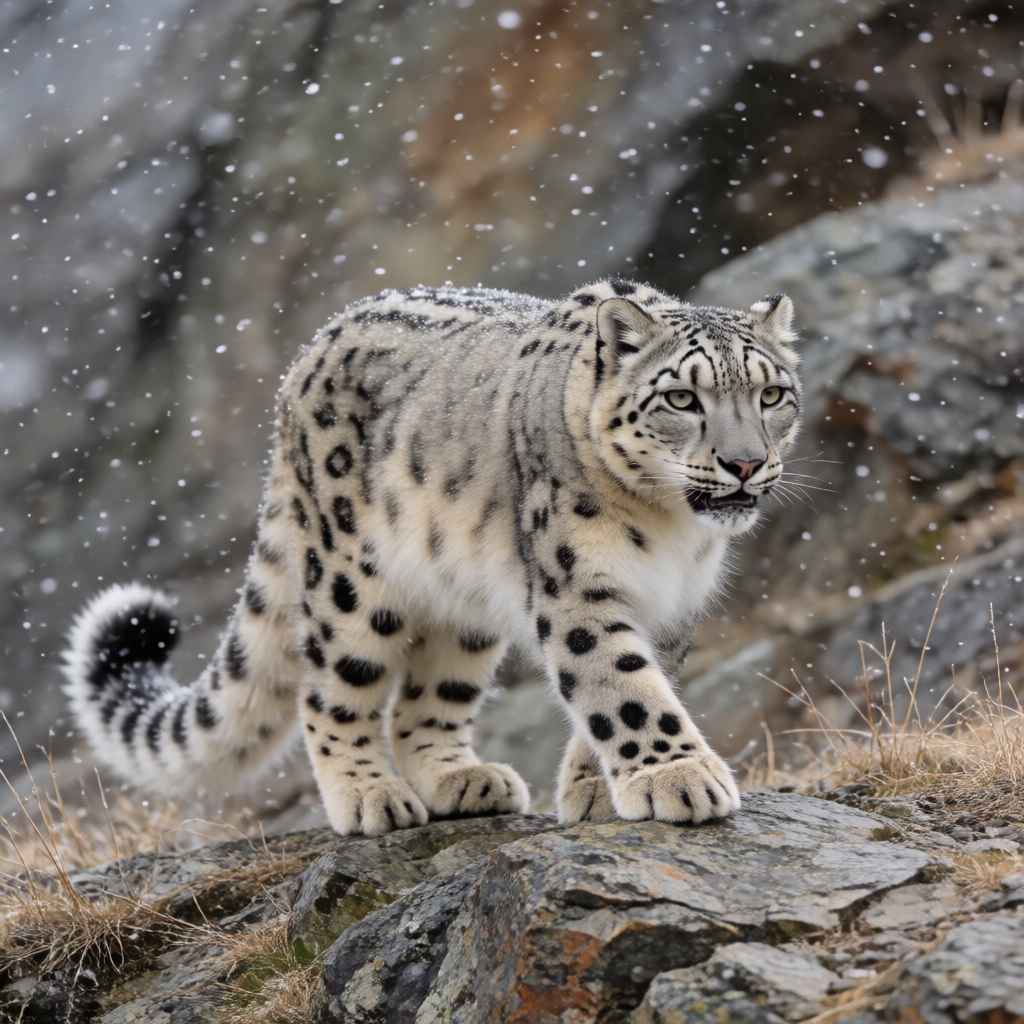
- assets/snowleopard_compare_turbo.jpg +2 -2
- assets/snowleopard_turbo_4step_lora_latest.jpg +0 -0
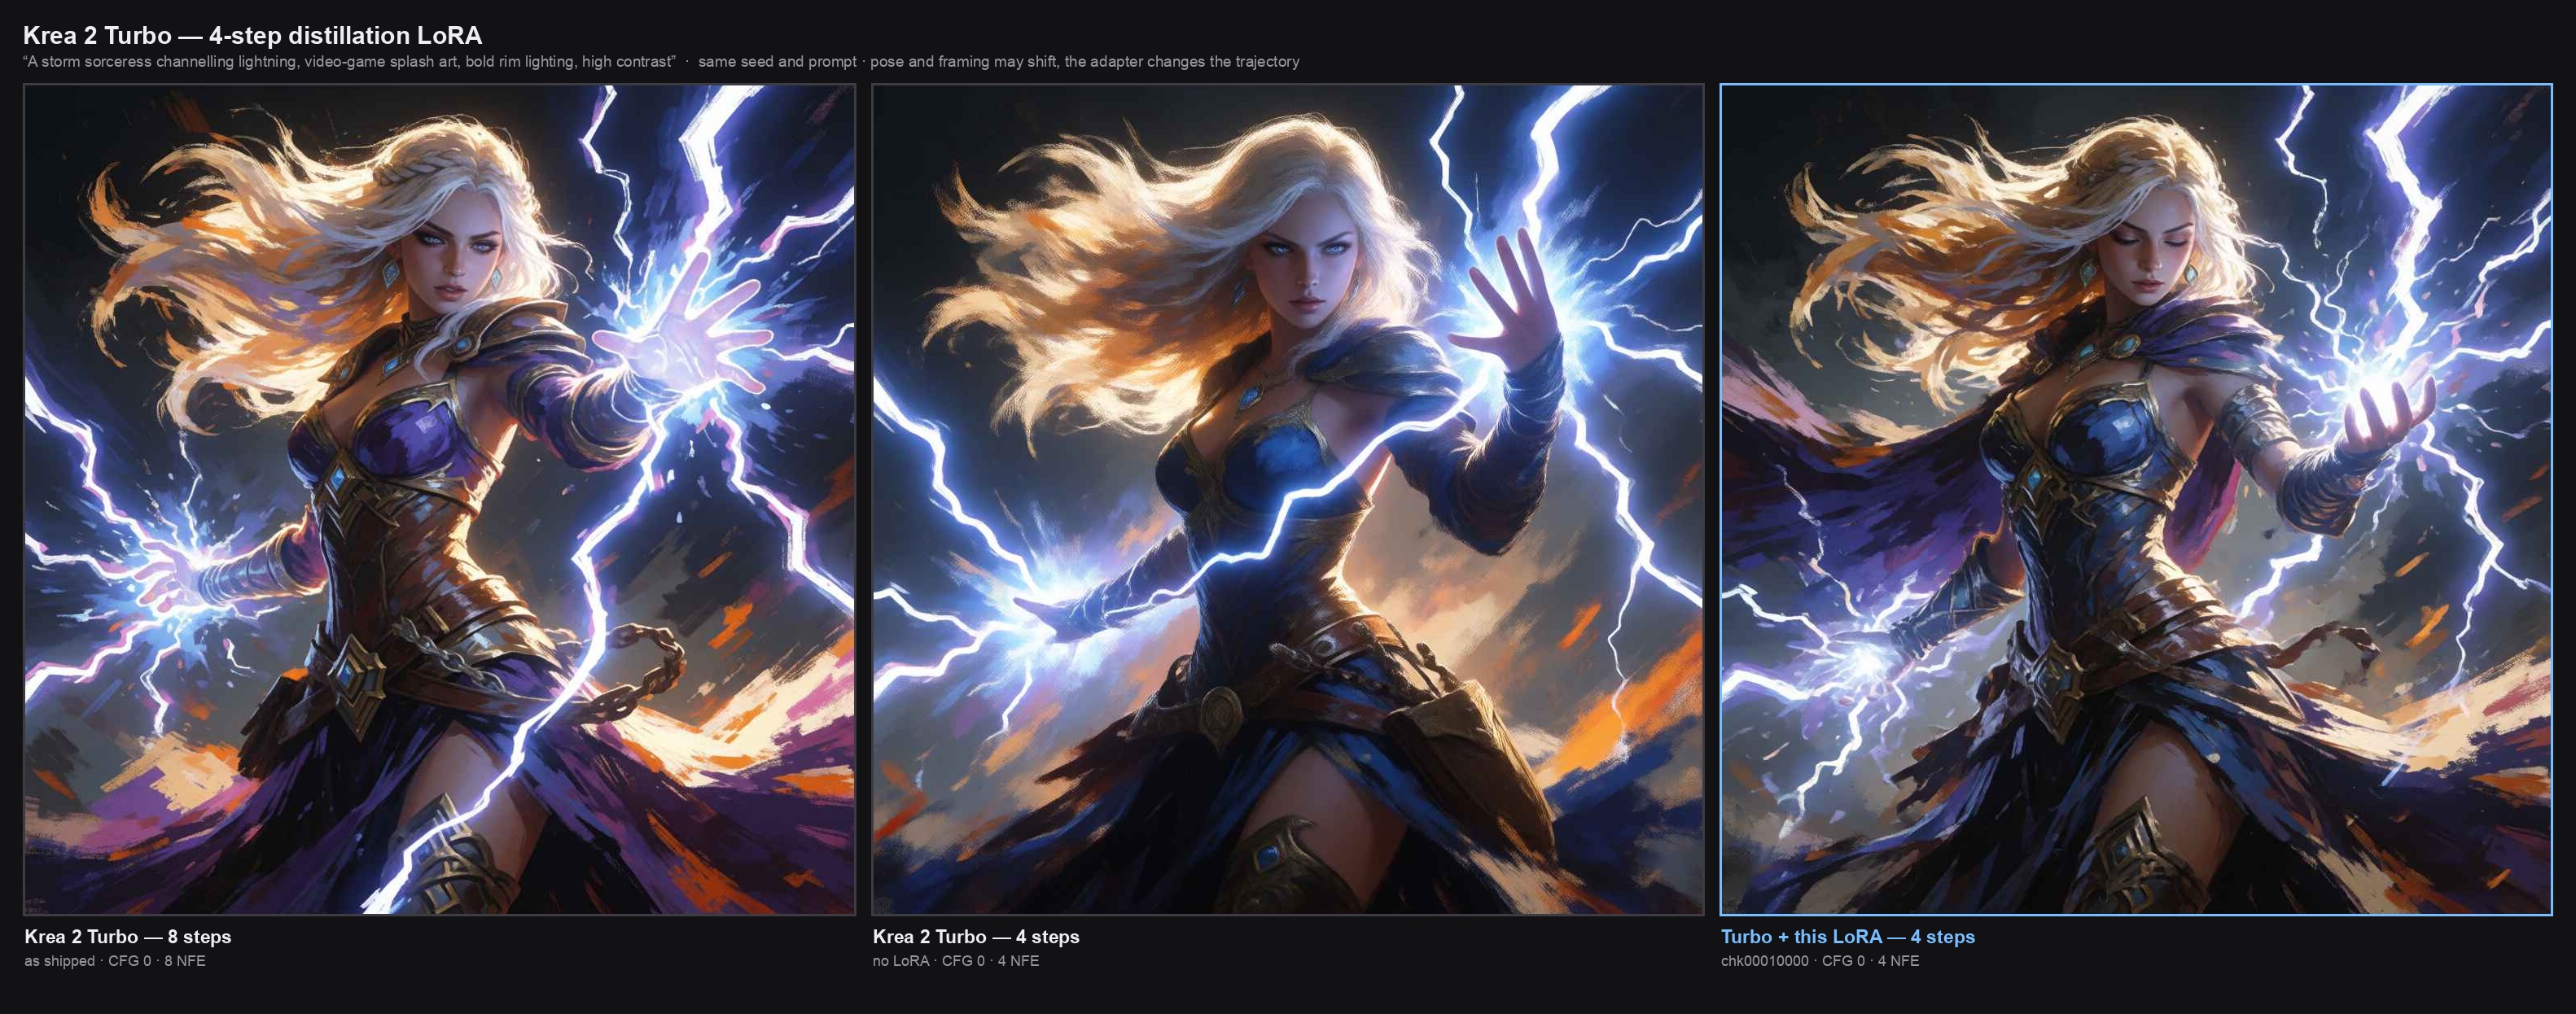
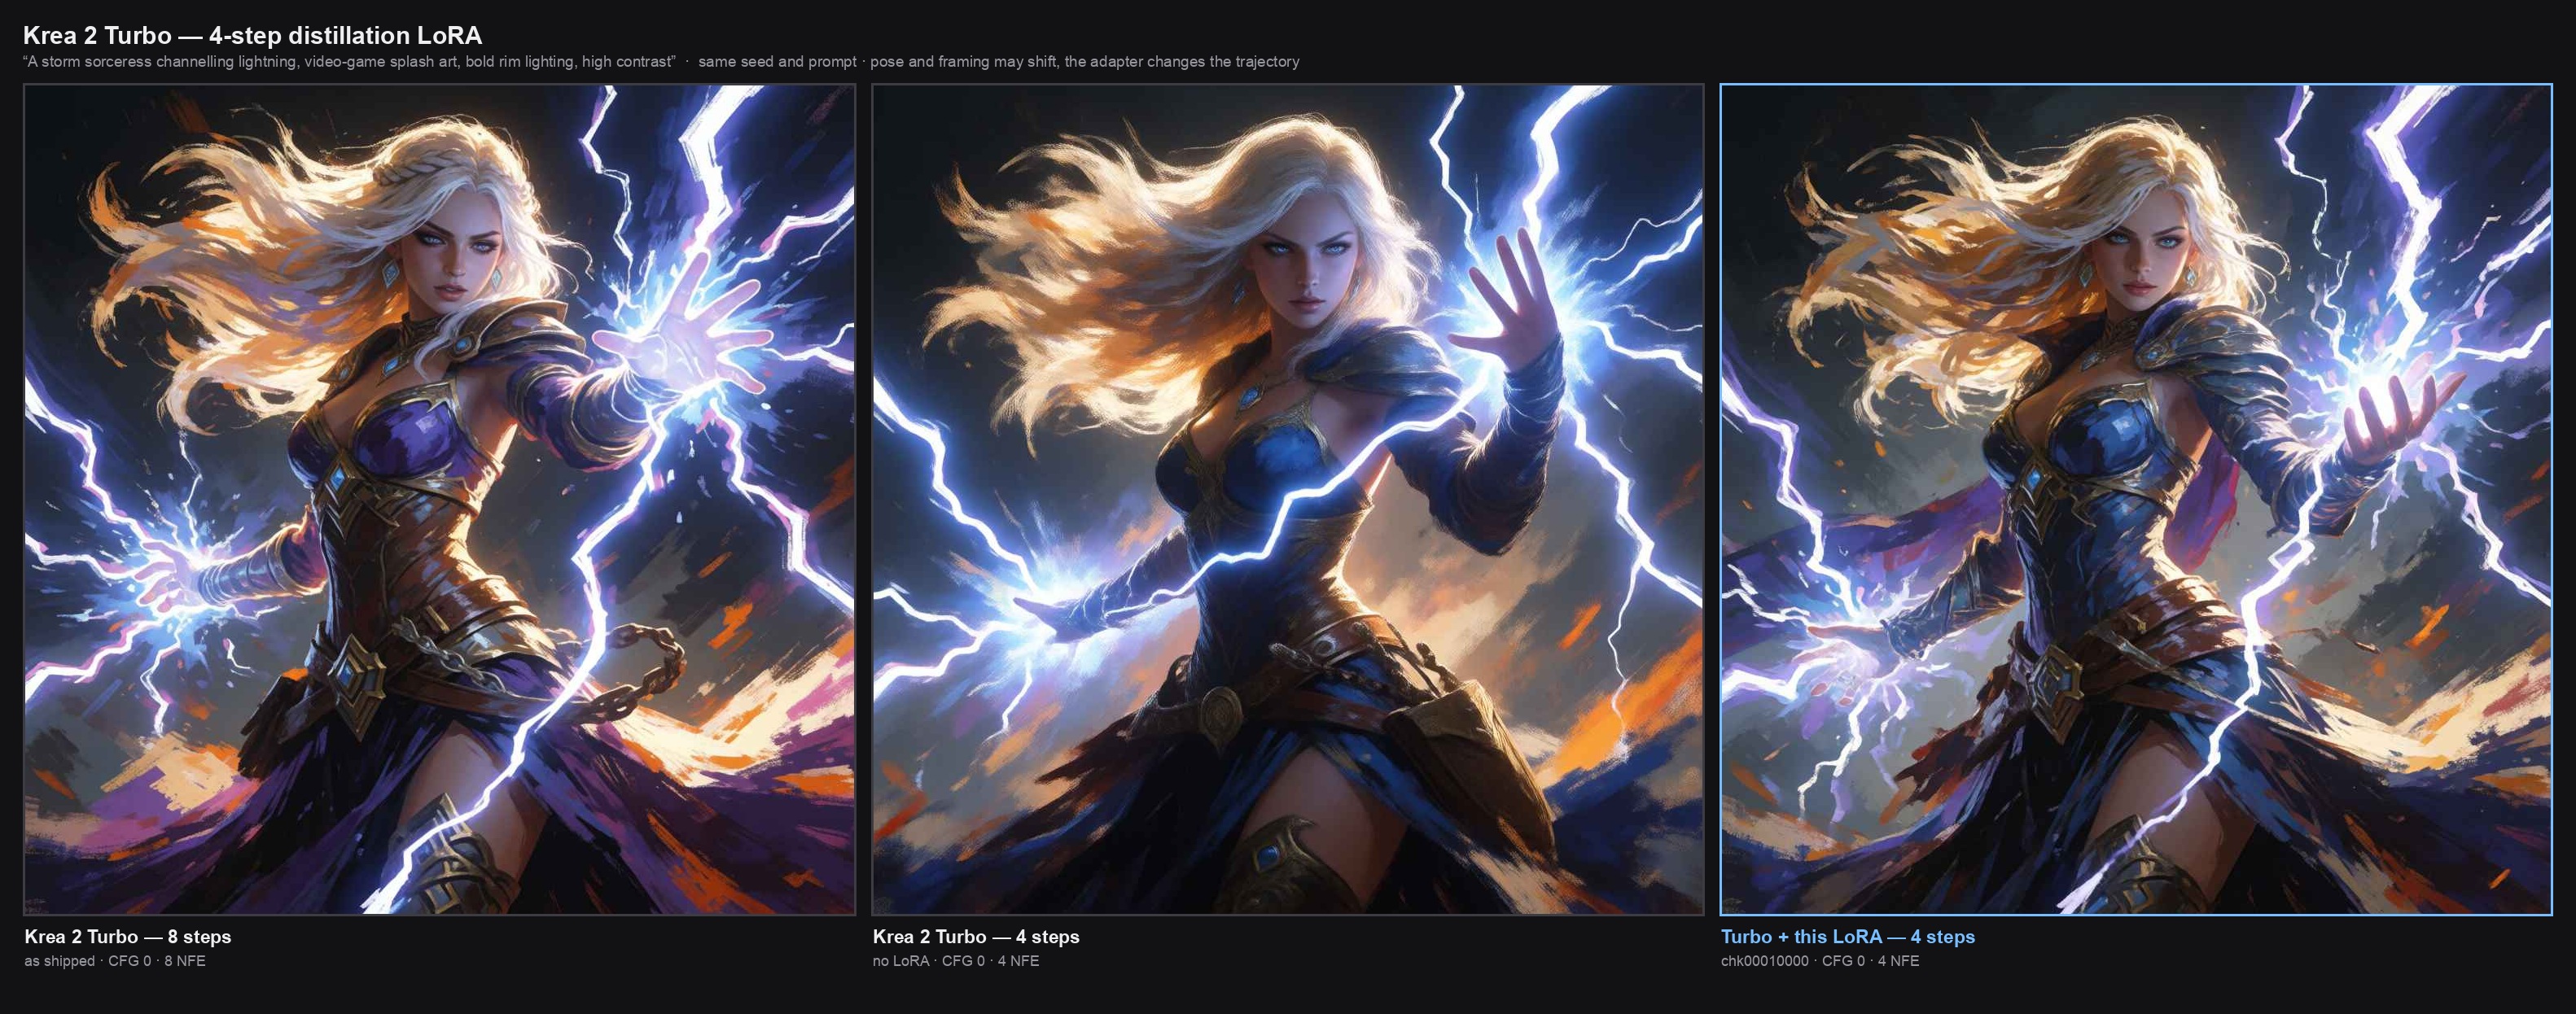
- assets/sorceress_compare_turbo.jpg +2 -2
- assets/sorceress_turbo_4step_lora_latest.jpg +0 -0
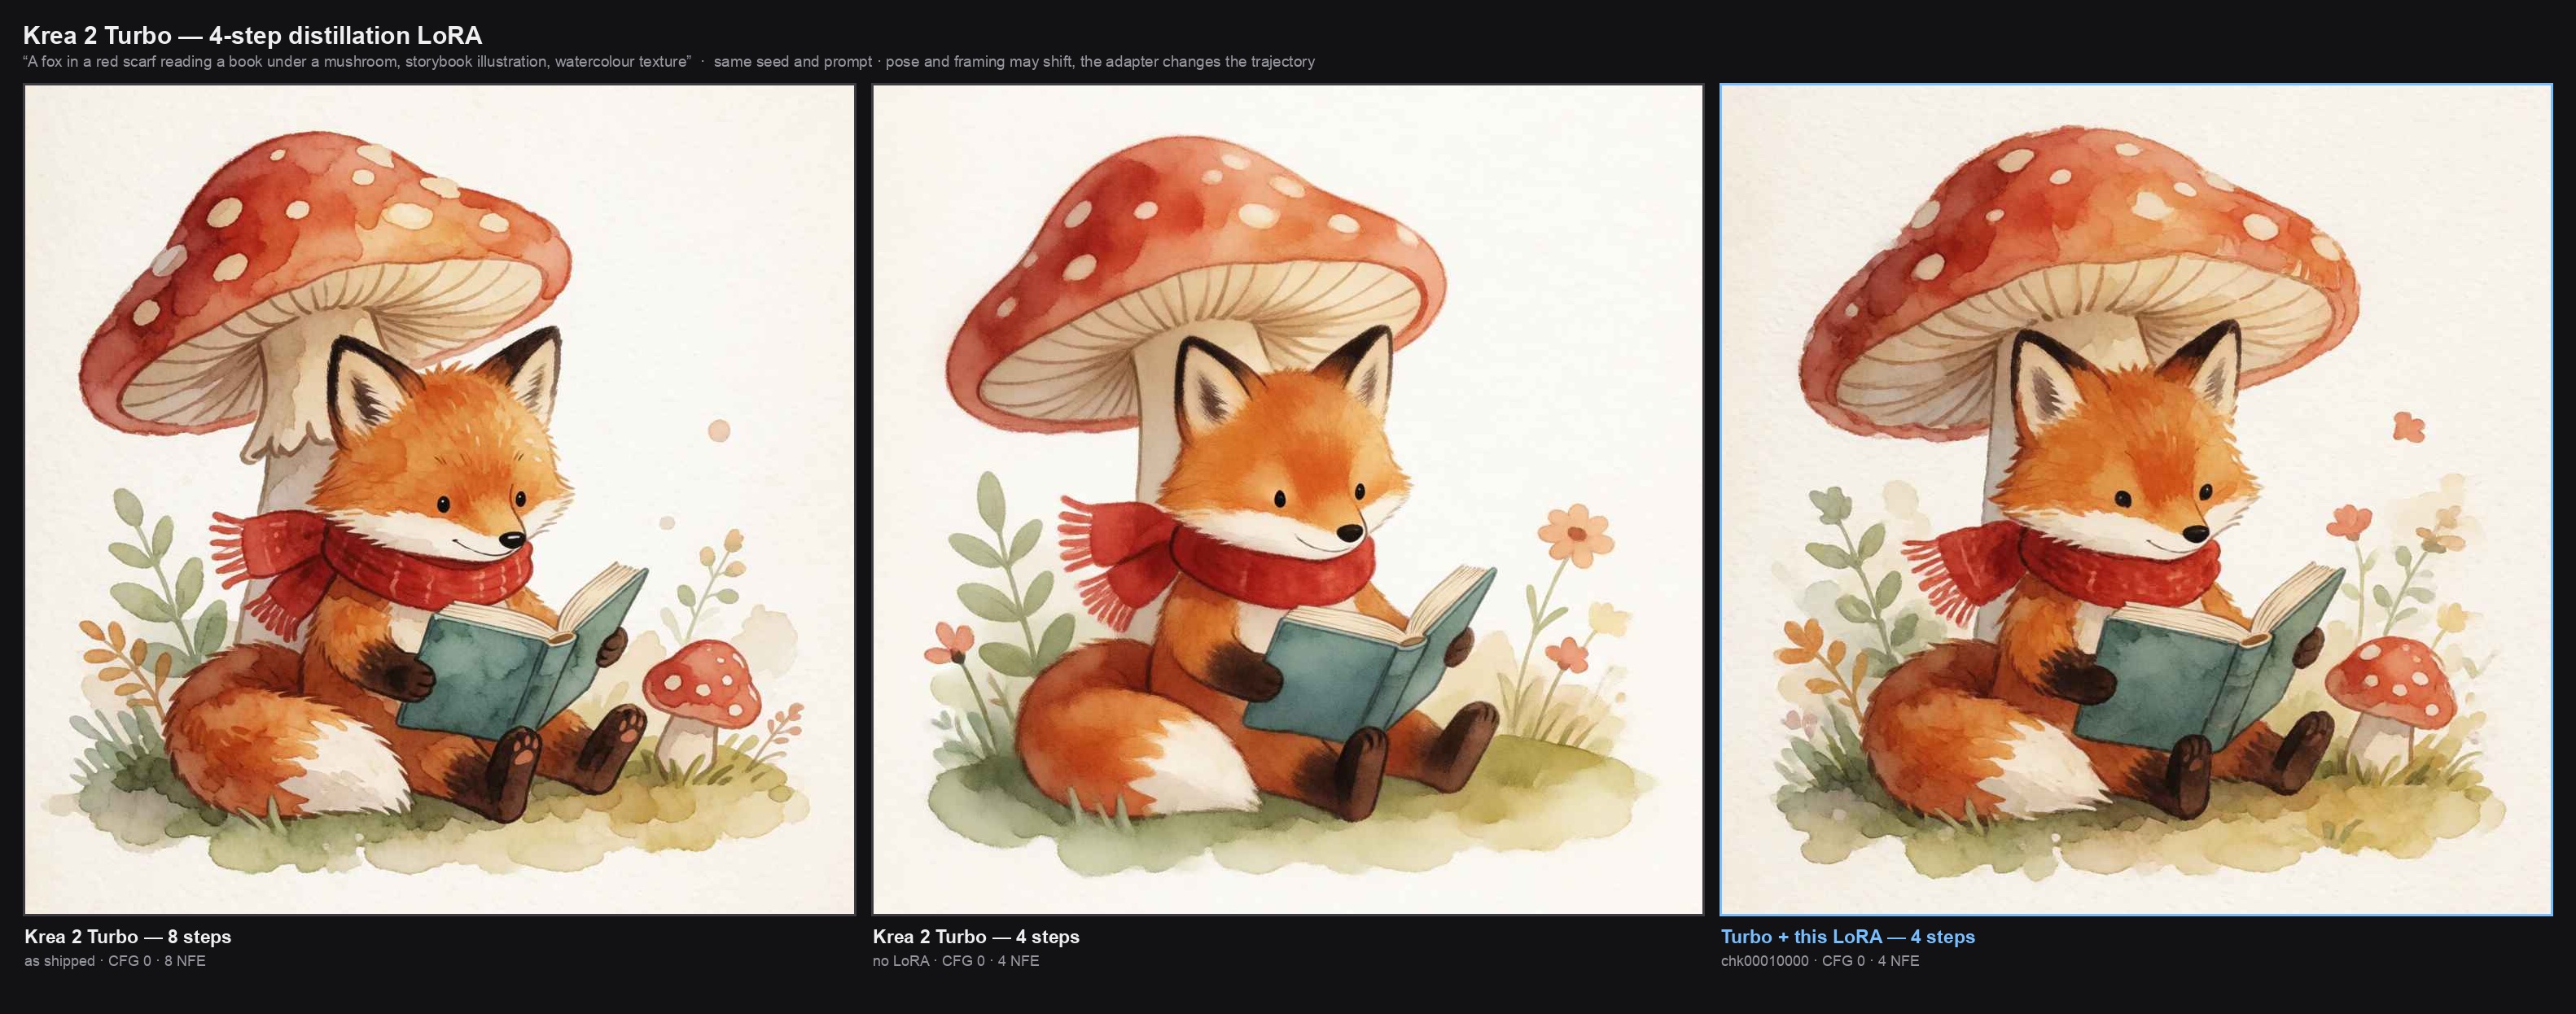
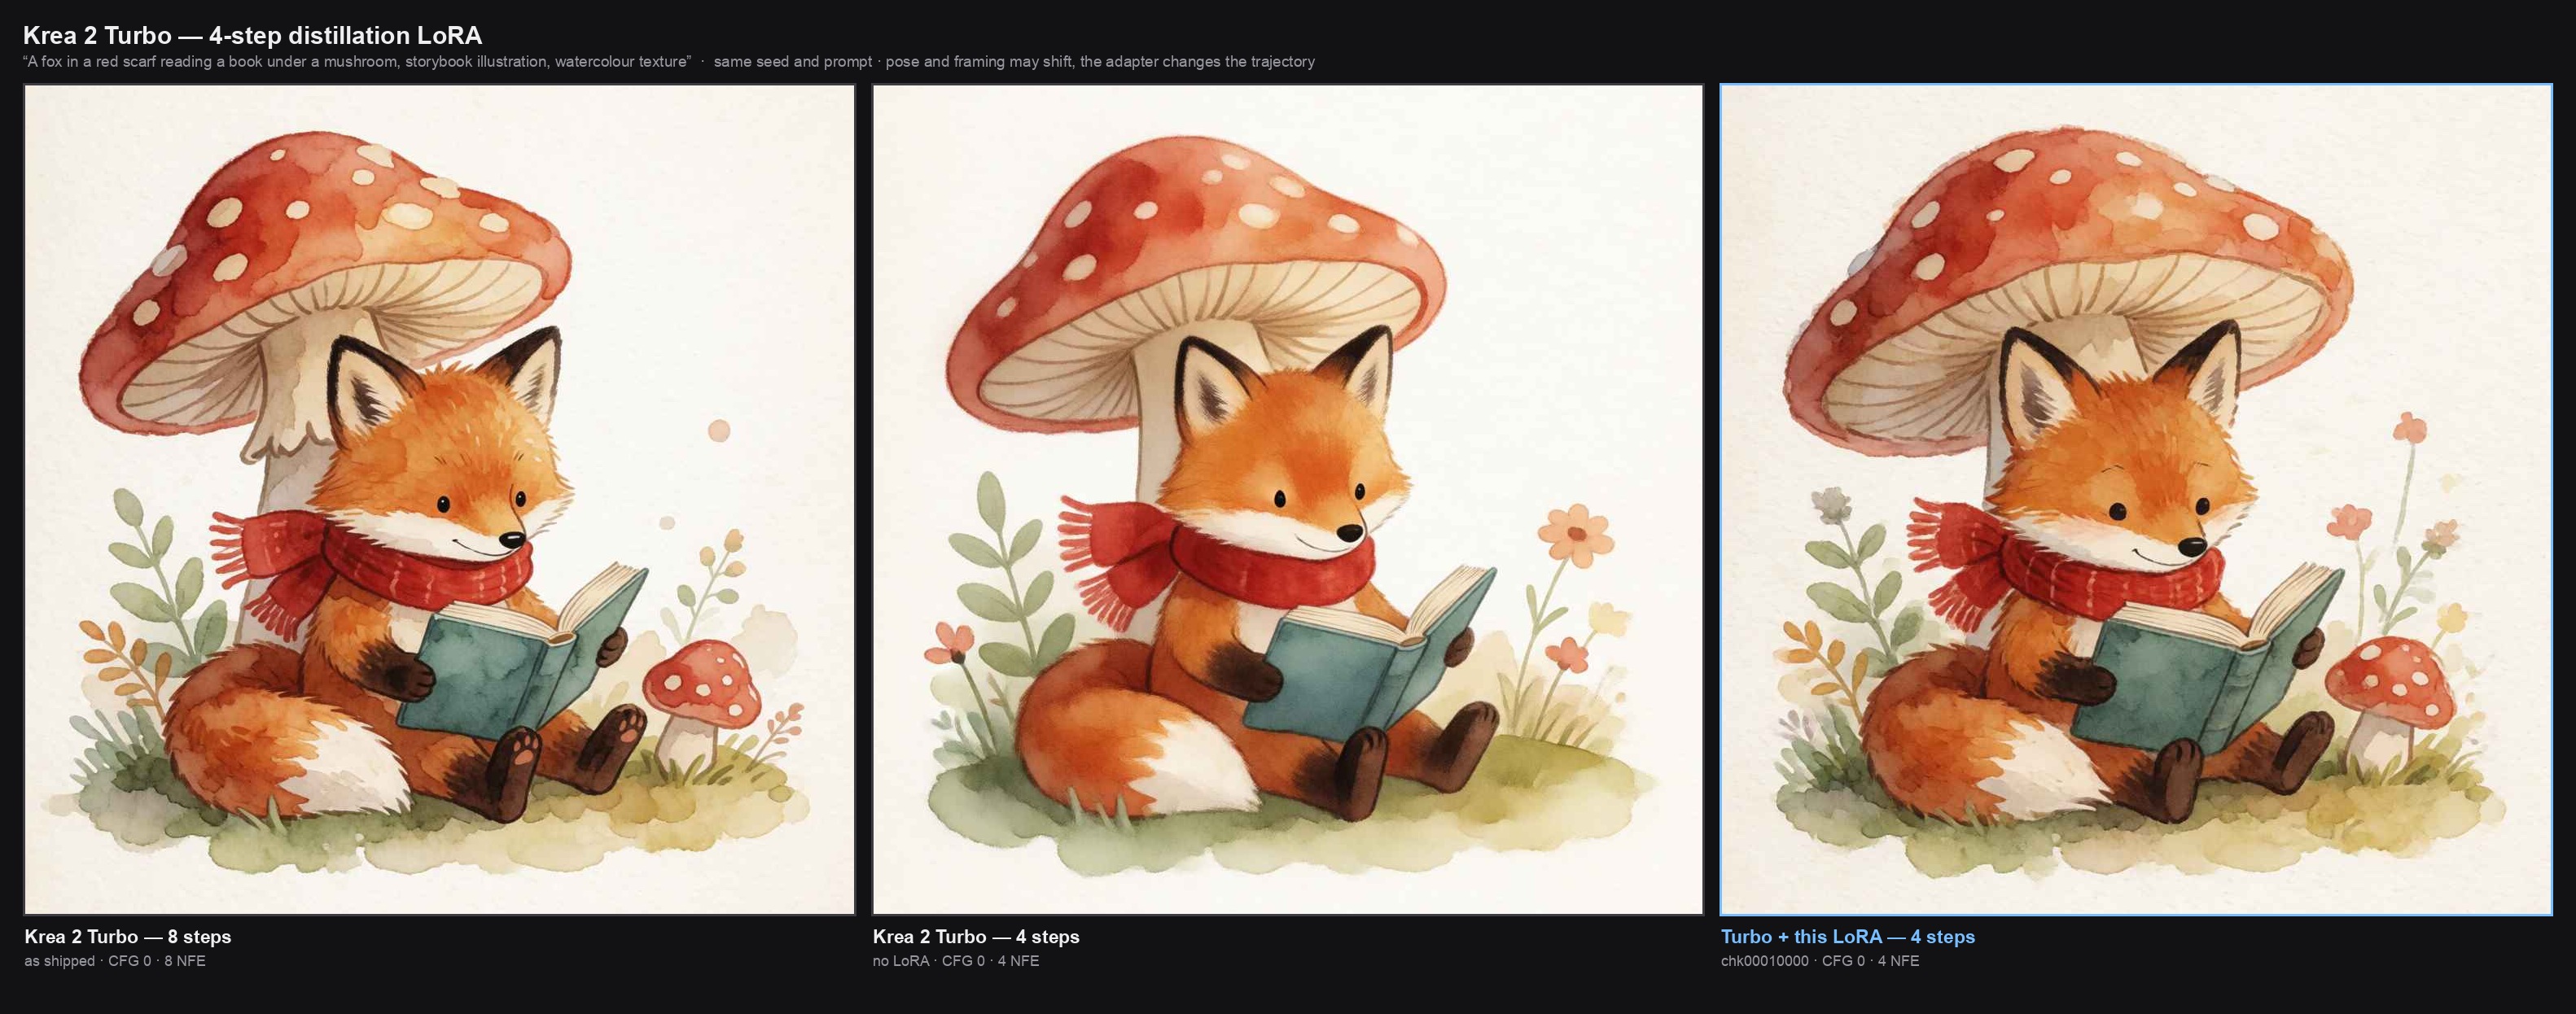
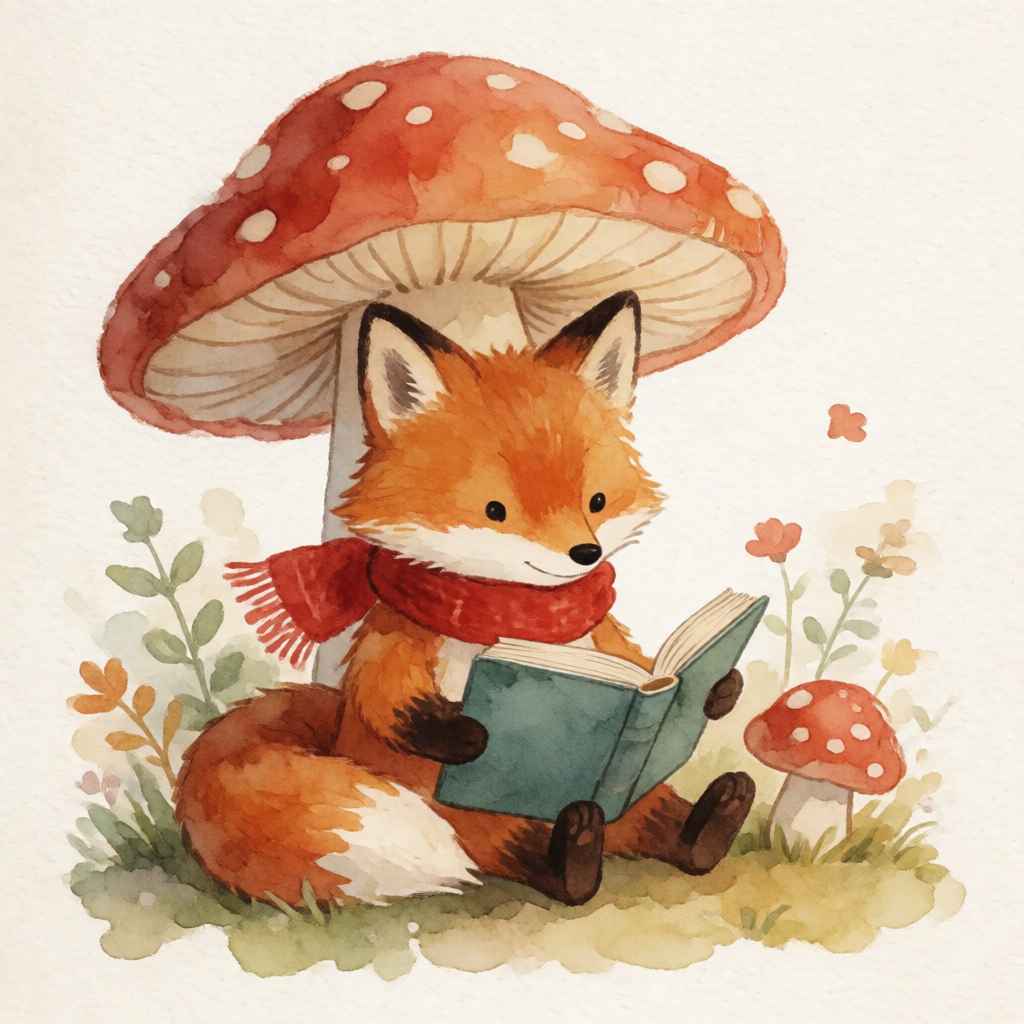
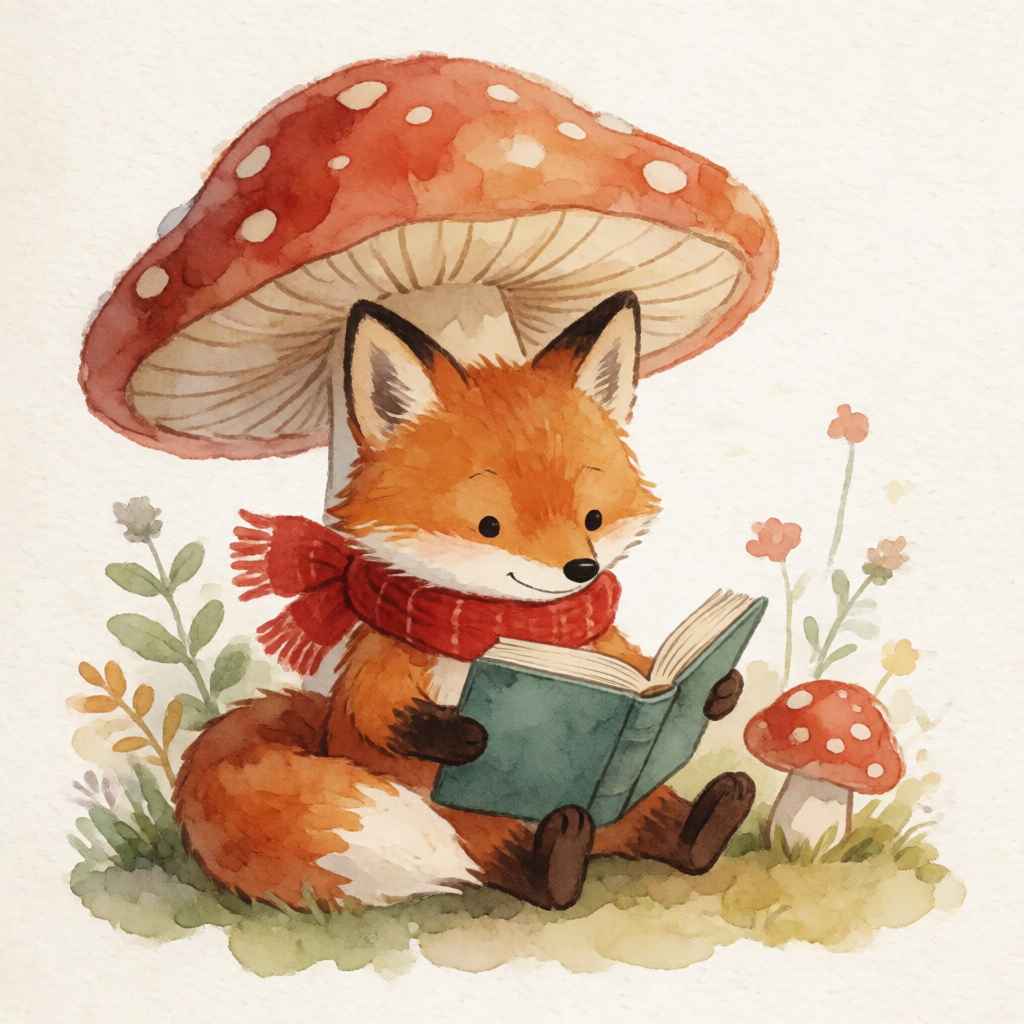
- assets/storybookfox_compare_turbo.jpg +2 -2
- assets/storybookfox_turbo_4step_lora_latest.jpg +0 -0
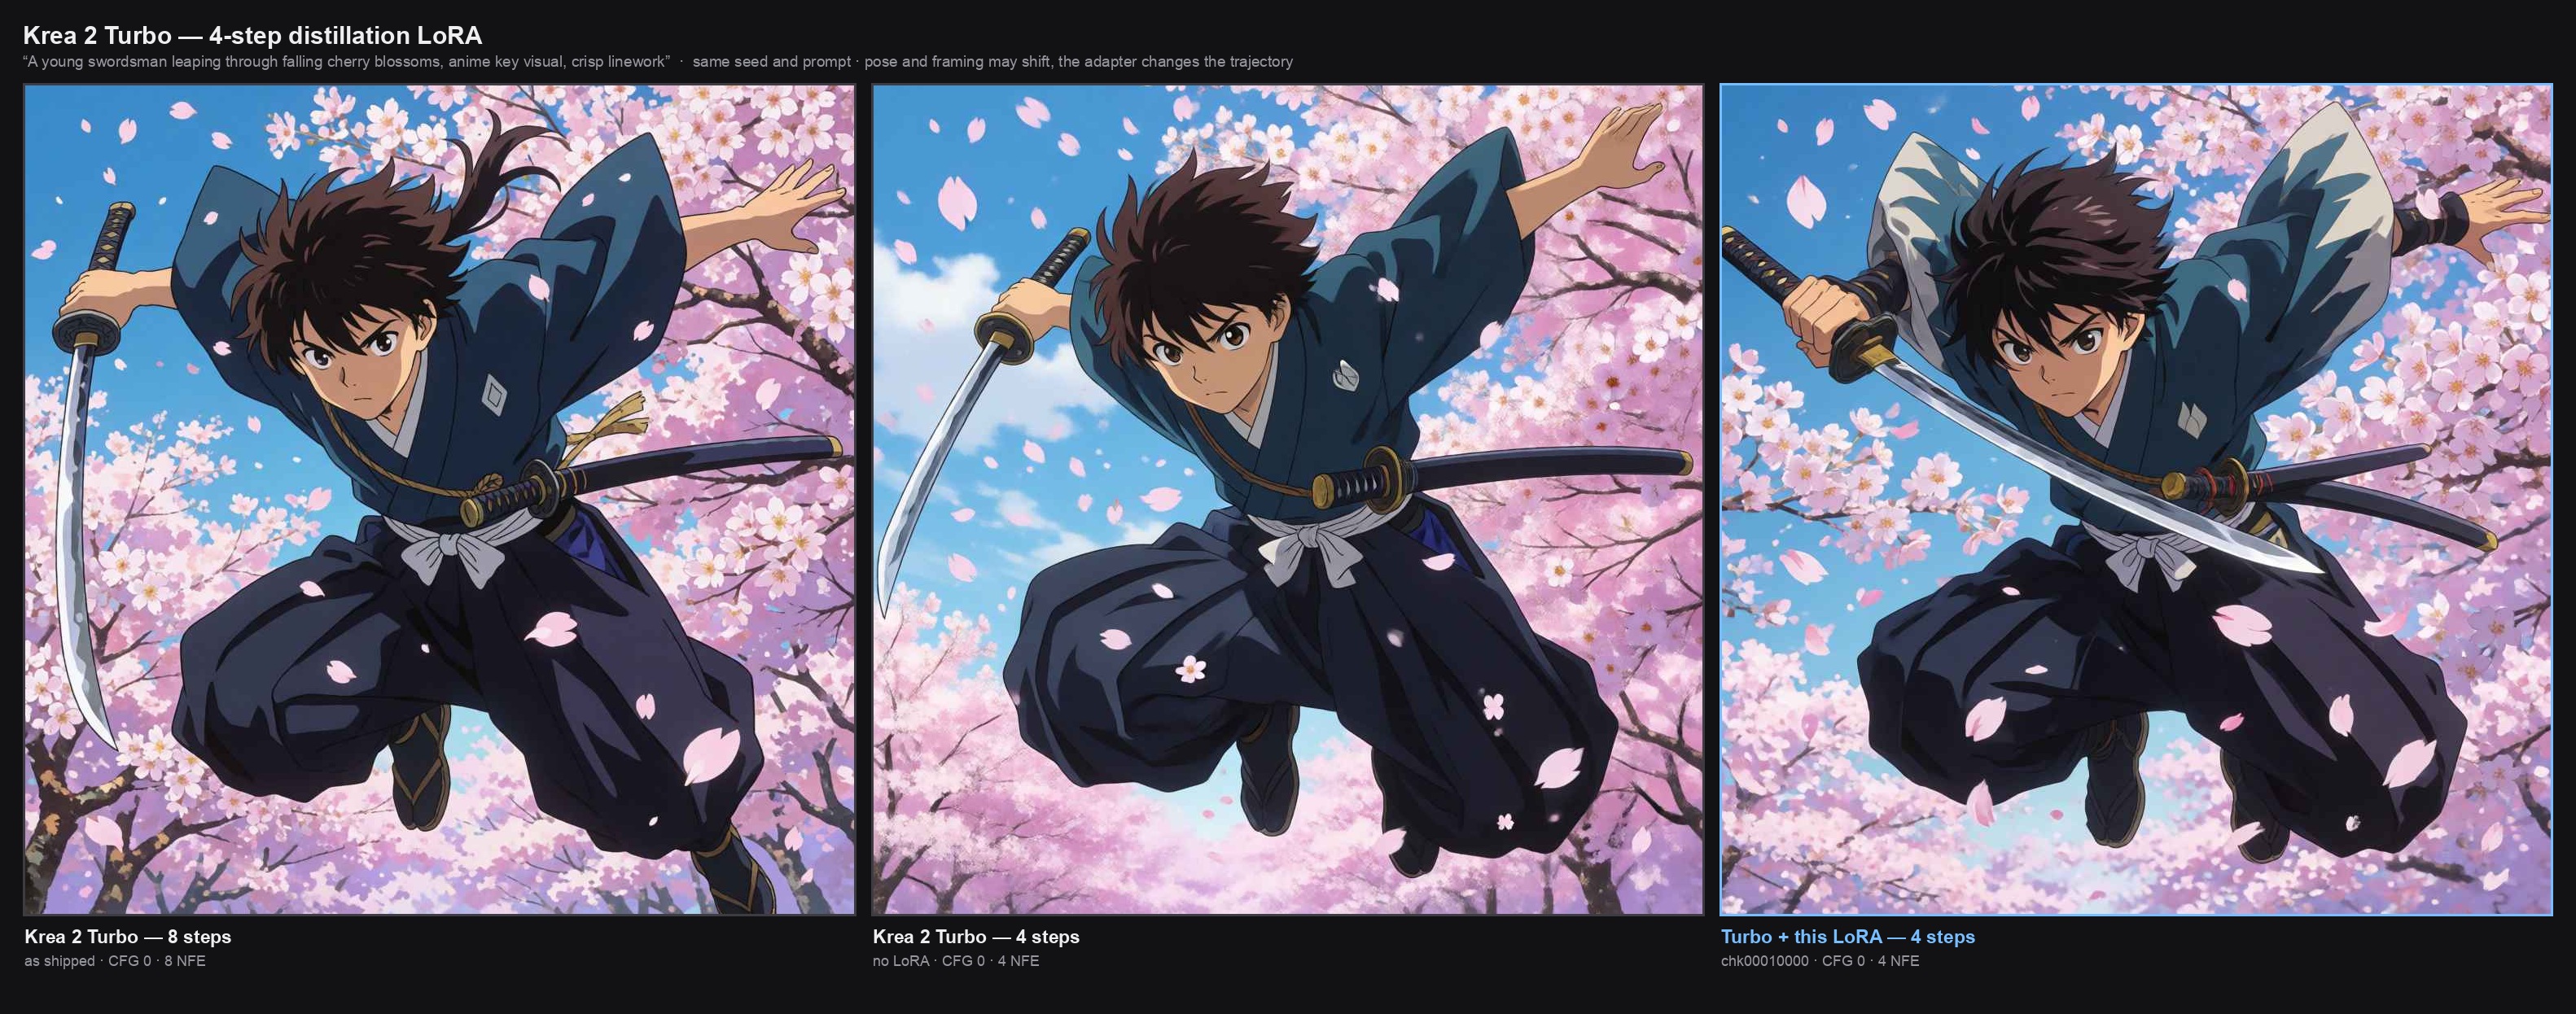
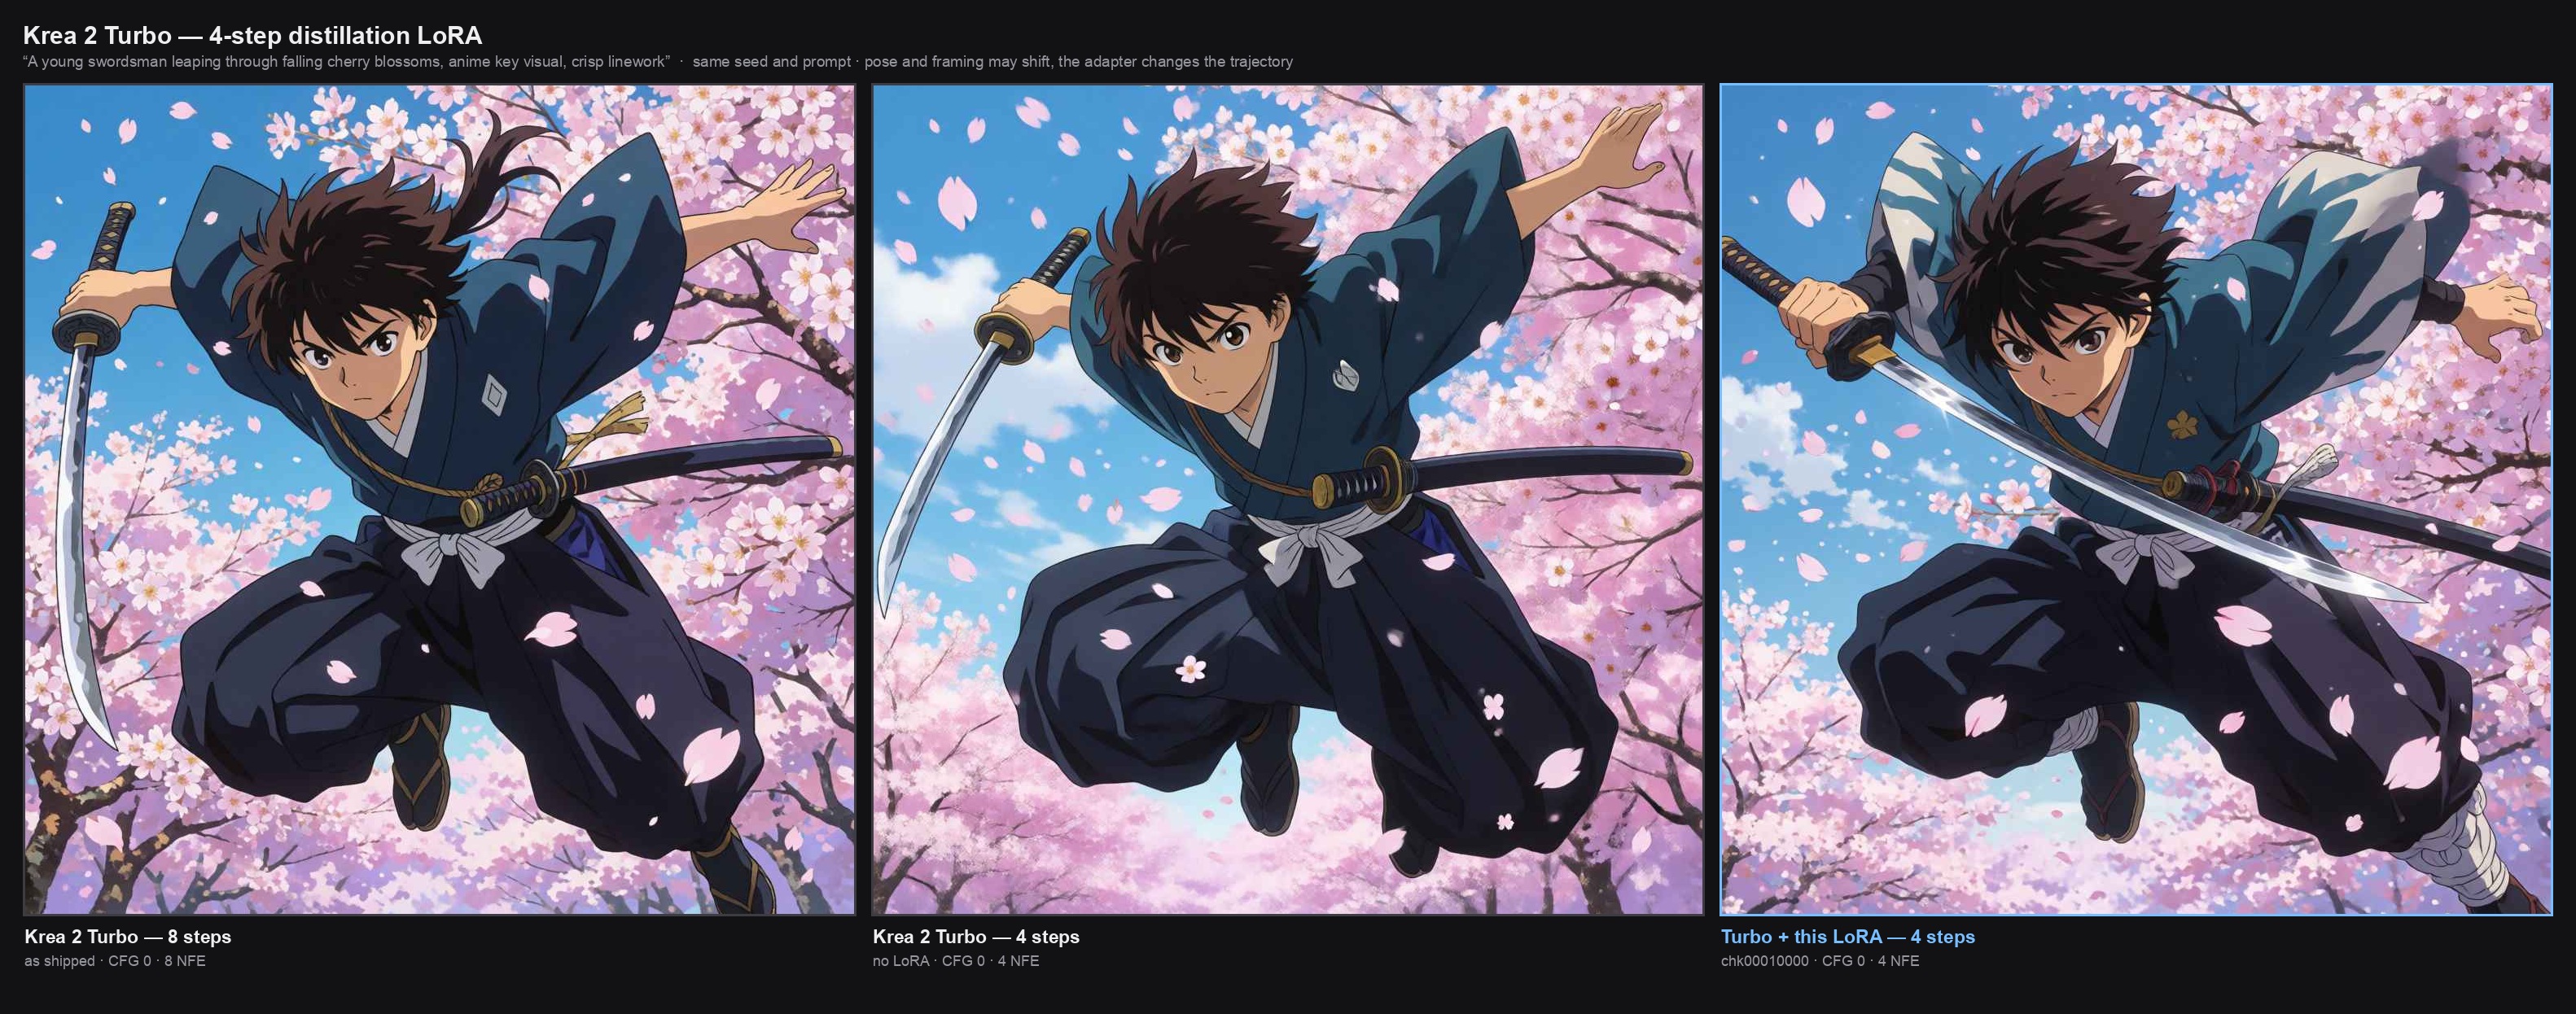
- assets/swordsman_compare_turbo.jpg +2 -2
- assets/swordsman_turbo_4step_lora_latest.jpg +0 -0
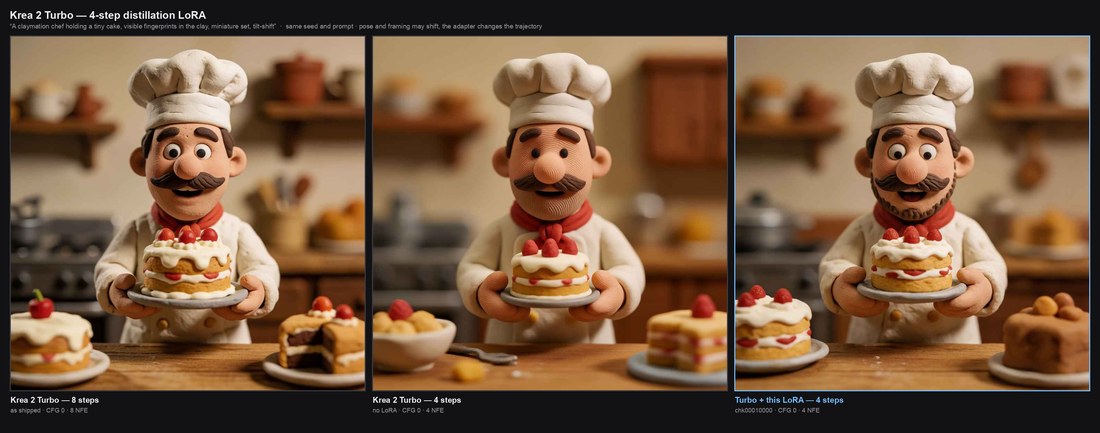
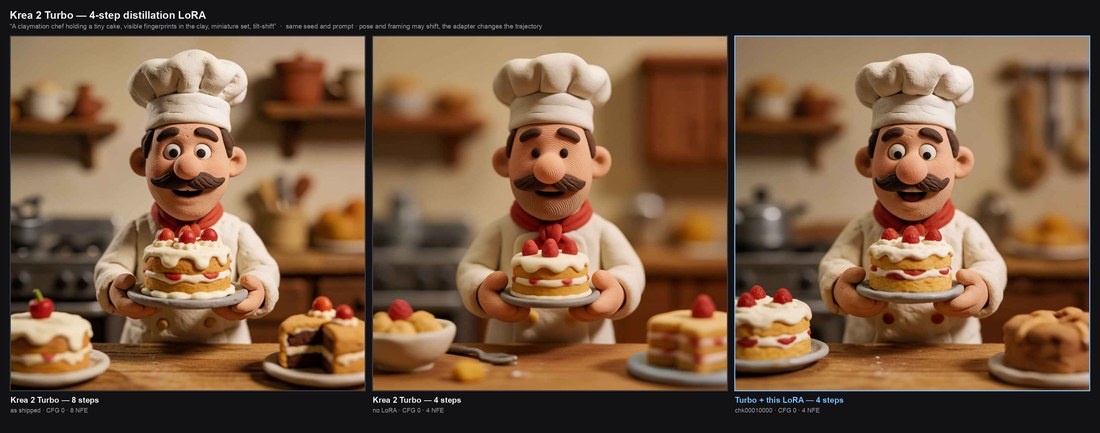
- assets/thumbs/claychef_compare_turbo.jpg +0 -0
- assets/thumbs/claychef_turbo_4step_lora_latest.jpg +0 -0
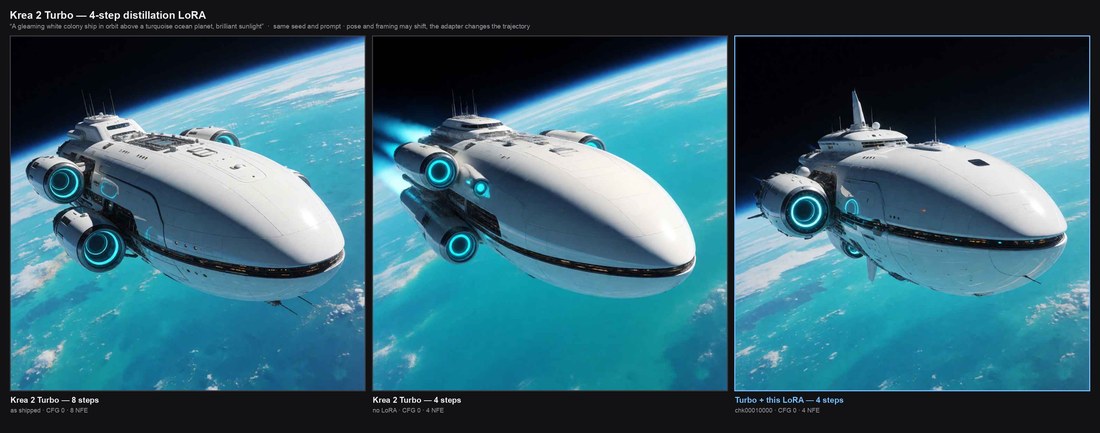
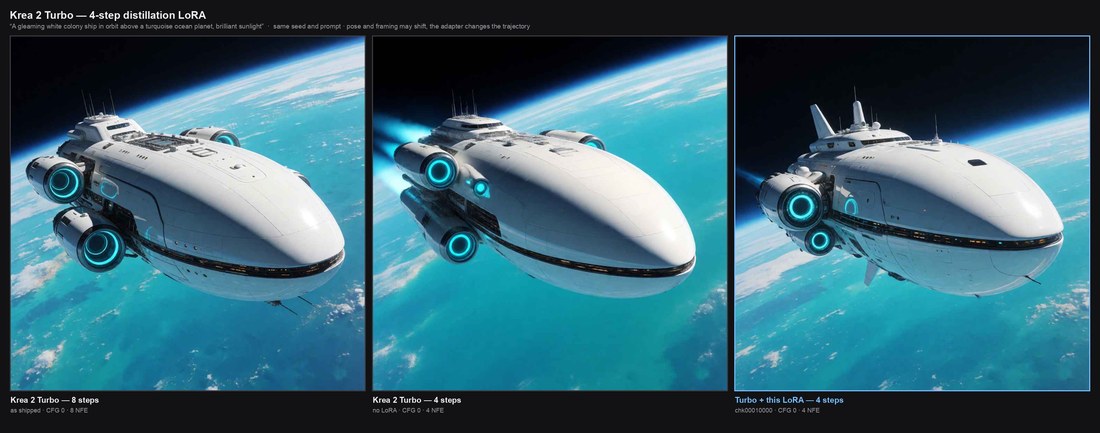
- assets/thumbs/colonyship_compare_turbo.jpg +0 -0
- assets/thumbs/colonyship_turbo_4step_lora_latest.jpg +0 -0
- assets/thumbs/inventor_compare_turbo.jpg +2 -2
- assets/thumbs/inventor_turbo_4step_lora_latest.jpg +0 -0
- assets/thumbs/kingfisher_compare_turbo.jpg +2 -2
- assets/thumbs/kingfisher_turbo_4step_lora_latest.jpg +0 -0
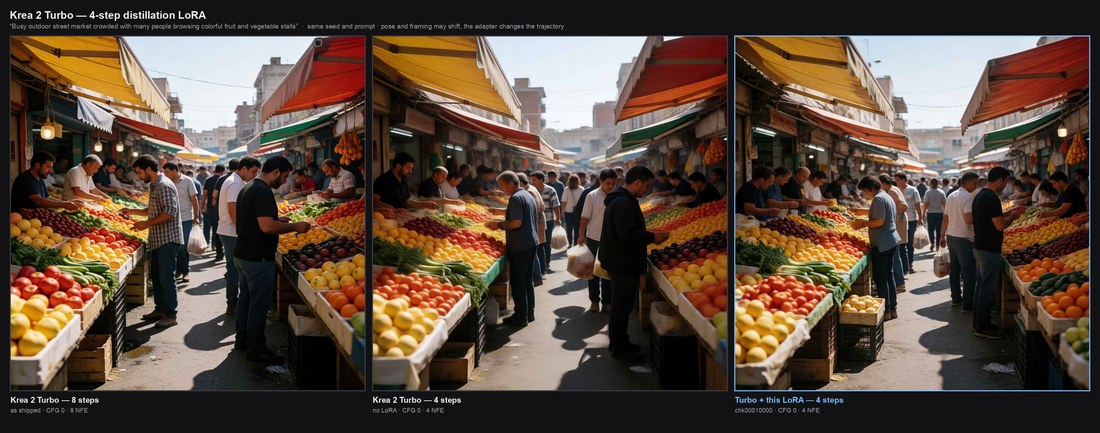
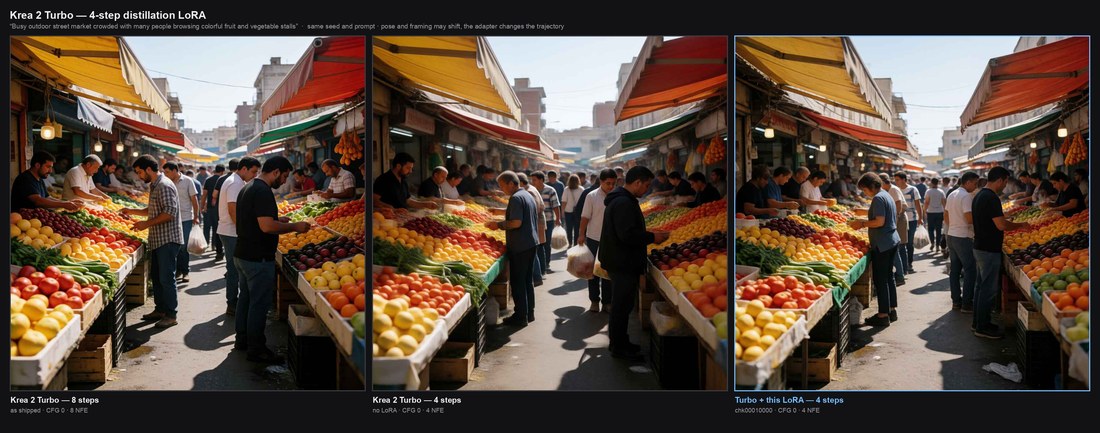
- assets/thumbs/market_compare_turbo.jpg +2 -2
- assets/thumbs/market_turbo_4step_lora_latest.jpg +0 -0
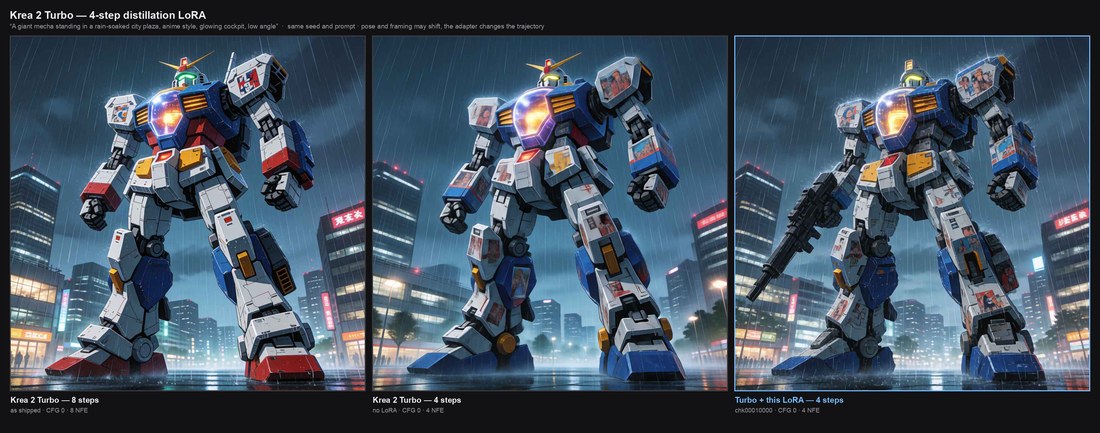
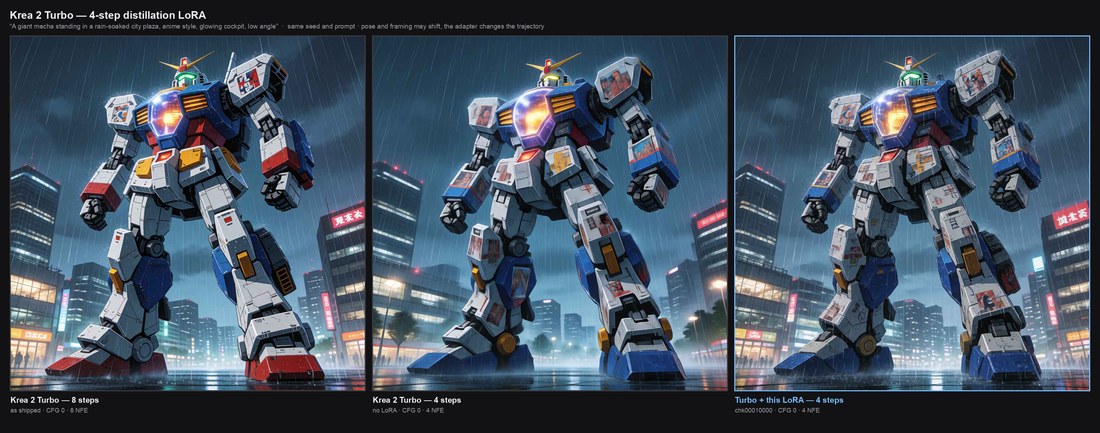
- assets/thumbs/mecha_compare_turbo.jpg +2 -2
- assets/thumbs/mecha_turbo_4step_lora_latest.jpg +0 -0
- assets/thumbs/megacity_compare_turbo.jpg +2 -2
- assets/thumbs/megacity_turbo_4step_lora_latest.jpg +0 -0
README.md
CHANGED
|
@@ -28,23 +28,24 @@ Right: 4 steps with this LoRA. Same seed throughout; click for full size. More c
|
|
| 28 |
| file | use it when |
|
| 29 |
| -------------------------------------------------------- | ---------------------------------------------------- |
|
| 30 |
| `krea2_turbo_4step_rank_64_lora_latest.safetensors` | **normally** — always the newest accepted checkpoint |
|
| 31 |
-
| `
|
| 32 |
|
| 33 |
and, beside them, the same files with a `_comfyui` suffix for ComfyUI. Earlier checkpoints
|
| 34 |
-
(`chk00004000`, `chk00005000`, `chk00006000`) are kept in
|
| 35 |
[`older_checkpoints/`](older_checkpoints), and their resolution sweeps stay in place, so the
|
| 36 |
progression remains visible and comparable.
|
| 37 |
|
| 38 |
-
The numbered files are points on **one continuous run**, not separate experiments — `
|
| 39 |
-
resumed from `chk00006000` rather than restarting.
|
| 40 |
|
| 41 |
-
`
|
| 42 |
-
teacher, where `
|
| 43 |
-
|
| 44 |
-
smaller than `
|
| 45 |
-
|
|
|
|
| 46 |
|
| 47 |
-
> **`_latest` currently points to `
|
| 48 |
> whenever a newer checkpoint is published.
|
| 49 |
|
| 50 |
**This is work in progress and better checkpoints may follow.** Training is ongoing, so
|
|
@@ -74,7 +75,19 @@ was published. The cause was traced to the optimiser: a constant learning rate w
|
|
| 74 |
lets the adapter keep drifting after it has converged, so its magnitude grows and it over-applies
|
| 75 |
its own correction. The same span was retrained from `chk00006000` with a cosine learning-rate decay
|
| 76 |
and weight decay, and every checkpoint of that second run improved on the one before it.
|
| 77 |
-
`chk00010000`
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 78 |
|
| 79 |
### Timeline of training process
|
| 80 |
|
|
@@ -102,11 +115,14 @@ shards is produced. A quiet stretch is shard generation, not abandonment; `_late
|
|
| 102 |
the newest checkpoint that passed review.
|
| 103 |
|
| 104 |
The current checkpoint and the one before it mark the last two revisions of the recipe:
|
| 105 |
-
`
|
| 106 |
-
|
| 107 |
-
|
| 108 |
-
|
| 109 |
-
|
|
|
|
|
|
|
|
|
|
| 110 |
|
| 111 |
Every file records which checkpoint it actually is in its safetensors metadata (`checkpoint`,
|
| 112 |
`training_samples`, and `rolling_pointer` on the `_latest` copies), so a downloaded file can always
|
|
@@ -115,54 +131,72 @@ be identified even if renamed.
|
|
| 115 |
### Checkpoint numbering
|
| 116 |
|
| 117 |
```
|
| 118 |
-
|
| 119 |
^^^^^^^^
|
| 120 |
```
|
| 121 |
|
| 122 |
-
The number is the count of **training samples consumed** — `
|
| 123 |
an epoch count, a step count, or a quality score. Higher-numbered checkpoints are further along the
|
| 124 |
same continuous run, resuming from the previous checkpoint rather than restarting.
|
| 125 |
|
| 126 |
-
##
|
| 127 |
|
| 128 |
-
**The measure.** Every checkpoint is scored the same way. On
|
| 129 |
-
a gradient step, the 4-step student's predicted velocity is compared with the 8-step
|
| 130 |
-
recorded two-step chord at each of the four sigmas the student actually deploys on (see
|
| 131 |
[Method](#method)). The result is a relative error — the **gap to the teacher** — and it is
|
| 132 |
-
deterministic: the same weights always score the same number.
|
| 133 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
| 134 |
|
| 135 |
| | gap to the 8-step teacher | of the 4-step deficit closed |
|
| 136 |
| -------------------------------- | ------------------------- | ---------------------------- |
|
| 137 |
-
| Krea 2 Turbo — 4 steps, no LoRA | 4.
|
| 138 |
-
| `chk00005000` | 3.
|
| 139 |
-
| `chk00006000` | 3.
|
| 140 |
-
|
|
|
|
|
| 141 |
|
| 142 |
Two ways to read the same numbers, with different denominators — they are not meant to be added:
|
| 143 |
|
| 144 |
-
- **Against the no-LoRA run** (the right-hand column): `
|
| 145 |
-
4-step deficit, 4 percentage points more than `
|
| 146 |
-
- **Against each other** (the gap column): `
|
| 147 |
-
`
|
| 148 |
same 4 points of deficit are a larger share of a gap that has already shrunk, which is why the
|
| 149 |
checkpoint-to-checkpoint figure is the bigger number.
|
| 150 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 151 |
**Read these as error figures, not as quality fractions.** A plain 4-step run already produces a
|
| 152 |
complete, coherent image; what it loses against 8 steps is fine detail and texture, and that loss
|
| 153 |
-
shows up as its predictions sitting about 4.
|
| 154 |
-
about
|
| 155 |
-
means
|
| 156 |
two-step chords exactly, i.e. perfect 8-step equivalence in 4 steps, which no low-rank adapter on
|
| 157 |
a frozen base reaches and which the images do not need in order to match.
|
| 158 |
|
| 159 |
-
**Why it is better, not just later.** `
|
| 160 |
-
|
| 161 |
-
|
| 162 |
-
|
| 163 |
-
|
| 164 |
-
|
| 165 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 166 |
|
| 167 |
**What the number does not say.** It is a training-space measure and does not rank images pixel
|
| 168 |
for pixel. With a fixed seed the student's trajectory drifts away from the teacher's, so
|
|
@@ -342,11 +376,11 @@ ships bf16 simply because it is the one build guaranteed to run everywhere.
|
|
| 342 |
> graph executes fine right up to the sampler. The fp8 _text encoder_ does run on MPS, but only
|
| 343 |
> because ComfyUI places it on CPU; the published workflow does not rely on that.
|
| 344 |
|
| 345 |
-
> **`_latest_comfyui` currently points to `
|
| 346 |
|
| 347 |
The workflow references the **`_latest`** LoRA filename deliberately: as training continues and
|
| 348 |
newer checkpoints are published, replacing that one file is enough — the workflow itself never
|
| 349 |
-
needs editing. A numbered copy (`...
|
| 350 |
rather pin a specific checkpoint in the node.
|
| 351 |
|
| 352 |
**Why a separate file.** ComfyUI addresses the transformer by its own layer names, so the adapter
|
|
@@ -389,8 +423,8 @@ cherry-picked; a sweep is the complete set or it is not published.
|
|
| 389 |
|
| 390 |
```
|
| 391 |
checkpoint_resolution_sweeps/
|
| 392 |
-
├── chk4000/ chk5000/ chk6000/
|
| 393 |
-
└──
|
| 394 |
├── 512x512/ one folder per resolution
|
| 395 |
│ ├── portrait.jpg
|
| 396 |
│ ├── kingfisher.jpg
|
|
@@ -496,7 +530,7 @@ targets are permanent, so the teacher's error is baked into every trajectory for
|
|
| 496 |
`chk00006000` and every checkpoint after it are trained this way. Everything up to and including
|
| 497 |
`chk00005000` used an NF4 teacher and an NF4 base. On the same held-out set the cleaner targets were
|
| 498 |
worth a **13% smaller gap to the teacher** at `chk00006000`; the optimiser changes that followed
|
| 499 |
-
took it further (see [
|
| 500 |
|
| 501 |
There is a second, subtler effect worth stating plainly. Re-scoring the _older_ `chk00005000`
|
| 502 |
against int8 targets instead of NF4 ones drops its measured gap-recovery from 28.9% to 17.9% — the
|
|
|
|
| 28 |
| file | use it when |
|
| 29 |
| -------------------------------------------------------- | ---------------------------------------------------- |
|
| 30 |
| `krea2_turbo_4step_rank_64_lora_latest.safetensors` | **normally** — always the newest accepted checkpoint |
|
| 31 |
+
| `krea2_turbo_4step_rank_64_lora_chk00014000.safetensors` | pin this exact checkpoint |
|
| 32 |
|
| 33 |
and, beside them, the same files with a `_comfyui` suffix for ComfyUI. Earlier checkpoints
|
| 34 |
+
(`chk00004000`, `chk00005000`, `chk00006000`, `chk00010000`) are kept in
|
| 35 |
[`older_checkpoints/`](older_checkpoints), and their resolution sweeps stay in place, so the
|
| 36 |
progression remains visible and comparable.
|
| 37 |
|
| 38 |
+
The numbered files are points on **one continuous run**, not separate experiments — `chk00014000`
|
| 39 |
+
resumed from `chk00010000`, which resumed from `chk00006000`, rather than restarting.
|
| 40 |
|
| 41 |
+
`chk00014000` removes **44%** of the prediction error a plain 4-step run has against the 8-step
|
| 42 |
+
teacher, where `chk00010000` removed 40% and `chk00006000` 27% — all measured on the same enlarged
|
| 43 |
+
held-out set (100 prompts across every trained resolution). Measured against each other rather than
|
| 44 |
+
against the no-LoRA run, its remaining error is **6% smaller than `chk00010000`'s** and **23%
|
| 45 |
+
smaller than `chk00006000`'s**. What that number is — and what it is not — is in
|
| 46 |
+
[chk00014000 vs chk00010000](#chk00014000-vs-chk00010000).
|
| 47 |
|
| 48 |
+
> **`_latest` currently points to `chk00014000`** — 14,000 training samples. This line is updated
|
| 49 |
> whenever a newer checkpoint is published.
|
| 50 |
|
| 51 |
**This is work in progress and better checkpoints may follow.** Training is ongoing, so
|
|
|
|
| 75 |
lets the adapter keep drifting after it has converged, so its magnitude grows and it over-applies
|
| 76 |
its own correction. The same span was retrained from `chk00006000` with a cosine learning-rate decay
|
| 77 |
and weight decay, and every checkpoint of that second run improved on the one before it.
|
| 78 |
+
`chk00010000` was its end point.
|
| 79 |
+
|
| 80 |
+
`chk00014000` is the next example, and it shows the other half of the same lesson. The run was
|
| 81 |
+
continued from `chk00010000` over the whole pool of teacher trajectories, with two changes: the
|
| 82 |
+
final, texture-deciding call of the schedule was weighted more heavily in the loss, and a running
|
| 83 |
+
**average of the weights** was kept beside the live ones and scored at every evaluation (a
|
| 84 |
+
single checkpoint is one sample of a weight vector that moves from step to step; the average is
|
| 85 |
+
its mean). At 14,000 samples the averaged weights measured a smaller gap to the teacher than any
|
| 86 |
+
checkpoint before them, and a smaller gap than the live weights at the same point — so the averaged
|
| 87 |
+
weights are what `chk00014000` is. The run was allowed to continue well past that point, and the
|
| 88 |
+
adapter's magnitude began to grow again: later checkpoints measured worse on the held-out set and
|
| 89 |
+
further from the teacher in fixed-seed renders, and none of them was published. The number is
|
| 90 |
+
chosen by measurement, not by how far the run went.
|
| 91 |
|
| 92 |
### Timeline of training process
|
| 93 |
|
|
|
|
| 115 |
the newest checkpoint that passed review.
|
| 116 |
|
| 117 |
The current checkpoint and the one before it mark the last two revisions of the recipe:
|
| 118 |
+
`chk00010000` continued `chk00006000` with **cosine learning-rate decay and weight decay**, and
|
| 119 |
+
`chk00014000` continued `chk00010000` over the full pool of teacher trajectories with the final
|
| 120 |
+
call of the schedule **weighted more heavily** and the shipped weights taken as a **running
|
| 121 |
+
average** of the trained ones. The checkpoints before them were earlier points on the same run
|
| 122 |
+
(`chk00006000` was the first trained on **int8** teacher trajectories and an int8 base, see
|
| 123 |
+
[Hardware](#hardware); the ones before it used an NF4 teacher). Each published checkpoint has
|
| 124 |
+
measured a smaller gap to the teacher than the one it replaced, and the earlier files are kept in
|
| 125 |
+
[`older_checkpoints/`](older_checkpoints) for comparison only.
|
| 126 |
|
| 127 |
Every file records which checkpoint it actually is in its safetensors metadata (`checkpoint`,
|
| 128 |
`training_samples`, and `rolling_pointer` on the `_latest` copies), so a downloaded file can always
|
|
|
|
| 131 |
### Checkpoint numbering
|
| 132 |
|
| 133 |
```
|
| 134 |
+
krea2_turbo_4step_rank_64_lora_chk00014000.safetensors
|
| 135 |
^^^^^^^^
|
| 136 |
```
|
| 137 |
|
| 138 |
+
The number is the count of **training samples consumed** — `chk00014000` has seen 14,000. It is not
|
| 139 |
an epoch count, a step count, or a quality score. Higher-numbered checkpoints are further along the
|
| 140 |
same continuous run, resuming from the previous checkpoint rather than restarting.
|
| 141 |
|
| 142 |
+
## chk00014000 vs chk00010000
|
| 143 |
|
| 144 |
+
**The measure.** Every checkpoint is scored the same way. On a fixed set of held-out prompts that
|
| 145 |
+
never receive a gradient step, the 4-step student's predicted velocity is compared with the 8-step
|
| 146 |
+
teacher's recorded two-step chord at each of the four sigmas the student actually deploys on (see
|
| 147 |
[Method](#method)). The result is a relative error — the **gap to the teacher** — and it is
|
| 148 |
+
deterministic: the same weights always score the same number. The set behind the figures below is
|
| 149 |
+
the enlarged one: **one hundred held-out prompts across all eleven trained resolutions** (800
|
| 150 |
+
teacher states). Every earlier checkpoint has been re-scored on it, so all rows are comparable;
|
| 151 |
+
the earlier, smaller set (eight prompts at four resolutions) gave different absolute values and is
|
| 152 |
+
no longer used. Krea 2 Turbo run at 4 steps with no LoRA scores 4.69e-02 on this set; that is the
|
| 153 |
+
deficit this LoRA exists to close.
|
| 154 |
|
| 155 |
| | gap to the 8-step teacher | of the 4-step deficit closed |
|
| 156 |
| -------------------------------- | ------------------------- | ---------------------------- |
|
| 157 |
+
| Krea 2 Turbo — 4 steps, no LoRA | 4.69e-02 | 0% |
|
| 158 |
+
| `chk00005000` | 3.26e-02 | 30% |
|
| 159 |
+
| `chk00006000` | 3.45e-02 | 27% |
|
| 160 |
+
| `chk00010000` | 2.81e-02 | 40% |
|
| 161 |
+
| **`chk00014000`** | **2.64e-02** | **44%** |
|
| 162 |
|
| 163 |
Two ways to read the same numbers, with different denominators — they are not meant to be added:
|
| 164 |
|
| 165 |
+
- **Against the no-LoRA run** (the right-hand column): `chk00014000` has removed 44% of the
|
| 166 |
+
4-step deficit, about 4 percentage points more than `chk00010000`'s 40%.
|
| 167 |
+
- **Against each other** (the gap column): `chk00014000`'s remaining error is **6.1% smaller than
|
| 168 |
+
`chk00010000`'s** (2.64 vs 2.81) and **23% smaller than `chk00006000`'s** (2.64 vs 3.45). The
|
| 169 |
same 4 points of deficit are a larger share of a gap that has already shrunk, which is why the
|
| 170 |
checkpoint-to-checkpoint figure is the bigger number.
|
| 171 |
|
| 172 |
+
One thing the larger set changed: on it, `chk00005000` scores slightly better than `chk00006000`
|
| 173 |
+
(3.26 vs 3.45), the opposite of the order the small set gave. Eight prompts were not enough to
|
| 174 |
+
separate two neighbouring checkpoints reliably; one hundred across every resolution is what the
|
| 175 |
+
set was enlarged for, and the rows above are the numbers that count from here on.
|
| 176 |
+
|
| 177 |
**Read these as error figures, not as quality fractions.** A plain 4-step run already produces a
|
| 178 |
complete, coherent image; what it loses against 8 steps is fine detail and texture, and that loss
|
| 179 |
+
shows up as its predictions sitting about 4.7% away from the teacher's. The LoRA brings that to
|
| 180 |
+
about 2.6%. "44% of the deficit closed" therefore does not mean "44% of the teacher's quality" — it
|
| 181 |
+
means 44% of that 4.7% error is gone. A gap of zero would be the student reproducing the teacher's
|
| 182 |
two-step chords exactly, i.e. perfect 8-step equivalence in 4 steps, which no low-rank adapter on
|
| 183 |
a frozen base reaches and which the images do not need in order to match.
|
| 184 |
|
| 185 |
+
**Why it is better, not just later.** `chk00010000` → `chk00014000` continued the same run over
|
| 186 |
+
the whole pool of teacher trajectories, with the last call of the 4-step schedule — the one that
|
| 187 |
+
decides fine texture — weighted more heavily in the loss, and with a running average of the
|
| 188 |
+
adapter weights scored beside the live ones at every evaluation (see
|
| 189 |
+
[How checkpoints get chosen](#how-checkpoints-get-chosen)). The averaged weights at 14,000 samples
|
| 190 |
+
are what ships: 2.64e-02, against 2.77e-02 for the live weights at the same point and 2.81e-02 for
|
| 191 |
+
`chk00010000`. The gain is on every one of the four calls, not just the weighted one: against
|
| 192 |
+
`chk00010000`, `chk00014000`'s error is 5.9% lower at the first sigma (composition), 4.2% and 7.0%
|
| 193 |
+
lower at the two middle sigmas, and 6.2% lower at the final, texture-deciding sigma; a full 4-call
|
| 194 |
+
rollout from the teacher's noise also ends 6% nearer the teacher's final latent. In fixed-seed
|
| 195 |
+
renders of the fifteen published prompts `chk00014000` lands nearer the
|
| 196 |
+
8-step images than `chk00010000` does, and its texture energy is closer
|
| 197 |
+
to the teacher's (0.90 of the teacher's on a scale where 1.0 is teacher-like, against 0.86 for
|
| 198 |
+
`chk00010000`) without crossing it. The continuation past 14,000 samples measured worse at every
|
| 199 |
+
subsequent evaluation as the adapter's magnitude grew again; none of it was published.
|
| 200 |
|
| 201 |
**What the number does not say.** It is a training-space measure and does not rank images pixel
|
| 202 |
for pixel. With a fixed seed the student's trajectory drifts away from the teacher's, so
|
|
|
|
| 376 |
> graph executes fine right up to the sampler. The fp8 _text encoder_ does run on MPS, but only
|
| 377 |
> because ComfyUI places it on CPU; the published workflow does not rely on that.
|
| 378 |
|
| 379 |
+
> **`_latest_comfyui` currently points to `chk00014000`** — 14,000 training samples.
|
| 380 |
|
| 381 |
The workflow references the **`_latest`** LoRA filename deliberately: as training continues and
|
| 382 |
newer checkpoints are published, replacing that one file is enough — the workflow itself never
|
| 383 |
+
needs editing. A numbered copy (`..._chk00014000_comfyui.safetensors`) sits beside it if you would
|
| 384 |
rather pin a specific checkpoint in the node.
|
| 385 |
|
| 386 |
**Why a separate file.** ComfyUI addresses the transformer by its own layer names, so the adapter
|
|
|
|
| 423 |
|
| 424 |
```
|
| 425 |
checkpoint_resolution_sweeps/
|
| 426 |
+
├── chk4000/ chk5000/ chk6000/ chk10000/
|
| 427 |
+
└── chk14000/ one folder per checkpoint, named for the checkpoint it renders
|
| 428 |
├── 512x512/ one folder per resolution
|
| 429 |
│ ├── portrait.jpg
|
| 430 |
│ ├── kingfisher.jpg
|
|
|
|
| 530 |
`chk00006000` and every checkpoint after it are trained this way. Everything up to and including
|
| 531 |
`chk00005000` used an NF4 teacher and an NF4 base. On the same held-out set the cleaner targets were
|
| 532 |
worth a **13% smaller gap to the teacher** at `chk00006000`; the optimiser changes that followed
|
| 533 |
+
took it further (see [chk00014000 vs chk00010000](#chk00014000-vs-chk00010000)).
|
| 534 |
|
| 535 |
There is a second, subtler effect worth stating plainly. Re-scoring the _older_ `chk00005000`
|
| 536 |
against int8 targets instead of NF4 ones drops its measured gap-recovery from 28.9% to 17.9% — the
|
assets/claychef_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/claychef_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/colonyship_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/colonyship_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/inventor_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/inventor_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/kingfisher_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/kingfisher_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/market_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/market_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/mecha_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/mecha_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/megacity_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/megacity_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/neonstreet_compare_turbo.jpg
CHANGED
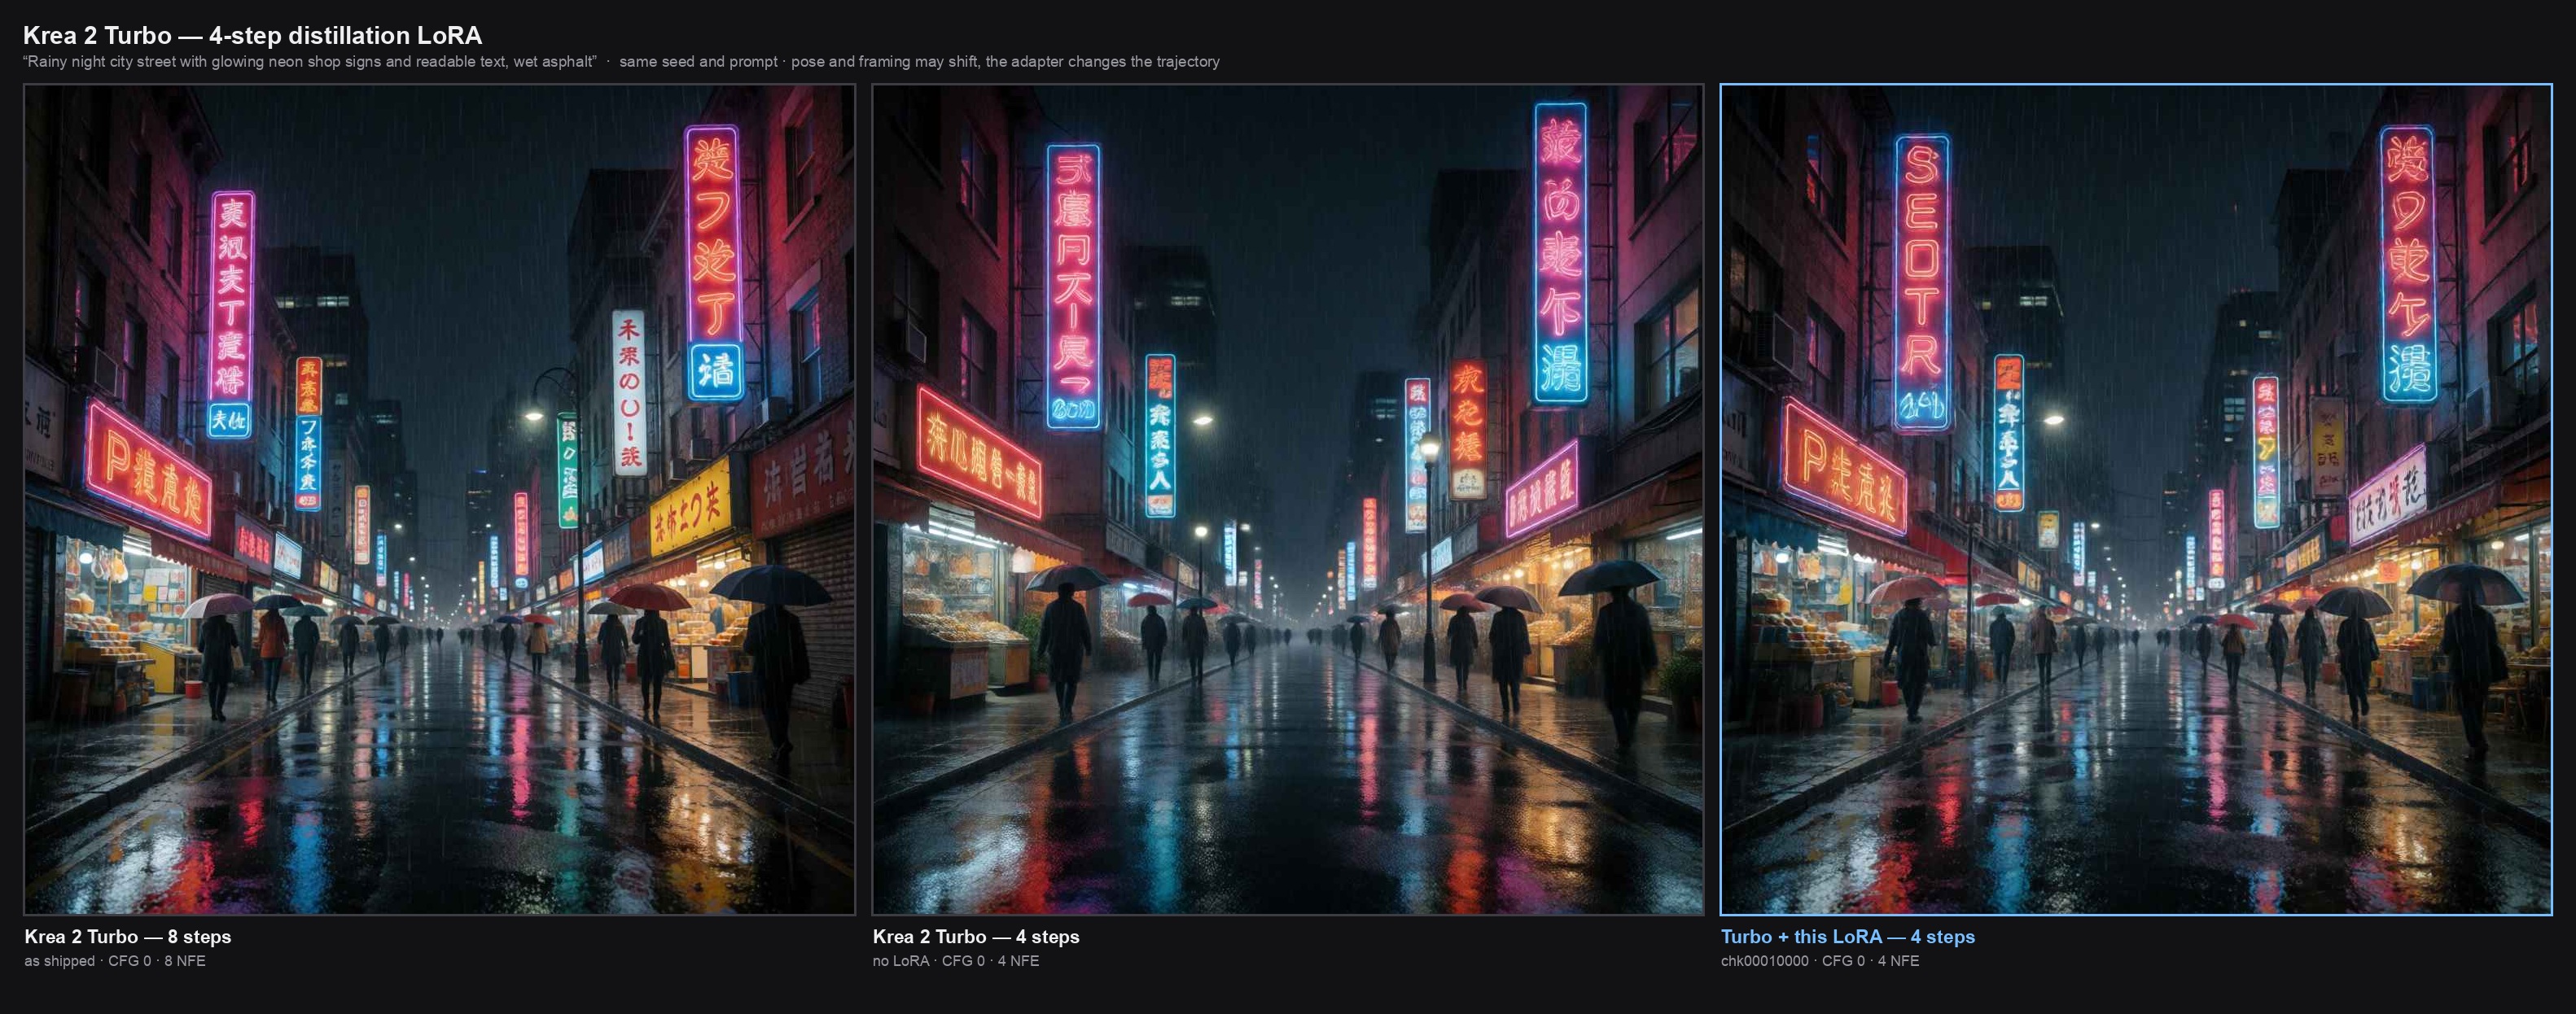
|
Git LFS Details
|
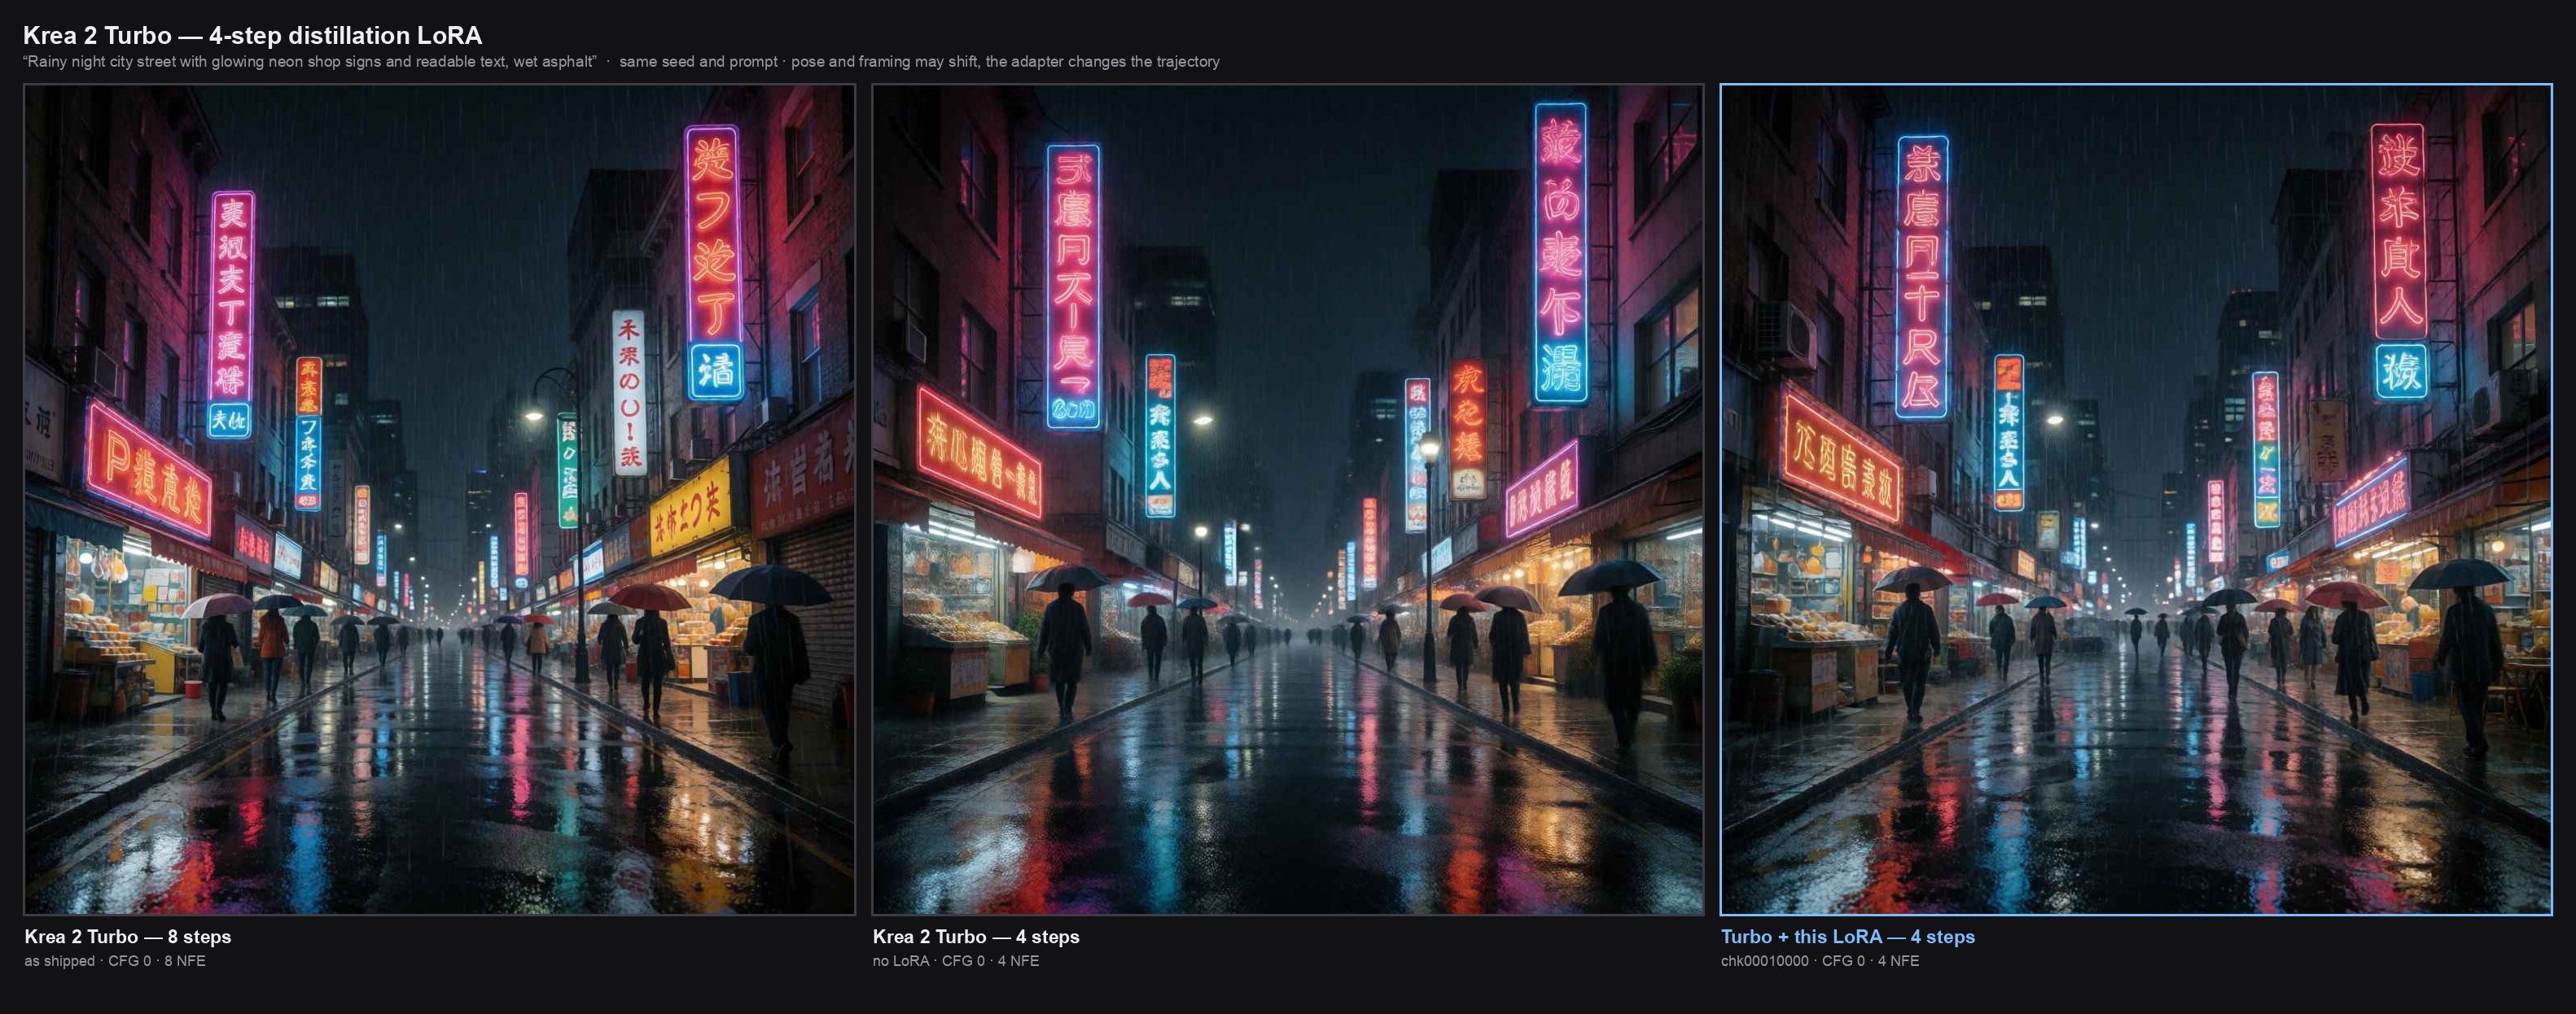
|
Git LFS Details
|
assets/neonstreet_turbo_4step_lora_latest.jpg
CHANGED
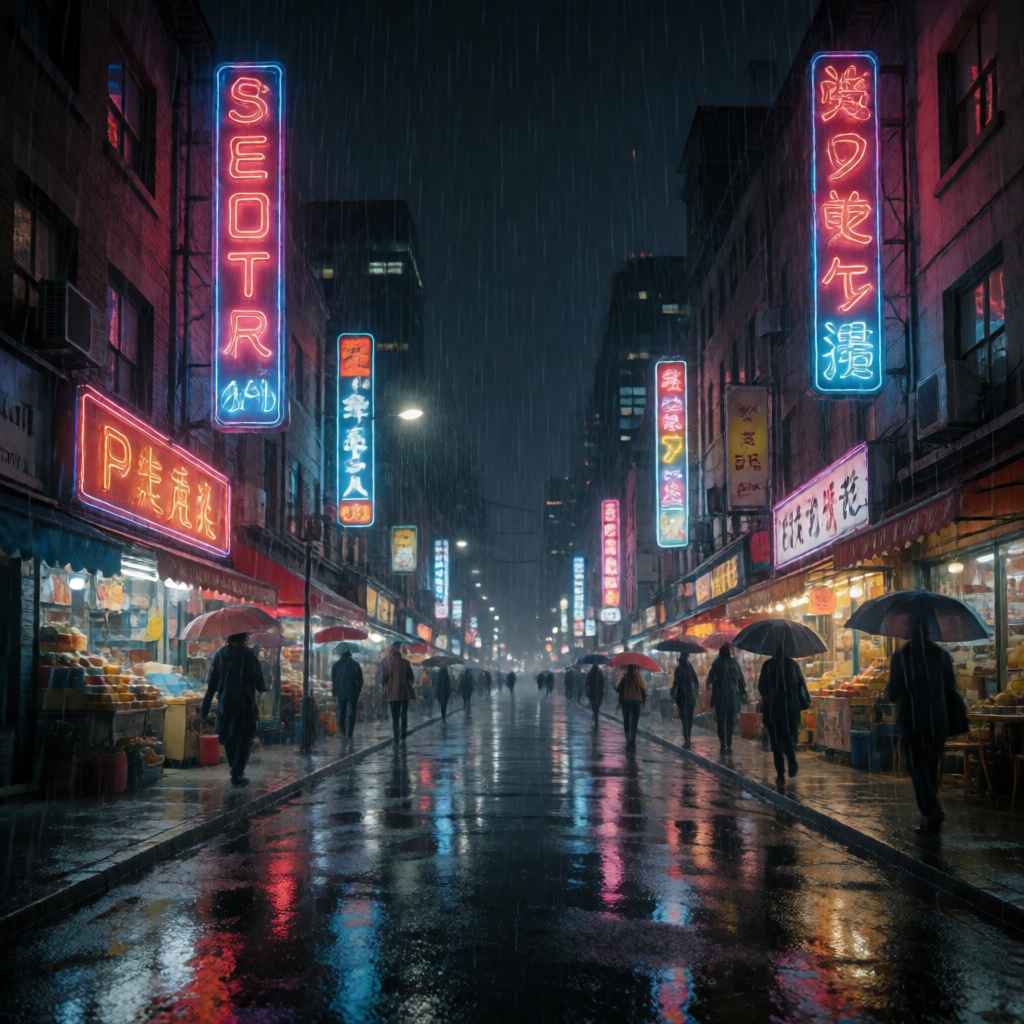
|
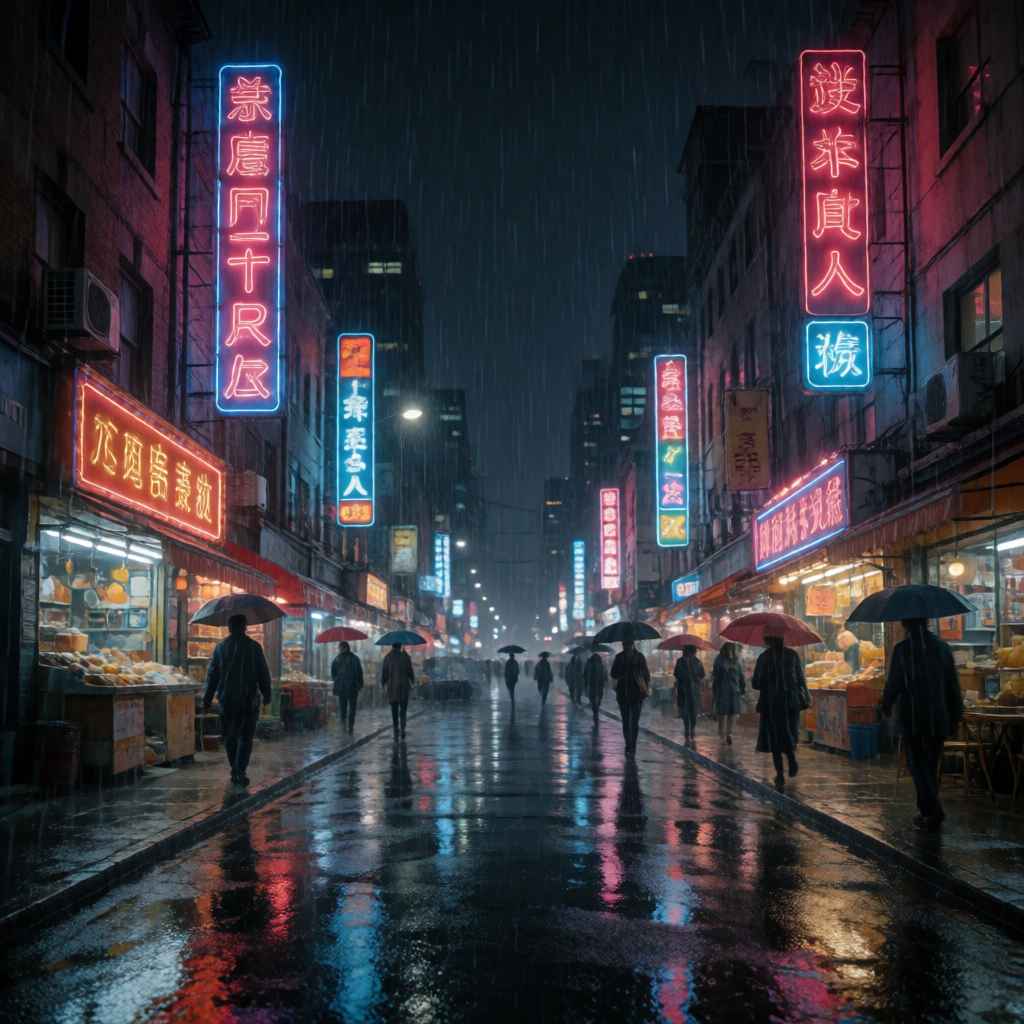
|
assets/pizza_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/pizza_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/portrait_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/portrait_strength_0.5.jpg
CHANGED
|
|
assets/portrait_strength_1.0.jpg
CHANGED
|
|
assets/portrait_strength_1.5.jpg
CHANGED
|
|
assets/portrait_strength_2.0.jpg
CHANGED
|
|
assets/portrait_strength_sweep.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/portrait_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/racecar_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/racecar_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/snowleopard_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/snowleopard_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/sorceress_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/sorceress_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/storybookfox_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/storybookfox_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/swordsman_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/swordsman_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/thumbs/claychef_compare_turbo.jpg
CHANGED
|
|
assets/thumbs/claychef_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/thumbs/colonyship_compare_turbo.jpg
CHANGED
|
|
assets/thumbs/colonyship_turbo_4step_lora_latest.jpg
CHANGED
|
|
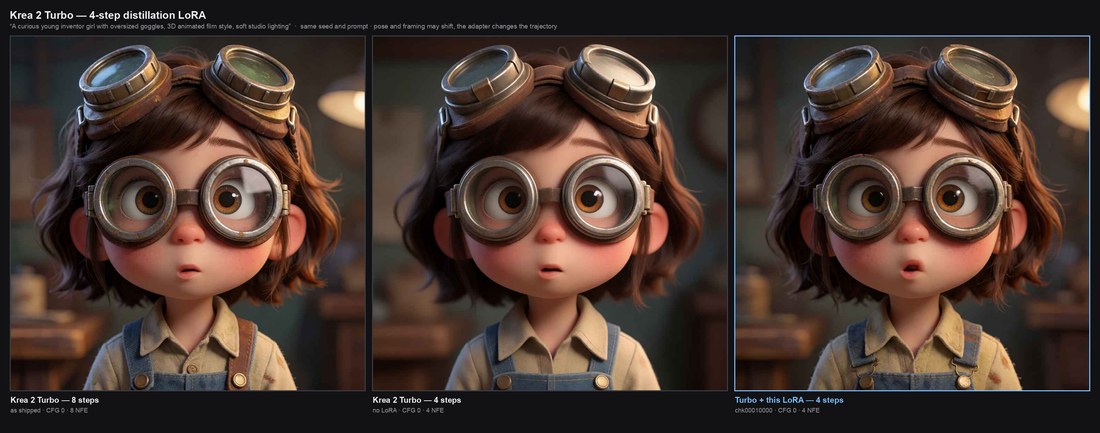
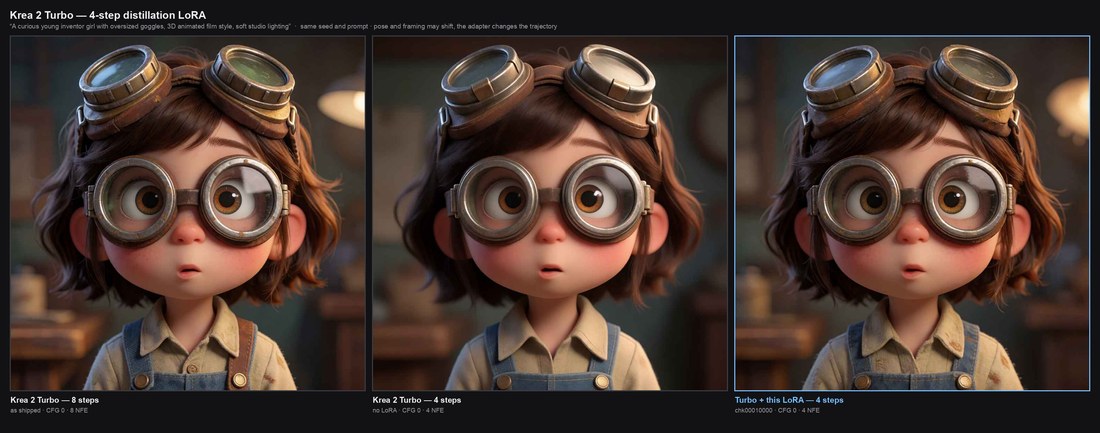
assets/thumbs/inventor_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/thumbs/inventor_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/thumbs/kingfisher_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/thumbs/kingfisher_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/thumbs/market_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/thumbs/market_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/thumbs/mecha_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/thumbs/mecha_turbo_4step_lora_latest.jpg
CHANGED
|
|
assets/thumbs/megacity_compare_turbo.jpg
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
assets/thumbs/megacity_turbo_4step_lora_latest.jpg
CHANGED
|
|