

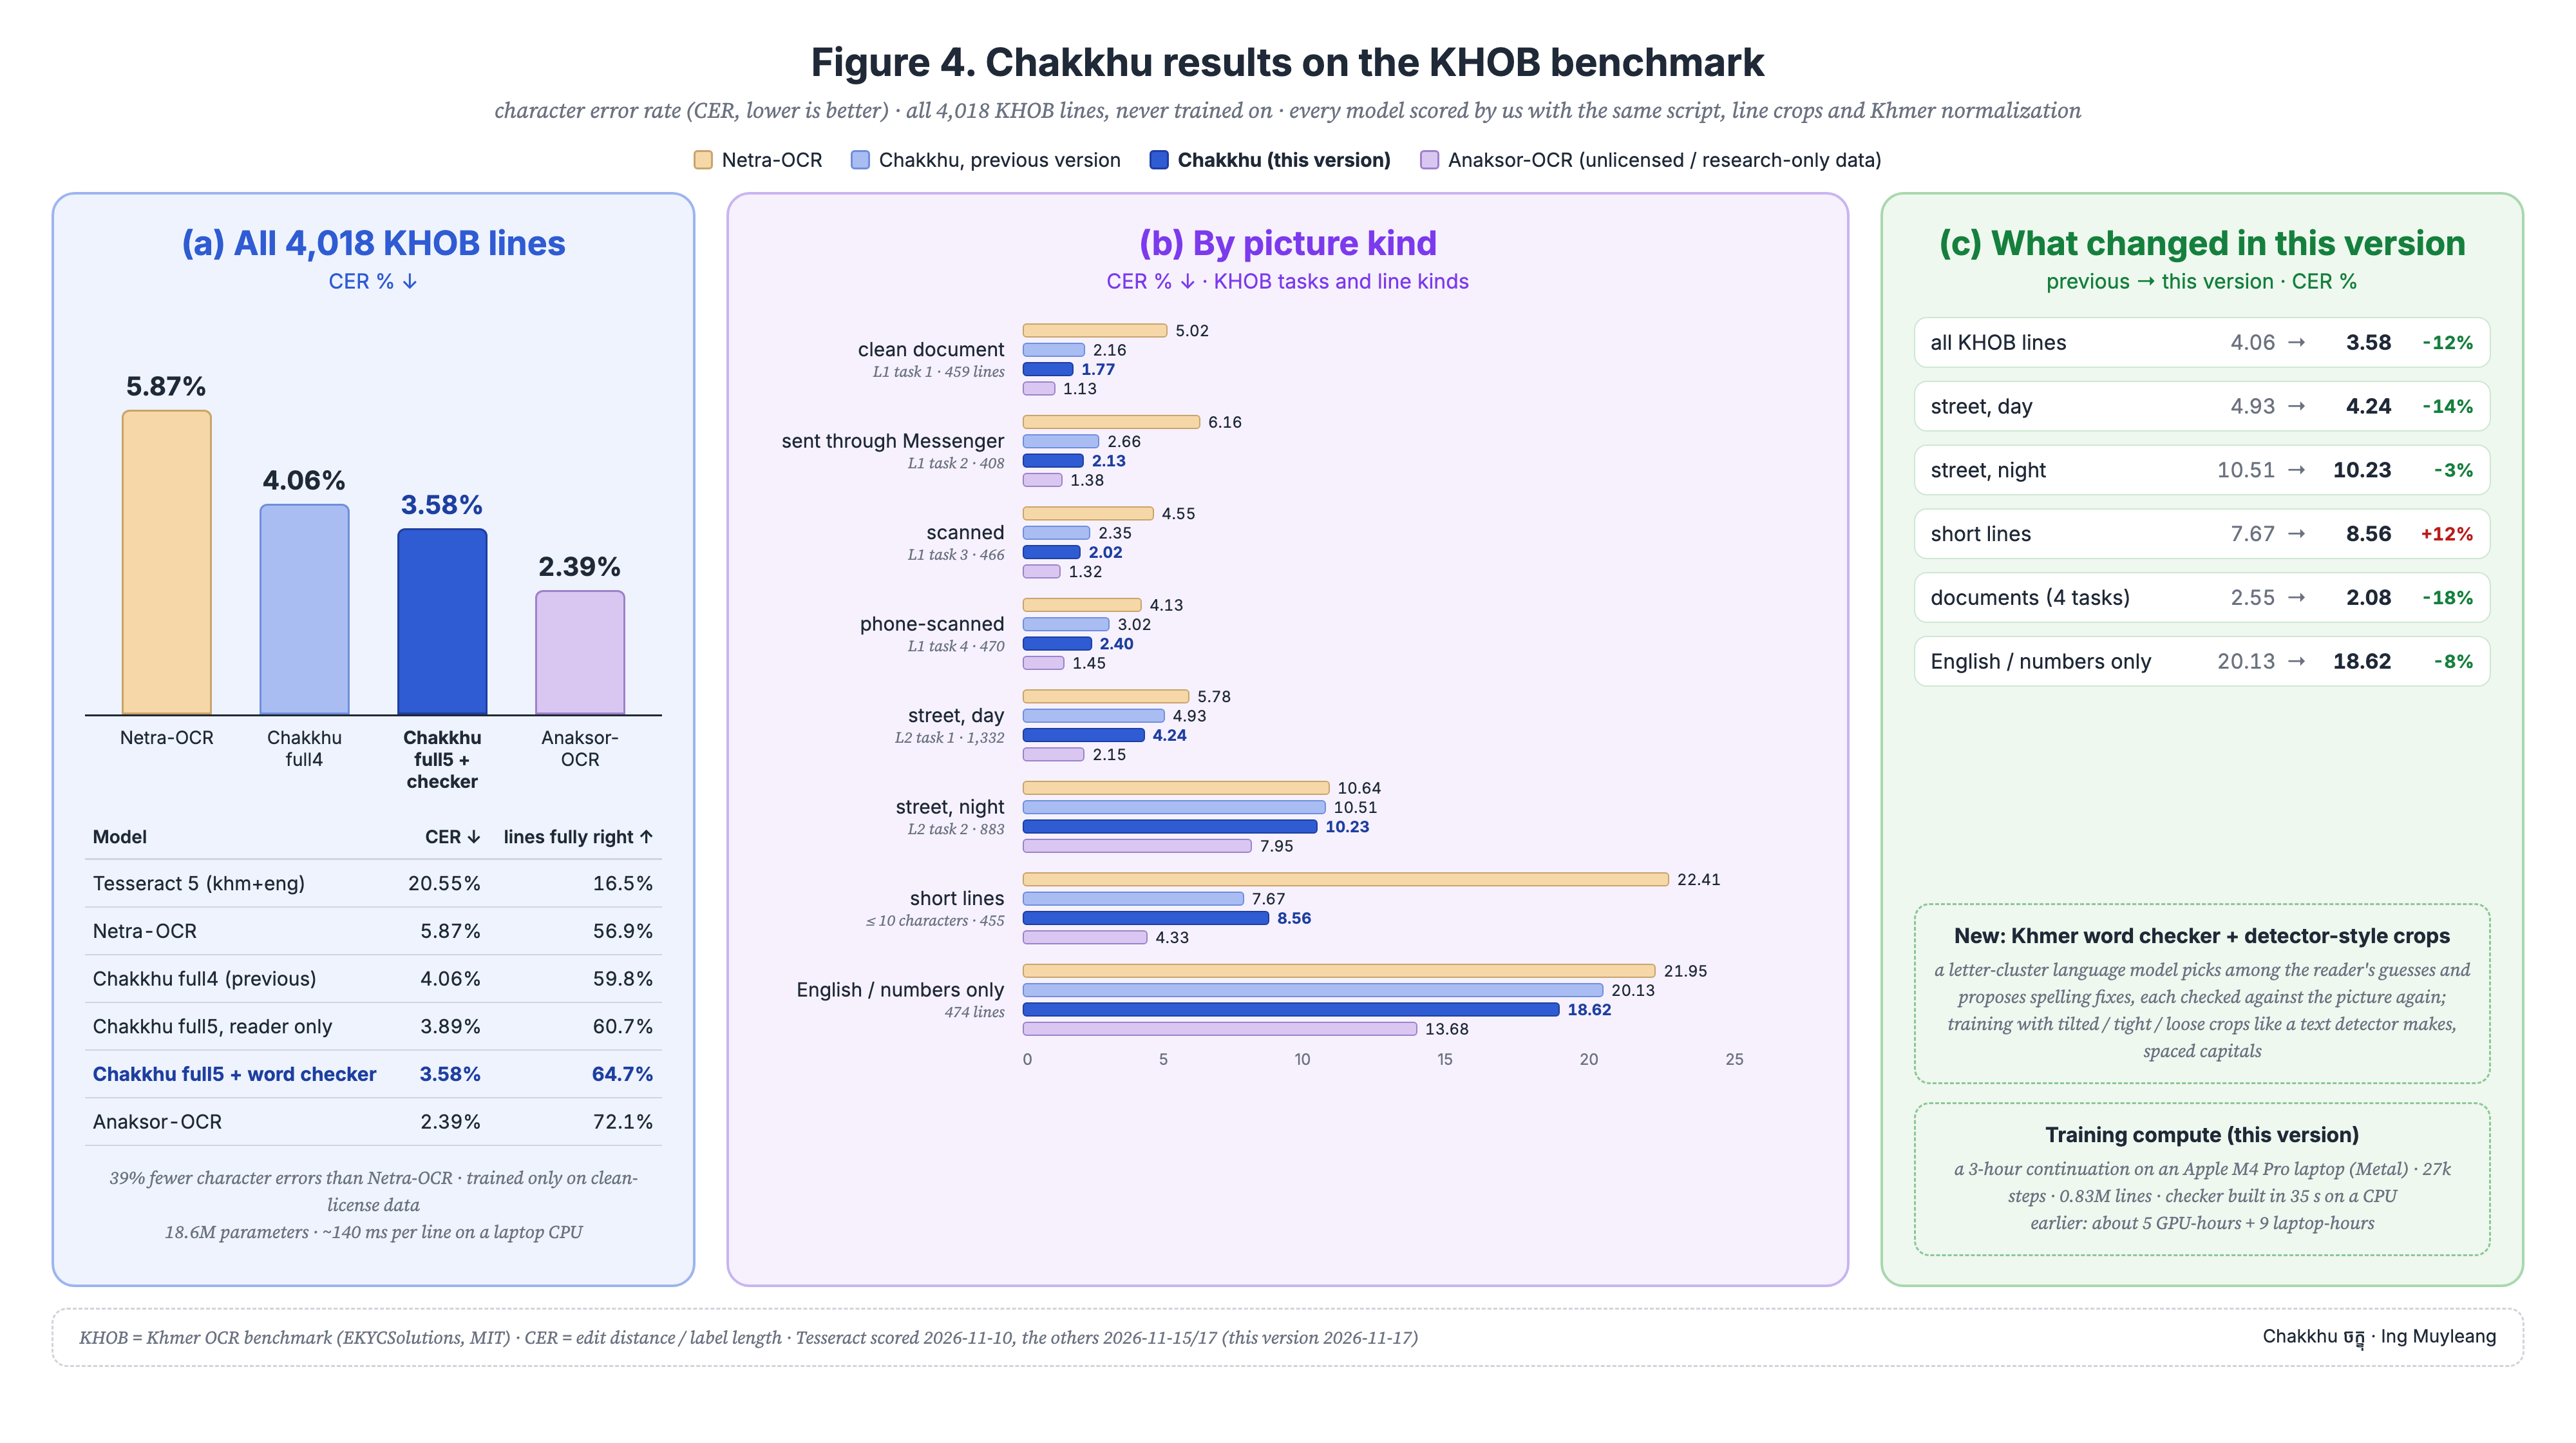
full5 + Khmer word checker: 3.58% CER on KHOB (reader alone 3.89%)
Browse files- README.md +43 -25
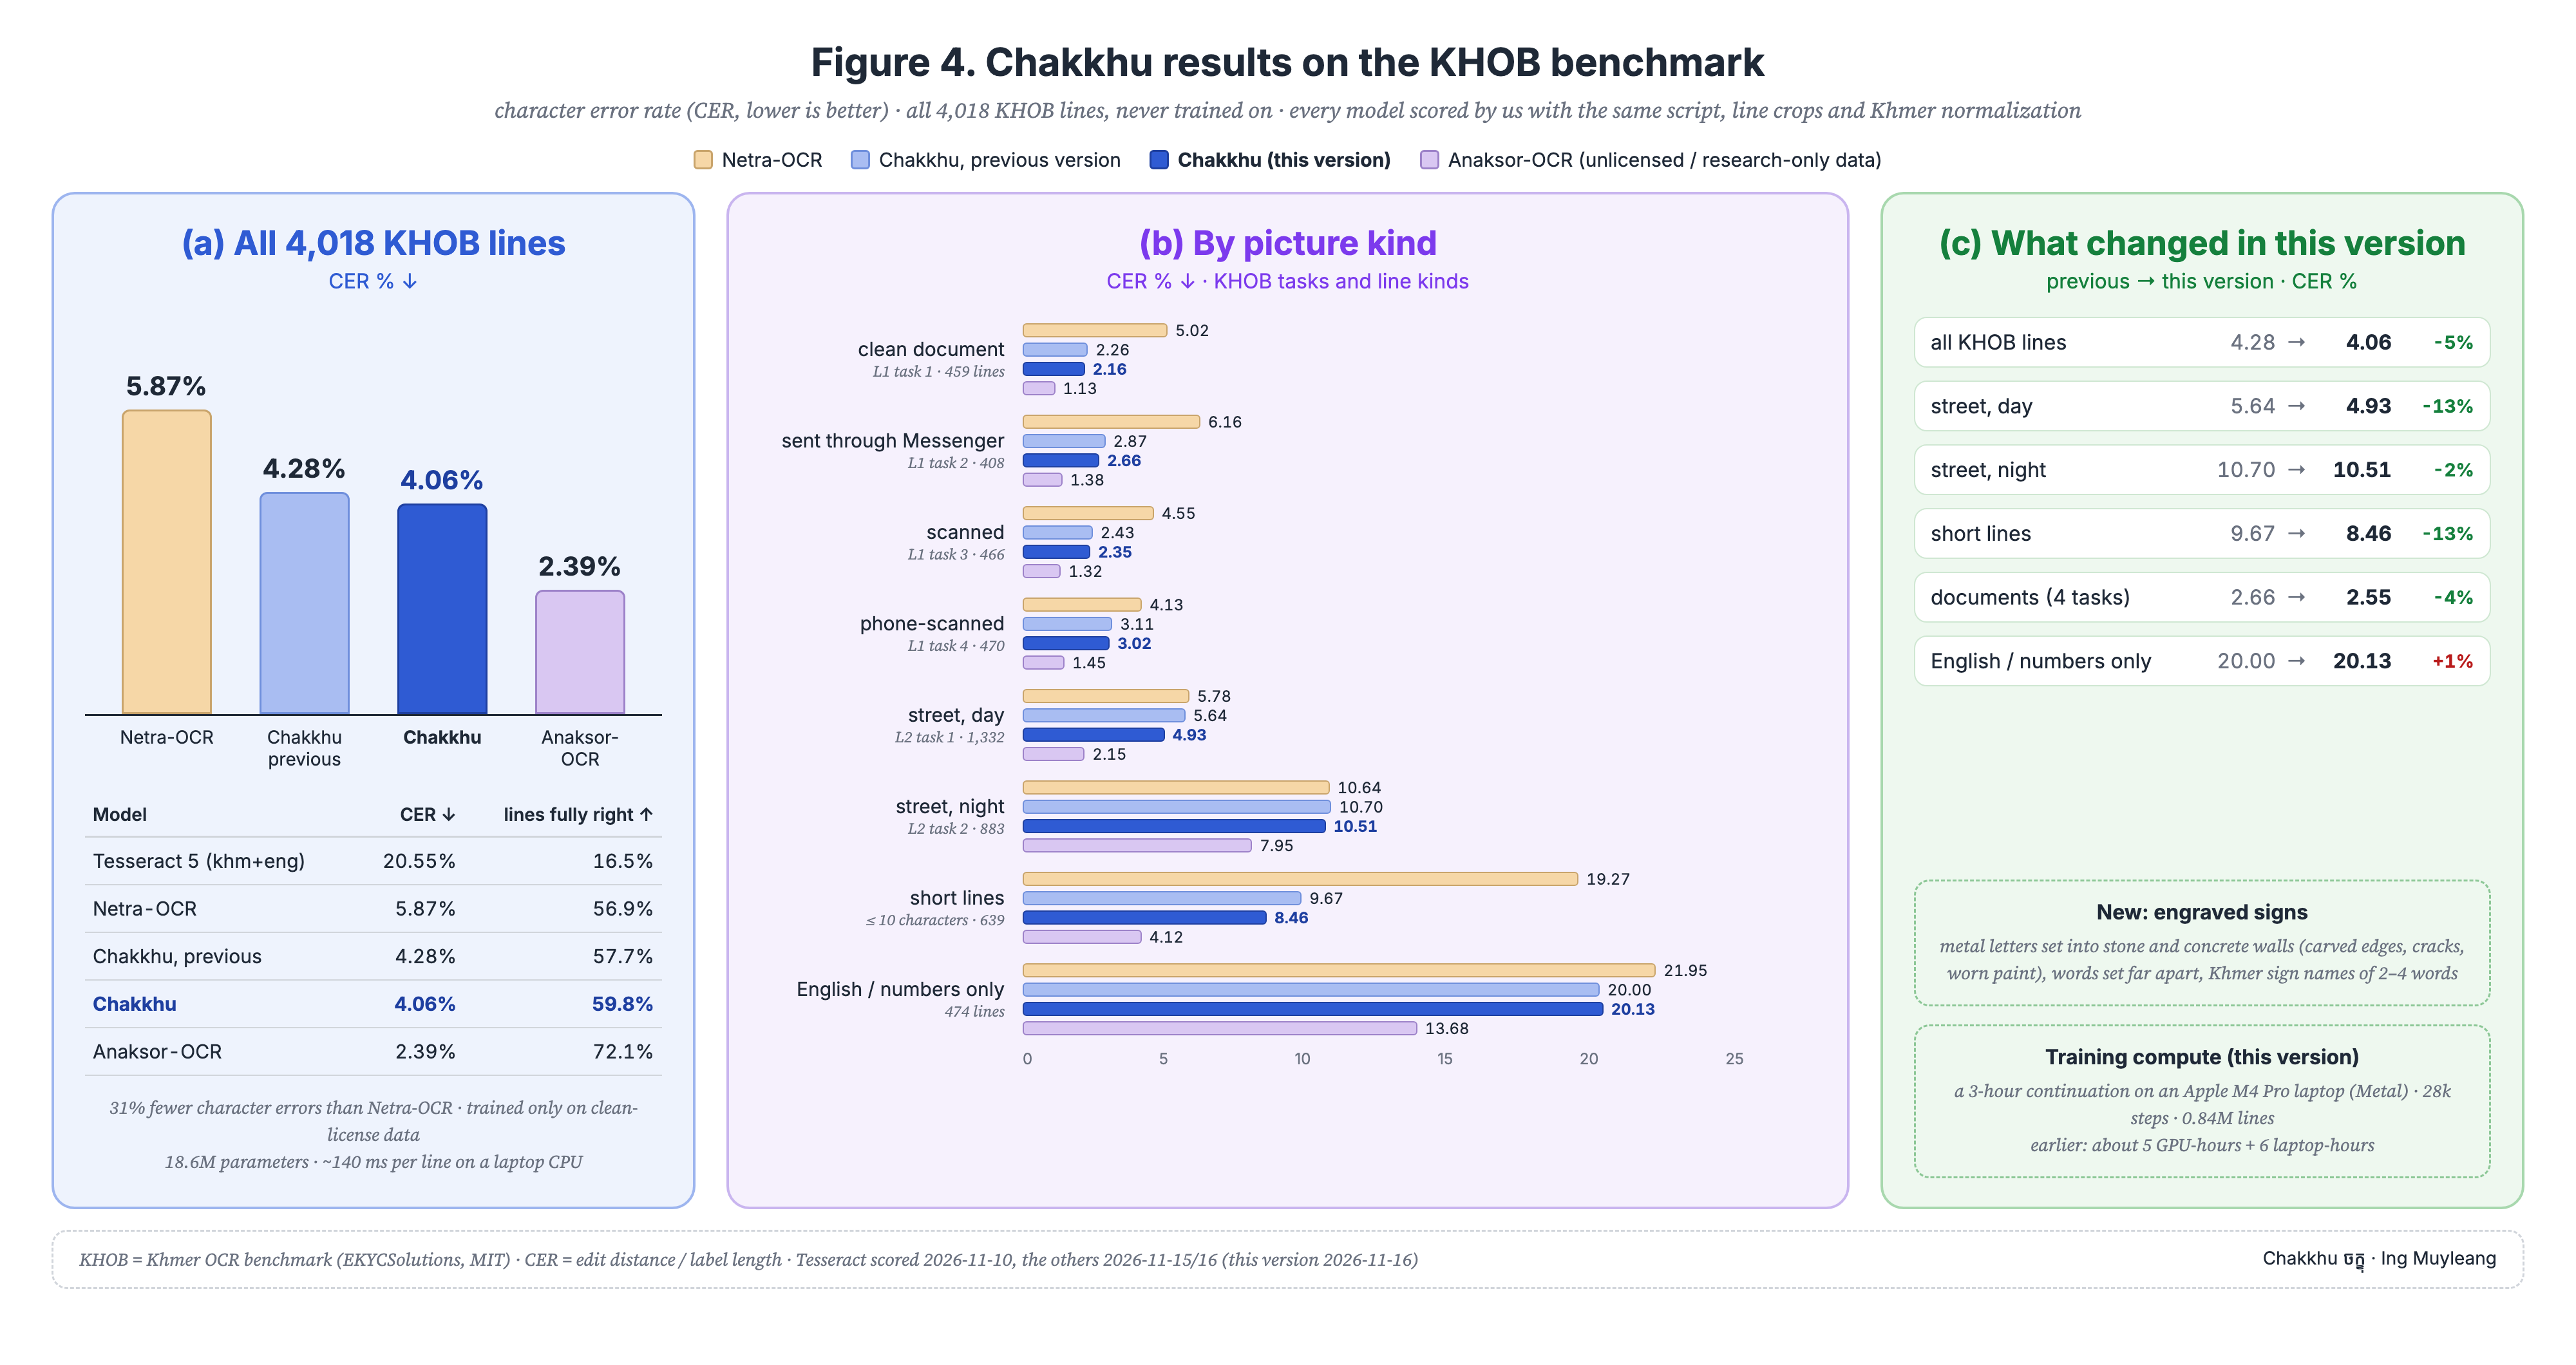
- assets/results.png +2 -2
- chakkhu/__init__.py +19 -6
- chakkhu/checker.py +309 -0
- checker/checker_lm.npz +3 -0
- checker/latin_words.json +1 -0
- model.safetensors +1 -1
README.md
CHANGED
|
@@ -22,10 +22,10 @@ model-index:
|
|
| 22 |
name: KHOB (all 4,018 lines)
|
| 23 |
metrics:
|
| 24 |
- type: cer
|
| 25 |
-
value:
|
| 26 |
-
name: CER (%)
|
| 27 |
- type: accuracy
|
| 28 |
-
value:
|
| 29 |
name: Lines fully right (%)
|
| 30 |
---
|
| 31 |
|
|
@@ -35,8 +35,10 @@ model-index:
|
|
| 35 |
typewritten pages, scans, phone photos of paper, screenshots, chat pictures and signs. It is small
|
| 36 |
(18.6M parameters), runs on a CPU, and tells you **how sure it is** about every line.
|
| 37 |
|
| 38 |
-
- **
|
| 39 |
-
- **new in this version:**
|
|
|
|
|
|
|
| 40 |
- a **confidence** (0–1) for every line, to decide which lines a person should check
|
| 41 |
- about 140 ms per line on a laptop CPU, ~20 ms on a GPU
|
| 42 |
- writes whole Khmer letter **clusters** (ស្ត្រី = 1 step), so subscripts and left-drawn vowels come out in typed order
|
|
@@ -51,22 +53,31 @@ Demo + free API: [muyleanging/Chakkhu-OCR-Demo](https://huggingface.co/spaces/mu
|
|
| 51 |
|---|---|---|---|
|
| 52 |
| Tesseract 5 (khm+eng, best) | | 20.55% | 16.5% |
|
| 53 |
| Netra-OCR | includes research-only data | 5.87% | 56.9% |
|
| 54 |
-
| Chakkhu
|
| 55 |
-
|
|
|
|
|
| 56 |
| Anaksor-OCR (rec-v4) | includes unlicensed / research-only data | 2.39% | 72.1% |
|
| 57 |
|
| 58 |
By picture kind (CER %):
|
| 59 |
|
| 60 |
-
| KHOB task | Netra-OCR | Chakkhu
|
| 61 |
-
|---|---|---|---|---|
|
| 62 |
-
| clean document | 5.02 | 2.
|
| 63 |
-
| sent through Messenger | 6.16 | 2.
|
| 64 |
-
| scanned | 4.55 | 2.
|
| 65 |
-
| phone-scanned | 4.13 | 3.
|
| 66 |
-
| street, day | 5.78 |
|
| 67 |
-
| street, night | 10.64 | 10.
|
| 68 |
-
| short lines (≤ 10 chars,
|
| 69 |
-
| English / numbers only (474 lines) |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 70 |
|
| 71 |
[Anaksor-OCR](https://huggingface.co/Sokheng/anaksor-ocr) (SVTRv2-B, fine-tuned from a large pretrained model) is the most
|
| 72 |
accurate Khmer recognizer we know of; its training data includes KhmerST, khmer-hanuman-100k and KhmerSynthetic1M,
|
|
@@ -76,15 +87,14 @@ All models were scored by us with the same script, the same line crops and the s
|
|
| 76 |
(`chakkhu/khnormal.py`: one fixed order inside every cluster, split vowels joined, invisible characters removed —
|
| 77 |
NFC alone does not do this for Khmer). KHOB level-1 tasks 2–4 use the task-1 boxes aligned to each picture; two
|
| 78 |
pages that show a different letter were left out. The reader's CTC weight (0.5) was set before scoring; 0.3 and
|
| 79 |
-
0.7 give
|
| 80 |
|
| 81 |
**Old government documents:** the previous version read 12 held-out pages of 1993–2003 decrees at 2.09% CER. Those
|
| 82 |
test pages were not available for this version, so it was not measured again; on KHOB's government documents its
|
| 83 |
error rate is a little lower than before.
|
| 84 |
|
| 85 |
-
**Weaker on:** night street photos, curved and vertical text (round seals, logos),
|
| 86 |
-
|
| 87 |
-
lines in general. Handwriting: some (2,311 real lines in training), not measured yet.
|
| 88 |
|
| 89 |
## How it works
|
| 90 |
|
|
@@ -127,6 +137,11 @@ model, tok = load(folder) # CPU; load(folder, devi
|
|
| 127 |
print(read(model, tok, ["line.png"])) # one picture = one text line
|
| 128 |
print(read(model, tok, ["line.png"], confidence=True)) # [("…", 0.98)]
|
| 129 |
# read(..., beam=0) → faster, CTC head only
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 130 |
```
|
| 131 |
|
| 132 |
Whole pages: the [demo](https://huggingface.co/spaces/muyleanging/Chakkhu-OCR-Demo) has a line finder, and a free API:
|
|
@@ -140,10 +155,11 @@ c.predict(handle_file("page.jpg"), "page", api_name="/read")
|
|
| 140 |
|
| 141 |
## Training
|
| 142 |
|
| 143 |
-
|
| 144 |
continuation on an Apple M4 Pro laptop with a new **sign** picture style, and a 3-hour continuation on the same
|
| 145 |
laptop with **engraved signs** (metal letters set into stone and concrete, carved edges, cracks, worn paint),
|
| 146 |
-
words set far apart and Khmer sign names of 2–4 words
|
|
|
|
| 147 |
|
| 148 |
**Training data:** [Chakkhu-OCR-Khmer-Data](https://huggingface.co/datasets/muyleanging/Chakkhu-OCR-Khmer-Data)
|
| 149 |
(303k drawn lines, the text they come from, and a download script for the open sets below; access on request).
|
|
@@ -176,7 +192,9 @@ words set far apart and Khmer sign names of 2–4 words.
|
|
| 176 |
| Run 2 (continuation, + old-document lines) | 1 hour · learning rate 2e-4, warm-up 500 steps |
|
| 177 |
| Run 3 (continuation, + sign style) | 6 hours · 54k steps · 1.6M lines · learning rate 4e-4 · fp32 · batch ≤ 48 (wide lines in smaller batches) · 76 lines/s |
|
| 178 |
| Run 4 (continuation, + engraved signs) | 3 hours · 28k steps · 0.84M lines · learning rate 2e-4, warm-up 500 steps · fp32 · batch ≤ 48 · 78 lines/s |
|
| 179 |
-
|
|
|
|
|
|
|
|
| 180 |
| Speed | reading ~20 ms per line on a GPU, ~140 ms on a laptop CPU |
|
| 181 |
| Parameters | 18.6M (weights 74 MB) |
|
| 182 |
|
|
@@ -194,7 +212,7 @@ If you use Chakkhu, please cite it:
|
|
| 194 |
year = {2026},
|
| 195 |
publisher = {Hugging Face},
|
| 196 |
howpublished = {\url{https://huggingface.co/muyleanging/Chakkhu-OCR-Khmer}},
|
| 197 |
-
note = {Model and demo; CER
|
| 198 |
}
|
| 199 |
```
|
| 200 |
|
|
|
|
| 22 |
name: KHOB (all 4,018 lines)
|
| 23 |
metrics:
|
| 24 |
- type: cer
|
| 25 |
+
value: 3.58
|
| 26 |
+
name: CER (%) with the word checker
|
| 27 |
- type: accuracy
|
| 28 |
+
value: 64.7
|
| 29 |
name: Lines fully right (%)
|
| 30 |
---
|
| 31 |
|
|
|
|
| 35 |
typewritten pages, scans, phone photos of paper, screenshots, chat pictures and signs. It is small
|
| 36 |
(18.6M parameters), runs on a CPU, and tells you **how sure it is** about every line.
|
| 37 |
|
| 38 |
+
- **3.58% character error rate** on the full [KHOB benchmark](https://github.com/EKYCSolutions/khmer-ocr-benchmark-dataset) (all 4,018 real text lines, never trained on) with the new **Khmer word checker**; 3.89% without it; Netra-OCR 5.87%
|
| 39 |
+
- **new in this version:**
|
| 40 |
+
- a **Khmer word checker** (`checker/`, CPU, no extra model): a letter-cluster language model built from our clean training text picks among the reader's guesses and proposes spelling fixes, and every fix is checked against the picture again (`សេដ្ឋកិបូ → សេដ្ឋកិច្ច`, `អប់រិយុវជននឹងកីព្យា → អប់រំយុវជននិងកីឡា`)
|
| 41 |
+
- trained with **detector-style crops** (tilted, cut too tight or too loose, like a text detector makes them), **spaced capitals** (`H A N O I`) and more CAPITAL signs: better on every KHOB task (daylight street 4.49%, was 4.93%)
|
| 42 |
- a **confidence** (0–1) for every line, to decide which lines a person should check
|
| 43 |
- about 140 ms per line on a laptop CPU, ~20 ms on a GPU
|
| 44 |
- writes whole Khmer letter **clusters** (ស្ត្រី = 1 step), so subscripts and left-drawn vowels come out in typed order
|
|
|
|
| 53 |
|---|---|---|---|
|
| 54 |
| Tesseract 5 (khm+eng, best) | | 20.55% | 16.5% |
|
| 55 |
| Netra-OCR | includes research-only data | 5.87% | 56.9% |
|
| 56 |
+
| Chakkhu full4 (previous version) | clean licenses only | 4.06% | 59.8% |
|
| 57 |
+
| Chakkhu full5 (this version, reader only) | clean licenses only | 3.89% | 60.7% |
|
| 58 |
+
| **Chakkhu full5 + word checker** | **clean licenses only** | **3.58%** | **64.7%** |
|
| 59 |
| Anaksor-OCR (rec-v4) | includes unlicensed / research-only data | 2.39% | 72.1% |
|
| 60 |
|
| 61 |
By picture kind (CER %):
|
| 62 |
|
| 63 |
+
| KHOB task | Netra-OCR | Chakkhu full4 | Chakkhu full5 | **full5 + checker** | Anaksor-OCR |
|
| 64 |
+
|---|---|---|---|---|---|
|
| 65 |
+
| clean document | 5.02 | 2.16 | 2.07 | **1.77** | 1.13 |
|
| 66 |
+
| sent through Messenger | 6.16 | 2.66 | 2.55 | **2.13** | 1.38 |
|
| 67 |
+
| scanned | 4.55 | 2.35 | 2.31 | **2.02** | 1.32 |
|
| 68 |
+
| phone-scanned | 4.13 | 3.02 | 2.91 | **2.40** | 1.45 |
|
| 69 |
+
| street, day | 5.78 | 4.93 | 4.47 | **4.24** | 2.15 |
|
| 70 |
+
| street, night | 10.64 | 10.51 | 10.35 | **10.23** | 7.95 |
|
| 71 |
+
| short lines (≤ 10 chars, 455 lines) | | **7.67** | 8.39 | 8.56 | |
|
| 72 |
+
| English / numbers only (474 lines) | | 20.13 | 19.02 | **18.62** | |
|
| 73 |
+
|
| 74 |
+
Short lines are a little worse than full4 (one-word signs; the checker has little text to work with there).
|
| 75 |
+
**Whole street photos** (the demo's Photo mode on 120 KHOB street photos: find the text, then read it): full4 24.0%,
|
| 76 |
+
full5 23.0% character errors. The checker is not used in Photo mode, where it did not help (23.3%).
|
| 77 |
+
|
| 78 |
+
**How the checker was tested fairly:** every KHOB sentence was removed from the checker's text before testing, and its
|
| 79 |
+
settings were tuned on one half of the lines and scored on the other half (and the other way round). The published
|
| 80 |
+
checker is built from all of our training text.
|
| 81 |
|
| 82 |
[Anaksor-OCR](https://huggingface.co/Sokheng/anaksor-ocr) (SVTRv2-B, fine-tuned from a large pretrained model) is the most
|
| 83 |
accurate Khmer recognizer we know of; its training data includes KhmerST, khmer-hanuman-100k and KhmerSynthetic1M,
|
|
|
|
| 87 |
(`chakkhu/khnormal.py`: one fixed order inside every cluster, split vowels joined, invisible characters removed —
|
| 88 |
NFC alone does not do this for Khmer). KHOB level-1 tasks 2–4 use the task-1 boxes aligned to each picture; two
|
| 89 |
pages that show a different letter were left out. The reader's CTC weight (0.5) was set before scoring; 0.3 and
|
| 90 |
+
0.7 give 3.95% and 3.93% (full5). Tesseract was scored on 2026-11-10, the others on 2026-11-15/17 (KHOB release of 2026-01-31).
|
| 91 |
|
| 92 |
**Old government documents:** the previous version read 12 held-out pages of 1993–2003 decrees at 2.09% CER. Those
|
| 93 |
test pages were not available for this version, so it was not measured again; on KHOB's government documents its
|
| 94 |
error rate is a little lower than before.
|
| 95 |
|
| 96 |
+
**Weaker on:** night street photos, curved and vertical text (round seals, logos), very short sign words, decorative
|
| 97 |
+
fonts, and English-only lines in general. Handwriting: some (2,311 real lines in training), not measured yet.
|
|
|
|
| 98 |
|
| 99 |
## How it works
|
| 100 |
|
|
|
|
| 137 |
print(read(model, tok, ["line.png"])) # one picture = one text line
|
| 138 |
print(read(model, tok, ["line.png"], confidence=True)) # [("…", 0.98)]
|
| 139 |
# read(..., beam=0) → faster, CTC head only
|
| 140 |
+
|
| 141 |
+
# + the Khmer word checker (about 1.5× slower, fewer spelling mistakes)
|
| 142 |
+
from chakkhu import Checker
|
| 143 |
+
checker = Checker.load(f"{folder}/checker")
|
| 144 |
+
print(read(model, tok, ["line.png"], checker=checker))
|
| 145 |
```
|
| 146 |
|
| 147 |
Whole pages: the [demo](https://huggingface.co/spaces/muyleanging/Chakkhu-OCR-Demo) has a line finder, and a free API:
|
|
|
|
| 155 |
|
| 156 |
## Training
|
| 157 |
|
| 158 |
+
Five runs: from scratch (4 h on a rented GPU), a 1-hour continuation with old-document data, a 6-hour
|
| 159 |
continuation on an Apple M4 Pro laptop with a new **sign** picture style, and a 3-hour continuation on the same
|
| 160 |
laptop with **engraved signs** (metal letters set into stone and concrete, carved edges, cracks, worn paint),
|
| 161 |
+
words set far apart and Khmer sign names of 2–4 words, then a 3-hour run with **detector-style crops**,
|
| 162 |
+
spaced capitals and more CAPITAL signs.
|
| 163 |
|
| 164 |
**Training data:** [Chakkhu-OCR-Khmer-Data](https://huggingface.co/datasets/muyleanging/Chakkhu-OCR-Khmer-Data)
|
| 165 |
(303k drawn lines, the text they come from, and a download script for the open sets below; access on request).
|
|
|
|
| 192 |
| Run 2 (continuation, + old-document lines) | 1 hour · learning rate 2e-4, warm-up 500 steps |
|
| 193 |
| Run 3 (continuation, + sign style) | 6 hours · 54k steps · 1.6M lines · learning rate 4e-4 · fp32 · batch ≤ 48 (wide lines in smaller batches) · 76 lines/s |
|
| 194 |
| Run 4 (continuation, + engraved signs) | 3 hours · 28k steps · 0.84M lines · learning rate 2e-4, warm-up 500 steps · fp32 · batch ≤ 48 · 78 lines/s |
|
| 195 |
+
| Run 5 (continuation, + detector crops, spaced capitals) | 3 hours · 27k steps · 0.83M lines · learning rate 2e-4, warm-up 500 steps · fp32 · batch ≤ 48 |
|
| 196 |
+
| Word checker | cluster 5-gram language model from the training text (593k lines), built in 35 s on a CPU; 30 MB |
|
| 197 |
+
| Total | about **5 GPU-hours + 12 laptop-hours** |
|
| 198 |
| Speed | reading ~20 ms per line on a GPU, ~140 ms on a laptop CPU |
|
| 199 |
| Parameters | 18.6M (weights 74 MB) |
|
| 200 |
|
|
|
|
| 212 |
year = {2026},
|
| 213 |
publisher = {Hugging Face},
|
| 214 |
howpublished = {\url{https://huggingface.co/muyleanging/Chakkhu-OCR-Khmer}},
|
| 215 |
+
note = {Model and demo; CER 3.58\% on the KHOB benchmark}
|
| 216 |
}
|
| 217 |
```
|
| 218 |
|
assets/results.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
chakkhu/__init__.py
CHANGED
|
@@ -16,7 +16,8 @@ import torch
|
|
| 16 |
from PIL import Image
|
| 17 |
from rapidfuzz.distance import Levenshtein
|
| 18 |
|
| 19 |
-
from .
|
|
|
|
| 20 |
from .model import Chakkhu, Config
|
| 21 |
from .tokenizer import ClusterTokenizer, normalize
|
| 22 |
|
|
@@ -47,11 +48,14 @@ def to_line(img: Image.Image) -> Image.Image:
|
|
| 47 |
|
| 48 |
|
| 49 |
@torch.no_grad()
|
| 50 |
-
def read(model, tok, images, beam: int = 4, lam: float = 0.5, batch: int = 16, confidence: bool = False
|
|
|
|
| 51 |
"""images: file paths or PIL images, one text line each. Reads with BOTH heads (decoder beam + CTC check).
|
| 52 |
beam=0 → fast CTC-only reading.
|
| 53 |
confidence=True → list of (text, confidence 0–1). Confidence = how much the two heads agree × how sure the
|
| 54 |
-
CTC columns are. On old printed pages: the most sure half of lines had 0.7% errors, the least sure 10% had 9%.
|
|
|
|
|
|
|
| 55 |
dev = next(model.parameters()).device
|
| 56 |
lines = [to_line(Image.open(i) if isinstance(i, (str, Path)) else i) for i in images]
|
| 57 |
order = sorted(range(len(lines)), key=lambda k: lines[k].width)
|
|
@@ -66,7 +70,16 @@ def read(model, tok, images, beam: int = 4, lam: float = 0.5, batch: int = 16, c
|
|
| 66 |
x[j, 0, :, : im.width] = torch.frombuffer(bytearray(im.tobytes()), dtype=torch.uint8).view(HEIGHT, im.width) / 255
|
| 67 |
w = torch.tensor([im.width for im in part])
|
| 68 |
x, w = x.to(dev), w.to(dev)
|
| 69 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 70 |
res, drafts = joint_read(model, x, w, k=beam, lams=(lam,))
|
| 71 |
ids = res[lam]
|
| 72 |
else:
|
|
@@ -76,7 +89,7 @@ def read(model, tok, images, beam: int = 4, lam: float = 0.5, batch: int = 16, c
|
|
| 76 |
_, _, lp, lens = model.encode(x, w)
|
| 77 |
best = lp.exp().max(-1).values
|
| 78 |
for j, (k, i) in enumerate(zip(idx, ids)):
|
| 79 |
-
out[k] = normalize(tok.decode(i))
|
| 80 |
if confidence:
|
| 81 |
d = normalize(tok.decode(drafts[j]))
|
| 82 |
agree = 1 - Levenshtein.normalized_distance(out[k], d)
|
|
@@ -84,4 +97,4 @@ def read(model, tok, images, beam: int = 4, lam: float = 0.5, batch: int = 16, c
|
|
| 84 |
return list(zip(out, conf)) if confidence else out
|
| 85 |
|
| 86 |
|
| 87 |
-
__all__ = ["load", "read", "Chakkhu", "Config", "ClusterTokenizer"]
|
|
|
|
| 16 |
from PIL import Image
|
| 17 |
from rapidfuzz.distance import Levenshtein
|
| 18 |
|
| 19 |
+
from .checker import Checker
|
| 20 |
+
from .decode import decoder_beam, joint_read, score_guesses
|
| 21 |
from .model import Chakkhu, Config
|
| 22 |
from .tokenizer import ClusterTokenizer, normalize
|
| 23 |
|
|
|
|
| 48 |
|
| 49 |
|
| 50 |
@torch.no_grad()
|
| 51 |
+
def read(model, tok, images, beam: int = 4, lam: float = 0.5, batch: int = 16, confidence: bool = False,
|
| 52 |
+
checker: Checker | None = None):
|
| 53 |
"""images: file paths or PIL images, one text line each. Reads with BOTH heads (decoder beam + CTC check).
|
| 54 |
beam=0 → fast CTC-only reading.
|
| 55 |
confidence=True → list of (text, confidence 0–1). Confidence = how much the two heads agree × how sure the
|
| 56 |
+
CTC columns are. On old printed pages: the most sure half of lines had 0.7% errors, the least sure 10% had 9%.
|
| 57 |
+
checker=Checker.load(folder) → the Khmer word checker picks among the guesses and proposes spelling fixes,
|
| 58 |
+
each scored against the picture (KHOB with full5: 3.90% → 3.58% CER)."""
|
| 59 |
dev = next(model.parameters()).device
|
| 60 |
lines = [to_line(Image.open(i) if isinstance(i, (str, Path)) else i) for i in images]
|
| 61 |
order = sorted(range(len(lines)), key=lambda k: lines[k].width)
|
|
|
|
| 70 |
x[j, 0, :, : im.width] = torch.frombuffer(bytearray(im.tobytes()), dtype=torch.uint8).view(HEIGHT, im.width) / 255
|
| 71 |
w = torch.tensor([im.width for im in part])
|
| 72 |
x, w = x.to(dev), w.to(dev)
|
| 73 |
+
texts = None
|
| 74 |
+
if beam and checker is not None:
|
| 75 |
+
memory, mem_pad, lp, lens = model.encode(x, w)
|
| 76 |
+
drafts = model.ctc_greedy(lp, lens)
|
| 77 |
+
beams = decoder_beam(model, memory, mem_pad, [int(1.5 * len(d)) + 4 for d in drafts], beam)
|
| 78 |
+
guesses = [[list(b) for b in bs] + ([d] if d not in [list(b) for b in bs] else []) for bs, d in zip(beams, drafts)]
|
| 79 |
+
scored = score_guesses(model, memory, mem_pad, lp, lens, guesses)
|
| 80 |
+
texts = checker.choose(tok, model, memory, mem_pad, lp, lens, scored)
|
| 81 |
+
ids = [None] * len(texts)
|
| 82 |
+
elif beam:
|
| 83 |
res, drafts = joint_read(model, x, w, k=beam, lams=(lam,))
|
| 84 |
ids = res[lam]
|
| 85 |
else:
|
|
|
|
| 89 |
_, _, lp, lens = model.encode(x, w)
|
| 90 |
best = lp.exp().max(-1).values
|
| 91 |
for j, (k, i) in enumerate(zip(idx, ids)):
|
| 92 |
+
out[k] = texts[j] if texts is not None else normalize(tok.decode(i))
|
| 93 |
if confidence:
|
| 94 |
d = normalize(tok.decode(drafts[j]))
|
| 95 |
agree = 1 - Levenshtein.normalized_distance(out[k], d)
|
|
|
|
| 97 |
return list(zip(out, conf)) if confidence else out
|
| 98 |
|
| 99 |
|
| 100 |
+
__all__ = ["load", "read", "Chakkhu", "Config", "ClusterTokenizer", "Checker"]
|
chakkhu/checker.py
ADDED
|
@@ -0,0 +1,309 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
"""Khmer word checker: a small cluster n-gram language model that knows which Khmer spellings are real.
|
| 2 |
+
|
| 3 |
+
The reader already writes ~5 guesses per line (decoder beam + CTC draft), each with two image scores.
|
| 4 |
+
The checker adds a third score, "how much does this look like real Khmer text", and the best total wins:
|
| 5 |
+
|
| 6 |
+
total = λ·CTC + (1−λ)·decoder + μ·(LM + β·clusters)
|
| 7 |
+
|
| 8 |
+
So the checker can only choose among guesses the picture supports; it never rewrites text on its own.
|
| 9 |
+
The LM is built from our own clean training text only (Akkhara sentences, Khmer Wikipedia, sign words).
|
| 10 |
+
|
| 11 |
+
Case-blind: Latin text is lower-cased before scoring, so CAPS vs lowercase is left to the picture.
|
| 12 |
+
|
| 13 |
+
Storage: each n-gram of cluster ids is packed into one int64 (13 bits per id, order ≤ 4 + ...).
|
| 14 |
+
Counts are sorted arrays, looked up with np.searchsorted, so it is small and fast on the CPU.
|
| 15 |
+
"""
|
| 16 |
+
from __future__ import annotations
|
| 17 |
+
|
| 18 |
+
import math
|
| 19 |
+
import re
|
| 20 |
+
from pathlib import Path
|
| 21 |
+
|
| 22 |
+
import numpy as np
|
| 23 |
+
|
| 24 |
+
from .tokenizer import clusters, normalize
|
| 25 |
+
|
| 26 |
+
BITS = 13 # cluster ids < 8192
|
| 27 |
+
BOS_ID, EOS_ID, UNK_ID = 1, 2, 3 # our own ids inside the LM (0 = padding)
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
class ClusterLM:
|
| 31 |
+
def __init__(self, vocab: dict[str, int], keys: list[np.ndarray], counts: list[np.ndarray], order: int):
|
| 32 |
+
self.vocab, self.keys, self.counts, self.order = vocab, keys, counts, order
|
| 33 |
+
# context totals: for n-gram order n, total count of its (n-1) prefix is stored in the order n-1 table
|
| 34 |
+
self.total1 = float(counts[0].sum())
|
| 35 |
+
|
| 36 |
+
# ---------- build ----------
|
| 37 |
+
@classmethod
|
| 38 |
+
def build(cls, lines, order: int = 5, min_vocab: int = 2) -> "ClusterLM":
|
| 39 |
+
from collections import Counter
|
| 40 |
+
cc = Counter()
|
| 41 |
+
seqs = []
|
| 42 |
+
for line in lines:
|
| 43 |
+
cl = clusters(normalize(line.strip()).lower())
|
| 44 |
+
if cl:
|
| 45 |
+
cc.update(cl)
|
| 46 |
+
seqs.append(cl)
|
| 47 |
+
vocab = {c: i + 4 for i, (c, n) in enumerate(cc.most_common()) if n >= min_vocab}
|
| 48 |
+
assert len(vocab) + 4 < (1 << BITS), len(vocab)
|
| 49 |
+
ids = []
|
| 50 |
+
for cl in seqs:
|
| 51 |
+
ids.extend([BOS_ID] + [vocab.get(c, UNK_ID) for c in cl] + [EOS_ID, 0]) # 0 separates lines
|
| 52 |
+
arr = np.array(ids, dtype=np.int64)
|
| 53 |
+
keys, counts = [], []
|
| 54 |
+
for n in range(1, order + 1):
|
| 55 |
+
if len(arr) < n:
|
| 56 |
+
break
|
| 57 |
+
packed = np.zeros(len(arr) - n + 1, dtype=np.int64)
|
| 58 |
+
ok = np.ones(len(arr) - n + 1, dtype=bool)
|
| 59 |
+
for j in range(n):
|
| 60 |
+
part = arr[j: len(arr) - n + 1 + j]
|
| 61 |
+
packed = (packed << BITS) | part
|
| 62 |
+
ok &= part != 0
|
| 63 |
+
k, c = np.unique(packed[ok], return_counts=True)
|
| 64 |
+
keys.append(k)
|
| 65 |
+
counts.append(c.astype(np.int64))
|
| 66 |
+
return cls(vocab, keys, counts, order)
|
| 67 |
+
|
| 68 |
+
def save(self, path):
|
| 69 |
+
np.savez_compressed(path, order=self.order, vocab=np.array(list(self.vocab.keys())),
|
| 70 |
+
vocab_ids=np.array(list(self.vocab.values())),
|
| 71 |
+
**{f"k{n}": k for n, k in enumerate(self.keys)},
|
| 72 |
+
**{f"c{n}": c for n, c in enumerate(self.counts)})
|
| 73 |
+
|
| 74 |
+
@classmethod
|
| 75 |
+
def load(cls, path) -> "ClusterLM":
|
| 76 |
+
z = np.load(path, allow_pickle=False)
|
| 77 |
+
order = int(z["order"])
|
| 78 |
+
vocab = dict(zip(z["vocab"].tolist(), z["vocab_ids"].tolist()))
|
| 79 |
+
n = sum(1 for f in z.files if f.startswith("k"))
|
| 80 |
+
return cls(vocab, [z[f"k{i}"] for i in range(n)], [z[f"c{i}"] for i in range(n)], order)
|
| 81 |
+
|
| 82 |
+
# ---------- score ----------
|
| 83 |
+
def _count(self, gram: tuple[int, ...]) -> int:
|
| 84 |
+
n = len(gram)
|
| 85 |
+
key = 0
|
| 86 |
+
for g in gram:
|
| 87 |
+
key = (key << BITS) | g
|
| 88 |
+
k = self.keys[n - 1]
|
| 89 |
+
i = np.searchsorted(k, key)
|
| 90 |
+
return int(self.counts[n - 1][i]) if i < len(k) and k[i] == key else 0
|
| 91 |
+
|
| 92 |
+
def _ids(self, text):
|
| 93 |
+
return [BOS_ID] + [self.vocab.get(c, UNK_ID) for c in clusters(normalize(text).lower())] + [EOS_ID]
|
| 94 |
+
|
| 95 |
+
def token_logps(self, ids, alpha: float = 0.4) -> list[float]:
|
| 96 |
+
"""Stupid-backoff log probability of each id after the first (natural log)."""
|
| 97 |
+
out = []
|
| 98 |
+
for t in range(1, len(ids)):
|
| 99 |
+
pen = 0.0
|
| 100 |
+
for n in range(min(self.order, t + 1), 0, -1):
|
| 101 |
+
gram = tuple(ids[t - n + 1: t + 1])
|
| 102 |
+
c = self._count(gram)
|
| 103 |
+
if c:
|
| 104 |
+
ctx = self._count(gram[:-1]) if n > 1 else self.total1
|
| 105 |
+
out.append(pen + math.log(c / ctx))
|
| 106 |
+
break
|
| 107 |
+
pen += math.log(alpha)
|
| 108 |
+
else:
|
| 109 |
+
out.append(pen + math.log(0.5 / self.total1))
|
| 110 |
+
return out
|
| 111 |
+
|
| 112 |
+
def logp(self, text: str, alpha: float = 0.4) -> float:
|
| 113 |
+
"""Stupid-backoff log probability (natural log) of a whole line, including its end."""
|
| 114 |
+
return sum(self.token_logps(self._ids(text), alpha))
|
| 115 |
+
|
| 116 |
+
def next_ids(self, ctx: list[int], top: int = 5) -> list[int]:
|
| 117 |
+
"""Most likely next cluster ids after this context (longest context that was seen)."""
|
| 118 |
+
for n in range(min(self.order, len(ctx) + 1), 1, -1):
|
| 119 |
+
pre = 0
|
| 120 |
+
for g in ctx[len(ctx) - n + 1:]:
|
| 121 |
+
pre = (pre << BITS) | g
|
| 122 |
+
k = self.keys[n - 1]
|
| 123 |
+
lo, hi = np.searchsorted(k, pre << BITS), np.searchsorted(k, (pre + 1) << BITS)
|
| 124 |
+
if hi > lo:
|
| 125 |
+
c = self.counts[n - 1][lo:hi]
|
| 126 |
+
best = np.argsort(-c)[: top + 2]
|
| 127 |
+
ids = [int(k[lo + i] & ((1 << BITS) - 1)) for i in best]
|
| 128 |
+
return [i for i in ids if i > UNK_ID][:top]
|
| 129 |
+
return []
|
| 130 |
+
|
| 131 |
+
@property
|
| 132 |
+
def inv(self):
|
| 133 |
+
if not hasattr(self, "_inv"):
|
| 134 |
+
self._inv = {i: c for c, i in self.vocab.items()}
|
| 135 |
+
return self._inv
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
# ---------------- spelling-fix proposals ----------------
|
| 139 |
+
LATIN = re.compile(r"[A-Za-z][A-Za-z']*")
|
| 140 |
+
|
| 141 |
+
|
| 142 |
+
def _case_like(word: str, model: str) -> str:
|
| 143 |
+
if model.isupper() and len(model) > 1:
|
| 144 |
+
return word.upper()
|
| 145 |
+
if model[:1].isupper():
|
| 146 |
+
return word[:1].upper() + word[1:]
|
| 147 |
+
return word
|
| 148 |
+
|
| 149 |
+
|
| 150 |
+
class Proposer:
|
| 151 |
+
"""Suggests corrected versions of a read line. The reader then scores each one against the picture."""
|
| 152 |
+
|
| 153 |
+
def __init__(self, lm: ClusterLM, latin_words: dict[str, int]):
|
| 154 |
+
self.lm = lm
|
| 155 |
+
self.words = latin_words
|
| 156 |
+
self.by_len: dict[int, list[str]] = {}
|
| 157 |
+
for w in latin_words:
|
| 158 |
+
self.by_len.setdefault(len(w), []).append(w)
|
| 159 |
+
|
| 160 |
+
def near_words(self, w: str, maxd: int = 2, top: int = 3) -> list[str]:
|
| 161 |
+
from rapidfuzz.distance import Levenshtein
|
| 162 |
+
w = w.lower()
|
| 163 |
+
if w in self.words or len(w) < 3:
|
| 164 |
+
return []
|
| 165 |
+
d = 1 if len(w) <= 4 else maxd
|
| 166 |
+
cands = []
|
| 167 |
+
for L in range(len(w) - d, len(w) + d + 1):
|
| 168 |
+
for v in self.by_len.get(L, ()):
|
| 169 |
+
e = Levenshtein.distance(w, v, score_cutoff=d)
|
| 170 |
+
if e <= d:
|
| 171 |
+
cands.append((e, -self.words[v], v))
|
| 172 |
+
return [v for _, _, v in sorted(cands)[:top]]
|
| 173 |
+
|
| 174 |
+
def latin_fixes(self, text: str) -> list[str]:
|
| 175 |
+
out = []
|
| 176 |
+
for m in LATIN.finditer(text):
|
| 177 |
+
w = m.group()
|
| 178 |
+
for v in self.near_words(w):
|
| 179 |
+
out.append(text[: m.start()] + _case_like(v, w) + text[m.end():])
|
| 180 |
+
if len(w) >= 6 and w.lower() not in self.words: # stuck-together words: MODARKING → NO PARKING
|
| 181 |
+
for i in range(2, len(w) - 1):
|
| 182 |
+
a, b = w[:i], w[i:]
|
| 183 |
+
va = [a.lower()] if a.lower() in self.words else self.near_words(a, 1, 1)
|
| 184 |
+
vb = [b.lower()] if b.lower() in self.words else self.near_words(b, 1, 1)
|
| 185 |
+
if va and vb and len(va[0]) >= 2:
|
| 186 |
+
out.append(text[: m.start()] + _case_like(va[0], a) + " " + _case_like(vb[0], b) + text[m.end():])
|
| 187 |
+
return out
|
| 188 |
+
|
| 189 |
+
def khmer_fixes(self, text: str, n_pos: int = 6, top: int = 4) -> list[str]:
|
| 190 |
+
"""At the most surprising clusters: swap in the clusters the LM expects, or drop the cluster."""
|
| 191 |
+
cl = clusters(normalize(text))
|
| 192 |
+
if not cl:
|
| 193 |
+
return []
|
| 194 |
+
ids = [BOS_ID] + [self.lm.vocab.get(c.lower(), UNK_ID) for c in cl] + [EOS_ID]
|
| 195 |
+
lps = self.lm.token_logps(ids) # lps[t] = logp of ids[t+1] = cluster t (last one = end)
|
| 196 |
+
pos = [t for t in sorted(range(len(cl)), key=lambda t: lps[t]) if re.match(r"[ក-]", cl[t])][:n_pos]
|
| 197 |
+
out = []
|
| 198 |
+
for t in pos:
|
| 199 |
+
for j in self.lm.next_ids(ids[: t + 1], top):
|
| 200 |
+
c = self.lm.inv[j]
|
| 201 |
+
if c != cl[t].lower():
|
| 202 |
+
out.append("".join(cl[:t] + [c] + cl[t + 1:])) # replace
|
| 203 |
+
out.append("".join(cl[:t] + [c] + cl[t:])) # insert before
|
| 204 |
+
out.append("".join(cl[:t] + cl[t + 1:])) # drop
|
| 205 |
+
return out
|
| 206 |
+
|
| 207 |
+
def propose(self, text: str, limit: int = 60) -> list[str]:
|
| 208 |
+
seen, out = {text}, []
|
| 209 |
+
for v in self.latin_fixes(text) + self.khmer_fixes(text):
|
| 210 |
+
v = normalize(v)
|
| 211 |
+
if v not in seen and v.strip():
|
| 212 |
+
seen.add(v)
|
| 213 |
+
out.append(v)
|
| 214 |
+
return out[:limit]
|
| 215 |
+
|
| 216 |
+
|
| 217 |
+
def latin_words(root: Path, lm_text_files=None) -> dict[str, int]:
|
| 218 |
+
"""English / sign word counts: our word lists + Latin words seen ≥3 times in the training text."""
|
| 219 |
+
from collections import Counter
|
| 220 |
+
words = Counter()
|
| 221 |
+
for l in (root / "hf/data/text/english_words.tsv").read_text(encoding="utf-8").splitlines()[1:]:
|
| 222 |
+
w, _, c = l.partition("\t")
|
| 223 |
+
if w.isascii() and w.isalpha():
|
| 224 |
+
words[w.lower()] += int(c or 1)
|
| 225 |
+
for l in (root / "hf/data/text/sign_words.txt").read_text(encoding="utf-8").splitlines():
|
| 226 |
+
for w in LATIN.findall(l):
|
| 227 |
+
words[w.lower()] += 1000
|
| 228 |
+
seen = Counter()
|
| 229 |
+
for f in lm_text_files or []:
|
| 230 |
+
for l in Path(f).read_text(encoding="utf-8").splitlines():
|
| 231 |
+
seen.update(w.lower() for w in LATIN.findall(l))
|
| 232 |
+
for w, c in seen.items():
|
| 233 |
+
if c >= 3:
|
| 234 |
+
words[w] += c
|
| 235 |
+
return dict(words)
|
| 236 |
+
|
| 237 |
+
|
| 238 |
+
def pick(guesses, lm: ClusterLM, lam: float = 0.5, mu: float = 0.0, beta: float = 0.0):
|
| 239 |
+
"""guesses: [(text, decoder_logp, ctc_logp)]. Returns the chosen text."""
|
| 240 |
+
def total(g):
|
| 241 |
+
s = lam * g[2] + (1 - lam) * g[1]
|
| 242 |
+
if mu:
|
| 243 |
+
s += mu * (lm.logp(g[0]) + beta * len(clusters(g[0])))
|
| 244 |
+
return s
|
| 245 |
+
return max(guesses, key=total)[0]
|
| 246 |
+
|
| 247 |
+
|
| 248 |
+
def default_text_files(root: Path):
|
| 249 |
+
return [root / "hf/data/text/khmer_sentences.txt", root / "hf/data/text/khmer_wiki.txt",
|
| 250 |
+
root / "hf/data/text/sign_words.txt"]
|
| 251 |
+
|
| 252 |
+
|
| 253 |
+
class Checker:
|
| 254 |
+
"""The whole word checker for live reading: pick + spelling-fix proposals scored against the picture.
|
| 255 |
+
|
| 256 |
+
Settings come from the fair KHOB test (tuned on one half, scored on the other): μ .3, β 6, γ 1 per proposal.
|
| 257 |
+
"""
|
| 258 |
+
|
| 259 |
+
def __init__(self, lm: ClusterLM, words: dict[str, int], mu=.3, beta=6., gamma=1., lam=.5, rounds=2):
|
| 260 |
+
self.lm, self.prop = lm, Proposer(lm, words)
|
| 261 |
+
self.mu, self.beta, self.gamma, self.lam, self.rounds = mu, beta, gamma, lam, rounds
|
| 262 |
+
self.changed: set[str] = set() # texts the checker chose over the reader's own pick
|
| 263 |
+
|
| 264 |
+
@classmethod
|
| 265 |
+
def load(cls, folder, **kw) -> "Checker":
|
| 266 |
+
import json
|
| 267 |
+
folder = Path(folder)
|
| 268 |
+
return cls(ClusterLM.load(folder / "checker_lm.npz"),
|
| 269 |
+
json.loads((folder / "latin_words.json").read_text(encoding="utf-8")), **kw)
|
| 270 |
+
|
| 271 |
+
def total(self, g):
|
| 272 |
+
"""g = (text, decoder_logp, ctc_logp, is_proposal)"""
|
| 273 |
+
return (self.lam * g[2] + (1 - self.lam) * g[1]
|
| 274 |
+
+ self.mu * (self.lm.logp(g[0]) + self.beta * len(clusters(g[0]))) - self.gamma * g[3])
|
| 275 |
+
|
| 276 |
+
def choose(self, tok, model, memory, mem_pad, ctc_lp, lens, scored):
|
| 277 |
+
"""scored: per line [(ids, dec, ctc)] from score_guesses. Returns per line the chosen text."""
|
| 278 |
+
from .decode import score_guesses
|
| 279 |
+
cands = [[(normalize(tok.decode(i)), d, c, 0) for i, d, c in s] for s in scored]
|
| 280 |
+
for rnd in range(1, self.rounds + 1):
|
| 281 |
+
want = []
|
| 282 |
+
for cs in cands:
|
| 283 |
+
if rnd == 1:
|
| 284 |
+
bases = [g[0] for g in sorted(cs, key=lambda g: -(g[1] + g[2]))[:2]]
|
| 285 |
+
else:
|
| 286 |
+
bases = [max(cs, key=self.total)[0]]
|
| 287 |
+
have, vs = {g[0] for g in cs}, []
|
| 288 |
+
for b in bases:
|
| 289 |
+
for v in self.prop.propose(b):
|
| 290 |
+
if v in have:
|
| 291 |
+
continue
|
| 292 |
+
ids = tok.encode(v)
|
| 293 |
+
if ids and normalize(tok.decode(ids)) == v:
|
| 294 |
+
have.add(v)
|
| 295 |
+
vs.append((v, ids))
|
| 296 |
+
want.append(vs)
|
| 297 |
+
if not any(want):
|
| 298 |
+
break
|
| 299 |
+
sc = score_guesses(model, memory, mem_pad, ctc_lp, lens, [[ids for _, ids in vs] for vs in want])
|
| 300 |
+
for cs, vs, s in zip(cands, want, sc):
|
| 301 |
+
cs += [(v, d, c, 1) for (v, _), (_, d, c) in zip(vs, s)]
|
| 302 |
+
out = []
|
| 303 |
+
for cs in cands:
|
| 304 |
+
best = max(cs, key=self.total)[0]
|
| 305 |
+
plain = max((g for g in cs if not g[3]), key=lambda g: self.lam * g[2] + (1 - self.lam) * g[1])[0]
|
| 306 |
+
if best != plain:
|
| 307 |
+
self.changed.add(best)
|
| 308 |
+
out.append(best)
|
| 309 |
+
return out
|
checker/checker_lm.npz
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:446ae0efb060899b08039fb2def78eeff6e5fe5513da2c928005d3d776c984e9
|
| 3 |
+
size 30443567
|
checker/latin_words.json
ADDED
|
@@ -0,0 +1 @@
|
|
|
|
|
|
|
| 1 |
+
{"bro": 17340, "game": 12694, "ok": 11904, "call": 11774, "chat": 11696, "haha": 11596, "team": 11311, "sorry": 11132, "sis": 10432, "phone": 10615, "fb": 872, "cg": 774, "yt": 631, "tt": 521, "tik": 476, "tok": 476, "live": 438, "post": 388, "tele": 354, "home": 357, "news": 284, "vs": 290, "inbox": 276, "dc": 275, "wifi": 1260, "ig": 254, "video": 255, "present": 253, "samsung": 254, "follow": 252, "wedding": 251, "rap": 246, "rank": 242, "free": 1238, "telegram": 228, "bank": 1234, "check": 227, "exam": 224, "wing": 224, "link": 231, "report": 223, "stock": 220, "page": 222, "delivery": 1219, "party": 225, "next": 220, "feed": 216, "class": 1220, "driver": 213, "set": 213, "meeting": 212, "carry": 210, "squad": 210, "confirm": 210, "slide": 210, "facebook": 215, "ms": 217, "online": 213, "rapper": 204, "update": 204, "test": 200, "pro": 199, "covid": 204, "lunch": 196, "promotion": 1197, "google": 222, "busy": 196, "cafe": 1191, "noob": 186, "boss": 184, "share": 187, "file": 182, "grab": 178, "net": 196, "tiktok": 170, "dinner": 166, "location": 166, "instagram": 166, "aba": 158, "coffee": 1160, "cup": 178, "movie": 156, "single": 156, "send": 155, "bzy": 154, "bd": 165, "hack": 150, "pick": 148, "internship": 148, "meme": 148, "atm": 1149, "soundcheck": 146, "apartment": 1147, "mention": 147, "bio": 144, "usb": 145, "comedy": 142, "pubg": 140, "usdt": 140, "content": 141, "spam": 140, "boost": 140, "lag": 140, "kkk": 140, "champagne": 141, "accessory": 138, "calendar": 138, "dress": 138, "insurance": 139, "sister": 136, "voa": 139, "private": 136, "rock": 150, "topping": 136, "caster": 136, "fresh": 1137, "system": 141, "cen": 134, "code": 138, "motor": 1136, "gym": 132, "lecturer": 132, "retinol": 132, "dollar": 130, "like": 135, "software": 143, "group": 1152, "join": 131, "space": 137, "tracking": 130, "sandwich": 130, "pause": 130, "darling": 131, "hmmm": 130, "picnic": 130, "please": 1131, "absent": 128, "positive": 128, "la": 151, "acleda": 128, "conditioner": 128, "source": 132, "deadline": 128, "reception": 128, "bday": 128, "flirt": 128, "show": 128, "care": 128, "resume": 128, "youtube": 142, "outfit": 129, "policy": 131, "relax": 129, "cctv": 130, "professor": 130, "start": 127, "total": 126, "box": 131, "story": 130, "domain": 130, "charge": 128, "kkkk": 126, "depression": 127, "anime": 126, "adapter": 126, "decline": 126, "poster": 126, "teacher": 126, "jelly": 126, "idol": 127, "massage": 1125, "cheer": 124, "screenshot": 124, "limit": 124, "hihi": 124, "hotdog": 124, "butter": 124, "eyeshadow": 124, "project": 127, "camera": 132, "hotpot": 124, "express": 1131, "submit": 124, "debug": 124, "draft": 125, "discord": 124, "quit": 125, "register": 124, "corset": 124, "scholarship": 124, "pin": 124, "date": 125, "quality": 1125, "peeling": 124, "lazy": 125, "trip": 122, "concert": 125, "laptop": 122, "babe": 122, "alcohol": 122, "open": 2131, "brand": 123, "support": 122, "guide": 123, "react": 122, "photo": 1123, "emoji": 122, "holiday": 122, "loc": 122, "banner": 123, "print": 1123, "profile": 123, "sofa": 122, "essence": 122, "villa": 1123, "lobby": 122, "custom": 120, "powder": 120, "night": 127, "tax": 132, "pancake": 120, "feel": 120, "lecture": 120, "offer": 122, "scrub": 120, "vocal": 120, "quarantine": 120, "cardio": 120, "cart": 120, "build": 121, "device": 124, "restart": 120, "travel": 1123, "inb": 120, "agency": 118, "webcam": 118, "balance": 118, "cfm": 119, "price": 1119, "success": 118, "shipping": 118, "original": 122, "feeling": 120, "shutdown": 118, "lotion": 118, "error": 120, "character": 118, "bestie": 118, "riel": 119, "dimsum": 118, "action": 121, "visa": 118, "cookie": 118, "stage": 118, "streaming": 118, "brief": 116, "leave": 116, "fix": 116, "surprise": 116, "homestay": 116, "hello": 122, "premiere": 116, "diamond": 117, "taxi": 116, "staycation": 116, "save": 121, "comment": 116, "play": 117, "scan": 119, "breakfast": 116, "boots": 116, "jealous": 116, "master": 122, "seafood": 1117, "detox": 116, "jeep": 115, "spoiler": 114, "subscribe": 114, "wallet": 114, "feature": 115, "client": 114, "time": 121, "rfi": 119, "click": 114, "program": 117, "notice": 114, "extra": 114, "boba": 114, "trailer": 114, "sale": 2117, "void": 114, "release": 118, "manager": 115, "ayyy": 114, "assistant": 115, "bill": 122, "trainer": 114, "partner": 114, "claim": 114, "delay": 114, "protein": 114, "brunch": 114, "gmail": 116, "violin": 114, "recruit": 114, "delete": 114, "status": 115, "makeup": 114, "hkhk": 114, "tint": 112, "solar": 114, "sim": 113, "outro": 112, "highlighter": 112, "blush": 112, "assignment": 112, "item": 113, "level": 112, "motherboard": 112, "sexy": 113, "contract": 112, "internet": 119, "revise": 112, "mocktail": 112, "combo": 112, "otp": 112, "blazer": 112, "thank": 1113, "corner": 112, "confess": 112, "receipt": 112, "foodpanda": 112, "account": 114, "roadtrip": 112, "hehe": 112, "boarding": 113, "result": 112, "intern": 110, "major": 117, "band": 111, "smh": 110, "size": 112, "return": 110, "cancel": 110, "burger": 1114, "battery": 110, "esport": 110, "offside": 110, "probation": 110, "soulmate": 110, "selfie": 110, "passport": 110, "upgrade": 111, "hiphop": 110, "debit": 110, "concealer": 110, "scroll": 114, "desktop": 115, "miss": 113, "countdown": 110, "deposit": 110, "checkin": 110, "barista": 110, "buff": 110, "task": 110, "branch": 114, "channel": 117, "lounge": 110, "consult": 110, "logo": 111, "moisturizer": 110, "stream": 110, "unblock": 108, "gamer": 108, "alert": 110, "gps": 109, "switch": 110, "reset": 108, "benefit": 108, "rate": 109, "caramel": 108, "clean": 108, "planner": 108, "quiz": 108, "meta": 114, "degree": 108, "fit": 108, "zoom": 109, "classmate": 108, "keyboard": 109, "computer": 1116, "order": 111, "remake": 108, "ignore": 108, "wtf": 108, "reply": 110, "soft": 111, "daily": 1115, "fail": 108, "urgent": 108, "weekend": 108, "fun": 108, "bot": 109, "freelance": 109, "summary": 109, "advance": 109, "wth": 108, "lord": 110, "reject": 108, "spot": 111, "booking": 108, "fee": 108, "jacket": 108, "hi": 109, "cpu": 117, "buffet": 108, "director": 108, "menu": 109, "lineup": 108, "wow": 108, "oversize": 108, "glow": 106, "refund": 106, "doctor": 108, "pharmacy": 1107, "qr": 109, "sushi": 106, "form": 110, "merch": 106, "chocolate": 106, "subject": 108, "homework": 106, "tournament": 107, "pilates": 106, "messenger": 106, "daddy": 106, "condo": 107, "emergency": 106, "ping": 106, "scope": 106, "reserve": 106, "model": 107, "lipstick": 106, "damage": 108, "rating": 107, "web": 116, "hacker": 108, "asg": 106, "canteen": 106, "couple": 106, "thanks": 106, "skill": 107, "prompt": 107, "shoot": 106, "email": 121, "coach": 106, "piano": 106, "volt": 106, "cousin": 106, "array": 107, "hurt": 107, "overtime": 106, "copy": 1110, "sponsor": 106, "theme": 106, "sensor": 104, "junior": 108, "ticket": 1105, "member": 104, "highway": 105, "back": 107, "airline": 104, "offline": 104, "scene": 106, "botox": 104, "scam": 104, "solo": 111, "clutch": 104, "block": 104, "cashout": 104, "search": 108, "pickup": 104, "timer": 104, "sticker": 104, "staff": 104, "lol": 104, "bbq": 1105, "drama": 104, "clinic": 1105, "omfg": 104, "msg": 104, "frontend": 104, "exchange": 1106, "sneaker": 104, "highlight": 104, "gift": 104, "boxing": 104, "antivirus": 104, "creatine": 104, "fandom": 104, "score": 104, "research": 106, "squat": 104, "spaghetti": 104, "style": 107, "slow": 103, "terminal": 104, "hoodie": 102, "transit": 102, "lock": 102, "resign": 102, "film": 107, "salad": 102, "rider": 102, "creator": 104, "ib": 106, "soda": 102, "message": 105, "serious": 102, "lonely": 102, "charger": 102, "mage": 102, "honey": 102, "filler": 102, "mri": 102, "drone": 102, "benchmark": 102, "healthy": 102, "studio": 1108, "lane": 102, "remix": 102, "viral": 102, "bacon": 103, "promo": 102, "taste": 102, "effect": 103, "hostel": 1103, "voice": 105, "bungalow": 102, "zone": 106, "period": 103, "midterm": 100, "album": 105, "demo": 100, "plot": 100, "skin": 100, "signal": 100, "experience": 100, "case": 100, "pack": 101, "croissant": 101, "lipgloss": 100, "christmas": 102, "monitor": 102, "hero": 100, "seller": 100, "luggage": 100, "sound": 105, "clingy": 100, "sunscreen": 100, "presentation": 100, "token": 100, "contour": 100, "echo": 101, "concept": 100, "mouse": 104, "tower": 103, "strawberry": 100, "kk": 101, "cushion": 101, "takeaway": 100, "filter": 100, "teaser": 101, "league": 114, "view": 1103, "mentor": 101, "server": 106, "clip": 101, "cast": 100, "room": 1104, "tone": 98, "cash": 98, "mommy": 98, "record": 101, "format": 98, "workshop": 98, "app": 103, "skip": 98, "schedule": 98, "reboot": 98, "paste": 98, "hangout": 98, "player": 98, "headphone": 98, "farm": 98, "service": 1103, "booth": 98, "review": 100, "cute": 98, "eyeliner": 98, "passapp": 98, "pose": 98, "admin": 99, "edit": 103, "microwave": 98, "break": 98, "failed": 98, "follower": 98, "crypto": 98, "penalty": 98, "topup": 98, "shift": 98, "fine": 98, "ramen": 98, "producer": 98, "unfollow": 98, "crush": 98, "heal": 98, "bus": 1099, "cheers": 98, "push": 98, "golf": 98, "depressed": 98, "customer": 98, "download": 99, "kpi": 96, "bar": 1101, "address": 97, "foundation": 97, "skincare": 96, "huhu": 96, "setting": 96, "police": 96, "supervisor": 96, "commission": 97, "read": 99, "tent": 96, "cover": 97, "ghosting": 96, "hardware": 101, "commit": 96, "point": 96, "upload": 96, "marathon": 96, "logic": 97, "windows": 119, "grade": 96, "license": 98, "cloud": 96, "flex": 96, "stalk": 96, "setup": 96, "postpone": 96, "login": 97, "pc": 101, "jeans": 96, "organic": 96, "judge": 94, "champion": 94, "framework": 95, "season": 95, "beer": 1096, "resort": 1095, "stop": 96, "fake": 94, "sashimi": 94, "hotspot": 94, "card": 97, "merge": 94, "install": 94, "cappuccino": 94, "option": 94, "brother": 95, "cake": 94, "sample": 94, "budget": 95, "troll": 94, "bby": 94, "event": 94, "simp": 94, "website": 99, "payslip": 94, "americano": 94, "verify": 94, "wine": 1095, "hang": 96, "jazz": 95, "macchiato": 94, "debut": 96, "close": 95, "assign": 94, "cache": 94, "bye": 95, "work": 94, "excel": 94, "camping": 94, "morning": 94, "radar": 94, "reel": 94, "calorie": 92, "coupon": 92, "espresso": 92, "whey": 92, "auto": 1093, "drip": 92, "ulti": 92, "remote": 93, "agenda": 92, "acoustic": 92, "hahaha": 92, "speed": 92, "mask": 93, "gate": 93, "interview": 92, "noti": 92, "unseen": 92, "coke": 92, "kill": 92, "network": 100, "toner": 92, "office": 97, "folder": 92, "watt": 92, "slip": 92, "electronic": 94, "garage": 90, "netflix": 92, "credit": 91, "stress": 91, "fitness": 90, "seen": 90, "alarm": 90, "memory": 96, "statement": 91, "premium": 90, "melody": 91, "discount": 1091, "rofl": 90, "hall": 92, "apply": 90, "camp": 93, "browser": 93, "shop": 1093, "digital": 98, "plank": 90, "icu": 90, "fan": 90, "mlbb": 90, "portfolio": 90, "touchpad": 90, "popcorn": 90, "semester": 90, "recommend": 90, "waffle": 90, "workout": 88, "moto": 91, "pudding": 88, "roaming": 88, "vanilla": 88, "retake": 88, "fashion": 1091, "sense": 89, "training": 1089, "allowance": 88, "frappe": 88, "vitamin": 94, "parking": 1089, "nerf": 88, "final": 89, "hybrid": 91, "collagen": 88, "deadlift": 88, "edm": 89, "design": 1093, "light": 91, "ehe": 88, "comeback": 88, "family": 1090, "trend": 88, "pasta": 86, "virus": 86, "love": 92, "library": 1089, "cashback": 86, "playlist": 86, "vaccine": 87, "intro": 86, "cream": 1087, "backdrop": 86, "speaker": 88, "syrup": 86, "donut": 86, "wew": 86, "macbook": 86, "leader": 86, "serum": 88, "vip": 87, "cleanser": 86, "episode": 86, "dating": 86, "salary": 87, "laser": 86, "nugget": 86, "function": 100, "invoice": 86, "warmup": 86, "influencer": 86, "deluxe": 86, "soundtrack": 84, "crash": 84, "tune": 84, "script": 84, "bluetooth": 84, "reaction": 84, "healing": 84, "official": 84, "supplier": 84, "campaign": 84, "flight": 86, "diet": 85, "esports": 85, "comfort": 84, "juice": 1088, "seminar": 84, "xray": 84, "kitty": 84, "soup": 84, "bass": 84, "transfer": 1083, "valentine": 82, "dis": 82, "club": 1085, "guitar": 82, "payment": 82, "match": 82, "pop": 91, "data": 89, "host": 82, "omg": 82, "crack": 82, "cool": 82, "crop": 82, "jersey": 89, "latte": 82, "okay": 82, "bakery": 1083, "password": 83, "restore": 82, "recap": 82, "senior": 82, "lightstick": 82, "chip": 80, "kiss": 81, "backend": 80, "aerobic": 81, "cheese": 81, "toxic": 80, "appointment": 80, "assist": 80, "subtitle": 80, "iphone": 85, "pizza": 1083, "job": 80, "feedback": 80, "voucher": 80, "lmao": 80, "mood": 80, "chill": 80, "ending": 80, "shot": 78, "more": 80, "dose": 78, "oxygen": 78, "cocktail": 78, "target": 78, "campus": 78, "matcha": 78, "ship": 78, "marketing": 79, "vibe": 76, "smoothie": 76, "mascara": 76, "tour": 1082, "agent": 76, "done": 76, "baby": 78, "invite": 76, "snack": 76, "audit": 76, "birthday": 76, "database": 76, "passion": 74, "track": 76, "laundry": 1075, "checkout": 74, "deploy": 74, "primer": 72, "backup": 72, "mana": 72, "logout": 72, "turbo": 73, "meet": 72, "topic": 72, "animation": 73, "pending": 70, "spoil": 70, "the": 186, "headset": 70, "base": 73, "caption": 71, "decor": 68, "tv": 96, "trending": 68, "trump": 66, "series": 79, "eu": 106, "cable": 66, "new": 1107, "cmt": 60, "uninstall": 60, "android": 64, "ii": 168, "apple": 64, "ios": 57, "previous": 50, "un": 60, "kh": 70, "kde": 63, "pap": 63, "mih": 46, "amazon": 48, "bbc": 78, "akp": 44, "sina": 44, "world": 75, "cd": 74, "khmer": 65, "eba": 42, "cambodia": 1058, "fderp": 40, "afp": 40, "john": 67, "us": 48, "duterte": 36, "cm": 45, "gdp": 66, "adb": 37, "cnc": 35, "one": 53, "cnn": 36, "bitcoin": 36, "beat": 34, "richner": 34, "abc": 131, "mary": 40, "plus": 35, "apr": 34, "vovworld": 32, "ieo": 32, "weibo": 32, "sms": 33, "galaxy": 37, "dafabet": 32, "kim": 42, "nina": 32, "acu": 32, "mv": 33, "iso": 45, "lg": 30, "nea": 30, "ecoslim": 30, "kg": 45, "nasa": 38, "joe": 30, "si": 46, "ip": 32, "co": 1042, "unesco": 32, "mysql": 38, "bc": 78, "thaad": 28, "asian": 39, "phuc": 28, "xuan": 28, "messi": 28, "gb": 29, "jodi": 26, "qt": 34, "cnrp": 27, "james": 39, "km": 85, "ab": 61, "nguyen": 26, "whatsapp": 26, "oxford": 36, "mangosteen": 24, "on": 37, "mark": 26, "niied": 24, "fm": 48, "pml": 27, "cpp": 30, "appf": 24, "tranny": 24, "sme": 24, "apk": 24, "real": 27, "william": 32, "man": 29, "bayon": 22, "who": 31, "dbcs": 27, "dough": 22, "com": 47, "seress": 32, "amanda": 22, "delta": 25, "kerry": 24, "breaking": 22, "flash": 27, "hawaii": 23, "swift": 79, "undrip": 22, "cl": 25, "dragon": 27, "fmis": 20, "cam": 22, "fa": 26, "vespucci": 25, "ipu": 21, "almond": 26, "china": 26, "nbc": 20, "mhz": 30, "pnn": 20, "kode": 20, "manga": 20, "david": 37, "twitter": 24, "games": 33, "tesco": 20, "fong": 20, "day": 40, "zuma": 20, "upsize": 20, "to": 42, "jica": 33, "air": 24, "cpc": 20, "by": 35, "dap": 20, "rfa": 21, "bizkhmer": 20, "sea": 41, "honda": 29, "van": 34, "donald": 22, "daigou": 20, "jong": 20, "madrid": 24, "iss": 20, "huawei": 20, "trouve": 18, "alibaba": 18, "evergrande": 18, "smart": 21, "led": 21, "jesus": 21, "ft": 42, "khnews": 18, "oca": 28, "chelsea": 18, "wp": 18, "mourinho": 18, "ilo": 18, "am": 1037, "devith": 18, "al": 29, "cc": 28, "vov": 18, "views": 17, "mobile": 1020, "taew": 16, "gecko": 16, "mh": 17, "id": 22, "biden": 16, "city": 2024, "li": 36, "tn": 17, "cdc": 19, "wikipedia": 22, "dlt": 16, "big": 36, "tran": 19, "ai": 21, "hee": 17, "tanh": 29, "aeon": 16, "paul": 30, "apec": 16, "farooq": 17, "acg": 16, "wcs": 16, "eth": 21, "dhokko": 16, "ctn": 22, "beng": 17, "ice": 1018, "michael": 30, "all": 22, "enarita": 16, "key": 20, "pak": 16, "wang": 17, "msx": 16, "cna": 16, "sarin": 16, "tim": 25, "atul": 16, "cook": 17, "prius": 16, "sabay": 17, "makro": 16, "song": 17, "lean": 16, "off": 1020, "ecommerce": 16, "max": 23, "emi": 17, "and": 36, "prince": 19, "tartuffe": 14, "pass": 15, "lexus": 14, "korpela": 14, "ak": 17, "rx": 14, "santos": 15, "pais": 15, "rmb": 14, "tags": 14, "chompoo": 14, "nikki": 14, "haley": 15, "ipos": 14, "ted": 15, "ima": 17, "shia": 15, "ghulam": 15, "ishaq": 15, "comfrel": 14, "wordpress": 17, "ustr": 14, "mk": 17, "cbr": 14, "tpp": 14, "epo": 15, "gmac": 14, "in": 1031, "louis": 19, "ac": 51, "gas": 1015, "pm": 1020, "cosh": 24, "utd": 14, "chevron": 14, "axiata": 14, "hrw": 14, "due": 14, "jetro": 14, "park": 19, "ohchr": 14, "asa": 15, "ah": 73, "star": 1019, "tiger": 15, "kinme": 14, "press": 19, "sinh": 25, "pcs": 14, "allicin": 14, "disney": 22, "airbnb": 14, "rt": 13, "san": 17, "freeware": 12, "fda": 13, "uk": 13, "shah": 13, "soyo": 12, "gao": 12, "unido": 12, "york": 24, "xinfadi": 12, "merced": 12, "cbd": 14, "cambodian": 1019, "washington": 16, "wi": 12, "fi": 15, "xiaomi": 12, "electronics": 1014, "raoul": 12, "marc": 13, "jennar": 12, "tadakuma": 12, "henri": 19, "pa": 29, "cf": 20, "tf": 13, "jane": 15, "ladyluck": 12, "tel": 1013, "livre": 12, "futanari": 12, "mm": 24, "kyeong": 12, "permana": 12, "rappler": 12, "nokia": 13, "ages": 12, "keqiang": 12, "futa": 12, "ecg": 13, "nnp": 12, "chan": 17, "pp": 14, "boeing": 23, "davidson": 12, "alt": 17, "ico": 12, "ki": 27, "url": 16, "ifl": 14, "independent": 13, "east": 190, "cmac": 13, "ma": 22, "shemale": 12, "ctrl": 12, "or": 25, "telexfree": 12, "tag": 19, "agung": 13, "thanksgiving": 15, "kaps": 12, "pcx": 12, "taller": 12, "aung": 14, "lee": 27, "window": 14, "cop": 13, "vape": 12, "mers": 13, "wmc": 12, "khan": 22, "june": 12, "ui": 14, "forex": 12, "specs": 12, "th": 65, "ti": 19, "media": 25, "english": 1024, "ct": 13, "road": 1014, "ph": 45, "umno": 12, "icd": 13, "france": 16, "afpfl": 15, "auroville": 12, "mike": 14, "at": 18, "fifa": 28, "yi": 18, "ltd": 1022, "duke": 15, "bi": 21, "clc": 12, "mou": 14, "galid": 12, "benjamin": 14, "kan": 15, "oh": 17, "candida": 12, "agorapulse": 12, "mc": 19, "bdv": 12, "minusma": 12, "beta": 17, "sfrs": 10, "kang": 12, "sak": 12, "unodc": 11, "bektleay": 10, "uyfc": 10, "mpwt": 10, "sam": 13, "sperbund": 10, "osius": 10, "sinus": 11, "omega": 13, "tool": 11, "ku": 15, "ka": 17, "hard": 11, "united": 19, "ram": 17, "paris": 16, "sulforaphane": 10, "iammst": 10, "aiib": 10, "koo": 10, "igf": 10, "afc": 23, "iii": 102, "accra": 10, "best": 1012, "maria": 14, "zurich": 14, "ibm": 15, "stand": 10, "gmt": 12, "tvk": 15, "btc": 10, "razr": 10, "punjab": 10, "nmc": 10, "ocm": 10, "pams": 10, "lecithin": 10, "cia": 19, "ns": 10, "kia": 10, "vivo": 10, "tvb": 11, "blog": 17, "rodrigo": 10, "judo": 10, "don": 16, "sahong": 10, "peter": 20, "michelin": 8, "vdo": 8, "nissan": 9, "dubai": 9, "gold": 1014, "raccoon": 8, "xiaodie": 8, "alexis": 9, "bhumibol": 11, "adulyadej": 10, "eri": 8, "kaneko": 8, "kildare": 8, "fomo": 8, "hermite": 10, "keyan": 8, "pepsi": 8, "face": 9, "palea": 8, "rein": 8, "mrt": 10, "down": 10, "hgb": 8, "kmh": 8, "mekong": 1011, "likes": 8, "boy": 9, "bong": 8, "thomas": 24, "hai": 10, "phong": 9, "conway": 8, "tham": 8, "luang": 9, "kitakyushu": 8, "peypey": 8, "dy": 8, "sars": 8, "cov": 8, "pkaya": 8, "unicef": 9, "hyun": 9, "mo": 10, "ndt": 8, "sturgess": 8, "houthi": 8, "if": 9, "oneplus": 8, "tablet": 8, "tzu": 8, "jetsun": 8, "pema": 8, "lomhel": 8, "little": 11, "harvard": 21, "thanh": 11, "yang": 10, "jiangsu": 10, "los": 14, "angeles": 14, "hun": 8, "sen": 10, "zealand": 10, "agave": 8, "katayama": 8, "cost": 9, "metric": 8, "kelley": 8, "thc": 8, "ra": 11, "vod": 11, "harley": 8, "ray": 12, "pedro": 11, "nex": 8, "comey": 8, "folczyk": 8, "hanja": 9, "vong": 9, "allen": 12, "yammie": 8, "lam": 10, "sql": 13, "display": 8, "amp": 11, "ken": 11, "castro": 8, "adhoc": 9, "el": 11, "hdr": 8, "ressa": 8, "najib": 8, "eo": 8, "erdogan": 8, "scott": 8, "neeson": 8, "bmw": 8, "snorkelling": 8, "tanchon": 8, "kanha": 8, "itf": 8, "tl": 9, "fidel": 10, "hiv": 11, "aids": 9, "fumizen": 8, "manop": 8, "milwaukee": 8, "khum": 9, "phath": 8, "explore": 8, "utorrent": 8, "jonh": 8, "chu": 12, "elon": 8, "roi": 9, "oled": 9, "kratie": 8, "cha": 11, "hangeul": 9, "cmdf": 8, "ankara": 8, "brunson": 8, "quoc": 9, "mp": 15, "moon": 12, "ant": 8, "ict": 10, "somaly": 8, "joker": 8, "chung": 8, "sima": 8, "gloomy": 12, "sunday": 13, "pse": 9, "wenger": 8, "lgbt": 9, "mersin": 8, "bangkok": 15, "skype": 24, "everton": 8, "science": 11, "xiamen": 8, "myung": 8, "bak": 9, "pb": 8, "takhon": 8, "alejandro": 8, "lashkar": 8, "jhangvi": 8, "pieter": 8, "dank": 8, "ozawa": 8, "ld": 17, "dara": 9, "sai": 10, "icbm": 8, "ocic": 10, "college": 1015, "son": 10, "pek": 8, "amr": 9, "moussa": 9, "jose": 8, "harmony": 8, "foy": 8, "nm": 13, "sambuor": 9, "dear": 8, "fao": 8, "zoolander": 8, "gaal": 8, "airports": 8, "bagel": 8, "strange": 8, "bo": 15, "judaism": 10, "young": 16, "otto": 11, "marseille": 9, "kalib": 8, "neymar": 8, "cchr": 12, "zambia": 8, "abanova": 8, "caltex": 9, "my": 19, "nikkei": 10, "inc": 20, "reddit": 9, "year": 13, "kilin": 8, "texas": 14, "azure": 8, "mart": 1009, "doug": 10, "sir": 16, "psn": 8, "pisa": 9, "no": 2016, "paing": 8, "yonhap": 8, "unpo": 8, "scoopy": 8, "ielts": 8, "nature": 9, "en": 49, "une": 8, "ccleaner": 8, "it": 21, "pr": 12, "sl": 9, "franklin": 12, "levy": 8, "ndou": 8, "we": 12, "organize": 8, "zina": 9, "arsenal": 10, "joy": 8, "doc": 9, "yoga": 9, "soon": 8, "chol": 8, "micro": 9, "pence": 8, "ucl": 8, "ffc": 10, "dien": 13, "tangmo": 8, "aviv": 8, "ktv": 1009, "riya": 8, "prime": 9, "jack": 13, "lionel": 8, "edc": 9, "ember": 8, "wto": 13, "ri": 10, "sang": 8, "article": 9, "wind": 8, "michelle": 8, "obama": 23, "camnewsonline": 8, "bach": 8, "vgp": 9, "gnu": 13, "sop": 9, "isp": 9, "qq": 8, "imt": 8, "vislink": 8, "iris": 8, "ioc": 27, "bien": 11, "isi": 17, "asean": 13, "meada": 9, "lao": 15, "westerdam": 8, "version": 10, "undp": 11, "mouhot": 12, "harry": 9, "king": 17, "bao": 8, "moi": 10, "lemma": 8, "wazamba": 8, "ppp": 16, "mall": 11, "nocc": 9, "ranking": 8, "defi": 8, "christ": 9, "current": 16, "isil": 11, "fcc": 11, "butler": 8, "ranieri": 8, "taiwan": 9, "serval": 8, "berry": 8, "feremol": 8, "fbi": 14, "sipt": 8, "enrico": 9, "sw": 8, "sar": 10, "saracen": 8, "linkedin": 11, "keisuke": 8, "bible": 8, "oda": 8, "cruz": 11, "dna": 24, "pen": 10, "fars": 8, "north": 173, "pacific": 10, "boku": 8, "oecd": 9, "rsn": 10, "help": 8, "iyi": 8, "bavar": 8, "liga": 8, "foodbuzz": 8, "hua": 9, "russier": 6, "seng": 7, "cxxxi": 6, "cxxxii": 6, "gsp": 7, "feets": 6, "scoliosis": 6, "saadet": 6, "chef": 6, "coraline": 6, "gamers": 6, "efeo": 7, "nctc": 6, "kathy": 6, "gruver": 6, "diy": 6, "july": 7, "mojo": 6, "clmtv": 6, "hbr": 6, "mlc": 6, "av": 7, "lampung": 6, "vanna": 6, "aigle": 6, "rainsy": 6, "dbts": 6, "tvet": 6, "costa": 7, "files": 6, "vinyl": 6, "rca": 15, "camup": 6, "csn": 6, "bp": 10, "usd": 18, "then": 6, "erp": 6, "mytv": 8, "orso": 6, "mario": 6, "corbino": 6, "jin": 9, "faryab": 6, "xbet": 11, "stars": 7, "ems": 6, "osiris": 6, "rex": 6, "ch": 45, "khmerload": 6, "ceo": 7, "fc": 11, "lek": 6, "phit": 6, "ic": 10, "mra": 7, "lift": 6, "koi": 6, "oc": 10, "janie": 6, "times": 14, "oishi": 6, "translate": 6, "ekod": 6, "adcon": 6, "con": 6, "coinfalls": 6, "chemical": 6, "global": 10, "ramirez": 6, "kr": 7, "nim": 6, "gap": 6, "graham": 12, "pectin": 6, "kampuchea": 7, "thmey": 10, "cbc": 6, "arena": 8, "tika": 6, "commentary": 6, "miche": 8, "mao": 9, "links": 7, "mlm": 6, "navi": 6, "eoat": 6, "diac": 6, "hong": 9, "sambaur": 6, "unionwebs": 6, "wikimedia": 6, "commons": 6, "icos": 6, "fujil": 6, "buy": 6, "station": 1009, "som": 6, "csa": 6, "khmerpart": 6, "uefa": 16, "patent": 8, "lining": 6, "hd": 15, "god": 9, "bless": 6, "flexible": 6, "mandeb": 6, "bwar": 6, "toyota": 6, "nsa": 7, "spp": 9, "remi": 6, "charrel": 6, "nice": 9, "tensai": 6, "orient": 7, "persico": 7, "liu": 7, "sbs": 8, "ldp": 10, "msnbc": 6, "clapper": 6, "cyber": 6, "naik": 7, "ppsez": 6, "gearbest": 6, "troy": 7, "neo": 8, "fca": 6, "asic": 6, "aug": 6, "matic": 6, "robbie": 6, "tit": 6, "avengers": 6, "never": 6, "make": 7, "up": 14, "ar": 9, "novels": 6, "spn": 6, "acmecs": 6, "uttama": 6, "savanayana": 6, "flux": 6, "mawl": 6, "guild": 7, "aspartic": 6, "amazing": 6, "dz": 8, "sta": 6, "nato": 8, "acer": 6, "anel": 6, "sunny": 6, "lbh": 6, "masyarakat": 6, "smb": 6, "plan": 8, "come": 6, "obor": 6, "alisha": 6, "lish": 6, "bihar": 7, "suu": 7, "kyi": 7, "deyan": 6, "moses": 8, "noscript": 6, "store": 1000, "minimart": 1000, "supermarket": 1000, "market": 1006, "restaurant": 1000, "tea": 1004, "milk": 1000, "noodle": 1000, "beef": 1000, "chicken": 1000, "pork": 1000, "fish": 1000, "grill": 1000, "water": 1003, "pub": 1000, "karaoke": 1000, "hotel": 1006, "guesthouse": 1000, "guest": 1000, "house": 2012, "rooms": 1000, "for": 1015, "rent": 1000, "closed": 1000, "welcome": 1003, "exit": 1000, "entrance": 1000, "smoking": 1000, "you": 1014, "money": 1005, "hospital": 1003, "dental": 1000, "medical": 1000, "center": 1008, "centre": 1000, "health": 1004, "school": 1010, "university": 1017, "academy": 1006, "institute": 1006, "company": 1012, "trading": 1000, "import": 1000, "export": 1000, "construction": 1000, "engineering": 1000, "printing": 1000, "repair": 1000, "services": 1000, "motorbike": 1000, "car": 1000, "wash": 1000, "parts": 1000, "tire": 1000, "tyre": 1000, "beauty": 1000, "salon": 1000, "spa": 1000, "nail": 1000, "hair": 1000, "barber": 1000, "clothes": 1000, "shoes": 1000, "jewelry": 1000, "jewellery": 1000, "tailor": 1000, "tours": 1000, "transport": 1000, "logistics": 1000, "petrol": 1000, "oil": 1000, "kingdom": 1003, "of": 1106, "royal": 2014, "government": 1000, "ministry": 1000, "national": 1012, "red": 1010, "cross": 1000, "product": 1000, "made": 1000, "phnom": 1008, "penh": 1006, "siem": 1000, "reap": 1000, "battambang": 1000, "kampot": 1000, "kep": 1000, "sihanoukville": 1000, "street": 1006, "st": 1020, "village": 1004, "district": 1007, "province": 1009, "since": 1000, "est": 1003, "hotline": 1000, "only": 1000, "special": 1000, "hours": 1000, "golden": 1004, "lucky": 1000, "happy": 1003, "smile": 1003, "angkor": 1000, "lotus": 1000, "sunrise": 1000, "sunset": 1000, "garden": 1004, "river": 1012, "central": 1009, "f": 237, "c": 646, "t": 298, "x": 399, "wilhelm": 4, "glyphosate": 3, "k": 407, "knob": 4, "amir": 3, "m": 276, "g": 149, "e": 131, "bb": 3, "d": 330, "nol": 3, "p": 167, "rose": 4, "kt": 4, "a": 683, "variant": 3, "y": 129, "n": 479, "b": 483, "q": 65, "v": 152, "i": 247, "samos": 4, "apennines": 3, "sey": 3, "u": 127, "door": 3, "tm": 3, "ps": 6, "thiamin": 4, "zuckerberg": 3, "tnt": 5, "helsinki": 5, "j": 49, "sex": 3, "indra": 4, "s": 243, "h": 153, "eria": 5, "gerd": 4, "hc": 3, "plate": 3, "text": 5, "hue": 3, "ahn": 4, "o": 110, "dawn": 3, "gnome": 8, "xi": 20, "holocaust": 3, "khandha": 3, "voip": 5, "industrial": 3, "community": 3, "tep": 5, "w": 42, "robert": 15, "de": 74, "niro": 6, "joomla": 19, "georges": 3, "groslier": 3, "minh": 11, "easter": 3, "lincoln": 4, "xml": 4, "mccain": 3, "isis": 3, "isaf": 3, "wikidb": 3, "ninja": 4, "r": 129, "bmi": 3, "harold": 3, "chengdu": 4, "gis": 3, "expired": 3, "firefox": 3, "aec": 3, "pheak": 3, "hydrosphere": 3, "watch": 3, "seap": 3, "acc": 3, "nhk": 4, "coral": 3, "z": 97, "kash": 3, "rizzo": 3, "pe": 5, "montagnards": 3, "ln": 5, "tian": 5, "hiroshima": 4, "singh": 3, "language": 13, "maya": 8, "what": 4, "afm": 3, "carl": 10, "island": 6, "human": 7, "rights": 3, "tigris": 3, "lego": 3, "pdf": 11, "vista": 6, "thai": 12, "green": 9, "puncak": 3, "karl": 7, "be": 15, "na": 16, "hf": 4, "nom": 3, "gpa": 4, "bok": 3, "mmr": 3, "tho": 5, "vinh": 5, "airbus": 7, "public": 7, "org": 16, "cgs": 3, "radio": 10, "jakarta": 8, "rover": 3, "syracuse": 4, "log": 4, "tenaserim": 3, "capital": 5, "niger": 4, "ru": 4, "skills": 3, "aq": 4, "unhcr": 4, "usenet": 3, "black": 6, "wei": 3, "marcus": 4, "holmes": 3, "ca": 9, "claire": 3, "town": 30, "hg": 3, "gene": 3, "kkf": 3, "tw": 3, "wolf": 3, "hsinbyushin": 5, "people's": 6, "ebc": 5, "monorail": 4, "vp": 3, "as": 8, "gatille": 3, "bx": 4, "irish": 3, "dan": 7, "cpi": 3, "yong": 3, "xiii": 11, "ap": 13, "moeys": 3, "bucharest": 3, "blaise": 3, "pascal": 3, "cps": 3, "cyrillic": 5, "cinnamon": 3, "psa": 3, "disk": 4, "dong": 3, "ho": 6, "grand": 13, "thor": 6, "bv": 3, "printer": 3, "se": 4, "business": 4, "creative": 3, "au": 16, "zc": 3, "bg": 5, "can": 7, "dfm": 3, "xiong": 3, "floyd": 3, "dj": 3, "torah": 8, "christchuech": 3, "bol": 3, "jr": 3, "aix": 3, "charlotte": 4, "noun": 5, "mae": 4, "imf": 5, "barcelona": 5, "roma": 3, "ng": 94, "lady": 4, "berhad": 3, "olympic": 6, "il": 4, "hot": 9, "logique": 3, "bh": 8, "koica": 6, "vdpp": 3, "pnh": 3, "ireland": 3, "mong": 4, "lu": 5, "avatar": 15, "today": 4, "mohammed": 4, "bin": 5, "plaza": 3, "gi": 10, "xu": 8, "may": 4, "mpi": 5, "dk": 4, "gallup": 3, "prang": 3, "sports": 5, "alex": 21, "niels": 5, "bohr": 5, "hazard": 3, "icon": 3, "brahmagupta": 5, "exe": 3, "sk": 4, "ceremony": 21, "gt": 4, "earth": 9, "po": 15, "l": 105, "folate": 5, "java": 7, "sochi": 3, "tb": 3, "tony": 5, "fernandes": 3, "lix": 5, "untac": 5, "tae": 3, "georgia": 6, "barry": 3, "timor": 3, "icc": 6, "tebi": 3, "d'or": 3, "century": 3, "dream": 9, "fight": 5, "rapid": 3, "sabbath": 4, "jan": 3, "top": 4, "persian": 5, "great": 12, "colombo": 4, "root": 5, "arthur": 3, "tullio": 3, "pompey": 4, "tube": 7, "sweet": 3, "see": 4, "usa": 5, "telegraph": 3, "martin": 5, "string": 3, "shimon": 3, "wales": 6, "lc": 5, "hemadri": 3, "blue": 7, "mount": 4, "tat": 4, "shopping": 4, "robbins": 3, "goods": 3, "tan": 6, "cheng": 3, "hoe": 3, "urpp": 4, "lcd": 24, "cultural": 5, "ad": 26, "christopher": 7, "opec": 3, "cramer": 3, "object": 4, "flolate": 4, "uc": 9, "dr": 5, "tiara": 3, "blueberry": 5, "broccoli": 6, "volkswagen": 3, "alan": 4, "bay": 13, "ngu": 4, "sony": 4, "tom": 7, "ini": 3, "smes": 4, "ipa": 6, "itc": 3, "min": 7, "carolina": 4, "genoa": 5, "ana": 4, "wal": 3, "charles": 24, "noble": 4, "path": 4, "microsoft": 29, "south": 170, "nuovo": 3, "cimento": 3, "munich": 5, "endosperm": 6, "gram": 3, "felix": 3, "leaf": 3, "roger": 8, "premier": 6, "fbd": 3, "commerce": 4, "bun": 3, "border": 3, "eude": 3, "messiah": 3, "virashrama": 3, "nath": 4, "bob": 6, "ae": 6, "ben": 8, "gurion": 3, "place": 5, "california": 12, "bourget": 3, "kong": 4, "roh": 3, "maha": 6, "soma": 3, "energy": 5, "angela": 3, "corcoran": 3, "bac": 7, "lieu": 3, "belt": 3, "mah": 12, "ndi": 7, "wave": 4, "iic": 3, "chicago": 8, "pile": 4, "jp": 5, "tu": 11, "kampong": 4, "sdgs": 4, "beach": 4, "jeffrey": 4, "spacex": 3, "cpl": 4, "kaka": 3, "seville": 3, "meteors": 3, "angel": 4, "knot": 3, "hoa": 10, "jonghyun": 3, "site": 5, "cid": 3, "anaukpetlun": 3, "ins": 3, "barbara": 3, "matthew": 4, "riboflavin": 3, "direct": 3, "ninh": 6, "nat": 4, "henry": 23, "war": 11, "union": 9, "nupedia": 3, "run": 6, "smith": 6, "pu": 3, "dvd": 11, "shikoku": 3, "quang": 6, "xue": 3, "fk": 3, "europe": 9, "dm": 4, "gd": 3, "tick": 3, "charts": 7, "touch": 5, "chea": 6, "win": 3, "naphan": 3, "muhammad": 5, "cn": 5, "jay": 4, "fermilab": 3, "dinh": 7, "tectonic": 4, "rss": 3, "holy": 5, "bm": 4, "font": 5, "mpa": 4, "maxwell": 7, "sarah": 5, "guyana": 3, "maguire": 3, "tokyo": 5, "bts": 14, "asem": 3, "nbsp": 3, "islands": 3, "cmos": 4, "die": 3, "go": 4, "boot": 3, "howard": 4, "rangoon": 4, "luigi": 3, "sbc": 5, "bscp": 3, "peng": 3, "carotene": 4, "por": 3, "jerusalem": 3, "dpa": 3, "wikiuser": 4, "gpl": 6, "lok": 4, "state": 9, "casey": 3, "jal": 3, "ramon": 3, "stephen": 5, "coll": 5, "icpd": 3, "manchester": 4, "rain": 3, "sok": 4, "zootopia": 6, "cox": 3, "ha": 14, "add": 4, "corps": 3, "living": 3, "qin": 3, "tsai": 3, "qing": 6, "championship": 5, "kn": 4, "squash": 3, "ford": 4, "histamine": 3, "shinzo": 3, "abe": 3, "age": 4, "picture": 7, "lake": 4, "marvel": 3, "boom": 3, "levi": 5, "tcp": 5, "thi": 6, "corporation": 6, "hope": 4, "mindon": 4, "php": 19, "cv": 3, "theorem": 19, "marshall": 5, "fermi": 4, "art": 7, "super": 18, "le": 26, "far": 3, "side": 3, "prasat": 21, "preah": 3, "wall": 3, "xy": 6, "bang": 4, "boris": 3, "heard": 3, "geo": 3, "julie": 3, "carron": 3, "aarau": 3, "india": 8, "ann": 4, "wan": 5, "inch": 5, "sa": 14, "forum": 3, "last": 5, "xii": 13, "japan": 6, "not": 3, "atlas": 4, "annalen": 3, "der": 5, "physik": 3, "rupp": 4, "aymonier": 6, "gupta": 5, "dylan": 3, "lowell": 3, "sic": 3, "wormhole": 3, "css": 4, "moore": 5, "solid": 4, "devi": 3, "leiper": 3, "faraday": 4, "america": 5, "norway": 5, "ta": 16, "minnesota": 4, "rong": 3, "gergonne": 3, "nang": 3, "jones": 8, "lang": 38, "unix": 8, "phd": 6, "icomos": 4, "power": 7, "gn": 4, "study": 3, "ao": 4, "reuters": 5, "index": 3, "ef": 3, "jean": 6, "alfred": 3, "indian": 3, "states": 5, "information": 3, "asia": 8, "sq": 16, "mi": 35, "religion": 3, "region": 3, "queen": 8, "vat": 24, "output": 7, "input": 8, "caf": 3, "square": 6, "where": 4, "right": 5, "acres": 4, "alexander": 11, "colspan": 18, "malaysia": 4, "pou": 3, "tang": 3, "andr": 3, "du": 18, "prey": 23, "snc": 7, "mean": 7, "chey": 5, "leap": 3, "gregory": 5, "amsterdam": 3, "wiki": 4, "html": 28, "javascript": 4, "berners": 4, "jpg": 4, "title": 8, "random": 4, "number": 9, "euler": 7, "singapore": 10, "saigon": 5, "gon": 3, "cochinchine": 4, "franco": 4, "prussian": 3, "vi": 44, "nam": 16, "bell": 8, "programming": 3, "loop": 3, "utc": 9, "zh": 4, "eas": 7, "ly": 4, "second": 3, "land": 7, "debian": 3, "minor": 3, "saint": 9, "nicolas": 3, "santa": 7, "tr": 27, "kandy": 6, "is": 12, "chasseloup": 3, "laubat": 3, "prefecture": 8, "ju": 4, "nida": 5, "robin": 8, "soriya": 5, "full": 6, "hdtv": 7, "yinsoriya": 3, "rule": 5, "num": 5, "rua": 4, "nie": 3, "nu": 7, "access": 4, "iv": 43, "chart": 4, "bit": 5, "processing": 3, "hypertext": 18, "sign": 3, "nobel": 3, "preap": 4, "sovath": 3, "economic": 4, "production": 5, "icao": 3, "emperor": 3, "et": 7, "alpha": 3, "west": 171, "hill": 7, "yew": 3, "tong": 3, "five": 6, "formula": 13, "international": 16, "airlines": 3, "sia": 3, "civil": 4, "society": 9, "bat": 3, "www": 12, "gov": 3, "thumb": 53, "abcd": 10, "elisha": 3, "gray": 4, "edison": 3, "maastricht": 3, "ec": 5, "supranational": 3, "ecsc": 3, "eec": 9, "common": 3, "efta": 3, "european": 5, "monetary": 3, "emu": 7, "out": 5, "jacques": 4, "leang": 3, "ang": 3, "espa": 3, "quebec": 3, "ol": 3, "cambridge": 4, "development": 4, "social": 6, "unit": 4, "eiffel": 6, "khuddaka": 4, "ya": 5, "strait": 6, "majjhima": 3, "nikaya": 9, "mn": 8, "tuol": 4, "hangul": 6, "edu": 3, "mil": 3, "canal": 3, "passage": 3, "meridian": 3, "ocean": 8, "yahoo": 5, "jh": 4, "an": 19, "name": 23, "venue": 19, "fran": 12, "ois": 7, "complex": 4, "dbfc": 4, "greenland": 3, "yellow": 4, "laptev": 3, "bengal": 3, "ko": 6, "acide": 3, "neptune": 25, "lines": 4, "bridge": 4, "re": 17, "long": 28, "friedman": 3, "del": 5, "linux": 13, "command": 3, "rd": 3, "apache": 7, "http": 10, "brahmagupta's": 3, "bretschneider's": 4, "council": 4, "nocs": 5, "cos": 5, "sup": 3, "brown": 3, "brazil": 3, "aral": 3, "kok": 3, "guy": 13, "caspian": 7, "triangle": 3, "ag": 6, "ge": 8, "mass": 3, "caucasus": 8, "baku": 3, "albert": 5, "he": 4, "him": 3, "lun": 3, "sor": 3, "qur'an": 3, "nation": 4, "girls": 3, "line": 11, "elizabeth": 8, "zia": 3, "ul": 5, "haq": 3, "question": 3, "general": 4, "aquino": 4, "joseph": 6, "ga": 4, "einstein": 3, "boyle": 3, "mile": 3, "br": 5, "mathworld": 3, "method": 5, "integral": 5, "leonhard": 3, "george": 12, "sin": 4, "cuneiform": 5, "historiography": 3, "history": 8, "edward": 8, "ci": 6, "inequality": 13, "rn": 7, "gm": 5, "commune": 33, "vii": 18, "laplace": 6, "bernard": 3, "ahc": 4, "mbc": 4, "hans": 3, "em": 3, "af": 3, "op": 3, "ferdinand": 5, "analytic": 3, "ur": 4, "boc": 3, "magazine": 3, "will": 4, "petersburg": 4, "marie": 3, "abel": 3, "christian": 3, "pt": 3, "arago": 4, "augustin": 3, "des": 8, "nations": 3, "cole": 3, "koh": 3, "ff": 4, "zeta": 4, "pierre": 10, "abd": 3, "sciences": 3, "fourier": 6, "db": 4, "factor": 6, "friedrich": 4, "principal": 3, "isaac": 3, "newton": 3, "symbol": 3, "hurwitz": 3, "area": 4, "grandi": 4, "gal": 3, "magellan": 6, "forms": 4, "dance": 5, "court": 4, "theory": 4, "axis": 6, "bos": 4, "reich": 3, "third": 3, "nazi": 3, "association": 4, "selenium": 3, "da": 11, "propri": 3, "loi": 3, "ne": 4, "cao": 9, "glass": 3, "so": 3, "cairo": 5, "giza": 3, "liban": 3, "beautiful": 3, "law": 3, "pythagoras": 3, "scanner": 3, "proto": 4, "zero": 3, "ba": 12, "cr": 6, "do": 6, "ee": 4, "es": 6, "hu": 10, "im": 3, "io": 10, "ir": 5, "jo": 3, "me": 9, "mg": 6, "ni": 6, "nl": 5, "pn": 6, "py": 4, "sh": 7, "sm": 7, "sn": 12, "sr": 3, "sv": 7, "vc": 5, "ws": 4, "securities": 5, "organization": 3, "lou": 3, "pan": 3, "cap": 3, "pas": 4, "freedom": 4, "ria": 3, "nh": 62, "di": 6, "qu": 19, "vincent": 3, "tamil": 3, "word": 4, "standard": 6, "copenhagen": 3, "adler": 3, "albania": 3, "cambodge": 3, "also": 3, "ecole": 3, "te": 22, "type": 4, "dame": 6, "blanche": 3, "stiffness": 6, "cycle": 4, "race": 3, "this": 5, "buddhist": 5, "iron": 3, "moonos": 13, "ubuntu": 11, "pidgin": 8, "mail": 4, "crt": 6, "kpa": 6, "catherine": 8, "american": 7, "your": 3, "billboard": 14, "kaa": 6, "wide": 5, "hedge": 4, "fund": 5, "purple": 4, "mac": 5, "os": 10, "dos": 3, "minix": 3, "andrew": 7, "xi'an": 3, "yin": 3, "xian": 4, "zheng": 3, "xinjiang": 3, "nanking": 3, "sun": 6, "tung": 3, "homo": 9, "ref": 9, "giao": 5, "lin": 4, "phan": 6, "quan": 3, "nguy": 8, "chi": 4, "gia": 9, "cee": 4, "gaulle": 3, "berlin": 7, "yougoslavie": 4, "atlantique": 3, "otan": 4, "tch": 3, "ukraine": 3, "les": 6, "irak": 14, "bush": 26, "pyongyang": 4, "venezuela": 3, "iran": 4, "syrie": 5, "egypte": 4, "turquie": 4, "chiite": 3, "isra": 27, "juif": 4, "kowe": 3, "arabe": 4, "palestine": 17, "perse": 3, "rusalem": 3, "oslo": 5, "hamas": 8, "gaza": 4, "sc": 6, "hezbollah": 3, "afghanistan": 5, "saddam": 11, "hussein": 11, "bagdad": 3, "ahmadinejad": 5, "koizumi": 3, "miyako": 3, "archive": 4, "county": 5, "mon": 3, "ans": 3, "end": 4, "management": 3, "template": 7, "xuanzang": 4, "faxian": 3, "ceylon": 3, "kataragama": 5, "vihara": 3, "companies": 3, "warder": 3, "analysis": 4, "mind": 8, "body": 3, "illinois": 3, "springfield": 3, "image": 3, "pla": 4, "mercury": 7, "iucn": 4, "urbain": 3, "elara": 4, "sri": 5, "kalinga": 3, "shi": 5, "non": 3, "isbn": 11, "ddc": 3, "dewey": 3, "vol": 29, "resonance": 4, "courant": 4, "grammy": 9, "bros": 5, "dave": 3, "records": 4, "chakraborty": 3, "sydney": 3, "perception": 16, "consciousness": 5, "latin": 3, "sutta": 11, "isle": 3, "cvcc": 3, "life": 7, "white": 5, "plato": 10, "mental": 3, "xxii": 7, "pitchblende": 5, "curie": 4, "magnolia": 12, "libreoffice": 6, "dn": 4, "cartier": 12, "bresson": 10, "lhote": 5, "pennsylvania": 8, "vaccaro": 3, "fascist": 3, "newyork": 3, "normandie": 3, "look": 3, "flair": 3, "williams": 3, "jackson": 3, "zen": 5, "dark": 5, "cpk": 3, "gardner": 4, "ottoman": 5, "meego": 17, "intel": 3, "eset": 9, "nt": 5, "jupiter": 26, "pioneer": 6, "juno": 16, "europa": 16, "byzantine": 6, "zeus": 5, "nebula": 5, "uranus": 52, "voyager": 39, "jovian": 13, "convection": 6, "dipole": 3, "tai": 10, "galileo": 19, "galilean": 6, "marius": 3, "ganymede": 84, "cassini": 6, "heinrich": 3, "frank": 3, "flybys": 4, "callisto": 12, "esa": 7, "trojan": 4, "kuiper": 7, "hubble": 9, "zeno": 3, "vedic": 3, "titan": 5, "olympus": 3, "mons": 4, "mariner": 3, "mars": 4, "spirit": 4, "opportunity": 4, "venus": 77, "venusian": 15, "phosphine": 3, "venera": 9, "terra": 5, "eccentricity": 3, "johann": 5, "codex": 3, "parker": 3, "probe": 3, "uranian": 7, "tauri": 3, "herschel": 8, "parallax": 4, "johan": 3, "bode": 6, "saturn": 9, "simon": 3, "verrier": 6, "jacob": 4, "troposphere": 8, "stratosphere": 4, "corona": 3, "hst": 4, "keck": 3, "flyby": 3, "ariel": 4, "adams": 6, "ori": 3, "neptunian": 4, "pluto": 3, "triton": 3, "ring": 6, "planet": 3, "discovery": 5, "empire": 4, "borneo": 3, "township": 3, "phra": 8, "temple": 4, "country": 3, "biology": 4, "adn": 5, "arn": 5, "px": 17, "left": 61, "sapiens": 5, "mit": 3, "allies": 4, "taylor": 8, "zoroastrianism": 3, "kierkegaard": 3, "girl": 4, "football": 3, "arpanet": 7, "nsfnet": 3, "editor": 4, "bosco": 3, "gomes": 7, "pce": 5, "daguerre": 3, "talbot": 4, "eastman": 4, "philadelphia": 4, "levitsky": 3, "kodak": 3, "ccd": 6, "shannon": 3, "communication": 4, "small": 3, "cbs": 4, "ryb": 3, "cmyk": 5, "rgb": 7, "opera": 4, "das": 3, "paper": 6, "citation": 3, "needed": 3, "altair": 3, "singleness": 3, "wilderness": 3, "nothingness": 3, "people": 3, "talmud": 6, "mishnah": 3, "rabbi": 4, "gaon": 10, "kabbalah": 3, "doung": 4, "align": 60, "ane": 3, "scandinavia": 3, "core": 4, "obscura": 3, "sontag": 3, "hz": 4, "moana": 21, "lumi": 3, "blogspot": 4, "blogger": 3, "templates": 5, "vis": 25, "nipkow": 3, "baird": 3, "ban": 4, "fank": 3, "cern": 13, "mau": 8, "xuy": 3, "ix": 14, "nai": 6, "chief": 3, "quarter": 3, "afl": 3, "farian": 3, "matt": 3, "jake": 24, "sipar": 4, "francis": 5, "itv": 6, "farnsworth": 5, "zworykin": 4, "iconoscope": 3, "pure": 6, "buddhism": 3, "dom": 4, "wedgwood": 6, "daguerreotype": 6, "giroux": 3, "chevalier": 4, "gaudin": 5, "voigtl": 3, "nder": 4, "petzval": 3, "zeiss": 3, "rack": 7, "lewis": 4, "slr": 3, "telephoto": 8, "viewfinder": 3, "four": 4, "tree": 3, "lb": 8, "countryballs": 3, "osaka": 4, "electric": 3, "prize": 3, "cdf": 3, "xxiii": 7, "freddie": 3, "dion": 3, "music": 16, "entertainment": 9, "variable": 3, "saemaul": 13, "undong": 12, "beatocello": 5, "hayes": 3, "giang": 15, "columbus": 18, "miles": 5, "von": 5, "ara": 16, "oricon": 3, "mnet": 3, "peep": 4, "hwayoung": 4, "contents": 3, "amerigo": 3, "rio": 4, "nationale": 4, "manila": 4, "kuala": 5, "lumpur": 5, "atlanta": 3, "chang": 3, "chun": 3, "sunspots": 3, "coronal": 3, "vatican": 3, "armenia": 49, "timurid": 3, "vres": 3, "wilson": 4, "yerevan": 7, "csto": 3, "nagorno": 5, "karabakh": 5, "diaspora": 3, "tripadvisor": 3, "vagga": 3, "asceticism": 4, "vb": 33, "color": 3, "oligarchy": 6, "mig": 6, "isoc": 6, "queensland": 3, "viii": 23, "just": 4, "gui": 8, "sub": 3, "console": 3, "xbox": 3, "xx": 4, "puthisastra": 3, "genghis": 3, "info": 3, "tre": 3, "visaya": 3, "simple": 3, "bieber": 6, "romeo": 8, "juliet": 5, "verona": 3, "capulet": 3, "noly": 7, "vcd": 4, "supersonic": 3, "mirage": 4, "arm": 5, "amur": 3, "su": 13, "sukhoi": 3, "ud": 4, "eng": 4, "sithi": 3, "richard": 4, "roman": 3, "kiva": 4, "fixed": 4, "uhf": 4, "tss": 3, "ucss": 4, "ucdc": 3, "uccrcy": 4, "ucf": 5, "guangxi": 3, "ohio": 3, "corp": 3, "mughal": 4, "locke": 4, "mecca": 3, "certain": 3, "regard": 3, "awards": 9, "odc": 3, "playboy": 5, "aac": 6, "clique": 3, "crowds": 3, "wikihow": 4, "menorah": 4, "puja": 3, "lakshmi": 3, "vilakku": 3, "pinch": 4, "rim": 5, "spout": 6, "bailey": 4, "kone": 3, "theodore": 3, "era": 5, "curatorium": 3, "rdoba": 3, "hondajet": 4, "ecliptic": 6, "vernal": 3, "libra": 3, "dog": 5, "lua": 3, "birds": 4, "sutra": 3, "vietnamese": 3, "lead": 3, "neang": 3, "evd": 3, "cell": 3, "ttg": 3, "photonics": 12, "quantum": 3, "spider": 3, "scrimmage": 11, "nfl": 6, "jamestown": 6, "virginia": 5, "intramural": 4, "rutgers": 5, "intercollegiate": 5, "mcgill": 4, "touchdown": 6, "montreal": 5, "walter": 3, "michigan": 6, "warner": 9, "rockne": 6, "notre": 6, "popularizing": 3, "bcs": 5, "canton": 4, "jim": 3, "bowl": 4, "xlix": 5, "punt": 3, "rna": 5, "briggs": 3, "cailliau": 3, "enquire": 4, "lampblack": 3, "bromine": 3, "halide": 4, "rabies": 5, "furious": 4, "rodas": 4, "walker": 7, "dymtrow": 3, "chapman": 4, "blu": 12, "lefsetz": 3, "application": 3, "citv": 3, "anna": 5, "ngum": 5, "pursat": 3, "sangkat": 3, "vajiravudh": 10, "surrey": 3, "knight": 6, "sirikit": 18, "saovabha": 4, "kiernan": 8, "ump": 3, "rated": 3, "austin": 4, "ronja": 3, "divina": 3, "count": 5, "kirby": 9, "dedede": 4, "tiff": 10, "tuff": 3, "zoroastrian": 3, "vanga": 5, "dimitar": 4, "nickelodeon": 3, "wayne": 3, "kandal": 3, "char": 3, "svay": 5, "boeng": 5, "trapeang": 5, "krang": 5, "ruessei": 4, "thmei": 3, "tbaeng": 3, "ouk": 3, "sdok": 3, "direction": 7, "take": 3, "krom": 3, "vlamertinge": 7, "ypres": 5, "dalai": 4, "prc": 8, "lama": 5, "exo": 14, "baekhyun": 12, "inkigayo": 3, "cp": 57, "mag": 24, "ibid": 20, "xiv": 8, "xv": 8, "xvi": 8, "xviii": 8, "xix": 8, "xxvi": 7, "xxvii": 8, "xxxiii": 3, "xxxiv": 6, "xxxv": 8, "xxi": 5, "xxv": 4, "xxviii": 8, "xxxvi": 7, "xvii": 7, "xxix": 5, "xxxi": 7, "xxxii": 6, "xxxviii": 4, "xxxix": 6, "xl": 7, "xli": 6, "xlii": 5, "xlv": 7, "xlvi": 5, "xlvii": 4, "lii": 3, "liv": 3, "lvi": 3, "lvii": 5, "lx": 4, "nd": 5, "xxx": 7, "vbh": 19, "bapat": 4, "xxxvii": 5, "xliv": 3, "lv": 3, "xliii": 3, "xlviii": 3, "phat": 4, "liii": 3, "pts": 3, "spk": 3, "chinese": 5, "abhmv": 3, "carlos": 5, "binh": 4, "halal": 5, "cisark": 4, "protozoa": 3, "oocysts": 6, "kepler": 4, "abec": 4, "coli": 3, "copper": 4, "kanamycin": 3, "blood": 3, "parasites": 24, "paramphistomatatos": 3, "cestodes": 28, "taenia": 8, "scolex": 8, "capsul": 3, "cyste": 16, "echinococcus": 12, "cysticercus": 17, "bovis": 3, "saginata": 4, "solium": 4, "echinococcosis": 5, "ascaride": 3, "mis": 3, "kprp": 4, "paleolithic": 4, "wings": 4, "blackpink": 3, "prokaryotes": 3, "luca": 4, "plantae": 3, "viridiplantae": 3, "sporophyte": 4, "ais": 4, "nec": 3, "sarabun": 3, "psk": 3, "cercle": 3, "bangla": 3, "steam": 3, "hitler": 3, "della": 4, "nmsp": 4, "slorc": 3, "tnaot": 5, "spyder": 3, "ofc": 3, "lyon": 3, "aun": 5, "sarlat": 3, "films": 3, "mycobacteria": 3, "pcr": 8, "samanea": 3, "marty": 11, "melman": 8, "gloria": 9, "julien": 3, "kenorei": 3, "cobain": 3, "ttp": 3, "pavn": 7, "pathet": 3, "lpla": 3, "rla": 5, "khao": 3, "gnc": 6, "fox": 6, "lprp": 6, "roc": 3, "ming": 5, "shifu": 7, "lung": 7, "zeng": 3, "pleng": 3, "plo": 12, "dttv": 3, "nbtc": 4, "anne": 8, "michel": 3, "andy": 3, "monaco": 3, "leviev": 4, "ipl": 4, "ganymedian": 4, "joseon": 4, "yangban": 5, "maui": 18, "fiti": 12, "tala": 5, "tamatoa": 4, "roblox": 4, "judy": 12, "bogo": 5, "nick": 5, "emmitt": 4, "manchas": 5, "jailbreak": 4, "vtv": 34, "htv": 18, "lntv": 3, "rtgs": 9, "eep": 9, "croods": 5, "grug": 13, "cocos": 7, "endocarp": 3, "niu": 3, "schofield": 16, "blake": 9, "mrtv": 4, "kaew": 3, "kpnlf": 3, "linda": 4, "jewel": 6, "tulio": 3, "vx": 5, "lplaaf": 3, "nuol": 3, "ccp": 5, "bolyne": 4, "cromwell": 3, "zuba": 7, "makunga": 5, "arvn": 3, "ciff": 4, "vnu": 13, "bma": 3, "pandora": 8, "cameron": 11, "rda": 4, "naytiri": 5, "quaritch": 8, "grace": 5, "mendel": 3, "kmt": 4, "springer": 3, "ifma": 5, "cepea": 4, "nsu": 3, "swahili": 3, "inca": 3, "kossuth": 4, "quete": 3, "leduc": 4, "paramount": 5, "borgward": 3, "oppo": 3, "nantes": 7, "scorsese": 4, "dicaprio": 4, "osage": 3, "atc": 3}
|
model.safetensors
CHANGED
|
@@ -1,3 +1,3 @@
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
-
oid sha256:
|
| 3 |
size 74273672
|
|
|
|
| 1 |
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:464914d1cd432ba2079a5bc27623fe284e9c61fd1b0eedef1fcdc37346ff22a6
|
| 3 |
size 74273672
|