


Commit ·
a326822
0
Parent(s):
initial commit
Browse filesCo-authored-by: avskliar-nvidia <[email protected]>
This view is limited to 50 files because it contains too many changes. See raw diff
- .gitattributes +37 -0
- README.md +785 -0
- __init__.py +0 -0
- accuracy.png +3 -0
- bias.md +10 -0
- chat_template.jinja +240 -0
- config.json +0 -0
- configuration_nemotron_h.py +410 -0
- configuration_nemotron_h_omni.py +166 -0
- configuration_nemotron_h_puzzle.py +151 -0
- configuration_radio.py +93 -0
- explainability.md +14 -0
- generation_config.json +13 -0
- hf_quant_config.json +0 -0
- image_processing_nemotron_h_omni.py +216 -0
- model-00001-of-00090.safetensors +3 -0
- model-00002-of-00090.safetensors +3 -0
- model-00003-of-00090.safetensors +3 -0
- model-00004-of-00090.safetensors +3 -0
- model-00005-of-00090.safetensors +3 -0
- model-00006-of-00090.safetensors +3 -0
- model-00007-of-00090.safetensors +3 -0
- model-00008-of-00090.safetensors +3 -0
- model-00009-of-00090.safetensors +3 -0
- model-00010-of-00090.safetensors +3 -0
- model-00011-of-00090.safetensors +3 -0
- model-00012-of-00090.safetensors +3 -0
- model-00013-of-00090.safetensors +3 -0
- model-00014-of-00090.safetensors +3 -0
- model-00015-of-00090.safetensors +3 -0
- model-00016-of-00090.safetensors +3 -0
- model-00017-of-00090.safetensors +3 -0
- model-00018-of-00090.safetensors +3 -0
- model-00019-of-00090.safetensors +3 -0
- model-00020-of-00090.safetensors +3 -0
- model-00021-of-00090.safetensors +3 -0
- model-00022-of-00090.safetensors +3 -0
- model-00023-of-00090.safetensors +3 -0
- model-00024-of-00090.safetensors +3 -0
- model-00025-of-00090.safetensors +3 -0
- model-00026-of-00090.safetensors +3 -0
- model-00027-of-00090.safetensors +3 -0
- model-00028-of-00090.safetensors +3 -0
- model-00029-of-00090.safetensors +3 -0
- model-00030-of-00090.safetensors +3 -0
- model-00031-of-00090.safetensors +3 -0
- model-00032-of-00090.safetensors +3 -0
- model-00033-of-00090.safetensors +3 -0
- model-00034-of-00090.safetensors +3 -0
- model-00035-of-00090.safetensors +3 -0
.gitattributes
ADDED
|
@@ -0,0 +1,37 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
*.7z filter=lfs diff=lfs merge=lfs -text
|
| 2 |
+
*.arrow filter=lfs diff=lfs merge=lfs -text
|
| 3 |
+
*.bin filter=lfs diff=lfs merge=lfs -text
|
| 4 |
+
*.bz2 filter=lfs diff=lfs merge=lfs -text
|
| 5 |
+
*.ckpt filter=lfs diff=lfs merge=lfs -text
|
| 6 |
+
*.ftz filter=lfs diff=lfs merge=lfs -text
|
| 7 |
+
*.gz filter=lfs diff=lfs merge=lfs -text
|
| 8 |
+
*.h5 filter=lfs diff=lfs merge=lfs -text
|
| 9 |
+
*.joblib filter=lfs diff=lfs merge=lfs -text
|
| 10 |
+
*.lfs.* filter=lfs diff=lfs merge=lfs -text
|
| 11 |
+
*.mlmodel filter=lfs diff=lfs merge=lfs -text
|
| 12 |
+
*.model filter=lfs diff=lfs merge=lfs -text
|
| 13 |
+
*.msgpack filter=lfs diff=lfs merge=lfs -text
|
| 14 |
+
*.npy filter=lfs diff=lfs merge=lfs -text
|
| 15 |
+
*.npz filter=lfs diff=lfs merge=lfs -text
|
| 16 |
+
*.onnx filter=lfs diff=lfs merge=lfs -text
|
| 17 |
+
*.ot filter=lfs diff=lfs merge=lfs -text
|
| 18 |
+
*.parquet filter=lfs diff=lfs merge=lfs -text
|
| 19 |
+
*.pb filter=lfs diff=lfs merge=lfs -text
|
| 20 |
+
*.pickle filter=lfs diff=lfs merge=lfs -text
|
| 21 |
+
*.pkl filter=lfs diff=lfs merge=lfs -text
|
| 22 |
+
*.pt filter=lfs diff=lfs merge=lfs -text
|
| 23 |
+
*.pth filter=lfs diff=lfs merge=lfs -text
|
| 24 |
+
*.rar filter=lfs diff=lfs merge=lfs -text
|
| 25 |
+
*.safetensors filter=lfs diff=lfs merge=lfs -text
|
| 26 |
+
saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
| 27 |
+
*.tar.* filter=lfs diff=lfs merge=lfs -text
|
| 28 |
+
*.tar filter=lfs diff=lfs merge=lfs -text
|
| 29 |
+
*.tflite filter=lfs diff=lfs merge=lfs -text
|
| 30 |
+
*.tgz filter=lfs diff=lfs merge=lfs -text
|
| 31 |
+
*.wasm filter=lfs diff=lfs merge=lfs -text
|
| 32 |
+
*.xz filter=lfs diff=lfs merge=lfs -text
|
| 33 |
+
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
+
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
+
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
tokenizer.json filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
accuracy.png filter=lfs diff=lfs merge=lfs -text
|
README.md
ADDED
|
@@ -0,0 +1,785 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
library_name: transformers
|
| 3 |
+
license: other
|
| 4 |
+
license_name: openmdw-1.1
|
| 5 |
+
license_link: https://openmdw.ai/license/1-1/
|
| 6 |
+
pipeline_tag: image-text-to-text
|
| 7 |
+
language:
|
| 8 |
+
- en
|
| 9 |
+
- es
|
| 10 |
+
- fr
|
| 11 |
+
- de
|
| 12 |
+
- it
|
| 13 |
+
- ja
|
| 14 |
+
tags:
|
| 15 |
+
- nvidia
|
| 16 |
+
- pytorch
|
| 17 |
+
- nemotron-3.5
|
| 18 |
+
base_model: nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-BF16
|
| 19 |
+
base_model_relation: quantized
|
| 20 |
+
datasets:
|
| 21 |
+
- nvidia/nemotron-post-training-v3
|
| 22 |
+
- nvidia/nemotron-pre-training-datasets
|
| 23 |
+
track_downloads: true
|
| 24 |
+
---
|
| 25 |
+
|
| 26 |
+
# nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB
|
| 27 |
+
|
| 28 |
+
<div align="center" style="line-height: 1;">
|
| 29 |
+
<a href="https://huggingface.co/collections/nvidia/nemotron-pre-training-datasets" target="_blank" style="margin: 2px;">
|
| 30 |
+
<img alt="Pre-Training Datasets" src="https://img.shields.io/badge/🗄️_Pre--Training_Datasets-Available_Here-76B900?logoColor=white" style="display: inline-block; vertical-align: middle;"/>
|
| 31 |
+
</a>
|
| 32 |
+
<a href="https://developer.nvidia.com/nemotron" target="_blank" style="margin: 2px;">
|
| 33 |
+
<img alt="Homepage" src="https://img.shields.io/badge/🏠Nemotron Developer Page-Learn More Here!-536af5?color=76B900&logoColor=white" style="display: inline-block; vertical-align: middle;"/>
|
| 34 |
+
</a>
|
| 35 |
+
<a href="https://discord.gg/9xpKQtVvrk" target="_blank" style="margin: 2px;">
|
| 36 |
+
<img alt="Discord" src="https://img.shields.io/badge/Discord-NVIDIA%20AI%20Developer-7289da?logo=discord&logoColor=white&color=7289da" style="display: inline-block; vertical-align: middle;"/>
|
| 37 |
+
</a>
|
| 38 |
+
</div>
|
| 39 |
+
|
| 40 |
+
<div style="text-align: center; line-height: 1;">
|
| 41 |
+
<a href="https://openmdw.ai/license/1-1/" style="margin: 2px;">
|
| 42 |
+
<img alt="License" src="https://img.shields.io/badge/License-OpenMDW--1.1-f5de53" style="display: inline-block; vertical-align: middle;"/>
|
| 43 |
+
</a>
|
| 44 |
+
</div>
|
| 45 |
+
|
| 46 |
+

|
| 47 |
+
|
| 48 |
+
## Description
|
| 49 |
+
|
| 50 |
+
**NVIDIA Nemotron 3.5 Bolt 74B-A9B 24GB** is a vision-language model (VLM) designed to run everyday agentic tasks locally, using a native 2-bit quantization to fit in 24GB of memory and run alongside other applications. It optimizes intelligence and speed per GB. It aims to achieve the optimal balance between speed and intelligence, being faster than most popular dense models while smarter than most popular MoE models with a similar memory footprint.
|
| 51 |
+
|
| 52 |
+
This model is ready for commercial or non‑commercial use.
|
| 53 |
+
|
| 54 |
+
## Model Summary
|
| 55 |
+
|
| 56 |
+
| | |
|
| 57 |
+
|:---|:---|
|
| 58 |
+
| **Total Parameters** | 74B (9B active) |
|
| 59 |
+
| **Architecture** | Mamba-2–Transformer hybrid LatentMoE with a C-RADIO v4-H vision encoder |
|
| 60 |
+
| **Precision** | IQ2 (2-bit quantization with quantization-aware training) |
|
| 61 |
+
| **Context Length** | Up to 256K tokens |
|
| 62 |
+
| **Inputs / Outputs** | Text, images, and video / text |
|
| 63 |
+
| **Deployment** | 24GB packed model; vLLM on NVIDIA Ampere (A100), Hopper (H100-80GB), or Blackwell |
|
| 64 |
+
| **Speculative Decoding** | LiLiCorr drafter via DFlash; 7 speculative tokens in the companion Bolt vLLM recipes |
|
| 65 |
+
| **Reasoning Mode** | Chat-template controls (`enable_thinking=True/False`), inherited from the Super 3.5 VL client |
|
| 66 |
+
| **Recommended Sampling** | Text: temperature 1.0, top_p 0.95 (inherited from the Super 3.5 VL client) |
|
| 67 |
+
| **Best For** | Running everyday agentic tasks locally |
|
| 68 |
+
| **License** | [OpenMDW-1.1](https://openmdw.ai/license/1-1/) |
|
| 69 |
+
|
| 70 |
+
## Model Overview
|
| 71 |
+
|
| 72 |
+
**Model Developer:** NVIDIA Corporation
|
| 73 |
+
|
| 74 |
+
**Model Dates:** December 2025 - May 2026
|
| 75 |
+
|
| 76 |
+
**Data Freshness:**
|
| 77 |
+
|
| 78 |
+
* The post-training data has a cutoff date of May 2026.
|
| 79 |
+
|
| 80 |
+
### What is Nemotron?
|
| 81 |
+
|
| 82 |
+
NVIDIA Nemotron™ is a family of open models with open weights, training data, and recipes, delivering leading efficiency and accuracy for building specialized AI agents.
|
| 83 |
+
|
| 84 |
+
## Quick Start
|
| 85 |
+
|
| 86 |
+
This model requires the following vLLM version or newer. Please use this command.
|
| 87 |
+
|
| 88 |
+
```sh
|
| 89 |
+
docker run -it --name vllm --gpus all --ipc=host -p 8000:8000 \
|
| 90 |
+
--entrypoint /bin/bash \
|
| 91 |
+
vllm/vllm-openai:nightly-77154ca6116ae34cbfe314beef1016bde9b63989
|
| 92 |
+
|
| 93 |
+
pip install b12x
|
| 94 |
+
vllm download-kernels
|
| 95 |
+
|
| 96 |
+
wget https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB/resolve/main/ultra_v3_reasoning_parser.py
|
| 97 |
+
|
| 98 |
+
export VLLM_USE_V2_MODEL_RUNNER=1
|
| 99 |
+
vllm serve nvidia/Nemotron-3.5-Bolt-74B-A9B-24GB \
|
| 100 |
+
--trust-remote-code \
|
| 101 |
+
--load-format auto \
|
| 102 |
+
--tensor-parallel-size 1 \
|
| 103 |
+
--max-model-len 262144 \
|
| 104 |
+
--max-num-seqs 1 \
|
| 105 |
+
--enable-chunked-prefill \
|
| 106 |
+
--kv-cache-dtype fp8 \
|
| 107 |
+
--linear-backend b12x \
|
| 108 |
+
--moe-backend b12x \
|
| 109 |
+
--attention-backend FLASHINFER \
|
| 110 |
+
--mamba-backend flashinfer \
|
| 111 |
+
--mamba-ssm-cache-dtype bfloat16 \
|
| 112 |
+
--mamba-cache-dtype bfloat16 \
|
| 113 |
+
--mamba-cache-mode align \
|
| 114 |
+
--seed 42 \
|
| 115 |
+
--allowed-local-media-path / \
|
| 116 |
+
--limit-mm-per-prompt '{"video":1,"image":1}' \
|
| 117 |
+
--video-pruning-rate 0.5 \
|
| 118 |
+
--media-io-kwargs '{"video":{"fps":2,"num_frames":256}}' \
|
| 119 |
+
--enable-auto-tool-choice \
|
| 120 |
+
--tool-call-parser qwen3_coder \
|
| 121 |
+
--reasoning-parser-plugin ultra_v3_reasoning_parser.py \
|
| 122 |
+
--reasoning-parser ultra_v3 \
|
| 123 |
+
--speculative-config '{"method":"dflash","model":"nvidia/Nemotron-3.5-Bolt-74B-A9B-24GB-LiLiCorr","num_speculative_tokens":7,"rejection_sample_method":"standard","attention_backend":"FLASHINFER","draft_load_config":{"load_format":"auto"}}'
|
| 124 |
+
```
|
| 125 |
+
|
| 126 |
+
For more details on how to deploy and use the model — see the [Quick Start Guide](#quick-start-guide) below!
|
| 127 |
+
|
| 128 |
+
## License/Terms of Use
|
| 129 |
+
|
| 130 |
+
**Governing Terms:** Use of the models is governed by the [OpenMDW License Agreement, version 1.1](https://github.com/OpenMDW/OpenMDW/blob/main/1.1/LICENSE.OpenMDW-1.1).
|
| 131 |
+
|
| 132 |
+
## Benchmarks
|
| 133 |
+
|
| 134 |
+
| Benchmark | Qwen3.6-35B-A3B BF16 | Gemma4 26B-A4B-BF16 | Nemotron 3.5 Lightning 30B-A3B-BF16 | Nemotron 3.5 Bolt 74B-A9B-24GB (IQ2) |
|
| 135 |
+
|---|---:|---:|---:|---:|
|
| 136 |
+
| GDPVal-AA-V2 | 25.75 | 15.33 | 18.26 | **28.47** |
|
| 137 |
+
| Terminal-Bench 2.1 | 44.38 | 37.22 | 23.46 | **50.98** |
|
| 138 |
+
| Tau3 Banking | 10.52 | 14.02 | 9.48 | **17.01** |
|
| 139 |
+
| HLE (no tools) | 19.56 | 17.42 | 10.47 | **25.30** |
|
| 140 |
+
| AA-Omniscience accuracy | 19.47 | **22.17** | 16.63 | 16.90 |
|
| 141 |
+
| SciCode | 35.33 | 40.28 | 31.38 | **41.02** |
|
| 142 |
+
| GPQA Diamond | 83.40 | 79.61 | 75.57 | **86.43** |
|
| 143 |
+
| AA-LCR | 61.06 | 57.56 | 49.19 | **64.06** |
|
| 144 |
+
| AA-Omniscience non-hallucination | 65.85 | 14.22 | **68.81** | 61.27 |
|
| 145 |
+
| PinchBench | **88.07** | 74.70 | 83.43 | 87.82 |
|
| 146 |
+
| MCP-Atlas | 51.20* | — | 46.4 | **52.20** |
|
| 147 |
+
| BrowseComp | 48.74 | 26.30 | 36.81 | **66.75** |
|
| 148 |
+
| WebArena (vision) | 36.60 | 38.2 | — | **50.86** |
|
| 149 |
+
|
| 150 |
+
\*The reported MCP-Atlas score for Qwen3.6-35B-A3B-BF16 is 62.8; we measured 51.2 on the 500 public MCP-Atlas tasks.
|
| 151 |
+
|
| 152 |
+
### Deployment Geography: Global
|
| 153 |
+
|
| 154 |
+
### Use Case
|
| 155 |
+
|
| 156 |
+
Nemotron-3.5-Bolt-74B-A9B-24GB is optimized for use in local agent harnesses and general agentic tasks involving tool calling, web browsing, and terminal use. English and coding languages are the primary languages, with Spanish, French, German, Italian, and Japanese also being supported.
|
| 157 |
+
|
| 158 |
+
### Release Date
|
| 159 |
+
|
| 160 |
+
Hugging Face 10/15/2026 via https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB
|
| 161 |
+
|
| 162 |
+
## Reference(s)
|
| 163 |
+
|
| 164 |
+
* [NVIDIA Nemotron 3 model family on Hugging Face](https://huggingface.co/collections/nvidia/nvidia-nemotron-v3)
|
| 165 |
+
* [NVIDIA Nemotron 3.5 Bolt 74B A9B 24GB Technical Report](https://research.nvidia.com/labs/nemotron/files/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-Technical-Report.pdf)
|
| 166 |
+
* [NVIDIA Nemotron 3.5 Bolt 74B A9B 24GB Technical Blog](https://research.nvidia.com/labs/nemotron/Nemotron-3.5-Bolt-24GB/)
|
| 167 |
+
|
| 168 |
+
## Model Architecture
|
| 169 |
+
|
| 170 |
+
- **Architecture Type:** Mamba2-Transformer Hybrid Mixture of Experts (MoE) with vision encoder
|
| 171 |
+
- **Network Architecture:** Nemotron Hybrid LatentMoE
|
| 172 |
+
- Nemotron 3.5 Super LLM — hybrid Mamba-2 + MoE + Attention backbone
|
| 173 |
+
- [C-RADIO v4-H](https://huggingface.co/nvidia/C-RADIOv4-H) — vision encoder for image and video frames, connected to the backbone through an MLP projector
|
| 174 |
+
- **Number of model parameters:** 74B Total / 9B Active
|
| 175 |
+
|
| 176 |
+
|
| 177 |
+
## Model Design
|
| 178 |
+
|
| 179 |
+
The model was compressed from [Nemotron 3.5 Super VL 120B-A12B](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16).
|
| 180 |
+
The model supports up to 256K tokens of context. The prompt, visual inputs, conversation history, tool results, and generated response share this context window. Individual deployment recipes may use a smaller context window to accommodate the available GPU memory and concurrency.
|
| 181 |
+
|
| 182 |
+
## Training Methodology
|
| 183 |
+
|
| 184 |
+
**Stage 1: Compression**
|
| 185 |
+
|
| 186 |
+
We compress the Nemotron 3.5 Super VL parent checkpoint (120B-A12B) to Nemotron 3.5 Bolt 74B-A9B 24GB using [Star Elastic](https://arxiv.org/pdf/2605.07182), a push-button, router-guided architecture search and end-to-end compression algorithm invented at NVIDIA.
|
| 187 |
+
|
| 188 |
+
A budget-conditioned router heterogeneously selects routed-expert counts and MoE intermediate widths across layers, while expert top-K is fixed at 9, down from 22 in the parent model. The router’s architecture search targets a deployment footprint below 24 GB at batch size 1 and 128K context. Its budget already accounts for subsequent quantization and the precision of weights and runtime states (such as 2-bit routed-expert weights and 16-bit SSM states, to name but two, with further details provided in the quantization section). The objective is to find the architecture with the lowest knowledge-distillation loss that satisfies this memory budget, jointly optimizing architecture and model weights through knowledge distillation and a model-size penalty.
|
| 189 |
+
|
| 190 |
+
Architecture search runs at 8K context, with the router converging during the first 8B tokens. Once the architecture is fixed, recovery continues at 8K to a total of 72B tokens, followed by 48B tokens at 128K context, for 120B tokens overall. Following Star Elastic’s schedule, this takes advantage of faster knowledge recovery at 8K rather than starting directly at 128K, before extending recovery to long contexts.
|
| 191 |
+
|
| 192 |
+
**Stage 2: Vision Adaptor Training:**
|
| 193 |
+
|
| 194 |
+
We constructed the Nemotron 3.5 Bolt 74B-A9B VL model by re-attaching the trained vision tower from the parent Super 3.5 VL model back to the compressed LLM. We then performed lightweight fine-tuning of only the vision-to-language projection layers (the vision adapter), using image-text datasets previously used to train the parent model’s vision adapter.
|
| 195 |
+
Training used an image-only blend of approximately 6.6M samples per epoch. The blend comprised a general English mix of captioning, visual question answering, counting, and document datasets (\~2M samples), CC3M images recaptioned by Qwen3-30B (\~1.7M samples), and Chinese document OCR data (\~2.5M samples). It also included PDF and table document data, along with datasets used to train NVCLIP OCR. No video or text-only data was used during vision adapter training.
|
| 196 |
+
|
| 197 |
+
**Stage 3: Supervised Fine-Tuning**
|
| 198 |
+
|
| 199 |
+
Post vision-adaptor training, the model is trained with vision heavy SFT training to recover vision capabilities further. Before moving to multi-turn agentic training, we applied checkpoint merging as it provided more well-rounded capabilities across text and vision capabilities. The model was further trained on agentic environments and RLHF, and a final checkpoint merging yielded the final BF16 checkpoint.
|
| 200 |
+
|
| 201 |
+
For vision, we used dataset blends targeting ScreenSpot Pro (\~10.1B tokens) and WebArena (\~9.5B tokens), supplemented with small amounts of MolmoWeb/WebVoyager browsing data, CharXiv chart data, HopChain multi-page document data, and BabyVision-targeted reasoning data. For text, we used a downsampled blend of Kimi-K3-generated synthetic datasets targeting the AIME, GPQA Diamond, Terminal Bench 2.1, SciCode, AA-LCR, APEX, and LMArena benchmarks. We also incorporated a very small proportion of GLM 5.2-generated trajectories targeting MCP-Atlas. During this stage, the LLM, vision-adaptor and the vision encoder were all trained.
|
| 202 |
+
|
| 203 |
+
Following the vision-heavy SFT stage, we performed model merge with the vision adaptor only trained checkpoint using SLERP interpolation. Vision adaptor training and SFT stage with vision heavy dataset is critical to recovering vision benchmarks, as compression was performed only on the text tower of the parent model with knowledge distillation applied to recover text only benchmarks during compression. There is little to no degradation in text accuracy.
|
| 204 |
+
|
| 205 |
+
**Stage 4: Reinforcement Learning**
|
| 206 |
+
|
| 207 |
+
The model was further trained with RLHF and several stages of E2E RL training to improve agentic capabilities and minimize task completion times for tool-heavy multi-turn workloads. During RLHF, we used the Nemotron 3 Ultra GenRM model which was also trained with a reasoning penalty for token efficiency.
|
| 208 |
+
|
| 209 |
+
For further training, we have used multiple agentic environments with full E2E GRPO to target MCP and SWE tasks. We use 32 prompts with 16 generations per prompt, giving a total of 512 batch size. For the Terminal environment, it was not used for RL training, but it has been used to generate on-policy rollouts to prevent regressions during quantization. Our MCP E2E RL environment includes a simulated MCP-server with tasks requiring multi-turn tool interactions to achieve the goals. Training on this environment improved MCP use capabilities and provided around 8 nominal point increase from \~48 to \~56 on 500 public task subset out of 1000 total tasks on the MCP-Atlas benchmark. The scoring mechanism for the MCP-Atlas benchmark uses a 0.75 threshold on coverage metric, i.e. the mean claim score (each task has multiple claims that are scored separately) and it provides a binary pass / fail score per task coverage in the end. We observed further RL training continued to provide improvement on coverage scores across tasks, but it did not translate to post-threshold based official score improvements. Whether longer RL training would have eventually provided improvements on the benchmark remains an open-question. SWE-RL E2E training also used some optimizations to improve efficiency in terms of generated tokens and tool-call efficiency. Training used 64 prompts with 16 generations per prompt, giving 1,024 trajectories per optimizer step, with a maximum total sequence length of 196,608 tokens. We used Adam at a learning rate of \$3 \\times 10^{-6}\$. This training also led to accuracy and efficiency improvements on PinchBench as a generalization benefit with scores up-to 90.4 across 10-repeat average.
|
| 210 |
+
|
| 211 |
+
**Stage 5: Quantization**
|
| 212 |
+
|
| 213 |
+
We quantize the experts of the model to 2-bits to fit the network in RTX Spark's memory. We use quantization-aware-distillation ([QAD](https://arxiv.org/pdf/2601.20088)) to recover the accuracy.
|
| 214 |
+
Quantization was performed using [Modelopt](https://github.com/NVIDIA/Model-Optimizer).To further reduce the size of the network with quantization to 24GB, we quantize all experts to IQ2-XXS, such that each parameter has 2.0625 bits per element ([ggml-org](http://ggml.org)). This includes both the routed and shared experts. Previous work on low-bit quantization such as ParetoQ ([Liu et al., 2025](https://arxiv.org/pdf/2502.02631)) and Quest ([Panferov et al., 2025](https://arxiv.org/abs/2502.05003)) have shown that lower-bits for FC layers could be pareto-optimal, i.e., layers at twice the size in 2 bits are better than the original size in 4 bits. This is a major lever we use to create our for-size checkpoint. In low-batch size inference scenarios, the latency of the kernels also improve linear with the compression rate of the weights, leading to significant inference speed gains due to the low-bit quantization. We performed further mixed-precision to achieve our memory constraint without impacting the capabilities of the model. The model keeps some layers quantized to either NVFP4 (Mamba layers) or Q8\_0 (Embedding and output layers).
|
| 215 |
+
|
| 216 |
+
Nemotron-3.5-Bolt-74B-A9B-24GB is a result of the above work.
|
| 217 |
+
|
| 218 |
+
|
| 219 |
+
## Input
|
| 220 |
+
|
| 221 |
+
- **Input Type(s):** Image, Video, Text
|
| 222 |
+
- **Input Format(s):**
|
| 223 |
+
- Image: Red, Green, Blue (RGB) (jpeg, png)
|
| 224 |
+
- Video: mp4, up to 2 minutes. For 1080p videos, sample up to 1 FPS / 128 frames. For lower-resolution videos such as 720p, higher temporal sampling such as 2 FPS / 256 frames may be used.
|
| 225 |
+
- Text: String
|
| 226 |
+
- **Input Parameters:**
|
| 227 |
+
- Image: Two-Dimensional (2D)
|
| 228 |
+
- Video: Three-Dimensional (3D)
|
| 229 |
+
- Text: One-Dimensional (1D)
|
| 230 |
+
- **Other Properties Related to Input:** Maximum context length up to 256K tokens. Supported languages include English, French, Spanish, Italian, German, Japanese, Hindi, Korean, Brazilian Portuguese, and Chinese.
|
| 231 |
+
|
| 232 |
+
## Output
|
| 233 |
+
|
| 234 |
+
- **Output Type(s):** Text
|
| 235 |
+
- **Output Format:** String
|
| 236 |
+
- **Output Parameters:** One-Dimensional (1D): Sequences
|
| 237 |
+
- **Other Properties Related to Output:** Maximum context length up to 256K tokens. Supports JSON output format, reasoning output with chain-of-thought, and tool calling.
|
| 238 |
+
|
| 239 |
+
Our AI models are designed and/or optimized to run on NVIDIA GPU-accelerated systems. By leveraging NVIDIA's hardware (e.g. GPU cores) and software frameworks (e.g., CUDA libraries), the model achieves faster training and inference times compared to CPU-only solutions.
|
| 240 |
+
|
| 241 |
+
## Software Integration
|
| 242 |
+
|
| 243 |
+
- **Runtime Engine(s):** vLLM
|
| 244 |
+
- **Supported Hardware Microarchitecture Compatibility:** NVIDIA Blackwell SM120 & SM121
|
| 245 |
+
- **Supported Operating System(s):** Linux
|
| 246 |
+
|
| 247 |
+
The integration of foundation and fine-tuned models into AI systems requires additional testing using use-case-specific data to ensure safe and effective deployment. Following the V-model methodology, iterative testing and validation at both unit and system levels are essential to mitigate risks, meet technical and functional requirements, and ensure compliance with safety and ethical standards before deployment.
|
| 248 |
+
|
| 249 |
+
## Model Version(s)
|
| 250 |
+
|
| 251 |
+
* Nemotron-3.5-Bolt-74B-A9B-24GB
|
| 252 |
+
|
| 253 |
+
Other variants and drafter models are availble.
|
| 254 |
+
- [nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB)
|
| 255 |
+
- [nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-GGUF](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-GGUF)
|
| 256 |
+
- [nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-BF16](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-BF16)
|
| 257 |
+
- [nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-LiLiCorr](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-LiLiCorr)
|
| 258 |
+
- [nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-LiLiCorr-GGUF](https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB-LiLiCorr-GGUF)
|
| 259 |
+
|
| 260 |
+
|
| 261 |
+
## Quick Start Guide
|
| 262 |
+
|
| 263 |
+
### vLLM
|
| 264 |
+
|
| 265 |
+
```sh
|
| 266 |
+
export VLLM_USE_V2_MODEL_RUNNER=1
|
| 267 |
+
|
| 268 |
+
vllm serve nvidia/Nemotron-3.5-Bolt-74B-A9B-24GB \
|
| 269 |
+
--trust-remote-code \
|
| 270 |
+
--load-format auto \
|
| 271 |
+
--tensor-parallel-size 1 \
|
| 272 |
+
--max-model-len 262144 \
|
| 273 |
+
--max-num-seqs 1 \
|
| 274 |
+
--enable-chunked-prefill \
|
| 275 |
+
--kv-cache-dtype fp8 \
|
| 276 |
+
--linear-backend b12x \
|
| 277 |
+
--moe-backend b12x \
|
| 278 |
+
--attention-backend FLASHINFER \
|
| 279 |
+
--mamba-backend flashinfer \
|
| 280 |
+
--mamba-ssm-cache-dtype bfloat16 \
|
| 281 |
+
--mamba-cache-dtype bfloat16 \
|
| 282 |
+
--mamba-cache-mode align \
|
| 283 |
+
--seed 42 \
|
| 284 |
+
--allowed-local-media-path / \
|
| 285 |
+
--limit-mm-per-prompt '{"video":1,"image":1}' \
|
| 286 |
+
--video-pruning-rate 0.5 \
|
| 287 |
+
--media-io-kwargs '{"video":{"fps":2,"num_frames":256}}' \
|
| 288 |
+
--enable-auto-tool-choice \
|
| 289 |
+
--tool-call-parser qwen3_coder \
|
| 290 |
+
--reasoning-parser-plugin ultra_v3_reasoning_parser.py \
|
| 291 |
+
--reasoning-parser ultra_v3 \
|
| 292 |
+
--speculative-config '{"method":"dflash","model":"nvidia/Nemotron-3.5-Bolt-74B-A9B-24GB-LiLiCorr","num_speculative_tokens":7,"rejection_sample_method":"standard","attention_backend":"FLASHINFER","draft_load_config":{"load_format":"auto"}}'
|
| 293 |
+
```
|
| 294 |
+
|
| 295 |
+
### API Client
|
| 296 |
+
|
| 297 |
+
Install the OpenAI-compatible client:
|
| 298 |
+
|
| 299 |
+
```bash
|
| 300 |
+
pip install openai
|
| 301 |
+
```
|
| 302 |
+
|
| 303 |
+
#### Text and reasoning
|
| 304 |
+
|
| 305 |
+
```python
|
| 306 |
+
from openai import OpenAI
|
| 307 |
+
|
| 308 |
+
client = OpenAI(base_url="http://localhost:8000/v1", api_key="EMPTY")
|
| 309 |
+
model = "nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB"
|
| 310 |
+
|
| 311 |
+
response = client.chat.completions.create(
|
| 312 |
+
model=model,
|
| 313 |
+
messages=[{"role": "user", "content": "Explain why binary search takes logarithmic time."}],
|
| 314 |
+
temperature=1.0,
|
| 315 |
+
top_p=0.95,
|
| 316 |
+
max_tokens=16384,
|
| 317 |
+
extra_body={"chat_template_kwargs": {"enable_thinking": True}},
|
| 318 |
+
)
|
| 319 |
+
choice = response.choices[0]
|
| 320 |
+
if choice.finish_reason == "length":
|
| 321 |
+
raise RuntimeError("The response reached max_tokens; increase the output budget.")
|
| 322 |
+
print(choice.message.content)
|
| 323 |
+
```
|
| 324 |
+
|
| 325 |
+
Set `enable_thinking` to `False` to disable reasoning. For medium reasoning effort, use `{"enable_thinking": True, "medium_effort": True}`. Reasoning tokens and the final answer share the `max_tokens` budget.
|
| 326 |
+
|
| 327 |
+
#### Tool calling
|
| 328 |
+
|
| 329 |
+
The model requests a tool call; the application executes it and returns the result. This complete example uses a local inventory lookup.
|
| 330 |
+
|
| 331 |
+
```python
|
| 332 |
+
import json
|
| 333 |
+
from openai import OpenAI
|
| 334 |
+
|
| 335 |
+
client = OpenAI(base_url="http://localhost:8000/v1", api_key="EMPTY")
|
| 336 |
+
model = "nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-24GB"
|
| 337 |
+
inventory = {"keyboard": 12, "monitor": 5}
|
| 338 |
+
tools = [{"type": "function", "function": {
|
| 339 |
+
"name": "get_inventory",
|
| 340 |
+
"description": "Return the inventory count for a product.",
|
| 341 |
+
"parameters": {
|
| 342 |
+
"type": "object",
|
| 343 |
+
"properties": {"product": {"type": "string", "enum": ["keyboard", "monitor"]}},
|
| 344 |
+
"required": ["product"],
|
| 345 |
+
"additionalProperties": False,
|
| 346 |
+
},
|
| 347 |
+
}}]
|
| 348 |
+
messages = [{"role": "user", "content": "How many keyboards are in stock?"}]
|
| 349 |
+
|
| 350 |
+
def complete(history, tool_choice="auto"):
|
| 351 |
+
response = client.chat.completions.create(
|
| 352 |
+
model=model,
|
| 353 |
+
messages=history,
|
| 354 |
+
tools=tools,
|
| 355 |
+
tool_choice=tool_choice,
|
| 356 |
+
temperature=1.0,
|
| 357 |
+
top_p=0.95,
|
| 358 |
+
max_tokens=16384,
|
| 359 |
+
extra_body={"chat_template_kwargs": {"enable_thinking": True}},
|
| 360 |
+
)
|
| 361 |
+
choice = response.choices[0]
|
| 362 |
+
if choice.finish_reason == "length":
|
| 363 |
+
raise RuntimeError("The response was truncated; increase max_tokens.")
|
| 364 |
+
return choice.message
|
| 365 |
+
|
| 366 |
+
message = complete(messages)
|
| 367 |
+
messages.append(message.model_dump(exclude_none=True))
|
| 368 |
+
if not message.tool_calls:
|
| 369 |
+
print(message.content)
|
| 370 |
+
else:
|
| 371 |
+
for call in message.tool_calls:
|
| 372 |
+
arguments = json.loads(call.function.arguments)
|
| 373 |
+
if (call.function.name != "get_inventory"
|
| 374 |
+
or not isinstance(arguments, dict)
|
| 375 |
+
or set(arguments) != {"product"}
|
| 376 |
+
or not isinstance(arguments["product"], str)
|
| 377 |
+
or arguments["product"] not in inventory):
|
| 378 |
+
raise ValueError("Invalid inventory tool call")
|
| 379 |
+
product = arguments["product"]
|
| 380 |
+
messages.append({
|
| 381 |
+
"role": "tool",
|
| 382 |
+
"tool_call_id": call.id,
|
| 383 |
+
"content": json.dumps({"product": product, "count": inventory[product]}),
|
| 384 |
+
})
|
| 385 |
+
print(complete(messages, tool_choice="none").content)
|
| 386 |
+
```
|
| 387 |
+
|
| 388 |
+
## Training, Testing, and Evaluation Datasets
|
| 389 |
+
|
| 390 |
+
### Training
|
| 391 |
+
|
| 392 |
+
#### Dataset Overview
|
| 393 |
+
|
| 394 |
+
##### Parent Corpus
|
| 395 |
+
|
| 396 |
+
The parent NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 model card reports the following foundation and post-training corpus information. Foundation training size is separate from Bolt’s 80-billion-token compression training data described below.
|
| 397 |
+
|
| 398 |
+
**Data Modality:** Text, images, and video<br>
|
| 399 |
+
**Foundation Training Data Size:** More than 20 trillion tokens<br>
|
| 400 |
+
**Foundation Data Collection Period:** 2013 to December 2025<br>
|
| 401 |
+
**Data Collection Method:** Hybrid: automated, manually collected, and synthetic<br>
|
| 402 |
+
**Labeling Method:** Hybrid: automated, manually labeled, and synthetic
|
| 403 |
+
|
| 404 |
+
The foundation corpus contains curated and synthetic text covering English, 19 other spoken languages, and 43 programming languages. Sources include webpages, dialogue, articles, code, and other written materials across math, science, legal, finance, and general knowledge domains.
|
| 405 |
+
|
| 406 |
+
The post-training corpus includes reasoning, coding, tool use, instruction following, structured outputs, chat, safety, and long-context tasks, together with image and video understanding. Synthetic trajectories are filtered for structural correctness, repetition, and task validity.
|
| 407 |
+
|
| 408 |
+
##### Bolt Training
|
| 409 |
+
|
| 410 |
+
**Data Modality:** Image, Video, Text
|
| 411 |
+
**Training Data Size:** 80 Billion Tokens
|
| 412 |
+
**Dataset partition:** *Training [100%], testing [0%], validation [0%]*
|
| 413 |
+
**Time period for training data collection:** 2013 to February 24, 2026
|
| 414 |
+
**Time period for testing data collection:** 2013 to February 24, 2026
|
| 415 |
+
**Time period for validation data collection:** 2013 to February 24, 2026
|
| 416 |
+
**Data Collection Method by dataset:** Hybrid: Automated, Manually-Collected, Synthetic
|
| 417 |
+
**Labeling Method by dataset:** Hybrid: Automated, Manually-Labeled, Synthetic
|
| 418 |
+
|
| 419 |
+
Nemotron 3.5 Bolt 74B-A9B is a compressed version of the NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 model. The below describes the pre-training and post-training methodology used to develop the NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 model. Whereas Super VL had a training data size of more than 20T tokens, Nemotron 3.5 Bolt 74B-A9B has a training data size of 80B tokens.
|
| 420 |
+
|
| 421 |
+
The NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 language backbone is pre-trained on a large corpus of high-quality curated and synthetically-generated text data. Our sources cover a variety of document types such as: webpages, dialogue, articles, and other written materials. The corpus spans domains including legal, math, science, finance, and more. We also include a small portion of question-answering, and alignment style data to improve model accuracy.
|
| 422 |
+
|
| 423 |
+
Multimodal training data was assembled from a diverse collection of image, video, and text datasets. Raw datasets were first converted into a standardized JSONL format with unified conversation-turn structure. Image and video datasets were paired with question-answer annotations, often regenerated or refined using large vision-language models to improve quality and consistency. Quality filtering was applied using model-based judges to remove low-quality, unsafe, or off-topic samples. Deduplication and CSAM scanning were performed across all image datasets. Data was then packed into fixed-length sequences for efficient training.
|
| 424 |
+
|
| 425 |
+
Multiple safety measures were implemented throughout the data pipeline. All image/text datasets underwent CSAM (Child Sexual Abuse Material) scanning, with results tracked per dataset. Content safety filtering was applied using two independent safety judge models to flag and remove samples containing harmful content including weapons references, criminal planning, sexual content involving minors, harassment, hate speech, profanity, threats, violence, or suicide-related content. Synthetic data generation pipelines included explicit quality and safety filtering stages.
|
| 426 |
+
|
| 427 |
+
The post-training corpus for NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 consists of high-quality curated and synthetically-generated data across text+image, text+video, and text-only samples, structured to support document reasoning, computer use, and long-horizon workflows. During post-training, we generate synthetic data by distilling trajectories, solutions, and translations from strong teacher models and agent systems, often grounded in real tasks or documents and aggressively filtered for quality. Across all pipelines we stack automated verification — compilers, numerical checks, language identification, model-based judges — to ensure our data is high quality.
|
| 428 |
+
|
| 429 |
+
For all domains, we apply a unified data filtering pipeline to ensure that only high-quality, license-compliant, and verifiable samples are used for post-training. We first discard malformed examples using structural checks (e.g., missing tool definitions when tool calls are present). We then aggressively filter reasoning traces exhibiting pathological repetition, such as repeated n-grams within a sliding window or across the entire trajectory, which we found to be a strong indicator of malformed or low-quality reasoning. Finally, based on internal audits of synthetically generated datasets, we observed that some teacher models occasionally produce reasoning traces and final responses that implicitly align with specific political entities or promote nationalistic narratives. To mitigate this, we apply targeted keyword- and regex-based filters and remove all trajectories matching such behavior.
|
| 430 |
+
|
| 431 |
+
Prior to training this model, NVIDIA implemented measures to respect EU text and data mining opt-outs by (1) respecting robots.txt instructions to the extent such signals reflect valid rights reservations, and (2) filtering datasets on any actionable metadata identifiers provided by rightsholders.
|
| 432 |
+
|
| 433 |
+
For more information about the datasets used to train this model, please see the [Public Summary of Training Content](https://developer.download.nvidia.com/assets/nemo/docs/public-summary-of-training-content-for-nvidia-nemotron.pdf)
|
| 434 |
+
|
| 435 |
+
<details>
|
| 436 |
+
<summary>Detailed dataset information</summary>
|
| 437 |
+
|
| 438 |
+
#### **Base Pre-Training Corpus (Nemotron 3 Foundation)**
|
| 439 |
+
|
| 440 |
+
The foundation of the model is trained on the Nemotron 3 corpus, comprising the following datasets from the [Nemotron Pretraining Datasets collection](https://huggingface.co/collections/nvidia/nemotron-pre-training-datasets):
|
| 441 |
+
|
| 442 |
+
| Dataset Collection | Token Counts | Description |
|
| 443 |
+
| :--- | :--- | :--- |
|
| 444 |
+
| **Nemotron-CC-v2** & **v2.1** | 9.1T | A massive collection of English web data filtered from Common Crawl, including 2.5T+ tokens of new organic, translated, and synthetically rephrased content. |
|
| 445 |
+
| **Nemotron-CC-Code-v1** | 427.9B | High-quality code tokens extracted from Common Crawl using the Lynx + LLM pipeline to preserve structure and equations. |
|
| 446 |
+
| **Nemotron-Pretraining-Code-v1** & **v2** & **v3** | 1.7T | Curated GitHub code references with multi-stage filtering, deduplication, and large-scale synthetic code data. |
|
| 447 |
+
| **Nemotron-CC-Math-v1** | 133.3B | High-quality math pre-training dataset preserving LaTeX formatting and mathematical structures. |
|
| 448 |
+
| **Nemotron-Pretraining-Specialized-v1** & **v1.1** & **v1.2** & **Nemotron-Pretraining-SFT-v1** | 660.0B | Synthetic datasets targeting specialized domains such as STEM reasoning and scientific coding. |
|
| 449 |
+
| **Nemotron-Pretraining-Legal-v1** | 4.3B | Synthetic datasets targeting the legal domain. |
|
| 450 |
+
|
| 451 |
+
#### Public Datasets
|
| 452 |
+
|
| 453 |
+
| Dataset | Collection Period |
|
| 454 |
+
| :---- | :---- |
|
| 455 |
+
| [GSM8K](https://github.com/openai/grade-school-math) | 4/23/2025 |
|
| 456 |
+
| [CC-NEWS](https://commoncrawl.org/blog/news-dataset-available) | 4/23/2025 |
|
| 457 |
+
| [Common Crawl](https://commoncrawl.org/) | 4/23/2025 |
|
| 458 |
+
| [Wikimedia](https://dumps.wikimedia.org/) | 4/23/2025 |
|
| 459 |
+
| [Bespoke-Stratos-17k](https://huggingface.co/datasets/bespokelabs/Bespoke-Stratos-17k) | 4/23/2025 |
|
| 460 |
+
| [tigerbot-kaggle-leetcodesolutions-en-2k](https://huggingface.co/datasets/TigerResearch/tigerbot-kaggle-leetcodesolutions-en-2k) | 4/23/2025 |
|
| 461 |
+
| [glaive-function-calling-v2](https://huggingface.co/datasets/glaiveai/glaive-function-calling-v2) | 4/23/2025 |
|
| 462 |
+
| [APIGen Function-Calling](https://huggingface.co/datasets/Salesforce/xlam-function-calling-60k) | 4/23/2025 |
|
| 463 |
+
| [LMSYS-Chat-1M](https://huggingface.co/datasets/lmsys/lmsys-chat-1m) | 4/23/2025 |
|
| 464 |
+
| [Open Textbook Library - CC BY-SA & GNU subset](https://open.umn.edu/opentextbooks/textbooks/) and [OpenStax - CC BY-SA subset](https://openstax.org/) | 4/23/2025 |
|
| 465 |
+
| [Advanced Reasoning Benchmark](https://github.com/TheDuckAI/arb), [tigerbot-kaggle-leetcodesolutions-en-2k](https://huggingface.co/datasets/TigerResearch/tigerbot-kaggle-leetcodesolutions-en-2k), [PRM800K](https://github.com/openai/prm800k), and [SciBench](https://github.com/mandyyyyii/scibench) | 4/23/2025 |
|
| 466 |
+
| [FineWeb-2](https://huggingface.co/datasets/HuggingFaceFW/fineweb-2) | 4/23/2025 |
|
| 467 |
+
| [Court Listener](https://www.courtlistener.com/help/api/bulk-data/) | Legacy Download |
|
| 468 |
+
| [peS2o](https://huggingface.co/datasets/allenai/peS2o) | Legacy Download |
|
| 469 |
+
| [OpenWebMath](https://huggingface.co/datasets/open-web-math/open-web-math) | Legacy Download |
|
| 470 |
+
| [BioRxiv](https://www.biorxiv.org/tdm) | Legacy Download |
|
| 471 |
+
| [PMC Open Access Subset](https://pmc.ncbi.nlm.nih.gov/tools/openftlist/) | Legacy Download |
|
| 472 |
+
| [OpenWebText2](https://openwebtext2.readthedocs.io/en/latest/) | Legacy Download |
|
| 473 |
+
| [Stack Exchange Data Dump](https://archive.org/details/stackexchange) | Legacy Download |
|
| 474 |
+
| [PubMed Abstracts](https://github.com/thoppe/The-Pile-PubMed) | Legacy Download |
|
| 475 |
+
| [NIH ExPorter](https://exporter.nih.gov/ExPORTER_Catalog.aspx) | Legacy Download |
|
| 476 |
+
| [arXiv](https://info.arxiv.org/help/bulk_data/index.html) | Legacy Download |
|
| 477 |
+
| [BigScience Workshop Datasets](https://github.com/bigscience-workshop/bigscience/tree/master/train/tr11-176B-ml#datasets) | Legacy Download |
|
| 478 |
+
| [Reddit Dataset](https://files.pushshift.io/reddit/) | Legacy Download |
|
| 479 |
+
| [SEC's Electronic Data Gathering, Analysis, and Retrieval (EDGAR)](https://www.sec.gov/search-filings) | Legacy Download |
|
| 480 |
+
| [Advanced Mathematical Problem Solving](https://github.com/hendrycks/math?tab=readme-ov-file) | Legacy Download |
|
| 481 |
+
| [MathPile](https://github.com/GAIR-NLP/MathPile/) | Legacy Download |
|
| 482 |
+
| [NuminaMath CoT](https://huggingface.co/datasets/AI-MO/NuminaMath-CoT) | Legacy Download |
|
| 483 |
+
| [PMC Article](https://pmc.ncbi.nlm.nih.gov/tools/textmining/) | Legacy Download |
|
| 484 |
+
| [FLAN](https://github.com/google-research/FLAN) | Legacy Download |
|
| 485 |
+
| [Advanced Reasoning Benchmark](https://github.com/TheDuckAI/arb) | Legacy Download |
|
| 486 |
+
| [SciBench](https://github.com/mandyyyyii/scibench) | Legacy Download |
|
| 487 |
+
| [WikiTableQuestions](https://huggingface.co/datasets/wikitablequestions) | Legacy Download |
|
| 488 |
+
| [FinQA](https://finqasite.github.io/) | Legacy Download |
|
| 489 |
+
| [Riddles](https://github.com/crawsome/riddles) | Legacy Download |
|
| 490 |
+
| [Problems in Elementary Mathematics for Home Study](https://archive.org/details/AntonovVygodskyNikitinSankinProblemsInElementaryMathematicsForHomeStudyMir1982) | Legacy Download |
|
| 491 |
+
| [MedMCQA](https://huggingface.co/datasets/openlifescienceai/medmcqa) | Legacy Download |
|
| 492 |
+
| [Cosmos QA](https://huggingface.co/datasets/allenai/cosmos_qa) | Legacy Download |
|
| 493 |
+
| [MCTest](https://huggingface.co/datasets/sagnikrayc/mctest) | Legacy Download |
|
| 494 |
+
| [AI2's Reasoning Challenge](https://huggingface.co/datasets/ai2_arc) | Legacy Download |
|
| 495 |
+
| [OpenBookQA](https://github.com/allenai/OpenBookQA) | Legacy Download |
|
| 496 |
+
| [MMLU Auxiliary Train](https://huggingface.co/datasets/cais/mmlu/viewer/all/auxiliary_train) | Legacy Download |
|
| 497 |
+
| [social-chemestry-101](https://huggingface.co/datasets/tasksource/social-chemestry-101) | Legacy Download |
|
| 498 |
+
| [Moral Stories](https://huggingface.co/datasets/demelin/moral_stories) | Legacy Download |
|
| 499 |
+
| [The Common Pile v0.1](https://huggingface.co/common-pile) | Legacy Download |
|
| 500 |
+
| [FineMath](https://huggingface.co/datasets/HuggingFaceTB/finemath) | Legacy Download |
|
| 501 |
+
| [MegaMath](https://huggingface.co/datasets/LLM360/MegaMath) | Legacy Download |
|
| 502 |
+
| [MultiverseMathHard](https://huggingface.co/datasets/Nexusflow/MultiverseMathHard) | 10/2/2025 |
|
| 503 |
+
| [SWE-Gym](https://huggingface.co/datasets/SWE-Gym/SWE-Gym) | 10/2/2025 |
|
| 504 |
+
| [WorkBench](https://github.com/olly-styles/WorkBench/tree/main/data/raw) | 10/2/2025 |
|
| 505 |
+
| [WildChat-1M](https://huggingface.co/datasets/allenai/WildChat-1M) | 10/2/2025 |
|
| 506 |
+
| [OpenCodeReasoning-2](https://huggingface.co/datasets/nvidia/OpenCodeReasoning-2) | 10/2/2025 |
|
| 507 |
+
| [HelpSteer3](https://huggingface.co/datasets/nvidia/HelpSteer3) | 10/2/2025 |
|
| 508 |
+
| [opc-sft-stage2](https://huggingface.co/datasets/OpenCoder-LLM/opc-sft-stage2) | 10/2/2025 |
|
| 509 |
+
| [Big-Math-RL-Verified](https://huggingface.co/datasets/SynthLabsAI/Big-Math-RL-Verified) | 10/2/2025 |
|
| 510 |
+
| [MetaMathQA](https://huggingface.co/datasets/meta-math/MetaMathQA) | 10/2/2025 |
|
| 511 |
+
| [simple-arithmetic-problems](https://huggingface.co/datasets/garrethlee/simple-arithmetic-problems) | 10/2/2025 |
|
| 512 |
+
| [arithmetic](https://huggingface.co/datasets/EleutherAI/arithmetic) | 10/2/2025 |
|
| 513 |
+
| [Skywork-OR1-RL-Data](https://huggingface.co/datasets/Skywork/Skywork-OR1-RL-Data) | 10/2/2025 |
|
| 514 |
+
| [FastChat](https://github.com/lm-sys/FastChat/blob/main/playground/data/dummy.json) | 10/2/2025 |
|
| 515 |
+
| [News Commentary](https://opus.nlpl.eu/News-Commentary.php) | 10/2/2025 |
|
| 516 |
+
| [Essential-Web](https://huggingface.co/datasets/EssentialAI/essential-web-v1.0) | 10/2/2025 |
|
| 517 |
+
| [finepdfs](https://huggingface.co/datasets/HuggingFaceFW/finepdfs) | 10/2/2025 |
|
| 518 |
+
| [HotpotQA](https://huggingface.co/hotpot_qa/datasets) | 10/2/2025 |
|
| 519 |
+
| [SQuAD2.0](https://rajpurkar.github.io/SQuAD-explorer/) | 10/2/2025 |
|
| 520 |
+
| [NLTK Words Lists](https://www.nltk.org/nltk_data/) | 10/2/2025 |
|
| 521 |
+
|
| 522 |
+
#### **Crawled and Scraped from Online Sources by NVIDIA**
|
| 523 |
+
|
| 524 |
+
The English Common Crawl data was downloaded from the Common Crawl Foundation (see their FAQ for details on their crawling) and includes the snapshots CC-MAIN-2013-20 through CC-MAIN-2025-13. The data was subsequently deduplicated and filtered in various ways used in the Nemotron-CC data pipeline. Additionally, we extracted data for fifteen languages from the following three Common Crawl snapshots: CC-MAIN-2024-51, CC-MAIN-2025-08, CC-MAIN-2025-18. The fifteen languages included were Arabic, Chinese, Danish, Dutch, French, German, Italian, Japanese, Korean, Polish, Portuguese, Russian, Spanish, Swedish, and Thai. As we did not have reliable multilingual model-based quality classifiers available, we applied just heuristic filtering instead—similar to what we did for lower quality English data in the Nemotron-CC pipeline, but selectively removing some filters for some languages that did not work well. Deduplication was done in the same way as for Nemotron-CC.
|
| 525 |
+
|
| 526 |
+
The GitHub Crawl was collected using the GitHub REST API and the Amazon S3 API. Each crawl was operated in accordance with the rate limits set by its respective source, either GitHub or S3. We collect raw source code and subsequently remove any having a license which does not exist in our permissive-license set.
|
| 527 |
+
|
| 528 |
+
| Dataset | Modality | Dataset Size | Collection Period | Collecting Organisation |
|
| 529 |
+
| :---- | :---- | :---- | :---- | :---- |
|
| 530 |
+
| English Common Crawl | Text | 3.36T | 4/8/2025 | NVIDIA Advanced Deep Learning Research |
|
| 531 |
+
| English Common Crawl 1.1 | Text | Not disclosed | 10/2/2025 | NVIDIA Advanced Deep Learning Research |
|
| 532 |
+
| Multilingual Common Crawl | Text | 812.7B | 5/1/2025 | NVIDIA Advanced Deep Learning Research |
|
| 533 |
+
| GitHub Crawl | Text | 747.4B | 4/29/2025 | NVIDIA Advanced Deep Learning Research |
|
| 534 |
+
| GitHub Crawl 1.1 | Text | 172.7B | 9/30/2025 | NVIDIA Advanced Deep Learning Research |
|
| 535 |
+
|
| 536 |
+
#### Private Non-publicly Accessible Datasets of Third Parties
|
| 537 |
+
|
| 538 |
+
| Dataset | Model(s) used |
|
| 539 |
+
|---------|---------------|
|
| 540 |
+
| Global Regulation | Unknown |
|
| 541 |
+
| TAUS Translation Memory | Unknown |
|
| 542 |
+
| Scale HLE | Unknown |
|
| 543 |
+
| HackerRank Coding | Unknown |
|
| 544 |
+
| RL data for Search | Gemini 3; GPT-5 |
|
| 545 |
+
| Mercor SWE-AgentsV1 | Undisclosed |
|
| 546 |
+
|
| 547 |
+
#### Private Non-publicly Accessible Datasets by NVIDIA
|
| 548 |
+
|
| 549 |
+
| Dataset | Model(s) used |
|
| 550 |
+
|---------|---------------|
|
| 551 |
+
| Simple Minesweeper | Undisclosed |
|
| 552 |
+
| Simple Sudoku | Undisclosed |
|
| 553 |
+
| Multitool Typewriter Hard | Undisclosed |
|
| 554 |
+
| Machine Translation of News Commentary and TAUS Translation Memory | Undisclosed |
|
| 555 |
+
| Machine Translation of STEM - | [Qwen2.5-14B-Instruct](https://huggingface.co/Qwen/Qwen2.5-14B-Instruct) |
|
| 556 |
+
| Competitive Coding RL data from Nemotron Cascade | Undisclosed |
|
| 557 |
+
| Long context RL | Undisclosed |
|
| 558 |
+
| Single-step SWE RL for patch generation | Undisclosed |
|
| 559 |
+
| OpenHands SWE | Undisclosed |
|
| 560 |
+
|
| 561 |
+
#### User-Sourced Data (Collected by Provider including Prompts)
|
| 562 |
+
|
| 563 |
+
No user-sourced data, including user inputs, prompts, or interactions with the AI model, was used to train this model. Data point counts, modality sizes, and provider services/products for this category are not applicable.
|
| 564 |
+
|
| 565 |
+
#### NVIDIA-Sourced Synthetic Datasets (Pre-Training)
|
| 566 |
+
|
| 567 |
+
| Dataset | Modality | Dataset Size | Seed Dataset | Model(s) used for generation |
|
| 568 |
+
| :---- | :---- | :---- | :---- | :---- |
|
| 569 |
+
| Nemotron-Pretraining-Fact-Seeking | Text | 35.0B | [FineWiki](https://huggingface.co/datasets/HuggingFaceFW/finewiki) | [Qwen3-30B-A3B-Instruct-2507](https://huggingface.co/Qwen/Qwen3-30B-A3B-Instruct-2507) |
|
| 570 |
+
| Nemotron-Pretraining-Legal | Text | 4.3B | CommonPile (caselaw_access_project_filtered); California Code of Regulations; Judicial Ethics Opinions; [GLOBALCIT](https://globalcit.eu/); [CUAD](https://www.atticusprojectai.org/cuad); Nemotron Personas; [ToSDR Terms of Service Corpus](https://www.kaggle.com/datasets/sonu1607/tosdr-terms-of-service-corpus); CodeHima/TOS_Dataset; [ContractNLI](https://stanfordnlp.github.io/contract-nli/); CaseHOLD; Code of Federal Regulations; [Canadian Case Law](https://huggingface.co/datasets/a2aj/canadian-case-law) (subsets that allow commercial use) | [Qwen3-235B-A22B-Thinking-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507) |
|
| 571 |
+
| Nemotron-Pretraining-Formal-Logic | Text | 128M | [Nemotron Personas](https://huggingface.co/datasets/nvidia/Nemotron-Personas-USA) | [Qwen3-235B-A22B-Thinking-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507) |
|
| 572 |
+
| Nemotron-Pretraining-Economics | Text | 73.4M | - | [Qwen3-235B-A22B-Thinking-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507) |
|
| 573 |
+
| Nemotron-Pretraining-Multiple-Choice | Text | 1.6B | [MMLU Auxiliary Train](https://huggingface.co/datasets/cais/mmlu/viewer/all/auxiliary_train) | [DeepSeek-V3](https://huggingface.co/deepseek-ai/DeepSeek-V3); [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B) |
|
| 574 |
+
| Nemotron-Pretraining-Code-Concepts | Text | 7.3B | - | [gpt-oss-20b](https://huggingface.co/openai/gpt-oss-20b); [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b) |
|
| 575 |
+
| Nemotron-Pretraining-Unconditional-Algorithmic | Text | 196.5M | - | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b); [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B) |
|
| 576 |
+
| More Synthetic Tasks from DeepSeek-V3 and Qwen3-235B-A22B | Text | 1.1B | train splits of acp_bench; ai2_arc; babi; gsm8k; hendrycks_math; IFEval; MedText; mediqa_qa; mlqa; MMLU-Pro; mmlu-pro-plus; MMLU-ProX; nq_open; tinyGSM8k; truthful_qa; truthfulqa-multi; MATH-lighteval; mmlu; awesome-chatgpt-prompts; super_glue | [DeepSeek v3](https://huggingface.co/deepseek-ai/DeepSeek-V3); [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B) |
|
| 577 |
+
| Synthetic Tasks from DeepSeek-V3 and Qwen3-235B-A22B | Text | 6.7B | train splits of Into the Unknown; AI2 ARC (AI2 Reasoning Challenge); BLiMP (Benchmark of Linguistic Minimal Pairs); CommonSenseQA; GLUE; HeadQA; Hendrycks Ethics; Memo Trap; modus-tollens; NeQA; pattern-matching-suppression; mastermind_24_mcq_random; mastermind_24_mcq_close; quote-repetition; redefine-math; Repetitive Algebra; sig-figs; MMLU-Pro; MC-TACO; MedConceptsQA; MMLU_dataset; OpenbooksQA; PIQA (Physical Interaction Question Answering); SocialIQA; SuperGLUE; tinyAI2_arc; tinyMMLU; tinyWinogrande; TruthfulQA; WebQuestions; Winogrande; GPQA; MBPP | [DeepSeek v3](https://huggingface.co/deepseek-ai/DeepSeek-V3); [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B) |
|
| 578 |
+
| Synthetic Art of Problem Solving from DeepSeek-R1 | Text | 40B | [Art of Problem Solving](https://artofproblemsolving.com/company); [American Mathematics Competitions 8](https://artofproblemsolving.com/wiki/index.php/AMC_8_Problems_and_Solutions); [American Mathematics Competitions 10](https://artofproblemsolving.com/wiki/index.php/AMC_10_Problems_and_Solutions) | [DeepSeek-R1](https://huggingface.co/deepseek-ai/DeepSeek-R1) |
|
| 579 |
+
| Synthetic Moral Stories and Social Chemistry from Qwen3-235B-A22B-Thinking-2507 and Mixtral-8x22B-v0.1 | Text | 15.2M | [social-chemestry-101](https://huggingface.co/datasets/tasksource/social-chemestry-101); [Moral Stories](https://huggingface.co/datasets/demelin/moral_stories) | [Qwen3-235B-A22B-Thinking-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507); [Mixtral-8x22B-v0.1](https://huggingface.co/mistralai/Mixtral-8x22B-v0.1) |
|
| 580 |
+
| Synthetic Moral Stories and Social Chemistry from Mixtral-8x22B-v0.1 | Text | 327M | [social-chemestry-101](https://huggingface.co/datasets/tasksource/social-chemestry-101); [Moral Stories](https://huggingface.co/datasets/demelin/moral_stories) | [Mixtral-8x22B-v0.1](https://huggingface.co/mistralai/Mixtral-8x22B-v0.1) |
|
| 581 |
+
| Synthetic Social Sciences seeded with OpenStax from DeepSeek-V3, Mixtral-8x22B-v0.1, and Qwen2.5-72B | Text | 83.6M | [OpenStax - CC BY-SA subset](https://openstax.org/) | [DeepSeek-V3](https://huggingface.co/deepseek-ai/DeepSeek-V3); [Mixtral-8x22B-v0.1](https://huggingface.co/mistralai/Mixtral-8x22B-v0.1); [Qwen2.5-72B](https://huggingface.co/Qwen/Qwen2.5-72B) |
|
| 582 |
+
| Synthetic Health Sciences seeded with OpenStax from DeepSeek-V3, Mixtral-8x22B-v0.1, and Qwen2.5-72B | Text | 9.7M | [OpenStax - CC BY-SA subset](https://openstax.org/) | [DeepSeek-V3](https://huggingface.co/deepseek-ai/DeepSeek-V3); [Mixtral-8x22B-v0.1](https://huggingface.co/mistralai/Mixtral-8x22B-v0.1); [Qwen2.5-72B](https://huggingface.co/Qwen/Qwen2.5-72B) |
|
| 583 |
+
| Synthetic STEM seeded with OpenStax, Open Textbook Library, and GSM8K from DeepSeek-R1, DeepSeek-V3, DeepSeek-V3-0324, and Qwen2.5-72B | Text | 175M | [OpenStax - CC BY-SA subset](https://openstax.org/); [GSM8K](https://github.com/openai/grade-school-math); [Open Textbook Library - CC BY-SA & GNU subset](https://open.umn.edu/opentextbooks/textbooks/) | [DeepSeek-R1](https://huggingface.co/deepseek-ai/DeepSeek-R1), [DeepSeek-V3](https://huggingface.co/deepseek-ai/DeepSeek-V3); [DeepSeek-V3-0324](https://huggingface.co/deepseek-ai/DeepSeek-V3-0324); [Qwen2.5-72B](https://huggingface.co/Qwen/Qwen2.5-72B) |
|
| 584 |
+
| [Nemotron-PrismMath](https://huggingface.co/datasets/nvidia/Nemotron-PrismMath) | Text | 4.6B | [Big-Math-RL-Verified](https://huggingface.co/datasets/SynthLabsAI/Big-Math-RL-Verified); [OpenR1-Math-220k](https://huggingface.co/datasets/open-r1/OpenR1-Math-220k) | [Qwen2.5-0.5B-instruct](https://huggingface.co/Qwen/Qwen2.5-0.5B-Instruct), [Qwen2.5-72B-Instruct](https://huggingface.co/Qwen/Qwen2.5-72B-Instruct); [DeepSeek-R1-Distill-Qwen-32B](https://huggingface.co/deepseek-ai/DeepSeek-R1-Distill-Qwen-32B) |
|
| 585 |
+
| Synthetic Question Answering Data from Papers and Permissible Books from Qwen2.5-72B-Instruct | Text | 350M | [arXiv](https://info.arxiv.org/help/bulk_data/index.html); [National Institutes of Health ExPorter](https://www.nih.gov/); [BioRxiv](https://www.biorxiv.org/tdm); [PMC Article](https://pmc.ncbi.nlm.nih.gov/tools/textmining/); [USPTO Backgrounds](https://data.uspto.gov/apis/transition-guide/bdss#pats); [peS2o](https://huggingface.co/datasets/allenai/peS2o); Global Regulation; [CORE](https://core.ac.uk/documentation/dataset); [PG-19](https://github.com/google-deepmind/pg19); [DOAB CC BY & CC BY-SA subset](https://www.doabooks.org/en); [NDLTD](https://ndltd.org/thesis-resources/global-etd-search/) | [Qwen2.5-72B-Instruct](https://huggingface.co/Qwen/Qwen2.5-72B-Instruct) |
|
| 586 |
+
| Synthetic Rephrased [Math Data from Common Crawl](https://huggingface.co/datasets/nvidia/Nemotron-MIND) from phi-4 | Text | 73B | [Common Crawl](https://commoncrawl.org/latest-crawl) | [phi-4](https://huggingface.co/microsoft/phi-4) |
|
| 587 |
+
| Synthetic Math Data from Common Crawl 4plus | Text | 52.3B | [Common Crawl](https://commoncrawl.org/latest-crawl) | [phi-4](https://huggingface.co/microsoft/phi-4) |
|
| 588 |
+
| Synthetic Math Data from Common Crawl 3 | Text | 80.9B | [Common Crawl](https://commoncrawl.org/latest-crawl) | [phi-4](https://huggingface.co/microsoft/phi-4) |
|
| 589 |
+
| Synthetic AGIEval seeded with AQUA-RAT, LogiQA, and AR-LSAT from DeepSeek-V3 and DeepSeek-V3-0324 | Text | 4.0B | [AQUA-RAT](https://huggingface.co/datasets/deepmind/aqua_rat); [LogiQA](https://huggingface.co/datasets/lucasmccabe/logiqa); [AR-LSAT](https://github.com/zhongwanjun/AR-LSAT) | [DeepSeek-V3](https://huggingface.co/deepseek-ai/DeepSeek-V3); [DeepSeek-V3-0324](https://huggingface.co/deepseek-ai/DeepSeek-V3-0324) |
|
| 590 |
+
| Synthetic AGIEval seeded with AQUA-RAT, LogiQA, and AR-LSAT from Qwen3-30B-A3B | Text | 4.2B | [AQUA-RAT](https://huggingface.co/datasets/deepmind/aqua_rat); [LogiQA](https://huggingface.co/datasets/lucasmccabe/logiqa); [AR-LSAT](https://github.com/zhongwanjun/AR-LSAT) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B) |
|
| 591 |
+
| Synthetic Art of Problem Solving from Qwen2.5-32B-Instruct, Qwen2.5-Math-72B, Qwen2.5-Math-7B, and Qwen2.5-72B-Instruct | Text | Undisclosed | [Art of Problem Solving](https://artofproblemsolving.com/company); [American Mathematics Competitions 8](https://artofproblemsolving.com/wiki/index.php/AMC_8_Problems_and_Solutions); [American Mathematics Competitions 10](https://artofproblemsolving.com/wiki/index.php/AMC_10_Problems_and_Solutions); [GSM8K](https://github.com/openai/grade-school-math); [PRM800K](https://github.com/openai/prm800k) | [Qwen2.5-32B-Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct); [Qwen2.5-Math-72B](https://huggingface.co/Qwen/Qwen2.5-Math-72B); [Qwen2.5-Math-7B](https://huggingface.co/Qwen/Qwen2.5-Math-7B); [Qwen2.5-72B-Instruct](https://huggingface.co/Qwen/Qwen2.5-72B-Instruct) |
|
| 592 |
+
| Synthetic MMLU Auxiliary Train from DeepSeek-R1 | Text | 0.5B | [MMLU Auxiliary Train](https://huggingface.co/datasets/cais/mmlu/viewer/all/auxiliary_train) | [DeepSeek-R1](https://huggingface.co/deepseek-ai/DeepSeek-R1) |
|
| 593 |
+
| Synthetic Long Context Continued Post-Training Data from Papers and Permissible Books from Qwen2.5-72B-Instruct | Text | Undisclosed | [arXiv](https://info.arxiv.org/help/bulk_data/index.html); [National Institutes of Health ExPorter](https://www.nih.gov/); [BioRxiv](https://www.biorxiv.org/tdm); [PMC Article](https://pmc.ncbi.nlm.nih.gov/tools/textmining/); [USPTO Backgrounds](https://data.uspto.gov/apis/transition-guide/bdss#pats); [peS2o](https://huggingface.co/datasets/allenai/peS2o); Global Regulation; [CORE](https://core.ac.uk/documentation/dataset); [PG-19](https://github.com/google-deepmind/pg19); [DOAB CC BY & CC BY-SA subset](https://www.doabooks.org/en); [NDLTD](https://ndltd.org/thesis-resources/global-etd-search/) | [Qwen2.5-72B-Instruct](https://huggingface.co/Qwen/Qwen2.5-72B-Instruct) |
|
| 594 |
+
| Synthetic Common Crawl from Qwen3-30B-A3B and Mistral-Nemo-12B-Instruct | Text | 415.8B | [Common Crawl](https://commoncrawl.org/) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B); [Mistral-NeMo-12B-Instruct](https://huggingface.co/nvidia/Mistral-NeMo-12B-Instruct) |
|
| 595 |
+
| Synthetic Multilingual Data from Common Crawl from Qwen3-30B-A3B | Text | Undisclosed | [Common Crawl](https://commoncrawl.org/) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B) |
|
| 596 |
+
| Synthetic Multilingual Data from Wikimedia from Qwen3-30B-A3B | Text | Undisclosed | [Wikimedia](https://dumps.wikimedia.org/) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B) |
|
| 597 |
+
| Synthetic Math Data from Wikimedia from Nemotron-4-340B-Instruct | Text | Undisclosed | - | [Nemotron-4-340B-Instruct](https://huggingface.co/nvidia/Nemotron-4-340B-Instruct) |
|
| 598 |
+
| Synthetic Common Crawl Code from phi-4 | Text | 427.9B | [Common Crawl](https://commoncrawl.org/latest-crawl) | [phi-4](https://huggingface.co/microsoft/phi-4) |
|
| 599 |
+
| Synthetic Scientific Coding from Qwen3-235B-A22B | Text | 1.2B | [Wikimedia](https://dumps.wikimedia.org/) | [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507) |
|
| 600 |
+
| Tool Calling Data | Text | 26.2B | - | [Qwen3-235B-A22B-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507); [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b) |
|
| 601 |
+
| Synthetic Essential-Web from QwQ-32B | Text | 28.1B | [Essential-Web](https://huggingface.co/datasets/EssentialAI/essential-web-v1.0) | [QwQ-32B](https://huggingface.co/Qwen/QwQ-32B) |
|
| 602 |
+
| Translated Synthetic Crawl | Text | 389.9B | [Common Crawl](https://commoncrawl.org/) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B) |
|
| 603 |
+
| Translated Synthetic Wikipedia | Text | 7.9B | [Wikimedia](https://dumps.wikimedia.org/) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B) |
|
| 604 |
+
| Synthetic Long Context from Qwen3-235B-A22B-Instruct-2507 | Text | Undisclosed | [CORE](https://core.ac.uk/documentation/dataset); [PG-19](https://github.com/google-deepmind/pg19); [DOAB CC BY & CC BY-SA subset](https://www.doabooks.org/en); [NDLTD](https://ndltd.org/thesis-resources/global-etd-search/) | [Qwen3-235B-A22B-Instruct-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507) |
|
| 605 |
+
| Synthetic Search STEM OPENQ from DeepSeek-R1-0528 | Text | Undisclosed | - | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 606 |
+
| Synthetic MCQ from Qwen2.5-32B-Instruct and DeepSeek-R1-0528 | Text | Undisclosed | - | [Qwen2.5-32B-Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct); [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 607 |
+
| Synthetic Offline Search MCQA HLE from DeepSeek-R1-0528 | Text | Undisclosed | - | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 608 |
+
| Synthetic Offline Search MCQA GPQA from Qwen3-235B-A22B and DeepSeek-R1-0528 | Text | Undisclosed | - | [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B); [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 609 |
+
| Synthetic Human Preference from QwQ-32B, Qwen3-30B-A3B, Qwen3-235B-A22B, Qwen3-235B-A22B-Instruct-2507, Mistral-Small-3.1-24B-Instruct-2503, Mistral-Small-3.2-24B-Instruct-2506, MiniMax-M1-80k, MiniMax-M1-40k, Kimi-K2-Instruct, DeepSeek-V3-0324, DeepSeek-R1-0528 | Text | Undisclosed | - | [QwQ-32B](https://huggingface.co/Qwen/QwQ-32B); [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B); [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B); [Qwen3-235B-A22B-Instruct-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507); [Mistral-Small-3.1-24B-Instruct-2503](https://huggingface.co/mistralai/Mistral-Small-3.1-24B-Instruct-2503); [Mistral-Small-3.2-24B-Instruct-2506](https://huggingface.co/mistralai/Mistral-Small-3.2-24B-Instruct-2506); [MiniMax-M1-80k](https://huggingface.co/MiniMaxAI/MiniMax-M1-80k); [MiniMax-M1-40k](https://huggingface.co/MiniMaxAI/MiniMax-M1-40k); [Kimi-K2-Instruct](https://huggingface.co/moonshotai/Kimi-K2-Instruct); [DeepSeek-V3-0324](https://huggingface.co/deepseek-ai/DeepSeek-V3-0324); [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 610 |
+
| Synthetic WildChat-1M and arena-human-preference-140k from DeepSeek-R1, gemma-2-2b-it, gemma-3-27b-it, gpt-oss-20b, gpt-oss-120b, Mistral-7B-Instruct-v0.3, Mixtral-8x22B-Instruct-v0.1, Nemotron-4-340B-Instruct, NVIDIA-Nemotron-Nano-9B-v2, Phi-4-mini-instruct, Phi-3-small-8k-instruct, Phi-3-medium-4k-instruct, Qwen3-235B-A22B, QwQ-32B | Text | Undisclosed | [WildChat-1M](https://huggingface.co/datasets/allenai/WildChat-1M); [arena-human-preference-140k](https://huggingface.co/datasets/lmarena-ai/arena-human-preference-140k) | [DeepSeek-R1](https://huggingface.co/deepseek-ai/DeepSeek-R1); [gemma-2-2b-it](https://huggingface.co/google/gemma-2-2b-it); [gemma-3-27b-it](https://huggingface.co/google/gemma-3-27b-it); [gpt-oss-20b](https://huggingface.co/openai/gpt-oss-20b); [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b); [Mistral-7B-Instruct-v0.3](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.3); [Mixtral-8x22B-Instruct-v0.1](https://huggingface.co/mistralai/Mixtral-8x22B-Instruct-v0.1); [Nemotron-4-340B-Instruct](https://huggingface.co/nvidia/Nemotron-4-340B-Instruct); [NVIDIA-Nemotron-Nano-9B-v2](https://huggingface.co/nvidia/NVIDIA-Nemotron-Nano-9B-v2); [Phi-4-mini-instruct](https://huggingface.co/microsoft/Phi-4-mini-instruct); [Phi-3-small-8k-instruct](https://huggingface.co/microsoft/Phi-3-small-8k-instruct); [Phi-3-medium-4k-instruct](https://huggingface.co/microsoft/Phi-3-medium-4k-instruct); [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B); [QwQ-32B](https://huggingface.co/Qwen/QwQ-32B) |
|
| 611 |
+
| Synthetic Code from Qwen3-32B | Text | Undisclosed | English Common Crawl; English Common Crawl 1.1 | [Qwen3-32B](https://huggingface.co/Qwen/Qwen3-32B) |
|
| 612 |
+
| Synthetic OpenCodeReasoning from DeepSeek-R1 | Text | Undisclosed | [OpenCodeReasoning](https://huggingface.co/datasets/nvidia/OpenCodeReasoning) | [DeepSeek-R1](https://huggingface.co/deepseek-ai/DeepSeek-R1) |
|
| 613 |
+
| Synthetic OpenCodeReasoning from DeepSeek-R1-0528 | Text | Undisclosed | [OpenCodeReasoning](https://huggingface.co/datasets/nvidia/OpenCodeReasoning) | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 614 |
+
| Synthetic HackerRank Coding from DeepSeek-R1-0528 | Text | Undisclosed | HackerRank Coding Dataset | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 615 |
+
| Synthetic LIMO from DeepSeek-R1-0528 | Text | Undisclosed | [LIMO](https://huggingface.co/datasets/GAIR/LIMO) | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 616 |
+
| Synthetic SCP from DeepSeek-R1-0528 | Text | Undisclosed | [SCP-116K](https://huggingface.co/datasets/EricLu/SCP-116K) | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 617 |
+
| Synthetic Stack Exchange from DeepSeek-R1-0528 | Text | Undisclosed | [Stack Exchange](https://archive.org/details/stackexchange) | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 618 |
+
| Synthetic Stack Exchange from gpt-oss-120b and Qwen2.5-32B-Instruct | Text | Undisclosed | [Stack Exchange](https://archive.org/details/stackexchange) | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b); [Qwen2.5-32B-Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct) |
|
| 619 |
+
| Synthetic Stack Exchange from gpt-oss-120b | Text | Undisclosed | [Stack Exchange](https://archive.org/details/stackexchange) | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b) |
|
| 620 |
+
| Synthetic Art of Problem Solving from gpt-oss-120b and Qwen2.5-32B-Instruct | Text | Undisclosed | [Art of Problem Solving](https://artofproblemsolving.com/company); [American Mathematics Competitions 8](https://artofproblemsolving.com/wiki/index.php/AMC_8_Problems_and_Solutions); [American Mathematics Competitions 10](https://artofproblemsolving.com/wiki/index.php/AMC_10_Problems_and_Solutions) | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b); [Qwen2.5-32B-Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct) |
|
| 621 |
+
| Synthetic Common Crawl from Qwen3-30B-A3B | Text | Undisclosed | [Common Crawl](https://commoncrawl.org/) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B) |
|
| 622 |
+
| Synthetic Wikipedia from Qwen3-30B-A3B | Text | Undisclosed | [Wikimedia](https://dumps.wikimedia.org/) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B) |
|
| 623 |
+
| Synthetic Essential-Web from Qwen3-30B-A3B and Qwen3-235B-A22B-Thinking-2507 | Text | Undisclosed | [Essential-Web](https://huggingface.co/datasets/EssentialAI/essential-web-v1.0) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B); [Qwen3-235B-A22B-Thinking-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Thinking-2507) |
|
| 624 |
+
| Synthetic Essential-Web from gpt-oss-120b | Text | Undisclosed | [Essential-Web](https://huggingface.co/datasets/EssentialAI/essential-web-v1.0) | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b) |
|
| 625 |
+
| Synthetic Textbook Math from Qwen3-30B-A3B, Qwen3-235B-A22B, phi-4 | Text | Undisclosed | [Common Crawl](https://commoncrawl.org/); [FineMath](https://huggingface.co/datasets/HuggingFaceTB/finemath) | [Qwen3-30B-A3B](https://huggingface.co/Qwen/Qwen3-30B-A3B); [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B); [phi-4](https://huggingface.co/microsoft/phi-4) |
|
| 626 |
+
| Synthetic Math and Code from DeepSeek-R1 and DeepSeek-R1-0528 | Text | Undisclosed | [Magicoder-Evol-Instruct-110K](https://huggingface.co/datasets/ise-uiuc/Magicoder-Evol-Instruct-110K); [opc-sft-stage2](https://huggingface.co/datasets/OpenCoder-LLM/opc-sft-stage2); [TACO](https://huggingface.co/datasets/BAAI/TACO); [OpenCodeReasoning](https://huggingface.co/datasets/nvidia/OpenCodeReasoning); [OpenMathReasoning](https://huggingface.co/datasets/nvidia/OpenMathReasoning); [NuminaMath CoT](https://huggingface.co/datasets/AI-MO/NuminaMath-CoT) | [DeepSeek-R1](https://huggingface.co/deepseek-ai/DeepSeek-R1); [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 627 |
+
| Synthetic Math from gpt-oss-120b and Qwen2.5-32B-Instruct | Text | Undisclosed | - | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b); [Qwen2.5-32B-Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct) |
|
| 628 |
+
| Synthetic OpenMathReasoning from gpt-oss-120b and Qwen2.5-32B-Instruct | Text | Undisclosed | [OpenMathReasoning](https://huggingface.co/datasets/nvidia/OpenMathReasoning) | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b); [Qwen2.5-32B-Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct) |
|
| 629 |
+
| Synthetic KernelBook from DeepSeek-R1-0528 | Text | Undisclosed | [KernelBook](https://huggingface.co/datasets/GPUMODE/KernelBook) | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 630 |
+
| Synthetic Scale HLE from gpt-oss-120b | Text | Undisclosed | Scale HLE | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b) |
|
| 631 |
+
| Synthetic CDQuestions from gpt-oss-120b | Text | Undisclosed | [CDQuestions](https://cdquestions.com/) | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b) |
|
| 632 |
+
| Synthetic GPQA from gpt-oss-120b and Qwen2.5-32B-Instruct | Text | Undisclosed | [Stack Exchange](https://archive.org/details/stackexchange) | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b); [Qwen2.5-32B-Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct) |
|
| 633 |
+
| Synthetic Vedantu from gpt-oss-120b | Text | Undisclosed | [Vedantu](https://www.vedantu.com/) | [gpt-oss-120b](https://huggingface.co/openai/gpt-oss-120b) |
|
| 634 |
+
| Synthetic Search STEM MCQ from Qwen3-235B-A22B and DeepSeek-R1-0528 | Text | Undisclosed | - | [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B); [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 635 |
+
| Synthetic OpenSTEM from Qwen2.5-32B-Instruct and DeepSeek-R1-0528 | Text | Undisclosed | - | [Qwen2.5-32B-Instruct](https://huggingface.co/Qwen/Qwen2.5-32B-Instruct); [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 636 |
+
| Synthetic MCQ10 from DeepSeek-R1-0528 | Text | Undisclosed | - | [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528) |
|
| 637 |
+
| Synthetic MCQ4 from Qwen3-235B-A22B, DeepSeek-R1-0528, and Qwen3-235B-A22B-Instruct-2507 | Text | Undisclosed | - | [Qwen3-235B-A22B](https://huggingface.co/Qwen/Qwen3-235B-A22B); [DeepSeek-R1-0528](https://huggingface.co/deepseek-ai/DeepSeek-R1-0528); [Qwen3-235B-A22B-Instruct-2507](https://huggingface.co/Qwen/Qwen3-235B-A22B-Instruct-2507) |
|
| 638 |
+
|
| 639 |
+
#### NVIDIA-Sourced Synthetic Datasets (Post-Training)
|
| 640 |
+
|
| 641 |
+
| Dataset | Modality | Dataset Size | Seed Dataset | Model(s) used for generation |
|
| 642 |
+
| :---- | :---- | :---- | :---- | :---- |
|
| 643 |
+
| Synthetic Competitive MATH Proofs from DeepSeek-V4-Pro | Text | Undisclosed | [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions] | [deepseek-ai/DeepSeek-V4-Pro] |
|
| 644 |
+
| Synthetic Hermes Agent Reasoning Traces | Text | Undisclosed | [lambda/hermes-agent-reasoning-traces] | [hermes-agent-generator] |
|
| 645 |
+
| Synthetic Competitive Coding from DeepSeek-V4-Pro | Text | Undisclosed | [NVCompetitiveCodingV1] | [deepseek-ai/DeepSeek-V4-Pro] |
|
| 646 |
+
| Synthetic Competitive Science Reasoning from DeepSeek-V4-Pro | Text | Undisclosed | [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [EssentialAI/essential-web-v1.0]; [cdquestions.com]; [Pile-FreeLaw]; [Vedantu]; [askfilo]; [doubtnut]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)]; [AAPT]; [ChemData 700K]; [oMeBench]; [Flavor Analysis and Recognition Transformer]; [ChemCoTBench]; [Llama Nemotron Dataset] | [deepseek-ai/DeepSeek-V4-Pro] |
|
| 647 |
+
| Synthetic Competitive MATH CoT and TIR from Nemotron 5.5 | Text | Undisclosed | [Pile-FreeLaw]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions] | [Nemotron 5.5] |
|
| 648 |
+
| Vendor Terminal Bench-like Tasks from Mercor | Text | Undisclosed | [Terminal bench like tasks curated by the vendor] | [Undisclosed - purchased dataset] |
|
| 649 |
+
| Turing Math Data Pack | Text | Undisclosed | [Turing Math Data Pack dataset] | [Undisclosed - purchased dataset] |
|
| 650 |
+
| Synthetic Holdout, Skywork, DAPO, and Turing Math from GPT-5.5 | Text | Undisclosed | [DocQA-RL-1.6K]; [DAPO-Math-17k] | [GPT-5.5] |
|
| 651 |
+
| Synthetic Long Context RL from QwenLong L1 and DocQA-RL-1.6K | Text | Undisclosed | [DocQA-RL-1.6K] | Undisclosed |
|
| 652 |
+
| Synthetic Competitive Coding Gym Tasks | Text | Undisclosed | [NVCompetitiveCodingV1.1] | Undisclosed |
|
| 653 |
+
| Synthetic Finance SEC Search Agent from GPT-OSS-120B and Qwen3 | Text | Undisclosed | [SEC filings from sec.gov] | [GPT-OSS-120B]; [Qwen3-235B-A22B-Instruct]; [Qwen3-4B-Instruct] |
|
| 654 |
+
| Synthetic Structured Outputs from Qwen3-30B-A3B-Instruct-2507, Qwen3-30B-A3B-Thinking-2507, Qwen3-235B-A22B-Instruct-2507, and Qwen3-235B-A22B-Thinking-2507 | Text | Undisclosed | [Nemotron-RL-agent-structured-outputs-v1] | [Qwen3-30B-A3B-Instruct-2507]; [Qwen3-235B-A22B-Instruct-2507] |
|
| 655 |
+
| Synthetic Long Context Equivalence Rule from Qwen3-235B-A22B-Thinking-2507 and DeepSeek-R1 | Text | Undisclosed | [Long-context SFT data] | [Qwen/Qwen3-235B-A22B-Thinking-2507]; [Deepseek-ai/DeepSeek-R1] |
|
| 656 |
+
| Synthetic Science RL Data Blend from Qwen2.5-32B | Text | Undisclosed | [doubtnut]; [Pile-FreeLaw]; [Llama Nemotron Dataset]; [askfilo]; [EssentialAI/essential-web-v1.0]; [Vedantu]; [auxiliary_train]; [cdquestions.com]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [AAPT]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)] | [Qwen2.5-32B] |
|
| 657 |
+
| Synthetic Abstention Data from Nemotron Super v3 | Text | Undisclosed | [Go abstention Dataset] | [nvidia/nvidia/nemotron-3-super-v3] |
|
| 658 |
+
| Synthetic Chemistry Data from Nemotron Super v3 | Text | Undisclosed | [ChemData 700K] | [nvidia/nvidia/nemotron-3-super-v3] |
|
| 659 |
+
| Synthetic Tool Call Schema for RL | Text | 469,983 | [UltraTool]; [ToolEyes]; [AutoTools]; [API-Bank]; [Nemotron-Personas-USA]; [Salesforce xLAM function-calling]; [Glaive function-calling-v2]; [Agent-Ark/Toucan-1.5M] | [DeepSeek-V3.2]; [GLM-4.6]; [gpt-oss-120b]; [Kimi-K2-Instruct] |
|
| 660 |
+
| Synthetic Freeform Text Formatting from GPT-OSS-120B | Text | Undisclosed | [In-house data] | [GPT OSS 120B - Apache 2.0] |
|
| 661 |
+
| Synthetic Citation Formatting from GPT-OSS-120B | Text | Undisclosed | [In-house data] | [GPT OSS 120B - Apache 2.0] |
|
| 662 |
+
| Droid Harness Pivot Vendor Data | Text | Undisclosed | [Droid Harness Pivot vendor data] | Undisclosed |
|
| 663 |
+
| Synthetic HotpotQA Training Data from Qwen3-235B | Text | Undisclosed | [HotpotQA] | [Qwen3-235B] |
|
| 664 |
+
| Synthetic Natural Language Math Proofs from Nemotron 5.5 | Text | Undisclosed | [AMC8, AMC10, and AIME problem sets hosted on Art of Problem Solving]; [Pile-StackExchange] | [Nemotron 5.5] |
|
| 665 |
+
| Synthetic Stack Overflow OpenQ | Text | Undisclosed | [Pile-FreeLaw] | Undisclosed |
|
| 666 |
+
| Chemistry Ether0 Vendor Data | Text | Undisclosed | [Chemistry ether0 vendor data] | Undisclosed |
|
| 667 |
+
| Synthetic Litmus-Bench Chemistry from ChEMBL | Text | Undisclosed | [ChEMBL]; [Nemo Gym RL dataset generated from ChEMBL with RDKit] | Undisclosed |
|
| 668 |
+
| Synthetic ZINC Chemistry from Nemotron Super v3 | Text | Undisclosed | [ZINC] | [Nemotron Super v3] |
|
| 669 |
+
| ARC-AGI Gym Environment | Text | Undisclosed | [ARC-AGI-2] | [ARC-AGI-2] |
|
| 670 |
+
| Synthetic Agentic Search Tool-Use from DeepSeek-V3.2 | Text | Undisclosed | [Mercor Data] | [DeepSeek-V3.2] |
|
| 671 |
+
| Synthetic Text-To-SQL | Text | 96,564 | [In-house Text-to-SQL data] | [gpt-oss-120b] |
|
| 672 |
+
| Dialog Memory Vendor Data | Text | Undisclosed | [Patronus external vendor agreement] | Undisclosed |
|
| 673 |
+
| Synthetic Indirect Prompt Injection from Nemotron Super v3 and Qwen3-Next-80B-A3B-Instruct | Text | Undisclosed | [In-house indirect prompt injection data] | [nvidia/nemotron-3-super-v3, qwen/qwen3-next-80b-a3b-instruct] |
|
| 674 |
+
| Synthetic Malicious Code and Agentic Security | Text | Undisclosed | [In-house malicious-code / agentic-security data] | Undisclosed |
|
| 675 |
+
| Synthetic Single-Step SWE Patch Selection | Text | Undisclosed | [SWE-Gym Dataset]; [SWE Bench Verified Benchmark] | [ground truth and task checks] |
|
| 676 |
+
| Synthetic Natural Language Math Final Answers from Nemotron 5.5 | Text | Undisclosed | [AMC8, AMC10, and AIME problem sets hosted on Art of Problem Solving]; [Pile-StackExchange] | [nemotron 5.5] |
|
| 677 |
+
| Synthetic Simple Math Prompts for Token Efficiency | Text | Undisclosed | [In-house simple math prompts] | Undisclosed |
|
| 678 |
+
| Synthetic Abstention Data from Nemotron Super v3 (CRAG) | Text | Undisclosed | [CRAG] | [nvidia/nvidia/nemotron-3-super-v3] |
|
| 679 |
+
| Synthetic Agentless SWE | Text | 242,536 | [SWE-Rebench-V2]; [SWEbench Training Set]; [R2E-Gym/R2E-Gym-Subset]; [SWE-Gym/SWE-Gym]; [SWE-Rebench] | [openai/gpt-oss-120b] |
|
| 680 |
+
| Synthetic Agentless SWE from DeepSeek-R1-0528 | Text | 209,976 | [SWE-Bench-Train]; [SWE-Fixer-Train]; [SWE-reBench]; [SWE-Smith] | [deepseek-ai/DeepSeek-R1-0528] |
|
| 681 |
+
| Synthetic Agentic CUDA Traces from GLM-4.7 | Text | 2,276 | [Internal CUDA task data] | [GLM-4.7] |
|
| 682 |
+
| Synthetic Math Proofs from DeepSeek-V3.2-Speciale | Text | 820,772 | [Nemotron-Math-Proofs-v1] | [SDG: DeepSeek-V3.2-Speciale]; [Filter: proof validation] |
|
| 683 |
+
| Synthetic Multilingual SFT from DeepSeek-V3 | Text | 1,245,284 | [Nano v3 SFT data] | [DeepSeek-V3] |
|
| 684 |
+
| Synthetic Agentic Code from gpt-oss-120b | Text | 109,086 | [NVAgenticCLIPrompts-v1]; [NVAgenticSkills-v1]; [NVAgenticCLIMultiTurnPrompts-v1] | [openai/gpt-oss-120b] |
|
| 685 |
+
| Synthetic Agentic CLI and Web Skills from gpt-oss-120b | Text | 27,418 | [NVAgenticCLIPrompts-v1]; [NVAgenticSkills-v1]; [NVAgenticCLIMultiTurnPrompts-v1]; [NVAgenticCLIPrompts-Web-v1] | [openai/gpt-oss-120b] |
|
| 686 |
+
| Synthetic Agentic Coding from gpt-oss-120b | Text | 160,531 | [NVAgenticCLIPrompts-v1]; [NVAgenticSkills-v1]; [NVAgenticCLIMultiTurnPrompts-v1]; [NVAgenticCLIPrompts-Web-v1] | [openai/gpt-oss-120b] |
|
| 687 |
+
| Synthetic OpenCode Agentic Tasks from gpt-oss-120b | Text | 614,773 | [NVAgenticCLIPrompts-v1]; [NVAgenticSkills-v1]; [NVAgenticCLIMultiTurnPrompts-v1]; [NVAgenticCLIPrompts-Web-v1] | [openai/gpt-oss-120b] |
|
| 688 |
+
| Synthetic SWE Unverified | Text | Undisclosed | [NVAgenticCLIPrompts-v1]; [NVAgenticSkills-v1]; [NVAgenticCLIMultiTurnPrompts-v1]; [NVAgenticCLIPrompts-Web-v1] | [gpt-oss-120b]; [Qwen/Qwen3-Coder-480B-A35B-Instruct]; [GLM-4.7-Flash] |
|
| 689 |
+
| Synthetic ARC-AGI Ultra Data | Text | 192,016 | [ARC-AGI-2]; [arc dataset collection] | [ARC-AGI-2] |
|
| 690 |
+
| Synthetic LiveCodeBench TIR from DeepSeek-R1-0528 | Text | 1,283,398 | [Nemotron-X training datasets] | [DeepSeek-R1-0528] |
|
| 691 |
+
| Synthetic Verilog and SystemVerilog Code from DeepSeek-R1-0528 and GPT-OSS-120B | Text | 1,233,247 | [Verilog/SystemVerilog seed code] | [SDR: DeepSeek R1 0528 and GPT-OSS-120B]; [Filtering: Claude 4 Sonnet] |
|
| 692 |
+
| Synthetic Aider Python Tasks from DeepSeek-R1-0528 | Text | 236,099 | [Exercism (GitHub Python)] | [Deepseek R1 0528] |
|
| 693 |
+
| Synthetic Chat Reasoning-Off Data from GLM-5 | Text | 646,738 | [lmarena-ai/repochat-arena-preference-4k user prompts] | [Multi-turn conversations generated by GLM-5 with best-of-4 selection via Qwen3-Nemotron-235B-A22B-GenRM] |
|
| 694 |
+
| Synthetic Chat Reasoning-On Data from GLM-5 | Text | 644,286 | [lmarena-ai/repochat-arena-preference-4k user prompts]; [lmarena-ai/arena-expert-5k user prompts]; [lmarena-ai/arena-human-preference-55k user prompts]; [lmarena-ai/arena-human-preference-100k user prompts]; [lmarena-ai/arena-human-preference-140k user prompts] | [Multi-turn conversations generated by GLM-5 with best-of-4 selection via Qwen3-Nemotron-235B-A22B-GenRM] |
|
| 695 |
+
| Synthetic Multilingual Safety from Riva-Translate-4B-Instruct-v1.1 | Text | 132,067 | [Safety SFT Data: Ultra] | [nvidia/Riva-Translate-4B-Instruct-v1.1] |
|
| 696 |
+
| Synthetic Science Reasoning Effort Medium | Text | 502,722 | [science-reasoning-effort-medium-v0] | Undisclosed |
|
| 697 |
+
| Synthetic Telecom Tool-Use Trajectories from gpt-oss-120b | Text | 12,455 | [Existing Tau2 telecom trajectories originally generated with DeepSeek V3.2] | [gpt-oss-120b] |
|
| 698 |
+
| Synthetic Terminal Bench Data from OpenReasoningv2 | Text | Undisclosed | [OpenCodeReasoningv2]; [OpenMathReasoning]; [nemo-swe-bench-repos]; [SWE-Rebench]; [SWE-Fixer-110K] | [OpenReasoningv2] |
|
| 699 |
+
| Synthetic Tulu Instruction Following from DeepSeek-R1-0528 | Text | 105,361 | [Nemotron-X training datasets] | [DeepSeek-R1-0528] |
|
| 700 |
+
| Synthetic Instruction Following from gpt-oss-120b | Text | 151,988 | [IFEval]; [IFEvalG] | [gpt-oss-120b] |
|
| 701 |
+
| Synthetic Instruction Following for RL | Text | Undisclosed | [WildChat-1M]; [LMSYS-340B-Eval Dataset]; [LMSYS-Chat-1M Prompts]; [IFEval]; [IFEvalG] | [Qwen/Qwen3-235B-A22B-Thinking-2507]; [gpt-oss-120b]; [Qwen3-235B-A22B-Instruct-2507] |
|
| 702 |
+
| Synthetic Identity Data from Qwen3-Next-80B-A3B-Instruct and Qwen3-235B-A22B-Instruct-2507 | Text | 25,992 | [Hand-written prompts] | [Qwen3-Next-80B-A3B-Instruct]; [Qwen3-235B-A22B-Instruct-2507] |
|
| 703 |
+
| Synthetic Terminus Ultra Agentic Reasoning Blend | Text | 96,881 | [ARC-AGI-2]; [OpenCodeReasoningv2]; [OpenMathReasoning]; [SWE-Fixer-110K]; [SWE-Rebench]; [SWE-Smith] | [DeepSeek-V3.2]; [Qwen3-235B-A22B-Thinking-2507]; [Ring-1T]; [Kimi-K2.5]; [GLM-4.7-FP8]; [Qwen3-Next-80B-A3B-Thinking]; [gpt-oss-120b]; [Ministral-3-14B-Reasoning-2512]; [LM-4.5-Air-FP8] |
|
| 704 |
+
| Synthetic STEM from Qwen3-235B-A22B-Thinking-2507 | Text | 1,174,694 | [IChO-IPhO-RL-v2]; [Physics-Big Dataset]; Scale HLE; [OpenMathReasoning]; [OpenCodeReasoning] | [Qwen3-235B-A22B-Thinking-2507] |
|
| 705 |
+
| Synthetic STEM from Qwen3-235B-A22B-Instruct-2507 and gpt-oss-120b | Text | Undisclosed | [arXiv]; [National Institutes of Health ExPorter]; [BioRxiv]; [PMC Article]; [USPTO Backgrounds]; [peS2o]; Global Regulation; [CORE]; [PG-19]; [DOAB CC BY & CC BY-SA subset]; [NDLTD] | [Qwen3-235B-A22B-Instruct-2507]; [gpt-oss-120b] |
|
| 706 |
+
| Translation Data from TAUS | Text | 1,618,055 | [TAUS proprietary dataset] | Undisclosed |
|
| 707 |
+
| Synthetic Art of Problem Solving and Stack Exchange from gpt-oss-120b, Qwen2.5-32B-Instruct, and Goedel-Prover-V2-32B | Text | 860,469 | [Nemotron-Math-Proofs-v1] | [Goedel-Prover-V2-32B] |
|
| 708 |
+
| Synthetic Art of Problem Solving and Stack Exchange from gpt-oss-120b | Text | 1,201,815 | [Upstream released math dataset]; [AoPS]; [StackOverflow / StackExchange] | [gpt-oss-120b] |
|
| 709 |
+
| Synthetic Multilingual Science and Code data from DeepSeek-R1, DeepSeek-R1-0528, Qwen2.5-32B-Instruct, and Qwen3-235B-A22B, translated with Qwen2.5-32B-Instruct and Qwen2.5-14B-Instruct | Text | Undisclosed | [Nano-V3 SFT Data (without tool call)] | [Qwen/Qwen2.5-14B-Instruct]; [Qwen/Qwen3-4B-Thinking-2507] |
|
| 710 |
+
| Synthetic Multilingual Science and Code data from DeepSeek-R1, DeepSeek-R1-0528, Qwen2.5-32B-Instruct, and Qwen3-235B-A22B, translated with Qwen2.5-32B-Instruct and Qwen2.5-14B-Instruct (Stack Exchange lineage) | Text | Undisclosed | [Stack Exchange]; [SCP-116K]; [LIMO]; [TACO]; Code Contest; Codeforces | [DeepSeek-R1]; [DeepSeek-R1-0528]; [Qwen2.5-32B-Instruct]; [Qwen3-235B-A22B] |
|
| 711 |
+
| Synthetic Search Graph Walk | Text | 6,977 | [Wikidata / Wikipedia KnowledgeBase] | [MiniMaxAI/MiniMax-M2] |
|
| 712 |
+
| Synthetic Agentic Diverse Domains | Text | 281,537 | [Handwritten prompts (synthetic; no external seed data used)] | [SDG model: deepseek-ai/DeepSeek-V3.2, deepseek-ai/DeepSeek-R1-0528, Qwen/Qwen3-235B-A22B-Thinking-2507, Qwen/Qwen3-32B]; [Filtering model: openai/gpt-oss-120b, Qwen/Qwen3-32B, Qwen/Qwen3-235B-A22B-Instruct-2507] |
|
| 713 |
+
| Synthetic Long Context from Qwen3-235B-A22B-Instruct-2507 | Text | Undisclosed | [Long-context SFT seed blend (pre-training blend + nano-v1 post-training data)]; [Long-context SFT data: lc_nothink 256k, MRCR 200k, RULER 256k]; [AALCR seed blend: SEC Filings, CC, Wikipedia, FinePDFs, ArXiv, Pile-NIH ExPorter, BioRxiv, PMC Article, USPTO Backgrounds, peS2o, Global Regulations, CORE, Gutenberg (PG-19), DOAB CC-BY, NDLTD, Amps, StackExchange, MathPile, Numinas] | [Qwen/Qwen3-235B-A22B-Thinking-2507]; [deepseek-ai/DeepSeek-R1]; [Qwen3-30B-A3B] |
|
| 714 |
+
| Synthetic Nemotron Math SFT from DeepSeek-V3.2-Speciale | Text | 1,900,553 | [Nemotron-Math-v2 (AOPS and StackExchange-math problems)] | [DeepSeek-V3.2-Speciale] |
|
| 715 |
+
| Synthetic Nemotron Math TIR from DeepSeek-V3.2 | Text | 1,789,258 | [Nemotron-Math-v2 (AOPS and StackExchange-math problems)] | [DeepSeek-V3.2] |
|
| 716 |
+
| Synthetic NemoCascade OCR Distillation from gpt-oss-120b | Text | 682,864 | [Nemotron-X training datasets] | [gpt-oss-120b] |
|
| 717 |
+
| Synthetic CUDA 100k | Text | 93,086 | [KernelBook]; [HuggingFace Transformers]; [FlashInfer] | [gpt-oss-120b]; [DeepSeek-R1-0528] |
|
| 718 |
+
| Synthetic Science MCQ and QA Diversity from GPT-OSS and Kimi-K2 | Text | 30,358 | [doubtnut]; [Pile-FreeLaw]; [Llama Nemotron Dataset]; [askfilo]; [EssentialAI/essential-web-v1.0]; [Vedantu]; [auxiliary_train]; [cdquestions.com]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [AAPT]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)] | [GPT-OSS]; [Kimi-K2] |
|
| 719 |
+
| Synthetic Science HLE with Python from GPT-OSS and Kimi-K2 | Text | 85,184 | [doubtnut]; [Pile-FreeLaw]; [Llama Nemotron Dataset]; [askfilo]; [EssentialAI/essential-web-v1.0]; [Vedantu]; [auxiliary_train]; [cdquestions.com]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [AAPT]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)] | [GPT-OSS]; [Kimi-K2] |
|
| 720 |
+
| Synthetic Science Search and Python from GPT-OSS and Kimi-K2 | Text | 6,179 | [doubtnut]; [Pile-FreeLaw]; [Llama Nemotron Dataset]; [askfilo]; [EssentialAI/essential-web-v1.0]; [Vedantu]; [auxiliary_train]; [cdquestions.com]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [AAPT]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)] | [GPT-OSS]; [Kimi-K2] |
|
| 721 |
+
| Synthetic Science Search from GPT-OSS and Kimi-K2 | Text | 32,554 | [doubtnut]; [Pile-FreeLaw]; [Llama Nemotron Dataset]; [askfilo]; [EssentialAI/essential-web-v1.0]; [Vedantu]; [auxiliary_train]; [cdquestions.com]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [AAPT]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)] | [GPT-OSS]; [Kimi-K2] |
|
| 722 |
+
| Synthetic Finance Reasoning from GPT-OSS-120B and Qwen3-235B-A22B-Instruct-2507 | Text | 326,700 | [SEC filings] | [GPT-OSS-120B, Qwen3-235B-A22B-Instruct-2507] |
|
| 723 |
+
| Synthetic Science Diversity MCQ from GPT-OSS and Kimi-K2 | Text | 532,942 | [doubtnut]; [Pile-FreeLaw]; [Llama Nemotron Dataset]; [askfilo]; [EssentialAI/essential-web-v1.0]; [Vedantu]; [auxiliary_train]; [cdquestions.com]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [AAPT]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)] | [GPT-OSS]; [Kimi-K2] |
|
| 724 |
+
| Synthetic Science Diversity OpenQ from GPT-OSS and Kimi-K2 | Text | 131,045 | [doubtnut]; [Pile-FreeLaw]; [Llama Nemotron Dataset]; [askfilo]; [EssentialAI/essential-web-v1.0]; [Vedantu]; [auxiliary_train]; [cdquestions.com]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [AAPT]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)] | [GPT-OSS]; [Kimi-K2] |
|
| 725 |
+
| Synthetic Science Reasoning No-Tool from GPT-OSS and Kimi-K2 | Text | 2,085,600 | [doubtnut]; [Pile-FreeLaw]; [Llama Nemotron Dataset]; [askfilo]; [EssentialAI/essential-web-v1.0]; [Vedantu]; [auxiliary_train]; [cdquestions.com]; [AMC 8 Problems and Solutions, AMC 10 Problems and Solution, and AIME Problems and Solutions]; [AAPT]; [ICHO-IPH0 Dataset]; [LIMO dataset (Less is More for Reasoning)] | [GPT-OSS]; [Kimi-K2] |
|
| 726 |
+
| Synthetic Text-To-SQL from gpt-oss-120b | Text | Undisclosed | [In-house Text-to-SQL data] | [gpt-oss-120b] |
|
| 727 |
+
| Synthetic Tool Call Schema for RL (extended) | Text | 707,967 | [UltraTool]; [ToolEyes]; [AutoTools]; [API-Bank]; [Nemotron-Personas-USA]; [Salesforce xLAM function-calling]; [Glaive function-calling-v2]; [Agent-Ark/Toucan-1.5M] | [DeepSeek-V3.2]; [GLM-4.6]; [gpt-oss-120b]; [Kimi-K2-Instruct] |
|
| 728 |
+
| Synthetic Safety from gemma-3-4b-it, Nemotron-Nano-9B-v2, and gpt-oss-120b | Text | 44,091 | [Safety SFT Data] | [google/gemma-3-4b-it]; [Nemotron-Nano-9B-v2]; [gpt-oss-120b] |
|
| 729 |
+
| Synthetic Safety from DeepSeek-R1-0528, gpt-oss-120b, DeepSeek-R1-Distill-Qwen-7B, and Mixtral-8x7B-v0.1 | Text | Undisclosed | [Nemotron Content Safety Dataset V2]; [Gretel Synthetic Safety Alignment Dataset]; [RedTeam-2K]; [Malicious Tasks]; [Nemotron-Personas-USA] | [DeepSeek-R1-0528]; [gpt-oss-120b]; [DeepSeek-R1-Distill-Qwen-7B]; [Qwen3-30B-A3B-Thinking-2507]; [Qwen3-235B-A22B-Instruct-2507]; [Mixtral-8x7B-v0.1] |
|
| 730 |
+
| Synthetic Tool Calling from Qwen3-235B-A22B-Thinking-2507 and Qwen3-Next-80B-A3B-Thinking | Text | Undisclosed | [ToolBench]; [glaive-function-calling-v2]; [APIGen Function-Calling]; [Nemotron-Personas-USA] | [Qwen3-235B-A22B-Thinking-2507]; [Qwen3-Next-80B-A3B-Thinking] |
|
| 731 |
+
| Synthetic Chat from gpt-oss-120b, Mixtral-8x22B-Instruct-v0.1, Qwen3-235B-A22B-Instruct-2507, and Qwen3-235B-A22B-Thinking-2507 | Text | Undisclosed | [C4]; [LMSYS-Chat-1M]; [ShareGPT]; [GSM8K]; [PRM800K]; [FinQA]; [WikiTableQuestions]; [Riddles]; [glaive-function-calling-v2]; [SciBench]; [tigerbot-kaggle-leetcodesolutions-en-2k]; [OpenBookQA]; [Advanced Reasoning Benchmark]; Software Heritage; [Khan Academy Math Keywords]; [WildChat-1M]; [Nemotron-Personas-USA] | [gpt-oss-120b]; [Mixtral-8x22B-Instruct-v0.1]; [Qwen3-235B-A22B-Instruct-2507]; [Qwen3-235B-A22B-Thinking-2507] |
|
| 732 |
+
| Synthetic Tool Use Interactive Agent from gpt-oss-120b, DeepSeek-R1-0528, Qwen3-32B, and Qwen3-235B-A22B-Thinking-2507 | Text | Undisclosed | NVIDIA Internal | [gpt-oss-120b]; [DeepSeek-R1-0528]; [Qwen3-32B]; [Qwen3-235B-A22B-Thinking-2507] |
|
| 733 |
+
| Synthetic DocFinQA and SWE-smith from Qwen3-Coder-480B-A35B-Instruct and Kimi-K2-Thinking | Text | Undisclosed | [DocFinQA]; [SWE-smith] | [Qwen3-Coder-480B-A35B-Instruct]; [Kimi-K2-Thinking] |
|
| 734 |
+
| Synthetic SWE-Gym from Qwen3-Coder-480B-A35B-Instruct | Text | Undisclosed | [SWE-Gym] | [Qwen3-Coder-480B-A35B-Instruct] |
|
| 735 |
+
| Synthetic SWE-Gym and R2E-Gym-Subset from Qwen3-Coder-480B-A35B-Instruct | Text | Undisclosed | [SWE-Gym]; [R2E-Gym-Subset] | [Qwen3-Coder-480B-A35B-Instruct] |
|
| 736 |
+
| Synthetic SWE-Gym and R2E-Gym-Subset from DeepSeek-R1-0528 | Text | Undisclosed | [SWE-Gym]; [R2E-Gym-Subset] | [DeepSeek-R1-0528] |
|
| 737 |
+
| Synthetic HelpSteer, LMSYS-Chat-1M, and Nemotron-Personas-USA from gpt-oss-120b, Qwen3-235B-A22B-Instruct-2507, and Qwen3-235B-A22B-Thinking-2507 | Text | Undisclosed | [HelpSteer2]; [HelpSteer3]; [LMSYS-Chat-1M]; [Nemotron-Personas-USA] | [gpt-oss-120b]; [Qwen3-235B-A22B-Instruct-2507]; [Qwen3-235B-A22B-Thinking-2507] |
|
| 738 |
+
| Synthetic Nemotron-Personas-USA from gpt-oss-120b and Qwen3-8B | Text | Undisclosed | [Nemotron-Personas-USA] | [gpt-oss-120b]; [Qwen3-8B] |
|
| 739 |
+
| Vendor Terminal Bench-like Tasks (Droid) | Text | Undisclosed | [Droid Harness Pivot vendor data] | Undisclosed |
|
| 740 |
+
|
| 741 |
+
|
| 742 |
+
## Testing Datasets
|
| 743 |
+
|
| 744 |
+
**Data Collection Method by dataset** <br>
|
| 745 |
+
* Hybrid: Automated, Manually-Collected, Synthetic
|
| 746 |
+
|
| 747 |
+
**Labeling Method by dataset** <br>
|
| 748 |
+
* Hybrid: Automated, Manually-Labeled, Synthetic
|
| 749 |
+
|
| 750 |
+
|
| 751 |
+
**Properties:** This corpus comprises a mix of high-quality standard benchmarks and test suites for modern multimodal agentic AI. These benchmarks test model capabilities on tasks such as document and chart understanding, GUI grounding, video understanding, tool-calling, and instruction following.
|
| 752 |
+
|
| 753 |
+
## Evaluation Datasets
|
| 754 |
+
|
| 755 |
+
**Data Collection Method by dataset** <br>
|
| 756 |
+
* Hybrid: Automated, Manually-Collected, Synthetic
|
| 757 |
+
|
| 758 |
+
**Labeling Method by dataset** <br>
|
| 759 |
+
* Hybrid: Automated, Manually-Labeled, Synthetic
|
| 760 |
+
|
| 761 |
+
|
| 762 |
+
**Properties:** This corpus comprises a mix of high-quality standard benchmarks and test suites for modern multimodal agentic AI. These benchmarks test model capabilities on tasks such as document and chart understanding, GUI grounding, video understanding, tool-calling, and instruction following.
|
| 763 |
+
|
| 764 |
+
## Inference
|
| 765 |
+
|
| 766 |
+
* **Acceleration Engine:** PyTorch
|
| 767 |
+
* **Test Hardware:**
|
| 768 |
+
* NVIDIA Hopper H100
|
| 769 |
+
* NVIDIA Hopper H200
|
| 770 |
+
* NVIDIA Blackwell GB200
|
| 771 |
+
* NVIDIA Blackwell GeForce RTX 5090
|
| 772 |
+
* NVIDIA DGX Spark
|
| 773 |
+
* NVIDIA RTX Spark
|
| 774 |
+
|
| 775 |
+
## Ethical Considerations
|
| 776 |
+
|
| 777 |
+
NVIDIA believes Trustworthy AI is a shared responsibility and we have established policies and practices to enable development for a wide array of AI applications. Developers should work with their internal model team to ensure this model meets requirements for the relevant industry and use case and addresses unforeseen product misuse.
|
| 778 |
+
|
| 779 |
+
Please make sure you have proper rights and permissions for all input image and video content; if image or video includes people, personal health information, or intellectual property, the model output will not blur or maintain proportions of image subjects included.
|
| 780 |
+
|
| 781 |
+
We advise against circumvention of any provided safety guardrails contained in the Model without a substantially similar guardrail appropriate for your use case. For more details: [Safety](./safety.md) and [Explainability](./explainability.md) Subcards.
|
| 782 |
+
|
| 783 |
+
For more detailed information on ethical considerations for this model, please see the Model Card++ [Bias](./bias.md), [Explainability](./explainability.md), [Safety & Security](./safety.md), and [Privacy](./privacy.md) Subcards.
|
| 784 |
+
|
| 785 |
+
Please report model quality, risk, security vulnerabilities or NVIDIA AI Concerns [here](https://www.nvidia.com/en-us/support/submit-security-vulnerability/).
|
__init__.py
ADDED
|
File without changes
|
accuracy.png
ADDED
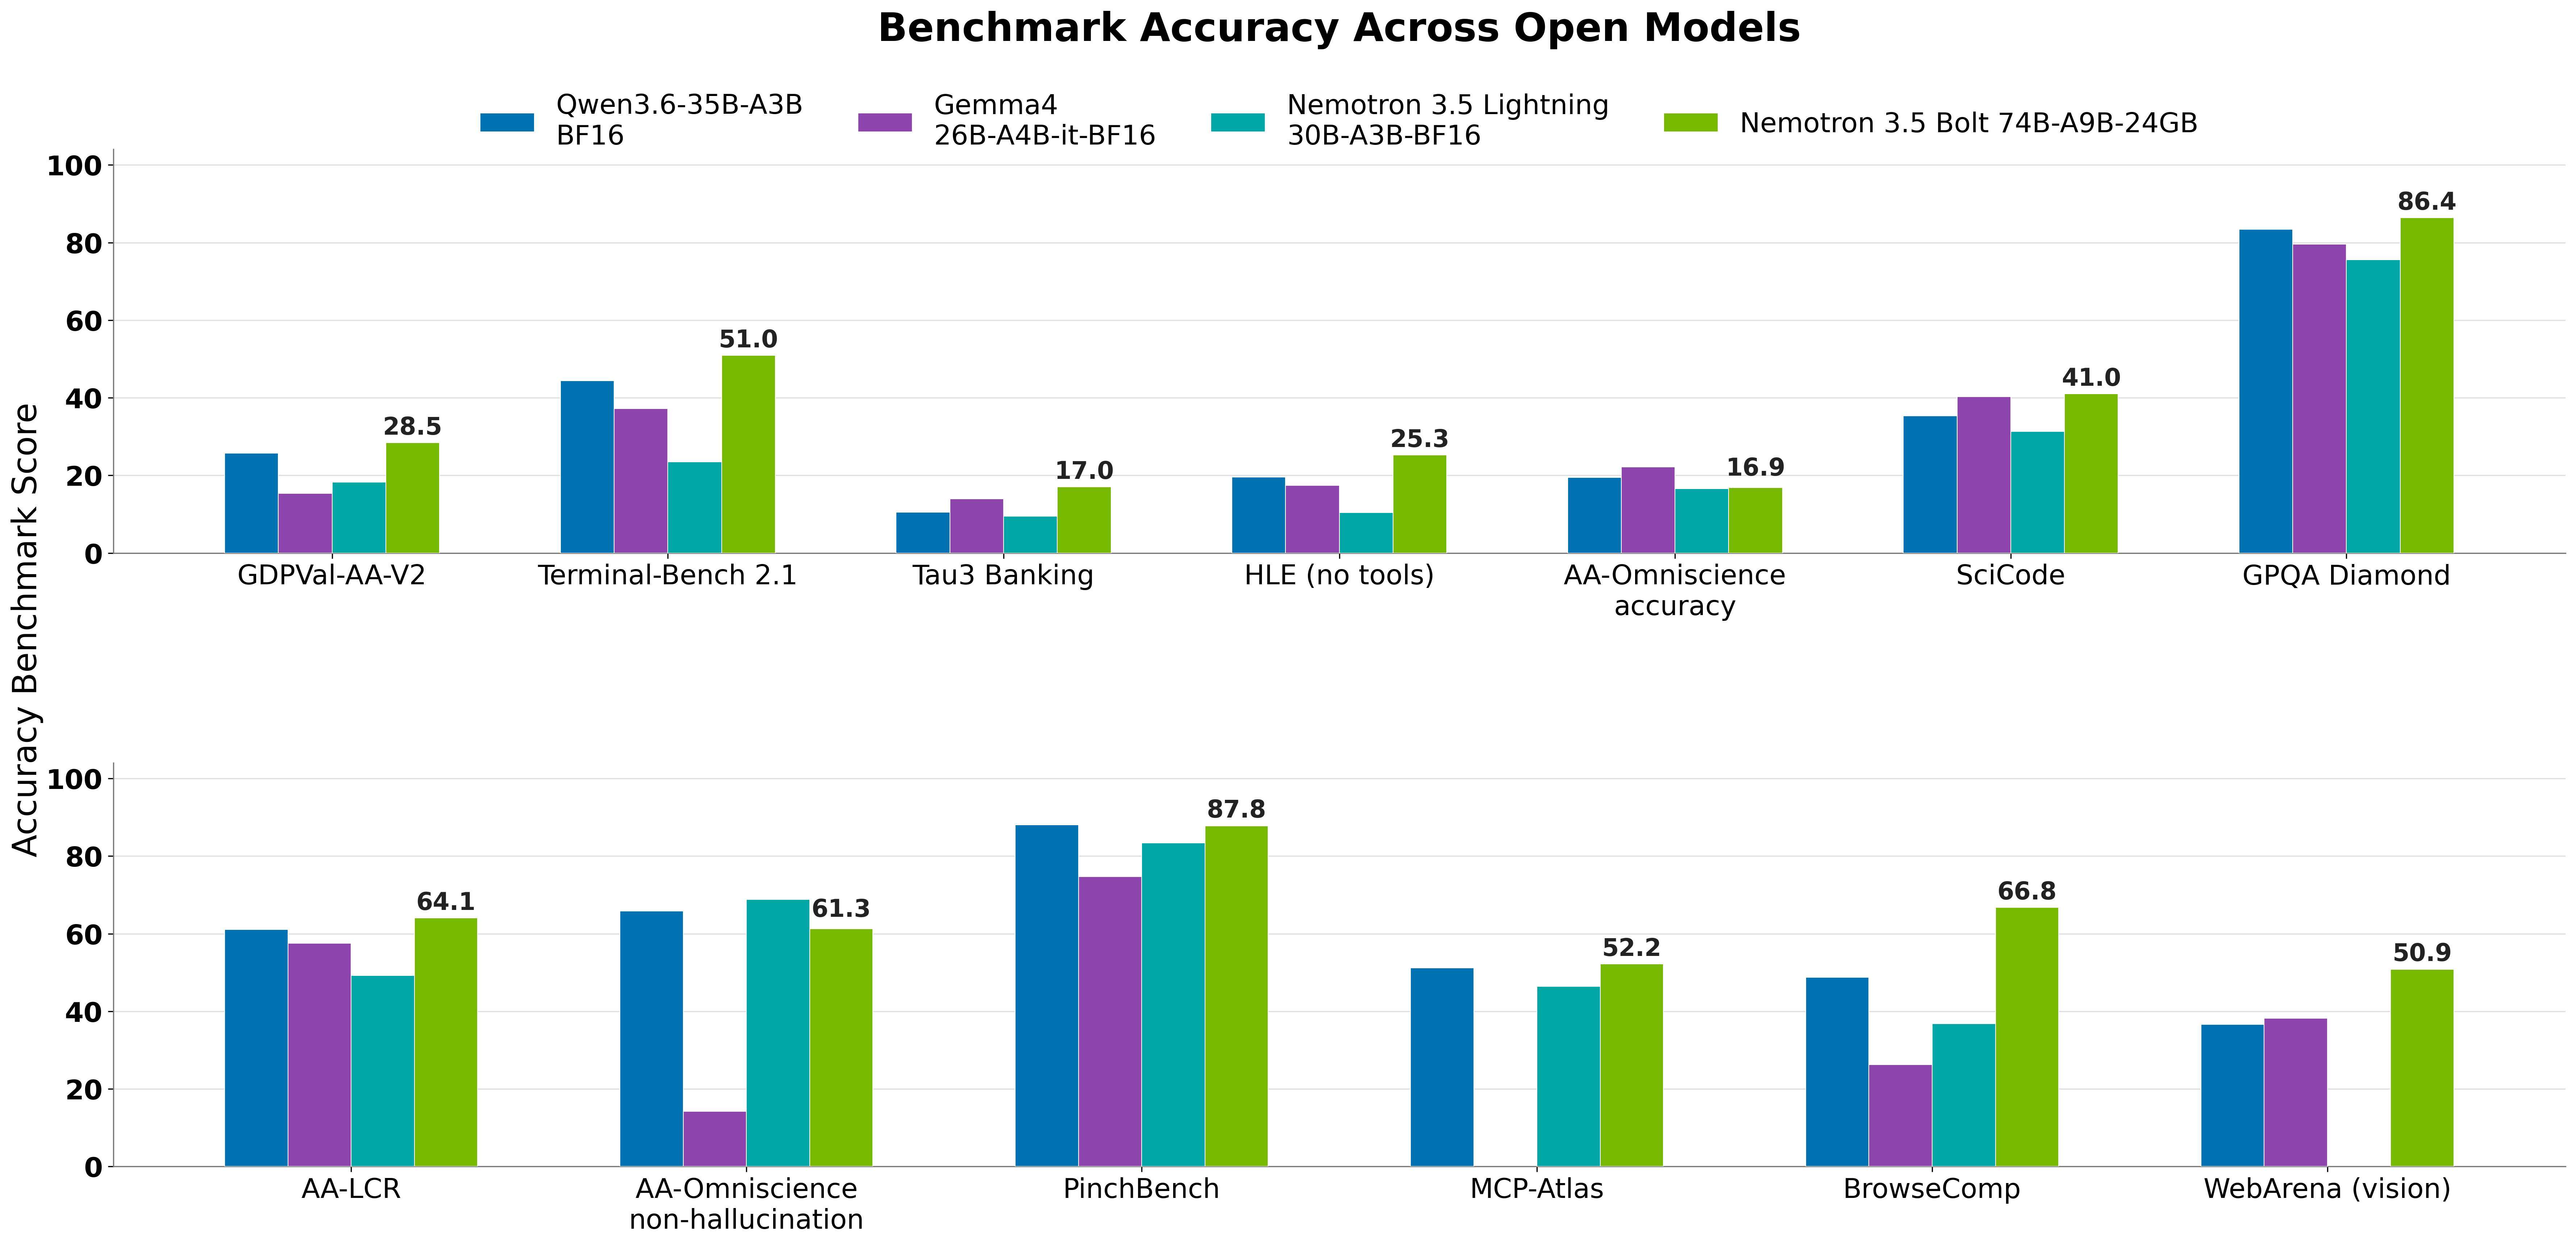
|
Git LFS Details
|
bias.md
ADDED
|
@@ -0,0 +1,10 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
| Field | Response |
|
| 2 |
+
| :---- | :---- |
|
| 3 |
+
| Participation considerations from adversely impacted groups [protected classes](https://www.senate.ca.gov/content/protected-classes) in model design and testing: | None |
|
| 4 |
+
| Bias Metric (If Measured): | [BBQ Accuracy Scores in Ambiguous Contexts](https://github.com/nyu-mll/BBQ/) |
|
| 5 |
+
| Which characteristic (feature) show(s) the greatest difference in performance?: | The model shows high variance in the characteristics when it is used with a high temperature. |
|
| 6 |
+
| Measures taken to mitigate against unwanted bias: | Supervised Fine-Tuning (SFT) and Reinforcement Learning from Human Feedback (RLHF) employed to calibrate the model’s reasoning capabilities to maintain logical consistency and appropriate complexity when interacting with or interpreting data from diverse age demographics. |
|
| 7 |
+
| If using internal data, description of methods implemented in data acquisition or processing, if any, to address the prevalence of identifiable biases in the training, testing, and validation data: | The training datasets contain a large amount of synthetic data generated by LLMs. We manually curated prompts. |
|
| 8 |
+
| Tools used to assess statistical imbalances and highlight patterns that may introduce bias into AI models: | [BBQ](https://github.com/nyu-mll/BBQ/) |
|
| 9 |
+
| Tools used to assess statistical imbalances and highlight patterns that may introduce bias into AI models: | These datasets, such as web-scraped finance reasoning data derived from SEC EDGAR filings, science and math problem datasets, OpenResearcher/source-document datasets, Common Crawl, CC-News, Wikimedia, and long-context document datasets, do not collectively or exhaustively represent all demographic groups (and proportionally therein). For instance, these datasets do not contain explicit mentions of demographic classes such as age, gender, or ethnicity in approximately 97% to 99.9% of finance reasoning samples and in over 85% of samples across the broader assessed datasets. In the subset where such terms are present, these datasets contain notable representational skews. For example, ethnicity mentions are often dominated by Middle Eastern contexts (found in finance documents) or "White," "Two or more," and "Black or African American" as the most frequent ethnic identifiers, while references categorized as male-only significantly outnumber those categorized as female-only. Furthermore, gender is explicitly mentioned in approximately 12% of samples across the broader dataset assessment, yet in only 0.9% of finance-specific samples. Dataset-level results vary by source type, with long-context/source-document datasets containing higher explicit demographic mention rates compared to certain web-scraped sources. To mitigate these imbalances, we recommend considering evaluation techniques such as bias audits, fine-tuning with demographically balanced datasets, and mitigation strategies such as counterfactual data augmentation to align with the desired model behavior. This evaluation used a 3,000-sample subset per dataset, identified as the optimal threshold for maximizing embedder accuracy. |
|
| 10 |
+
| Unwanted Bias Testing: | Constrained to English-language inputs. Multi-lingual parity is not currently claimed or guaranteed. |
|
chat_template.jinja
ADDED
|
@@ -0,0 +1,240 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{% macro render_extra_keys(json_dict, handled_keys) %}
|
| 2 |
+
{%- if json_dict is mapping %}
|
| 3 |
+
{%- for json_key in json_dict if json_key not in handled_keys %}
|
| 4 |
+
{%- if json_dict[json_key] is mapping or (json_dict[json_key] is sequence and json_dict[json_key] is not string) %}
|
| 5 |
+
{{- '\n<' ~ json_key ~ '>' ~ (json_dict[json_key] | tojson | safe) ~ '</' ~ json_key ~ '>' }}
|
| 6 |
+
{%- else %}
|
| 7 |
+
{{-'\n<' ~ json_key ~ '>' ~ (json_dict[json_key] | string) ~ '</' ~ json_key ~ '>' }}
|
| 8 |
+
{%- endif %}
|
| 9 |
+
{%- endfor %}
|
| 10 |
+
{%- endif %}
|
| 11 |
+
{% endmacro %}
|
| 12 |
+
{%- macro render_content(content) -%}
|
| 13 |
+
{%- if content is none -%}
|
| 14 |
+
{{- '' -}}
|
| 15 |
+
{%- elif content is string -%}
|
| 16 |
+
{{- content | string -}}
|
| 17 |
+
{%- else -%}
|
| 18 |
+
{%- set text_ns = namespace(val='') -%}
|
| 19 |
+
{%- set counters = namespace(images=0, videos=0) -%}
|
| 20 |
+
{%- for part in content -%}
|
| 21 |
+
{%- if part['type'] == 'image' or part['type'] == 'image_url' or part['type'] == 'input_image' -%}
|
| 22 |
+
{%- set counters.images = counters.images + 1 -%}
|
| 23 |
+
{%- elif part['type'] == 'video' or part['type'] == 'video_url' or part['type'] == 'input_video' -%}
|
| 24 |
+
{%- set counters.videos = counters.videos + 1 -%}
|
| 25 |
+
{%- elif part['type'] == 'text' or part['type'] == 'input_text' -%}
|
| 26 |
+
{%- set text_ns.val = text_ns.val + (part['text'] | default('', true)) -%}
|
| 27 |
+
{%- endif -%}
|
| 28 |
+
{%- endfor -%}
|
| 29 |
+
{%- if '<image>' in text_ns.val -%}
|
| 30 |
+
{%- set counters.images = 0 -%}
|
| 31 |
+
{%- endif -%}
|
| 32 |
+
{%- if '<video>' in text_ns.val -%}
|
| 33 |
+
{%- set counters.videos = 0 -%}
|
| 34 |
+
{%- endif -%}
|
| 35 |
+
{%- set content_ns = namespace(val='') -%}
|
| 36 |
+
{%- set render_ns = namespace(image_index=0) -%}
|
| 37 |
+
{%- for part in content -%}
|
| 38 |
+
{%- if part['type'] == 'image' or part['type'] == 'image_url' or part['type'] == 'input_image' -%}
|
| 39 |
+
{%- set render_ns.image_index = render_ns.image_index + 1 -%}
|
| 40 |
+
{%- if counters.images > 0 -%}
|
| 41 |
+
{%- if counters.images > 1 -%}
|
| 42 |
+
{%- set content_ns.val = content_ns.val
|
| 43 |
+
+ '<image ' + render_ns.image_index|string + '><image>' -%}
|
| 44 |
+
{%- else -%}
|
| 45 |
+
{%- set content_ns.val = content_ns.val + '<image>' -%}
|
| 46 |
+
{%- endif -%}
|
| 47 |
+
{%- endif -%}
|
| 48 |
+
{%- elif part['type'] == 'video' or part['type'] == 'video_url' or part['type'] == 'input_video' -%}
|
| 49 |
+
{%- if counters.videos > 0 -%}
|
| 50 |
+
{%- set content_ns.val = content_ns.val + '<video>' -%}
|
| 51 |
+
{%- endif -%}
|
| 52 |
+
{%- elif part['type'] == 'text' or part['type'] == 'input_text' -%}
|
| 53 |
+
{%- set content_ns.val = content_ns.val + (part['text'] | default('', true)) -%}
|
| 54 |
+
{%- endif -%}
|
| 55 |
+
{%- endfor -%}
|
| 56 |
+
{{- content_ns.val -}}
|
| 57 |
+
{%- endif -%}
|
| 58 |
+
{%- endmacro %}
|
| 59 |
+
{%- set enable_thinking = enable_thinking if enable_thinking is defined else True %}
|
| 60 |
+
{%- set medium_effort = medium_effort if medium_effort is defined else False %}
|
| 61 |
+
{%- set truncate_history_thinking = truncate_history_thinking if truncate_history_thinking is defined else True %}
|
| 62 |
+
{%- set ns = namespace(last_user_idx = -1) %}
|
| 63 |
+
{%- set loop_messages = messages %}
|
| 64 |
+
{%- for m in loop_messages %}
|
| 65 |
+
{%- if m["role"] == "user" %}
|
| 66 |
+
{%- set ns.last_user_idx = loop.index0 %}
|
| 67 |
+
{%- endif %}
|
| 68 |
+
{%- endfor %}
|
| 69 |
+
{%- if messages[0]["role"] == "system" %}
|
| 70 |
+
{%- set system_message = messages[0]["content"] %}
|
| 71 |
+
{%- set loop_messages = messages[1:] %}
|
| 72 |
+
{%- else %}
|
| 73 |
+
{%- set system_message = "" %}
|
| 74 |
+
{%- set loop_messages = messages %}
|
| 75 |
+
{%- endif %}
|
| 76 |
+
{%- if not tools is defined %}
|
| 77 |
+
{%- set tools = [] %}
|
| 78 |
+
{%- endif %}
|
| 79 |
+
{%- set ns = namespace(last_user_idx = -1) %}
|
| 80 |
+
{%- for m in loop_messages %}
|
| 81 |
+
{%- if m["role"] == "user" %}
|
| 82 |
+
{%- set ns.last_user_idx = loop.index0 %}
|
| 83 |
+
{%- endif %}
|
| 84 |
+
{%- endfor %}
|
| 85 |
+
{%- if system_message is defined %}
|
| 86 |
+
{{- "<|im_start|>system\n" ~ render_content(system_message) }}
|
| 87 |
+
{%- else %}
|
| 88 |
+
{%- if tools is iterable and tools | length > 0 %}
|
| 89 |
+
{{- "<|im_start|>system\n" }}
|
| 90 |
+
{%- endif %}
|
| 91 |
+
{%- endif %}
|
| 92 |
+
{%- if tools is iterable and tools | length > 0 %}
|
| 93 |
+
{%- if system_message is defined and system_message | length > 0 %}
|
| 94 |
+
{{- "\n\n" }}
|
| 95 |
+
{%- endif %}
|
| 96 |
+
{{- "# Tools\n\nYou have access to the following functions:\n\n" }}
|
| 97 |
+
{{- "<tools>" }}
|
| 98 |
+
{%- for tool in tools %}
|
| 99 |
+
{%- if tool.function is defined %}
|
| 100 |
+
{%- set tool = tool.function %}
|
| 101 |
+
{%- endif %}
|
| 102 |
+
{{- "\n<function>\n<name>" ~ tool.name ~ "</name>" }}
|
| 103 |
+
{%- if tool.description is defined %}
|
| 104 |
+
{{- '\n<description>' ~ (tool.description | trim) ~ '</description>' }}
|
| 105 |
+
{%- endif %}
|
| 106 |
+
{{- '\n<parameters>' }}
|
| 107 |
+
{%- if tool.parameters is defined and tool.parameters is mapping and tool.parameters.properties is defined and tool.parameters.properties is mapping %}
|
| 108 |
+
{%- for param_name, param_fields in tool.parameters.properties|items %}
|
| 109 |
+
{{- '\n<parameter>' }}
|
| 110 |
+
{{- '\n<name>' ~ param_name ~ '</name>' }}
|
| 111 |
+
{%- if param_fields.type is defined %}
|
| 112 |
+
{{- '\n<type>' ~ (param_fields.type | string) ~ '</type>' }}
|
| 113 |
+
{%- endif %}
|
| 114 |
+
{%- if param_fields.description is defined %}
|
| 115 |
+
{{- '\n<description>' ~ (param_fields.description | trim) ~ '</description>' }}
|
| 116 |
+
{%- endif %}
|
| 117 |
+
{%- if param_fields.enum is defined %}
|
| 118 |
+
{{- '\n<enum>' ~ (param_fields.enum | tojson | safe) ~ '</enum>' }}
|
| 119 |
+
{%- endif %}
|
| 120 |
+
{%- set handled_keys = ['name', 'type', 'description', 'enum'] %}
|
| 121 |
+
{{- render_extra_keys(param_fields, handled_keys) }}
|
| 122 |
+
{{- '\n</parameter>' }}
|
| 123 |
+
{%- endfor %}
|
| 124 |
+
{%- endif %}
|
| 125 |
+
{% set handled_keys = ['type', 'properties', 'required'] %}
|
| 126 |
+
{{- render_extra_keys(tool.parameters, handled_keys) }}
|
| 127 |
+
{%- if tool.parameters is defined and tool.parameters.required is defined %}
|
| 128 |
+
{{- '\n<required>' ~ (tool.parameters.required | tojson | safe) ~ '</required>' }}
|
| 129 |
+
{%- endif %}
|
| 130 |
+
{{- '\n</parameters>' }}
|
| 131 |
+
{%- set handled_keys = ['type', 'name', 'description', 'parameters'] %}
|
| 132 |
+
{{- render_extra_keys(tool, handled_keys) }}
|
| 133 |
+
{{- '\n</function>' }}
|
| 134 |
+
{%- endfor %}
|
| 135 |
+
{{- "\n</tools>" }}
|
| 136 |
+
{{- '\n\nIf you choose to call a function ONLY reply in the following format with NO suffix:\n\n<tool_call>\n<function=example_function_name>\n<parameter=example_parameter_1>\nvalue_1\n</parameter>\n<parameter=example_parameter_2>\nThis is the value for the second parameter\nthat can span\nmultiple lines\n</parameter>\n</function>\n</tool_call>\n\n<IMPORTANT>\nReminder:\n- Function calls MUST follow the specified format: an inner <function=...></function> block must be nested within <tool_call></tool_call> XML tags\n- Required parameters MUST be specified\n- You may provide optional reasoning for your function call in natural language BEFORE the function call, but NOT after\n- If there is no function call available, answer the question like normal with your current knowledge and do not tell the user about function calls\n</IMPORTANT>' }}
|
| 137 |
+
{%- endif %}
|
| 138 |
+
{%- if system_message is defined %}
|
| 139 |
+
{{- '<|im_end|>\n' }}
|
| 140 |
+
{%- else %}
|
| 141 |
+
{%- if tools is iterable and tools | length > 0 %}
|
| 142 |
+
{{- '<|im_end|>\n' }}
|
| 143 |
+
{%- endif %}
|
| 144 |
+
{%- endif %}
|
| 145 |
+
{%- for message in loop_messages %}
|
| 146 |
+
{%- set content = render_content(message.content | default('', true)) %}
|
| 147 |
+
{%- if message.role == "assistant" %}
|
| 148 |
+
{%- if message.reasoning_content is defined and message.reasoning_content is string and message.reasoning_content | trim | length > 0 %}
|
| 149 |
+
{%- set content = "<think>\n" ~ message.reasoning_content ~ "</think>" ~ content %}
|
| 150 |
+
{%- else %}
|
| 151 |
+
{%- if content is string -%}
|
| 152 |
+
{%- if '<think>' not in content and '</think>' not in content -%}
|
| 153 |
+
{%- set content = "<think></think>" ~ content -%}
|
| 154 |
+
{%- endif -%}
|
| 155 |
+
{%- endif -%}
|
| 156 |
+
{%- endif %}
|
| 157 |
+
{%- if message.tool_calls is defined and message.tool_calls is iterable and message.tool_calls | length > 0 %}
|
| 158 |
+
{{- '<|im_start|>assistant\n' }}
|
| 159 |
+
{%- set include_content = not (truncate_history_thinking and loop.index0 < ns.last_user_idx) %}
|
| 160 |
+
{%- if content is string and content | trim | length > 0 %}
|
| 161 |
+
{%- if include_content %}
|
| 162 |
+
{{- (content | trim) ~ '\n' -}}
|
| 163 |
+
{%- else %}
|
| 164 |
+
{%- set c = (content | string) %}
|
| 165 |
+
{%- if '</think>' in c %}
|
| 166 |
+
{%- set c = c.split('</think>')[-1] %}
|
| 167 |
+
{%- elif '<think>' in c %}
|
| 168 |
+
{%- set c = c.split('<think>')[0] %}
|
| 169 |
+
{%- endif %}
|
| 170 |
+
{%- set c = "<think></think>" ~ c %}
|
| 171 |
+
{%- if c | length > 0 %}
|
| 172 |
+
{{- c ~ '\n' -}}
|
| 173 |
+
{%- endif %}
|
| 174 |
+
{%- endif %}
|
| 175 |
+
{%- else %}
|
| 176 |
+
{{- "<think></think>" -}}
|
| 177 |
+
{%- endif %}
|
| 178 |
+
{%- for tool_call in message.tool_calls %}
|
| 179 |
+
{%- if tool_call.function is defined %}
|
| 180 |
+
{%- set tool_call = tool_call.function %}
|
| 181 |
+
{%- endif %}
|
| 182 |
+
{{- '<tool_call>\n<function=' ~ tool_call.name ~ '>\n' -}}
|
| 183 |
+
{%- if tool_call.arguments is defined %}
|
| 184 |
+
{%- for args_name, args_value in tool_call.arguments|items %}
|
| 185 |
+
{{- '<parameter=' ~ args_name ~ '>\n' -}}
|
| 186 |
+
{%- set args_value = args_value | tojson | safe if args_value is mapping or (args_value is sequence and args_value is not string) else args_value | string %}
|
| 187 |
+
{{- args_value ~ '\n</parameter>\n' -}}
|
| 188 |
+
{%- endfor %}
|
| 189 |
+
{%- endif %}
|
| 190 |
+
{{- '</function>\n</tool_call>\n' -}}
|
| 191 |
+
{%- endfor %}
|
| 192 |
+
{{- '<|im_end|>\n' }}
|
| 193 |
+
{%- else %}
|
| 194 |
+
{%- if not (truncate_history_thinking and loop.index0 < ns.last_user_idx) %}
|
| 195 |
+
{{- '<|im_start|>assistant\n' ~ (content | default('', true) | string | trim) ~ '<|im_end|>\n' }}
|
| 196 |
+
{%- else %}
|
| 197 |
+
{%- set c = (content | default('', true) | string) %}
|
| 198 |
+
{%- if '<think>' in c and '</think>' in c %}
|
| 199 |
+
{%- set c = "<think></think>" ~ c.split('</think>')[-1] %}
|
| 200 |
+
{%- endif %}
|
| 201 |
+
{%- set c = c | trim %}
|
| 202 |
+
{%- if c | length > 0 %}
|
| 203 |
+
{{- '<|im_start|>assistant\n' ~ c ~ '<|im_end|>\n' }}
|
| 204 |
+
{%- else %}
|
| 205 |
+
{{- '<|im_start|>assistant\n<|im_end|>\n' }}
|
| 206 |
+
{%- endif %}
|
| 207 |
+
{%- endif %}
|
| 208 |
+
{%- endif %}
|
| 209 |
+
{%- elif message.role == "user" or message.role == "system" %}
|
| 210 |
+
{{- '<|im_start|>' + message.role + '\n' }}
|
| 211 |
+
{#- Render structured image/video content in its original order. -#}
|
| 212 |
+
{%- if message.role == "user" and loop.index0 == ns.last_user_idx and medium_effort %}
|
| 213 |
+
{{- content + '\n\n{reasoning effort: efficient}' }}
|
| 214 |
+
{%- else %}
|
| 215 |
+
{{- content }}
|
| 216 |
+
{%- endif %}
|
| 217 |
+
{{- '<|im_end|>\n' }}
|
| 218 |
+
{%- elif message.role == "tool" %}
|
| 219 |
+
{%- if loop.previtem and loop.previtem.role != "tool" %}
|
| 220 |
+
{{- '<|im_start|>user\n' }}
|
| 221 |
+
{%- endif %}
|
| 222 |
+
{{- '<tool_response>\n' }}
|
| 223 |
+
{{- content }}
|
| 224 |
+
{{- '\n</tool_response>\n' }}
|
| 225 |
+
{%- if not loop.last and loop.nextitem.role != "tool" %}
|
| 226 |
+
{{- '<|im_end|>\n' }}
|
| 227 |
+
{%- elif loop.last %}
|
| 228 |
+
{{- '<|im_end|>\n' }}
|
| 229 |
+
{%- endif %}
|
| 230 |
+
{%- else %}
|
| 231 |
+
{{- '<|im_start|>' ~ message.role ~ '\n' ~ content ~ '<|im_end|>\n' }}
|
| 232 |
+
{%- endif %}
|
| 233 |
+
{%- endfor %}
|
| 234 |
+
{%- if add_generation_prompt %}
|
| 235 |
+
{%- if enable_thinking %}
|
| 236 |
+
{{- '<|im_start|>assistant\n<think>\n' }}
|
| 237 |
+
{%- else %}
|
| 238 |
+
{{- '<|im_start|>assistant\n<think></think>' }}
|
| 239 |
+
{%- endif %}
|
| 240 |
+
{%- endif %}
|
config.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
configuration_nemotron_h.py
ADDED
|
@@ -0,0 +1,410 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright 2024-2025 NVIDIA Corporation and The HuggingFace Inc. team. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
"""NemotronH model configuration"""
|
| 15 |
+
|
| 16 |
+
from transformers.configuration_utils import PretrainedConfig
|
| 17 |
+
from transformers.utils import logging
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
logger = logging.get_logger(__name__)
|
| 21 |
+
|
| 22 |
+
|
| 23 |
+
class NemotronHConfig(PretrainedConfig):
|
| 24 |
+
r"""
|
| 25 |
+
This is the configuration class to store the configuration of a [`NemotronHModel`]. It is used to instantiate a
|
| 26 |
+
NemotronH model according to the specified arguments, defining the model architecture. Instantiating a configuration
|
| 27 |
+
with the defaults will yield a similar configuration to that of NVIDIA-Nemotron-3-Nano-30B-A3B-BF16 [nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-BF16](https://huggingface.co/nvidia/NVIDIA-Nemotron-3-Nano-30B-A3B-BF16).
|
| 28 |
+
|
| 29 |
+
Configuration objects inherit from [`PretrainedConfig`] and can be used to control the model outputs. Read the
|
| 30 |
+
documentation from [`PretrainedConfig`] for more information.
|
| 31 |
+
|
| 32 |
+
|
| 33 |
+
Args:
|
| 34 |
+
vocab_size (`int`, *optional*, defaults to 131072):
|
| 35 |
+
Vocabulary size of the NemotronH model. Defines the number of different tokens that can be represented by
|
| 36 |
+
the `inputs_ids` passed when calling [`NemotronHModel`].
|
| 37 |
+
hidden_size (`int`, *optional*, defaults to 4096):
|
| 38 |
+
Dimension of the hidden representations.
|
| 39 |
+
layers_block_type (`list`, *optional*):
|
| 40 |
+
Explicit list of layer types for each layer. Each element must be one of: "mamba", "attention", or "moe".
|
| 41 |
+
The number of layers is determined by the length of this list.
|
| 42 |
+
num_hidden_layers (`int`, *optional*):
|
| 43 |
+
Number of hidden layers in the Transformer encoder. This parameter is deprecated and only kept for
|
| 44 |
+
backward compatibility. The number of layers is now determined by the length of `layers_block_type`.
|
| 45 |
+
tie_word_embeddings (`bool`, *optional*, defaults to `False`):
|
| 46 |
+
Whether the model's input and output word embeddings should be tied.
|
| 47 |
+
use_cache (`bool`, *optional*, defaults to `True`):
|
| 48 |
+
Whether or not the model should return the last key/values attentions.
|
| 49 |
+
num_logits_to_keep (`int`, *optional*, defaults to 1):
|
| 50 |
+
Number of prompt logits to calculate during generation. If `None`, all logits will be calculated.
|
| 51 |
+
pad_token_id (`int`, *optional*, defaults to 0):
|
| 52 |
+
The id of the padding token.
|
| 53 |
+
bos_token_id (`int`, *optional*, defaults to 1):
|
| 54 |
+
The id of the "beginning-of-sequence" token.
|
| 55 |
+
eos_token_id (`int`, *optional*, defaults to 2):
|
| 56 |
+
The id of the "end-of-sequence" token.
|
| 57 |
+
num_attention_heads (`int`, *optional*, defaults to 32):
|
| 58 |
+
Number of attention heads for each attention layer in the Transformer encoder.
|
| 59 |
+
num_key_value_heads (`int`, *optional*, defaults to 8):
|
| 60 |
+
This is the number of key_value heads that should be used to implement Grouped Query Attention.
|
| 61 |
+
head_dim (`int`, *optional*, defaults to 128):
|
| 62 |
+
Dimension of each attention head.
|
| 63 |
+
max_position_embeddings (`int`, *optional*, defaults to 4096):
|
| 64 |
+
The maximum sequence length that this model might ever be used with.
|
| 65 |
+
attention_bias (`bool`, *optional*, defaults to `False`):
|
| 66 |
+
Whether to use bias in attention layers.
|
| 67 |
+
attention_dropout (`float`, *optional*, defaults to 0.0):
|
| 68 |
+
The dropout ratio for the attention probabilities.
|
| 69 |
+
sliding_window (`int`, *optional*):
|
| 70 |
+
Sliding window attention window size.
|
| 71 |
+
intermediate_size (`int`, *optional*, defaults to 21504):
|
| 72 |
+
Dimension of the MLP representations.
|
| 73 |
+
mlp_hidden_act (`str`, *optional*, defaults to `"relu2"`):
|
| 74 |
+
The non-linear activation function in the MLP layers.
|
| 75 |
+
mlp_bias (`bool`, *optional*, defaults to `False`):
|
| 76 |
+
Whether to use bias in MLP layers.
|
| 77 |
+
use_mamba_kernels (`bool`, *optional*, defaults to `True`):
|
| 78 |
+
Flag indicating whether or not to use the fast mamba kernels.
|
| 79 |
+
ssm_state_size (`int`, *optional*, defaults to 128):
|
| 80 |
+
The dimension of the mamba state space latents.
|
| 81 |
+
mamba_num_heads (`int`, *optional*, defaults to 128):
|
| 82 |
+
Number of heads in Mamba layers.
|
| 83 |
+
mamba_n_groups (`int`, *optional*, defaults to 8):
|
| 84 |
+
Number of groups in Mamba layers.
|
| 85 |
+
mamba_head_dim (`int`, *optional*, defaults to 64):
|
| 86 |
+
Dimension of each Mamba head.
|
| 87 |
+
mamba_d_conv (`int`, *optional*, defaults to 4):
|
| 88 |
+
The size of the mamba convolution kernel.
|
| 89 |
+
mamba_expand (`int`, *optional*, defaults to 2):
|
| 90 |
+
Expanding factor used to determine the mamba intermediate size.
|
| 91 |
+
mamba_hidden_act (`str`, *optional*, defaults to `"silu"`):
|
| 92 |
+
The non-linear activation function in the Mamba layers.
|
| 93 |
+
mamba_dt_min (`float`, *optional*, defaults to 0.001):
|
| 94 |
+
Minimum value for the time step in Mamba.
|
| 95 |
+
mamba_dt_max (`float`, *optional*, defaults to 0.1):
|
| 96 |
+
Maximum value for the time step in Mamba.
|
| 97 |
+
mamba_dt_limit (`tuple`, *optional*, defaults to `(0.0, inf)`):
|
| 98 |
+
Limits for the time step in Mamba.
|
| 99 |
+
mamba_dt_init_floor (`float`, *optional*, defaults to 0.0001):
|
| 100 |
+
Floor value for time step initialization in Mamba.
|
| 101 |
+
mamba_conv_bias (`bool`, *optional*, defaults to `True`):
|
| 102 |
+
Whether to use bias in the convolution layer of the mamba mixer block.
|
| 103 |
+
mamba_proj_bias (`bool`, *optional*, defaults to `False`):
|
| 104 |
+
Whether to use bias in the input and output projections of the mamba mixer block.
|
| 105 |
+
mamba_chunk_size (`int`, *optional*, defaults to 128):
|
| 106 |
+
Size of chunks for Mamba processing.
|
| 107 |
+
mamba_ssm_cache_dtype (`str`, *optional*, defaults to `"float32"`):
|
| 108 |
+
Data type for Mamba SSM cache states.
|
| 109 |
+
n_routed_experts (`int`, *optional*, defaults to 8):
|
| 110 |
+
Number of routed experts in MoE layers.
|
| 111 |
+
n_shared_experts (`int`, *optional*, defaults to 1):
|
| 112 |
+
Number of shared experts that are always activated in MoE layers.
|
| 113 |
+
moe_intermediate_size (`int`, *optional*, defaults to 7688):
|
| 114 |
+
Dimension of the MLP representations in routed experts.
|
| 115 |
+
moe_shared_expert_intermediate_size (`int`, *optional*, defaults to 7688):
|
| 116 |
+
Dimension of the MLP representations in shared experts.
|
| 117 |
+
moe_latent_size (`int`, *optional*):
|
| 118 |
+
Latent size for MoE expert projections. If `None`, uses `hidden_size`.
|
| 119 |
+
moe_shared_expert_overlap (`bool`, *optional*, defaults to `True`):
|
| 120 |
+
Whether shared experts overlap with routed experts.
|
| 121 |
+
num_experts_per_tok (`int`, *optional*, defaults to 2):
|
| 122 |
+
The number of experts to route per token (top-k routing parameter).
|
| 123 |
+
routed_scaling_factor (`float`, *optional*, defaults to 1.0):
|
| 124 |
+
Scaling factor applied to routed expert outputs.
|
| 125 |
+
n_group (`int`, *optional*, defaults to 1):
|
| 126 |
+
Number of groups for expert routing.
|
| 127 |
+
topk_group (`int`, *optional*, defaults to 1):
|
| 128 |
+
Top-k group parameter for expert selection.
|
| 129 |
+
norm_topk_prob (`bool`, *optional*, defaults to `True`):
|
| 130 |
+
Whether to normalize top-k probabilities in expert routing.
|
| 131 |
+
num_nextn_predict_layers (`int`, *optional*, defaults to 0):
|
| 132 |
+
Number of additional layers for multi-token prediction. If 0, multi-token prediction is disabled.
|
| 133 |
+
mtp_layers_block_type (`list`, *optional*, defaults to `['attention', 'moe']`):
|
| 134 |
+
Explicit list of layer types for multi-token prediction layers when `num_nextn_predict_layers` > 0.
|
| 135 |
+
use_bias (`bool`, *optional*, defaults to `False`):
|
| 136 |
+
Whether to use bias in the model.
|
| 137 |
+
initializer_range (`float`, *optional*, defaults to 0.02):
|
| 138 |
+
The standard deviation of the truncated_normal_initializer for initializing all weight matrices.
|
| 139 |
+
layer_norm_epsilon (`float`, *optional*, defaults to 1e-05):
|
| 140 |
+
The epsilon used by the layer normalization layers.
|
| 141 |
+
residual_in_fp32 (`bool`, *optional*, defaults to `False`):
|
| 142 |
+
Whether or not residuals should be in `float32`.
|
| 143 |
+
hidden_dropout (`float`, *optional*, defaults to 0.0):
|
| 144 |
+
The dropout ratio for the hidden states.
|
| 145 |
+
rescale_prenorm_residual (`bool`, *optional*, defaults to `True`):
|
| 146 |
+
Whether to rescale the pre-normalization residual connections.
|
| 147 |
+
|
| 148 |
+
```python
|
| 149 |
+
>>> from transformers import NemotronHModel, NemotronHConfig
|
| 150 |
+
|
| 151 |
+
>>> # Initializing a NemotronH configuration
|
| 152 |
+
>>> configuration = NemotronHConfig()
|
| 153 |
+
|
| 154 |
+
>>> # Initializing a model (with random weights) from the configuration
|
| 155 |
+
>>> model = NemotronHModel(configuration)
|
| 156 |
+
|
| 157 |
+
>>> # Accessing the model configuration
|
| 158 |
+
>>> configuration = model.config
|
| 159 |
+
```"""
|
| 160 |
+
|
| 161 |
+
model_type = "nemotron_h"
|
| 162 |
+
keys_to_ignore_at_inference = ["past_key_values"]
|
| 163 |
+
|
| 164 |
+
@staticmethod
|
| 165 |
+
def _validate_layers_block_type(layers_block_type, expected_length=None, param_name="layers_block_type"):
|
| 166 |
+
"""
|
| 167 |
+
Validate layers_block_type list.
|
| 168 |
+
|
| 169 |
+
Args:
|
| 170 |
+
layers_block_type: List of layer types to validate
|
| 171 |
+
expected_length: If provided, validate the list has this length
|
| 172 |
+
param_name: Parameter name for error messages
|
| 173 |
+
|
| 174 |
+
Raises:
|
| 175 |
+
ValueError: If validation fails
|
| 176 |
+
"""
|
| 177 |
+
if not isinstance(layers_block_type, list):
|
| 178 |
+
raise ValueError(f"{param_name} must be a list of strings. Got type: {type(layers_block_type)}")
|
| 179 |
+
|
| 180 |
+
if expected_length is not None and len(layers_block_type) != expected_length:
|
| 181 |
+
raise ValueError(f"{param_name} must have length {expected_length}. Got length {len(layers_block_type)}.")
|
| 182 |
+
|
| 183 |
+
valid_types = {"mamba", "attention", "moe"}
|
| 184 |
+
if not all(block_type in valid_types for block_type in layers_block_type):
|
| 185 |
+
invalid = set(layers_block_type) - valid_types
|
| 186 |
+
raise ValueError(f"{param_name} contains invalid types: {invalid}. Must be one of: {valid_types}")
|
| 187 |
+
|
| 188 |
+
def __init__(
|
| 189 |
+
self,
|
| 190 |
+
# General model config
|
| 191 |
+
vocab_size=131072,
|
| 192 |
+
hidden_size=4096,
|
| 193 |
+
layers_block_type=None,
|
| 194 |
+
num_hidden_layers=None, # Deprecated, only for backward compatibility
|
| 195 |
+
tie_word_embeddings=False,
|
| 196 |
+
use_cache=True,
|
| 197 |
+
num_logits_to_keep=1,
|
| 198 |
+
# Token IDs
|
| 199 |
+
pad_token_id=0,
|
| 200 |
+
bos_token_id=1,
|
| 201 |
+
eos_token_id=2,
|
| 202 |
+
# Attention layer config
|
| 203 |
+
num_attention_heads=32,
|
| 204 |
+
num_key_value_heads=8,
|
| 205 |
+
head_dim=128,
|
| 206 |
+
max_position_embeddings=4096,
|
| 207 |
+
attention_bias=False,
|
| 208 |
+
attention_dropout=0.0,
|
| 209 |
+
sliding_window=None,
|
| 210 |
+
# MLP layer config
|
| 211 |
+
intermediate_size=21504,
|
| 212 |
+
mlp_hidden_act="relu2",
|
| 213 |
+
mlp_bias=False,
|
| 214 |
+
# Mamba layer config
|
| 215 |
+
use_mamba_kernels=True,
|
| 216 |
+
ssm_state_size=128,
|
| 217 |
+
mamba_num_heads=128,
|
| 218 |
+
mamba_n_groups=8,
|
| 219 |
+
mamba_head_dim=64,
|
| 220 |
+
mamba_d_conv=4,
|
| 221 |
+
mamba_expand=2,
|
| 222 |
+
mamba_hidden_act="silu",
|
| 223 |
+
mamba_dt_min=0.001,
|
| 224 |
+
mamba_dt_max=0.1,
|
| 225 |
+
mamba_dt_limit=(0.0, float("inf")),
|
| 226 |
+
mamba_dt_init_floor=1e-4,
|
| 227 |
+
mamba_conv_bias=True,
|
| 228 |
+
mamba_proj_bias=False,
|
| 229 |
+
mamba_chunk_size=128,
|
| 230 |
+
mamba_ssm_cache_dtype="float32",
|
| 231 |
+
# MoE config
|
| 232 |
+
n_routed_experts=8,
|
| 233 |
+
n_shared_experts=1,
|
| 234 |
+
moe_intermediate_size=7688,
|
| 235 |
+
moe_shared_expert_intermediate_size=7688,
|
| 236 |
+
moe_latent_size=None,
|
| 237 |
+
moe_shared_expert_overlap=True,
|
| 238 |
+
num_experts_per_tok=2,
|
| 239 |
+
routed_scaling_factor=1.0,
|
| 240 |
+
n_group=1,
|
| 241 |
+
topk_group=1,
|
| 242 |
+
norm_topk_prob=True,
|
| 243 |
+
# Multi-token prediction config
|
| 244 |
+
num_nextn_predict_layers=0,
|
| 245 |
+
mtp_layers_block_type=["attention", "moe"],
|
| 246 |
+
# General training config
|
| 247 |
+
use_bias=False,
|
| 248 |
+
initializer_range=0.02,
|
| 249 |
+
layer_norm_epsilon=1e-5,
|
| 250 |
+
residual_in_fp32=False,
|
| 251 |
+
hidden_dropout=0.0,
|
| 252 |
+
rescale_prenorm_residual=True,
|
| 253 |
+
**kwargs,
|
| 254 |
+
):
|
| 255 |
+
# Backward compatibility: convert hybrid_override_pattern to layers_block_type
|
| 256 |
+
# Always pop hybrid_override_pattern from kwargs to prevent it from being set as an attribute
|
| 257 |
+
if "hybrid_override_pattern" in kwargs:
|
| 258 |
+
pattern = kwargs.pop("hybrid_override_pattern")
|
| 259 |
+
if layers_block_type is None:
|
| 260 |
+
layers_block_type = self._pattern_to_list(pattern)
|
| 261 |
+
elif layers_block_type is None:
|
| 262 |
+
# Default layers_block_type if not provided
|
| 263 |
+
layers_block_type = ["mamba", "moe", "attention", "moe"]
|
| 264 |
+
|
| 265 |
+
# Note: num_hidden_layers is deprecated and ignored if layers_block_type is explicitly provided
|
| 266 |
+
# It's only kept for backward compatibility when loading old configs
|
| 267 |
+
if num_hidden_layers is not None:
|
| 268 |
+
# Warn if num_hidden_layers is provided but doesn't match layers_block_type
|
| 269 |
+
if len(layers_block_type) != num_hidden_layers:
|
| 270 |
+
logger.warning(
|
| 271 |
+
f"num_hidden_layers ({num_hidden_layers}) is deprecated and doesn't match "
|
| 272 |
+
f"layers_block_type length ({len(layers_block_type)}). Using layers_block_type length."
|
| 273 |
+
)
|
| 274 |
+
|
| 275 |
+
# Backward compatibility: convert mtp_hybrid_override_pattern to mtp_layers_block_type
|
| 276 |
+
# Always pop mtp_hybrid_override_pattern from kwargs to prevent it from being set as an attribute
|
| 277 |
+
if "mtp_hybrid_override_pattern" in kwargs:
|
| 278 |
+
pattern = kwargs.pop("mtp_hybrid_override_pattern")
|
| 279 |
+
if mtp_layers_block_type is None or mtp_layers_block_type == ["attention", "moe"]:
|
| 280 |
+
mtp_layers_block_type = self._pattern_to_list(pattern)
|
| 281 |
+
|
| 282 |
+
self.vocab_size = vocab_size
|
| 283 |
+
self.tie_word_embeddings = tie_word_embeddings
|
| 284 |
+
self.hidden_size = hidden_size
|
| 285 |
+
self.intermediate_size = intermediate_size
|
| 286 |
+
self.num_attention_heads = num_attention_heads
|
| 287 |
+
self.head_dim = head_dim
|
| 288 |
+
self.sliding_window = sliding_window
|
| 289 |
+
self.max_position_embeddings = max_position_embeddings
|
| 290 |
+
self.attention_dropout = attention_dropout
|
| 291 |
+
self.hidden_dropout = hidden_dropout
|
| 292 |
+
|
| 293 |
+
# Validate layers_block_type (no longer checking length against num_hidden_layers)
|
| 294 |
+
self._validate_layers_block_type(layers_block_type, expected_length=None, param_name="layers_block_type")
|
| 295 |
+
self.layers_block_type = layers_block_type
|
| 296 |
+
|
| 297 |
+
# for backward compatibility
|
| 298 |
+
if num_key_value_heads is None:
|
| 299 |
+
num_key_value_heads = num_attention_heads
|
| 300 |
+
|
| 301 |
+
self.num_key_value_heads = num_key_value_heads
|
| 302 |
+
self.mlp_hidden_act = mlp_hidden_act
|
| 303 |
+
self.attention_bias = attention_bias
|
| 304 |
+
self.mlp_bias = mlp_bias
|
| 305 |
+
self.use_bias = use_bias
|
| 306 |
+
self.initializer_range = initializer_range
|
| 307 |
+
self.layer_norm_epsilon = layer_norm_epsilon
|
| 308 |
+
self.residual_in_fp32 = residual_in_fp32
|
| 309 |
+
|
| 310 |
+
self.use_cache = use_cache
|
| 311 |
+
self.num_logits_to_keep = num_logits_to_keep
|
| 312 |
+
|
| 313 |
+
self.use_mamba_kernels = use_mamba_kernels
|
| 314 |
+
self.n_groups = mamba_n_groups
|
| 315 |
+
self.mamba_head_dim = mamba_head_dim
|
| 316 |
+
self.ssm_state_size = ssm_state_size
|
| 317 |
+
self.mamba_num_heads = mamba_num_heads
|
| 318 |
+
self.conv_kernel = mamba_d_conv
|
| 319 |
+
self.expand = mamba_expand
|
| 320 |
+
self.mamba_hidden_act = mamba_hidden_act
|
| 321 |
+
self.time_step_min = mamba_dt_min
|
| 322 |
+
self.time_step_max = mamba_dt_max
|
| 323 |
+
self.time_step_limit = mamba_dt_limit
|
| 324 |
+
self.time_step_floor = mamba_dt_init_floor
|
| 325 |
+
self.use_conv_bias = mamba_conv_bias
|
| 326 |
+
self.mamba_proj_bias = mamba_proj_bias
|
| 327 |
+
self.chunk_size = mamba_chunk_size
|
| 328 |
+
self.rescale_prenorm_residual = rescale_prenorm_residual
|
| 329 |
+
self.n_routed_experts = n_routed_experts
|
| 330 |
+
self.n_shared_experts = n_shared_experts
|
| 331 |
+
self.moe_intermediate_size = moe_intermediate_size
|
| 332 |
+
self.moe_shared_expert_intermediate_size = moe_shared_expert_intermediate_size
|
| 333 |
+
self.moe_latent_size = moe_latent_size
|
| 334 |
+
self.moe_shared_expert_overlap = moe_shared_expert_overlap
|
| 335 |
+
self.num_experts_per_tok = num_experts_per_tok
|
| 336 |
+
self.routed_scaling_factor = routed_scaling_factor
|
| 337 |
+
self.n_group = n_group
|
| 338 |
+
self.topk_group = topk_group
|
| 339 |
+
self.norm_topk_prob = norm_topk_prob
|
| 340 |
+
self.mamba_ssm_cache_dtype = mamba_ssm_cache_dtype
|
| 341 |
+
|
| 342 |
+
# MTP config
|
| 343 |
+
self.num_nextn_predict_layers = num_nextn_predict_layers
|
| 344 |
+
|
| 345 |
+
# Validate mtp_layers_block_type is provided when MTP is enabled
|
| 346 |
+
if self.num_nextn_predict_layers > 0:
|
| 347 |
+
if mtp_layers_block_type is None:
|
| 348 |
+
raise ValueError(
|
| 349 |
+
"mtp_layers_block_type is required when num_nextn_predict_layers > 0. "
|
| 350 |
+
"Please provide an explicit list of layer types for MTP layers. "
|
| 351 |
+
"Example: mtp_layers_block_type=['attention', 'moe']"
|
| 352 |
+
)
|
| 353 |
+
self._validate_layers_block_type(mtp_layers_block_type, None, "mtp_layers_block_type")
|
| 354 |
+
self.mtp_layers_block_type = mtp_layers_block_type
|
| 355 |
+
|
| 356 |
+
super().__init__(
|
| 357 |
+
pad_token_id=pad_token_id,
|
| 358 |
+
bos_token_id=bos_token_id,
|
| 359 |
+
eos_token_id=eos_token_id,
|
| 360 |
+
tie_word_embeddings=tie_word_embeddings,
|
| 361 |
+
**kwargs,
|
| 362 |
+
)
|
| 363 |
+
|
| 364 |
+
@property
|
| 365 |
+
def num_hidden_layers(self) -> int:
|
| 366 |
+
"""
|
| 367 |
+
Number of hidden layers derived from the length of layers_block_type.
|
| 368 |
+
This property replaces the deprecated num_hidden_layers parameter.
|
| 369 |
+
"""
|
| 370 |
+
return len(self.layers_block_type)
|
| 371 |
+
|
| 372 |
+
@num_hidden_layers.setter
|
| 373 |
+
def num_hidden_layers(self, value):
|
| 374 |
+
"""
|
| 375 |
+
Setter for backward compatibility when loading configs.
|
| 376 |
+
The value is ignored since num_hidden_layers is computed from layers_block_type.
|
| 377 |
+
"""
|
| 378 |
+
# Ignore the value - num_hidden_layers is always derived from layers_block_type
|
| 379 |
+
pass
|
| 380 |
+
|
| 381 |
+
@property
|
| 382 |
+
def hybrid_override_pattern(self) -> str:
|
| 383 |
+
"""
|
| 384 |
+
Backward compatibility property.
|
| 385 |
+
Returns the pattern string representation of layers_block_type.
|
| 386 |
+
"""
|
| 387 |
+
return self._list_to_pattern(self.layers_block_type)
|
| 388 |
+
|
| 389 |
+
@property
|
| 390 |
+
def mtp_hybrid_override_pattern(self) -> str:
|
| 391 |
+
"""
|
| 392 |
+
Backward compatibility property.
|
| 393 |
+
Returns the pattern string representation of mtp_layers_block_type.
|
| 394 |
+
"""
|
| 395 |
+
return self._list_to_pattern(self.mtp_layers_block_type)
|
| 396 |
+
|
| 397 |
+
@staticmethod
|
| 398 |
+
def _list_to_pattern(layers_list: list) -> str:
|
| 399 |
+
"""Convert list of layer types back to pattern string (for backward compatibility)."""
|
| 400 |
+
reverse_mapping = {"mamba": "M", "moe": "E", "attention": "*"}
|
| 401 |
+
return "".join(reverse_mapping[layer_type] for layer_type in layers_list)
|
| 402 |
+
|
| 403 |
+
@staticmethod
|
| 404 |
+
def _pattern_to_list(pattern: str) -> list:
|
| 405 |
+
"""Convert pattern string to list of layer types (for backward compatibility)."""
|
| 406 |
+
pattern_mapping = {"M": "mamba", "E": "moe", "*": "attention"}
|
| 407 |
+
return [pattern_mapping[char] for char in pattern]
|
| 408 |
+
|
| 409 |
+
|
| 410 |
+
__all__ = ["NemotronHConfig"]
|
configuration_nemotron_h_omni.py
ADDED
|
@@ -0,0 +1,166 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright (c) 2025, NVIDIA CORPORATION. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
from huggingface_hub.dataclasses import strict
|
| 15 |
+
from transformers.configuration_utils import PreTrainedConfig
|
| 16 |
+
from transformers.models.nemotron_h import NemotronHConfig
|
| 17 |
+
from transformers.models.parakeet.configuration_parakeet import ParakeetEncoderConfig
|
| 18 |
+
from transformers.utils import auto_docstring, logging
|
| 19 |
+
|
| 20 |
+
from .configuration_radio import RadioConfig
|
| 21 |
+
from .configuration_nemotron_h_puzzle import NemotronHPuzzleConfig
|
| 22 |
+
|
| 23 |
+
# Imported by name even though NemotronHPuzzleConfig re-exports what we need:
|
| 24 |
+
# for a local checkpoint directory Transformers stages only the direct relative
|
| 25 |
+
# imports of this one file into HF_MODULES_CACHE, while the loader then walks
|
| 26 |
+
# imports recursively. Without this line the nested
|
| 27 |
+
# configuration_nemotron_h_puzzle -> configuration_nemotron_h import is never
|
| 28 |
+
# copied and AutoConfig.from_pretrained fails with FileNotFoundError.
|
| 29 |
+
from .configuration_nemotron_h import NemotronHConfig as _NemotronHConfig # noqa: F401
|
| 30 |
+
|
| 31 |
+
|
| 32 |
+
__all__ = ["NemotronH_Omni_Reasoning_V3_Config"]
|
| 33 |
+
|
| 34 |
+
logger = logging.get_logger(__name__)
|
| 35 |
+
|
| 36 |
+
|
| 37 |
+
def _nemotron_h_compatible_config(config: dict) -> dict:
|
| 38 |
+
"""Translate current Nemotron-H layer names for Transformers versions using legacy names."""
|
| 39 |
+
config = dict(config)
|
| 40 |
+
legacy_names = {"linear_attention": "mamba", "full_attention": "attention"}
|
| 41 |
+
for field in ("layers_block_type", "mtp_layers_block_type"):
|
| 42 |
+
if field in config and config[field] is not None:
|
| 43 |
+
config[field] = [legacy_names.get(layer_type, layer_type) for layer_type in config[field]]
|
| 44 |
+
return config
|
| 45 |
+
|
| 46 |
+
|
| 47 |
+
@auto_docstring(checkpoint="nvidia/Nemotron-3-Nano-Omni-30B-A3B-Reasoning-BF16")
|
| 48 |
+
@strict
|
| 49 |
+
class NemotronH_Omni_Reasoning_V3_Config(PreTrainedConfig):
|
| 50 |
+
r"""
|
| 51 |
+
vision_config (`dict` or `RadioConfig`, *optional*):
|
| 52 |
+
Configuration for the RADIO vision encoder. Defaults to a default [`RadioConfig`].
|
| 53 |
+
llm_config (`dict` or `NemotronHConfig`, *optional*):
|
| 54 |
+
Configuration for the NemotronH language model. Defaults to a default [`NemotronHConfig`].
|
| 55 |
+
sound_config (`dict` or `ParakeetEncoderConfig`, *optional*):
|
| 56 |
+
Configuration for the optional Parakeet sound encoder. `None` disables the audio branch.
|
| 57 |
+
force_image_size (`int`, *optional*):
|
| 58 |
+
Fixed input image resolution (in pixels) the vision tower expects.
|
| 59 |
+
downsample_ratio (`float`, *optional*, defaults to 0.5):
|
| 60 |
+
Pixel-shuffle spatial downsample ratio applied to the vision features.
|
| 61 |
+
template (`str`, *optional*):
|
| 62 |
+
Conversation template name (legacy; the chat template is carried by the processor).
|
| 63 |
+
ps_version (`str`, *optional*, defaults to `"v1"`):
|
| 64 |
+
Pixel-shuffle implementation version (`"v2"` swaps height/width back; `"v1"` is the legacy
|
| 65 |
+
transposed variant).
|
| 66 |
+
image_tag_type (`str`, *optional*, defaults to `"internvl"`):
|
| 67 |
+
Image-tag convention used when expanding image placeholders.
|
| 68 |
+
projector_hidden_size (`int`, *optional*, defaults to 4096):
|
| 69 |
+
Hidden size of the vision-to-LLM MLP projector.
|
| 70 |
+
vit_hidden_size (`int`, *optional*, defaults to 1280):
|
| 71 |
+
Hidden size of the RADIO vision features.
|
| 72 |
+
video_pruning_rate (`float`, *optional*, defaults to 0.0):
|
| 73 |
+
Efficient-Video-Sampling token pruning rate; `0.0` disables pruning.
|
| 74 |
+
video_temporal_patch_size (`int`, *optional*, defaults to 2):
|
| 75 |
+
Number of frames collapsed into a single temporal patch by the video embedder.
|
| 76 |
+
patch_size (`int`, *optional*, defaults to 16):
|
| 77 |
+
Vision patch size in pixels.
|
| 78 |
+
img_context_token_id (`int`, *optional*):
|
| 79 |
+
Token id used as the image-context placeholder in `input_ids`.
|
| 80 |
+
img_context_token (`str`, *optional*, defaults to `"<image>"`):
|
| 81 |
+
Textual image-context placeholder token.
|
| 82 |
+
video_context_token_id (`int`, *optional*):
|
| 83 |
+
Token id used as the video-context placeholder in `input_ids`.
|
| 84 |
+
video_context_token (`str`, *optional*, defaults to `"<video>"`):
|
| 85 |
+
Textual video-context placeholder token.
|
| 86 |
+
sound_context_token_id (`int`, *optional*):
|
| 87 |
+
Token id used as the audio-context placeholder in `input_ids`.
|
| 88 |
+
sound_context_token (`str`, *optional*, defaults to `"<audio>"`):
|
| 89 |
+
Textual audio-context placeholder token.
|
| 90 |
+
"""
|
| 91 |
+
|
| 92 |
+
model_type = "nemotron_h_omni"
|
| 93 |
+
is_composition = True
|
| 94 |
+
|
| 95 |
+
vision_config: dict | RadioConfig | None = None
|
| 96 |
+
# NemotronHPuzzleConfig is listed explicitly because it derives from this
|
| 97 |
+
# checkpoint's local NemotronHConfig, which is an independent PretrainedConfig
|
| 98 |
+
# subclass rather than the `transformers` one named above; the @strict union
|
| 99 |
+
# check compares concrete classes and would otherwise reject it.
|
| 100 |
+
llm_config: dict | NemotronHConfig | NemotronHPuzzleConfig | None = None
|
| 101 |
+
sound_config: dict | ParakeetEncoderConfig | None = None
|
| 102 |
+
force_image_size: int | None = None
|
| 103 |
+
downsample_ratio: float = 0.5
|
| 104 |
+
template: str | None = None # TODO move out of here and into the tokenizer
|
| 105 |
+
ps_version: str = "v1" # Pixel shuffle version
|
| 106 |
+
image_tag_type: str = "internvl" # TODO: into the tokenizer too?
|
| 107 |
+
projector_hidden_size: int = 4096
|
| 108 |
+
vit_hidden_size: int = 1280
|
| 109 |
+
# Whether the vision tower output is layer-normalized before the projector.
|
| 110 |
+
# This is a property of how the vision side was trained, not of the current
|
| 111 |
+
# language model, so it is stored explicitly. Left unset it falls back to
|
| 112 |
+
# the original behaviour of inferring it from the language model's MTP.
|
| 113 |
+
vision_final_layernorm: bool | None = None
|
| 114 |
+
video_pruning_rate: float = 0.0
|
| 115 |
+
video_temporal_patch_size: int = 2
|
| 116 |
+
# Vision token settings
|
| 117 |
+
patch_size: int = 16
|
| 118 |
+
img_context_token_id: int | None = None
|
| 119 |
+
img_context_token: str = "<image>"
|
| 120 |
+
video_context_token_id: int | None = None
|
| 121 |
+
video_context_token: str = "<video>"
|
| 122 |
+
# Sound/audio token settings
|
| 123 |
+
sound_context_token_id: int | None = None
|
| 124 |
+
sound_context_token: str = "<audio>"
|
| 125 |
+
|
| 126 |
+
def __post_init__(self, **kwargs):
|
| 127 |
+
if isinstance(self.vision_config, dict):
|
| 128 |
+
self.vision_config = RadioConfig(**self.vision_config)
|
| 129 |
+
elif self.vision_config is None:
|
| 130 |
+
self.vision_config = RadioConfig()
|
| 131 |
+
# The vision tower needs the temporal patch size to build its video patch projection.
|
| 132 |
+
self.vision_config.video_temporal_patch_size = self.video_temporal_patch_size
|
| 133 |
+
|
| 134 |
+
# Handle both cases: when loading from JSON (llm_config is dict) and when called
|
| 135 |
+
# internally by transformers (llm_config is None).
|
| 136 |
+
if isinstance(self.llm_config, dict):
|
| 137 |
+
# A "puzzle" language model gives every layer its own expert count
|
| 138 |
+
# and FFN width, which a uniform NemotronHConfig cannot represent;
|
| 139 |
+
# it has to be built by its own config class or the per-layer sizes
|
| 140 |
+
# are lost and most layers are constructed at the wrong shape.
|
| 141 |
+
if self.llm_config.get("model_type") == "nemotron_h_puzzle":
|
| 142 |
+
self.llm_config = NemotronHPuzzleConfig(**self.llm_config)
|
| 143 |
+
else:
|
| 144 |
+
self.llm_config = NemotronHConfig(**_nemotron_h_compatible_config(self.llm_config))
|
| 145 |
+
elif self.llm_config is None:
|
| 146 |
+
self.llm_config = NemotronHConfig()
|
| 147 |
+
|
| 148 |
+
# This checkpoint's sound_config omits `attention_bias`/`scale_input`, which are `False` for
|
| 149 |
+
# its Parakeet variant, so supply them before building the encoder config.
|
| 150 |
+
if isinstance(self.sound_config, dict):
|
| 151 |
+
sound_config = {"attention_bias": False, "scale_input": False, **self.sound_config}
|
| 152 |
+
sound_config.pop("model_type", None)
|
| 153 |
+
self.sound_config = ParakeetEncoderConfig(**sound_config)
|
| 154 |
+
|
| 155 |
+
super().__post_init__(**kwargs)
|
| 156 |
+
|
| 157 |
+
# `attn_implementation` flows in through `**kwargs` (the base `PreTrainedConfig` stores it as
|
| 158 |
+
# `self._attn_implementation`, as for every other model); propagate it to the language model.
|
| 159 |
+
self.llm_config._attn_implementation = self._attn_implementation
|
| 160 |
+
|
| 161 |
+
# vLLM's `NemotronH_Nano_VL_V2` implementation reads the language-model sub-config as
|
| 162 |
+
# `config.text_config`. Our HF config stores it as `config.llm_config`; expose an alias so the
|
| 163 |
+
# same config object loads under both loaders without having to duplicate the dict on disk.
|
| 164 |
+
@property
|
| 165 |
+
def text_config(self):
|
| 166 |
+
return self.llm_config
|
configuration_nemotron_h_puzzle.py
ADDED
|
@@ -0,0 +1,151 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# SPDX-FileCopyrightText: Copyright (c) 2026 NVIDIA CORPORATION & AFFILIATES. All rights reserved.
|
| 2 |
+
# SPDX-License-Identifier: OpenMDW-1.1
|
| 3 |
+
|
| 4 |
+
from typing import Any
|
| 5 |
+
|
| 6 |
+
import dataclasses
|
| 7 |
+
from dataclasses import dataclass
|
| 8 |
+
|
| 9 |
+
from .configuration_nemotron_h import NemotronHConfig
|
| 10 |
+
|
| 11 |
+
|
| 12 |
+
@dataclass
|
| 13 |
+
class MoeConfig:
|
| 14 |
+
moe_intermediate_size: int | None = None
|
| 15 |
+
num_experts_per_tok: int | None = None
|
| 16 |
+
n_routed_experts: int | None = None
|
| 17 |
+
block_type: str = "moe"
|
| 18 |
+
|
| 19 |
+
|
| 20 |
+
@dataclass
|
| 21 |
+
class AttentionConfig:
|
| 22 |
+
block_type: str = "attention"
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
@dataclass
|
| 26 |
+
class MambaConfig:
|
| 27 |
+
block_type: str = "mamba"
|
| 28 |
+
|
| 29 |
+
|
| 30 |
+
BLOCK_TYPE_TO_CONFIG_CLASS = {config_class.block_type: config_class
|
| 31 |
+
for config_class in (AttentionConfig, MoeConfig, MambaConfig)}
|
| 32 |
+
|
| 33 |
+
|
| 34 |
+
class NemotronHPuzzleConfig(NemotronHConfig):
|
| 35 |
+
model_type = "nemotron_h_puzzle"
|
| 36 |
+
|
| 37 |
+
def __init__(self, **kwargs):
|
| 38 |
+
self.block_configs = []
|
| 39 |
+
if "block_configs" in kwargs:
|
| 40 |
+
self.block_configs, layers_block_type = build_block_configs(kwargs.pop("block_configs"))
|
| 41 |
+
kwargs["layers_block_type"] = layers_block_type
|
| 42 |
+
|
| 43 |
+
self.mtp_block_configs = []
|
| 44 |
+
if "mtp_block_configs" in kwargs:
|
| 45 |
+
self.mtp_block_configs, mtp_layers_block_type = build_block_configs(kwargs.pop("mtp_block_configs"))
|
| 46 |
+
kwargs["num_nextn_predict_layers"] = len(self.mtp_block_configs) // 2
|
| 47 |
+
if mtp_layers_block_type:
|
| 48 |
+
kwargs["mtp_layers_block_type"] = mtp_layers_block_type
|
| 49 |
+
assert mtp_layers_block_type == ["attention", "moe"], \
|
| 50 |
+
"The MTP module must either not exist or be ['attention', 'moe'] to be supported by vLLM."
|
| 51 |
+
|
| 52 |
+
super().__init__(**kwargs)
|
| 53 |
+
|
| 54 |
+
self._validate_block_field_consistency()
|
| 55 |
+
self._delete_blockwise_members_from_global_config()
|
| 56 |
+
|
| 57 |
+
def to_dict(self) -> dict[str, Any]:
|
| 58 |
+
"""
|
| 59 |
+
Remove None values from block_configs and mtp_block_configs.
|
| 60 |
+
"""
|
| 61 |
+
output = super().to_dict()
|
| 62 |
+
output["block_configs"] = [{k: v for k, v in dataclasses.asdict(block_config).items() if v is not None}
|
| 63 |
+
for block_config in self.block_configs]
|
| 64 |
+
output["mtp_block_configs"] = [{k: v for k, v in dataclasses.asdict(block_config).items() if v is not None}
|
| 65 |
+
for block_config in self.mtp_block_configs]
|
| 66 |
+
return output
|
| 67 |
+
|
| 68 |
+
def get_nemotron_h_config_for_layer(self, layer_idx: int) -> NemotronHConfig:
|
| 69 |
+
"""
|
| 70 |
+
Builds a vanilla NemotronHConfig that matches the block configuration for a specific layer.
|
| 71 |
+
MTP layers are considered to be in location self.num_hidden_layers + mtp_layer_idx.
|
| 72 |
+
"""
|
| 73 |
+
config_dict = self.to_dict()
|
| 74 |
+
|
| 75 |
+
if layer_idx < self.num_hidden_layers:
|
| 76 |
+
block_configs = config_dict["block_configs"]
|
| 77 |
+
else:
|
| 78 |
+
assert layer_idx < self.num_hidden_layers + len(self.mtp_block_configs), \
|
| 79 |
+
f"layer_idx={layer_idx} is out of bounds for " \
|
| 80 |
+
f"{self.num_hidden_layers=} + {len(self.mtp_block_configs)=}"
|
| 81 |
+
layer_idx -= self.num_hidden_layers
|
| 82 |
+
block_configs = config_dict["mtp_block_configs"]
|
| 83 |
+
|
| 84 |
+
block_config = block_configs[layer_idx]
|
| 85 |
+
|
| 86 |
+
config_dict.update(block_config)
|
| 87 |
+
del config_dict["block_configs"]
|
| 88 |
+
del config_dict["mtp_block_configs"]
|
| 89 |
+
|
| 90 |
+
nemotron_h_config = NemotronHConfig.from_dict(config_dict)
|
| 91 |
+
nemotron_h_config._attn_implementation = self._attn_implementation
|
| 92 |
+
|
| 93 |
+
return nemotron_h_config
|
| 94 |
+
|
| 95 |
+
@property
|
| 96 |
+
def mtp_n_routed_experts(self) -> int:
|
| 97 |
+
n_routed_experts = self.n_routed_experts
|
| 98 |
+
assert isinstance(n_routed_experts, int)
|
| 99 |
+
return n_routed_experts
|
| 100 |
+
|
| 101 |
+
def _validate_block_field_consistency(self):
|
| 102 |
+
"""Validate that no block field is set on only some of the blocks that define it.
|
| 103 |
+
|
| 104 |
+
A block field is either global for every block (left unset / None) or explicitly set for
|
| 105 |
+
every block that defines it - mixing the two (some blocks set it, others fall back to the
|
| 106 |
+
global value) is not supported.
|
| 107 |
+
"""
|
| 108 |
+
field_is_set: dict[str, set[bool]] = {}
|
| 109 |
+
for block_config in self.block_configs + self.mtp_block_configs:
|
| 110 |
+
for field in dataclasses.fields(block_config):
|
| 111 |
+
if field.name == "block_type":
|
| 112 |
+
continue
|
| 113 |
+
field_is_set.setdefault(field.name, set()).add(getattr(block_config, field.name) is not None)
|
| 114 |
+
for name, statuses in field_is_set.items():
|
| 115 |
+
if len(statuses) > 1:
|
| 116 |
+
raise ValueError(
|
| 117 |
+
f"Block field '{name}' must be either set for all blocks that define it, or left "
|
| 118 |
+
f"unset (global) for all of them - mixing per-block and global values is not supported."
|
| 119 |
+
)
|
| 120 |
+
|
| 121 |
+
def _delete_blockwise_members_from_global_config(self):
|
| 122 |
+
"""Move blockwise fields off the global config.
|
| 123 |
+
|
| 124 |
+
A field is blockwise iff it is set (non-None) in the blocks that define it; otherwise it
|
| 125 |
+
stays on the global config.
|
| 126 |
+
"""
|
| 127 |
+
self.blockwise_members = list(set(
|
| 128 |
+
field.name
|
| 129 |
+
for block_config in self.block_configs + self.mtp_block_configs
|
| 130 |
+
for field in dataclasses.fields(block_config)
|
| 131 |
+
if getattr(block_config, field.name) is not None
|
| 132 |
+
))
|
| 133 |
+
for member in self.blockwise_members:
|
| 134 |
+
if hasattr(self, member):
|
| 135 |
+
delattr(self, member)
|
| 136 |
+
|
| 137 |
+
|
| 138 |
+
def build_block_configs(block_config_dicts: list[dict]) -> tuple[list[dataclass], list[str]]:
|
| 139 |
+
block_configs = []
|
| 140 |
+
|
| 141 |
+
# build block config dataclasses
|
| 142 |
+
for block_config in block_config_dicts:
|
| 143 |
+
if isinstance(block_config, dict):
|
| 144 |
+
config_class = BLOCK_TYPE_TO_CONFIG_CLASS[block_config["block_type"]]
|
| 145 |
+
block_config = config_class(**block_config)
|
| 146 |
+
block_configs.append(block_config)
|
| 147 |
+
|
| 148 |
+
# build the explicit per-layer block-type list
|
| 149 |
+
layers_block_type = [block_config.block_type for block_config in block_configs]
|
| 150 |
+
|
| 151 |
+
return block_configs, layers_block_type
|
configuration_radio.py
ADDED
|
@@ -0,0 +1,93 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright (c) 2026, NVIDIA CORPORATION. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
"""RADIO vision encoder configuration."""
|
| 15 |
+
|
| 16 |
+
from huggingface_hub.dataclasses import strict
|
| 17 |
+
from transformers.configuration_utils import PreTrainedConfig
|
| 18 |
+
from transformers.image_utils import OPENAI_CLIP_MEAN, OPENAI_CLIP_STD
|
| 19 |
+
from transformers.utils import auto_docstring
|
| 20 |
+
|
| 21 |
+
|
| 22 |
+
__all__ = ["RadioConfig"]
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
@auto_docstring(checkpoint="nvidia/C-RADIOv4-H")
|
| 26 |
+
@strict
|
| 27 |
+
class RadioConfig(PreTrainedConfig):
|
| 28 |
+
r"""
|
| 29 |
+
mlp_ratio (`float`, *optional*, defaults to 4.0):
|
| 30 |
+
Ratio of the hidden size of the MLP relative to `hidden_size`.
|
| 31 |
+
use_swiglu_ffn (`bool`, *optional*, defaults to `False`):
|
| 32 |
+
Whether to use a SwiGLU feed-forward network in the encoder layers instead of the standard MLP.
|
| 33 |
+
layerscale_value (`float`, *optional*, defaults to 1.0):
|
| 34 |
+
Initial value for the LayerScale parameters. C-RADIO has no LayerScale; the default of `1.0` makes the
|
| 35 |
+
(inherited) LayerScale an identity operation.
|
| 36 |
+
max_img_size (`int`, *optional*, defaults to 2048):
|
| 37 |
+
Maximum supported image size (in pixels) used to size the position embedding table of the CPE patch generator.
|
| 38 |
+
num_cls_tokens (`int`, *optional*, defaults to 3):
|
| 39 |
+
Number of learned class (summary) tokens prepended to the patch sequence.
|
| 40 |
+
num_registers (`int`, *optional*, defaults to 7):
|
| 41 |
+
Number of learned register tokens prepended to the patch sequence.
|
| 42 |
+
summary_idxs (`list[int]`, *optional*, defaults to `[0, 1]`):
|
| 43 |
+
Indices of the class tokens to gather and flatten into the `summary` output embedding.
|
| 44 |
+
norm_mean (`tuple[float, float, float]`, *optional*, defaults to `OPENAI_CLIP_MEAN`):
|
| 45 |
+
Per-channel mean used by the input conditioner to normalize pixel values.
|
| 46 |
+
norm_std (`tuple[float, float, float]`, *optional*, defaults to `OPENAI_CLIP_STD`):
|
| 47 |
+
Per-channel standard deviation used by the input conditioner to normalize pixel values.
|
| 48 |
+
video_temporal_patch_size (`int`, *optional*):
|
| 49 |
+
Number of temporally-stacked frames per patch. When set, the patch generator also builds a
|
| 50 |
+
`video_patch_projection` for temporally-packed video patches; `None` disables the video path.
|
| 51 |
+
"""
|
| 52 |
+
|
| 53 |
+
model_type = "radio"
|
| 54 |
+
|
| 55 |
+
hidden_size: int = 1280
|
| 56 |
+
num_hidden_layers: int = 32
|
| 57 |
+
num_attention_heads: int = 16
|
| 58 |
+
mlp_ratio: float = 4.0
|
| 59 |
+
hidden_act: str = "gelu"
|
| 60 |
+
layer_norm_eps: float = 1e-6
|
| 61 |
+
attention_probs_dropout_prob: float = 0.0
|
| 62 |
+
hidden_dropout_prob: float = 0.0
|
| 63 |
+
drop_path_rate: float = 0.0
|
| 64 |
+
use_swiglu_ffn: bool = False
|
| 65 |
+
qkv_bias: bool = True
|
| 66 |
+
# C-RADIO has no layerscale; 1.0 makes the (inherited) layerscale an identity op.
|
| 67 |
+
layerscale_value: float = 1.0
|
| 68 |
+
# patch / image
|
| 69 |
+
num_channels: int = 3
|
| 70 |
+
patch_size: int = 16
|
| 71 |
+
image_size: int = 224
|
| 72 |
+
# CPE patch generator
|
| 73 |
+
max_img_size: int = 2048
|
| 74 |
+
num_cls_tokens: int = 3
|
| 75 |
+
num_registers: int = 7
|
| 76 |
+
video_temporal_patch_size: int | None = None
|
| 77 |
+
summary_idxs: list[int] | None = None
|
| 78 |
+
# input conditioner
|
| 79 |
+
norm_mean: list[float] | tuple[float, float, float] = tuple(OPENAI_CLIP_MEAN)
|
| 80 |
+
norm_std: list[float] | tuple[float, float, float] = tuple(OPENAI_CLIP_STD)
|
| 81 |
+
initializer_range: float = 0.02
|
| 82 |
+
|
| 83 |
+
def __post_init__(self, **kwargs):
|
| 84 |
+
if self.summary_idxs is None:
|
| 85 |
+
self.summary_idxs = [0, 1]
|
| 86 |
+
self.norm_mean = list(self.norm_mean)
|
| 87 |
+
self.norm_std = list(self.norm_std)
|
| 88 |
+
super().__post_init__(**kwargs)
|
| 89 |
+
|
| 90 |
+
@property
|
| 91 |
+
def num_summary_tokens(self) -> int:
|
| 92 |
+
"""Number of skipped prefix tokens (cls + registers) before spatial features."""
|
| 93 |
+
return self.num_cls_tokens + self.num_registers
|
explainability.md
ADDED
|
@@ -0,0 +1,14 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
| Field | Response |
|
| 2 |
+
| :---- | :---- |
|
| 3 |
+
| Intended Task/Domain: | Text generation, reasoning, and chat |
|
| 4 |
+
| Model Type: | Text-to-text Gemma-4 |
|
| 5 |
+
| Intended Users: | Generative AI creators working with conversational AI models and image content. |
|
| 6 |
+
| Output: | Text |
|
| 7 |
+
| Tools used to evaluate datasets to identify synthetic data and ensure data authenticity. | We used a Gemma-3 4B-based filtering model fine-tuned on [Nemotron Content Safety Dataset v2](https://huggingface.co/datasets/nvidia/Aegis-AI-Content-Safety-Dataset-2.0) to ensure the quality of synthetic data. |
|
| 8 |
+
| Describe how the model works: | Generates text by predicting the next word or token based on the context provided in the input sequence using multiple self-attention layers. |
|
| 9 |
+
| Name the adversely impacted groups this has been tested to deliver comparable outcomes regardless of: | Age, Disability Status, Gender Identity, Nationality, Physical Appearance, Ethnicity, Socioeconomic Status, Sexual Orientation, Religion |
|
| 10 |
+
| Technical Limitations & Mitigation: | This model performs particularly well in instruction following regimes, as such may be strongly influenced by untrusted inputs and should be paired with appropriate guardrails and data filtering to better align use-case behaviors when exposed to such data. |
|
| 11 |
+
| Verified to have met prescribed NVIDIA quality standards: | Yes |
|
| 12 |
+
| Performance Metrics: | Accuracy, Throughput, and User-side throughput |
|
| 13 |
+
| Potential Known Risks: | The model was optimized explicitly for instruction following and as such may be influenced by untrusted inputs (prompt injection, indirect prompt injection, jailbreaking, web search, etc.) as a result of its instruction tuning that may degrade safety alignment and other training efforts. This model should be paired with additional guardrails and data filtering to limit exposure to instructions from malicious sources. Bypassing of safety alignment, system guardrails, and filters may allow harmful outcomes up to and including remote code execution in some agentic systems when effective security controls are not in place. The model was trained on data that contains toxic language and societal biases originally crawled from the internet. Therefore, the model may generate and amplify harmful, biased, or otherwise unsafe content reinforcing these biases and return toxic responses especially when prompted with toxic prompts. The model may also generate answers that may be inaccurate, omit key information, or include irrelevant or redundant text producing socially unacceptable or undesirable text, even if the prompt itself does not include anything explicitly offensive. The model may exhibit self-anthropomorphism (e.g., displaying human-like characteristics in dialogue, such as expressing preferences and emotions). In integrated system contexts, the model could potentially be exploited to access or disclose information beyond the model's intended permissions or scope of operation. |
|
| 14 |
+
| Licensing: | Use of the models is governed by the [OpenMDW License Agreement, version 1.1](https://github.com/OpenMDW/OpenMDW/blob/main/1.1/LICENSE.OpenMDW-1.1). |
|
generation_config.json
ADDED
|
@@ -0,0 +1,13 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
{
|
| 2 |
+
"_from_model_config": true,
|
| 3 |
+
"bos_token_id": 1,
|
| 4 |
+
"do_sample": true,
|
| 5 |
+
"eos_token_id": [
|
| 6 |
+
2,
|
| 7 |
+
11
|
| 8 |
+
],
|
| 9 |
+
"pad_token_id": 0,
|
| 10 |
+
"temperature": 1.0,
|
| 11 |
+
"top_p": 0.95,
|
| 12 |
+
"transformers_version": "5.8.1"
|
| 13 |
+
}
|
hf_quant_config.json
ADDED
|
The diff for this file is too large to render.
See raw diff
|
|
|
image_processing_nemotron_h_omni.py
ADDED
|
@@ -0,0 +1,216 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# Copyright (c) 2026, NVIDIA CORPORATION. All rights reserved.
|
| 2 |
+
#
|
| 3 |
+
# Licensed under the Apache License, Version 2.0 (the "License");
|
| 4 |
+
# you may not use this file except in compliance with the License.
|
| 5 |
+
# You may obtain a copy of the License at
|
| 6 |
+
#
|
| 7 |
+
# http://www.apache.org/licenses/LICENSE-2.0
|
| 8 |
+
#
|
| 9 |
+
# Unless required by applicable law or agreed to in writing, software
|
| 10 |
+
# distributed under the License is distributed on an "AS IS" BASIS,
|
| 11 |
+
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
| 12 |
+
# See the License for the specific language governing permissions and
|
| 13 |
+
# limitations under the License.
|
| 14 |
+
"""Fast image processor for the NemotronH Omni model."""
|
| 15 |
+
|
| 16 |
+
import math
|
| 17 |
+
|
| 18 |
+
import numpy as np
|
| 19 |
+
from transformers.image_processing_backends import TorchvisionBackend
|
| 20 |
+
from transformers.image_processing_base import BatchFeature
|
| 21 |
+
from transformers.image_utils import ImageInput, ImageType, get_image_type, make_list_of_images
|
| 22 |
+
from transformers.utils import is_torch_available
|
| 23 |
+
|
| 24 |
+
|
| 25 |
+
if is_torch_available():
|
| 26 |
+
import torch
|
| 27 |
+
|
| 28 |
+
|
| 29 |
+
class NemotronH_Omni_Reasoning_V3ImageProcessor(TorchvisionBackend):
|
| 30 |
+
"""
|
| 31 |
+
Dynamic-resolution image processor for the NemotronH Omni model.
|
| 32 |
+
|
| 33 |
+
Each image is resized to a single tile whose patch-grid `(h_patches, w_patches)` is chosen to
|
| 34 |
+
land between `min_num_patches` and `max_num_patches` (on a `patch_size` grid), respecting the
|
| 35 |
+
aspect ratio, then normalized with `norm_mean` / `norm_std`. Video frames use a separate fixed
|
| 36 |
+
target-patch budget with aspect ratio preserved (toggled via `_is_video_mode`).
|
| 37 |
+
"""
|
| 38 |
+
|
| 39 |
+
model_input_names = ["pixel_values"]
|
| 40 |
+
|
| 41 |
+
def __init__(
|
| 42 |
+
self,
|
| 43 |
+
norm_mean=None,
|
| 44 |
+
norm_std=None,
|
| 45 |
+
patch_size=16,
|
| 46 |
+
downsample_ratio=0.5,
|
| 47 |
+
min_num_patches=1024,
|
| 48 |
+
max_num_patches=13312,
|
| 49 |
+
max_model_len=16384,
|
| 50 |
+
video_target_num_patches=1024,
|
| 51 |
+
video_maintain_aspect_ratio=True,
|
| 52 |
+
**kwargs,
|
| 53 |
+
):
|
| 54 |
+
super().__init__(**kwargs)
|
| 55 |
+
self.norm_mean = norm_mean
|
| 56 |
+
self.norm_std = norm_std
|
| 57 |
+
self.patch_size = patch_size
|
| 58 |
+
self.downsample_ratio = downsample_ratio
|
| 59 |
+
# Integer reduction factor for pixel_shuffle (downsample_ratio = 0.5 -> factor 2).
|
| 60 |
+
self._downsample_factor = int(round(1.0 / downsample_ratio))
|
| 61 |
+
# Per-image patch-grid bounds (on the pre-pixel-shuffle `patch_size` grid).
|
| 62 |
+
self.min_num_patches = min_num_patches
|
| 63 |
+
self.max_num_patches = max_num_patches
|
| 64 |
+
self.max_model_len = max_model_len
|
| 65 |
+
# Video frames use a separate (fixed) target-patch budget with aspect-ratio preserved.
|
| 66 |
+
self.video_target_num_patches = video_target_num_patches
|
| 67 |
+
self.video_maintain_aspect_ratio = video_maintain_aspect_ratio
|
| 68 |
+
|
| 69 |
+
# Keep the PIL image through to `_preprocess`: we need PIL.resize semantics to match the
|
| 70 |
+
# reference tiling algorithm exactly; resizing a tensor via `torchvision.transforms.Resize`
|
| 71 |
+
# uses different kernels and breaks bit-exact agreement.
|
| 72 |
+
def _process_image(self, image: ImageInput, **kwargs):
|
| 73 |
+
if get_image_type(image) == ImageType.PIL:
|
| 74 |
+
if image.mode != "RGB":
|
| 75 |
+
image = image.convert("RGB")
|
| 76 |
+
return image
|
| 77 |
+
|
| 78 |
+
# transformers 5.6 renamed this hook from `_process_image` to `process_image`; alias both.
|
| 79 |
+
process_image = _process_image
|
| 80 |
+
|
| 81 |
+
# Toggled by the processor around video calls (the strict `ImagesKwargs` validator won't let us
|
| 82 |
+
# thread a new kwarg down, so we use a flag on the instance instead).
|
| 83 |
+
_is_video_mode: bool = False
|
| 84 |
+
|
| 85 |
+
def _preprocess(self, images, return_tensors=None, **kwargs) -> BatchFeature:
|
| 86 |
+
"""Resize each image to its dynamic-resolution tile, normalize, and return pixel values.
|
| 87 |
+
|
| 88 |
+
When `self._is_video_mode=True` (flipped by the processor before the video call), each
|
| 89 |
+
input is resized using the **video** target-size rule (`video_target_num_patches`,
|
| 90 |
+
aspect-ratio preserved) instead of the image dynamic-res rule.
|
| 91 |
+
"""
|
| 92 |
+
is_video = self._is_video_mode
|
| 93 |
+
images = make_list_of_images(images)
|
| 94 |
+
|
| 95 |
+
target_sizes = []
|
| 96 |
+
if is_video:
|
| 97 |
+
for img in images:
|
| 98 |
+
target_w_patches, target_h_patches = self._compute_target_patches_video(img)
|
| 99 |
+
target_sizes.append((target_w_patches, target_h_patches))
|
| 100 |
+
else:
|
| 101 |
+
# Image path: per-image budget bounded by [min_num_patches, max_num_patches], with a
|
| 102 |
+
# global cap derived from `max_model_len` x pixel-shuffle factor^2.
|
| 103 |
+
num_tokens_available = self.max_model_len - 4
|
| 104 |
+
budget = num_tokens_available * (self._downsample_factor**2)
|
| 105 |
+
budget = max(budget, self.min_num_patches * len(images))
|
| 106 |
+
max_budget = self.max_num_patches if (self.max_num_patches and self.max_num_patches > 0) else float("inf")
|
| 107 |
+
per_image_budget = [max(min(budget, max_budget), self.min_num_patches) for _ in images]
|
| 108 |
+
for img, tokens_for_media in zip(images, per_image_budget):
|
| 109 |
+
target_w_patches, target_h_patches = self._compute_target_patches(img, tokens_for_media)
|
| 110 |
+
target_sizes.append((target_w_patches, target_h_patches))
|
| 111 |
+
|
| 112 |
+
norm_mean = torch.tensor(self.norm_mean).view(1, 3, 1, 1)
|
| 113 |
+
norm_std = torch.tensor(self.norm_std).view(1, 3, 1, 1)
|
| 114 |
+
|
| 115 |
+
pixel_values_list = []
|
| 116 |
+
num_tokens_per_image = []
|
| 117 |
+
imgs_sizes = []
|
| 118 |
+
for img, (wp, hp) in zip(images, target_sizes):
|
| 119 |
+
target_w = wp * self.patch_size
|
| 120 |
+
target_h = hp * self.patch_size
|
| 121 |
+
# Antialiased bicubic interpolation via `torch.nn.functional.interpolate`. PIL's bicubic
|
| 122 |
+
# uses a different kernel (and no antialiasing), producing pixel values that amplify
|
| 123 |
+
# through the ViT / mamba stack and cause outputs to diverge past the first few tokens.
|
| 124 |
+
arr = np.asarray(img, dtype=np.uint8) # (H, W, 3)
|
| 125 |
+
t = torch.from_numpy(arr).permute(2, 0, 1).unsqueeze(0).to(dtype=torch.float32) # (1, 3, H, W)
|
| 126 |
+
if t.shape[-2] != target_h or t.shape[-1] != target_w:
|
| 127 |
+
t = torch.nn.functional.interpolate(
|
| 128 |
+
t, size=(target_h, target_w), mode="bicubic", align_corners=False, antialias=True
|
| 129 |
+
)
|
| 130 |
+
t = (t / 255.0 - norm_mean) / norm_std
|
| 131 |
+
pixel_values_list.append(t.squeeze(0)) # (3, H, W)
|
| 132 |
+
num_tokens_per_image.append((wp * hp) // (self._downsample_factor**2))
|
| 133 |
+
imgs_sizes.append((target_h, target_w))
|
| 134 |
+
|
| 135 |
+
# Stack if all images have the same target size; otherwise keep as a list of
|
| 136 |
+
# (3, H_i, W_i) tensors (the model's `extract_feature` handles both).
|
| 137 |
+
all_same_shape = all(t.shape == pixel_values_list[0].shape for t in pixel_values_list)
|
| 138 |
+
pixel_values = torch.stack(pixel_values_list, dim=0) if all_same_shape else pixel_values_list
|
| 139 |
+
|
| 140 |
+
return BatchFeature(
|
| 141 |
+
data={
|
| 142 |
+
"pixel_values": pixel_values,
|
| 143 |
+
"num_patches": [1] * len(images),
|
| 144 |
+
"num_tokens": num_tokens_per_image,
|
| 145 |
+
"imgs_sizes": imgs_sizes,
|
| 146 |
+
},
|
| 147 |
+
tensor_type=(return_tensors if all_same_shape else None),
|
| 148 |
+
)
|
| 149 |
+
|
| 150 |
+
def _compute_target_patches(self, img, tokens_available: int):
|
| 151 |
+
"""Choose the `(w_patches, h_patches)` tile that best fits `tokens_available` (image path)."""
|
| 152 |
+
orig_w, orig_h = img.width, img.height
|
| 153 |
+
# Ceil-ish: `round(x + 0.5)` == `floor(x) + 1` for non-integer x, `x` for integer.
|
| 154 |
+
closest_patch_h = round(orig_h / self.patch_size + 0.5)
|
| 155 |
+
closest_patch_w = round(orig_w / self.patch_size + 0.5)
|
| 156 |
+
patches = closest_patch_h * closest_patch_w
|
| 157 |
+
|
| 158 |
+
# Downscale to fit the token budget.
|
| 159 |
+
factor = min(math.sqrt(tokens_available / patches), 1.0)
|
| 160 |
+
target_h = math.floor(factor * closest_patch_h)
|
| 161 |
+
target_w = math.floor(factor * closest_patch_w)
|
| 162 |
+
|
| 163 |
+
# Scale up if below the per-image minimum.
|
| 164 |
+
if tokens_available > self.min_num_patches and target_h * target_w < self.min_num_patches:
|
| 165 |
+
up = math.sqrt(self.min_num_patches / (target_h * target_w))
|
| 166 |
+
target_h = math.ceil(up * target_h)
|
| 167 |
+
target_w = math.ceil(up * target_w)
|
| 168 |
+
|
| 169 |
+
# Round each dim to a multiple of the pixel_shuffle factor so tokens divide evenly.
|
| 170 |
+
divisor = self._downsample_factor
|
| 171 |
+
rem_h = target_h % divisor
|
| 172 |
+
if rem_h:
|
| 173 |
+
inc_h = divisor - rem_h
|
| 174 |
+
if (target_h + inc_h) * target_w <= tokens_available:
|
| 175 |
+
target_h += inc_h
|
| 176 |
+
else:
|
| 177 |
+
target_h = max(divisor, target_h - rem_h)
|
| 178 |
+
rem_w = target_w % divisor
|
| 179 |
+
if rem_w:
|
| 180 |
+
inc_w = divisor - rem_w
|
| 181 |
+
if target_h * (target_w + inc_w) <= tokens_available:
|
| 182 |
+
target_w += inc_w
|
| 183 |
+
else:
|
| 184 |
+
target_w = max(divisor, target_w - rem_w)
|
| 185 |
+
|
| 186 |
+
return target_w, target_h
|
| 187 |
+
|
| 188 |
+
def _compute_target_patches_video(self, img):
|
| 189 |
+
"""Choose an aspect-preserving `(w_patches, h_patches)` tile near `video_target_num_patches`."""
|
| 190 |
+
orig_w, orig_h = img.width, img.height
|
| 191 |
+
target = self.video_target_num_patches
|
| 192 |
+
divisor = self._downsample_factor
|
| 193 |
+
if self.video_maintain_aspect_ratio:
|
| 194 |
+
aspect_wh = orig_w / max(orig_h, 1)
|
| 195 |
+
ph = max(round(math.sqrt(target / aspect_wh)), 1)
|
| 196 |
+
pw = max(round(math.sqrt(target * aspect_wh)), 1)
|
| 197 |
+
if divisor > 1:
|
| 198 |
+
rem_h = ph % divisor
|
| 199 |
+
rem_w = pw % divisor
|
| 200 |
+
ph_up = ph + (divisor - rem_h if rem_h else 0)
|
| 201 |
+
ph_down = ph - rem_h
|
| 202 |
+
pw_up = pw + (divisor - rem_w if rem_w else 0)
|
| 203 |
+
pw_down = pw - rem_w
|
| 204 |
+
if ph_up * pw_up <= target:
|
| 205 |
+
ph, pw = ph_up, pw_up
|
| 206 |
+
else:
|
| 207 |
+
ph = max(divisor, ph_down)
|
| 208 |
+
pw = max(divisor, pw_down)
|
| 209 |
+
else:
|
| 210 |
+
side = int(math.sqrt(target))
|
| 211 |
+
side = max(divisor, (side // divisor) * divisor)
|
| 212 |
+
ph = pw = side
|
| 213 |
+
return pw, ph
|
| 214 |
+
|
| 215 |
+
|
| 216 |
+
__all__ = ["NemotronH_Omni_Reasoning_V3ImageProcessor"]
|
model-00001-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:dbc36ec29905093301dd55335c52bc63e367f37b5f31c214f734ad9d5a08c568
|
| 3 |
+
size 1644175760
|
model-00002-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:39057c9ed8083885c452e38ded333f97cfb00cc8d58acc1bea83a1ff5792f79e
|
| 3 |
+
size 61765944
|
model-00003-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:75e0abc6a95bbf8de1536f49e8cbea933d03c22786d271f2ee32dbb5f7e11251
|
| 3 |
+
size 281832856
|
model-00004-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7047e2df7cd37aff7f94a04dd3b4e1666219f7044208c90c69e11b1929c49a14
|
| 3 |
+
size 61765944
|
model-00005-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5df578abee81e7bbec27227e9cff32b8a033d2bb57018afd6f7dd9dc2810be1d
|
| 3 |
+
size 216952088
|
model-00006-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a872e38a12938a3d44ce0af7dfba834305868ae007e75598bf7fa536242c2e94
|
| 3 |
+
size 61765944
|
model-00007-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:ea5f48c0d8173c6b6c9175678114064f9b8be66023d201c5e88e30eb1e149f48
|
| 3 |
+
size 281832856
|
model-00008-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5ac4c9dbf40721f00fa5c402dcdee3ce9f8a19144f8e0e5f4840eaeb83f95f91
|
| 3 |
+
size 61765944
|
model-00009-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:8137ebf1b5fdb6f2fd0e809c57147e99c1d0d179469627896f096d64ec7ae5c7
|
| 3 |
+
size 37888672
|
model-00010-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:2bd8dcd8bf50c3e4b33a0f6f5f839a0d7038739be814aac0c52d4303a002835f
|
| 3 |
+
size 392672584
|
model-00011-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:86bd79c50e365ba70aba34916c144dcd540761a6fac953e01b1c04c2a9027b4d
|
| 3 |
+
size 61765944
|
model-00012-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e94b7e9d9f7637f0c3bbb68484616f8de43197bc0d00340ce224043a42a97305
|
| 3 |
+
size 314273704
|
model-00013-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:cb1153fe885604ab35d6fdfb318525383b3b24647317760b778b4f6df37deb5d
|
| 3 |
+
size 61765960
|
model-00014-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:df1e376df256a3af2e8cfdd2161ac6a07cb83c900717f41412f4da0c62e1f8a6
|
| 3 |
+
size 281833344
|
model-00015-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:83cfac4f0c33e772d3cc14a1fa5ec55df693d09a5e009c5ee8425826d2e85bca
|
| 3 |
+
size 61765960
|
model-00016-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:07fc64bafd76ac775865bacf64178f09c606b11f1890084e536f532daaae097a
|
| 3 |
+
size 281833344
|
model-00017-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:715669b3d8f8c37a1e7e5c6bfe13c03b413406f665c8ed9389ad114c694f3692
|
| 3 |
+
size 61765960
|
model-00018-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:b97c4fe1b42ad83bc4a08e88d324a3cf420dea755f9052390c8a6a6d324119f0
|
| 3 |
+
size 37888680
|
model-00019-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:4965525c279b3a8d90ed3a17eb80dce05b1b956f6c4370657e71f855e4060588
|
| 3 |
+
size 392673200
|
model-00020-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:0553730544ec723af4aae3851aea4270f11583bbe9f67bccbb0389c1d21b8f2d
|
| 3 |
+
size 61765960
|
model-00021-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:5e55d6bcf532b9e06341945f5c36d22c335aa0d94bfb8065748e1fff3e688513
|
| 3 |
+
size 351582080
|
model-00022-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:06f4d0820e6fa48d59e9fdb5f770de65ccf51b9a5d5b222855d0424d3e734d40
|
| 3 |
+
size 61765960
|
model-00023-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c3b2d371a46d64c6cc1d81dd7e21984caaa6840f2a3ad7f28758ac8fafb3cc6b
|
| 3 |
+
size 607865224
|
model-00024-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a671c5a7e516b9e96b9705d84524b56c1f1382d9127c383e2382dbc28a7ede7b
|
| 3 |
+
size 61765960
|
model-00025-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:aa3a22b861affd7375fae241d8c89031d37c9a43ae109c4c7418035243dfab7f
|
| 3 |
+
size 549472184
|
model-00026-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:e920e22dd372a114ef703a7e0705efdbe8f4d392309b4ddba5f273959547c5e0
|
| 3 |
+
size 61765960
|
model-00027-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:c1e2a955db5927b1d5ecfb9c41b27f84440f0f23e909e0499a10614179db4e09
|
| 3 |
+
size 37888680
|
model-00028-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:d889748b07f7f47bea4afd940cc0e7f0a7b498742fe9d2edcd6e0a9cfd2ef88a
|
| 3 |
+
size 281833344
|
model-00029-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:60369f6ca059450dc0e09a8730ff7c1da692142b7d87fdc7768764a2c30745c3
|
| 3 |
+
size 61765960
|
model-00030-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:13d099a42e03e446b511bd504c60b8e6596ea1c2ba0f0835e2b947bb0f1a5f44
|
| 3 |
+
size 549472184
|
model-00031-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:a482a122726be6e7efc13fd87b67f0342f48cb1257965414cc494079a61a1c6c
|
| 3 |
+
size 61765960
|
model-00032-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7a8204e6497a22ee03c817fe7ef405f3a1334fff7f762b1972d2124015b41aed
|
| 3 |
+
size 433764608
|
model-00033-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:3acb7c27203df29410aecb4a3cd2fd1cbe52c73f1ebfa23f8505d2c59839f992
|
| 3 |
+
size 61765960
|
model-00034-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:7e0aa20cf20baada351a5623322b7e89e40dbb7163da17b98afcc4bd7d60dcb4
|
| 3 |
+
size 392673200
|
model-00035-of-00090.safetensors
ADDED
|
@@ -0,0 +1,3 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
version https://git-lfs.github.com/spec/v1
|
| 2 |
+
oid sha256:47887449a557ed0abbe55327f1f35dec5b93c42f0f838b52ffe7b75ce1d5ad4e
|
| 3 |
+
size 61765960
|