

Upload 10 files
Browse files- .gitattributes +7 -0
- README.md +19 -12
- San Diego Airport.jpg +3 -0
- Theodore_Roosevelt.png +3 -0
- Tricycle.jpg +3 -0
- app.py +205 -0
- bus.jpg +3 -0
- requirements.txt +4 -0
- tcganadolu.jpg +3 -0
- yolo_vision.jpg +3 -0
- zidane.jpg +3 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,10 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
bus.jpg filter=lfs diff=lfs merge=lfs -text
|
| 37 |
+
San[[:space:]]Diego[[:space:]]Airport.jpg filter=lfs diff=lfs merge=lfs -text
|
| 38 |
+
tcganadolu.jpg filter=lfs diff=lfs merge=lfs -text
|
| 39 |
+
Theodore_Roosevelt.png filter=lfs diff=lfs merge=lfs -text
|
| 40 |
+
Tricycle.jpg filter=lfs diff=lfs merge=lfs -text
|
| 41 |
+
yolo_vision.jpg filter=lfs diff=lfs merge=lfs -text
|
| 42 |
+
zidane.jpg filter=lfs diff=lfs merge=lfs -text
|
README.md
CHANGED
|
@@ -1,12 +1,19 @@
|
|
| 1 |
-
---
|
| 2 |
-
title: Yolo26
|
| 3 |
-
emoji:
|
| 4 |
-
colorFrom:
|
| 5 |
-
colorTo: blue
|
| 6 |
-
sdk: gradio
|
| 7 |
-
sdk_version: 5.49.1
|
| 8 |
-
app_file: app.py
|
| 9 |
-
pinned: false
|
| 10 |
-
|
| 11 |
-
|
| 12 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
---
|
| 2 |
+
title: Yolo26
|
| 3 |
+
emoji: 👁
|
| 4 |
+
colorFrom: indigo
|
| 5 |
+
colorTo: blue
|
| 6 |
+
sdk: gradio
|
| 7 |
+
sdk_version: 5.49.1
|
| 8 |
+
app_file: app.py
|
| 9 |
+
pinned: false
|
| 10 |
+
tags:
|
| 11 |
+
- Object Detection
|
| 12 |
+
- Instance Segmentation
|
| 13 |
+
- Pose/Keypoints
|
| 14 |
+
- Oriented Detection
|
| 15 |
+
- Image Classification
|
| 16 |
+
short_description: Detect, segment, classify objects in images and videos
|
| 17 |
+
---
|
| 18 |
+
|
| 19 |
+
Check out the configuration reference at https://huggingface.co/docs/hub/spaces-config-reference
|
San Diego Airport.jpg
ADDED
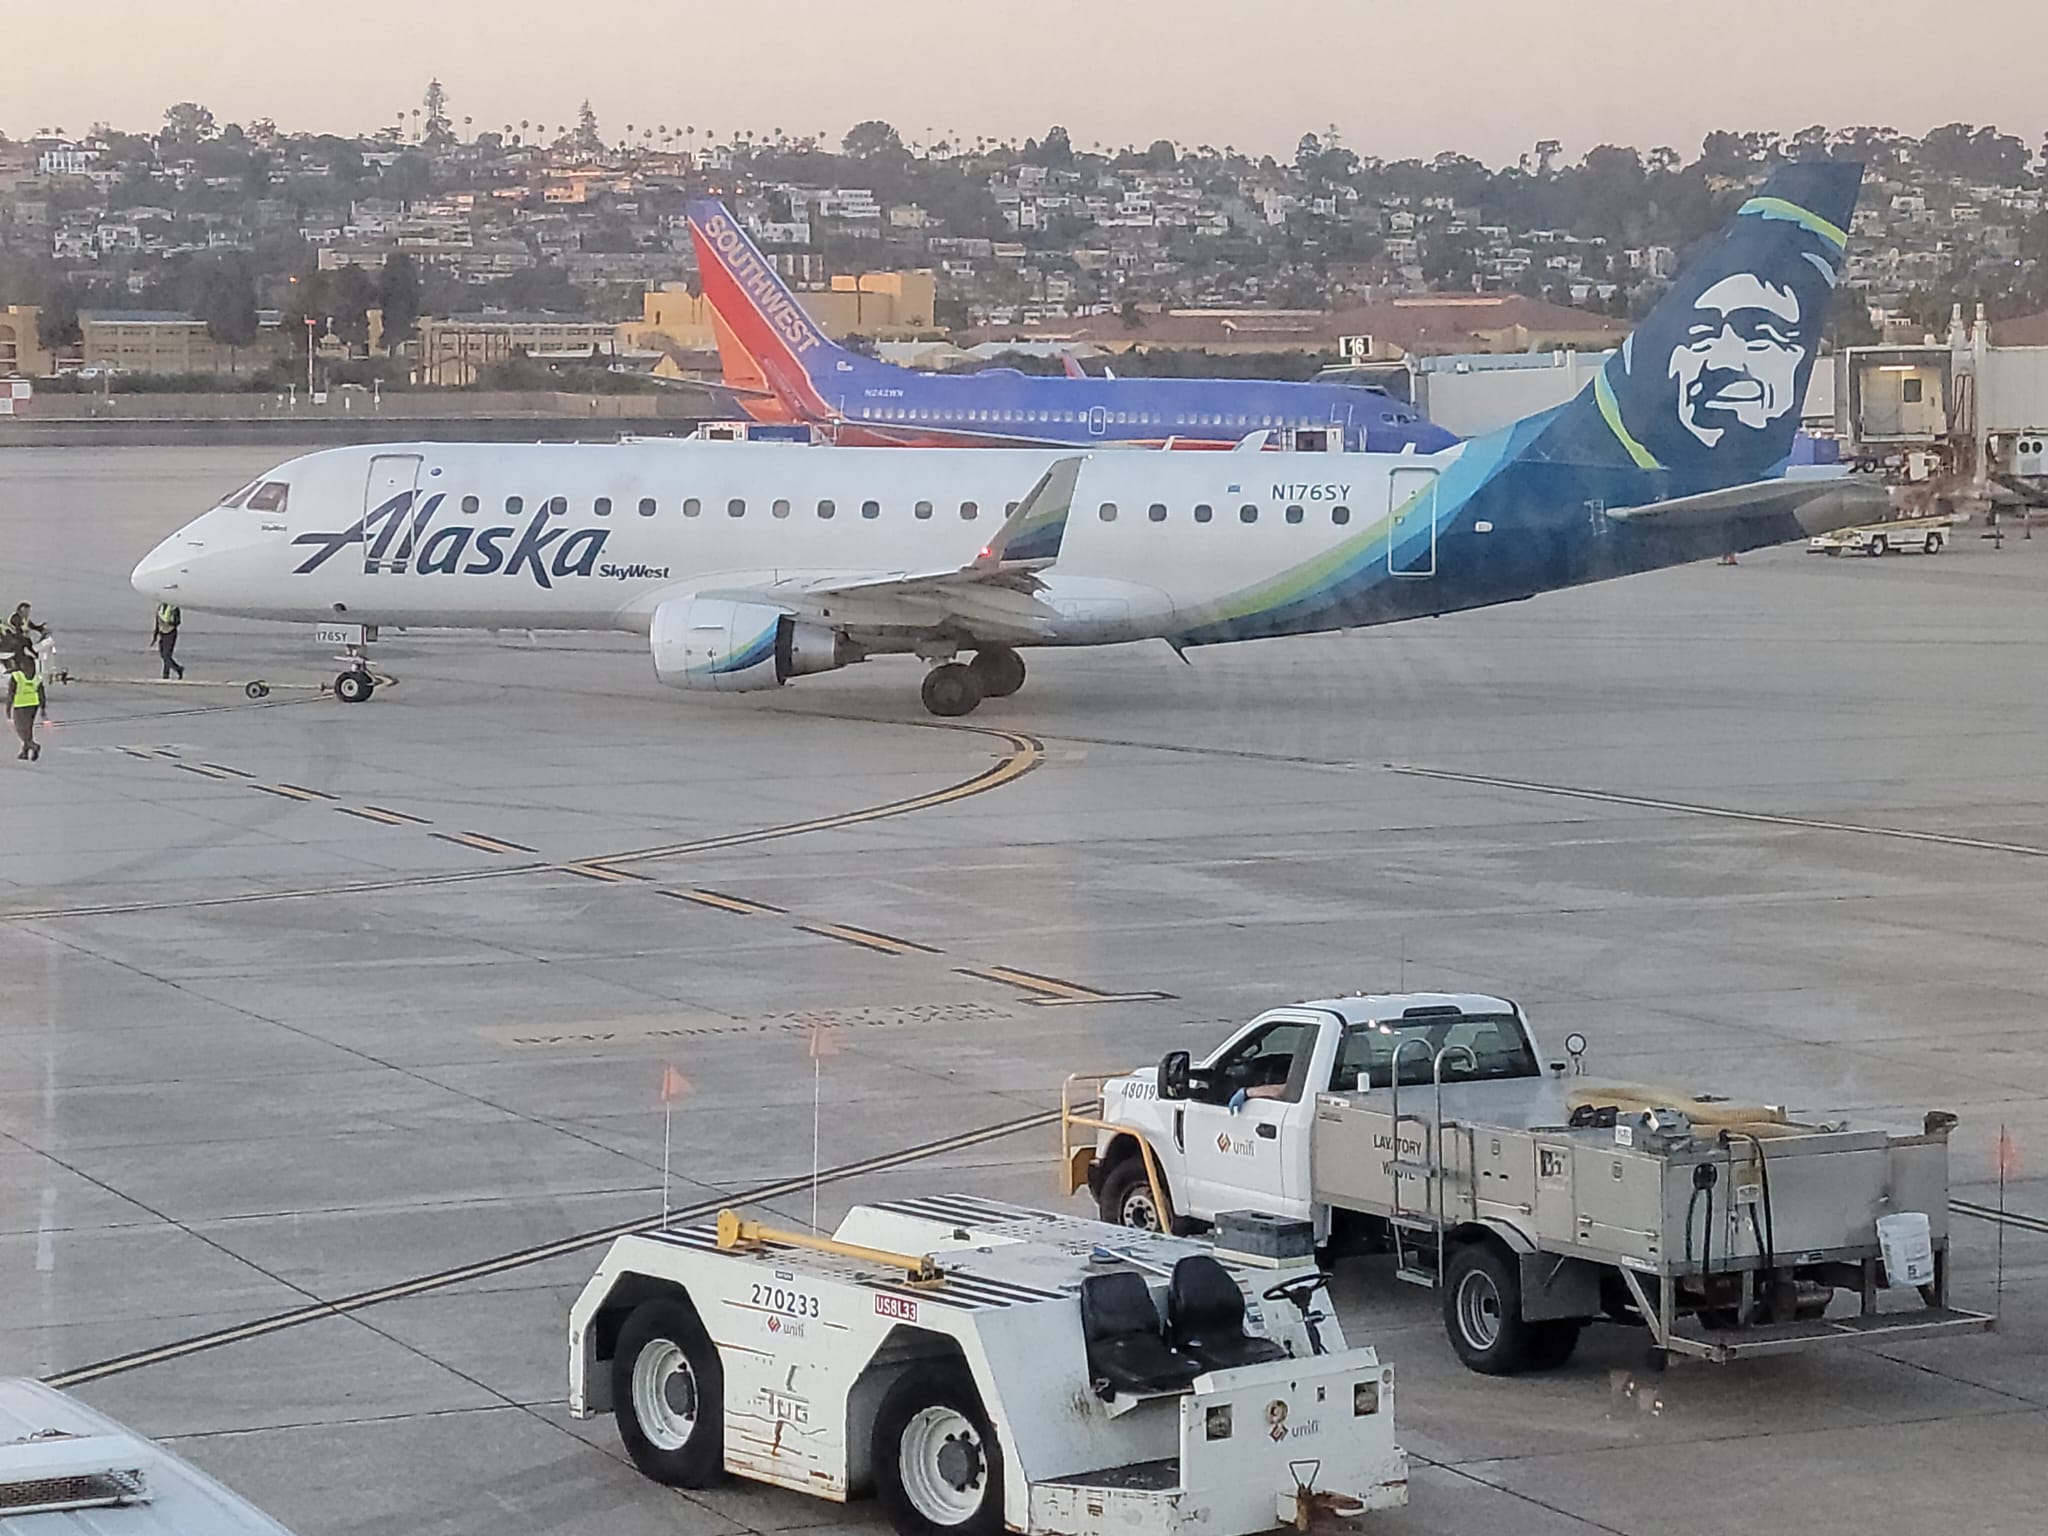
|
Git LFS Details
|
Theodore_Roosevelt.png
ADDED
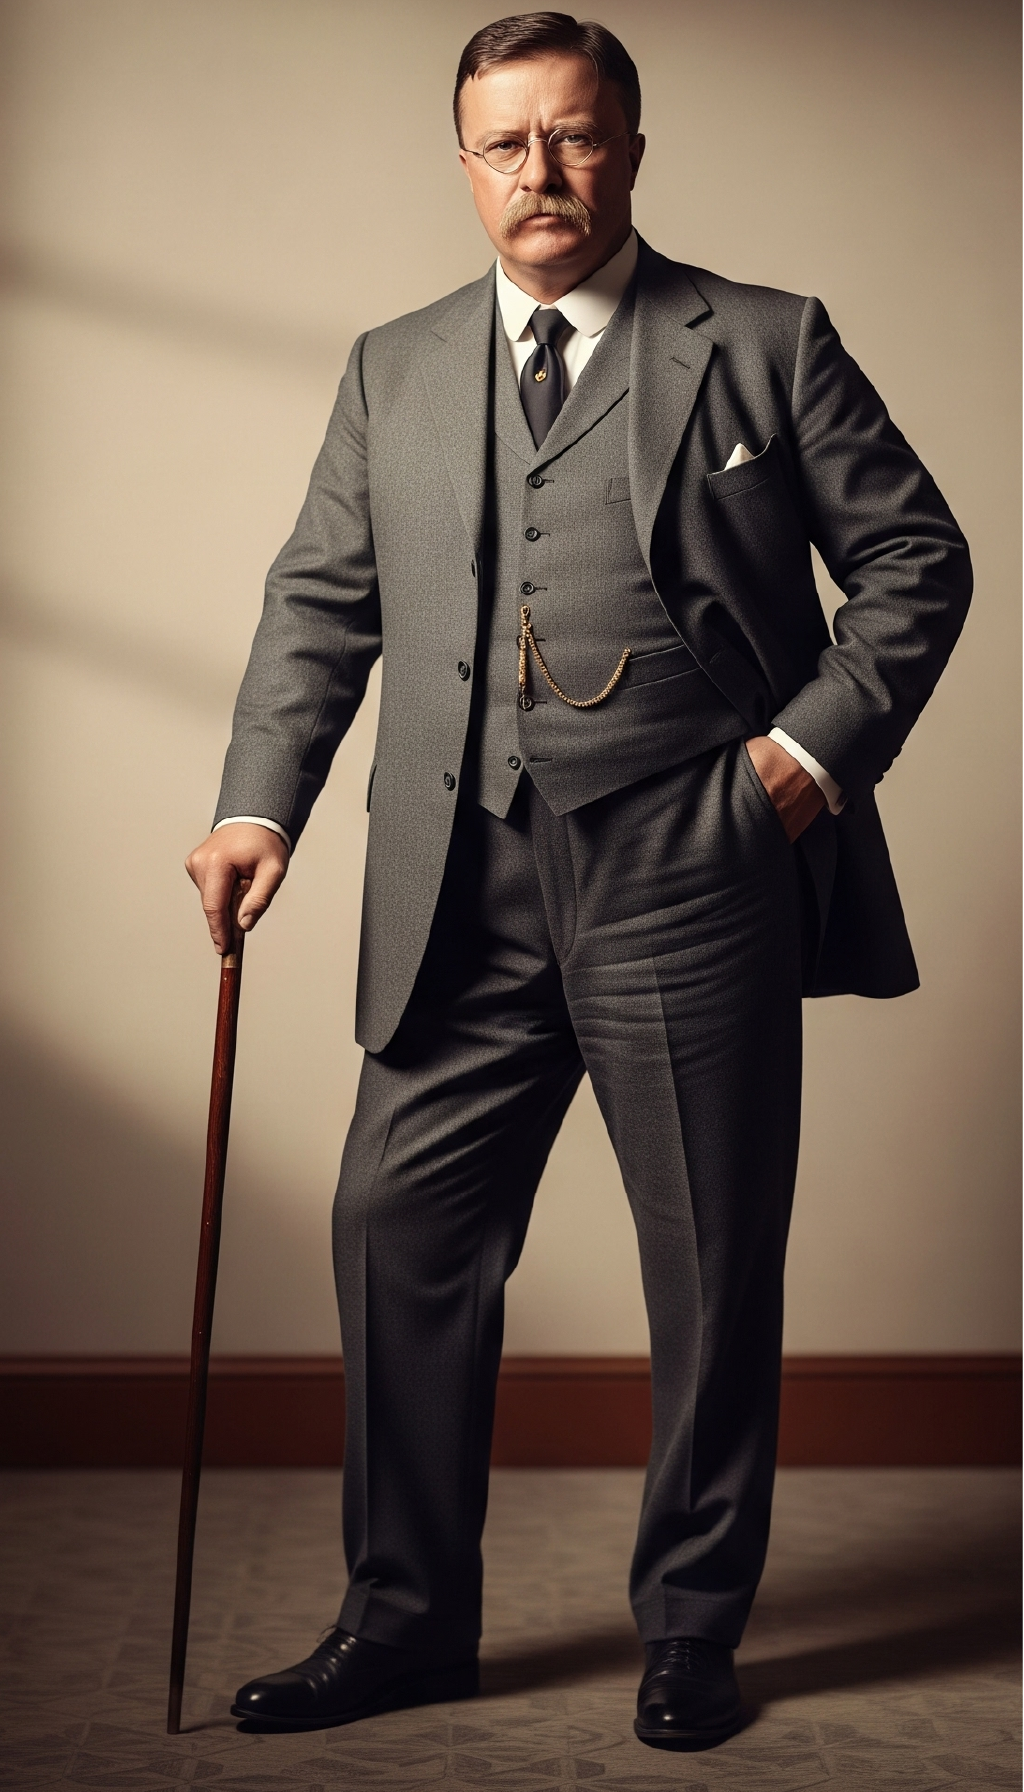
|
Git LFS Details
|
Tricycle.jpg
ADDED
|
Git LFS Details
|
app.py
ADDED
|
@@ -0,0 +1,205 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
import spaces
|
| 2 |
+
import gradio as gr
|
| 3 |
+
from PIL import Image, ImageDraw, ImageFont
|
| 4 |
+
from ultralytics import YOLO
|
| 5 |
+
import cv2
|
| 6 |
+
import tempfile
|
| 7 |
+
import numpy as np
|
| 8 |
+
|
| 9 |
+
# -----------------------------
|
| 10 |
+
# Inference
|
| 11 |
+
# -----------------------------
|
| 12 |
+
@spaces.GPU
|
| 13 |
+
def yolo_inference(input_type, image, video, model_id, conf_threshold, iou_threshold, max_detection):
|
| 14 |
+
"""
|
| 15 |
+
Ultralytics YOLO26 inference for image or video.
|
| 16 |
+
Accepts detect/seg/pose/obb/cls checkpoints and renders r.plot().
|
| 17 |
+
"""
|
| 18 |
+
model = YOLO(model_id)
|
| 19 |
+
|
| 20 |
+
if input_type == "Image":
|
| 21 |
+
if image is None:
|
| 22 |
+
w, h = 640, 480
|
| 23 |
+
blank = Image.new("RGB", (w, h), color="white")
|
| 24 |
+
draw = ImageDraw.Draw(blank)
|
| 25 |
+
msg = "No image provided"
|
| 26 |
+
font = ImageFont.load_default(size=40)
|
| 27 |
+
bbox = draw.textbbox((0, 0), msg, font=font)
|
| 28 |
+
tw, th = bbox[2] - bbox[0], bbox[3] - bbox[1]
|
| 29 |
+
draw.text(((w - tw) / 2, (h - th) / 2), msg, fill="black", font=font)
|
| 30 |
+
return blank, None
|
| 31 |
+
|
| 32 |
+
results = model.predict(
|
| 33 |
+
source=image,
|
| 34 |
+
conf=conf_threshold,
|
| 35 |
+
iou=iou_threshold,
|
| 36 |
+
imgsz=640,
|
| 37 |
+
max_det=max_detection,
|
| 38 |
+
show_labels=True,
|
| 39 |
+
show_conf=True,
|
| 40 |
+
)
|
| 41 |
+
annotated_image = None
|
| 42 |
+
for r in results:
|
| 43 |
+
img_bgr = r.plot()
|
| 44 |
+
annotated_image = Image.fromarray(img_bgr[..., ::-1])
|
| 45 |
+
return annotated_image, None
|
| 46 |
+
|
| 47 |
+
if input_type == "Video":
|
| 48 |
+
if video is None:
|
| 49 |
+
w, h = 640, 480
|
| 50 |
+
blank = Image.new("RGB", (w, h), color="white")
|
| 51 |
+
draw = ImageDraw.Draw(blank)
|
| 52 |
+
msg = "No video provided"
|
| 53 |
+
font = ImageFont.load_default(size=40)
|
| 54 |
+
bbox = draw.textbbox((0, 0), msg, font=font)
|
| 55 |
+
tw, th = bbox[2] - bbox[0], bbox[3] - bbox[1]
|
| 56 |
+
draw.text(((w - tw) / 2, (h - th) / 2), msg, fill="black", font=font)
|
| 57 |
+
tmp = tempfile.NamedTemporaryFile(suffix=".mp4", delete=False).name
|
| 58 |
+
fourcc = cv2.VideoWriter_fourcc(*"mp4v")
|
| 59 |
+
out = cv2.VideoWriter(tmp, fourcc, 1, (w, h))
|
| 60 |
+
out.write(cv2.cvtColor(np.array(blank), cv2.COLOR_RGB2BGR))
|
| 61 |
+
out.release()
|
| 62 |
+
return None, tmp
|
| 63 |
+
|
| 64 |
+
cap = cv2.VideoCapture(video)
|
| 65 |
+
fps = cap.get(cv2.CAP_PROP_FPS) if cap.get(cv2.CAP_PROP_FPS) > 0 else 25
|
| 66 |
+
frames = []
|
| 67 |
+
while True:
|
| 68 |
+
ret, frame = cap.read()
|
| 69 |
+
if not ret:
|
| 70 |
+
break
|
| 71 |
+
pil_frame = Image.fromarray(cv2.cvtColor(frame, cv2.COLOR_BGR2RGB))
|
| 72 |
+
results = model.predict(
|
| 73 |
+
source=pil_frame,
|
| 74 |
+
conf=conf_threshold,
|
| 75 |
+
iou=iou_threshold,
|
| 76 |
+
imgsz=640,
|
| 77 |
+
max_det=max_detection,
|
| 78 |
+
show_labels=True,
|
| 79 |
+
show_conf=True,
|
| 80 |
+
)
|
| 81 |
+
for r in results:
|
| 82 |
+
anno_bgr = r.plot()
|
| 83 |
+
anno_rgb = cv2.cvtColor(anno_bgr, cv2.COLOR_BGR2RGB)
|
| 84 |
+
frames.append(anno_rgb)
|
| 85 |
+
cap.release()
|
| 86 |
+
if not frames:
|
| 87 |
+
return None, None
|
| 88 |
+
|
| 89 |
+
h, w, _ = frames[0].shape
|
| 90 |
+
tmp = tempfile.NamedTemporaryFile(suffix=".mp4", delete=False).name
|
| 91 |
+
fourcc = cv2.VideoWriter_fourcc(*"mp4v")
|
| 92 |
+
out = cv2.VideoWriter(tmp, fourcc, fps, (w, h))
|
| 93 |
+
for f in frames:
|
| 94 |
+
out.write(cv2.cvtColor(f, cv2.COLOR_RGB2BGR))
|
| 95 |
+
out.release()
|
| 96 |
+
return None, tmp
|
| 97 |
+
|
| 98 |
+
return None, None
|
| 99 |
+
|
| 100 |
+
|
| 101 |
+
def update_visibility(input_type):
|
| 102 |
+
if input_type == "Image":
|
| 103 |
+
return gr.update(visible=True), gr.update(visible=False), gr.update(visible=True), gr.update(visible=False)
|
| 104 |
+
else:
|
| 105 |
+
return gr.update(visible=False), gr.update(visible=True), gr.update(visible=False), gr.update(visible=True)
|
| 106 |
+
|
| 107 |
+
|
| 108 |
+
def yolo_inference_for_examples(image, model_id, conf_threshold, iou_threshold, max_detection):
|
| 109 |
+
annotated_image, _ = yolo_inference(
|
| 110 |
+
input_type="Image",
|
| 111 |
+
image=image,
|
| 112 |
+
video=None,
|
| 113 |
+
model_id=model_id,
|
| 114 |
+
conf_threshold=conf_threshold,
|
| 115 |
+
iou_threshold=iou_threshold,
|
| 116 |
+
max_detection=max_detection
|
| 117 |
+
)
|
| 118 |
+
return annotated_image
|
| 119 |
+
|
| 120 |
+
theme = gr.themes.Ocean(primary_hue="indigo", secondary_hue="blue")
|
| 121 |
+
|
| 122 |
+
with gr.Blocks(theme=theme) as app:
|
| 123 |
+
gr.Markdown("# Ultralytics YOLO26")
|
| 124 |
+
gr.Markdown("Image or video inference with detection, segmentation, pose, oriented bounding boxes, and classification.")
|
| 125 |
+
with gr.Accordion("Reference", open=False):
|
| 126 |
+
gr.Markdown("""
|
| 127 |
+
**BibTeX:**
|
| 128 |
+
```
|
| 129 |
+
@software{yolo26_ultralytics,
|
| 130 |
+
author = {Glenn Jocher and Jing Qiu},
|
| 131 |
+
title = {Ultralytics YOLO26},
|
| 132 |
+
version = {26.0.0},
|
| 133 |
+
year = {2025},
|
| 134 |
+
url = {https://github.com/ultralytics/ultralytics},
|
| 135 |
+
orcid = {0000-0001-5950-6979, 0000-0003-3783-7069},
|
| 136 |
+
license = {AGPL-3.0}
|
| 137 |
+
}
|
| 138 |
+
```
|
| 139 |
+
"""
|
| 140 |
+
)
|
| 141 |
+
|
| 142 |
+
with gr.Row():
|
| 143 |
+
with gr.Column():
|
| 144 |
+
image = gr.Image(type="pil", label="Image", visible=True)
|
| 145 |
+
video = gr.Video(label="Video", visible=False)
|
| 146 |
+
input_type = gr.Radio(choices=["Image", "Video"], value="Image", label="Input Type")
|
| 147 |
+
|
| 148 |
+
model_id = gr.Dropdown(
|
| 149 |
+
label="Model",
|
| 150 |
+
choices=[
|
| 151 |
+
# detect
|
| 152 |
+
"yolo26n.pt","yolo26s.pt","yolo26m.pt","yolo26l.pt","yolo26x.pt",
|
| 153 |
+
# seg
|
| 154 |
+
"yolo26n-seg.pt","yolo26s-seg.pt","yolo26m-seg.pt","yolo26l-seg.pt","yolo26x-seg.pt",
|
| 155 |
+
# pose
|
| 156 |
+
"yolo26n-pose.pt","yolo26s-pose.pt","yolo26m-pose.pt","yolo26l-pose.pt","yolo26x-pose.pt",
|
| 157 |
+
# obb
|
| 158 |
+
"yolo26n-obb.pt","yolo26s-obb.pt","yolo26m-obb.pt","yolo26l-obb.pt","yolo26x-obb.pt",
|
| 159 |
+
# cls
|
| 160 |
+
"yolo26n-cls.pt","yolo26s-cls.pt","yolo26m-cls.pt","yolo26l-cls.pt","yolo26x-cls.pt",
|
| 161 |
+
],
|
| 162 |
+
value="yolo26n.pt",
|
| 163 |
+
)
|
| 164 |
+
|
| 165 |
+
conf_threshold = gr.Slider(minimum=0, maximum=1, value=0.25, label="Confidence Threshold")
|
| 166 |
+
iou_threshold = gr.Slider(minimum=0, maximum=1, value=0.45, label="IoU Threshold")
|
| 167 |
+
max_detection = gr.Slider(minimum=1, maximum=300, step=1, value=300, label="Max Detection")
|
| 168 |
+
|
| 169 |
+
infer_button = gr.Button("Detect Objects", variant="primary")
|
| 170 |
+
|
| 171 |
+
with gr.Column():
|
| 172 |
+
output_image = gr.Image(type="pil", show_label=False, show_share_button=False, visible=True)
|
| 173 |
+
output_video = gr.Video(show_label=False, show_share_button=False, visible=False)
|
| 174 |
+
gr.DeepLinkButton(variant="primary")
|
| 175 |
+
|
| 176 |
+
input_type.change(
|
| 177 |
+
fn=update_visibility,
|
| 178 |
+
inputs=input_type,
|
| 179 |
+
outputs=[image, video, output_image, output_video],
|
| 180 |
+
)
|
| 181 |
+
|
| 182 |
+
infer_button.click(
|
| 183 |
+
fn=yolo_inference,
|
| 184 |
+
inputs=[input_type, image, video, model_id, conf_threshold, iou_threshold, max_detection],
|
| 185 |
+
outputs=[output_image, output_video],
|
| 186 |
+
)
|
| 187 |
+
|
| 188 |
+
gr.Examples(
|
| 189 |
+
examples=[
|
| 190 |
+
["zidane.jpg", "yolo26s.pt", 0.25, 0.45, 300],
|
| 191 |
+
["bus.jpg", "yolo26m.pt", 0.25, 0.45, 300],
|
| 192 |
+
["yolo_vision.jpg", "yolo26x.pt", 0.25, 0.45, 300],
|
| 193 |
+
["Tricycle.jpg", "yolo26x-cls.pt", 0.25, 0.45, 300],
|
| 194 |
+
["tcganadolu.jpg", "yolo26m-obb.pt", 0.25, 0.45, 300],
|
| 195 |
+
["San Diego Airport.jpg", "yolo26x-seg.pt", 0.25, 0.45, 300],
|
| 196 |
+
["Theodore_Roosevelt.png", "yolo26l-pose.pt", 0.25, 0.45, 300],
|
| 197 |
+
],
|
| 198 |
+
fn=yolo_inference_for_examples,
|
| 199 |
+
inputs=[image, model_id, conf_threshold, iou_threshold, max_detection],
|
| 200 |
+
outputs=[output_image],
|
| 201 |
+
label="Examples",
|
| 202 |
+
)
|
| 203 |
+
|
| 204 |
+
if __name__ == "__main__":
|
| 205 |
+
app.launch(mcp_server=True)
|
bus.jpg
ADDED
|
Git LFS Details
|
requirements.txt
ADDED
|
@@ -0,0 +1,4 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
ultralytics
|
| 2 |
+
spaces
|
| 3 |
+
Pillow
|
| 4 |
+
huggingface_hub
|
tcganadolu.jpg
ADDED
|
Git LFS Details
|
yolo_vision.jpg
ADDED
|
Git LFS Details
|
zidane.jpg
ADDED
|
Git LFS Details
|