

Update the model card from turintech/artemis-models
Browse files- README.md +158 -124
- RESULTS.md +143 -0
- assets/buttons/artemis.png +0 -0
- assets/buttons/lm-studio.png +0 -0
- assets/buttons/ollama.png +0 -0
- assets/buttons/other-models.png +0 -0
- assets/buttons/turintech.png +0 -0
- assets/comparison.png +0 -0
- assets/turintech-logo-v2.png +0 -0
README.md
CHANGED
|
@@ -2,44 +2,70 @@
|
|
| 2 |
license: apache-2.0
|
| 3 |
base_model: google/embeddinggemma-2
|
| 4 |
base_model_relation: quantized
|
|
|
|
| 5 |
pipeline_tag: sentence-similarity
|
| 6 |
tags:
|
| 7 |
-
-
|
|
|
|
|
|
|
| 8 |
- embeddings
|
| 9 |
-
|
|
|
|
|
|
|
|
|
|
| 10 |
---
|
| 11 |
|
| 12 |
-
<!--
|
| 13 |
-
<
|
|
|
|
|
|
|
| 14 |
|
| 15 |
-
|
| 16 |
|
| 17 |
-
|
| 18 |
-
|
| 19 |
-
|
| 20 |
-
<
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 21 |
|
| 22 |
## Run it
|
| 23 |
|
| 24 |
-
An embedding model:
|
|
|
|
| 25 |
|
| 26 |
```bash
|
| 27 |
-
|
| 28 |
-
|
| 29 |
-
|
| 30 |
-
cd ./embeddinggemma-2-artemis
|
| 31 |
-
printf '%s %s\n' f76351ba13988274750620577c88911b195a15321c37fc991bed485ed8f81f45 embeddinggemma-2-Artemis-Q4_K_S.gguf | sha256sum -c -
|
| 32 |
```
|
| 33 |
|
| 34 |
-
<
|
| 35 |
-
|
|
|
|
| 36 |
|
| 37 |
-
|
| 38 |
-
|
|
|
|
|
|
|
| 39 |
|
| 40 |
-
|
|
|
|
| 41 |
|
| 42 |
-
|
|
|
|
|
|
|
|
|
|
| 43 |
|
| 44 |
```bash
|
| 45 |
set -e
|
|
@@ -56,25 +82,18 @@ export PATH="$PWD/llama-cpp-embeddinggemma2/build/bin:$PATH"
|
|
| 56 |
llama-server --version
|
| 57 |
```
|
| 58 |
|
| 59 |
-
Keep the build directory and its libraries together. `GGML_NATIVE=ON` targets the
|
|
|
|
| 60 |
|
| 61 |
-
|
| 62 |
-
|
| 63 |
-
With that build on PATH and the current directory containing the downloaded GGUF, run:
|
| 64 |
|
| 65 |
```bash
|
| 66 |
-
|
| 67 |
-
--embeddings --pooling mean --embd-normalize 2 \
|
| 68 |
-
-ngl 0 -t 4 -tb 4 -c 512 -b 512 -ub 512 -np 1 \
|
| 69 |
-
--flash-attn off --host 127.0.0.1 --port 8080 --no-warmup
|
| 70 |
```
|
| 71 |
|
| 72 |
-
|
| 73 |
-
|
| 74 |
-
|
| 75 |
-
<summary>Embed a query and document with Python</summary>
|
| 76 |
-
|
| 77 |
-
The prefixes, special tokens and 512-token cap match the measured path. Run this in another terminal:
|
| 78 |
|
| 79 |
```python
|
| 80 |
import json
|
|
@@ -101,22 +120,15 @@ for text in texts:
|
|
| 101 |
print(len(vector)) # 768 for each input
|
| 102 |
```
|
| 103 |
|
| 104 |
-
Both
|
| 105 |
-
|
| 106 |
-
</details>
|
| 107 |
-
|
| 108 |
-
### Ollama
|
| 109 |
|
| 110 |
-
|
|
|
|
|
|
|
| 111 |
|
| 112 |
```bash
|
| 113 |
ollama pull turintech/embeddinggemma-2-artemis:q4_k_s
|
| 114 |
-
```
|
| 115 |
-
|
| 116 |
-
<details>
|
| 117 |
-
<summary>Embed a query and document with Ollama</summary>
|
| 118 |
-
|
| 119 |
-
```bash
|
| 120 |
curl http://localhost:11434/api/embed -H 'Content-Type: application/json' -d '{
|
| 121 |
"model": "turintech/embeddinggemma-2-artemis:q4_k_s",
|
| 122 |
"input": [
|
|
@@ -128,96 +140,114 @@ curl http://localhost:11434/api/embed -H 'Content-Type: application/json' -d '{
|
|
| 128 |
}'
|
| 129 |
```
|
| 130 |
|
| 131 |
-
|
| 132 |
-
|
| 133 |
-
</details>
|
| 134 |
|
| 135 |
-
|
|
|
|
|
|
|
| 136 |
|
| 137 |
-
|
|
|
|
|
|
|
| 138 |
|
| 139 |
</details>
|
| 140 |
|
| 141 |
-
<!--
|
| 142 |
-
## Choose this model
|
| 143 |
-
|
| 144 |
-
- Best for search and retrieval where a small download matters.
|
| 145 |
-
- Consider another file when you want the best measured retrieval: our Q5_K_S (182.04 MB) has higher nDCG and Recall than Unsloth Q4. The default's Recall@10 is 0.914856, against 0.920933 for Unsloth's Q4.
|
| 146 |
-
<!-- choose:end -->
|
| 147 |
-
|
| 148 |
-
## Files
|
| 149 |
-
|
| 150 |
-
<!-- files:start -->
|
| 151 |
-
Every file we publish for this model. Sizes are download sizes, not memory.
|
| 152 |
-
|
| 153 |
-
| File | Size | Use it for | Ollama tag |
|
| 154 |
-
| --- | --- | --- | --- |
|
| 155 |
-
| [`embeddinggemma-2-Artemis-Q4_K_S.gguf`](https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/embeddinggemma-2-Artemis-Q4_K_S.gguf) | 157 MB | Default: smaller download; measured Recall below Unsloth Q4 | `q4_k_s` (latest) |
|
| 156 |
-
| [`embeddinggemma-2-Artemis-Q5_K_S.gguf`](https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/embeddinggemma-2-Artemis-Q5_K_S.gguf) | 182 MB | Larger file with higher observed nDCG and Recall on the exposed development panel | `q5_k_s` |
|
| 157 |
-
|
| 158 |
-
- With llama.cpp or a Hugging Face pull, add the file's quant label as the tag: `-hf turintech/embeddinggemma-2-Artemis-GGUF:Q4_K_S`.
|
| 159 |
-
- The Ollama tag pulls our package, which holds the same file: `ollama pull turintech/embeddinggemma-2-artemis:<tag>`.
|
| 160 |
-
- LM Studio's Hub entry [`turintech/embeddinggemma-2-artemis`](https://lmstudio.ai/turintech/embeddinggemma-2-artemis) offers every model file above.
|
| 161 |
-
|
| 162 |
-
Smaller weights do not shrink the embedding index.
|
| 163 |
-
<!-- files:end -->
|
| 164 |
-
|
| 165 |
-
<!-- results:start -->
|
| 166 |
## Results
|
| 167 |
|
| 168 |
-
|
| 169 |
|
| 170 |
| File | Size | nDCG@10 | Recall@10 |
|
| 171 |
| --- | --- | --- | --- |
|
| 172 |
-
| **
|
| 173 |
-
| **
|
| 174 |
-
| Unsloth
|
| 175 |
-
|
|
| 176 |
-
|
| 177 |
-
The default is the smallest file and gives up a little Recall@10 against Unsloth's Q4. Peak RAM and GPU compatibility are not established yet. [How it was tested](#measured-retrieval-trade-offs).
|
| 178 |
-
<!-- results:end -->
|
| 179 |
|
| 180 |
-
|
| 181 |
-
<
|
| 182 |
|
| 183 |
-
|
|
|
|
| 184 |
|
| 185 |
-
|
|
|
|
|
|
|
|
|
|
| 186 |
|
| 187 |
-
|
|
|
|
| 188 |
|
| 189 |
-
|
|
|
|
| 190 |
|
| 191 |
-
|
| 192 |
-
|
| 193 |
-
|
| 194 |
-
| Unsloth Q4 | 175.674 | .857125 | .920933 |
|
| 195 |
-
| Artemis compact, recommended for size | **156.935** | .859481 | .914856 |
|
| 196 |
-
| Artemis larger alternative | 182.036 | **.872079** | **.928224** |
|
| 197 |
|
| 198 |
-
|
| 199 |
|
| 200 |
-
|
| 201 |
-
|
|
|
|
|
|
|
|
|
|
| 202 |
|
| 203 |
-
|
| 204 |
|
| 205 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 206 |
|
| 207 |
-
|
| 208 |
|
| 209 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 210 |
|
| 211 |
<!-- closeness:start -->
|
| 212 |
## Retrieval quality
|
| 213 |
|
| 214 |
-
The retrieval numbers from the tables
|
| 215 |
|
| 216 |
<details>
|
| 217 |
<summary>Protocols and standard tables</summary>
|
| 218 |
|
| 219 |
n/a means the card's tables or our run records do not have that value.
|
| 220 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 221 |
### Protocol `cpu-dev-panel-512-20261016`
|
| 222 |
|
| 223 |
Four CPU cores, 16 October 2026.
|
|
@@ -226,46 +256,50 @@ Four CPU cores, 16 October 2026.
|
|
| 226 |
- Panel `dev`: BEIR SciFact and FiQA development panel, equal-domain average; dataset: BEIR SciFact and FiQA; split: development queries from the train and dev relevance judgments; queries: 96 (48 per domain); documents: 1,024 (512 per domain); text SHA-256: 097270111c4e6a70cdf602a8416897bdb393c0bebdddf1ec7c6fcf29b2487cb1 (SHA-256 of the panel file)
|
| 227 |
- Tool: llama-server `/v1/embeddings` for the GGUF files; nDCG@10 and Recall@10 from dot-product ranking of the normalised 768-dimensional vectors, averaged equally over the SciFact and FiQA domains
|
| 228 |
- llama.cpp build: commit f3363593f457169cdfbdfe22ea399b1cc139ba18
|
| 229 |
-
- Command: `llama-server -m <file.gguf> --embeddings --pooling mean --embd-normalize 2 -ngl 0 -t 4 -c 2048 -b 2048 -ub 2048 -np 1 --flash-attn off`, inputs capped at 512 tokens by our harness
|
| 230 |
- Hardware: four CPU cores, no GPU
|
| 231 |
- Settings: 512-token input cap, mean pooling including prompts, query prefix `task: search result | query: `, documents as `title: ... | text: ...`
|
| 232 |
-
- Measured by: TurinTech measured every file in this table, including Unsloth's UD-Q4_K_XL, the same way on the same machine. Our numbers were measured on the raw quantizer outputs; the published files change only header metadata, with identical tensors
|
| 233 |
-
- Selection: this development panel was used to choose the files; it is not an independent test or a full MTEB evaluation
|
| 234 |
-
- Source on
|
| 235 |
- Comparison files: Unsloth: `unsloth/embeddinggemma-2-GGUF` at `031f0d4b3553`, `embeddinggemma-2-UD-Q4_K_XL.gguf`, SHA-256 ea905fd08e8061db77a0031cbb5096d459d7cfd2bdd0ad2ba66e483f16719493
|
| 236 |
|
| 237 |
Protocol `cpu-dev-panel-512-20261016`, panel `dev` (BEIR SciFact and FiQA development panel, equal-domain average):
|
| 238 |
|
| 239 |
| File | Repository | Measured by | Size (MB) | Size (bytes) | nDCG@10 | Recall@10 |
|
| 240 |
| --- | --- | --- | --- | --- | --- | --- |
|
| 241 |
-
|
|
| 242 |
-
| `embeddinggemma-2-UD-Q4_K_XL.gguf` | `unsloth/embeddinggemma-2-GGUF` at `031f0d4b3553` | TurinTech | 175.674 | 175673856 | 0.857125 | 0.920933 |
|
| 243 |
| `embeddinggemma-2-Artemis-Q4_K_S.gguf` | `turintech/embeddinggemma-2-Artemis-GGUF` at `2f1be8eeab0f` | TurinTech | 156.935 | 156935264 | 0.859481 | 0.914856 |
|
| 244 |
| `embeddinggemma-2-Artemis-Q5_K_S.gguf` | `turintech/embeddinggemma-2-Artemis-GGUF` at `2f1be8eeab0f` | TurinTech | 182.036 | 182035552 | 0.872079 | 0.928224 |
|
|
|
|
| 245 |
|
| 246 |
</details>
|
| 247 |
<!-- closeness:end -->
|
| 248 |
|
| 249 |
-
|
| 250 |
-
|
| 251 |
-
|
| 252 |
|
| 253 |
-
| File | Bytes |
|
| 254 |
-
|---|---
|
| 255 |
| `embeddinggemma-2-Artemis-Q4_K_S.gguf` | 156,935,264 | `f76351ba13988274750620577c88911b195a15321c37fc991bed485ed8f81f45` |
|
| 256 |
| `embeddinggemma-2-Artemis-Q5_K_S.gguf` | 182,035,552 | `476a432281b3c9c8f16b5286bbe1aa482357e4b15fe69c3f8008ade36fd8f381` |
|
| 257 |
|
| 258 |
-
|
| 259 |
-
|
| 260 |
|
| 261 |
-
|
|
|
|
| 262 |
|
| 263 |
-
|
| 264 |
|
| 265 |
-
|
| 266 |
|
| 267 |
-
|
|
|
|
|
|
|
| 268 |
|
| 269 |
-
|
| 270 |
|
| 271 |
-
|
|
|
|
|
|
| 2 |
license: apache-2.0
|
| 3 |
base_model: google/embeddinggemma-2
|
| 4 |
base_model_relation: quantized
|
| 5 |
+
library_name: gguf
|
| 6 |
pipeline_tag: sentence-similarity
|
| 7 |
tags:
|
| 8 |
+
- turintech
|
| 9 |
+
- artemis
|
| 10 |
+
- embeddinggemma
|
| 11 |
- embeddings
|
| 12 |
+
- retrieval
|
| 13 |
+
- gguf
|
| 14 |
+
- llama.cpp
|
| 15 |
+
- quantized
|
| 16 |
---
|
| 17 |
|
| 18 |
+
<!-- v2-header:start -->
|
| 19 |
+
<div align="center">
|
| 20 |
+
|
| 21 |
+
<a href="https://www.turintech.ai"><img src="https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/assets/turintech-logo-v2.png" width="360" alt="TurinTech"></a>
|
| 22 |
|
| 23 |
+
<em>TurinTech models, built with Artemis</em>
|
| 24 |
|
| 25 |
+
### EmbeddingGemma 2 for search and retrieval on a CPU, compressed with Artemis
|
| 26 |
+
|
| 27 |
+
<div style="display: flex; flex-wrap: wrap; justify-content: center; align-items: center; gap: 6px;">
|
| 28 |
+
<a href="https://www.turintech.ai"><img src="https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/assets/buttons/artemis.png" width="84" alt="Artemis"></a>
|
| 29 |
+
<a href="https://huggingface.co/turintech"><img src="https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/assets/buttons/other-models.png" width="122" alt="Other TurinTech models on Hugging Face"></a>
|
| 30 |
+
<a href="https://ollama.com/turintech/embeddinggemma-2-artemis"><img src="https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/assets/buttons/ollama.png" width="78" alt="Run it with Ollama"></a>
|
| 31 |
+
<a href="https://lmstudio.ai/turintech/embeddinggemma-2-artemis"><img src="https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/assets/buttons/lm-studio.png" width="99" alt="Run it in LM Studio"></a>
|
| 32 |
+
<a href="https://www.linkedin.com/company/turintechai"><img src="https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/assets/buttons/turintech.png" width="98" alt="TurinTech on LinkedIn"></a>
|
| 33 |
+
</div>
|
| 34 |
+
|
| 35 |
+
| Download | Peak CPU memory | Recall@10, BEIR test |
|
| 36 |
+
| :---: | :---: | :---: |
|
| 37 |
+
| **156.935 MB** | **0.339 GiB** | **0.6588** (Unsloth UD-Q4_K_XL 0.6427) |
|
| 38 |
+
|
| 39 |
+
</div>
|
| 40 |
+
<!-- v2-header:end -->
|
| 41 |
|
| 42 |
## Run it
|
| 43 |
|
| 44 |
+
An embedding model: it turns a query or a document into a 768-dimensional vector for search and retrieval, served on
|
| 45 |
+
llama-server's `/v1/embeddings` endpoint. It does not chat.
|
| 46 |
|
| 47 |
```bash
|
| 48 |
+
hf download turintech/embeddinggemma-2-Artemis-GGUF embeddinggemma-2-Artemis-Q4_K_S.gguf --local-dir .
|
| 49 |
+
llama-server -m embeddinggemma-2-Artemis-Q4_K_S.gguf --embeddings --pooling mean --embd-normalize 2 \
|
| 50 |
+
-ngl 0 -t 4 -tb 4 -c 512 -b 512 -ub 512 -np 1 --flash-attn off --host 127.0.0.1 --port 8080 --no-warmup
|
|
|
|
|
|
|
| 51 |
```
|
| 52 |
|
| 53 |
+
<!-- v2-apps:start -->
|
| 54 |
+
Ollama: [`turintech/embeddinggemma-2-artemis`](https://ollama.com/turintech/embeddinggemma-2-artemis) on `/api/embed`, as in Run it · LM Studio: [`turintech/embeddinggemma-2-artemis`](https://lmstudio.ai/turintech/embeddinggemma-2-artemis)
|
| 55 |
+
<!-- v2-apps:end -->
|
| 56 |
|
| 57 |
+
`llama-server` here is llama.cpp at commit `f3363593`, built for the CPU as in the folded section below. Other
|
| 58 |
+
llama.cpp builds and GPUs have not been checked with these files; Ollama and LM Studio were checked as described there.
|
| 59 |
+
Queries take the prefix `task: search result | query: ` and documents the form `title: ... | text: ...`; every result
|
| 60 |
+
below was measured with them, mean pooling and inputs of at most 512 tokens.
|
| 61 |
|
| 62 |
+
<details>
|
| 63 |
+
<summary>Build the runtime, embed with Python, check the download, Ollama and LM Studio</summary>
|
| 64 |
|
| 65 |
+
On Linux x86-64, install Git, CMake, a C/C++ compiler and OpenMP development support with the system package manager
|
| 66 |
+
([upstream build instructions at this commit](https://github.com/ggml-org/llama.cpp/blob/f3363593f457169cdfbdfe22ea399b1cc139ba18/docs/build.md)).
|
| 67 |
+
These are the source commit and CMake options of our CPU build; another compiler or CPU can give different binaries,
|
| 68 |
+
and other platforms have not been checked. Run it in a directory without a `llama-cpp-embeddinggemma2` folder:
|
| 69 |
|
| 70 |
```bash
|
| 71 |
set -e
|
|
|
|
| 82 |
llama-server --version
|
| 83 |
```
|
| 84 |
|
| 85 |
+
Keep the build directory and its libraries together. `GGML_NATIVE=ON` targets the CPU of the build machine, so the
|
| 86 |
+
binaries may not run on another CPU.
|
| 87 |
|
| 88 |
+
Check the download against its checksum:
|
|
|
|
|
|
|
| 89 |
|
| 90 |
```bash
|
| 91 |
+
printf '%s %s\n' f76351ba13988274750620577c88911b195a15321c37fc991bed485ed8f81f45 embeddinggemma-2-Artemis-Q4_K_S.gguf | sha256sum -c -
|
|
|
|
|
|
|
|
|
|
| 92 |
```
|
| 93 |
|
| 94 |
+
For the larger file, download `embeddinggemma-2-Artemis-Q5_K_S.gguf` by its exact name with the same `hf download`
|
| 95 |
+
command; automatic Hugging Face imports have not been checked. With the server running, embed a query and a document
|
| 96 |
+
from another terminal:
|
|
|
|
|
|
|
|
|
|
| 97 |
|
| 98 |
```python
|
| 99 |
import json
|
|
|
|
| 120 |
print(len(vector)) # 768 for each input
|
| 121 |
```
|
| 122 |
|
| 123 |
+
Both files passed this two-input check on the CPU build above. The snippet keeps the first 512 tokens of a long text;
|
| 124 |
+
the test run kept the first 511 and the end token, as sentence-transformers does.
|
|
|
|
|
|
|
|
|
|
| 125 |
|
| 126 |
+
Ollama (0.40.4 tested) serves the package on `/api/embed`. `latest` and `q4_k_s` hold the default file, `q5_k_s` the
|
| 127 |
+
182.04 MB file; both files passed a public pull, a full checksum and a two-input CPU embedding check. The retrieval
|
| 128 |
+
numbers on this card come from llama.cpp, not Ollama.
|
| 129 |
|
| 130 |
```bash
|
| 131 |
ollama pull turintech/embeddinggemma-2-artemis:q4_k_s
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 132 |
curl http://localhost:11434/api/embed -H 'Content-Type: application/json' -d '{
|
| 133 |
"model": "turintech/embeddinggemma-2-artemis:q4_k_s",
|
| 134 |
"input": [
|
|
|
|
| 140 |
}'
|
| 141 |
```
|
| 142 |
|
| 143 |
+
This request runs on the CPU and rejects an input longer than the context instead of cutting it. Ollama lists both
|
| 144 |
+
tags as `Q4_K_M`, a label the files inherit from their headers; the tags and checksums identify the files.
|
|
|
|
| 145 |
|
| 146 |
+
LM Studio (0.4.26 tested, CPU engine 2.64.0) loaded the Hub entry
|
| 147 |
+
[turintech/embeddinggemma-2-artemis](https://lmstudio.ai/turintech/embeddinggemma-2-artemis) with the default file on
|
| 148 |
+
25 October 2026, and its `/v1/embeddings` on port 1234 returned 768-dimensional vectors:
|
| 149 |
|
| 150 |
+
```bash
|
| 151 |
+
lms get turintech/embeddinggemma-2-artemis@q4_k_s --gguf
|
| 152 |
+
```
|
| 153 |
|
| 154 |
</details>
|
| 155 |
|
| 156 |
+
<!-- v2-results:start -->
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 157 |
## Results
|
| 158 |
|
| 159 |
+

|
| 160 |
|
| 161 |
| File | Size | nDCG@10 | Recall@10 |
|
| 162 |
| --- | --- | --- | --- |
|
| 163 |
+
| [**TurinTech Q4_K_S**](https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/embeddinggemma-2-Artemis-Q4_K_S.gguf) | 156.935 MB | 0.5754 | **0.6588** |
|
| 164 |
+
| [**TurinTech Q5_K_S**](https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/embeddinggemma-2-Artemis-Q5_K_S.gguf) | 182.036 MB | 0.5790 | 0.6538 |
|
| 165 |
+
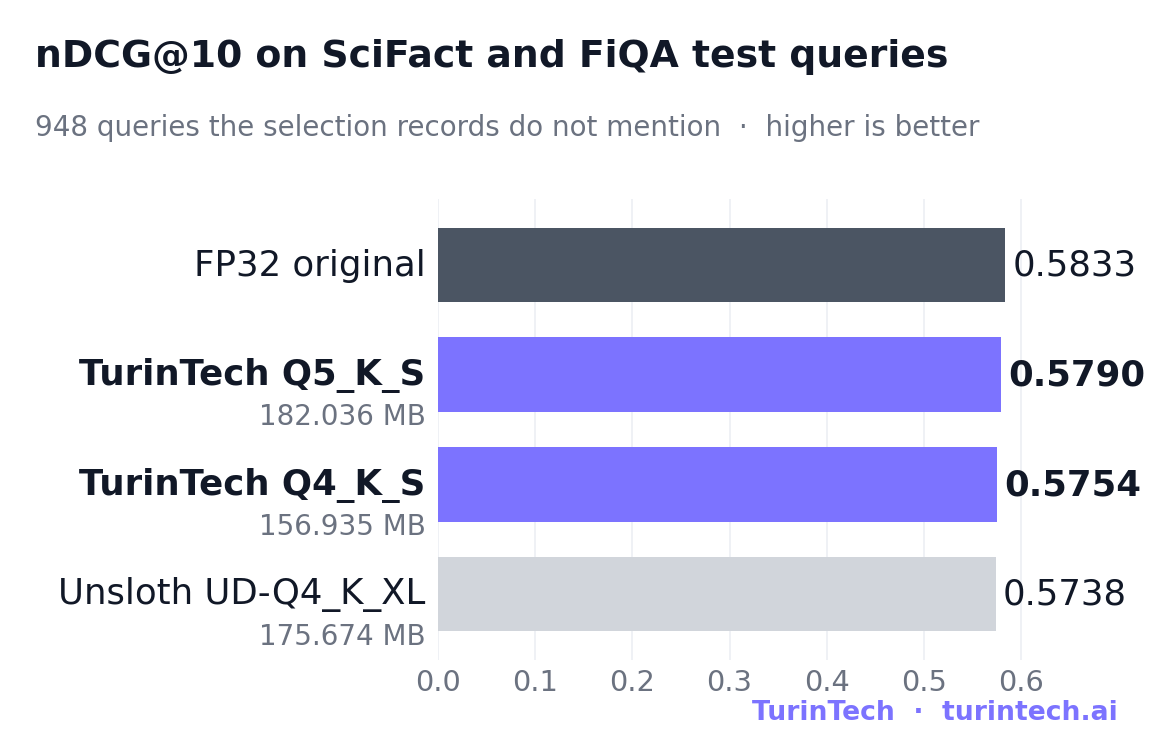
| Unsloth UD-Q4_K_XL | 175.674 MB | 0.5738 | 0.6427 |
|
| 166 |
+
| FP32 original | n/a | **0.5833** | 0.6541 |
|
|
|
|
|
|
|
|
|
|
| 167 |
|
| 168 |
+
Equal-weight means of SciFact (300 queries, 5,183 documents) and FiQA (648 queries, 57,638 documents): BEIR test queries, each ranked against its dataset's full corpus. The records of how the files were chosen do not mention these queries ([How it was tested](#how-it-was-tested)); bold marks the best in each column, not a tested difference. One gap holds after correcting for four planned tests: Recall@10 of our Q4_K_S over Unsloth's UD-Q4_K_XL (0.6588 against 0.6427, Bonferroni p 0.043). The default's nDCG@10 did not separate from Unsloth's file (0.5754 against 0.5738) or from the original (0.5833), and the plan did not test our Q5_K_S. [Full results, memory and method](RESULTS.md).
|
| 169 |
+
<!-- v2-results:end -->
|
| 170 |
|
| 171 |
+
<!-- v2-files:start -->
|
| 172 |
+
## Files
|
| 173 |
|
| 174 |
+
| File | Size | Peak CPU memory | Use it for |
|
| 175 |
+
| --- | --- | --- | --- |
|
| 176 |
+
| [`embeddinggemma-2-Artemis-Q4_K_S.gguf`](https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/embeddinggemma-2-Artemis-Q4_K_S.gguf) | 157 MB | 0.339 GiB | Default: the smaller download, Ollama tag `q4_k_s` (latest) |
|
| 177 |
+
| [`embeddinggemma-2-Artemis-Q5_K_S.gguf`](https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/main/embeddinggemma-2-Artemis-Q5_K_S.gguf) | 182 MB | 0.359 GiB | Larger file with higher measured nDCG@10 than the default, Ollama tag `q5_k_s` |
|
| 178 |
|
| 179 |
+
Text only. Smaller weights do not shrink the embedding index, which stores 768 values per text. The memory figures come from a 2,048-token context and batch; the 512-token settings in Run it were not measured. Peak CPU memory measured on AMD Ryzen 9 5900X, CPU only, 12 threads, llama.cpp f3363593 CPU build, -c 2048 -b 2048 -ub 2048 -np 1 --flash-attn off --no-warmup, peak resident memory over the 300 SciFact test queries in requests of up to 16, the memory-mapped file included.
|
| 180 |
+
<!-- v2-files:end -->
|
| 181 |
|
| 182 |
+
<!-- v2-pick:start -->
|
| 183 |
+
## Pick this model
|
| 184 |
|
| 185 |
+
- **Good for** search and retrieval on a CPU in a 156.935 MB download. On 948 test queries its Recall@10 was higher than that of Unsloth's 175.674 MB UD-Q4_K_XL (0.6588 against 0.6427), and its nDCG@10 did not separate from that file or the original.
|
| 186 |
+
- **Pick another file** when nDCG@10 matters more than download size: our Q5_K_S (182.036 MB) scored nDCG@10 0.5790 against the default's 0.5754 but Recall@10 0.6538 against 0.6588, and no planned test covers either gap.
|
| 187 |
+
<!-- v2-pick:end -->
|
|
|
|
|
|
|
|
|
|
| 188 |
|
| 189 |
+
## How it was made
|
| 190 |
|
| 191 |
+
Built with [Artemis](https://www.turintech.ai/product/overview), TurinTech's optimisation platform, from Google's
|
| 192 |
+
[EmbeddingGemma 2](https://huggingface.co/google/embeddinggemma-2) at revision `914f7f8`. Each file is a per-tensor mix
|
| 193 |
+
of standard llama.cpp quant types, so the llama.cpp build above, Ollama and LM Studio load it as it is. Its label is a
|
| 194 |
+
size class: the Q4_K_S file is smaller than a stock Q4_K_S file of this model, the Q5_K_S file smaller than a stock
|
| 195 |
+
Q5_K_S. The tensor types and bits per weight are on the [results page](RESULTS.md). Text only.
|
| 196 |
|
| 197 |
+
## How it was tested
|
| 198 |
|
| 199 |
+
Every file in the Results table ran on one AMD Ryzen 9 5900X with no GPU (12 threads) on 27 and 28 October 2026: the
|
| 200 |
+
GGUF files through llama-server at llama.cpp `f3363593`, the FP32 original through sentence-transformers, with the
|
| 201 |
+
same prompts, 512-token cap, mean pooling and normalisation. The queries are all 948 BEIR test queries of SciFact and
|
| 202 |
+
FiQA that have a relevance judgment, each ranked against the full corpus of its dataset. Before scoring, a BF16
|
| 203 |
+
conversion of the original on the same llama-server gave the same vectors as the FP32 original on 128 of the queries,
|
| 204 |
+
to a worst cosine error of 8.3e-06.
|
| 205 |
|
| 206 |
+
### Measured retrieval trade-offs
|
| 207 |
|
| 208 |
+
The files were chosen on a development panel of 96 queries from the train and dev relevance judgments of the same two
|
| 209 |
+
datasets, with 1,024 of their documents. The records of how the files were chosen mention only that panel; they do not
|
| 210 |
+
mention the test queries. On the development panel the default had a little lower Recall@10 than Unsloth's file
|
| 211 |
+
(0.914856 against 0.920933); on the test queries it was higher (0.6588 against 0.6427), the one gap that holds after a
|
| 212 |
+
Bonferroni correction over the four tests the run planned. nDCG@10 did not separate from Unsloth's file or from the
|
| 213 |
+
original. The [results page](RESULTS.md) has the method, the scores per dataset, the paired tests, peak memory and the
|
| 214 |
+
development panel.
|
| 215 |
|
| 216 |
<!-- closeness:start -->
|
| 217 |
## Retrieval quality
|
| 218 |
|
| 219 |
+
The retrieval numbers from the tables on the [results page](RESULTS.md), in one fixed layout with the protocol behind each table. nDCG@10 and Recall@10 score the ranking against the panel's relevance labels; higher is better.
|
| 220 |
|
| 221 |
<details>
|
| 222 |
<summary>Protocols and standard tables</summary>
|
| 223 |
|
| 224 |
n/a means the card's tables or our run records do not have that value.
|
| 225 |
|
| 226 |
+
### Protocol `cpu-beir-test-512-20261027`
|
| 227 |
+
|
| 228 |
+
AMD Ryzen 9 5900X, CPU only, 27 and 28 October 2026.
|
| 229 |
+
|
| 230 |
+
- Reference: the original google/embeddinggemma-2 FP32 checkpoint (revision 914f7f89142e33e77833254d9c9b90c3cef7303b) through sentence-transformers 6.2.0 and PyTorch 2.14.1 on the same CPU, mean pooling, L2-normalised; it is not a GGUF. A BF16 GGUF conversion served by the same llama-server matched its vectors on 128 test queries (mean cosine error 2.9e-06, worst 8.3e-06)
|
| 231 |
+
- Panel `test`: BEIR SciFact and FiQA test queries, full corpora, equal-domain average; dataset: BEIR SciFact (BeIR/scifact at b3b5335604bf5ee3c4447671af975ea25143d4f5, judgments BeIR/scifact-qrels at 2938d17dc3b09882fdb8c12bbbe2e2dc0e75a029) and FiQA (BeIR/fiqa at 979c07a7cb5ccc6ca009792241fa1250b98055dd, judgments BeIR/fiqa-qrels at 252958f2d646e22cab6d0c72dd3f0d5de6d0655a); split: test relevance judgments (test.tsv); every query with at least one positive judgment; queries: 948 (SciFact 300, FiQA 648); documents: 62,821, the full corpora (SciFact 5,183, FiQA 57,638); text SHA-256: 37688fe561f82a27b54e556d1e3b41b5d340df3ead021039d7c9681cb052c41f (SHA-256 of the panel file; content digest 904fd90350ab83bcd1edc11aa893353f3352bbbc59583b24385d0ab32f54e4eb)
|
| 232 |
+
- Tool: llama-server `/v1/embeddings` for the GGUF files, each text sent as the server's own token ids; cosine ranking within each dataset (ties by ascending document id), linear-gain nDCG@10 and Recall@10, averaged equally over SciFact and FiQA
|
| 233 |
+
- llama.cpp build: commit f3363593f457169cdfbdfe22ea399b1cc139ba18, CPU build from source (its version line reads build 1, commit f336359)
|
| 234 |
+
- Command: `llama-server -m <file.gguf> --embeddings --pooling mean --embd-normalize 2 -ngl 0 -t 12` (the flags the run record lists), 16 texts per request
|
| 235 |
+
- Hardware: AMD Ryzen 9 5900X 12-Core Processor, 12 threads, no GPU
|
| 236 |
+
- Settings: 512-token cap (a longer text keeps its first 511 tokens and the end token, as sentence-transformers cuts it; 2,890 of the 63,769 texts reached the cap), mean pooling including prompts, query prefix `task: search result | query: `, documents as `title: <title, or none> | text: <text>`
|
| 237 |
+
- Measured by: TurinTech measured every GGUF file in this table, including Unsloth's UD-Q4_K_XL, the same way on the same machine, each once, and the original through sentence-transformers on that machine; the GGUF files measured are the published ones
|
| 238 |
+
- Selection: the records of how the files were chosen do not mention these test queries; the files were chosen on the development panel of protocol cpu-dev-panel-512-20261016, whose documents come from the same two corpora
|
| 239 |
+
- Source, on the results page: the table columns "nDCG@10", "Recall@10"
|
| 240 |
+
- Comparison files: Unsloth: `unsloth/embeddinggemma-2-GGUF` at `031f0d4b3553`, `embeddinggemma-2-UD-Q4_K_XL.gguf`, SHA-256 ea905fd08e8061db77a0031cbb5096d459d7cfd2bdd0ad2ba66e483f16719493
|
| 241 |
+
|
| 242 |
+
Protocol `cpu-beir-test-512-20261027`, panel `test` (BEIR SciFact and FiQA test queries, full corpora, equal-domain average):
|
| 243 |
+
|
| 244 |
+
| File | Repository | Measured by | Size (MB) | Size (bytes) | nDCG@10 | Recall@10 |
|
| 245 |
+
| --- | --- | --- | --- | --- | --- | --- |
|
| 246 |
+
| FP32 original | `google/embeddinggemma-2` at `914f7f89142e` | reference | n/a | n/a | 0.5833 | 0.6541 |
|
| 247 |
+
| `embeddinggemma-2-Artemis-Q4_K_S.gguf` | `turintech/embeddinggemma-2-Artemis-GGUF` at `8748160053b5` | TurinTech | 156.935 | 156935264 | 0.5754 | 0.6588 |
|
| 248 |
+
| `embeddinggemma-2-Artemis-Q5_K_S.gguf` | `turintech/embeddinggemma-2-Artemis-GGUF` at `8748160053b5` | TurinTech | 182.036 | 182035552 | 0.5790 | 0.6538 |
|
| 249 |
+
| `embeddinggemma-2-UD-Q4_K_XL.gguf` | `unsloth/embeddinggemma-2-GGUF` at `031f0d4b3553` | TurinTech | 175.674 | 175673856 | 0.5738 | 0.6427 |
|
| 250 |
+
|
| 251 |
### Protocol `cpu-dev-panel-512-20261016`
|
| 252 |
|
| 253 |
Four CPU cores, 16 October 2026.
|
|
|
|
| 256 |
- Panel `dev`: BEIR SciFact and FiQA development panel, equal-domain average; dataset: BEIR SciFact and FiQA; split: development queries from the train and dev relevance judgments; queries: 96 (48 per domain); documents: 1,024 (512 per domain); text SHA-256: 097270111c4e6a70cdf602a8416897bdb393c0bebdddf1ec7c6fcf29b2487cb1 (SHA-256 of the panel file)
|
| 257 |
- Tool: llama-server `/v1/embeddings` for the GGUF files; nDCG@10 and Recall@10 from dot-product ranking of the normalised 768-dimensional vectors, averaged equally over the SciFact and FiQA domains
|
| 258 |
- llama.cpp build: commit f3363593f457169cdfbdfe22ea399b1cc139ba18
|
| 259 |
+
- Command: `llama-server -m <file.gguf> --embeddings --pooling mean --embd-normalize 2 -ngl 0 -t 4 -c 2048 -b 2048 -ub 2048 -np 1 --flash-attn off`, inputs capped at 512 tokens by our harness
|
| 260 |
- Hardware: four CPU cores, no GPU
|
| 261 |
- Settings: 512-token input cap, mean pooling including prompts, query prefix `task: search result | query: `, documents as `title: ... | text: ...`
|
| 262 |
+
- Measured by: TurinTech measured every GGUF file in this table, including Unsloth's UD-Q4_K_XL, the same way on the same machine. Our numbers were measured on the raw quantizer outputs; the published files change only header metadata, with identical tensors
|
| 263 |
+
- Selection: this development panel was used to choose the files, so it favours them; it is not an independent test or a full MTEB evaluation
|
| 264 |
+
- Source, on the results page: the table columns "nDCG@10, development panel", "Recall@10, development panel"
|
| 265 |
- Comparison files: Unsloth: `unsloth/embeddinggemma-2-GGUF` at `031f0d4b3553`, `embeddinggemma-2-UD-Q4_K_XL.gguf`, SHA-256 ea905fd08e8061db77a0031cbb5096d459d7cfd2bdd0ad2ba66e483f16719493
|
| 266 |
|
| 267 |
Protocol `cpu-dev-panel-512-20261016`, panel `dev` (BEIR SciFact and FiQA development panel, equal-domain average):
|
| 268 |
|
| 269 |
| File | Repository | Measured by | Size (MB) | Size (bytes) | nDCG@10 | Recall@10 |
|
| 270 |
| --- | --- | --- | --- | --- | --- | --- |
|
| 271 |
+
| FP32 original | `google/embeddinggemma-2` at `914f7f89142e` | reference | n/a | n/a | 0.856404 | 0.928224 |
|
|
|
|
| 272 |
| `embeddinggemma-2-Artemis-Q4_K_S.gguf` | `turintech/embeddinggemma-2-Artemis-GGUF` at `2f1be8eeab0f` | TurinTech | 156.935 | 156935264 | 0.859481 | 0.914856 |
|
| 273 |
| `embeddinggemma-2-Artemis-Q5_K_S.gguf` | `turintech/embeddinggemma-2-Artemis-GGUF` at `2f1be8eeab0f` | TurinTech | 182.036 | 182035552 | 0.872079 | 0.928224 |
|
| 274 |
+
| `embeddinggemma-2-UD-Q4_K_XL.gguf` | `unsloth/embeddinggemma-2-GGUF` at `031f0d4b3553` | TurinTech | 175.674 | 175673856 | 0.857125 | 0.920933 |
|
| 275 |
|
| 276 |
</details>
|
| 277 |
<!-- closeness:end -->
|
| 278 |
|
| 279 |
+
<!-- v2-checksums:start -->
|
| 280 |
+
<details>
|
| 281 |
+
<summary>File checksums</summary>
|
| 282 |
|
| 283 |
+
| File | Bytes | sha256 |
|
| 284 |
+
| --- | --- | --- |
|
| 285 |
| `embeddinggemma-2-Artemis-Q4_K_S.gguf` | 156,935,264 | `f76351ba13988274750620577c88911b195a15321c37fc991bed485ed8f81f45` |
|
| 286 |
| `embeddinggemma-2-Artemis-Q5_K_S.gguf` | 182,035,552 | `476a432281b3c9c8f16b5286bbe1aa482357e4b15fe69c3f8008ade36fd8f381` |
|
| 287 |
|
| 288 |
+
</details>
|
| 289 |
+
<!-- v2-checksums:end -->
|
| 290 |
|
| 291 |
+
<!-- v2-footer:start -->
|
| 292 |
+
---
|
| 293 |
|
| 294 |
+
<div align="center">
|
| 295 |
|
| 296 |
+
[Artemis](https://www.turintech.ai/product/overview) is TurinTech's optimisation platform: teams use it to make their own models smaller and faster, or to optimise their code.
|
| 297 |
|
| 298 |
+
[All our models](https://www.turintech.ai/models) · [LinkedIn](https://www.linkedin.com/company/turintechai) · [Questions and requests](https://huggingface.co/spaces/turintech/README/discussions/1)
|
| 299 |
+
|
| 300 |
+
<sub>Apache 2.0, as released by Google ([licence](https://www.apache.org/licenses/LICENSE-2.0)); see `LICENSE` and `NOTICE`. An independent TurinTech release, not affiliated with or endorsed by Google. When serving these files to others, for example through an API, an inference provider or OpenRouter, we'd appreciate a mention of TurinTech (turintech.ai) as the source of the quantization.</sub>
|
| 301 |
|
| 302 |
+
These files keep improving.
|
| 303 |
|
| 304 |
+
</div>
|
| 305 |
+
<!-- v2-footer:end -->
|
RESULTS.md
ADDED
|
@@ -0,0 +1,143 @@
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
+
# EmbeddingGemma 2 Artemis GGUF: full results and method
|
| 2 |
+
|
| 3 |
+
Everything behind the numbers on the [model card](README.md): the BEIR test queries the card reports, with the
|
| 4 |
+
paired tests, peak memory and the encoder check, then the development panel the files were chosen on.
|
| 5 |
+
|
| 6 |
+
## BEIR test queries, AMD Ryzen 9 5900X, 27 and 28 October 2026
|
| 7 |
+
|
| 8 |
+
The numbers on the card come from this run.
|
| 9 |
+
|
| 10 |
+
AMD Ryzen 9 5900X 12-Core Processor, CPU only, 12 threads. The queries are every BEIR test query of SciFact and FiQA
|
| 11 |
+
with at least one positive relevance judgment, 948 in all (SciFact 300, FiQA 648), and each is ranked against the full
|
| 12 |
+
corpus of its dataset (SciFact 5,183 documents, FiQA 57,638). The datasets are pinned to `BeIR/scifact` at
|
| 13 |
+
`b3b5335604bf5ee3c4447671af975ea25143d4f5` with the `test.tsv` judgments of `BeIR/scifact-qrels` at
|
| 14 |
+
`2938d17dc3b09882fdb8c12bbbe2e2dc0e75a029`, and `BeIR/fiqa` at `979c07a7cb5ccc6ca009792241fa1250b98055dd` with those of
|
| 15 |
+
`BeIR/fiqa-qrels` at `252958f2d646e22cab6d0c72dd3f0d5de6d0655a`. Texts take the prompts in Run it, `task: search result
|
| 16 |
+
| query: <text>` for a query and `title: <title, or none> | text: <text>` for a document. Each text is tokenized with
|
| 17 |
+
its special tokens and capped at 512 tokens; a longer text keeps its first 511 tokens and the end token, as
|
| 18 |
+
sentence-transformers cuts it (2,890 of the 63,769 texts reached the cap). Vectors are mean-pooled over every token,
|
| 19 |
+
prompt included, and L2-normalised to 768 dimensions. Each query ranks its own dataset's documents by cosine
|
| 20 |
+
similarity (ties by ascending document id). nDCG@10 (linear gain) and Recall@10 are averaged over the queries of each
|
| 21 |
+
dataset, and the card's numbers are the mean of the two datasets with equal weight.
|
| 22 |
+
|
| 23 |
+
The GGUF files ran on llama-server at llama.cpp `f3363593f457169cdfbdfe22ea399b1cc139ba18` (the commit Run it
|
| 24 |
+
builds), `llama-server -m <file> --embeddings --pooling mean --embd-normalize 2 -ngl 0 -t 12`, with each text sent as
|
| 25 |
+
the server's own token ids, 16 texts per request. The original, `google/embeddinggemma-2` at
|
| 26 |
+
`914f7f89142e33e77833254d9c9b90c3cef7303b` (`model.safetensors` SHA-256
|
| 27 |
+
`197a32965d4b1105faf060417baa899e193fb73cd401f42ec9295234d5553d79`), ran at FP32 through sentence-transformers 6.2.0
|
| 28 |
+
and PyTorch 2.14.1 on the same CPU with `max_seq_length` 512. The files measured are the published ones (SHA-256 in
|
| 29 |
+
the card's checksums) and Unsloth's `embeddinggemma-2-UD-Q4_K_XL.gguf` from `unsloth/embeddinggemma-2-GGUF` at
|
| 30 |
+
`031f0d4b35536f69ab3509d4893c923264fcf253` (SHA-256 `ea905fd08e8061db77a0031cbb5096d459d7cfd2bdd0ad2ba66e483f16719493`).
|
| 31 |
+
TurinTech measured every file the same way on the same machine, each once.
|
| 32 |
+
|
| 33 |
+
The files were chosen on the development panel further down, 96 queries from the train and dev relevance judgments of
|
| 34 |
+
the same two datasets with 1,024 of their documents. The records of how the files were chosen mention only that panel;
|
| 35 |
+
they do not mention these test queries. Both panels draw their documents from the same two corpora.
|
| 36 |
+
|
| 37 |
+
### Results
|
| 38 |
+
|
| 39 |
+
| File | Size | nDCG@10 | Recall@10 | SciFact nDCG@10 | SciFact Recall@10 | FiQA nDCG@10 | FiQA Recall@10 |
|
| 40 |
+
| --- | --- | --- | --- | --- | --- | --- | --- |
|
| 41 |
+
| TurinTech Q4_K_S | 156.935 MB | 0.5754 | 0.6588 | 0.8372 | 0.9413 | 0.3137 | 0.3763 |
|
| 42 |
+
| TurinTech Q5_K_S | 182.036 MB | 0.5790 | 0.6538 | 0.8455 | 0.9410 | 0.3125 | 0.3667 |
|
| 43 |
+
| Unsloth UD-Q4_K_XL | 175.674 MB | 0.5738 | 0.6427 | 0.8416 | 0.9337 | 0.3061 | 0.3518 |
|
| 44 |
+
| FP32 original | n/a | 0.5833 | 0.6541 | 0.8544 | 0.9403 | 0.3122 | 0.3680 |
|
| 45 |
+
|
| 46 |
+
Sizes are download sizes in decimal MB; n/a for the original, which ran as a safetensors checkpoint. No bold here: the
|
| 47 |
+
paired tests below decide what differs. The two datasets pull in different directions: on SciFact our Q4_K_S ranked a
|
| 48 |
+
little below Unsloth's file (nDCG@10 0.8372 against 0.8416), on FiQA a little above (0.3137 against 0.3061).
|
| 49 |
+
|
| 50 |
+
### Paired tests
|
| 51 |
+
|
| 52 |
+
A paired bootstrap over queries: 10,000 resamples with seed 20261027, queries drawn with replacement within each
|
| 53 |
+
dataset (dataset sizes kept), the equal-weight mean recomputed each time. The interval is the 2.5th to 97.5th
|
| 54 |
+
percentile of the resampled differences; p is two-sided (twice the smaller share of resampled differences on either
|
| 55 |
+
side of zero, at most 1). The plan for the run named two comparisons, our default against Unsloth's file and against
|
| 56 |
+
the original, on two metrics: four tests. It set no correction for multiple tests; this page applies Bonferroni over
|
| 57 |
+
the four, so a difference is stated only when the corrected p is below 0.05 (p below 0.0125).
|
| 58 |
+
|
| 59 |
+
| Comparison | Metric | First | Second | Difference | 95% interval | p | Bonferroni p (x4) | Queries first better / second better |
|
| 60 |
+
| --- | --- | --- | --- | --- | --- | --- | --- | --- |
|
| 61 |
+
| TurinTech Q4_K_S vs Unsloth UD-Q4_K_XL | nDCG@10 | 0.5754 | 0.5738 | +0.0016 | -0.0072 to +0.0105 | 0.716 (not significant) | 1.00 (not significant) | 155 / 139 |
|
| 62 |
+
| TurinTech Q4_K_S vs Unsloth UD-Q4_K_XL | Recall@10 | 0.6588 | 0.6427 | +0.0161 | +0.0038 to +0.0287 | 0.0108 | 0.043 | 64 / 34 |
|
| 63 |
+
| TurinTech Q4_K_S vs FP32 original | nDCG@10 | 0.5754 | 0.5833 | -0.0079 | -0.0165 to +0.0005 | 0.067 (not significant) | 0.27 (not significant) | 143 / 150 |
|
| 64 |
+
| TurinTech Q4_K_S vs FP32 original | Recall@10 | 0.6588 | 0.6541 | +0.0047 | -0.0062 to +0.0155 | 0.399 (not significant) | 1.00 (not significant) | 43 / 39 |
|
| 65 |
+
|
| 66 |
+
One difference holds: Recall@10 of our Q4_K_S over Unsloth's UD-Q4_K_XL. Our Q5_K_S was not in the plan, so its gaps
|
| 67 |
+
to the other files are descriptive only.
|
| 68 |
+
|
| 69 |
+
### Peak CPU memory
|
| 70 |
+
|
| 71 |
+
| File | Peak CPU memory, GiB | Peak CPU memory, MiB |
|
| 72 |
+
| --- | --- | --- |
|
| 73 |
+
| TurinTech Q4_K_S | 0.339 | 346.8 |
|
| 74 |
+
| TurinTech Q5_K_S | 0.359 | 367.4 |
|
| 75 |
+
| Unsloth UD-Q4_K_XL | 0.362 | 371.0 |
|
| 76 |
+
| BF16 conversion of the original | 0.657 | 672.8 |
|
| 77 |
+
|
| 78 |
+
A fresh llama-server per file, `llama-server -m <file> --embeddings --pooling mean --embd-normalize 2 -ngl 0 -t 12 -tb
|
| 79 |
+
12 -c 2048 -b 2048 -ub 2048 -np 1 --flash-attn off --no-warmup` at llama.cpp `f3363593`, embedded all 300 SciFact test
|
| 80 |
+
queries in requests of up to 16; the figure is the server process's peak resident memory (VmHWM) at the end. The
|
| 81 |
+
memory-mapped model file counts. Run it uses a 512-token context and batch, which was not measured. The BF16 row is
|
| 82 |
+
the original converted to a BF16 GGUF with the converter of the same llama.cpp commit; it is there for scale and is not
|
| 83 |
+
a published file.
|
| 84 |
+
|
| 85 |
+
### Encoder check
|
| 86 |
+
|
| 87 |
+
Before scoring, the first 64 test queries of each dataset (128 in all) were encoded twice with the same prompts,
|
| 88 |
+
pooling and normalisation: by the FP32 original through sentence-transformers, and by that BF16 conversion through
|
| 89 |
+
llama-server. The mean cosine error between the two was 2.9e-06 and the worst 8.3e-06 (SciFact query 5), inside the
|
| 90 |
+
limits of 0.001 and 0.01. The check compared only these 128 short queries (3,003 tokens, none at the cap);
|
| 91 |
+
documents, capped texts and the retrieval ranking of the BF16 conversion were not compared. In the scoring runs all
|
| 92 |
+
four arms counted the same 11,513,932 tokens, with the same 2,890 texts at the cap.
|
| 93 |
+
|
| 94 |
+
## Development panel, four CPU cores, 16 October 2026
|
| 95 |
+
|
| 96 |
+
The files were chosen on this panel, so it favours them. It is not an independent test or a full MTEB evaluation.
|
| 97 |
+
|
| 98 |
+
96 queries and 1,024 documents, 48 queries and 512 documents per dataset from SciFact and FiQA, the queries from the
|
| 99 |
+
train and dev relevance judgments (panel file SHA-256 `097270111c4e6a70cdf602a8416897bdb393c0bebdddf1ec7c6fcf29b2487cb1`;
|
| 100 |
+
the dataset revisions were not recorded). Four CPU cores, no GPU, CPU model not recorded; llama.cpp `f3363593`,
|
| 101 |
+
`llama-server -m <file> --embeddings --pooling mean --embd-normalize 2 -ngl 0 -t 4 -c 2048 -b 2048 -ub 2048 -np 1
|
| 102 |
+
--flash-attn off`, inputs capped at 512 tokens by the harness, the same prompts and pooling. Equal-domain averages. The
|
| 103 |
+
original is the same FP32 checkpoint, mean pooling, L2-normalised. Our numbers here were measured on the raw quantizer
|
| 104 |
+
outputs; the published files change only header metadata, with the same tensors.
|
| 105 |
+
|
| 106 |
+
| File | Size | nDCG@10, development panel | Recall@10, development panel |
|
| 107 |
+
| --- | --- | --- | --- |
|
| 108 |
+
| TurinTech Q4_K_S | 156.935 MB | 0.859481 | 0.914856 |
|
| 109 |
+
| TurinTech Q5_K_S | 182.036 MB | 0.872079 | 0.928224 |
|
| 110 |
+
| Unsloth UD-Q4_K_XL | 175.674 MB | 0.857125 | 0.920933 |
|
| 111 |
+
| FP32 original | n/a | 0.856404 | 0.928224 |
|
| 112 |
+
|
| 113 |
+
On this panel the default, 10.67% smaller than Unsloth's file, had nDCG@10 0.236 points higher and Recall@10 0.608
|
| 114 |
+
points lower (in percentage points). Our Q5_K_S, 3.62% larger than Unsloth's file, was 1.50 points higher in nDCG@10
|
| 115 |
+
and 0.73 points higher in Recall@10. No test of these gaps was run. Timing was observed once per file during the
|
| 116 |
+
choice: the Q5_K_S file's query latency was 6.94% higher than the paired Unsloth control and its document throughput
|
| 117 |
+
1.64% higher. A single observation is not a speed result, and the card makes no speed claim.
|
| 118 |
+
|
| 119 |
+
## Quantization labels and file size
|
| 120 |
+
|
| 121 |
+
`Q4_K_S` and `Q5_K_S` are size classes in a measured standard K-quant ladder made from the same BF16 parent and
|
| 122 |
+
quantizer build. They do not describe stock tensor recipes or rank quality. The compact file fits below the
|
| 123 |
+
178,164,000-byte stock Q4_K_S reference; the larger file fits below the 210,669,856-byte stock Q5_K_S reference.
|
| 124 |
+
Intermediate K classes were checked; IQ formats were not part of this naming ladder.
|
| 125 |
+
|
| 126 |
+
The compact file mixes Q3_K, Q4_K, BF16 and F32; the larger file mixes Q4_K, Q5_K, BF16 and F32. Whole-file bits per
|
| 127 |
+
weight are 4.632730 and 5.373691; tensor-payload values are 4.166577 and 4.907537. Both files include about 15.79 MB of
|
| 128 |
+
metadata and alignment. Their inherited `general.file_type` headers still read Q4_K_M; the exact file names select the
|
| 129 |
+
intended files, and the Ollama packages show the same inherited Q4_K_M label.
|
| 130 |
+
|
| 131 |
+
## Files and earlier versions
|
| 132 |
+
|
| 133 |
+
Both raw files rebuilt to their measured SHA-256 identities. Each published copy keeps all 413 tensor payloads and
|
| 134 |
+
all inference metadata; only the display name and modality tags changed. Both returned finite, normalized vectors
|
| 135 |
+
through the CPU endpoint.
|
| 136 |
+
|
| 137 |
+
16 October 2026: the larger Q5_K_S file went from 201.17 MB to 182.04 MB, with higher nDCG@10 and Recall@10 on the
|
| 138 |
+
development panel; the compact default did not change. The
|
| 139 |
+
[previous larger file](https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/resolve/42212da2548a4b9ae25db9ca429270da6d48119b/embeddinggemma-2-Artemis-Q5_K_S.gguf)
|
| 140 |
+
and [previous card](https://huggingface.co/turintech/embeddinggemma-2-Artemis-GGUF/blob/42212da2548a4b9ae25db9ca429270da6d48119b/README.md)
|
| 141 |
+
remain at their original revision. The earlier [151 MB](previous-compact-151mb.md) and
|
| 142 |
+
[154 MB](previous-compact-154mb.md) compact candidates remain in the research record; on the development panel the
|
| 143 |
+
current default has higher nDCG@10 and Recall@10 than both, at a slightly larger size.
|
assets/buttons/artemis.png
ADDED
|
assets/buttons/lm-studio.png
ADDED
|
assets/buttons/ollama.png
ADDED
|
assets/buttons/other-models.png
ADDED
|
assets/buttons/turintech.png
ADDED
|
assets/comparison.png
ADDED
|
assets/turintech-logo-v2.png
ADDED
|