


Expressive Turkish text-to-speech that laughs, sighs and whispers on cue.
Nefes 0.5 · preview · training-free · Apache 2.0 | Nefes 1 (open weights) coming soon
Listen
Write a tag where you want the emotion. Every sample below is an automatic output, with no manual editing.
| Text | Audio |
|---|---|
| Kahveyi yine dökmüşüm. [gül] Bugün benim günüm değil galiba. | |
| Sabahtan beri bu raporla uğraşıyorum. [iç çek] Bitmek bilmiyor. | |
| [fısılda] Kimseye söyleme ama bu akşam sana bir sürprizim var. | |
| [gül] Bunu gerçekten sen mi yaptın? Harika olmuş! | |
| [gül] Tamam, tamam, kabul ediyorum, haklıydın. [iç çek] Ama bir dahaki sefere beni de dinle. |
Why Nefes

Open Turkish text-to-speech reads correctly, but like a news anchor: no laughter, no sighs, no whispers. Open models that can laugh speak English only, and the services that do both are closed, paid cloud APIs.
The root cause is data: there is no open, licensed dataset of expressive Turkish speech to train on. Nefes 0.5 sidesteps that gap without training anything. It borrows a real laugh, sigh or whisper from an English expressive model and lets a Turkish-capable model continue from it, in one consistent voice, exactly where you put the tag.
Good for: voice-overs for videos and ads, game and story characters, audiobooks and podcasts, and generating expressive Turkish speech for research. Not for: real-time assistants (it is slow by design, see Evaluation).
Quickstart
pip install git+https://huggingface.co/alicangunduz/nefes-0.5
nefes "Kahveyi yine dökmüşüm. [gül] Bugün benim günüm değil galiba." -o out.wav
from nefes import Nefes

tts = Nefes.from_pretrained("alicangunduz/nefes-0.5")
wav, sr = tts.say("Otobüs kaçtı. [iç çek] Bir sonrakini bekleyeceğiz artık.")
tts.save(wav, "out.wav")
Requirements: NVIDIA GPU with 16 GB VRAM (measured peak 14.9 GB), Python ≥ 3.10.
The first run downloads VoxCPM2, Whisper large-v3 and WavLM-SV. After loading (70 s), a 6-second sentence takes ~30 s.
Tags
| Tag | Effect |
|---|---|
[gül] |
laughs, then keeps talking in the same voice |
[iç çek] |
sighs / takes a deep breath, then continues |
[fısılda] |
whispers the following text |
Tip: place a tag after a complete sentence or question, not right after a conjunction such as çünkü ("because") or ama ("but").
✅  İsmim Nefes… [iç çek] Duydun mu? Nefes alabiliyorum.
❌  İsmim Nefes… çünkü [iç çek] nefes alabiliyorum.
In the ❌ case the word right before the tag is read with a flat, sentence-final tone.
How it works

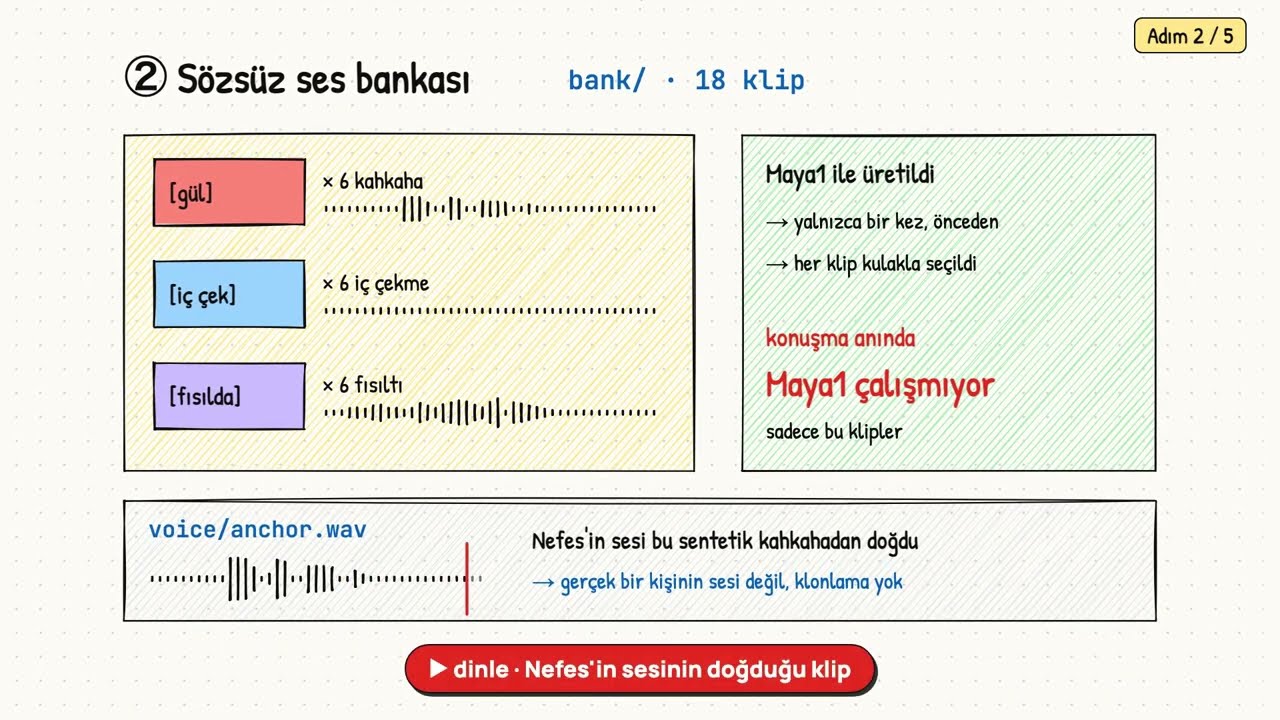
▶ Watch the 4:45 walkthrough (Turkish, with captions), narrated by Nefes 0.5 itself.
Every clip and score in it comes from one recorded run. Narration: best of 6 candidates per line; leading breaths trimmed and loudness evened out afterwards.
Nefes 0.5 is training-free: no model weights are trained or changed. It steers open models at inference time.
- Nonverbal prompt bank: 18 short synthetic clips (laugh, sigh, whisper) generated with Maya1 and approved by ear.
- Audio prompting: VoxCPM2 continues in Turkish from the audio right before it, so the laugh is real and the voice matches.
- Chained continuation: every segment continues from the previous one, keeping one voice for the whole utterance.
- Lookahead cut: the text before a tag is generated together with the next words and cut in the following pause, so it keeps natural mid-sentence intonation.
- Best-of-N reranking: six candidates are scored for voice similarity (WavLM-SV), intelligibility (Whisper) and naturalness (a small preference model trained on the author's own listening ratings); the best one is returned.
Model details
- Developed by: Ali Can Gündüz (@alicangunduzdev)
- Type: Training-free text-to-speech system (compound AI system), no new model weights
- Version: 0.5 preview, October 2026
- Language: Turkish (tags are written in Turkish)
- Voice: One synthetic female voice, designed with Maya1; belongs to no real person
- Output: 48 kHz mono audio
- License: Apache 2.0
- Runs at inference: VoxCPM2 (speech generation) · Whisper large-v3 (word timing and intelligibility) · WavLM-SV (voice similarity)
- Used offline only: Maya1 generated the nonverbal prompt bank once; not needed at runtime
- Included assets: Nefes voice clip · 18 synthetic nonverbal prompt clips · preference model (small logistic-regression classifier on Whisper-encoder and prosody features)
- Human data: No recorded human speech. The preference model was trained only on the author's own listening ratings of synthetic clips
- Hardware: NVIDIA GPU with ~16 GB VRAM (CUDA)
Evaluation
Measured on 10 unseen sentences (never used for tuning), covering every tag, mid-sentence tags, two tags in one sentence, a long untagged paragraph and one sentence that breaks the placement tip on purpose. Default settings, best of 6, picked automatically, no cherry-picking.
| Metric | Result |
|---|---|
| Intelligibility (WER, Whisper large-v3) | 11 % mean · 6 / 10 sentences at 0 % |
| Voice consistency (similarity to the Nefes voice, WavLM-SV) | 0.86 mean · min 0.77 · 9 / 10 ≥ 0.80 |
| Speed (6 candidates) | ≈ 30 s for a 6-second sentence · after a ≈ 70 s first load |
| Peak GPU memory | 14.9 GB |
WER is computed on the whole utterance, so a laugh or sigh that Whisper transcribes as a word counts as an error; the speech-only error is lower. Weakest case: a whisper starting mid-sentence (WER 50 %).
Per-sentence results
| Sentence | WER | Similarity |
|---|---|---|
| Bugün hava çok güzel, biraz yürüyüşe çıkalım mı? | 0 % | 0.77 |
| [gül] Bunu gerçekten sen mi yaptın? Harika olmuş! | 0 % | 0.80 |
| Sabahtan beri bu raporla uğraşıyorum. [iç çek] Bitmek bilmiyor. | 0 % | 0.87 |
| [fısılda] Bir sır vereyim mi? Yarın sana sürpriz var. | 0 % | 0.85 |
| Kahveyi yine dökmüşüm. [gül] Bugün benim günüm değil galiba. | 0 % | 0.94 |
| Otobüs kaçtı. [iç çek] Bir sonrakini bekleyeceğiz artık. | 17 % | 0.90 |
| Merhaba, ben Nefes. Size bugünün hava durumunu okuyacağım: … (long) | 10 % | 0.93 |
| Dur bir dakika… [fısılda] arkanda biri var. | 50 % | 0.84 |
| [gül] Tamam, tamam, kabul ediyorum, haklıydın. [iç çek] Ama bir dahaki sefere beni de dinle. | 33 % | 0.86 |
| Çok yorgunum ama [gül] yine de mutluyum. (breaks the tip) | 0 % | 0.86 |
A human listening study is planned for the Nefes 1 report.
Roadmap
| Version | What | Status |
|---|---|---|
| Nefes 0.5 | training-free system (this repo) | ✅ preview |
| Nefes 1 | open-weight model distilled from Nefes 0.5: one pass, no extra models | 🔜 coming soon |
| Nefes 2+ | more emotions and voices | planned |
FAQ
Is Nefes a fine-tuned model?
No. Nefes 0.5 is a training-free system: no weights are trained or changed. It combines open models at inference time (see How it works). The trained, open-weight model is Nefes 1.
Can I clone my own voice, or someone else's?
No, by design. Nefes speaks with one fixed synthetic voice and has no voice-cloning feature.
Can I use it commercially?
Nefes code and assets are Apache 2.0, so yes. At runtime it downloads VoxCPM2 (Apache 2.0), Whisper (MIT) and WavLM-SV; check their licenses for your use case.
Why is it slow?
Quality comes from trying several takes: by default it generates 6 candidates and keeps the best one (≈ 30 s for a
6-second sentence). -n 1 is much faster but only a draft. Nefes 1 is designed to produce a good take in one pass.
Does it run on CPU or Apple Silicon?
Not tested. Nefes 0.5 targets NVIDIA GPUs with CUDA and about 16 GB of memory.
Can it read long texts?
Yes, but split them into sentences and generate one sentence at a time; quality is best on short to medium sentences.
Which emotions are supported?
Three tags: [gül] (laugh), [iç çek] (sigh) and [fısılda] (whisper). More emotions and voices are planned for Nefes 2+.
What is Nefes 1?
An open-weight model distilled from Nefes 0.5: one model file, one pass, no extra models at runtime, so it is faster and simpler to run.
Limitations
- Turkish only, one voice, three tags.
- Whispering is the weakest tag: the voice can drift slightly.
- Slow by design: quality comes from trying several takes (
-n 1is a fast draft and can misread). - Long paragraphs: split them into sentences.
Responsible use
- The Nefes voice is synthetic (designed with Maya1) and belongs to no real person. No collected recordings are included.
- No voice cloning, by design.
- Do not use Nefes to impersonate real people or to deceive.
Acknowledgements & license
Code and assets: Apache 2.0. Built on VoxCPM2 (Apache 2.0),
Maya1 (Apache 2.0), Whisper (MIT) and
WavLM-SV. See NOTICE.
@misc{nefes2026,
  title  = {Nefes 0.5: training-free expressive Turkish TTS},
  author = {Gündüz, Ali Can},
  year   = {2026},
  url    = {https://huggingface.co/alicangunduz/nefes-0.5}
}
Contact
- X: @alicangunduzdev
- LinkedIn: alicangunduzdev
- Email: [email protected]
Model tree for alicangunduz/nefes-0.5
Base model
openbmb/VoxCPM2