

Ilk yayin: LoRA adaptoru + model karti + karar.py
Browse files- README.md +56 -54
- assets/fig_compare.png +2 -2
- birlestir.py +12 -6
- karar.py +59 -6
- test_karar.py +53 -4
README.md
CHANGED
|
@@ -30,7 +30,7 @@ tags:
|
|
| 30 |
- **Many questions, one pass.** Up to 16 questions about one text are answered in a single forward pass.
|
| 31 |
- **Runs on your hardware, offline.** You need a ~130 MB LoRA adapter (or the merged bf16 weights) and one consumer GPU. There is no API and the text never leaves the machine. CPU works, but slowly.
|
| 32 |
- **Cheap.** On your own hardware there is no per-call fee. For comparison, our logs show Jev's API at about 1.8e-5 $ per one-question request and 3.6e-5 $ per eight-question request, and Microsoft-Decision-1 at 0.7–1.5e-5 $ per request.
|
| 33 |
-
- **Three sizes, one recipe.** Turnike-0.8B, Turnike-4B and Turnike-9B share the data, the draw and the hyperparameters; nothing was tuned per size. See [Model family](#model-family).
|
| 34 |
- **Honest.** We found and fixed two training-data shortcuts (see [Training](#training)). "None of the above" is tested on a balanced set whose option count does not give the answer away. All test sets used to pick this run are listed in [Honesty notes](#honesty-notes).
|
| 35 |
|
| 36 |

|
|
@@ -71,13 +71,13 @@ Turnike-4B is a LoRA adapter (r=16, about 130 MB) on [Qwen/Qwen3.5-4B](https://h
|
|
| 71 |
|
| 72 |
Three sizes, one recipe: the same data, the same draw (seed 3) and the same hyperparameters (LoRA r=16, α=32, lr 1e-4, 2,831 steps, effective batch 32) for every size. Nothing was tuned per size, so the smallest and the largest model are probably somewhat under-tuned. Each size is its own repo; the row in bold is the model of this card.
|
| 73 |
|
| 74 |
-
| model | base | trainable params | JevBench EN-300 (EN) | held-6 / other-16 | tr_insan, 1,379 human-labelled (TR) |
|
| 75 |
-
|---|---|---|---|---|---|---|---|---|---|
|
| 76 |
-
| [Turnike-0.8B](https://huggingface.co/berkay123001/turnike-0.8b) | Qwen/Qwen3.5-0.8B | 10.8M | 0.676 | 0.682 / 0.674 | 0.699 | 0.
|
| 77 |
-
| **Turnike-4B** (this card) | Qwen/Qwen3.5-4B | 32.5M | 0.769 | 0.826 / 0.748 | 0.748 | 0.
|
| 78 |
-
| [Turnike-9B](https://huggingface.co/berkay123001/turnike-9b) | Qwen/Qwen3.5-9B | 43.3M | 0.780 | 0.839 / 0.758 | 0.763 | 0.
|
| 79 |
|
| 80 |
-
<sub>Same protocol as the tables below: single runs, the same items for every model, no calibration recipe. Differences below about 0.01
|
| 81 |
|
| 82 |
## Quick start
|
| 83 |
|
|
@@ -209,21 +209,21 @@ Yes/no questions are written as `A = no: The answer is no (...)`, `B = yes: The
|
|
| 209 |
|
| 210 |
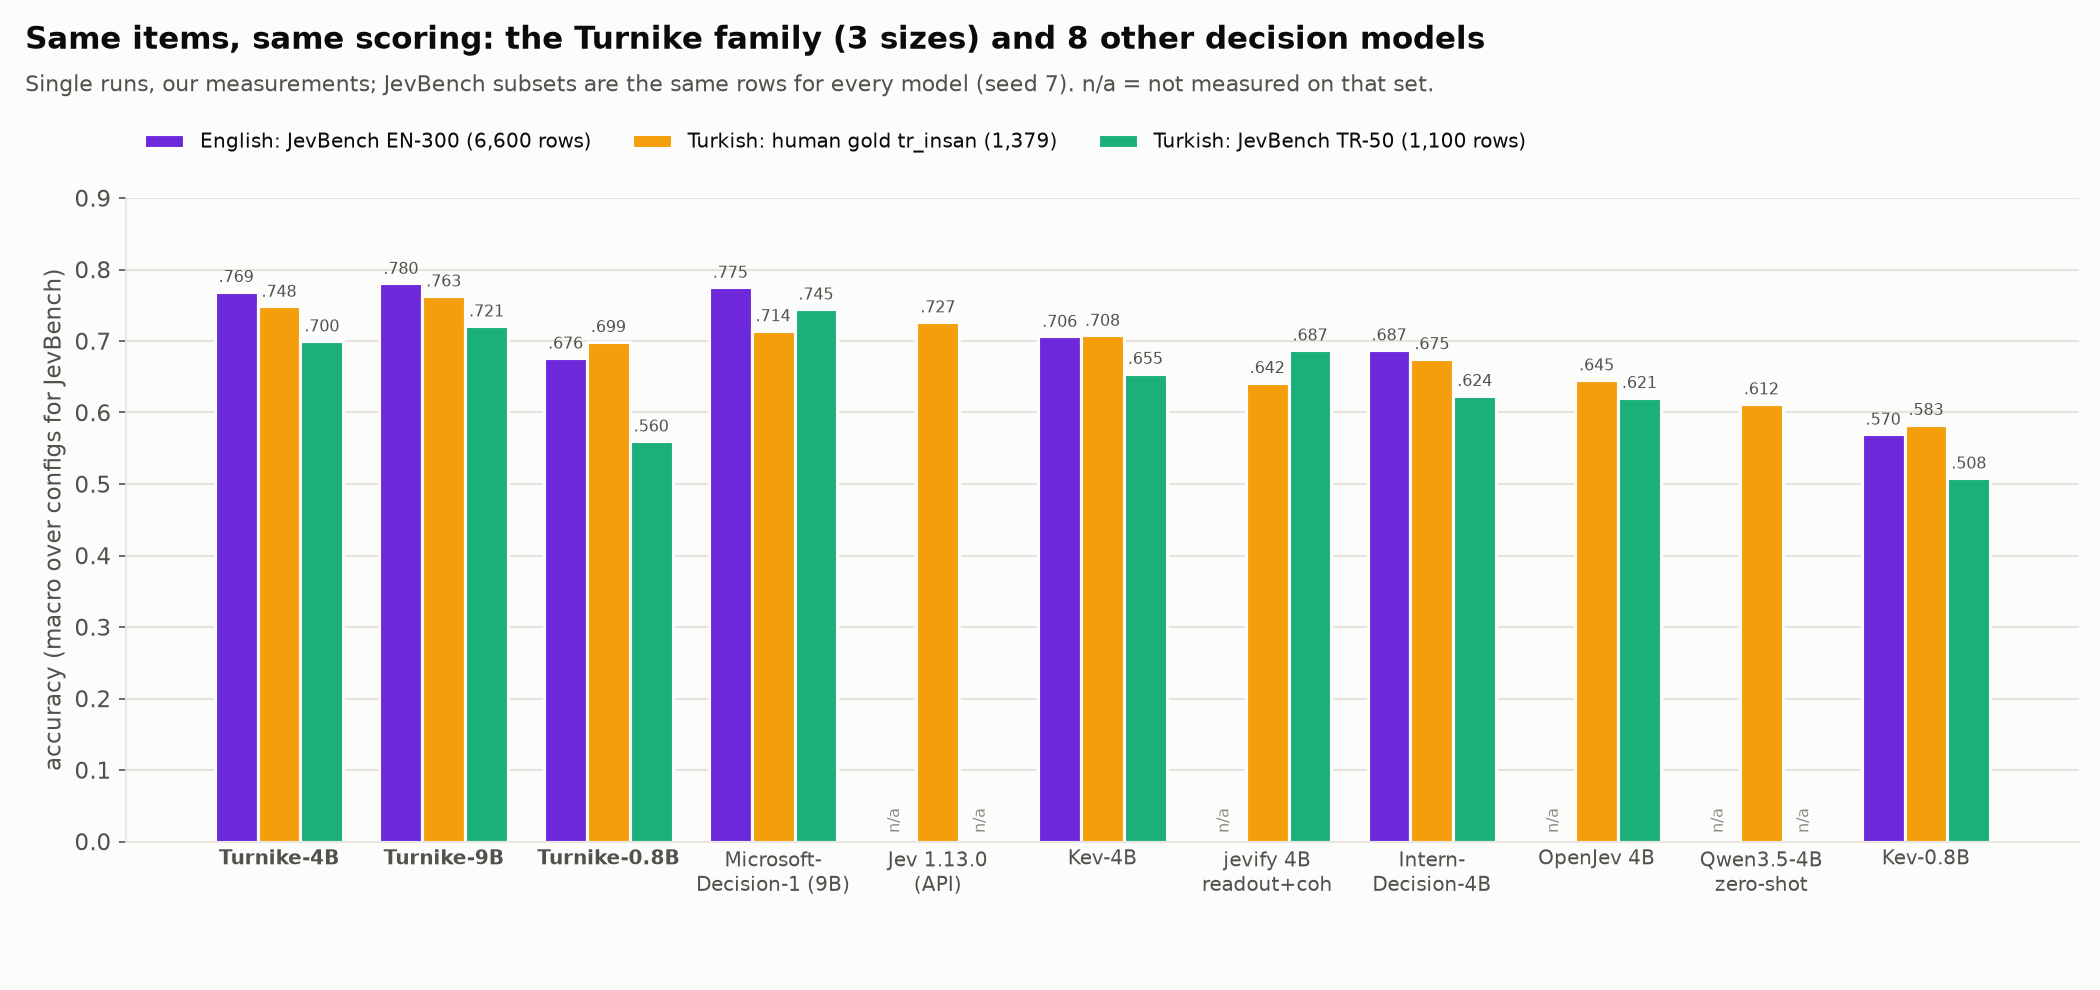
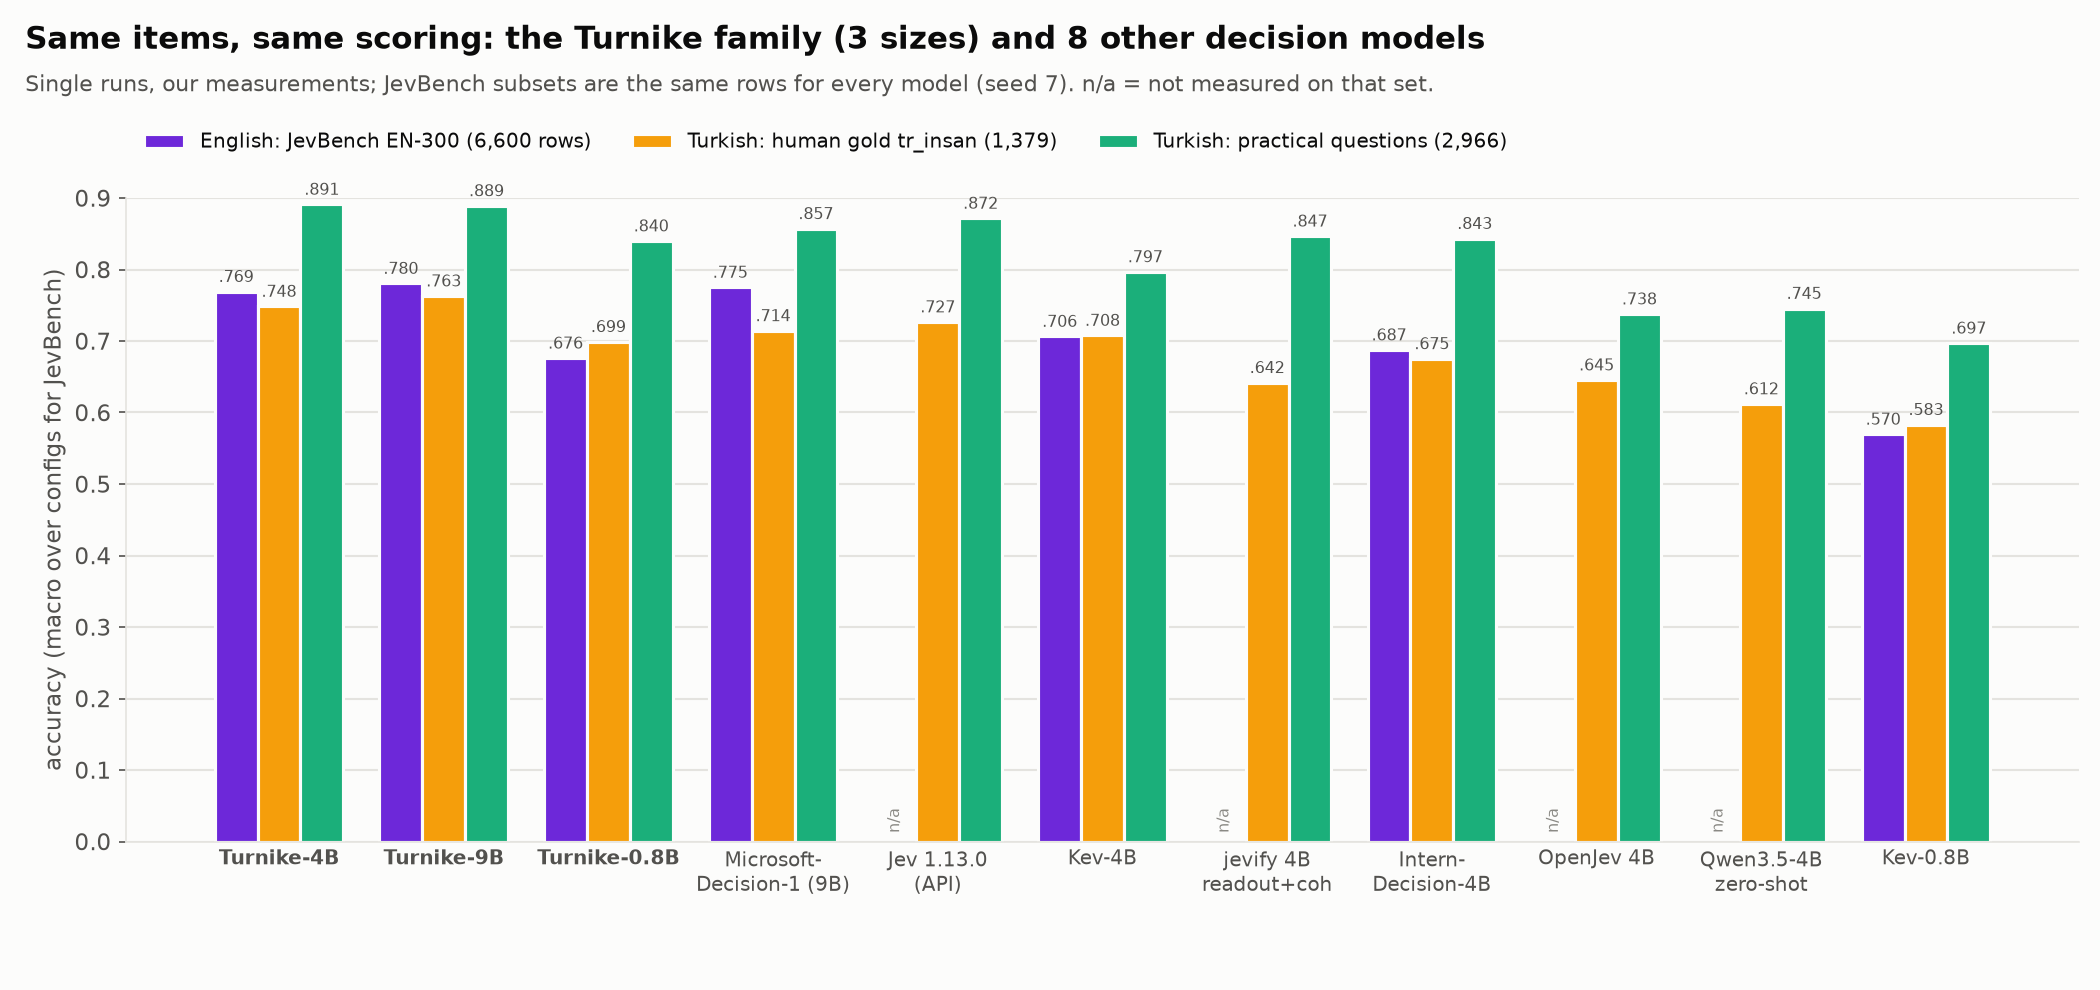
All numbers below are our own measurements unless marked as reported by someone else. Every model saw the same items and was scored by the same code. Probabilities are raw, with no calibration recipe. Each result is a single run.
|
| 211 |
|
| 212 |
-
| model | JevBench EN-300 (EN) | LegalBench rules, 885 (EN) | tr_insan, 1,379 human-labelled (TR) |
|
| 213 |
-
|---|---|---|---|---|
|
| 214 |
-
| **Turnike-4B** | 0.769 | 0.832 | 0.748 | 0.
|
| 215 |
-
| **Turnike-9B** | 0.780 | 0.890 | 0.763 | 0.
|
| 216 |
-
| **Turnike-0.8B** | 0.676 | 0.724 | 0.699 | 0.
|
| 217 |
-
| Microsoft-Decision-1 (9B, closed, API) | 0.775 | – | 0.714 | 0.
|
| 218 |
-
| Jev 1.13.0 (API) | – | 0.924 † | 0.727 |
|
| 219 |
-
| Kev-4B | 0.706 | 0.786 | 0.708 | 0.
|
| 220 |
-
| jevify Qwen3.5-4B readout LoRA + coherence | – | – | 0.642 | 0.
|
| 221 |
-
| internlm/Intern-Decision-4B | 0.687 | 0.656 | 0.675 | 0.
|
| 222 |
-
| OpenJev 4B (qwen3.5-4b-nli-v5) | – | – | 0.645 | 0.
|
| 223 |
-
| Qwen3.5-4B, zero-shot (our prompt) | – | – | 0.612 |
|
| 224 |
-
| Kev-0.8B | 0.570 | 0.496 | 0.583 | 0.
|
| 225 |
-
|
| 226 |
-
† Reported by the jevify author on the same 885 items (jevify README, finding 14); not our run. – = not measured. Run-to-run noise: retraining an earlier run of the same recipe with another seed moved tr_insan by +0.001
|
| 227 |
|
| 228 |
### English
|
| 229 |
|
|
@@ -232,6 +232,8 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 232 |
| model | source | macro acc | macro ECE ↓ | macro Brier ↓ | sel@90 | choice / score / noul acc |
|
| 233 |
|---|---|---|---|---|---|---|
|
| 234 |
| **Turnike-4B** | our run, not submitted | **0.774** | 0.084 | 0.293 | **0.805** | 0.791 / 0.599 / 0.902 |
|
|
|
|
|
|
|
| 235 |
| Qwen/Qwen-AgentWorld-35B-A3B (readout LoRA + coherence) | reported by the leaderboard | 0.770 | 0.055 | 0.292 | 0.799 | 0.792 / 0.566 / 0.917 |
|
| 236 |
| Qwen/Qwen3.5-9B (readout LoRA + coherence) | reported by the leaderboard | 0.763 | 0.056 | 0.299 | 0.791 | 0.791 / 0.554 / 0.906 |
|
| 237 |
| Qwen/Qwen3.5-9B (readout LoRA) | reported by the leaderboard | 0.759 | 0.052 | 0.302 | 0.787 | 0.790 / 0.541 / 0.905 |
|
|
@@ -256,35 +258,35 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 256 |
|
| 257 |
#### Table 2. Full JevBench, per config, against Jev 1.13.0
|
| 258 |
|
| 259 |
-
| config | type | n | Turnike-4B acc | Turnike-4B ECE | Jev 1.13.0 acc | Jev 1.13.0 ECE | Turnike-4B − Jev |
|
| 260 |
-
|---|---|---|---|---|---|---|---|
|
| 261 |
-
| *held-out 6 (not in training)* | | | | | | | |
|
| 262 |
-
| `arc_challenge` | choice | 1,000 | 0.932 | 0.087 | 0.979 | 0.010 | −0.047 |
|
| 263 |
-
| `clinc150` | choice | 1,000 | 0.856 | 0.162 | 0.893 | 0.033 | −0.037 |
|
| 264 |
-
| `fever_evidence` | noul | 1,000 | 0.952 | 0.066 | 0.972 | 0.028 | −0.020 |
|
| 265 |
-
| `measuring_hate_speech` | score | 1,000 | 0.631 | 0.070 | 0.527 | 0.237 | +0.104 |
|
| 266 |
-
| `strategyqa_grounded` | noul | 687 | 0.943 | 0.118 | 0.956 | 0.059 | −0.013 |
|
| 267 |
-
| `yelp5` | score | 1,000 | 0.668 | 0.061 | 0.685 | 0.174 | −0.017 |
|
| 268 |
-
| *held-out 6 (not in training), macro* | | 5,687 | **0.830** | 0.094 | 0.835 | 0.090 | −0.005 |
|
| 269 |
-
| *other 16 (train splits in training)* | | | | | | | |
|
| 270 |
-
| `banking77` | choice | 1,000 | 0.862 | 0.100 | 0.796 | 0.095 | +0.066 |
|
| 271 |
-
| `boolq` | noul | 1,000 | 0.904 | 0.085 | 0.917 | 0.021 | −0.013 |
|
| 272 |
-
| `chaosnli` | choice | 1,599 | 0.631 | 0.108 | 0.615 | 0.222 | +0.016 |
|
| 273 |
-
| `civil_comments` | noul | 2,000 | 0.919 | 0.086 | 0.729 | 0.045 | +0.191 |
|
| 274 |
-
| `go_emotions` | choice | 1,000 | 0.569 | 0.032 | 0.282 | 0.384 | +0.287 |
|
| 275 |
-
| `helpsteer2_helpfulness` | score | 1,000 | 0.446 | 0.025 | 0.363 | 0.232 | +0.083 |
|
| 276 |
-
| `helpsteer2_verbosity` | score | 1,000 | 0.679 | 0.160 | 0.341 | 0.231 | +0.338 |
|
| 277 |
-
| `ledgar` | choice | 1,000 | 0.775 | 0.099 | 0.751 | 0.117 | +0.024 |
|
| 278 |
-
| `massive` | choice | 1,000 | 0.857 | 0.099 | 0.808 | 0.090 | +0.049 |
|
| 279 |
-
| `mmlu` | choice | 1,000 | 0.729 | 0.075 | 0.923 | 0.027 | −0.194 |
|
| 280 |
-
| `mnli` | choice | 1,000 | 0.905 | 0.085 | 0.883 | 0.032 | +0.022 |
|
| 281 |
-
| `paws` | noul | 1,000 | 0.909 | 0.079 | 0.846 | 0.040 | +0.063 |
|
| 282 |
-
| `sms_spam` | noul | 800 | 0.983 | 0.093 | 0.965 | 0.068 | +0.018 |
|
| 283 |
-
| `sst5` | score | 1,000 | 0.582 | 0.059 | 0.565 | 0.190 | +0.017 |
|
| 284 |
-
| `strategyqa_closed` | noul | 687 | 0.703 | 0.055 | 0.785 | 0.042 | −0.082 |
|
| 285 |
-
| `stsb` | score | 1,000 | 0.585 | 0.048 | 0.538 | 0.119 | +0.047 |
|
| 286 |
-
| *other 16 (train splits in training), macro* | | 17,086 | **0.752** | 0.081 | 0.694 | 0.122 | +0.058 |
|
| 287 |
-
| **all 22, macro** | | 22,773 | **0.774** | **0.084** | 0.733 | 0.113 | +0.041 |
|
| 288 |
|
| 289 |
<sub>Jev values: the Jev 1.13.0 per-config table on the jev-bench dataset card (TypeSafe API, every test record); our project records hold the same accuracies for all 22 configs. Turnike-4B is ahead of Jev on 14 of 22 configs and by +0.041 macro. On the six held-out sources Turnike-4B (0.830) is above the leaderboard author's best open model (0.828, as stated on the card) and behind Jev (0.835) and the hosted pplx-decider-v1-27b (0.840). Jev also leads on the knowledge configs (mmlu, strategyqa_closed, arc_challenge).</sub>
|
| 290 |
|
|
@@ -322,7 +324,7 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 322 |
|
| 323 |
<sub>Protocol: human gold labels from five public Turkish datasets, test texts only. All models were scored by the same script against the same gold file; no model answered "unsure". Stars are exact match on a 5-point scale (within ±1 star Turnike-4B gets 0.91 / 0.90). Our leakage scan flagged 19 items as overlapping with training texts; without them Turnike-4B gets 0.746. Microsoft-Decision-1 and Jev were called through their APIs, the others ran locally.</sub>
|
| 324 |
|
| 325 |
-
#### Table 5. JevBench TR-50: the same 1,100 machine-translated rows for every model
|
| 326 |
|
| 327 |
| model | TR-50 macro | held-6 / other-16 | McNemar vs Turnike-4B (only-Turnike-4B / only-other) |
|
| 328 |
|---|---|---|---|
|
|
@@ -336,7 +338,7 @@ All numbers below are our own measurements unless marked as reported by someone
|
|
| 336 |
| OpenJev 4B (qwen3.5-4b-nli-v5) | 0.621 | 0.717 / 0.585 | 172 / 85, p = 6e-8 |
|
| 337 |
| Kev-0.8B | 0.508 | 0.580 / 0.481 | 295 / 84, p = 1e-28 |
|
| 338 |
|
| 339 |
-
<sub>Protocol: 50 rows per config (seed 7) from a machine-translated Turkish JevBench test, 22 configs, 1,100 rows. The set is small and noisy: it moved by 0.02 between two seeds of the same recipe. Exact two-sided McNemar on paired rows; Microsoft-Decision-1 rescored from its raw API answers with the same decision rule (macro 0.7445, as originally reported).</sub>
|
| 340 |
|
| 341 |
### Behaviour tests (Table 6)
|
| 342 |
|
|
@@ -398,7 +400,7 @@ This release contains no web/browser data; the browser version will be published
|
|
| 398 |
|
| 399 |
## Limitations
|
| 400 |
|
| 401 |
-
- **"None of the above" is used somewhat too often.** On the balanced test the model picks "none" in 0.80–0.81 of the items where the right option is missing, but also in 0.22–0.25 of the items where it is present.
|
| 402 |
- **Not the best everywhere.** Microsoft-Decision-1 (9B) is ahead on JevBench TR-50 (0.745 vs 0.700, p = 5e-4) and slightly ahead on EN-300 (n.s.). Jev is ahead on the six held-out JevBench sources, on knowledge questions (mmlu 0.923 vs 0.729) and on LegalBench rule application (0.924 vs 0.832).
|
| 403 |
- **KVKK thresholds are noisy.** The gold sets are tiny (9, 10, 12 items) and a few items sit near p = 0.5. Do not threshold yes/no probabilities near 0.5 without your own validation set.
|
| 404 |
- **go_emotions, hate speech, star ratings:** on full JevBench the model scores 0.569 on go_emotions and 0.631 on measuring_hate_speech. The boundary between offensive language and group-targeted hate is the weakest point, together with 5-level star ratings.
|
|
|
|
| 30 |
- **Many questions, one pass.** Up to 16 questions about one text are answered in a single forward pass.
|
| 31 |
- **Runs on your hardware, offline.** You need a ~130 MB LoRA adapter (or the merged bf16 weights) and one consumer GPU. There is no API and the text never leaves the machine. CPU works, but slowly.
|
| 32 |
- **Cheap.** On your own hardware there is no per-call fee. For comparison, our logs show Jev's API at about 1.8e-5 $ per one-question request and 3.6e-5 $ per eight-question request, and Microsoft-Decision-1 at 0.7–1.5e-5 $ per request.
|
| 33 |
+
- **Three sizes, one recipe.** Turnike-0.8B, Turnike-4B and Turnike-9B share the data, the draw and the hyperparameters; nothing was tuned per size. Full JevBench macro 0.681 / 0.774 / 0.783; the 9B fits a 16 GB GPU in FP8. See [Model family](#model-family).
|
| 34 |
- **Honest.** We found and fixed two training-data shortcuts (see [Training](#training)). "None of the above" is tested on a balanced set whose option count does not give the answer away. All test sets used to pick this run are listed in [Honesty notes](#honesty-notes).
|
| 35 |
|
| 36 |

|
|
|
|
| 71 |
|
| 72 |
Three sizes, one recipe: the same data, the same draw (seed 3) and the same hyperparameters (LoRA r=16, α=32, lr 1e-4, 2,831 steps, effective batch 32) for every size. Nothing was tuned per size, so the smallest and the largest model are probably somewhat under-tuned. Each size is its own repo; the row in bold is the model of this card.
|
| 73 |
|
| 74 |
+
| model | base | trainable params | full JevBench (22,773) | JevBench EN-300 (EN) | held-6 / other-16 | tr_insan, 1,379 human-labelled (TR) | practical TR, 2,966 | LegalBench rules, 885 (EN) | weights | trained on |
|
| 75 |
+
|---|---|---|---|---|---|---|---|---|---|---|
|
| 76 |
+
| [Turnike-0.8B](https://huggingface.co/berkay123001/turnike-0.8b) | Qwen/Qwen3.5-0.8B | 10.8M | **0.681** | 0.676 | 0.682 / 0.674 | 0.699 | 0.840 | 0.724 | adapter (43 MB) | RTX 5060 Ti 16 GB, batch 4 × 8 |
|
| 77 |
+
| **Turnike-4B** (this card) | Qwen/Qwen3.5-4B | 32.5M | **0.774** | 0.769 | 0.826 / 0.748 | 0.748 | 0.891 | 0.832 | adapter (130 MB) · [merged bf16](https://huggingface.co/berkay123001/turnike-4b-merged) | RTX 5060 Ti 16 GB, batch 4 × 8 |
|
| 78 |
+
| [Turnike-9B](https://huggingface.co/berkay123001/turnike-9b) | Qwen/Qwen3.5-9B | 43.3M | **0.783** | 0.780 | 0.839 / 0.758 | 0.763 | 0.889 | 0.890 | adapter (173 MB) · [merged bf16](https://huggingface.co/berkay123001/turnike-9b-merged) · [FP8](https://huggingface.co/berkay123001/turnike-9b-fp8) | Colab RTX PRO 6000 96 GB, batch 16 × 2 |
|
| 79 |
|
| 80 |
+
<sub>Same protocol as the tables below: single runs, the same items for every model, no calibration recipe; full JevBench = official `jevify-run report` on all 22,773 test rows. Differences below about 0.01 are within run-to-run noise. The machine-translated TR-50 is in Table 5.</sub>
|
| 81 |
|
| 82 |
## Quick start
|
| 83 |
|
|
|
|
| 209 |
|
| 210 |
All numbers below are our own measurements unless marked as reported by someone else. Every model saw the same items and was scored by the same code. Probabilities are raw, with no calibration recipe. Each result is a single run.
|
| 211 |
|
| 212 |
+
| model | JevBench EN-300 (EN) | LegalBench rules, 885 (EN) | tr_insan, 1,379 human-labelled (TR) | practical TR, 2,966 (TR) |
|
| 213 |
+
|---|---|---|---|---|
|
| 214 |
+
| **Turnike-4B** | 0.769 | 0.832 | 0.748 | 0.891 |
|
| 215 |
+
| **Turnike-9B** | 0.780 | 0.890 | 0.763 | 0.889 |
|
| 216 |
+
| **Turnike-0.8B** | 0.676 | 0.724 | 0.699 | 0.840 |
|
| 217 |
+
| Microsoft-Decision-1 (9B, closed, API) | 0.775 | – | 0.714 | 0.857 |
|
| 218 |
+
| Jev 1.13.0 (API) | – | 0.924 † | 0.727 | 0.872 |
|
| 219 |
+
| Kev-4B | 0.706 | 0.786 | 0.708 | 0.797 |
|
| 220 |
+
| jevify Qwen3.5-4B readout LoRA + coherence | – | – | 0.642 | 0.847 |
|
| 221 |
+
| internlm/Intern-Decision-4B | 0.687 | 0.656 | 0.675 | 0.843 |
|
| 222 |
+
| OpenJev 4B (qwen3.5-4b-nli-v5) | – | – | 0.645 | 0.738 |
|
| 223 |
+
| Qwen3.5-4B, zero-shot (our prompt) | – | – | 0.612 | 0.745 |
|
| 224 |
+
| Kev-0.8B | 0.570 | 0.496 | 0.583 | 0.697 |
|
| 225 |
+
|
| 226 |
+
† Reported by the jevify author on the same 885 items (jevify README, finding 14); not our run. – = not measured. Run-to-run noise: retraining an earlier run of the same recipe with another seed moved tr_insan by +0.001 and EN-300 by +0.002. The machine-translated JevBench TR-50 is a supplementary set (Table 5); the human-labelled tr_insan is the primary Turkish measure.
|
| 227 |
|
| 228 |
### English
|
| 229 |
|
|
|
|
| 232 |
| model | source | macro acc | macro ECE ↓ | macro Brier ↓ | sel@90 | choice / score / noul acc |
|
| 233 |
|---|---|---|---|---|---|---|
|
| 234 |
| **Turnike-4B** | our run, not submitted | **0.774** | 0.084 | 0.293 | **0.805** | 0.791 / 0.599 / 0.902 |
|
| 235 |
+
| **Turnike-9B** | our run, not submitted | **0.783** | 0.076 | 0.280 | **0.817** | 0.806 / 0.597 / 0.913 |
|
| 236 |
+
| **Turnike-0.8B** | our run, not submitted | **0.681** | 0.078 | 0.385 | **0.711** | 0.665 / 0.539 / 0.822 |
|
| 237 |
| Qwen/Qwen-AgentWorld-35B-A3B (readout LoRA + coherence) | reported by the leaderboard | 0.770 | 0.055 | 0.292 | 0.799 | 0.792 / 0.566 / 0.917 |
|
| 238 |
| Qwen/Qwen3.5-9B (readout LoRA + coherence) | reported by the leaderboard | 0.763 | 0.056 | 0.299 | 0.791 | 0.791 / 0.554 / 0.906 |
|
| 239 |
| Qwen/Qwen3.5-9B (readout LoRA) | reported by the leaderboard | 0.759 | 0.052 | 0.302 | 0.787 | 0.790 / 0.541 / 0.905 |
|
|
|
|
| 258 |
|
| 259 |
#### Table 2. Full JevBench, per config, against Jev 1.13.0
|
| 260 |
|
| 261 |
+
| config | type | n | Turnike-4B acc | Turnike-4B ECE | Turnike-9B acc | Turnike-9B ECE | Turnike-0.8B acc | Turnike-0.8B ECE | Jev 1.13.0 acc | Jev 1.13.0 ECE | Turnike-4B − Jev | Turnike-9B − Jev | Turnike-0.8B − Jev |
|
| 262 |
+
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
|
| 263 |
+
| *held-out 6 (not in training)* | | | | | | | | | | | | | |
|
| 264 |
+
| `arc_challenge` | choice | 1,000 | 0.932 | 0.087 | 0.949 | 0.097 | 0.701 | 0.052 | 0.979 | 0.010 | −0.047 | −0.030 | −0.278 |
|
| 265 |
+
| `clinc150` | choice | 1,000 | 0.856 | 0.162 | 0.863 | 0.123 | 0.710 | 0.120 | 0.893 | 0.033 | −0.037 | −0.030 | −0.183 |
|
| 266 |
+
| `fever_evidence` | noul | 1,000 | 0.952 | 0.066 | 0.961 | 0.079 | 0.865 | 0.088 | 0.972 | 0.028 | −0.020 | −0.011 | −0.107 |
|
| 267 |
+
| `measuring_hate_speech` | score | 1,000 | 0.631 | 0.070 | 0.635 | 0.060 | 0.599 | 0.055 | 0.527 | 0.237 | +0.104 | +0.108 | +0.072 |
|
| 268 |
+
| `strategyqa_grounded` | noul | 687 | 0.943 | 0.118 | 0.946 | 0.109 | 0.766 | 0.088 | 0.956 | 0.059 | −0.013 | −0.010 | −0.190 |
|
| 269 |
+
| `yelp5` | score | 1,000 | 0.668 | 0.061 | 0.695 | 0.070 | 0.521 | 0.055 | 0.685 | 0.174 | −0.017 | +0.010 | −0.164 |
|
| 270 |
+
| *held-out 6 (not in training), macro* | | 5,687 | **0.830** | 0.094 | **0.842** | 0.090 | **0.694** | 0.077 | 0.835 | 0.090 | −0.005 | +0.006 | −0.142 |
|
| 271 |
+
| *other 16 (train splits in training)* | | | | | | | | | | | | | |
|
| 272 |
+
| `banking77` | choice | 1,000 | 0.862 | 0.100 | 0.862 | 0.093 | 0.701 | 0.099 | 0.796 | 0.095 | +0.066 | +0.066 | −0.095 |
|
| 273 |
+
| `boolq` | noul | 1,000 | 0.904 | 0.085 | 0.921 | 0.079 | 0.812 | 0.043 | 0.917 | 0.021 | −0.013 | +0.004 | −0.105 |
|
| 274 |
+
| `chaosnli` | choice | 1,599 | 0.631 | 0.108 | 0.672 | 0.071 | 0.578 | 0.142 | 0.615 | 0.222 | +0.016 | +0.057 | −0.037 |
|
| 275 |
+
| `civil_comments` | noul | 2,000 | 0.919 | 0.086 | 0.912 | 0.074 | 0.921 | 0.074 | 0.729 | 0.045 | +0.191 | +0.183 | +0.193 |
|
| 276 |
+
| `go_emotions` | choice | 1,000 | 0.569 | 0.032 | 0.577 | 0.043 | 0.559 | 0.034 | 0.282 | 0.384 | +0.287 | +0.295 | +0.277 |
|
| 277 |
+
| `helpsteer2_helpfulness` | score | 1,000 | 0.446 | 0.025 | 0.441 | 0.032 | 0.410 | 0.034 | 0.363 | 0.232 | +0.083 | +0.078 | +0.047 |
|
| 278 |
+
| `helpsteer2_verbosity` | score | 1,000 | 0.679 | 0.160 | 0.637 | 0.111 | 0.678 | 0.184 | 0.341 | 0.231 | +0.338 | +0.296 | +0.337 |
|
| 279 |
+
| `ledgar` | choice | 1,000 | 0.775 | 0.099 | 0.790 | 0.090 | 0.686 | 0.064 | 0.751 | 0.117 | +0.024 | +0.039 | −0.065 |
|
| 280 |
+
| `massive` | choice | 1,000 | 0.857 | 0.099 | 0.849 | 0.093 | 0.739 | 0.114 | 0.808 | 0.090 | +0.049 | +0.041 | −0.069 |
|
| 281 |
+
| `mmlu` | choice | 1,000 | 0.729 | 0.075 | 0.795 | 0.064 | 0.497 | 0.111 | 0.923 | 0.027 | −0.194 | −0.128 | −0.426 |
|
| 282 |
+
| `mnli` | choice | 1,000 | 0.905 | 0.085 | 0.897 | 0.087 | 0.814 | 0.055 | 0.883 | 0.032 | +0.022 | +0.014 | −0.069 |
|
| 283 |
+
| `paws` | noul | 1,000 | 0.909 | 0.079 | 0.913 | 0.084 | 0.865 | 0.064 | 0.846 | 0.040 | +0.063 | +0.067 | +0.019 |
|
| 284 |
+
| `sms_spam` | noul | 800 | 0.983 | 0.093 | 0.980 | 0.089 | 0.976 | 0.089 | 0.965 | 0.068 | +0.018 | +0.015 | +0.011 |
|
| 285 |
+
| `sst5` | score | 1,000 | 0.582 | 0.059 | 0.593 | 0.042 | 0.525 | 0.037 | 0.565 | 0.190 | +0.017 | +0.028 | −0.040 |
|
| 286 |
+
| `strategyqa_closed` | noul | 687 | 0.703 | 0.055 | 0.761 | 0.037 | 0.550 | 0.063 | 0.785 | 0.042 | −0.082 | −0.024 | −0.235 |
|
| 287 |
+
| `stsb` | score | 1,000 | 0.585 | 0.048 | 0.581 | 0.047 | 0.501 | 0.047 | 0.538 | 0.119 | +0.047 | +0.043 | −0.037 |
|
| 288 |
+
| *other 16 (train splits in training), macro* | | 17,086 | **0.752** | 0.081 | **0.761** | 0.071 | **0.676** | 0.078 | 0.694 | 0.122 | +0.058 | +0.067 | −0.018 |
|
| 289 |
+
| **all 22, macro** | | 22,773 | **0.774** | **0.084** | **0.783** | **0.076** | **0.681** | **0.078** | 0.733 | 0.113 | +0.041 | +0.051 | −0.052 |
|
| 290 |
|
| 291 |
<sub>Jev values: the Jev 1.13.0 per-config table on the jev-bench dataset card (TypeSafe API, every test record); our project records hold the same accuracies for all 22 configs. Turnike-4B is ahead of Jev on 14 of 22 configs and by +0.041 macro. On the six held-out sources Turnike-4B (0.830) is above the leaderboard author's best open model (0.828, as stated on the card) and behind Jev (0.835) and the hosted pplx-decider-v1-27b (0.840). Jev also leads on the knowledge configs (mmlu, strategyqa_closed, arc_challenge).</sub>
|
| 292 |
|
|
|
|
| 324 |
|
| 325 |
<sub>Protocol: human gold labels from five public Turkish datasets, test texts only. All models were scored by the same script against the same gold file; no model answered "unsure". Stars are exact match on a 5-point scale (within ±1 star Turnike-4B gets 0.91 / 0.90). Our leakage scan flagged 19 items as overlapping with training texts; without them Turnike-4B gets 0.746. Microsoft-Decision-1 and Jev were called through their APIs, the others ran locally.</sub>
|
| 326 |
|
| 327 |
+
#### Table 5. JevBench TR-50 (supplementary): the same 1,100 machine-translated rows for every model
|
| 328 |
|
| 329 |
| model | TR-50 macro | held-6 / other-16 | McNemar vs Turnike-4B (only-Turnike-4B / only-other) |
|
| 330 |
|---|---|---|---|
|
|
|
|
| 338 |
| OpenJev 4B (qwen3.5-4b-nli-v5) | 0.621 | 0.717 / 0.585 | 172 / 85, p = 6e-8 |
|
| 339 |
| Kev-0.8B | 0.508 | 0.580 / 0.481 | 295 / 84, p = 1e-28 |
|
| 340 |
|
| 341 |
+
<sub>Protocol: 50 rows per config (seed 7) from a machine-translated Turkish JevBench test, 22 configs, 1,100 rows. The set is small and noisy: it moved by 0.02 between two seeds of the same recipe. Exact two-sided McNemar on paired rows; Microsoft-Decision-1 rescored from its raw API answers with the same decision rule (macro 0.7445, as originally reported). We treat this set as supplementary: 50 rows per config and machine translation; the human-labelled tr_insan (Table 4) is the primary Turkish measure.</sub>
|
| 342 |
|
| 343 |
### Behaviour tests (Table 6)
|
| 344 |
|
|
|
|
| 400 |
|
| 401 |
## Limitations
|
| 402 |
|
| 403 |
+
- **"None of the above" is used somewhat too often.** On the balanced test the model picks "none" in 0.80–0.81 of the items where the right option is missing, but also in 0.22–0.25 of the items where it is present. This is a decision-rule choice, not only a model property: `karar.secim(probs, hicbiri="oos", esik=0.6)` picks the catch-all option only when its probability is at least the threshold. On clinc150 (151 intents, EN-300) that lifts the 9B from 0.850 to 0.873 and the 4B from 0.830 to 0.840 at 0.5; on the balanced "none" test the same threshold costs 3–4 points, so keep plain argmax for gates and audits where flagging the uncertain case is useful.
|
| 404 |
- **Not the best everywhere.** Microsoft-Decision-1 (9B) is ahead on JevBench TR-50 (0.745 vs 0.700, p = 5e-4) and slightly ahead on EN-300 (n.s.). Jev is ahead on the six held-out JevBench sources, on knowledge questions (mmlu 0.923 vs 0.729) and on LegalBench rule application (0.924 vs 0.832).
|
| 405 |
- **KVKK thresholds are noisy.** The gold sets are tiny (9, 10, 12 items) and a few items sit near p = 0.5. Do not threshold yes/no probabilities near 0.5 without your own validation set.
|
| 406 |
- **go_emotions, hate speech, star ratings:** on full JevBench the model scores 0.569 on go_emotions and 0.631 on measuring_hate_speech. The boundary between offensive language and group-targeted hate is the weakest point, together with 5-level star ratings.
|
assets/fig_compare.png
CHANGED
|
Git LFS Details
|
|
Git LFS Details
|
birlestir.py
CHANGED
|
@@ -34,7 +34,7 @@ ANA_REPO = "berkay123001/turnike-4b"
|
|
| 34 |
BIRLESIK_REPO = "berkay123001/turnike-4b-merged"
|
| 35 |
BIRLESIK_KART = """---
|
| 36 |
license: apache-2.0
|
| 37 |
-
base_model:
|
| 38 |
base_model_relation: merge
|
| 39 |
pipeline_tag: text-classification
|
| 40 |
language:
|
|
@@ -47,7 +47,7 @@ tags:
|
|
| 47 |
|
| 48 |
# {ad} (merged bf16 weights)
|
| 49 |
|
| 50 |
-
The LoRA adapter [{ana}](https://huggingface.co/{ana}) merged into
|
| 51 |
`karar.py` performs at load time). Use it without PEFT:
|
| 52 |
|
| 53 |
```python
|
|
@@ -58,11 +58,12 @@ k.sor("Kulaklık bozuk geldi, paramı geri istiyorum.", {{"Yazar iade istiyor mu
|
|
| 58 |
|
| 59 |
Model card, evaluation, training data, limitations and declarations (training data not released; not distilled
|
| 60 |
from a commercial decision API; AI assistance): see [{ana}](https://huggingface.co/{ana}).
|
| 61 |
-
License: Apache-2.0 (base model
|
| 62 |
"""
|
| 63 |
|
| 64 |
|
| 65 |
-
def birlestir(adapter: str, taban: str, cikti: Path
|
|
|
|
| 66 |
from peft import PeftModel
|
| 67 |
from transformers import AutoProcessor, AutoTokenizer, Qwen3_5ForConditionalGeneration
|
| 68 |
|
|
@@ -87,7 +88,8 @@ def birlestir(adapter: str, taban: str, cikti: Path) -> None:
|
|
| 87 |
for ad in EK_DOSYALAR:
|
| 88 |
if (burasi / ad).exists():
|
| 89 |
shutil.copy2(burasi / ad, cikti / ad)
|
| 90 |
-
kart = BIRLESIK_KART.format(ad=MODEL_ADI, ana=ANA_REPO, birlesik=BIRLESIK_REPO
|
|
|
|
| 91 |
(cikti / "README.md").write_text(kart, encoding="utf-8")
|
| 92 |
print(f"yazildi: {cikti} ({sum(f.stat().st_size for f in cikti.iterdir()) / 1e9:.2f} GB)")
|
| 93 |
|
|
@@ -114,8 +116,12 @@ def main(argv: list[str] | None = None) -> None:
|
|
| 114 |
p.add_argument("--taban", default=VARSAYILAN_TABAN)
|
| 115 |
p.add_argument("--cikti", type=Path, required=True)
|
| 116 |
p.add_argument("--dogrula", action="store_true", help="birlestirdikten sonra bir ornekte esdegerlik kontrolu")
|
|
|
|
|
|
|
|
|
|
|
|
|
| 117 |
args = p.parse_args(argv)
|
| 118 |
-
birlestir(args.adapter, args.taban, args.cikti)
|
| 119 |
if args.dogrula and dogrula(args.adapter, args.taban, args.cikti) > DOGRULAMA_TOLERANS:
|
| 120 |
raise SystemExit(f"birlesik agirlik adaptorle ayni sonucu vermiyor (> {DOGRULAMA_TOLERANS})")
|
| 121 |
|
|
|
|
| 34 |
BIRLESIK_REPO = "berkay123001/turnike-4b-merged"
|
| 35 |
BIRLESIK_KART = """---
|
| 36 |
license: apache-2.0
|
| 37 |
+
base_model: {taban}
|
| 38 |
base_model_relation: merge
|
| 39 |
pipeline_tag: text-classification
|
| 40 |
language:
|
|
|
|
| 47 |
|
| 48 |
# {ad} (merged bf16 weights)
|
| 49 |
|
| 50 |
+
The LoRA adapter [{ana}](https://huggingface.co/{ana}) merged into {taban} (bf16, same merge that
|
| 51 |
`karar.py` performs at load time). Use it without PEFT:
|
| 52 |
|
| 53 |
```python
|
|
|
|
| 58 |
|
| 59 |
Model card, evaluation, training data, limitations and declarations (training data not released; not distilled
|
| 60 |
from a commercial decision API; AI assistance): see [{ana}](https://huggingface.co/{ana}).
|
| 61 |
+
License: Apache-2.0 (base model {taban}: Apache-2.0, Copyright 2026 Alibaba Cloud).
|
| 62 |
"""
|
| 63 |
|
| 64 |
|
| 65 |
+
def birlestir(adapter: str, taban: str, cikti: Path, ad: str = None, ana: str = None, birlesik: str = None,
|
| 66 |
+
taban_ad: str = None) -> None:
|
| 67 |
from peft import PeftModel
|
| 68 |
from transformers import AutoProcessor, AutoTokenizer, Qwen3_5ForConditionalGeneration
|
| 69 |
|
|
|
|
| 88 |
for ad in EK_DOSYALAR:
|
| 89 |
if (burasi / ad).exists():
|
| 90 |
shutil.copy2(burasi / ad, cikti / ad)
|
| 91 |
+
kart = BIRLESIK_KART.format(ad=ad or MODEL_ADI, ana=ana or ANA_REPO, birlesik=birlesik or BIRLESIK_REPO,
|
| 92 |
+
taban=taban_ad or (taban if taban.count("/") == 1 and not taban.startswith((".", "/")) else VARSAYILAN_TABAN))
|
| 93 |
(cikti / "README.md").write_text(kart, encoding="utf-8")
|
| 94 |
print(f"yazildi: {cikti} ({sum(f.stat().st_size for f in cikti.iterdir()) / 1e9:.2f} GB)")
|
| 95 |
|
|
|
|
| 116 |
p.add_argument("--taban", default=VARSAYILAN_TABAN)
|
| 117 |
p.add_argument("--cikti", type=Path, required=True)
|
| 118 |
p.add_argument("--dogrula", action="store_true", help="birlestirdikten sonra bir ornekte esdegerlik kontrolu")
|
| 119 |
+
p.add_argument("--ad", default=None, help=f"kart basligi (varsayilan {MODEL_ADI}); aile: Turnike-9B")
|
| 120 |
+
p.add_argument("--ana-repo", default=None, help=f"adaptor reposu (varsayilan {ANA_REPO})")
|
| 121 |
+
p.add_argument("--birlesik-repo", default=None, help=f"birlesik repo (varsayilan {BIRLESIK_REPO})")
|
| 122 |
+
p.add_argument("--taban-ad", default=None, help="kartta yazilacak taban Hub kimligi (--taban yerel yolsa, orn. Qwen/Qwen3.5-9B)")
|
| 123 |
args = p.parse_args(argv)
|
| 124 |
+
birlestir(args.adapter, args.taban, args.cikti, args.ad, args.ana_repo, args.birlesik_repo, args.taban_ad)
|
| 125 |
if args.dogrula and dogrula(args.adapter, args.taban, args.cikti) > DOGRULAMA_TOLERANS:
|
| 126 |
raise SystemExit(f"birlesik agirlik adaptorle ayni sonucu vermiyor (> {DOGRULAMA_TOLERANS})")
|
| 127 |
|
karar.py
CHANGED
|
@@ -69,6 +69,10 @@ TAM_BICIM_ANAHTARLARI = {"type", "instructions", "criteria"}
|
|
| 69 |
ALAN_ADI = re.compile(r"^[A-Za-z_][A-Za-z0-9_]{0,63}$")
|
| 70 |
# FP8: lineer-dikkat projeksiyonlarindan cikisi 128'den kucuk olanlar (in_proj_a/b) zaten disarida kalir.
|
| 71 |
FP8_MIN_CIKIS = 128
|
|
|
|
|
|
|
|
|
|
|
|
|
| 72 |
CLI_SORU_AYRACI = "|"
|
| 73 |
ADAPTOR_DOSYALARI = ("adapter_config.json", "adapter_model.safetensors")
|
| 74 |
|
|
@@ -251,6 +255,40 @@ def fp8_uygula(model):
|
|
| 251 |
return model
|
| 252 |
|
| 253 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 254 |
# --- Model --------------------------------------------------------------------
|
| 255 |
def _adaptor_yolu(adapter: str | Path) -> str:
|
| 256 |
"""Yerel dizinse gerekli dosyalar var mi (~ acilir); degilse Hub kimligi sayilir."""
|
|
@@ -303,9 +341,16 @@ class Karar:
|
|
| 303 |
warnings.warn("CUDA yok: model CPU'da bf16 calisir ama cok yavastir.", stacklevel=2)
|
| 304 |
try:
|
| 305 |
self.tok = AutoTokenizer.from_pretrained(taban)
|
| 306 |
-
|
| 307 |
-
|
| 308 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 309 |
except OSError as hata:
|
| 310 |
raise FileNotFoundError(f"taban model yuklenemedi: '{taban}' ({hata})") from hata
|
| 311 |
if adapter is not None:
|
|
@@ -315,9 +360,9 @@ class Karar:
|
|
| 315 |
model = PeftModel.from_pretrained(model, adapter).merge_and_unload()
|
| 316 |
except (OSError, ValueError) as hata:
|
| 317 |
raise FileNotFoundError(f"adaptor yuklenemedi: '{adapter}' ({hata})") from hata
|
| 318 |
-
|
| 319 |
-
|
| 320 |
-
|
| 321 |
self.model = model.eval()
|
| 322 |
self.model.requires_grad_(False)
|
| 323 |
self.fp8, self.maks_istem_token = fp8, maks_istem_token
|
|
@@ -327,6 +372,14 @@ class Karar:
|
|
| 327 |
bas = self.model.lm_head
|
| 328 |
# Aday sembollerin cikis agirliklari (fp32 kopya): okuma 62 x H carpim, tam sozluk (248k) hesaplanmaz.
|
| 329 |
self.sembol_agirlik = bas.weight[self.sembol_id.to(bas.weight.device)].detach().float().clone()
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 330 |
self.kesilen = 0 # sinira sigmayip metni kesilen gecis sayisi
|
| 331 |
|
| 332 |
@torch.inference_mode()
|
|
|
|
| 69 |
ALAN_ADI = re.compile(r"^[A-Za-z_][A-Za-z0-9_]{0,63}$")
|
| 70 |
# FP8: lineer-dikkat projeksiyonlarindan cikisi 128'den kucuk olanlar (in_proj_a/b) zaten disarida kalir.
|
| 71 |
FP8_MIN_CIKIS = 128
|
| 72 |
+
# Yukleme aninda FP8 (birlesik agirliklar, TorchAoConfig) icin haric kaliplari: fp8_uygula'nin kuraliyla (dil modeli
|
| 73 |
+
# lineerleri; 16'ya bolunmeyen ya da cikisi kucuk olanlar haric) 0.8B / 4B / 9B'de birebir ayni kume: gorme kulesi, lm_head,
|
| 74 |
+
# in_proj_a / in_proj_b (16-32 cikis). transformers kaliplari parametre adinin basindan regex ile eslestirir.
|
| 75 |
+
FP8_YUKLEME_HARIC = (r".*\.visual\.", "lm_head", r".*\.in_proj_a\.", r".*\.in_proj_b\.")
|
| 76 |
CLI_SORU_AYRACI = "|"
|
| 77 |
ADAPTOR_DOSYALARI = ("adapter_config.json", "adapter_model.safetensors")
|
| 78 |
|
|
|
|
| 255 |
return model
|
| 256 |
|
| 257 |
|
| 258 |
+
def fp8_yukleme_ayari():
|
| 259 |
+
"""Yukleme aninda FP8 (transformers TorchAoConfig): fp8_uygula ile ayni torchao tarifi, ayni haric kume.
|
| 260 |
+
|
| 261 |
+
Birlesik agirliklarda bf16 kopyasi hic olusmaz; katmanlar yuklenirken FP8'e cevrilir (9B ~10 GB, 16 GB karta sigar).
|
| 262 |
+
"""
|
| 263 |
+
try:
|
| 264 |
+
from torchao.float8.inference import Float8MMConfig
|
| 265 |
+
from torchao.quantization import Float8DynamicActivationFloat8WeightConfig
|
| 266 |
+
from torchao.quantization.granularity import PerRow
|
| 267 |
+
from transformers import TorchAoConfig
|
| 268 |
+
except ImportError as hata:
|
| 269 |
+
raise RuntimeError("fp8=True icin torchao gerekli: pip install torchao") from hata
|
| 270 |
+
ayar = Float8DynamicActivationFloat8WeightConfig(granularity=PerRow(),
|
| 271 |
+
mm_config=Float8MMConfig(use_fast_accum=True))
|
| 272 |
+
return TorchAoConfig(quant_type=ayar, modules_to_not_convert=list(FP8_YUKLEME_HARIC))
|
| 273 |
+
|
| 274 |
+
|
| 275 |
+
def secim(dagilim: dict[str, float], hicbiri: str | None = None, esik: float | None = None) -> str:
|
| 276 |
+
"""Karar kurali: argmax; hicbiri verilirse o secenek yalniz p(hicbiri) >= esik ise secilir, yoksa en iyi somut secenek.
|
| 277 |
+
|
| 278 |
+
Model "yukaridakilerden hicbiri" / "oos" turu secenege temkinli yaklasir (dengeli hicbiri egitimi). Niyet yonlendirme gibi
|
| 279 |
+
islerde esik 0.5-0.6 yanlis "hicbiri" kararlarini azaltir (clinc150: 9B 0.850 -> 0.873 @0.6); kapi/denetim islerinde
|
| 280 |
+
(belirsizi isaretlemek faydaliysa) argmax (esik=None) daha uygundur: ayni esik dengeli hicbiri testinde 3-4 puan kaybettirir.
|
| 281 |
+
"""
|
| 282 |
+
if not dagilim:
|
| 283 |
+
raise ValueError("bos dagilim")
|
| 284 |
+
en = max(dagilim, key=dagilim.get)
|
| 285 |
+
if hicbiri is not None and esik is not None and en == hicbiri and dagilim[hicbiri] < esik:
|
| 286 |
+
digerleri = [s for s in dagilim if s != hicbiri]
|
| 287 |
+
if digerleri:
|
| 288 |
+
en = max(digerleri, key=dagilim.get)
|
| 289 |
+
return en
|
| 290 |
+
|
| 291 |
+
|
| 292 |
# --- Model --------------------------------------------------------------------
|
| 293 |
def _adaptor_yolu(adapter: str | Path) -> str:
|
| 294 |
"""Yerel dizinse gerekli dosyalar var mi (~ acilir); degilse Hub kimligi sayilir."""
|
|
|
|
| 341 |
warnings.warn("CUDA yok: model CPU'da bf16 calisir ama cok yavastir.", stacklevel=2)
|
| 342 |
try:
|
| 343 |
self.tok = AutoTokenizer.from_pretrained(taban)
|
| 344 |
+
if adapter is None:
|
| 345 |
+
# Birlesik agirliklar dogrudan cihaza yuklenir; fp8=True ise katmanlar yuklenirken FP8'e cevrilir
|
| 346 |
+
# (bf16 kopyasi olusmaz: 9B ~10 GB ile 16 GB karta sigar, RAM gerekmez).
|
| 347 |
+
model = Qwen3_5ForConditionalGeneration.from_pretrained(
|
| 348 |
+
taban, dtype=VERI_TIPI, attn_implementation=DIKKAT_UYGULAMASI, device_map=str(self.device),
|
| 349 |
+
quantization_config=fp8_yukleme_ayari() if fp8 else None)
|
| 350 |
+
else:
|
| 351 |
+
# CPU'ya yuklenir, LoRA CPU'da birlestirilir, sonra cihaza tasinir (olcum koduyla ayni yol).
|
| 352 |
+
model = Qwen3_5ForConditionalGeneration.from_pretrained(
|
| 353 |
+
taban, dtype=VERI_TIPI, attn_implementation=DIKKAT_UYGULAMASI)
|
| 354 |
except OSError as hata:
|
| 355 |
raise FileNotFoundError(f"taban model yuklenemedi: '{taban}' ({hata})") from hata
|
| 356 |
if adapter is not None:
|
|
|
|
| 360 |
model = PeftModel.from_pretrained(model, adapter).merge_and_unload()
|
| 361 |
except (OSError, ValueError) as hata:
|
| 362 |
raise FileNotFoundError(f"adaptor yuklenemedi: '{adapter}' ({hata})") from hata
|
| 363 |
+
model = model.to(self.device)
|
| 364 |
+
if fp8:
|
| 365 |
+
model = fp8_uygula(model)
|
| 366 |
self.model = model.eval()
|
| 367 |
self.model.requires_grad_(False)
|
| 368 |
self.fp8, self.maks_istem_token = fp8, maks_istem_token
|
|
|
|
| 372 |
bas = self.model.lm_head
|
| 373 |
# Aday sembollerin cikis agirliklari (fp32 kopya): okuma 62 x H carpim, tam sozluk (248k) hesaplanmaz.
|
| 374 |
self.sembol_agirlik = bas.weight[self.sembol_id.to(bas.weight.device)].detach().float().clone()
|
| 375 |
+
# Metin yolu yalniz dil govdesini (self.govde) ve yukaridaki sembol satirlarini kullanir: gorme kulesi ve tam
|
| 376 |
+
# lm_head (248k satir; 9B'de baglanmamis, ~2 GB) bellekten cikarilir. Bagli (tied) sozlukte lm_head embed ile
|
| 377 |
+
# ayni tensor oldugundan yalniz kule kazandirir.
|
| 378 |
+
self.model.lm_head = None
|
| 379 |
+
if getattr(self.model.model, "visual", None) is not None:
|
| 380 |
+
self.model.model.visual = None
|
| 381 |
+
if self.device.type == "cuda":
|
| 382 |
+
torch.cuda.empty_cache()
|
| 383 |
self.kesilen = 0 # sinira sigmayip metni kesilen gecis sayisi
|
| 384 |
|
| 385 |
@torch.inference_mode()
|
test_karar.py
CHANGED
|
@@ -1,11 +1,14 @@
|
|
| 1 |
-
"""karar.py icin
|
| 2 |
-
(TR + EN), CLI, uzun metin / cok sik / cok soru, referans esdegerligi (istege bagli), FP8
|
|
|
|
| 3 |
|
| 4 |
Ortam degiskenleri:
|
| 5 |
KARAR_ADAPTER adaptor dizini ya da Hub kimligi (varsayilan: bu dizin)
|
| 6 |
KARAR_TABAN taban model (varsayilan: Qwen/Qwen3.5-4B; yerel yol da olur)
|
| 7 |
KARAR_REFERANS (istege bagli) olcum kodunun dizini (qwen35_decider.py); verilirse ayni girdi icin iki yolun
|
| 8 |
olasiliklari karsilastirilir, verilmezse bu test ATLANDI sayilir.
|
|
|
|
|
|
|
| 9 |
python test_karar.py # ya da: pytest -s test_karar.py
|
| 10 |
Model en fazla uc kez yuklenir (bf16 karar, referans, FP8), sirayla; ayni anda tek 4B model bellekte (~9 GB).
|
| 11 |
"""
|
|
@@ -32,6 +35,7 @@ BURASI = Path(__file__).resolve().parent
|
|
| 32 |
ADAPTER = os.environ.get("KARAR_ADAPTER", str(BURASI))
|
| 33 |
TABAN = os.environ.get("KARAR_TABAN", VARSAYILAN_TABAN)
|
| 34 |
REFERANS = os.environ.get("KARAR_REFERANS")
|
|
|
|
| 35 |
# bf16 ayni agirlik + ayni istem: iki yol ayni cekirdekleri kullanir; fark beklenmez, sinir gorev tanimindan.
|
| 36 |
REFERANS_TOLERANS = 0.02
|
| 37 |
# FP8 olasiliklari bf16'dan oynatir (olculen ort. |dp| .017, en buyuk .34, binlerce satirda); 9 ornekte gevsek sinir.
|
|
@@ -163,6 +167,20 @@ def test_bagimsiz_yukleme() -> None:
|
|
| 163 |
assert cikti == "[] Karar"
|
| 164 |
|
| 165 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 166 |
def test_hatali_girdi() -> None:
|
| 167 |
"""Hatali her bicim ValueError; dogru bicimler kabul, alan adlari ve noul etiketleri dogru."""
|
| 168 |
kotuler = [("", {"a?": ["x", "y"]}), (" ", {"a?": ["x", "y"]}), (None, {"a?": ["x", "y"]}),
|
|
@@ -352,13 +370,44 @@ def test_fp8() -> None:
|
|
| 352 |
fark = _en_buyuk_fark(bizim, fp8)
|
| 353 |
toplam, uyan = _argmax_uyumu(bizim, fp8)
|
| 354 |
_DURUM["fp8_fark"] = fark
|
|
|
|
| 355 |
print(f"FP8: max |dp| {fark:.4f} (sinir {FP8_TOLERANS}), argmax {uyan}/{toplam}, 4 soru {ms:.0f} ms")
|
| 356 |
assert fark <= FP8_TOLERANS and uyan == toplam
|
| 357 |
|
| 358 |
|
| 359 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 360 |
test_dokuz_ornek, test_cli,
|
| 361 |
-
test_uzun_metin_cok_secenek_cok_soru, test_referans_esdeger, test_fp8]
|
| 362 |
|
| 363 |
if __name__ == "__main__":
|
| 364 |
for test in TESTLER:
|
|
|
|
| 1 |
+
"""karar.py icin 11 test: bagimsizlik, secim kurali, girdi dogrulama, CLI hatalari, istem birebirligi (istege bagli), 9 ornek
|
| 2 |
+
(TR + EN), CLI, uzun metin / cok sik / cok soru, referans esdegerligi (istege bagli), FP8, birlesik agirlik +
|
| 3 |
+
yukleme aninda FP8 (istege bagli).
|
| 4 |
|
| 5 |
Ortam degiskenleri:
|
| 6 |
KARAR_ADAPTER adaptor dizini ya da Hub kimligi (varsayilan: bu dizin)
|
| 7 |
KARAR_TABAN taban model (varsayilan: Qwen/Qwen3.5-4B; yerel yol da olur)
|
| 8 |
KARAR_REFERANS (istege bagli) olcum kodunun dizini (qwen35_decider.py); verilirse ayni girdi icin iki yolun
|
| 9 |
olasiliklari karsilastirilir, verilmezse bu test ATLANDI sayilir.
|
| 10 |
+
KARAR_BIRLESIK (istege bagli) birlesik agirlik dizini ya da Hub reposu (birlestir.py ciktisi); verilirse
|
| 11 |
+
Karar(None, taban=..., fp8=True) yukleme aninda FP8 yolu adaptor + sonradan FP8 ile karsilastirilir.
|
| 12 |
python test_karar.py # ya da: pytest -s test_karar.py
|
| 13 |
Model en fazla uc kez yuklenir (bf16 karar, referans, FP8), sirayla; ayni anda tek 4B model bellekte (~9 GB).
|
| 14 |
"""
|
|
|
|
| 35 |
ADAPTER = os.environ.get("KARAR_ADAPTER", str(BURASI))
|
| 36 |
TABAN = os.environ.get("KARAR_TABAN", VARSAYILAN_TABAN)
|
| 37 |
REFERANS = os.environ.get("KARAR_REFERANS")
|
| 38 |
+
BIRLESIK = os.environ.get("KARAR_BIRLESIK")
|
| 39 |
# bf16 ayni agirlik + ayni istem: iki yol ayni cekirdekleri kullanir; fark beklenmez, sinir gorev tanimindan.
|
| 40 |
REFERANS_TOLERANS = 0.02
|
| 41 |
# FP8 olasiliklari bf16'dan oynatir (olculen ort. |dp| .017, en buyuk .34, binlerce satirda); 9 ornekte gevsek sinir.
|
|
|
|
| 167 |
assert cikti == "[] Karar"
|
| 168 |
|
| 169 |
|
| 170 |
+
def test_secim_kurali() -> None:
|
| 171 |
+
"""secim(): argmax; hicbiri + esik ile temkinli secenek ancak p >= esik ise."""
|
| 172 |
+
from karar import secim
|
| 173 |
+
d = {"a": 0.30, "b": 0.25, "oos": 0.45}
|
| 174 |
+
assert secim(d) == "oos" and secim(d, "oos", 0.4) == "oos" and secim(d, "oos", 0.5) == "a"
|
| 175 |
+
assert secim({"oos": 1.0}, "oos", 0.9) == "oos" and secim({"x": 0.6, "y": 0.4}, "oos", 0.5) == "x"
|
| 176 |
+
try:
|
| 177 |
+
secim({})
|
| 178 |
+
except ValueError:
|
| 179 |
+
pass
|
| 180 |
+
else:
|
| 181 |
+
raise AssertionError("bos dagilim ValueError vermeli")
|
| 182 |
+
|
| 183 |
+
|
| 184 |
def test_hatali_girdi() -> None:
|
| 185 |
"""Hatali her bicim ValueError; dogru bicimler kabul, alan adlari ve noul etiketleri dogru."""
|
| 186 |
kotuler = [("", {"a?": ["x", "y"]}), (" ", {"a?": ["x", "y"]}), (None, {"a?": ["x", "y"]}),
|
|
|
|
| 370 |
fark = _en_buyuk_fark(bizim, fp8)
|
| 371 |
toplam, uyan = _argmax_uyumu(bizim, fp8)
|
| 372 |
_DURUM["fp8_fark"] = fark
|
| 373 |
+
_DURUM["fp8"] = fp8
|
| 374 |
print(f"FP8: max |dp| {fark:.4f} (sinir {FP8_TOLERANS}), argmax {uyan}/{toplam}, 4 soru {ms:.0f} ms")
|
| 375 |
assert fark <= FP8_TOLERANS and uyan == toplam
|
| 376 |
|
| 377 |
|
| 378 |
+
# --- 10: birlesik agirlik + yukleme aninda FP8 ------------------------------------
|
| 379 |
+
def test_birlesik_fp8_akis() -> None:
|
| 380 |
+
"""Karar(None, taban=BIRLESIK, fp8=True): katmanlar yuklenirken FP8 (TorchAoConfig). Sonradan FP8 ile ayni olasiliklar
|
| 381 |
+
(|dp| <= 1e-3), bf16 ile argmax uyumu; bf16 kopyasi olusmadigi icin tepe bellek bf16 yuklemesinden kucuk."""
|
| 382 |
+
if not BIRLESIK or not torch.cuda.is_available():
|
| 383 |
+
print("ATLANDI: KARAR_BIRLESIK verilmedi" if not BIRLESIK else "ATLANDI: CUDA yok")
|
| 384 |
+
_DURUM["atlanan"] = _DURUM.get("atlanan", 0) + 1
|
| 385 |
+
return
|
| 386 |
+
bizim = bf16_sonuclari()
|
| 387 |
+
_bosalt()
|
| 388 |
+
torch.cuda.reset_peak_memory_stats()
|
| 389 |
+
k8 = Karar(None, BIRLESIK, fp8=True)
|
| 390 |
+
try:
|
| 391 |
+
tepe = torch.cuda.max_memory_allocated() / 1e9
|
| 392 |
+
kuantize = sum(1 for _, m in k8.model.named_modules()
|
| 393 |
+
if isinstance(m, torch.nn.Linear) and type(m.weight).__name__ != "Parameter")
|
| 394 |
+
akis = {ad: k8.olasiliklar(metin, sorular) for ad, metin, sorular, _ in ORNEKLER}
|
| 395 |
+
finally:
|
| 396 |
+
del k8
|
| 397 |
+
gc.collect()
|
| 398 |
+
torch.cuda.empty_cache()
|
| 399 |
+
fark_bf = _en_buyuk_fark(bizim, akis)
|
| 400 |
+
toplam, uyan = _argmax_uyumu(bizim, akis)
|
| 401 |
+
fark_fp8 = _en_buyuk_fark(_DURUM["fp8"], akis) if "fp8" in _DURUM else None
|
| 402 |
+
print(f"birlesik + akis FP8: kuantize lineer {kuantize}, tepe {tepe:.2f} GB, vs bf16 max |dp| {fark_bf:.4f} argmax "
|
| 403 |
+
f"{uyan}/{toplam}, vs sonradan FP8 max |dp| {'-' if fark_fp8 is None else f'{fark_fp8:.5f}'}")
|
| 404 |
+
assert kuantize > 0 and fark_bf <= FP8_TOLERANS and uyan == toplam
|
| 405 |
+
assert fark_fp8 is None or fark_fp8 <= 1e-3
|
| 406 |
+
|
| 407 |
+
|
| 408 |
+
TESTLER = [test_bagimsiz_yukleme, test_secim_kurali, test_hatali_girdi, test_soru_ayristir_ve_cli_hatalari, test_istem_birebir,
|
| 409 |
test_dokuz_ornek, test_cli,
|
| 410 |
+
test_uzun_metin_cok_secenek_cok_soru, test_referans_esdeger, test_fp8, test_birlesik_fp8_akis]
|
| 411 |
|
| 412 |
if __name__ == "__main__":
|
| 413 |
for test in TESTLER:
|