
Datasets:


metadata
configs:
  - config_name: default
    data_files:
      - split: train
        path: data/train-*
dataset_info:
  features:
    - name: uuid
      dtype: string
    - name: language
      dtype: string
    - name: site
      dtype: string
    - name: url
      dtype: string
    - name: html
      dtype: string
    - name: annotations
      list:
        - name: labels
          list: string
        - name: text
          dtype: string
        - name: xpath
          dtype: string
    - name: html_wtl
      dtype: string
    - name: html_en
      dtype: string
    - name: screenshot
      dtype: image
    - name: elements_metadata
      dtype: string
  splits:
    - name: train
      num_bytes: 82140877457
      num_examples: 29081
  download_size: 48603187188
  dataset_size: 82140877457
task_categories:
  - token-classification
language:
  - en
  - es
  - ru
  - ar
  - fr
  - pt
  - hr
  - zh
  - de
  - ko
tags:
  - web
  - multilingual
  - extraction
  - news
size_categories:
  - 10K<n<100K
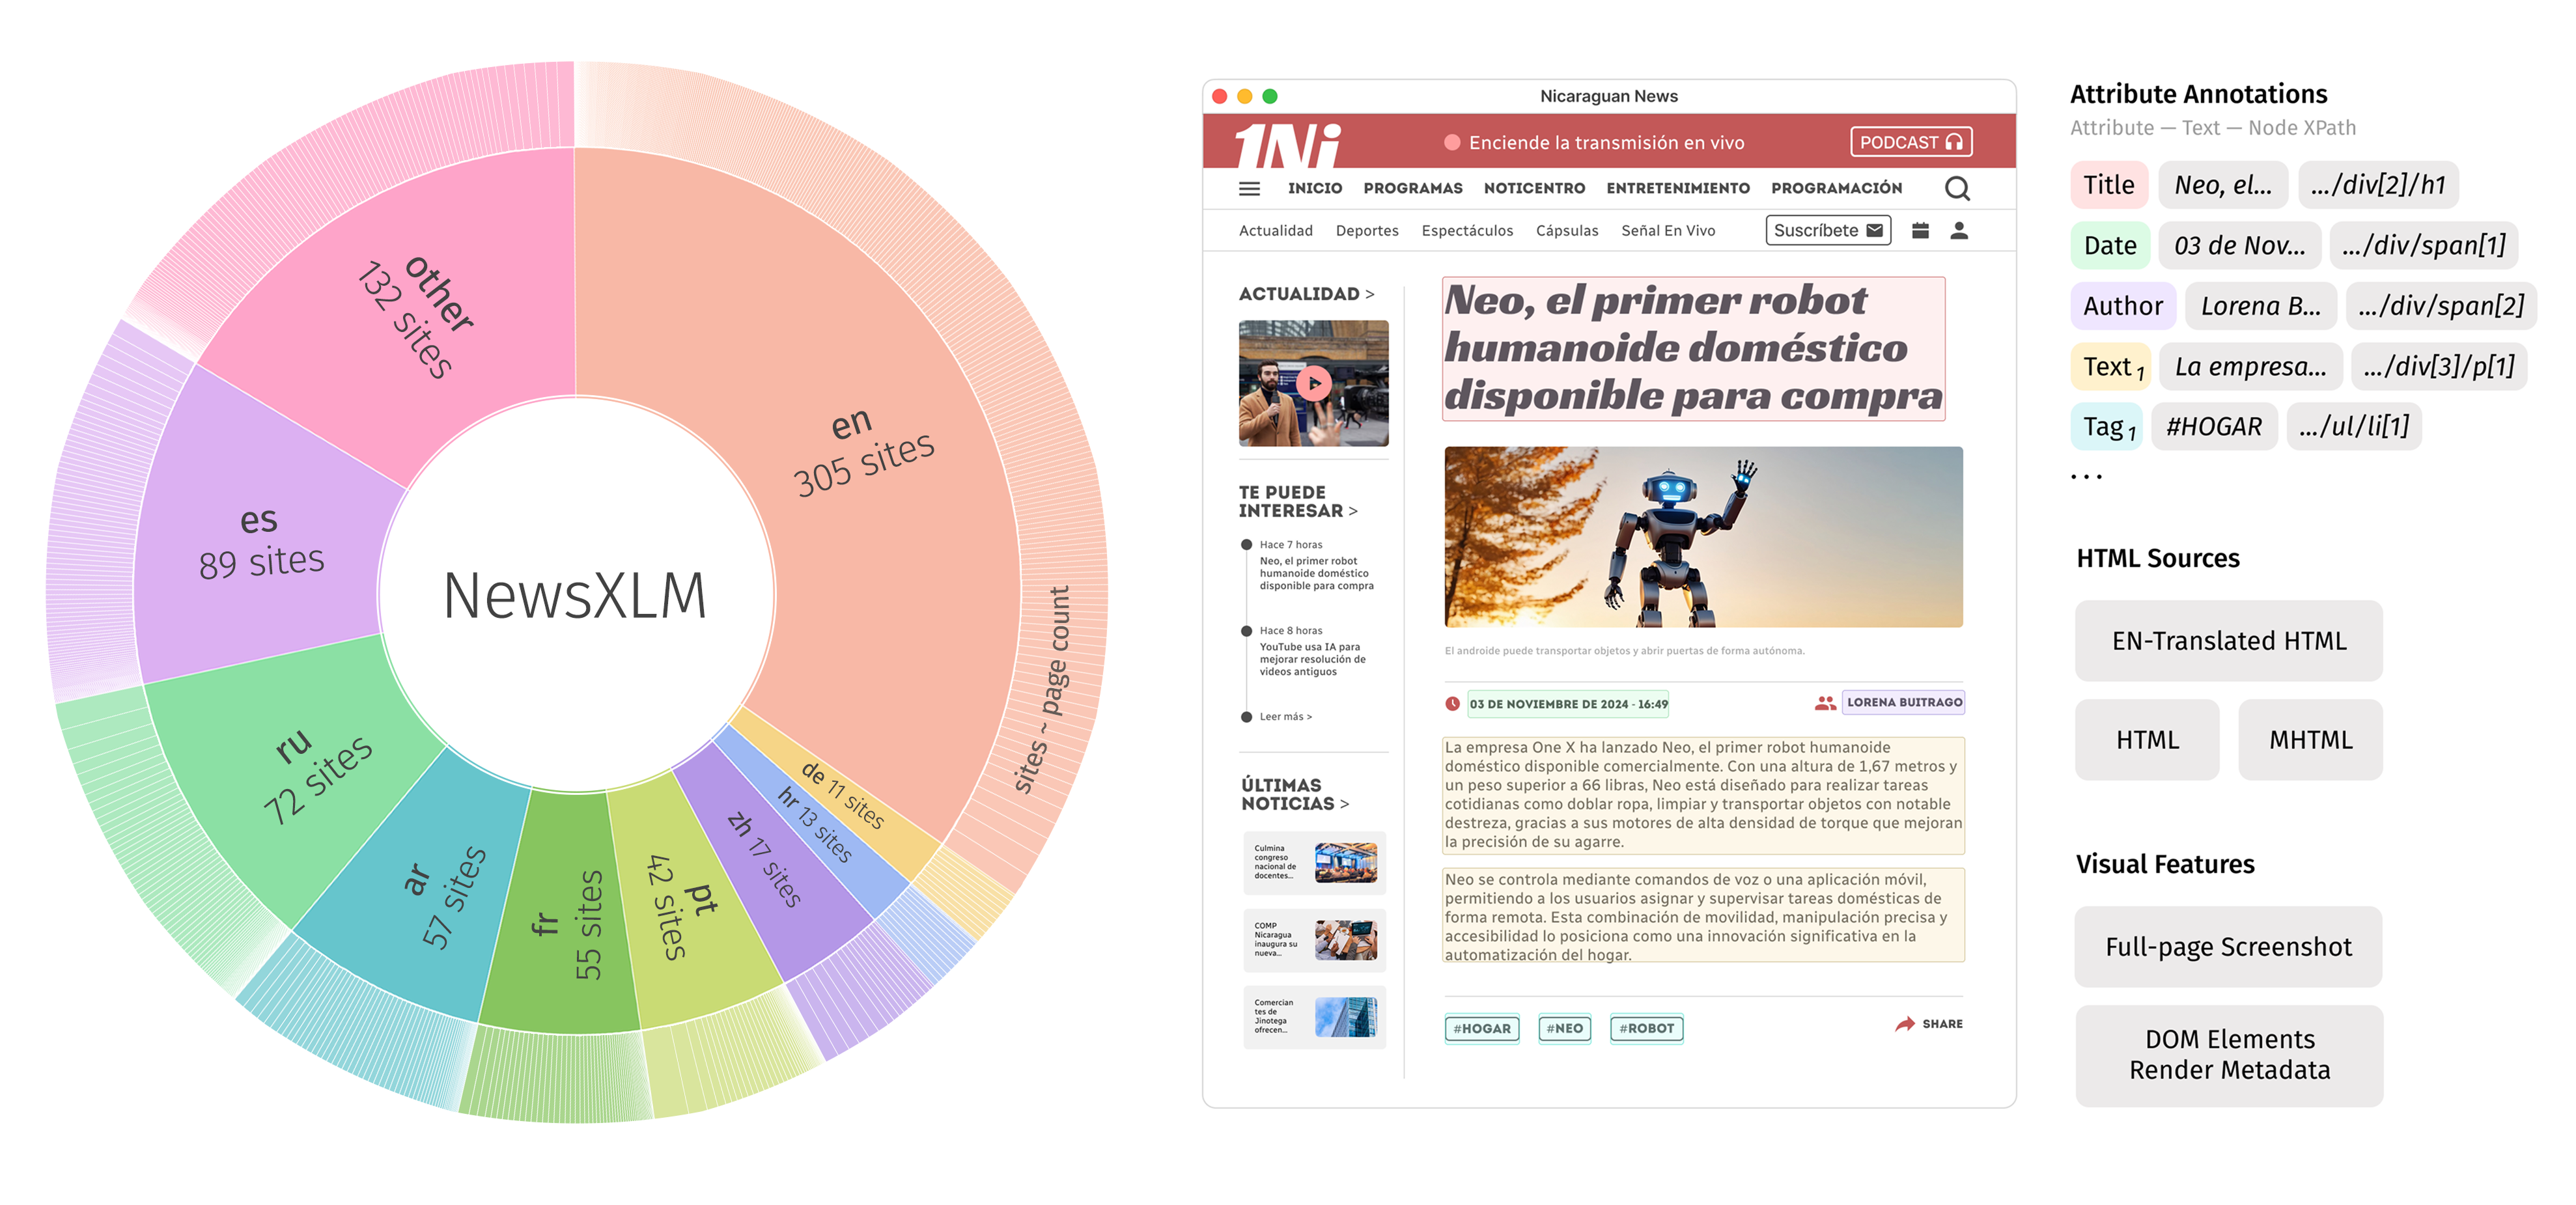
NewsXLM Dataset
The first large-scale multilingual dataset for news web page attribute extraction, containing 29,081 annotated pages from 759 websites across 56 languages.
Columns Explanation
html: Cleaned original HTMLhtml_en:htmlwith text nodes translated into Englishhtml_wtl:htmlwithwtl-uidandwtl-parent-uidattributes added to each element in <body>, following the WTL algorithmannotations: List of labeled page nodes in the following format:[ { "xpath": "string", // May end with "/tail" "text": "string", "labels": ["string"] // In this dataset, the list always contains exactly one label }, // ... ]elements_metadata: A JSON string containing <body> elements metadata produced by the WTL:{ "wtl-uid": { /* element metadata */ }, // ... }
Labeled Attributes
title, publication_date, text, author, tag. A very limited number of category labels may appear.